I found a couple of months in the past that I might drive to the closest Amtrak station in about 35 minutes. From there, it was one other hour and ten minutes to Philadelphia. Then a fast, ten minute stroll to my workplace.
Earlier than this, I might get up as early as attainable to be on the highway as early as attainable. Any little accident or building delay on I-95 meant sitting within the automobile and attending to the workplace 3 and even 4 hours after I left the home. Then I might keep in Philadelphia till late within the night to keep away from visitors again, and it nonetheless meant a 2 hour and 20 minute drive again, not counting restroom breaks or grabbing dinner.
And, let’s face it, quick meals dinner isn’t going to do me any favors. Neither is the sitting in visitors. So I’ve by no means seemed again since discovering Amtrak. It saves me time and permits me to jot down this for you, compensate for emails, or nap if I didn’t get sufficient sleep the night time earlier than. Yeah, it’s not low cost, however I’m saving on psychological well being and the damage and tear on my car.
Plus, these quick walks to and from the workplace to the practice station give me loads of materials to jot down about. I see every part from the worst of individuals to one of the best of individuals, all within the span of some metropolis blocks. There are unhoused individuals, offended individuals, individuals with the situational consciousness of a rutabaga, and people who find themselves hyper conscious of their environment as a result of they’ve a number of baggage objects with them.
Even with all that individuals watching, you’ll suppose that I might get pleasure from using the practice with a fellow passenger sitting subsequent to me the entire method. I don’t. The practice seats are in pairs on both aspect of the aisle, and seemingly everybody makes an effort to search out an empty pair to assert their very own.
My technique is to go to the again of the practice and board on the junction of the enterprise class automobile and the following coach automobile, which is normally the “quiet automobile.” Then I rapidly transfer towards the entrance of the practice, scanning for seats. As quickly as I see an open pair of seats, that’s the place I plant myself.
I don’t care of the overall place of the seats. All I care about is using in consolation.
In fact, after I can afford it (by way of a coupon or particular, or by incomes sufficient factors), I purchase a enterprise class seat. With or with out a companion, they’re roomy and comfy. And the assigned seating makes it so I don’t should seek out a seat. I do know precisely the place I’m headed after I board the practice.
I’m not the one one who does this. Everybody else appears to have the same technique. Every now and then, I’ll see somebody be disrespectful and never permit an individual to take a seat subsequent to them. “I’d somewhat sit alone, thanks,” they are saying. Nicely, with all of the seats being full, you type of don’t have any different choice, my dude.
Then there was that point I stepped right into a seat house whereas making an attempt to determine my seat in enterprise class. Because it turned out, an older man and his spouse have been seated within the house I stepped to. As an alternative of asking me to maneuver, the person simply grabbed my arm and shoved me apart. “Please don’t contact me,” I mentioned to him.
“I don’t give a shit,” he mentioned in return.
My seat was simply behind his, and I made positive to make my presence recognized. No, I didn’t kick his seat or something prefer it. I talked loudly, in Spanish, on the telephone with my brother… And I slept. By “sleep,” I imply I snored.
As luck would have it, I might see the couple once more in a unique practice. They appear to journey so much between New York and Washington, DC.
General, the expertise on Amtrak hasn’t been dangerous. It’s not as dangerous because the cumulative experiences posted on the web would have you ever consider. (Bias a lot?) Twice, the practice has run late and even been cancelled, each occasions due to climate. One time, two individuals acquired right into a heated argument over their seating preparations. However they have been rapidly introduced below management by an assertive conductor.
And one drunk and belligerent Boston Pink Sox fan was introduced below management by the group who shamed him to the purpose he stood up and went to the café automobile, by no means to be seen once more. Speak about “crowd management,” huh?
I haven’t been on trains as a lot as I’ve within the final six months. Earlier than then, my solely expertise was after I was three years previous and my grandmothers took me from Chihuahua to Sinaloa on the Chepe practice over the Tarahumara sierra. After that, it was leisure journeys on historic trains for a couple of miles.
And, no, I’m not counting using the Metro in Washington as a practice expertise. That’s only a fancy bus. (However, then once more, possibly using the practice from Baltimore to Philadelphia is a fancier bus?)
All of this has acquired me excited about the inequity in transportation we see in cities and rural areas in the USA. Individuals are restricted in the place they will work as a result of they’ve restricted methods to get there. So that they purchase low cost and inefficient automobiles that pollute or value an excessive amount of to restore.
I’m very fortunate to be paying off a three-year-old automobile in a month, a automobile that takes me to the practice station, the place I can afford a ticket to Philly to be there the 2 days required for me to be in individual on the workplace. I’m very fortunate to have the ability to work at home the opposite two days, although you’ll normally discover me doing one thing in the neighborhood. (You may solely accomplish that a lot for public well being from behind a desk in an workplace of any type.)
We should always all be this fortunate.
Now, when you’ll excuse me, I’ve some emails to reply and conferences to arrange for, as we’re an hour out from Philly.
A while again I took the time to clarify that matrix multiplication might be seen as a linear transformation. Having that perspective helps to know the inner-workings of all AI fashions throughout varied domains (audio, photographs, and so on.). Constructing on that, these subsequent couple of posts will assist you perceive the inputs utilized in these matrix multiplication operations, particularly for individuals who wish to perceive how text-based fashions and LLMs perform. Our focus is on the notorious one-hot encoding, as it’s the key to unlock the underlying idea. It can present you, I hope, the often-illusive instinct behind word-embeddings.
I take advantage of the next easy instance sentences:
S1: “The canine chased the cat”
S2: “The cat watched the hen”
For simplicity I take advantage of the time period ‘phrases’ however in follow we use the extra common time period ‘tokens’ which may stand for something, for instance a query marks or phrase fragments, reasonably than complete phrases. However we hold at it as if our tokens are simply complete phrases. The place to begin of feeding these texts to the machine the conversion to numerical values. Textual content to numbers conversion might be completed in few alternative ways, which could appear a bit complicated for newcomers. Here’s a abstract desk to verify we’re all discussing the identical factor.
Technique
Definition
Construction
Data Preserved
Instance
One-Sizzling Encoding
Every distinctive phrase as a sparse vector with a single “1”
columns- or rows-concatenated of bag-of-words vectors for a number of paperwork or sentences
Matrix: vocabulary dimension × paperwork
Phrase frequencies throughout corpus
Phrase
S1
S2
the
2
2
canine
1
0
chased
1
0
cat
1
1
watched
0
1
hen
0
1
As talked about, our focus right here is on utilizing one-hot encoding (first row within the desk above) the dimensions of the whole one-hot matrix is:Whole Phrases × Distinctive Phrases. The place:
Whole Phrases = The sum of all phrase occurrences throughout all paperwork/sentences
Distinctive Phrases = The variety of completely different phrases within the vocabulary
Within the one-hot matrix every row corresponds to a single phrase incidence within the corpus, every column corresponds to a singular phrase within the vocabulary, and every row incorporates precisely one “1” with zeros elsewhere. Because the corpus grows, the matrix turns into very massive and more and more sparse, which is why one-hot encoding in itself is often a no-go for direct storage and manipulation in large-scale functions. Nevertheless it’s essential for greedy the ideas we’ll construct on later. The next desk illustrates how sparsity grows with dimensionality:
Corpus Measurement
Whole Phrases
Distinctive Phrases
Matrix Measurement
Non-Zero Parts
Non-Zero Proportion
Small
10
7
10×7 = 70
10
14.3%
Medium
1,000
200
1,000×200 = 200,000
1,000
0.5%
Giant
1,000,000
100,000
= 100 billion
0.001%
Whereas in itself the one-hot matrix will not be tremendous sensible, all phrase embeddings originate from that one-hot matrix. Heads up: Algebra forward 📐!
Why is the one-hot matrix the muse for embedding Studying?
The one-hot matrix is a foundation within the algebraic sense. I first clarify the which means of foundation, then we see why it’s related for phrase embeddings. Foundation within the algebraic sense implies that:
The vectors in that matrix are linearly impartial
Some other vector you possibly can consider might be expressed as a linear mixture of the one-hot vectors. Extra formally, the one-hot matrix spans the vector house.
In much less summary phrases you possibly can consider the one-hot vectors as colours. Think about your colours as a “palette.” A whole palette, able to making any colour, has these properties: Completeness – it “spans” all colours, and non-redundancy – its colours are “impartial”. Crimson, yellow, blue, white, and black are full and non-redundant. In distinction: Crimson, blue, and white are incomplete, lacking colours like yellow and inexperienced. The set: pink, orange, yellow, inexperienced, blue, purple, white, and black has some redundancies, for instance purple might be created utilizing a combination of pink and blue.
Returning to our ordinary formal perspective:
Linear dependence means one vector might be precisely written as a mixture of others. To state that two vectors are linearly dependent is like saying: “one vector is fully predictable from the others,” like an ideal correlation. When vectors are linearly impartial, no vector is “explaining” or “duplicating” one other – just like uncorrelated variables. To indicate that one-hot vectors are linearly impartial we use the zero vector (the place all entries are zero). The zero vector might be created by a linear mixture of any vectors, how? you trivially set all of the weightscoefficients of the opposite vectors to zero. So, if the one manner we are able to get the zero vector is by setting all the weights to zero it implies that no vector might be “cancelled” by one other vector, which means there isn’t any redundancy or put in a different way there isn’t any linear dependence.
For the above to carry there isn’t any different manner however:
The solely solution to make the zero vector is by making all coefficients zero. So there’s your linear independence, now let’s transfer on to spanning.
For a set of vectors to span the vector house, you have to show that each vector in that house might be written as a linear mixture of the given set. The usual foundation vectors (the one-hot vectors in our case) span ( means a vector of actual variety of dimension the place must be regarded as the dimensions of the vocabulary) as a result of any vector , the place , might be written as a linear mixture of the idea vectors. Right here is why:
Outline for every . Then:
In phrases, you merely set the vectors such that their entries are all zeros besides the entry wanted to assemble the vector precisely; as a result of whenever you multiply that entry with 1, you get . This reveals that might be expressed as a linear mixture of , so that they span . That means: all and any embedding vectors (even in decrease dimensional house) are linear mixtures of the one-hot vectors.
Whereas one-hot encoding isn’t sensible for real-world use its algebraic understanding makes it why word-embeddings really works, and why it’s theoretically legit to shift from that giant, discrete and sparse house to a smaller, dense, steady, and semantically related house.
With algebra lined, the subsequent put up will discover the geometric interpretation of phrase embeddings.
At its core, a stack is a linear knowledge construction that follows the LIFO (Final In First Out) precept. Consider it as a stack of plates in a cafeteria; you solely take the plate that is on high, and when inserting a brand new plate, it goes to the highest of the stack.
The final ingredient added is the primary ingredient to be eliminated
However, why is knowing the stack essential? Through the years, stacks have discovered their purposes in a plethora of areas, from reminiscence administration in your favourite programming languages to the back-button performance in your internet browser. This intrinsic simplicity, mixed with its huge applicability, makes the stack an indispensable software in a developer’s arsenal.
On this information, we’ll deep dive into the ideas behind stacks, their implementation, use instances, and rather more. We’ll outline what stacks are, how they work, after which, we’ll check out two of the most typical methods to implement stack knowledge construction in Python.
Basic Ideas of a Stack Knowledge Construction
At its essence, a stack is deceptively easy, but it possesses nuances that grant it versatile purposes within the computational area. Earlier than diving into its implementations and sensible usages, let’s guarantee a rock-solid understanding of the core ideas surrounding stacks.
The LIFO (Final In First Out) Precept
LIFO is the tenet behind a stack. It implies that the final merchandise to enter the stack is the primary one to depart. This attribute differentiates stacks from different linear knowledge buildings, similar to queues.
Be aware: One other helpful instance that can assist you wrap your head across the idea of how stacks work is to think about folks getting out and in of an elevator – the final one that enters an elevator is the primary to get out!
Fundamental Operations
Each knowledge construction is outlined by the operations it helps. For stacks, these operations are easy however important:
Push – Provides a component to the highest of the stack. If the stack is full, this operation would possibly end in a stack overflow.
Pop – Removes and returns the topmost ingredient of the stack. If the stack is empty, trying a pop could cause a stack underflow.
Peek (or High) – Observes the topmost ingredient with out eradicating it. This operation is helpful if you need to examine the present high ingredient with out altering the stack’s state.
By now, the importance of the stack knowledge construction and its foundational ideas needs to be evident. As we transfer ahead, we’ll dive into its implementations, shedding mild on how these elementary rules translate into sensible code.
The way to Implement a Stack from Scratch in Python
Having grasped the foundational rules behind stacks, it is time to roll up our sleeves and delve into the sensible aspect of issues. Implementing a stack, whereas easy, may be approached in a number of methods. On this part, we’ll discover two main strategies of implementing a stack – utilizing arrays and linked lists.
Implementing a Stack Utilizing Arrays
Arrays, being contiguous reminiscence areas, supply an intuitive means to signify stacks. They permit O(1) time complexity for accessing components by index, guaranteeing swift push, pop, and peek operations. Additionally, arrays may be extra reminiscence environment friendly as a result of there is no overhead of pointers as in linked lists.
Then again, conventional arrays have a hard and fast measurement, that means as soon as initialized, they can not be resized. This may result in a stack overflow if not monitored. This may be overcome by dynamic arrays (like Python’s record), which may resize, however this operation is sort of pricey.
With all that out of the best way, let’s begin implementing our stack class utilizing arrays in Python. To start with, let’s create a category itself, with the constructor that takes the scale of the stack as a parameter:
As you possibly can see, we saved three values in our class. The measurement is the specified measurement of the stack, the stack is the precise array used to signify the stack knowledge construction, and the high is the index of the final ingredient within the stack array (the highest of the stack).
Any further, we’ll create and clarify one technique for every of the fundamental stack operations. Every of these strategies will likely be contained throughout the Stack class we have simply created.
Let’s begin with the push() technique. As beforehand mentioned, the push operation provides a component to the highest of the stack. To start with, we’ll test if the stack has any area left for the ingredient we need to add. If the stack is full, we’ll elevate the Stack Overflow exception. In any other case, we’ll simply add the ingredient and regulate the high and stack accordingly:
Now, we are able to outline the tactic for eradicating a component from the highest of the stack – the pop() technique. Earlier than we even attempt eradicating a component, we might must test if there are any components within the stack as a result of there is no level in making an attempt to pop a component from an empty stack:
Lastly, we are able to outline the peek() technique that simply returns the worth of the ingredient that is at present on the highest of the stack:
defpeek(self):if self.high == -1:
elevate Exception("Stack is empty")
return self.stack[self.top]
And that is it! We now have a category that implements the habits of stacks utilizing lists in Python.
Implementing a Stack Utilizing Linked Lists
Linked lists, being dynamic knowledge buildings, can simply develop and shrink, which may be helpful for implementing stacks. Since linked lists allocate reminiscence as wanted, the stack can dynamically develop and scale back with out the necessity for express resizing. One other good thing about utilizing linked lists to implement stacks is that push and pop operations solely require easy pointer modifications. The draw back to that’s that each ingredient within the linked record has an extra pointer, consuming extra reminiscence in comparison with arrays.
Take a look at our hands-on, sensible information to studying Git, with best-practices, industry-accepted requirements, and included cheat sheet. Cease Googling Git instructions and truly study it!
As we already mentioned within the “Python Linked Lists” article, the very first thing we might must implement earlier than the precise linked record is a category for a single node:
This implementation shops solely two factors of information – the worth saved within the node (knowledge) and the reference to the subsequent node (subsequent).
Our 3-part collection about linked lists in Python:
Now we are able to hop onto the precise stack class itself. The constructor will likely be a little bit totally different from the earlier one. It’ll include just one variable – the reference to the node on the highest of the stack:
classStack:def__init__(self):
self.high = None
As anticipated, the push() technique provides a brand new ingredient (node on this case) to the highest of the stack:
Lastly, the peek() technique merely reads the worth of the ingredient from the highest of the stack (if there may be one):
defpeek(self):ifnot self.high:
elevate Exception("Stack is empty")
return self.high.knowledge
Be aware: The interface of each Stack lessons is identical – the one distinction is the interior implementation of the category strategies. Meaning that you would be able to simply change between totally different implementations with out the concern concerning the internals of the lessons.
The selection between arrays and linked lists is determined by the precise necessities and constraints of the appliance.
The way to Implement a Stack utilizing Python’s Constructed-in Constructions
For a lot of builders, constructing a stack from scratch, whereas academic, is probably not essentially the most environment friendly method to make use of a stack in real-world purposes. Happily, many standard programming languages come outfitted with in-built knowledge buildings and lessons that naturally assist stack operations. On this part, we’ll discover Python’s choices on this regard.
Python, being a flexible and dynamic language, would not have a devoted stack class. Nonetheless, its built-in knowledge buildings, notably lists and the deque class from the collections module, can effortlessly function stacks.
Utilizing Python Lists as Stacks
Python lists can emulate a stack fairly successfully resulting from their dynamic nature and the presence of strategies like append() and pop().
Push Operation – Including a component to the highest of the stack is so simple as utilizing the append() technique:
stack = []
stack.append('A')
stack.append('B')
Pop Operation – Eradicating the topmost ingredient may be achieved utilizing the pop() technique with none argument:
top_element = stack.pop()
Peek Operation Accessing the highest with out popping may be performed utilizing detrimental indexing:
top_element = stack[-1]
Utilizing deque Class from collections Module
The deque (quick for double-ended queue) class is one other versatile software for stack implementations. It is optimized for quick appends and pops from each ends, making it barely extra environment friendly for stack operations than lists.
Initialization:
from collections import deque
stack = deque()
Push Operation – Much like lists, append() technique is used:
stack.append('A')
stack.append('B')
Pop Operation – Like lists, pop() technique does the job:
top_element = stack.pop()
Peek Operation – The strategy is identical as with lists:
top_element = stack[-1]
When To Use Which?
Whereas each lists and deques can be utilized as stacks, in the event you’re primarily utilizing the construction as a stack (with appends and pops from one finish), the deque may be barely quicker resulting from its optimization. Nonetheless, for many sensible functions and until coping with performance-critical purposes, Python’s lists ought to suffice.
Be aware: This part dives into Python’s built-in choices for stack-like habits. You do not essentially must reinvent the wheel (by implementing stack from scratch) when you’ve got such highly effective instruments at your fingertips.
Potential Stack-Associated Points and The way to Overcome Them
Whereas stacks are extremely versatile and environment friendly, like every other knowledge construction, they don’t seem to be proof against potential pitfalls. It is important to acknowledge these challenges when working with stacks and have methods in place to deal with them. On this part, we’ll dive into some frequent stack-related points and discover methods to beat them.
Stack Overflow
This happens when an try is made to push a component onto a stack that has reached its most capability. It is particularly a problem in environments the place stack measurement is mounted, like in sure low-level programming situations or recursive operate calls.
When you’re utilizing array-based stacks, contemplate switching to dynamic arrays or linked-list implementations, which resize themselves. One other step in prevention of the stack overflow is to repeatedly monitor the stack’s measurement, particularly earlier than push operations, and supply clear error messages or prompts for stack overflows.
If stack overflow occurs resulting from extreme recursive calls, contemplate iterative options or enhance the recursion restrict if the atmosphere permits.
Stack Underflow
This occurs when there’s an try and pop a component from an empty stack. To stop this from occurring, all the time test if the stack is empty earlier than executing pop or peek operations. Return a transparent error message or deal with the underflow gracefully with out crashing this system.
In environments the place it is acceptable, contemplate returning a particular worth when popping from an empty stack to suggest the operation’s invalidity.
Reminiscence Constraints
In memory-constrained environments, even dynamically resizing stacks (like these based mostly on linked lists) would possibly result in reminiscence exhaustion in the event that they develop too giant. Due to this fact, control the general reminiscence utilization of the appliance and the stack’s progress. Maybe introduce a comfortable cap on the stack’s measurement.
Thread Security Considerations
In multi-threaded environments, simultaneous operations on a shared stack by totally different threads can result in knowledge inconsistencies or sudden behaviors. Potential options to this drawback is perhaps:
Mutexes and Locks – Use mutexes (mutual exclusion objects) or locks to make sure that just one thread can carry out operations on the stack at a given time.
Atomic Operations – Leverage atomic operations, if supported by the atmosphere, to make sure knowledge consistency throughout push and pop operations.
Thread-local Stacks – In situations the place every thread wants its stack, think about using thread-local storage to offer every thread its separate stack occasion.
Whereas stacks are certainly highly effective, being conscious of their potential points and actively implementing options will guarantee strong and error-free purposes. Recognizing these pitfalls is half the battle – the opposite half is adopting greatest practices to deal with them successfully.
Authors: Augusto Cerqua, Marco Letta, Gabriele Pinto
studying (ML) has gained a central position in economics, the social sciences, and enterprise decision-making. Within the public sector, ML is more and more used for so-called prediction coverage issues: settings the place policymakers purpose to establish items most susceptible to a adverse consequence and intervene proactively; for example, focusing on public subsidies, predicting native recessions, or anticipating migration patterns. Within the non-public sector, related predictive duties come up when companies search to forecast buyer churn, or optimize credit score danger evaluation. In each domains, higher predictions translate into extra environment friendly allocation of sources and simpler interventions.
To realize these targets, ML algorithms are more and more utilized to panel information, characterised by repeated observations of the identical items over a number of time durations. Nonetheless, ML fashions weren’t initially designed to be used with panel information, which function distinctive cross-sectional and longitudinal dimensions. When ML is utilized to panel information, there’s a excessive danger of a delicate however major problem: information leakage. This happens when info unavailable at prediction time by accident enters the mannequin coaching course of, inflating predictive efficiency. In our paper “On the Mis(Use) of Machine Studying With Panel Knowledge” (Cerqua, Letta, and Pinto, 2025), just lately revealed within the Oxford Bulletin of Economics and Statistics, we offer the primary systematic evaluation of knowledge leakage in ML with panel information, suggest clear pointers for practitioners, and illustrate the implications by way of an empirical utility with publicly accessible U.S. county information.
The Leakage Drawback
Panel information mix two constructions: a temporal dimension (items noticed throughout time) and a cross-sectional dimension (a number of items, equivalent to areas or companies). Customary ML observe, splitting the pattern randomly into coaching and testing units, implicitly assumes unbiased and identically distributed (i.i.d.) information. This assumption is violated when default ML procedures (equivalent to a random break up) are utilized to panel information, creating two primary sorts of leakage:
Temporal leakage: future info leaks into the mannequin through the coaching section, making forecasts look unrealistically correct. Moreover, previous info can find yourself within the testing set, making ‘forecasts’ retrospective.
Cross-sectional leakage: the identical or very related items seem in each coaching and testing units, that means the mannequin has already “seen” a lot of the cross-sectional dimension of the information.
Determine 1 reveals how totally different splitting methods have an effect on the chance of leakage. A random break up on the unit–time degree (Panel A) is probably the most problematic, because it introduces each temporal and cross-sectional leakage. Alternate options equivalent to splitting by items (Panel B), by teams (Panel C), or by time (Panel D), mitigate one kind of leakage however not the opposite. Because of this, no technique utterly eliminates the issue: the suitable selection depends upon the duty at hand (see beneath), since in some circumstances one type of leakage might not be an actual concern.
Determine 1 | Coaching and testing units underneath totally different splitting guidelines
Notes: On this instance, the panel information are structured with years because the time variable, counties because the unit variable, and states because the group variable. Picture made by the authors.
Two Varieties of Prediction Coverage Issues
A key perception of the examine is that researchers should clearly outline their prediction objective ex-ante. We distinguish two broad courses of prediction coverage issues:
1. Cross-sectional prediction: The duty is to map outcomes throughout items in the identical interval. For instance, imputing lacking information on GDP per capita throughout areas when just some areas have dependable measurements. The very best break up right here is on the unit degree: totally different items are assigned to coaching and testing units, whereas all time durations are saved. This eliminates cross-sectional leakage, though temporal leakage stays. However since forecasting just isn’t the objective, this isn’t an actual challenge.
2. Sequential forecasting: The objective is to foretell future outcomes primarily based on historic information—for instance, predicting county-level earnings declines one yr forward to set off early interventions. Right here, the right break up is by time: earlier durations for coaching, later durations for testing. This avoids temporal leakage however not cross-sectional leakage, which isn’t an actual concern because the similar items are being forecasted throughout time.
The improper strategy in each circumstances is the random break up by unit-time (Panel A of Determine 1), which contaminates outcomes with each sorts of leakage and produces misleadingly excessive efficiency metrics.
Sensible Tips
To assist practitioners, we summarize a set of do’s and don’ts for making use of ML to panel information:
Select the pattern break up primarily based on the analysis query: unit-based for cross-sectional issues, time-based for forecasting.
Temporal leakage can happen not solely by way of observations, but in addition by way of predictors. For forecasting, solely use lagged or time-invariant predictors. Utilizing contemporaneous variables (e.g., utilizing unemployment in 2014 to foretell earnings in 2014) is conceptually improper and creates temporal information leakage.
Adapt cross-validation to panel information. Random k-fold CV present in most ready-to-use software program packages is inappropriate, because it mixes future and previous info. As an alternative, use rolling or increasing home windows for forecasting, or stratified CV by items/teams for cross-sectional prediction.
Be certain that out-of-sample efficiency is examined on actually unseen information, not on information already encountered throughout coaching.
Empirical Software
As an instance these points, we analyze a balanced panel of three,058 U.S. counties from 2000 to 2019, focusing solely on sequential forecasting. We contemplate two duties: a regression drawback—forecasting per capita earnings—and a classification drawback—forecasting whether or not earnings will decline within the subsequent yr.
We run a whole bunch of fashions, various break up methods, use of contemporaneous predictors, inclusion of lagged outcomes, and algorithms (Random Forest, XGBoost, Logit, and OLS). This complete design permits us to quantify how leakage inflates efficiency. Determine 2 beneath stories our primary findings.
Panel A of Determine 2 reveals forecasting efficiency for classification duties. Random splits yield very excessive accuracy, however that is illusory: the mannequin has already seen related information throughout coaching.
Panel B reveals forecasting efficiency for regression duties. As soon as once more, random splits make fashions look much better than they are surely, whereas appropriate time-based splits present a lot decrease, but sensible, accuracy.
Determine 2 | Temporal leakage within the forecasting drawback
Panel A – Classification activity
Panel B – Regression activity
Within the paper, we additionally present that the overestimation of mannequin accuracy turns into considerably extra pronounced throughout years marked by distribution shifts and structural breaks, such because the Nice Recession, making the outcomes notably deceptive for coverage functions.
Why It Issues
Knowledge leakage is greater than a technical pitfall; it has real-world penalties. In coverage functions, a mannequin that appears extremely correct throughout validation could collapse as soon as deployed, resulting in misallocated sources, missed crises, or misguided focusing on. In enterprise settings, the identical challenge can translate into poor funding selections, inefficient buyer focusing on, or false confidence in danger assessments. The hazard is very acute when machine studying fashions are supposed to function early-warning programs, the place misplaced belief in inflated efficiency may end up in pricey failures.
In contrast, correctly designed fashions, even when much less correct on paper, present trustworthy and dependable predictions that may meaningfully inform decision-making.
Takeaway
ML has the potential to rework decision-making in each coverage and enterprise, however provided that utilized accurately. Panel information supply wealthy alternatives, but are particularly susceptible to information leakage. To generate dependable insights, practitioners ought to align their ML workflow with the prediction goal, account for each temporal and cross-sectional constructions, and use validation methods that forestall overoptimistic assessments and an phantasm of excessive accuracy. When these ideas are adopted, fashions keep away from the lure of inflated efficiency and as an alternative present steering that genuinely helps policymakers allocate sources and companies make sound strategic decisions. Given the speedy adoption of ML with panel information in each private and non-private domains, addressing these pitfalls is now a urgent precedence for utilized analysis.
References
A. Cerqua, M. Letta, and G. Pinto, “On the (Mis)Use of Machine Studying With Panel Knowledge”, Oxford Bulletin of Economics and Statistics (2025): 1–13, https://doi.org/10.1111/obes.70019.
This week, AWS introduced to its workers that there can be a brand new vp on the town: Chet Kapoor was becoming a member of the tech large’s cloud arm to supervise safety providers and observability in direct response to AWS’s concern that “AI is totally altering what is feasible and what’s wanted on this space.”
On the face of it, the appointment appears routine, particularly contemplating the dimensions of AWS’s operations and its reported base of roughly 143,000 workers. However, notably, the brand new function comes with an elevated diploma of seniority, reporting on to the CEO and dealing alongside CISO Amy Herzog, versus underneath her. Whereas many enterprises have been exploring a extra horizontal hierarchical construction in what’s been termed The Nice Flattening, this new job has prompted a brand new query: What does it appear like to be chargeable for AI safety? And who inside the group is finally accountable?
“AI expands the assault floor and the CISO/CIO mandate,” stated Diana Kelley, CISO at Noma Safety. “Proper now, the scope of AI safety is so specialised that anticipating CISOs to soak up it totally underneath current constructions is an enormous leap.”
Fixing a Downside vs. Getting Forward of Threats
The overall response from IT leaders to the AWS rent is optimistic, with a number of CISOs describing it as an indication that the corporate is taking AI threats critically and is dedicated to constructing operations that work inside established guardrails. Somewhat than being a transfer to repair a selected flaw in safety, executives stated it’s a part of an ongoing funding in wholesome cybersecurity apply — one which should now grapple with a completely new menace within the type of AI-supported assaults.
Dan Lohrmann, area CISO for public sector at Presidio, famous that AWS has taken “many optimistic steps” to safe its programs, knowledge, and networks, including that the explosion of AI use calls for new vigilance.
“As we transfer ahead into 2026, the breadth and depth of AI alternatives, merchandise, and threats globally current a paradigm shift in cyber protection,” Lohrmann stated. He added that he was inspired by AWS’s recognition of the necessity for extra focus and a spotlight (and staffing) on these cyberthreats.
Edward Liebig, CEO of Yoink Industries and founding father of OT SOC Choices, agreed. He described the transfer as not simply “good and overdue,” but additionally an inevitable evolution in cybersecurity administration now that AI has entered the sphere.
“AWS is not simply filling a place; they’re formalizing a brand new layer of accountability,” Liebig stated. “It is the clearest signal but that AI safety is not an experimental self-discipline however a core operational requirement.”
Certainly, the AWS rent displays a broader ripple out there: Enterprises throughout industries are acknowledging that AI — and notably agentic AI — is not solely getting used for optimistic ends. It is usually being wielded maliciously and relentlessly by menace actors.
“Agentic AI attackers can now function with a ‘reflection loop’ so they’re successfully self-learning from failed assaults and modifying their assault strategy mechanically,” stated Simon Ratcliffe, fractional CIO at Freeman Clarke. “This implies the assaults are quicker and there are extra of them … placing overwhelming stress on CISOs to reply.”
Lohrmann stated he believes present cybersecurity fashions merely aren’t satisfactory to satisfy this new species of menace, particularly now that they’re coming at unprecedented velocity. He beneficial a complete system replace, one that may proceed to pose challenges over the following few years. Kelley, however, stated she believes that whereas conventional measures stay “foundational,” in addition they should be supplemented with AI-specific approaches.
“Zero belief, least privilege, and protection in depth — they have been constructed for deterministic programs. AI breaks that paradigm,” she stated. Fashions make probabilistic selections; they be taught from knowledge which may be opaque, and their “assault floor” is not restricted to code or APIs, she defined.
“What we want now’s AI-aware safety governance: a fusion of conventional controls with discovery, stock, and steady monitoring of AI belongings,” Kelley stated.
It could solely be a number of years down the street earlier than IT leaders uncover the best strategy to fight AI assaults. What is evident is that whichever technique a corporation pursues, there’s a number of work to be performed. So who takes that duty on?
The Accountability Query
Previous to AI coming into the sphere at scale, CIOs and CISOs have been the established homeowners of enterprise know-how and safety. Executives in these roles are sometimes the primary to acknowledge that cybersecurity now requires totally new approaches — and doubtlessly new talent units.
Earlier than the AWS announcement, there have been already some high-profile new roles being created round AI administration, comparable to chief AI officer. However this particular vp function at AWS — and its place inside the broader construction — displays a shifting perspective on who needs to be proudly owning the AI ingredient of cybersecurity. Can — and will — the CIO or CISO be anticipated to take this on themselves?
Kelley stated she is assured the CISO has the essential function to play, so long as it’s reshaped with key understandings in thoughts.
“I feel the CISO’s function will evolve to satisfy the broader governance ecosystem, bringing collectively AI safety specialists, knowledge scientists, compliance officers, and ethics leads,” she stated, including cybersecurity’s mantra that AI safety is everybody’s enterprise.
“But it surely calls for devoted experience,” she stated. “Going ahead, I hope that organizations deal with AI governance and assurance as integral components of cybersecurity, not siloed add-ons.”
Lohrmann stated he sees a future that shares cybersecurity duty throughout each CISO and AI-specific roles. Some enterprises could divide the duties amongst a number of leaders, splitting the safety of services from the safety of their networks and workers.
In Liebig’s opinion, the way forward for cybersecurity management appears to be like much less hierarchical than it does now.
“As for who owns that threat, I consider the CISO stays accountable, however new roles are rising to operationalize AI integrity — mannequin threat officers, AI safety architects, and governance engineers,” he defined. “The CISO’s function ought to broaden horizontally, guaranteeing AI aligns to enterprise belief frameworks, not stand other than them.”
It is Ratcliffe who stays essentially the most satisfied of the CISO’s function and duty, inside the context of the AI menace. To him, creating new roles is the flawed observe to take altogether, he defined. As an alternative, it is about preventing AI with AI.
“Including an individual towards the machines which can be attacking isn’t actually going to make a lot distinction,” he stated. “It means the CISOs must undertake AI themselves to struggle again. The one factor that may cease AI is AI on the opposite facet.”
OpenAI hasn’t launched an open-weight language mannequin since GPT-2 again in 2019. Six years later, they shocked everybody with two: gpt-oss-120b and the smaller gpt-oss-20b.
Naturally, we wished to know — how do they really carry out?
To seek out out, we ran each fashions via our open-source workflow optimization framework, syftr. It evaluates fashions throughout totally different configurations — quick vs. low-cost, excessive vs. low accuracy — and consists of help for OpenAI’s new “considering effort” setting.
In concept, extra considering ought to imply higher solutions. In follow? Not all the time.
Our first outcomes with GPT-OSS may shock you: the most effective performer wasn’t the largest mannequin or the deepest thinker.
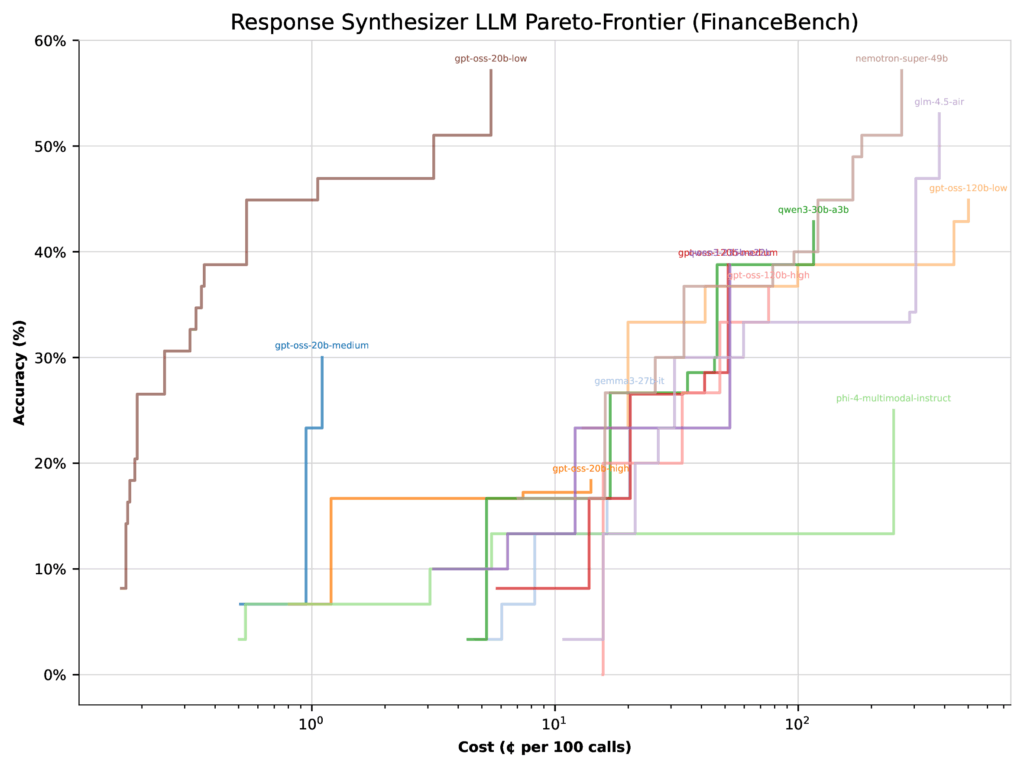
As an alternative, the 20b mannequin with low considering effort persistently landed on the Pareto frontier, even rivaling the 120b medium configuration on benchmarks like FinanceBench, HotpotQA, and MultihopRAG. In the meantime, excessive considering effort not often mattered in any respect.
How we arrange our experiments
We didn’t simply pit GPT-OSS in opposition to itself. As an alternative, we wished to see the way it stacked up in opposition to different sturdy open-weight fashions. So we in contrast gpt-oss-20b and gpt-oss-120b with:
qwen3-235b-a22b
glm-4.5-air
nemotron-super-49b
qwen3-30b-a3b
gemma3-27b-it
phi-4-multimodal-instruct
To check OpenAI’s new “considering effort” function, we ran every GPT-OSS mannequin in three modes: low, medium, and excessive considering effort. That gave us six configurations in complete:
gpt-oss-120b-low / -medium / -high
gpt-oss-20b-low / -medium / -high
For analysis, we solid a large web: 5 RAG and agent modes, 16 embedding fashions, and a variety of circulate configuration choices. To evaluate mannequin responses, we used GPT-4o-mini and in contrast solutions in opposition to recognized floor fact.
Lastly, we examined throughout 4 datasets:
FinanceBench (monetary reasoning)
HotpotQA (multi-hop QA)
MultihopRAG (retrieval-augmented reasoning)
PhantomWiki (artificial Q&A pairs)
We optimized workflows twice: as soon as for accuracy + latency, and as soon as for accuracy + price—capturing the tradeoffs that matter most in real-world deployments.
Optimizing for latency, price, and accuracy
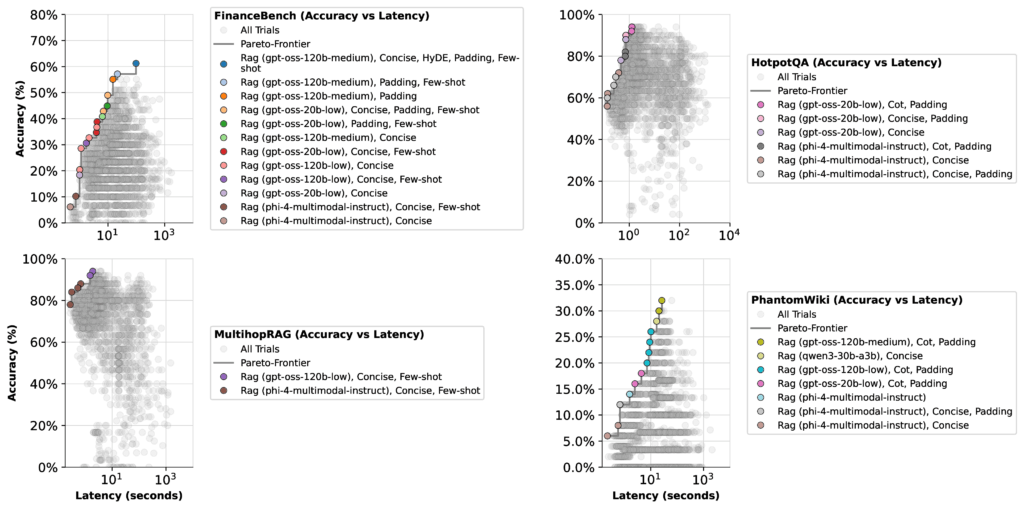
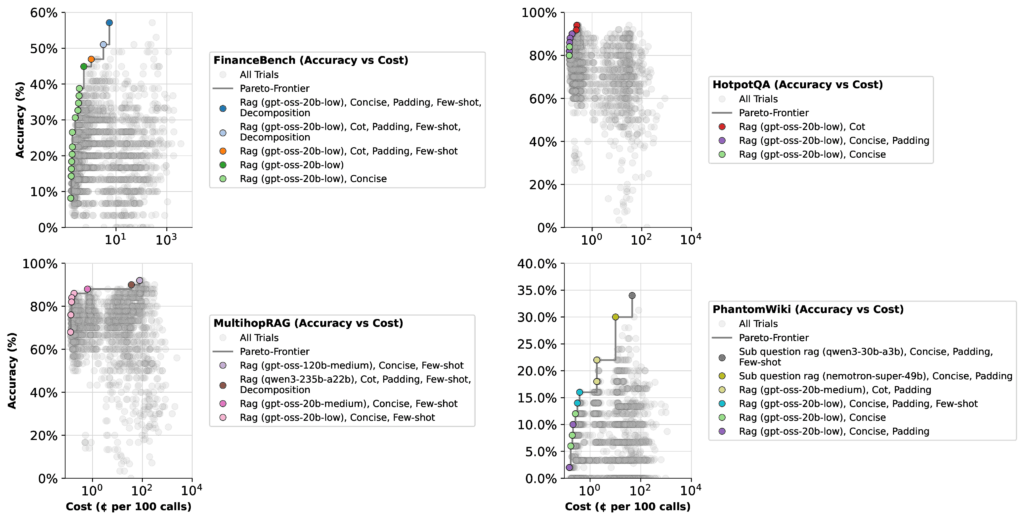
After we optimized the GPT-OSS fashions, we checked out two tradeoffs: accuracy vs. latency and accuracy vs. price. The outcomes have been extra shocking than we anticipated:
GPT-OSS 20b (low considering effort): Quick, cheap, and persistently correct. This setup appeared on the Pareto frontier repeatedly, making it the most effective default alternative for many non-scientific duties. In follow, meaning faster responses and decrease payments in comparison with larger considering efforts.
GPT-OSS 120b (medium considering effort): Greatest suited to duties that demand deeper reasoning, like monetary benchmarks. Use this when accuracy on complicated issues issues greater than price.
GPT-OSS 120b (excessive considering effort): Costly and normally pointless. Maintain it in your again pocket for edge circumstances the place different fashions fall brief. For our benchmarks, it didn’t add worth.
Determine 1: Accuracy-latency optimization with syftrDetermine 2: Accuracy-cost optimization with syftr
Studying the outcomes extra fastidiously
At first look, the outcomes look easy. However there’s an essential nuance: an LLM’s high accuracy rating relies upon not simply on the mannequin itself, however on how the optimizer weighs it in opposition to different fashions within the combine. As an example, let’s have a look at FinanceBench.
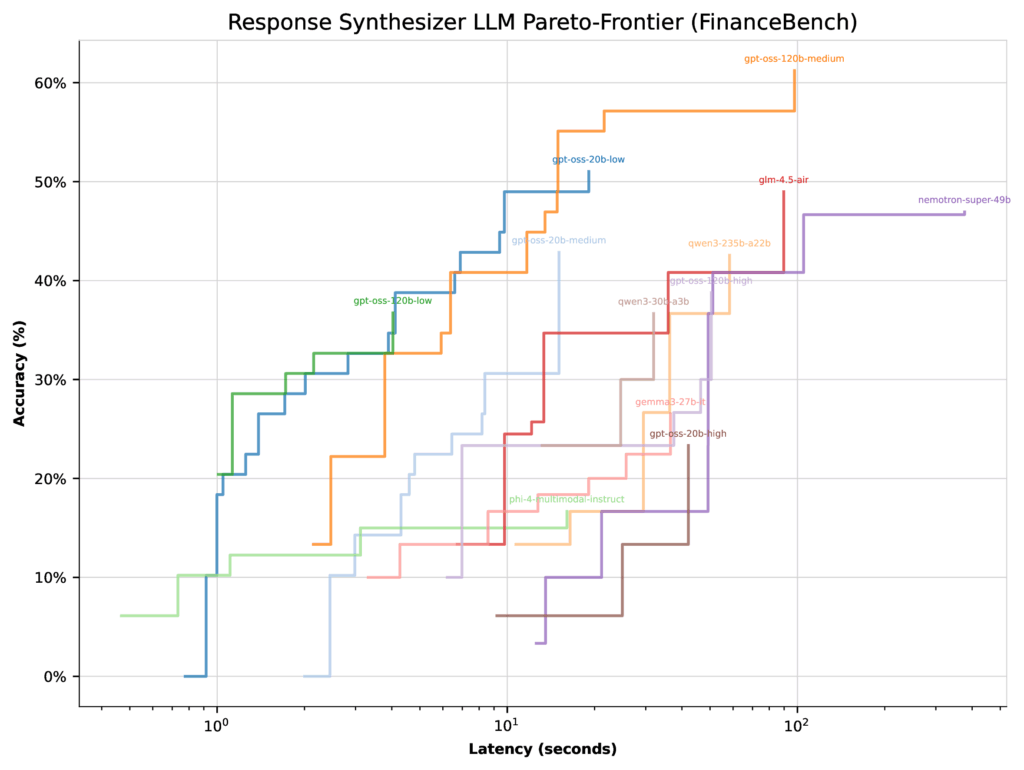
When optimizing for latency, all GPT-OSS fashions (besides excessive considering effort) landed with comparable Pareto-frontiers. On this case, the optimizer had little cause to focus on the 20b low considering configuration—its high accuracy was solely 51%.
Determine 3: Per-LLM Pareto-frontiers for latency optimization on FinanceBench
When optimizing for price, the image shifts dramatically. The identical 20b low considering configuration jumps to 57% accuracy, whereas the 120b medium configuration really drops 22%. Why? As a result of the 20b mannequin is way cheaper, so the optimizer shifts extra weight towards it.
Determine 4: Per-LLM Pareto-frontiers for price optimization on FinanceBench
The takeaway: Efficiency will depend on context. Optimizers will favor totally different fashions relying on whether or not you’re prioritizing velocity, price, or accuracy. And given the large search area of attainable configurations, there could also be even higher setups past those we examined.
Discovering agentic workflows that work properly in your setup
The brand new GPT-OSS fashions carried out strongly in our checks — particularly the 20b with low considering effort, which frequently outpaced dearer rivals. The larger lesson? Extra mannequin and extra effort doesn’t all the time imply extra accuracy. Generally, paying extra simply will get you much less.
That is precisely why we constructed syftr and made it open-source. Each use case is totally different, and the most effective workflow for you will depend on the tradeoffs you care about most. Need decrease prices? Sooner responses? Most accuracy?
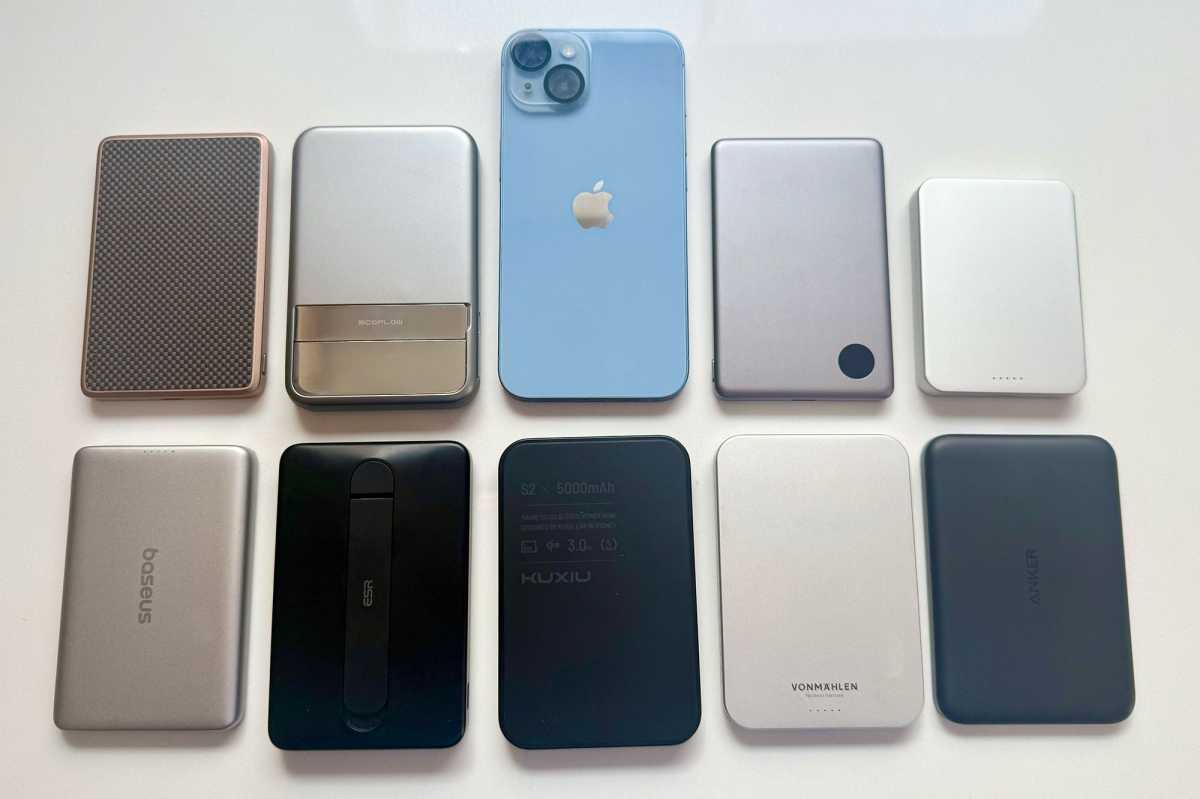
Moveable energy banks that cost your telephone are well-liked, however wi-fi battery packs utilizing Apple’s magnetic MagSafe know-how supply an easier and smarter cable-free answer for iPhone 12, 13, 14, 15, 16, 17 and Air customers.
Telephone batteries are susceptible to run dry simply once you’re heading away from an influence supply, so having a conveyable charging supply is one in all in the present day’s requirements. Annoyingly, most energy banks require you to hold round a cable, too. Wi-fi energy banks dispose of cables however include their very own main limitation—the inefficiency of wi-fi charging means you want a high-capacity energy financial institution to completely cost a drained iPhone.
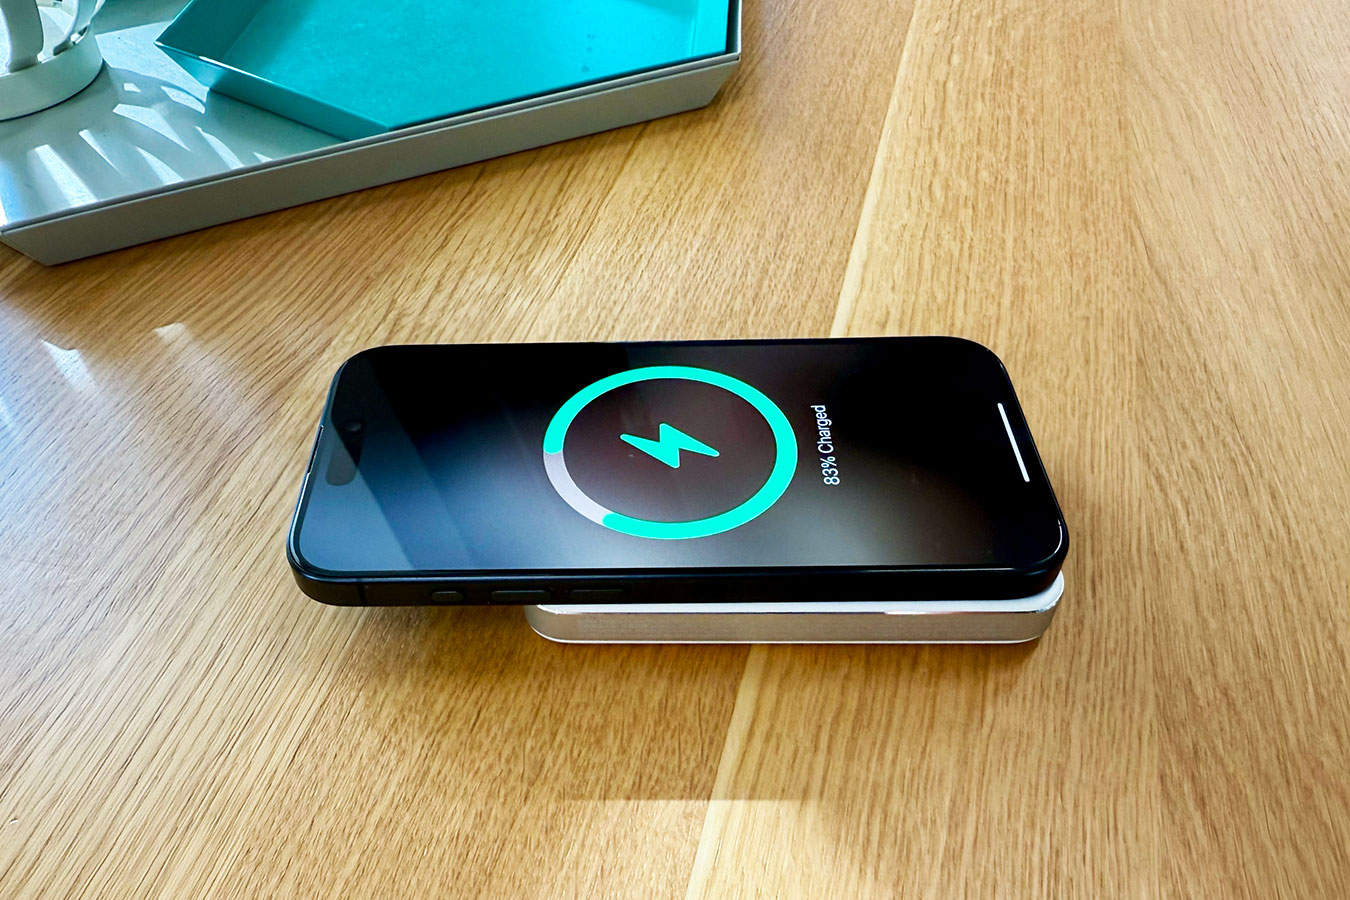
MagSafe is a know-how that’s appropriate with all iPhone 12, 13, 14, 15, 16, 17 and Air fashions, from the mini to the Professional Max, however unusually lacking from the 16e mannequin. It permits equipment to attach magnetically to the again of the iPhone. For extra data learn our Full information to Apple MagSafe: What’s MagSafe?
The MagSafe connection is exact sufficient to make wi-fi charging extra environment friendly as round 20% of non-magnetic energy loss is from poor placement of a telephone and the wi-fi charging pad. Customary Qi wi-fi charging can lose as a lot as 50% of the moveable battery’s energy, however MagSafe and Qi2 wi-fi charging loses ‘simply’ 30%. Sizzling out of the gadget laboratory, the brand new Qi 2.2 (also referred to as Qi2 25W) brings even sooner 25W wi-fi charging for the iPhone 16 and 17. 15% can be loads quick sufficient for many of us however who doesn’t need the quickest doable charging when your iPhone’s battery icon is within the purple?
Whereas it’s not as environment friendly as utilizing a cable to cost a telephone, MagSafe and Qi2 are techs that brings true wi-fi charging a step nearer to removing cables altogether. Qi2 25W brings wi-fi charging near wired’s, and a few energy banks embrace a built-in USB-C cable for even sooner charging as much as 30W.
Learn on or go straight to the very best magnetic energy banks we now have examined, listed by energy, portability and performance:
Greatest measurement magnetic energy financial institution for you
It is best to contemplate measurement relating to an influence financial institution: bodily measurement and battery capability. The upper the battery capability, the extra recharging energy you’ll get from the ability financial institution—however you’ll even be carrying round a bigger, heavier merchandise. Lighter, slimmer energy banks are simpler to pocket even when clamped to your telephone. Bigger energy banks won’t slot in your trouser pocket and might slide off simpler when pocketed even when clamped magnetically.
10K energy banks (with a 10000mAh battery capability) can cost a telephone shut to 2 instances over, whereas 5K (5000mAh) battery packs normally stretch between 60-75%, which is usually sufficient to get you to the subsequent wall-socket powering alternative. In case you are counting on the ability financial institution for long-haul journey or a tenting journey, a 10K battery or greater will go well with you higher. Belkin even presents a mid-range 8K energy financial institution.
Wi-fi energy financial institution charging pace
If an influence financial institution is rated as MagSafe Licensed it would wirelessly cost at as much as 15W. Uncertified however nonetheless “Appropriate” magnetic chargers are restricted to 7.5W, so will power-up at a slower tempo. Newer Qi2 chargers and energy banks match MagSafe at 15W. See Is Qi2 as quick as MagSafe?. Apple’s new MagSafe Charger can cost the iPhone 16 and 17 fashions at 25W and new Qi2 25W energy banks now match that pace.
We’ve listed the speeds at which every moveable energy financial institution may be charged itself (Enter charger) and cost the iPhone (Output charger). Some energy banks can cost a telephone sooner when you join a cable (most have a USB-C port and a few include their very own USB-C cable built-in), and we now have highlighted these under. The upper the wattage, the sooner the charging needs to be.
After the checklist of our favorites, you’ll discover extra particulars on how MagSafe works and why you ought to be an influence financial institution’s capability in Watt Hours relatively than the principally quoted Milliamp Hours.
Greatest high-capacity 10K MagSafe energy banks
A 10000mAh (10K) battery is the candy spot for each energy and portability. 5000mAh (5K) energy banks reviewed additional down are slimmer, lighter and simpler to pocket, however usually supply a most of 70-80% recharge potential versus a 10K energy financial institution that ought to be capable of recharge an iPhone no less than one and a half instances over.
EcoFlow RAPID Magnetic Energy Financial institution 10K – Greatest wi-fi battery pack for charging choices
This iPhone magnetic energy financial institution is our total winner as it’s a champion by way of each recharging capability and pace at which it may be recharged itself. It has a big capability, refilling a iPhone 16 Professional twice over in our exams—equalling the very best we’d seen earlier than. We run the iPhone’s battery down, recharge utilizing the ability financial institution, and hold doing this till the ability financial institution is empty.
What makes this energy financial institution particular—though not distinctive—is its quick built-in 65W USB-C cable that can be utilized for fast-charging an iPhone 15, 16 or 17 or refilling the ability financial institution itself. The cable suits neatly away when not in use on the backside of the ability financial institution.
Wirelessly it would work with any MagSafe iPhone (12/13/14/15/16/17) at 15W. iPhone 15/16/17 customers can join through the built-in USB-C cable or a separate longer cable through the facet USB-C port if required, for sooner 30W charging. House owners of earlier iPhones can use a USB-C to Lightning cable as a substitute for quick 20W wired charging from the ability financial institution’s port. Be aware that the iPhone 16e doesn’t work with magnetic wi-fi charging.
The Baseus Nomos energy financial institution, reviewed under, matches it for wi-fi charging pace as each use 15W Qi2 know-how. Additionally they boast sooner wired charging through their comparable built-in USB-C cable. In our recharging exams it beat the Nomos by spreading its 10000mAh battery capability for longer: 190% vs 166%. Nevertheless, each are crushed on charging pace by the brand new era of Qi2 25W energy banks such because the Ugreen MagFlow 10K reviewed under. That stated, the 25W energy banks we now have examined didn’t match the EcoFlow or Anker on battery capability in our exams.
Whereas the 10K Anker Zolo matched the 10K EcoFlow Fast on recharging capability in our exams, however has a slower 7.5W wi-fi charging pace.
No 10K magnetic wi-fi energy financial institution can match the EcoFlow on enter pace—that’s the price at which it’s recharged itself. Its 65W enter is far sooner than the 30W boasted by the Baseus or the 20W of the Anker.
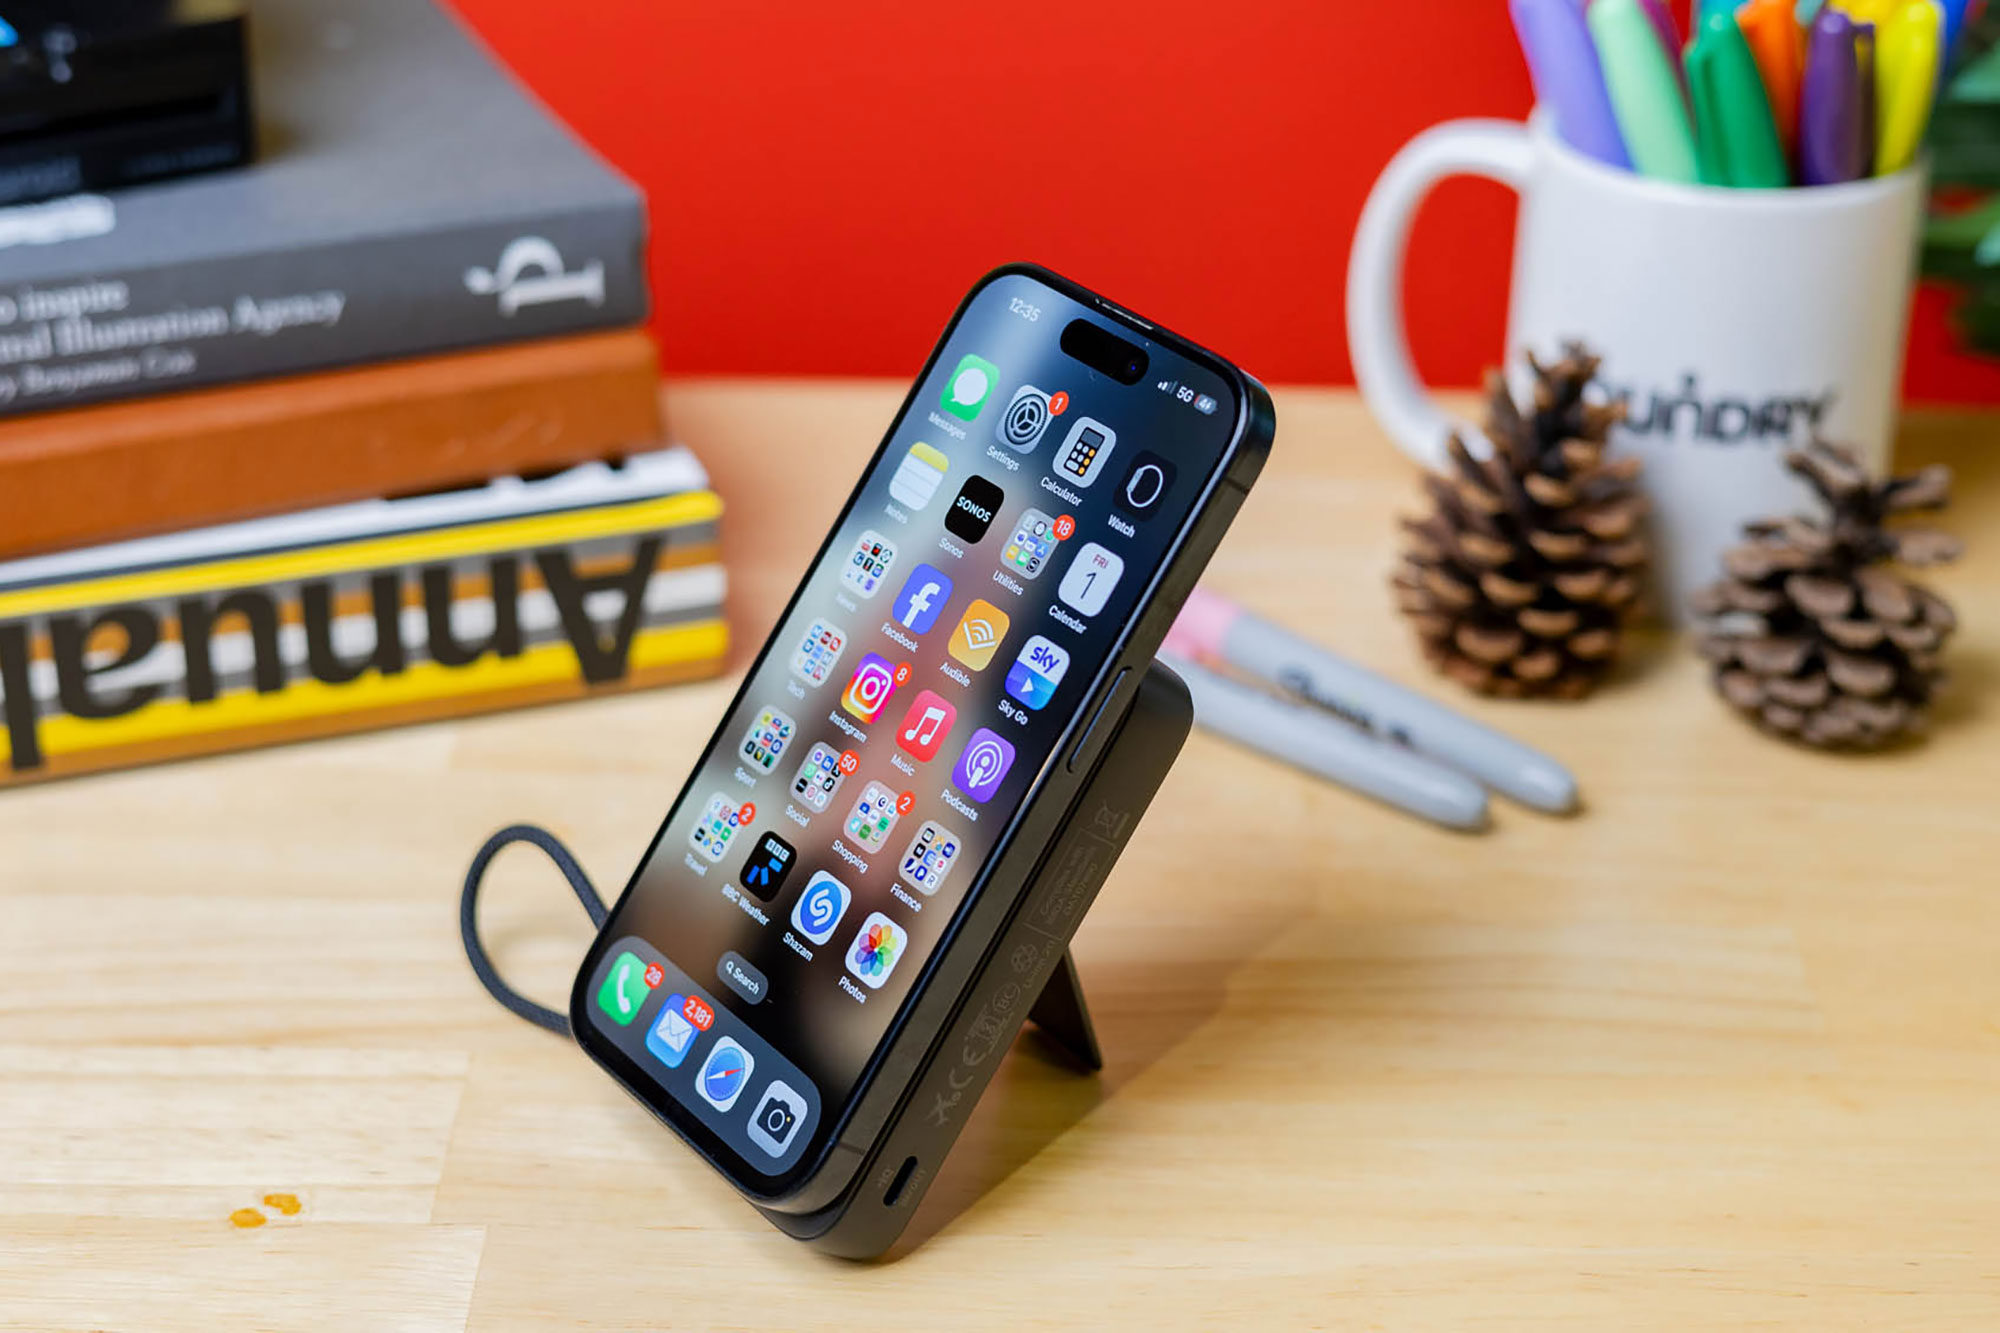
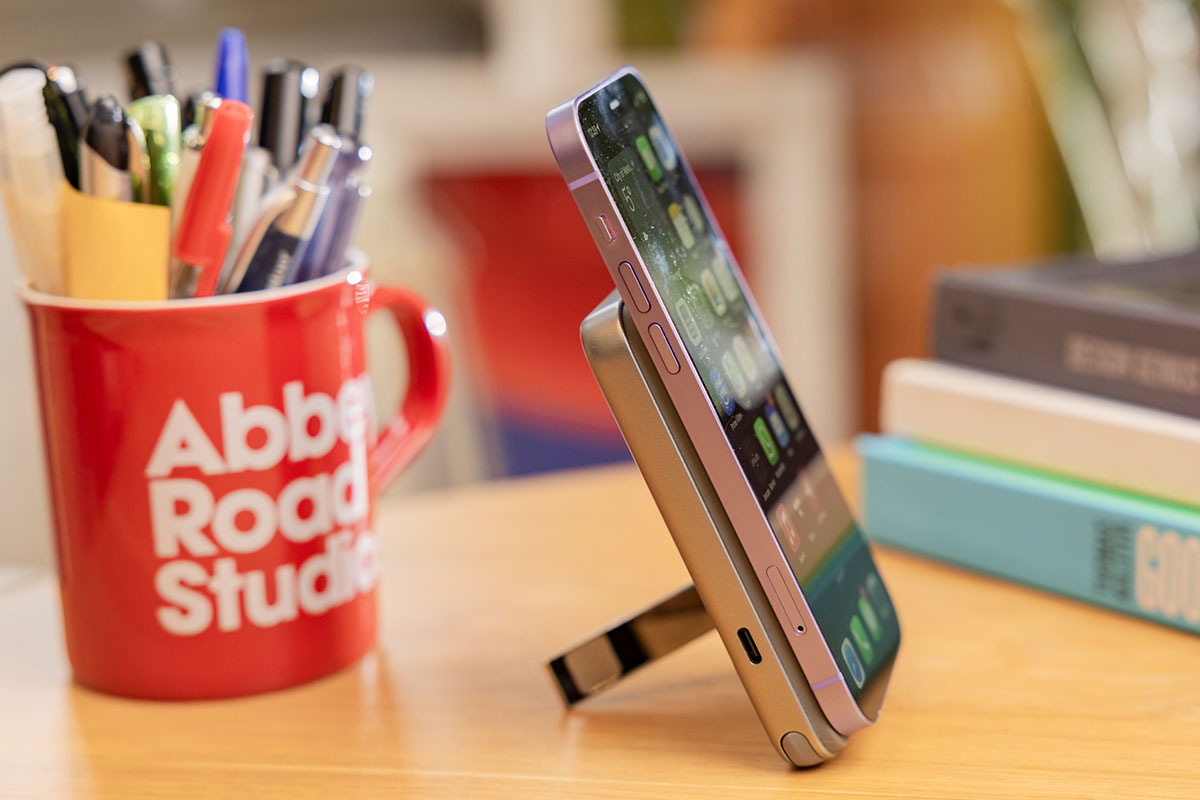
Whereas profitable on charging efficiency and capability, the EcoFlow Fast is fairly chunky in comparison with the Anker Zolo and Baseus Nomos, and notably bulkier than smaller-capacity 5K energy banks. It’s nonetheless pocketable however the barely bigger measurement is the compromise for the opposite advantages. In order for you a slimmer battery pack, search for a smaller 5000mAh choice—we’ve examined the finest slim energy banks additional on. It has a useful pull-out kickstand on the again.
This energy financial institution is clearly constructed for the iPhone 15/16/17 households—with its neat built-in USB-C cable—nevertheless it works in addition to another wi-fi energy financial institution examined right here with the opposite MagSafe iPhones, and that inbuilt cable can be utilized to cost the ability financial institution itself.
We love this iPhone magnetic energy financial institution for its massive capability, which was (albeit narrowly) the very best in our recharging exams. It refilled a light iPhone 15 Professional twice over in our exams—the very best we’ve seen. The EcoFlow Fast 10K energy financial institution was very shut in our exams, however is a bit of bigger and heavier and with a much less inexpensive price-tag.
The 10K Anker Zolo is rated at simply 7.5W for wi-fi charging as it’s only “MagSafe appropriate” relatively than utilizing licensed MagSafe or Qi2 magnetic wi-fi applied sciences. That stated, if you should recharge rapidly you should use its built-in 5.5-inch USB-C cable that can be utilized for fast-charging an iPhone 15/16/17 at 30W or refilling the ability financial institution itself at 20W. The cable may be neatly hooked right into a loop for straightforward carrying. House owners of earlier iPhones ought to use the facet USB-C port and a separate Lightning cable for 20W wired charging from the ability financial institution.
The place the Anker Zolo triumphs is its worth: it wins on capability the place it loses on charging pace, nevertheless it’s simply the very best worth when you don’t thoughts the charging pace compromise.
There are smaller-capacity 5K energy banks, however the 10K Anker Zolo continues to be very pocketable for such a high-capacity battery pack. It’s across the similar measurement as different 10000mAh MagSafe energy banks we’ve examined—apart from its sibling the Anker MagGo 10K Slim, reviewed under. Our total finest 10K magnetic energy financial institution, the EcoFlow Fast 10K, is noticeably greater, though nonetheless moveable.
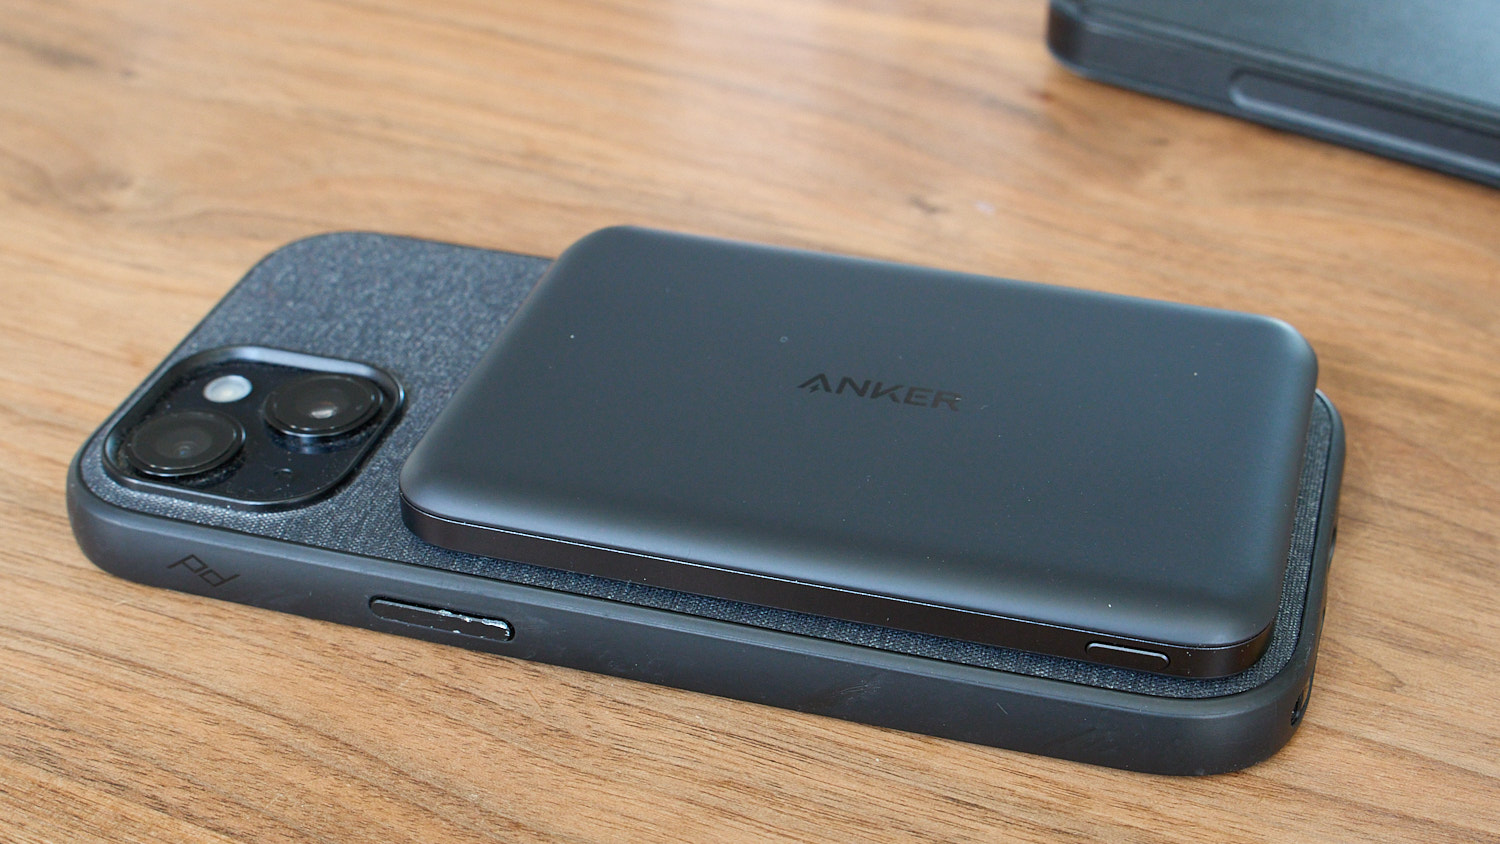
Dimensions: 4.1 x 2.7 x 0.75 inches (10.4 x 6.8 x 1.9cm)
Colours: Black
This 25W wi-fi energy financial institution lived as much as its claims of wirelessly charging an iPhone 16 Professional from 0% to 50% in 32 minutes—12 to fifteen minutes sooner than a 15W energy financial institution. That may not sound lots however once you’re in a rush to cost your telephone, each minute counts. 25W wi-fi charging is restricted to the iPhone 16 and 17 households, working no less than iOS 26; older iPhones will cost at 15W utilizing this energy financial institution.
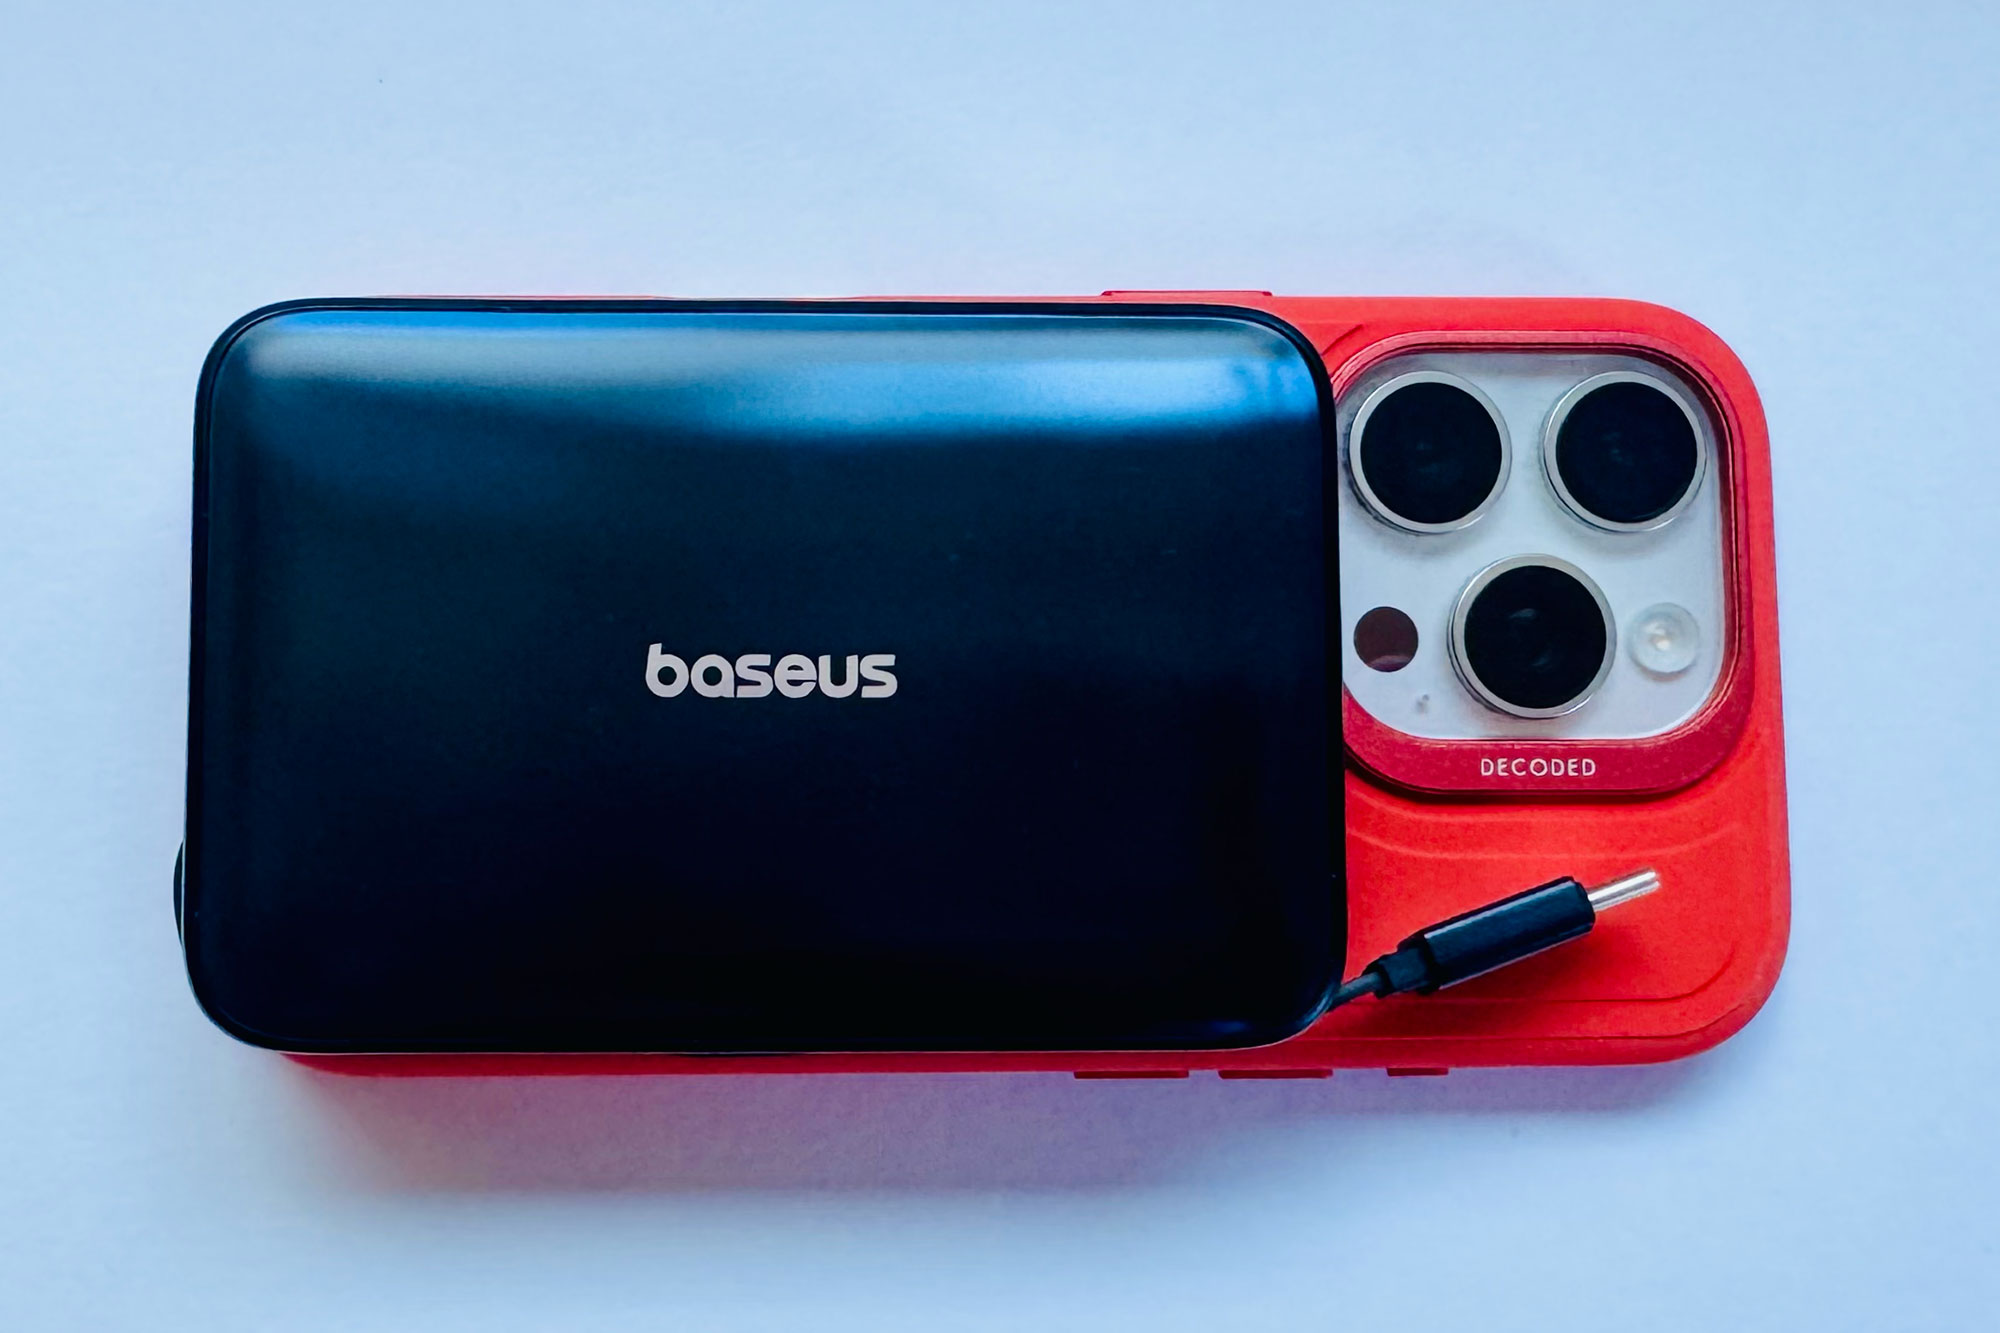
The Baseus PicoGo Magnetic 10K Energy Financial institution (AM61) is an output blazer is extra methods than one. It’s licensed Qi 2.2 so expenses wirelessly at 25W, as quick because the Ugreen MagFlow reviewed under, and just like the MagFlow additionally boasts a built-in USB-C cable. Whereas the Ugreen’s cable can wired-charge at 30W, the Baseus is rated at 45W, which is quick sufficient to maintain a MacBook going. We can be working additional exams to see how a lot recharge it may supply a MacBook; watch this area.
For those who use the wi-fi charging pad, the useful built-in USB-C cable and the spare USB-C port to concurrently cost three units—say your iPhone, Apple Watch and AirPods—complete output is restricted to 15W.
When recharging an iPhone, it refilled our take a look at 16 Professional multiple and a half instances, scoring 167% within the Macworldm Recharge Rating—going that bit additional than the Ugreen MagFlow that scored 144%. Different 10K energy banks have carried out higher: we recorded scores of 190% with the 15W EcoFlow Fast 10K and seven.5W Anker Zolo 10K, though each lag behind the Baseus by way of charging pace.
One space the place the Baseus will not be the champ is enter: the pace at which it’s recharged itself. Enter energy is 30W, which is common however nowhere close to the EcoFlow battery pack’s unmatched 65W.
The identical firm additionally sells the Baseus Nomos Magnetic 10K Energy Financial institution that, just like the PicoGo, has an built-in 45W USB-C cable, however slower 15W Qi2 wi-fi charging. Its recharge rating of 166% is remarkably near that of the 25W PicoGo. As it’s priced equally to the 25W PicoGo, the newer mannequin makes extra sense.
Ugreen MagFlow Qi2 25W Magnetic Wi-fi 10K Energy Financial institution – Tremendous-fast wi-fi energy financial institution
Execs
25W wi-fi or 30W wired charging
Giant battery capability
Constructed-in USB-C cable
Digital show
Cons
Battery capability not as nice as others examined
Worth When Reviewed:
$89.99
Greatest Costs Right this moment:
$69.99
Capability: 36Wh (10000mAh)
Enter charger: USB-C (30W)
Output charger: Wi-fi (25W) & USB-C (30W)
On take a look at charged iPhone to: 144%
Weight: 9oz (254g)
Dimensions: 4.4 x 2.8 x 0.8 inches (11.1 x 7 x 2.1cm)
Colours: Blue
This was the primary Qi2 25W wi-fi energy financial institution that we examined, and it accomplished a 50% recharge in simply over half-hour—so matching the 25W Baseus PicoGo reviewed above. It’s sooner at being recharged itself, with a 30W enter beating the PicoGo’s 20W enter.
Whole output when utilizing all three charging factors—magnetic wi-fi, USB-C cable and USB-C port—is restricted to 12.5W.
Whereas, with the Baseus PicoGo 25W, it’s the equal quickest energy financial institution at charging the iPhone, it paled a bit of in precise recharge efficiency, refilling an iPhone 16 Professional’s battery as soon as absolutely after which 44% on second recharge. That 144% recharge rating is underneath the PicoGo’s 167% and never as nice because the 190% seen with the 15W EcoFlow and seven.5W Anker Zolo wi-fi energy banks additionally reviewed above. The ability financial institution itself may be recharged at 30W, which is quicker than the PicoGo and Zolo 10K energy banks however on the 65W degree of the EcoFlow Fast.
These factors apart, the Ugreen 25W MagFlow Energy Financial institution is a super-speedy wi-fi charger for these within the greatest hurry for energy.
Dimensions: 4.1 x 2.8 x 0.58 inches (10.4 x 7.06 x 1.47cm)
Colours: Black, White, Pink, Teal
At simply 0.58 inches thick, this 10000mAh energy financial institution rivals even a number of the 5000mAh battery packs by way of slimness. It’s additionally lighter than another 10K magnetic wi-fi energy financial institution that we now have examined, and wins too on recharging energy. It’s solely the built-in USB-C cable that pushes us to advocate the Anker Zolo or Baseus energy banks for house owners of the iPhone 15/16/17. Whereas I love the built-in cables, I admit that the Anker Slim is the magnetic energy financial institution in my backpack day by day.
It makes use of quick Qi2 magnetic tech, so can wirelessly cost at a powerful 15W. When you’ve got a spare cable with you, it will probably cost at twice that pace through its USB-C port. This makes it as quick a wi-fi charger because the Baseus Nomos reviewed above. The Baseus charger is extra handy with its built-in USB-C cable, however house owners of iPhones 12/13/14 would possibly admire the flexibility so as to add a Lightning cable to the USB-C port and cost that manner. Wired charging through Lightning is restricted to 20W—a limitation set by Apple to make sure system security and efficiency, not by the cable or the ability financial institution. The newer Ugreen MagFlow is the excellent winner on wi-fi charging pace however is lots wider than this slim machine.
In our exams it carried out among the many better of the 10K magnetic energy banks we now have put by their paces: recharging an iPhone 15 Professional to 188% (over the course of two iPhone expenses from one energy financial institution cost).
It’s out there in as much as 4 colours relying in your nation and the place you purchase it—the pink and teal variations can be found solely direct from Anker.
There’s an excellent slimmer 5K Anker Nano mannequin, reviewed under.
Across the similar measurement because the Anker Zolo energy financial institution, reviewed above, the Anker MagGo Energy Financial institution (10K) didn’t fairly match that battery pack by way of recharging however was nonetheless spectacular—across the similar because the Baseus Nomos.
The place it beats the Zolo and matches the Nomos and EcoFlow Fast is in wi-fi charging pace. The Anker MagGo is licensed for the brand new Qi2 commonplace and so helps 15W wi-fi charging. This works with all MagSafe-supporting units: from the iPhone 12 to 17. (Be aware that the iPhone 12 doesn’t formally assist Qi2 however Macworld iPhone 12 Qi2 exams counsel that it does.)
The Zolo/Nomos/Fast have a barely extra highly effective cabled charging spec (30W vs Anker’s 27W) however the distinction is negligible. We just like the built-in USB-C cable included with these energy banks, however any first rate USB-C charging cable can be utilized with the MagGo to quick wire-charge an iPhone.
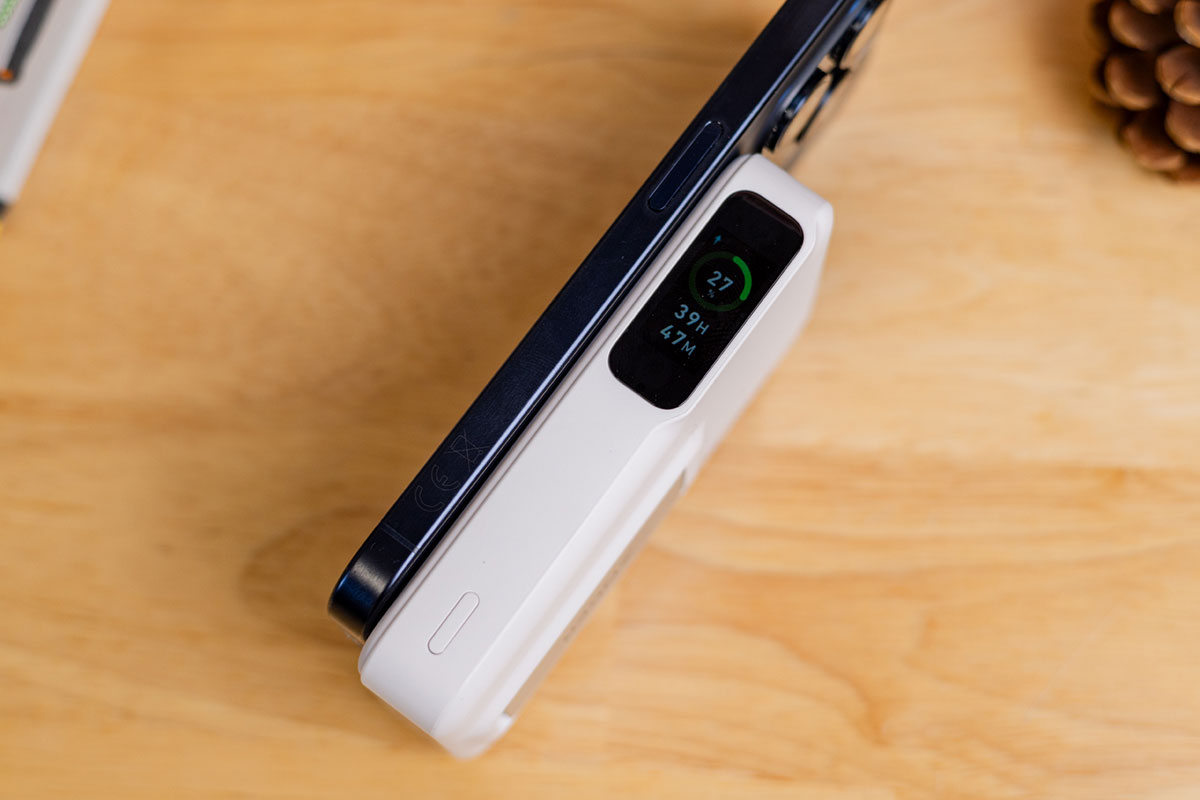
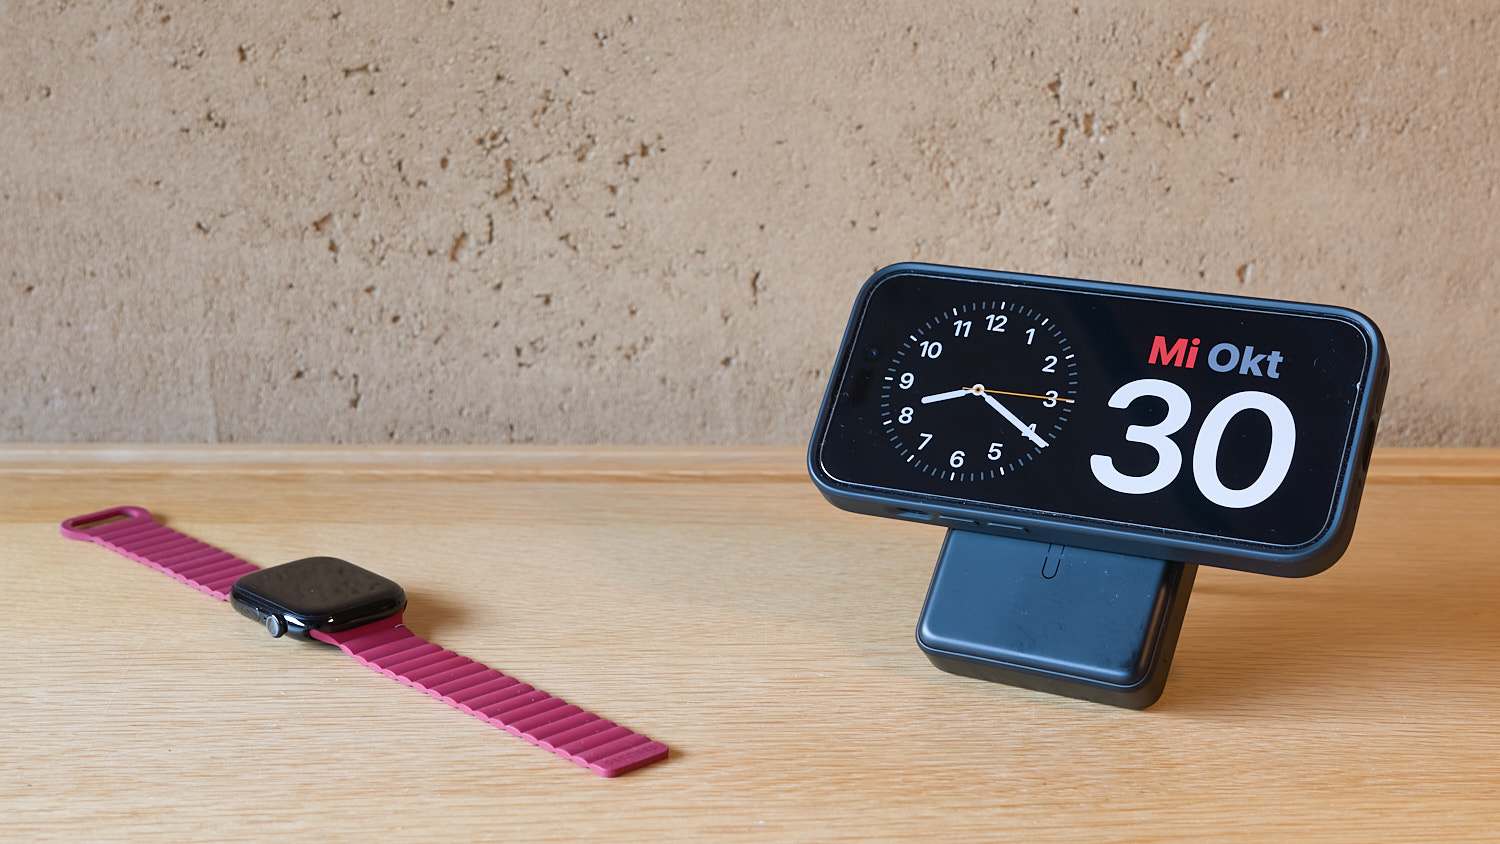
Except for sooner wi-fi charging, the Anker boasts a easy-to-read digital show that reveals you precisely how a lot cost is left within the battery pack. Seeing the precise share is way more helpful than the standard 4 LED lights seen on most energy banks. It additionally includes a stable pull-out stand on the again.
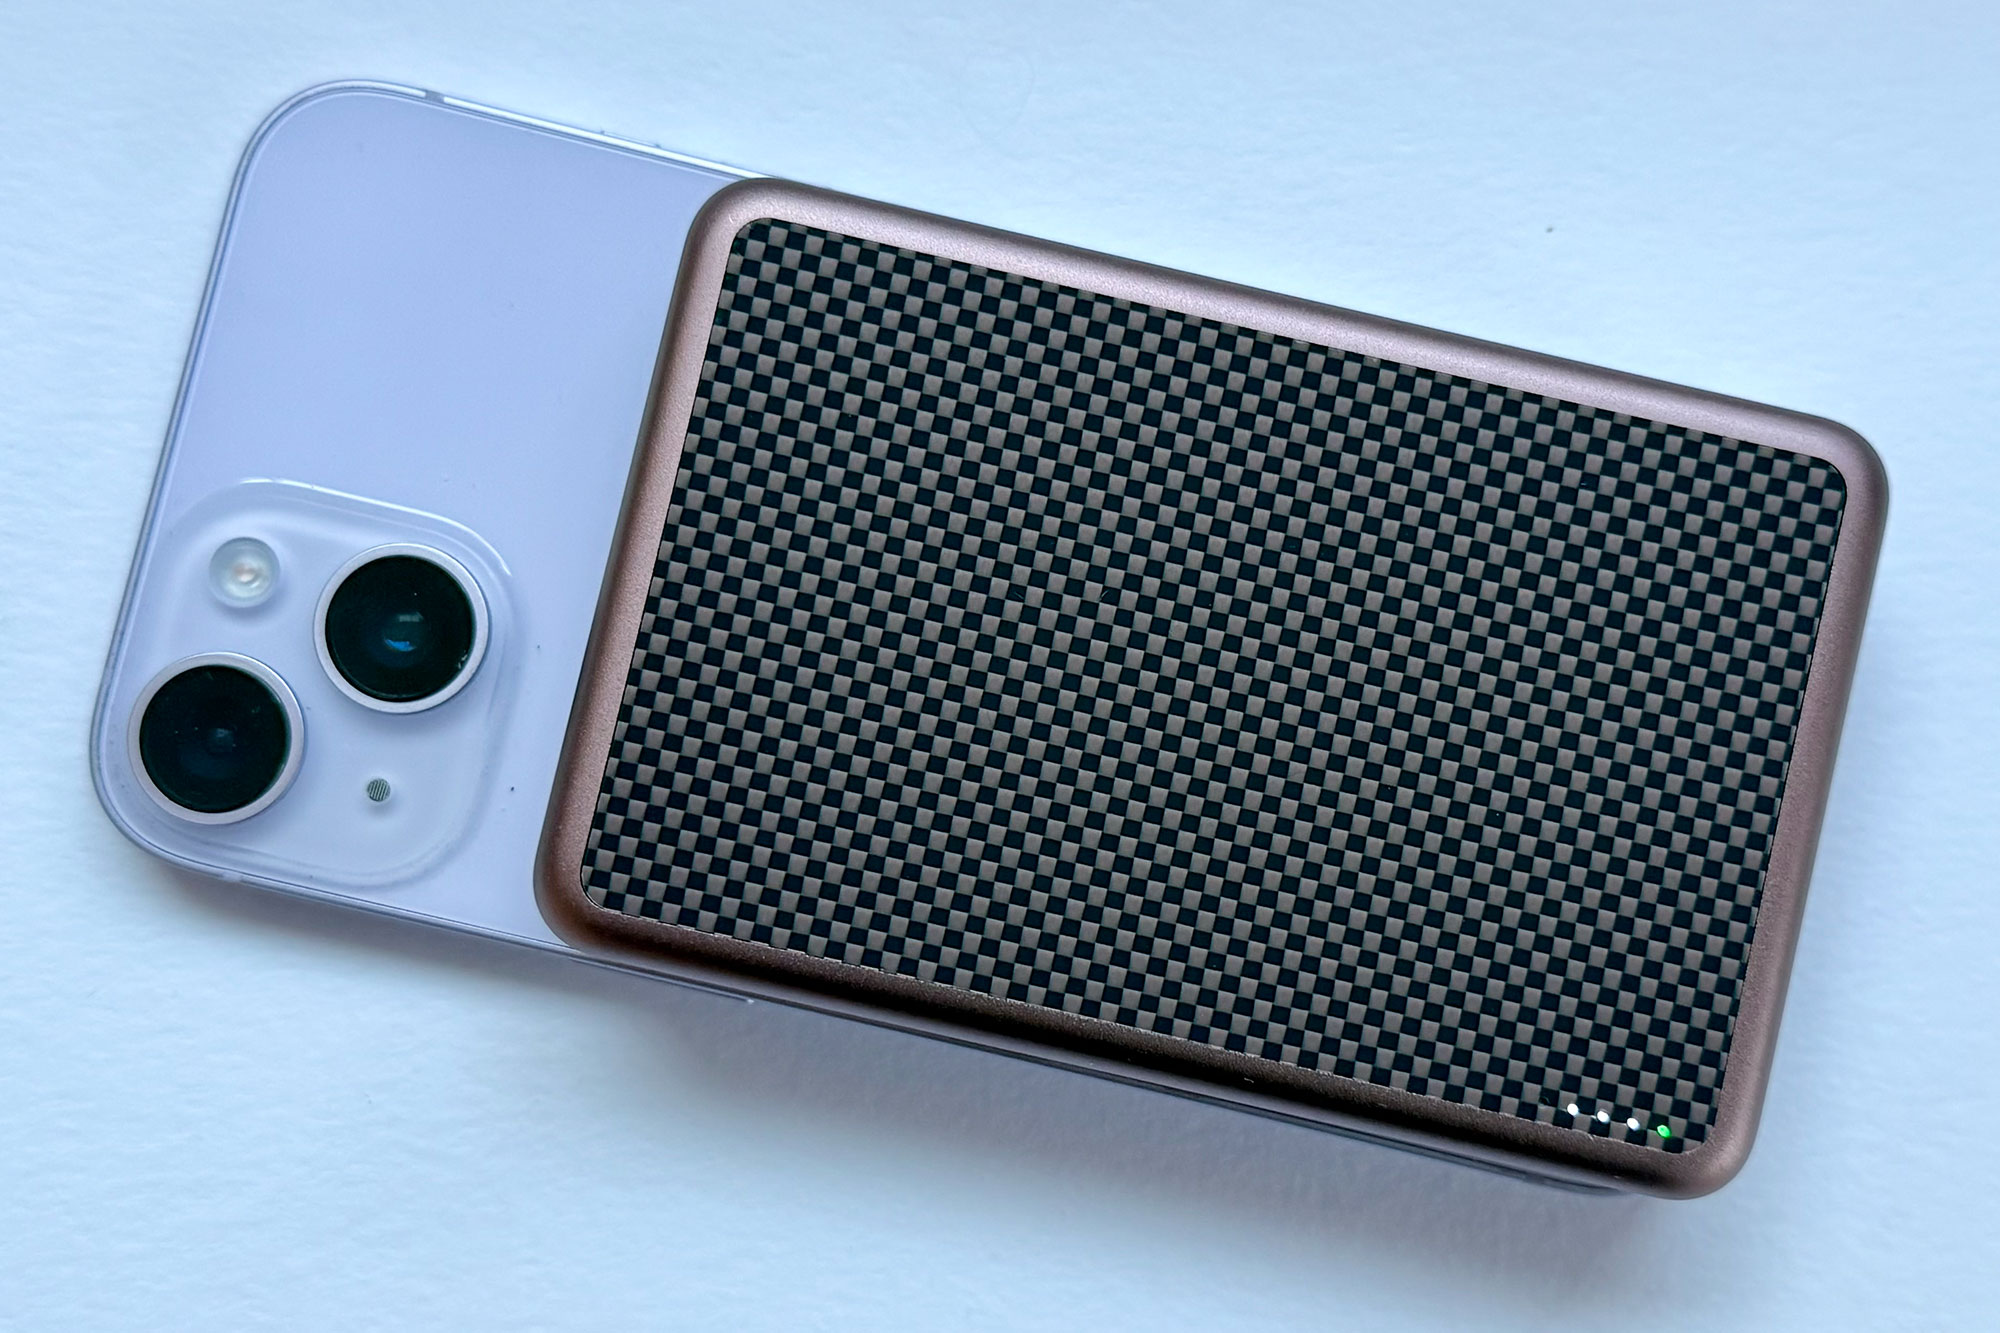
This energy financial institution stands out with its Aramid Fibre weave—a excessive energy materials that’s extra proof against warmth, cuts and abrasion than different circumstances and is usually utilized in protecting clothes and aerospace elements.
The rose gold colour additionally appears relatively good. Benks doesn’t name it that (or something) however that’s the way it appears with a delightful weave sample.
It’s Qi2 so able to 15W charging—not the quickest however what was till just lately the chopping fringe of wi-fi energy. It scored a good 165% within the Macworld recharging exams so offers you over 1.5 expenses earlier than it, too, wants filling up—which, by the best way, it takes its time doing because the 15W enter energy is lower than on different energy banks.
Benks additionally presents an equally powerful and super-slim 5K Aramid Fiber mannequin, though it’s only MagSafe Appropriate so a slower charging expertise at 7.5W. The 10K mannequin is Qi2 so sooner 15W charging energy.
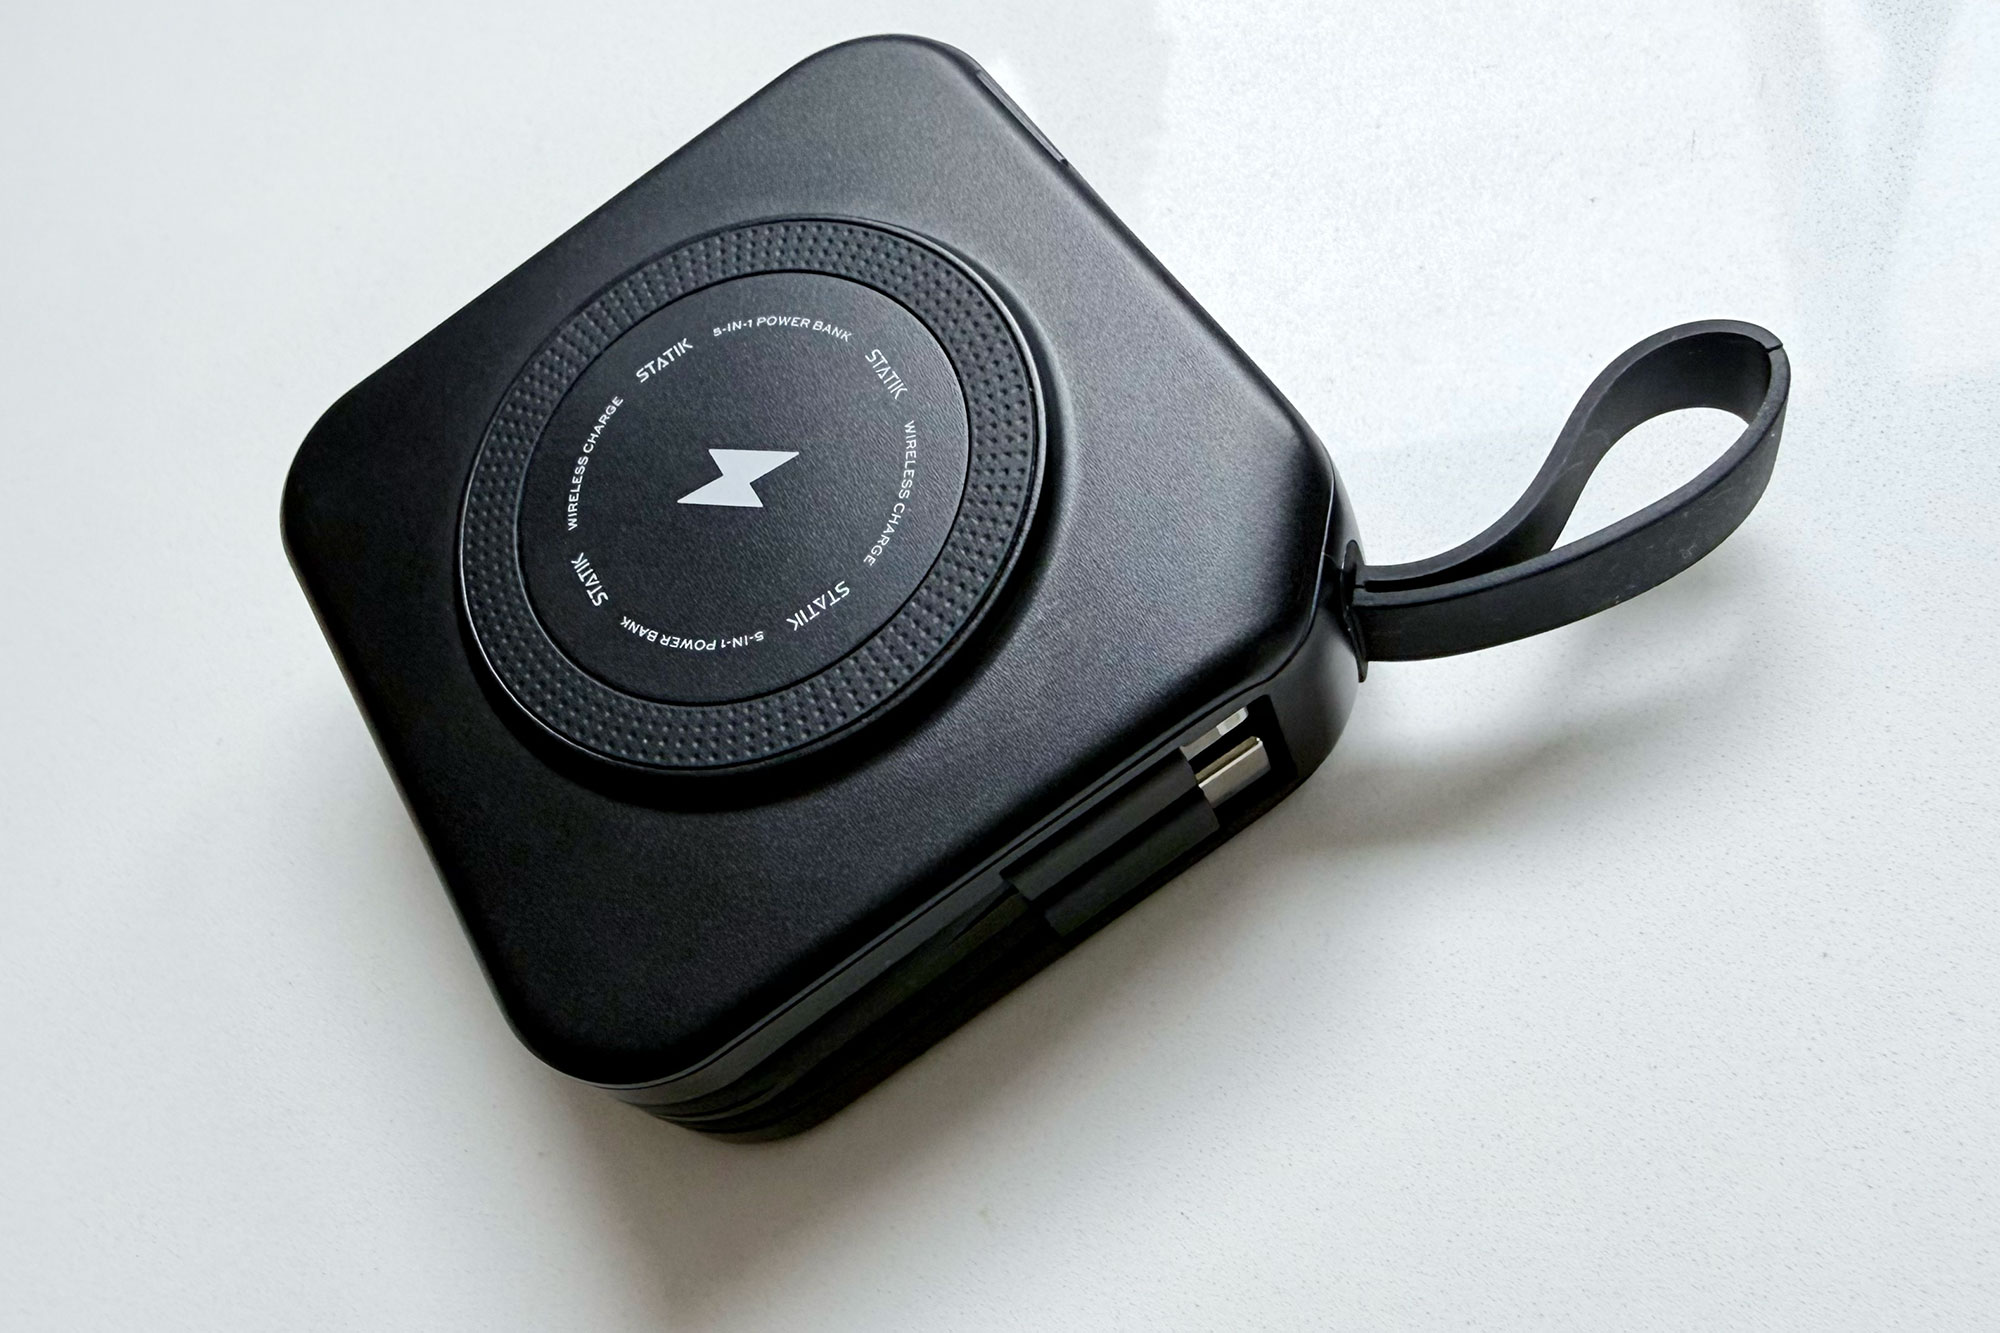
A lot greater and meaner than the ability banks reviewed above, the Statik 5-in-1 Journey Charger is an influence financial institution that may cost 5 units concurrently: two by the USB-C and USB-A ports, one wirelessly by a magnetic charging pad, and two by the built-in cables (USB-C for iPhone 15/16/17 and Lightning for older iPhones).
In our exams, it was very shut in battery charging energy to the highest scorers—charging an iPhone 16 Professional practically twice over.
It claims to supply 15W of wi-fi energy however isn’t formally licensed by Apple, so we price it at 7.5W for wi-fi. There are two built-in output cables: one USB-C for iPhone 15/16/17, and one Lightning for older iPhones and Apple units. For those who don’t have any Lightning-based units this can be superfluous, though mates in want of energy might thanks if their iPhones are older. Most individuals’s AirPods are nonetheless Lightning primarily based, so chances are you’ll nicely discover a use for it.
It options built-in U.S. plug prongs so may be related straight into an influence socket relatively than requiring a separate USB-C charger. That is positive for customers primarily based within the U.S. or Canada, however not for worldwide customers, though there are U.Ok., E.U, and AU/NZ plug adapters included making it work in these nations and as a journey companion. The ability financial institution even includes a useful pull-out telephone clip that holds your telephone upright, though the position of the cables means the battery pack can’t cost your telephone whereas it’s within the mini stand.
In contrast to the extra svelte energy banks reviewed right here, the Statik SmartCharge 5-in-1 Energy Financial institution is just too large and hulking to allow you to slip the iPhone plus battery pack into your pocket. As a conveyable energy financial institution you would possibly carry in a bag in your travels, however not your pocket.
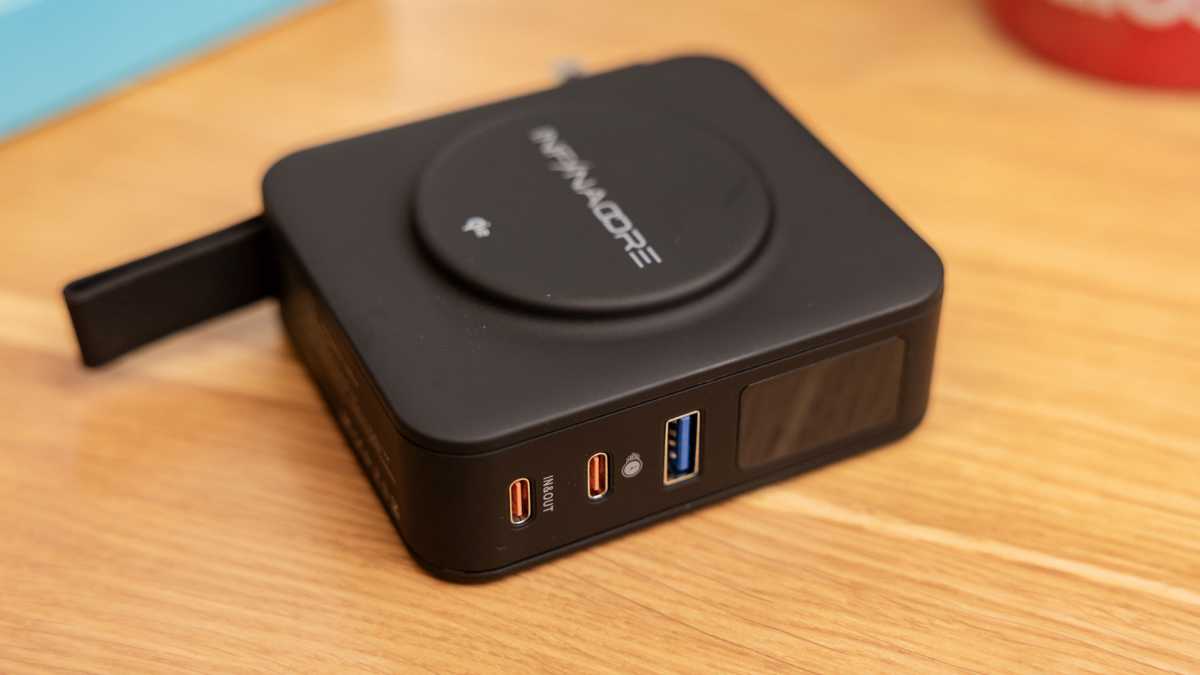
One other plug-in-the-wall energy financial institution choice is theInfinacore P3 Professional, pictured above, which prices $129 / £102, and might cost 4 units on the similar time, together with an iPhone at 15W Qi2. It lacks the built-in USB-C cable discovered on the Statik and Raycon energy financial institution chargers however because it plugs immediately right into a wall energy socket you gained’t want to hold a cable to recharge the ability financial institution itself. Just like the Statik battery pack, it comes with U.Ok., E.U, and AU/NZ journey adapter plug heads. In addition to the Qi2 charging pad, there are two USB-C ports and one USB-A. The P3 Professional additionally boasts a superb show, displaying charging pace, battery standing, temperature, and cost time remaining. We advocate this energy financial institution for MacBook customers who need a moveable 65W charger with MagSafe for wi-fi iPhone charging, plus USB choices. The Statik and Raycon aren’t as appropriate for laptop computer charging, however the P3 Professional’s 65W is sufficient to hold most MacBooks going when related.
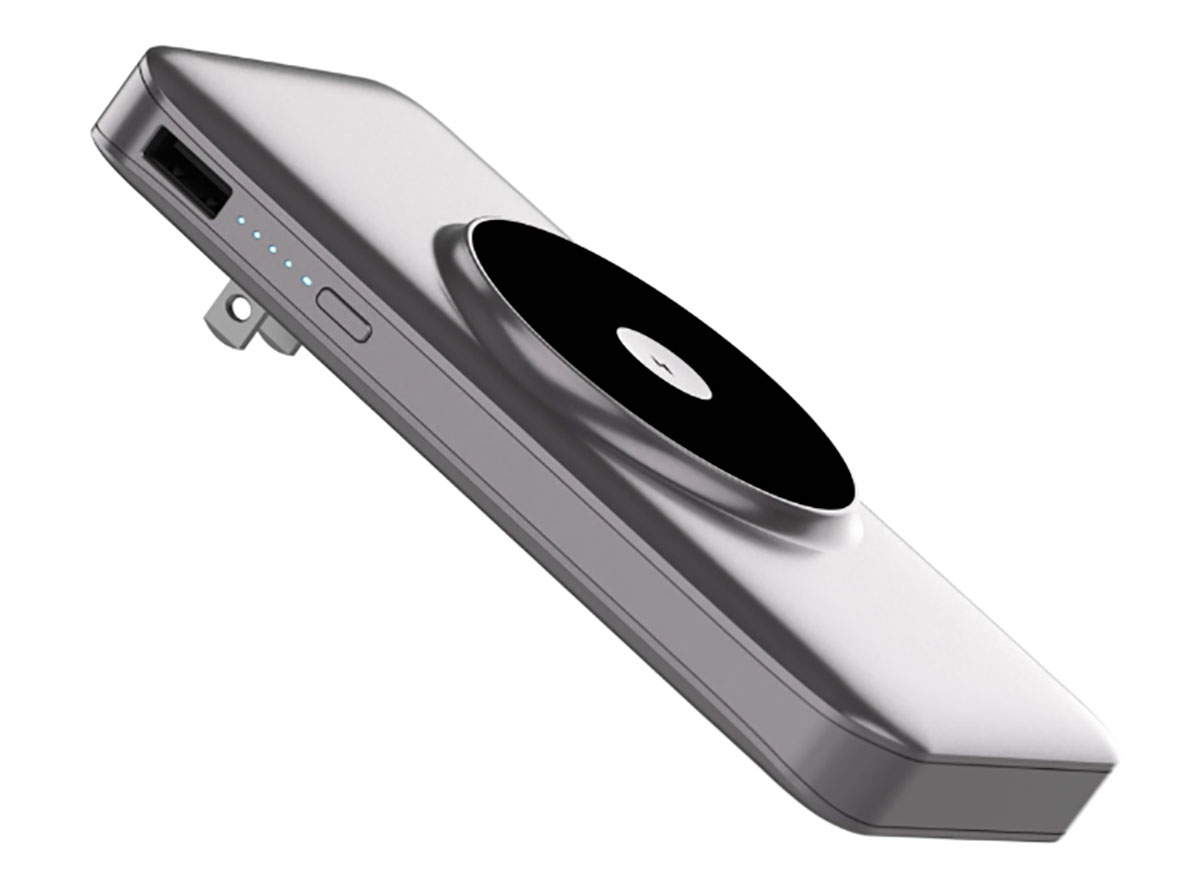
Whereas a wi-fi charging pad saves you the trouble of carrying a cable round to cost your telephone from an influence financial institution, you continue to want a wall charger handy to recharge the ability financial institution itself… however not with the PhoneSuit Journey Magazine, which options foldable North American plug prongs so you possibly can plug the battery pack straight into an influence socket. Whereas plugged in, the ability financial institution can cost the connected iPhone wirelessly concurrently recharging the battery pack.
Two additional USB ports are additionally useful. The USB-C port can cost at 20W, a lot sooner than the 7.5W MagSafe-compatible wi-fi charging pad—however you will want a USB-C cable on this occasion: USB-C to Lightning for iPhones older than the iPhone 15, and USB-C to USB-C for the 15, 16 and 17. The USB-A port can cost one other system at as much as 18W.
The 10000mAh battery capability allowed us to cost a light iPhone to 100% after which once more one other 50%, which is about common for this measurement battery.
Greatest small moveable magnetic energy banks
For those who carry your energy financial institution round with all day, in your bag or pocket, a slimmer, lighter magnetic/MagSafe energy financial institution will go well with you higher than a bigger, heavier 10K battery pack. They’re additionally simpler to pocket when clamped to your telephone. We’ve examined lots from 3000mAh to 6000mAh to search out the very best moveable MagSafe energy financial institution that may recharge your iPhone sufficient to get you thru the remainder of the day however not sufficient to answer on throughout a weekend’s tenting.
The Anker MagGo 10K Slim Energy Financial institution, reviewed above, is simply 0.58 inches thick and weighs solely 200g however these 5K magnetic energy banks will take up even much less area in your bag or desk drawer, and are simpler to pocket with iPhone connected.
Simon Jary
1. EcoFlow RAPID Magnetic Energy Financial institution 5K – Greatest 5K magnetic battery pack for pace
Execs
Slimmer than 10K
Constructed-in USB-C cable
Constructed-in stand
15W wi-fi or 30W wired
Cons
Barely bigger than different 5K energy banks
Worth When Reviewed:
$69.99
Greatest Costs Right this moment:
Capability: 19.35Wh (5000mAh)
Enter charger: USB-C (30W)
Output charger: Wi-fi (15W) & USB-C (30W)
On take a look at charged iPhone to: 70%
Weight: 6.4oz (180g)
Dimensions: 4.3 x 2.8 x 0.6 inch (10.8 x 7 x 1.4cm)
Colours: Grey/silver
5K battery packs are slim sufficient to clamp to your iPhone and nonetheless slip into your pocket. Whereas 10000mAh energy banks boast bigger re-charging capability, in order for you a barely smaller and lighter battery pack with a stand, we advocate you select between this energy financial institution—the smaller sibling of our really useful finest 10K magnetic energy financial institution—and both the Belkin BoostCharge Professional Energy Financial institution 5K + Stand or Ugreen 5000mAh Magnetic Wi-fi Energy Financial institution, each reviewed under.
All three have a 5000mAh battery however the Belkin gained in our head-to-head recharging exams, recharging a light iPhone 16 Professional by 79% in comparison with the 5K EcoFlow Fast (70%) and Ugreen (68%). For the most important recharge, Belkin wins.
The place the 5K EcoFlow Fast will get the general nod—particularly for house owners of the iPhone 15, 16 and 17—is its built-in USB-C cable. No different 5000mAh wi-fi energy financial institution we now have examined has the useful built-in cable. A number of of our favourite 10K battery packs have built-in cables however that is the primary 5K energy financial institution to boast one. Even you probably have an earlier Lightning iPhone, the built-in cable can be utilized to prime up the ability financial institution itself.
It options 15W Qi2 wi-fi charging when clamped to the again of an iPhone, and may be charged with a cable at a prime 30W pace.
2. Belkin BoostCharge Professional Magnetic Energy Financial institution Qi2 – Greatest 5K in our exams
Execs
Spectacular in battery exams
Constructed-in stand
15W wi-fi or 12W wired
Brilliant vary of colours
Cons
USB-C port a bit of underpowered
Worth When Reviewed:
$59.99
Greatest Costs Right this moment:
$54.70
$59.95
$59.95
$59.99
Capability: 19.25Wh (5000mAh)
Enter charger: USB-C (20W)
Output charger: Wi-fi (15W) & USB-C (12W)
On take a look at charged iPhone to: 79%
Weight: 4.8oz (136g)
Dimensions: 3.9 x 2.6 x 0.6 inches (9.8 x 6.6 x 1.4cm)
This 5K battery pack was the winner in our recharging exams, recharging a light iPhone 16 Professional by 79% in comparison with 70% by the 5K EcoFlow Fast and 68% for the Ugreen energy financial institution. Solely the Kuxiu S2 Stable-State energy financial institution carried out to this degree.
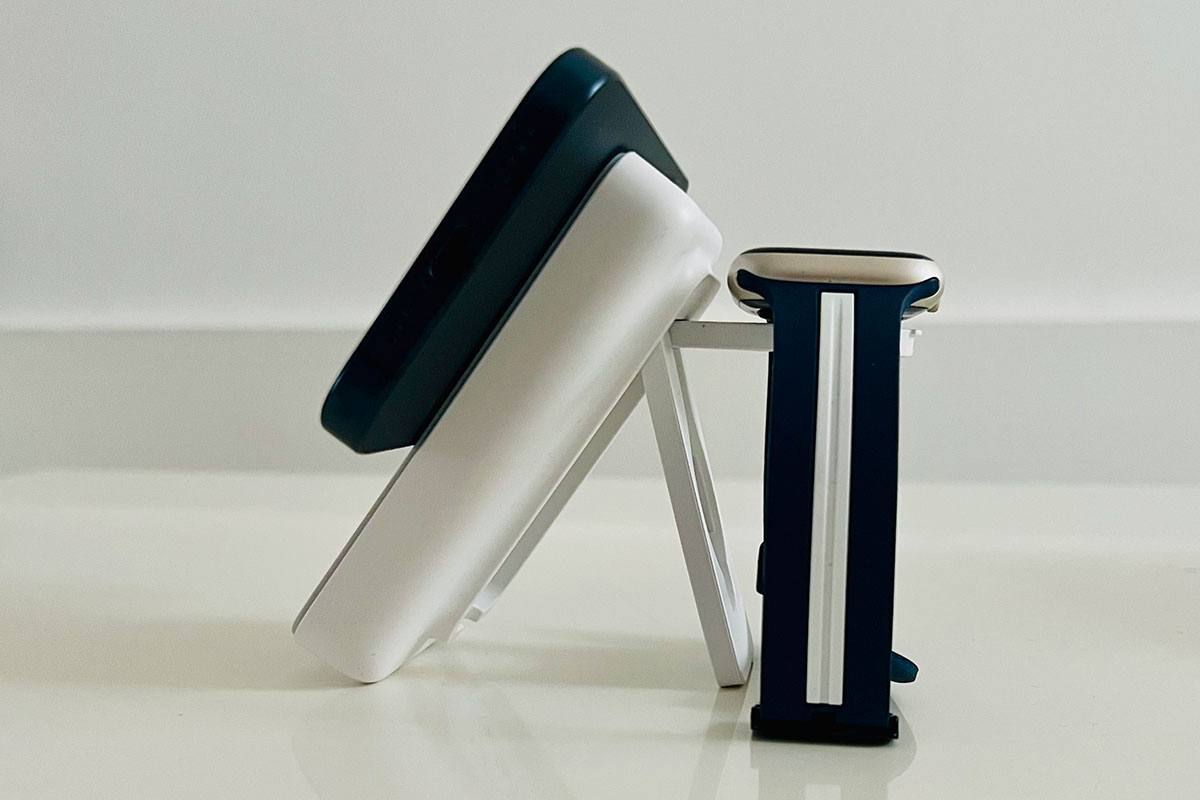
The Belkin’s kickstand is simple to make use of and feels sturdy, and the battery pack itself is marginally smaller than the Ugreen. The $49.99 Torras MagStall Energy Financial institution is a bit of slimmer however wider and boasts a stand/finger-grip, though recharges to a barely lesser extent.
It options 15W Qi2 wi-fi charging when clamped to the again of an iPhone, and may be charged with a cable at 12W, which isn’t as speedy as some energy banks which have 20W and even 30W USB-C ports.
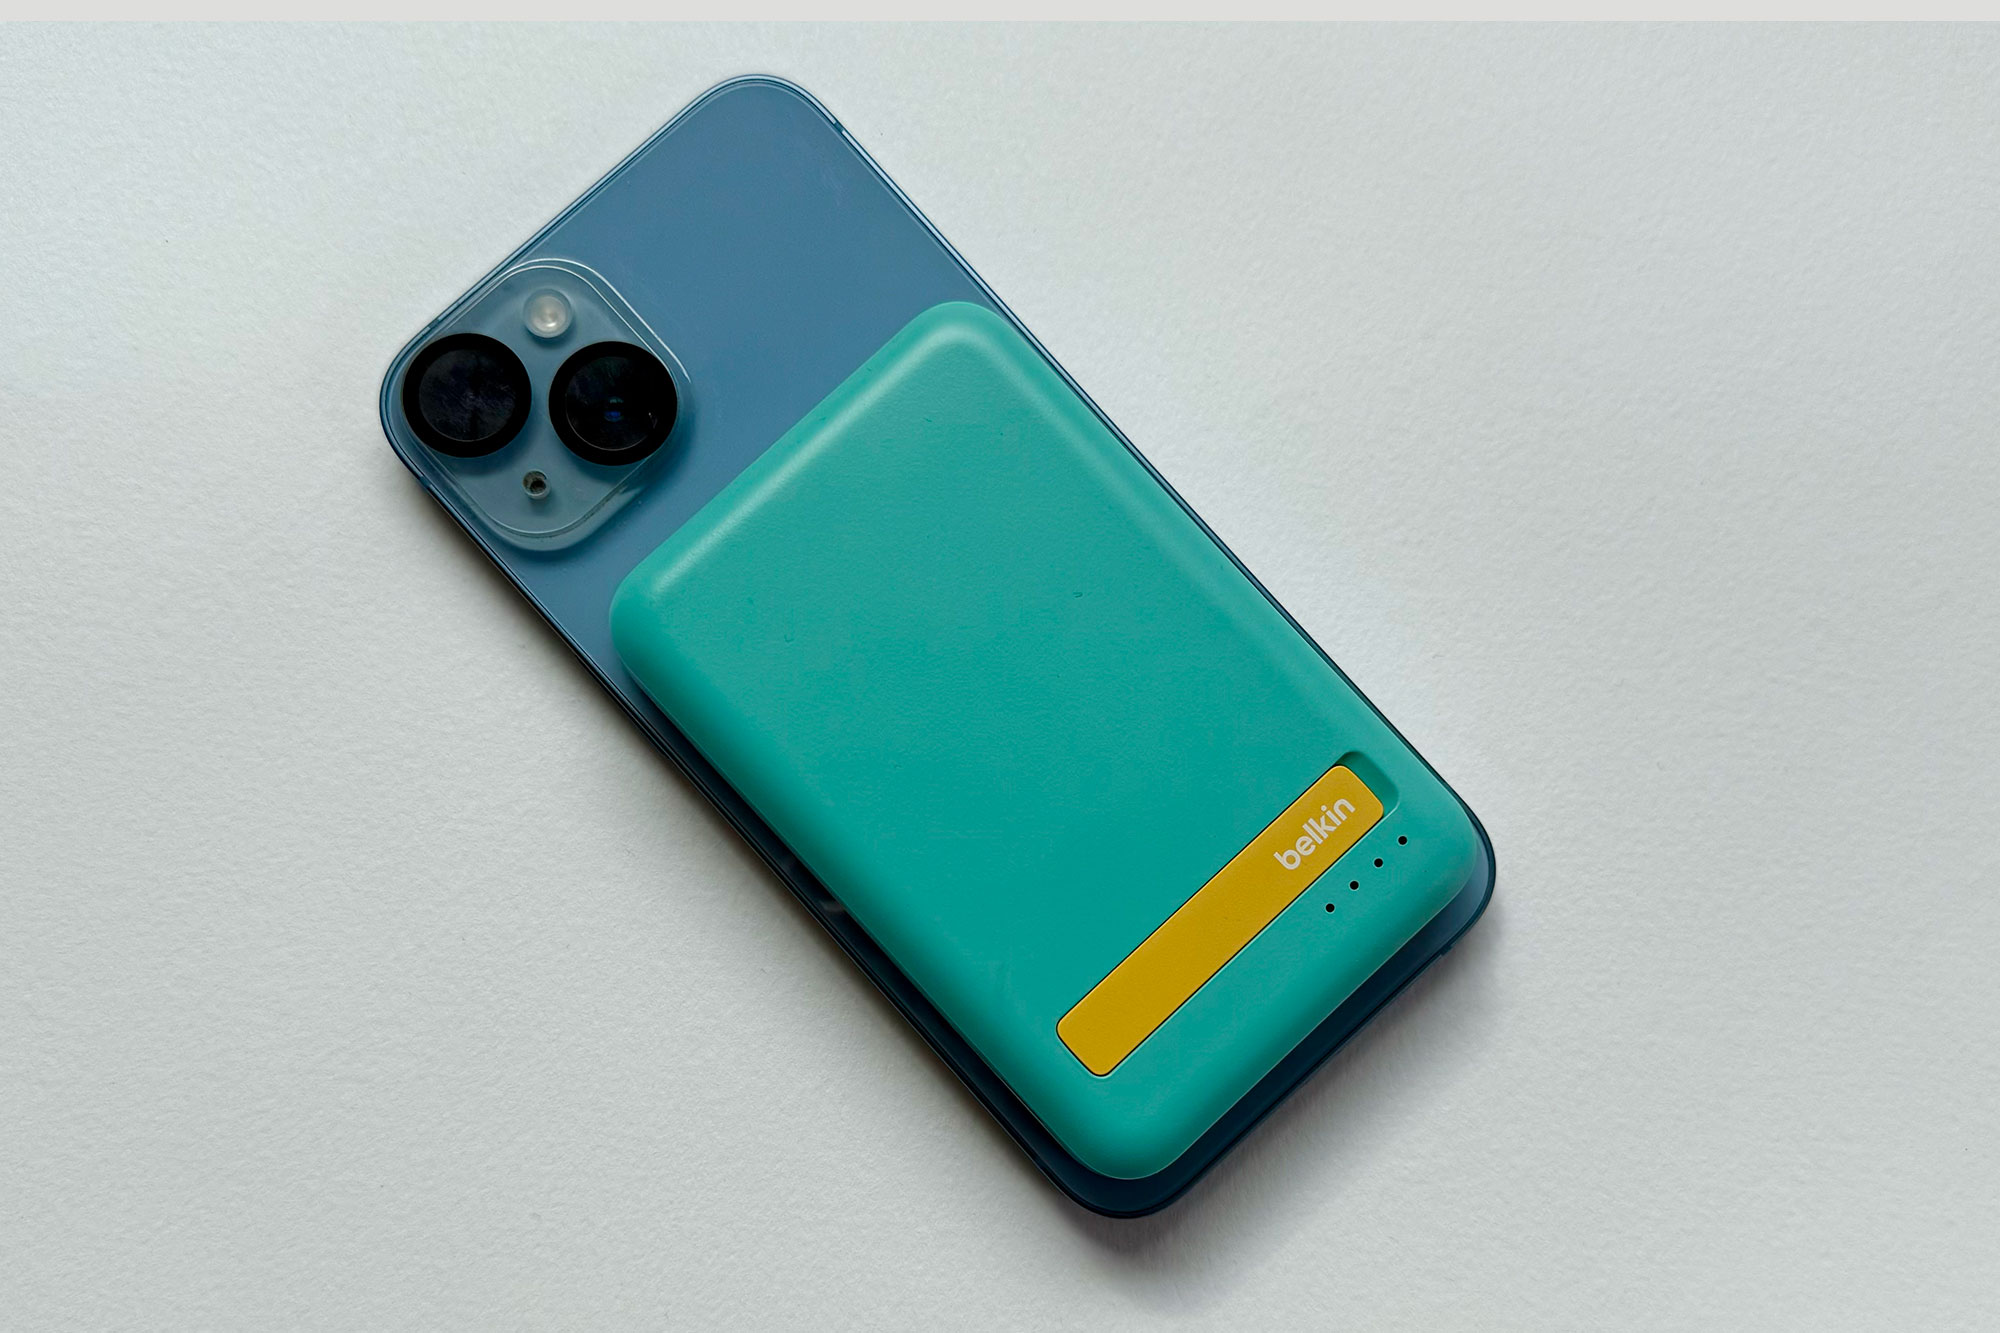
Verify right here first: Belkin and Amazon supply a alternative of colours, and the Apple Retailer now has an unique set of recent colours, together with a brighter Pink, Deep Purple with a purple stand and Teal with a yellow stand
3. Anker Nano 5K MagGo Slim Energy Financial institution – Slimmest 5K wi-fi energy financial institution
Execs
Very compact and light-weight
Spectacular in battery exams
15W wi-fi or 20W wired
Worth When Reviewed:
$54.99
Greatest Costs Right this moment:
$54.99
Capability: 19.35Wh (5000mAh)
Enter charger: USB-C (20W)
Output charger: Wi-fi (15W) & USB-C (20W)
On take a look at charged iPhone to: 77%
Weight: 4.3oz (122g)
Dimensions: 4 x 2.8 x 0.34 inches (10.2 × 7.1 x 0.86cm)
Colours: Grey, Black, and White
Most individuals carry their energy financial institution round with them, and there’s none higher in a small bag or pocket than the tremendous skinny Anker Nano MagGo 5K Slim, the slimmest magnetic energy financial institution we now have examined to this point. It’s the little sibling of the 10K Slim reviewed above.
At 0.34 inches slim, the closest rival is the Baseus PicoGo 5K, reviewed under, which is a mere 0.02 inches deeper however loses factors for charging at 7.5W relatively than the Anker’s 15W Qi2 pace.
It carried out excellently in our recharge exams, boosting an iPhone 16 Professional from 0% to 77%. Charging speeds had been impacted by the warmth, which is attributable to the good temperature management that slows issues down once they get scorching.
4. ESR Qi2 5K MagSlim Kickstand – Energy, pace and a stand
Execs
Constructed-in stand
15W wi-fi or 20W wired
Cons
Barely bigger than different 5K energy banks
Worth When Reviewed:
$43.99
Greatest Costs Right this moment:
$25.99
Capability: 18Wh (5000mAh) Enter charger: USB-C (18W) Output charger: Wi-fi (15W) & USB-C (20W) On take a look at charged iPhone to: 77% Weight: 5.3oz (151g) Dimensions: 4.1 x 2.7 x 0.6 inch (10.4 x 6.8 x 1.5cm) Colours: Black, White
This ESR magnetic energy financial institution is constructed on Qi2 tech so presents quick 15W wi-fi charging. It additionally boasts a sturdy kickstand that closes with a reassuring snap.
It carried out nicely in our iPhone battery charging exams with a rating of 77%—simply 2% lower than our highest-rated 5K energy banks (the 5K Belkin BoostCharge + Stand and Kuxiu S2, each reviewed under). The Belkin BoostCharge Professional 5K is a bit of smaller and gained in our recharge exams, however the ESR is shut sufficient within the outcomes to be value contemplating.
ESR additionally sells a 10K Qi2 Kickstand mannequin, however this fared much less nicely in our exams at 118% vs different 10K energy banks that reached 150% and extra. There are additionally 5K fashions with out the kickstand for rather less bulk and money.
5. Ugreen 5000mAh 15W MagSafe PD 3.0 Energy Financial institution – Greatest price range magnetic battery pack
You’ll discover loads of super-cheap energy banks on-line, however the best-priced magnetic energy financial institution that we now have examined from a trusted producer is the Ugreen 5000mAh Magnetic Wi-fi Energy Financial institution. For security’s sake, we advocate you keep away from the most affordable offers for merchandise from suppliers you possibly can belief—and we’ve achieved that testing for you.
It’d lack a built-in stand as seen on different comparable smaller-capacity energy banks, however the Ugreen can recharge your fading iPhone to about two-thirds full battery capability, and is tremendous slim and light-weight. It’s also blessed with the flexibility to cost at 15W through a separate cable (provided).
6. Baseus PicoGo Extremely-Slim 5K – Candy spot for measurement and recharge
Colours: Area Gray, Nebula Pink, Pure Titanium, Cosmic Black
There’s an fascinating battle for the crown of smallest, slimmest and lightest magnetic battery pack between three of the ability banks reviewed and examined right here
The Baseus PicoGo 5K is a tiny bit shorter and fewer extensive than the Vonmählen Evergreen Magazine however nearly precisely the identical slim depth and is 13g lighter. It’s exactly the identical weight (111g) because the Infinacore M3. We expect it’s the candy spot between the three, and is accessible from Amazon for lower than $23.
Recharging our iPhone 16 Professional to 71%, it carried out a lot better in our battery exams than the smallest energy financial institution (Infinacore: 56%) and really barely higher than the slimmest (Vonmählen: 70%), though that may cost sooner at 15W in comparison with the PicoGo’s 7.5W.
There’s a bigger capability 10K Baseus PicoGo (4 x 2.7 x 0.6 inches; 6.2oz) that’s about the identical credit-card size and width however noticeably thicker in depth than the 5K, as you’d count on from a way more highly effective battery pack. The 10K model is quicker charging at 15W Qi2, and carried out nicely in our exams with a rating of 142%.
7. Vonmählen Evergreen Magazine 5000mAh Energy Financial institution – Tremendous-slim magnetic energy financial institution
Execs
One of many slimmest examined
15W wi-fi or 20W wired
Greatest Costs Right this moment:
Capability: 19.25Wh (5000mAh) Enter charger: USB-C (20W) Output charger: Wi-fi (15W) & USB-C (20W) On take a look at charged iPhone to: 70% Weight: 4.4oz (124g) Dimensions: 3.3 x 2.4 x 0.4 inch (10.2 x 7 x 0.9cm) Colours: Black, White
Longer and wider than the smallest energy financial institution we now have examined, the well-named Infinacore M3 Mini reviewed under, the Vonmählen Evergreen Magazine 5000mAh Energy Financial institution nevertheless wins the crown for slimmest 5K energy financial institution. If you wish to shave 0.2cm off the width of the ability financial institution clamped iPhone sliding out and in of your pocket, then that is as skinny because it will get though the PhoneSuit Elite Magazine Slim 5K is about the identical depth.
It’s also sooner than the M3 Mini and Elite Magazine Slim at wirelessly charging because it helps Qi2, and in our exams it recharged an iPhone 16 Professional from 0% to 70% earlier than requiring a power-up itself, which simply beats the Infinacore and simply shades the PhoneSuit.
8. PhoneSuit Elite Magazine Slim 5K – Greatest 5K battery pack with show
Figuring out how a lot cost is left in your energy financial institution may imply the distinction between leaving the home assured that your battery pack is stuffed with juice and discovering out too late that it wants a recharge itself.
The Elite Magazine Slim from PhoneSuit has a big digital show displaying off remaining cost that’s extra accessible than the standard 4 LED dots discovered on most energy banks.
This battery pack can also be notable for its slimness, which is the same as the Vonmählen Evergreen Magazine, reviewed above. The Vonmählen energy financial institution narrowly beat it in our exams however actually not considerably so, nevertheless it does cost sooner wirelessly (15W vs 7.5W) than the PhoneSuit.
The PhoneSuit Elite Magazine Slim Professional is a 10K model, with a recharge rating of 149%, and the identical brilliant easy-to-read show for simply $10 extra however deeper (0.5in vs 0.35in).
9. Infinacore M3 Mini Wi-fi 5K Energy Financial institution – Smallest, lightest magnetic energy financial institution
Execs
Smallest, lightest we examined
7.5W wi-fi or 20W wired
Cons
Not 15W wi-fi
Decrease recharge than rivals
Worth When Reviewed:
$49.99
Greatest Costs Right this moment:
Capability: 19.25Wh (5000mAh)
Enter charger: USB-C (20W)
Output charger: Wi-fi (7.5W) & USB-C (20W)
On take a look at charged iPhone to: 56%
Weight: 3.9oz (111g)
Dimensions: 3.3 x 2.4 x 0.4 inch (8.38 x 6 x 1.1cm)
Colours: Stainless Black, Pearl Silver
In order for you a magnetic energy financial institution that’s tremendous small, the Infinacore M3 Mini Wi-fi Energy Financial institution is a slimmer, shorter and narrower and 25% lighter than most battery packs examined right here. The PhoneSuit Elite Magazine Slim and Baseus PicoGo energy banks, additionally reviewed right here, are equally mild. You’ll hardly discover any of them in your pocket or bag.
The compromise is in recharging efficiency—in our exams the M3 Mini resurrected a light iPhone 16 Professional by 56%, which may be sufficient for a number of hours service however is weaker than the opposite battery packs examined right here.
In order for you the safety of an influence financial institution in your purse or backpack, then this takes up little area and weighs subsequent to nothing, whereas providing simply sufficient juice to perk up your fading iPhone.
10. Kuxiu S2 Qi2 5000mAh – World’s first solid-state energy financial institution
Execs
Spectacular battery capability
15W wi-fi or 20W wired
Strong
Larger cost cycle than others
Worth When Reviewed:
$69.99
Greatest Costs Right this moment:
$49.99
Capability: 19Wh (5000mAh)
Enter charger: USB-C (18W)
Output charger: Wi-fi (15W) & USB-C (20W)
On take a look at charged iPhone to: 79%
Weight: 6.1oz (174g)
Dimensions: 3.3 x 2.4 x 0.4 inch (8.38 x 6 x 1.1cm)
Colours: Stainless Black, Pure Titanium
Stable-state batteries (SSB) are a brand new know-how that promise to be extra highly effective, sustainable and secure than typical Lithium-ion rivals by utilizing a stable relatively than liquid electrolyte. The Kuxiu S2 is definitely “semi solid-state” nevertheless it’s nonetheless the primary SSB energy financial institution that we’ve examined.
One of many advantages is that it’s best to get as a lot as twice as many expenses from the ability financial institution earlier than it begins to degrade: 1,000 vs a standard energy financial institution’s 500. It also needs to be extra sturdy and safer to hold and retailer.
The Kuxiu S2 carried out very nicely in our charging exams, matching the Belkin BoostCharge at 79%. With Qi2 it wirelessly expenses at 15W.
It’s not the smallest we’ve examined but additionally not the most important, though it does tip the scales greater than the tinier energy banks reviewed right here.
Greatest multi-device charging MagSafe energy banks
when you personal AirPods and an Apple Watch in addition to an iPhone, search for MagSafe energy banks that cost a number of Apple units on the similar time. As energy banks these ought to nonetheless be moveable, however typically convert into charging stands when in use. Most are two massive to slide in your pocket with the telephone connected however they’re helpful for if you end up away from base and have to energy up your favourite Apple package. Neither of the 2 we examined are rated at sooner than 7.5W.
1. OneAdaptr OneGo – Greatest 10K MagSafe energy financial institution with Watch and AirPods chargers
Dimensions: Folded: 2.8 x 0.94 x 4.7 inches (7 x 2.4 x 12cm)
Colours: White or Cool Grey
OneAdaptr has just lately up to date its OneGo 3-in-1 iPhone/Watch/AirPods charger and moveable energy financial institution, and made it much more compelling an answer. Not is the ability financial institution a separate half. Now the Watch and AirPods charging modules flip out from the again of the iPhone wi-fi charger, and the ability financial institution can recharge all of the units.
We’ve examined loads of nice moveable MagSafe wi-fi chargers however that is the smallest 3-in-1 iPhone/Apple Watch/AirPods charger that doubles up as an influence financial institution. The 10000mAh battery capability is excessive, and in our exams, we managed to get round one and three quarters recharge of an iPhone 15 Professional, which is spectacular. That’s greater than with the same iPhone/Watch charging Alogic Elevate energy financial institution (1.5 expenses).
You may get slimmer and lighter 10K energy banks however not with built-in Apple Watch and AirPods charging stands. We’ve examined and reviewed 10K battery packs that supply better charging energy: the Baseus Magnetic 10K Energy Financial institution (187%) and Anker MagGo 10K Slim (188%) each supply higher efficiency however in fact, lack the built-in Apple Watch and AirPods modules.
Sure, it’s a bit of bigger and positively heavier than a lot of the wi-fi energy banks reviewed right here, nevertheless it’s a neat answer if you’re away from an influence supply when all of your Apple units ping you that terrifying Low Energy Mode suggestion.
The Apple Watch charging module flips up from the again of the ability financial institution and feels sturdy sufficient to outlive in-bag journey. It expenses at 2W relatively than 5W so doesn’t assist Apple Watch Quick Cost however it would inject the juice that your Watch requires once you want it—no Transfer calorie counting or Train minutes want be missed.
There’s one USB-C port (the Alogic Elevate has a USB-A port for older cables) for enter or sooner wired iPhone charging (18W).
2. Alogic Elevate 4-in-1 MagSafe Wi-fi 10000mAh Energy Financial institution – Compact 10K MagSafe energy financial institution with Watch charger
The Alogic Elevate MagSafe and Apple Watch energy financial institution is a bit of fatter however shorter than the OneAdaptr OneGo, reviewed above. Whereas very comparable, it lacks the OneGo’s base with AirPods charging pad nevertheless it does boast two USB ports to the OneGo’s single enter/output port.
One USB-C port is for enter or sooner wired iPhone charging (18W); and the USB-A port is there for older charging cables. You may use both port to cost your AirPods or one other iPhone. Whereas you should use each on the similar time, simultaneous USB charging does drop energy tempo to simply 5W.
The robust-when-folded Apple Watch charging module expenses at 3W relatively than 5W so doesn’t assist Apple Watch Quick Cost however it’s a little sooner than the 2W OneGo Watch charger.
For those who don’t want the AirPods charging pad, the Alogic Elevate is as in a position and professional because the OneGo.
Greatest iPhone battery case
Whereas not a wi-fi or magnetic answer, a battery case is an influence financial institution constructed right into a protecting case to your iPhone. You’re much less more likely to depart this back-up battery at dwelling as you would possibly with a separate energy financial institution as it’s at all times along with your iPhone. The drawback of a battery case is that it’s going to doubtless be out of date once you change telephone however many people wouldn’t be with out one.
We’ve examined battery circumstances for the iPhone 15 and 16—try our roundup evaluations of the finest iPhone 15 circumstances and finest iPhone 16 circumstances. Our two favourite battery circumstances for each households of iPhone are from Mophie and Newdery. We’re actively testing the finest iPhone 17 circumstances however are but to search out an iPhone 17 battery case that we belief to advocate right here, though we’re certain Mophie or Newdery will carry one out quickly.
1. Mophie Juice Pack Battery Case for iPhone 16
Execs
Inside battery in protecting case
Extra environment friendly than a wi-fi energy financial institution
Slimmer than rival battery circumstances
Feels extra sturdy than mannequin for iPhone 15
Cons
Smaller battery than energy banks
Worth When Reviewed:
$99.95
Greatest Costs Right this moment:
$79.95
$99.95
Capability: 10.78Wh (2800mAh) for iPhone 16 and 16 Professional; 3600mAh for 16 Professional Max
Compatibility: iPhone 16, 16 Professional, 16 Professional Max
This Mophie battery case for the iPhone 16 household (omitting the 16 Plus) feels extra sturdy in its two half design than the model for the 15. It once more presents much less recharge potential than its rival however is considerably slimmer and lighter with its smaller battery capability.
Compatibility: iPhone 16, 16 Plus, 16 Professional, 16 Professional Max
This extra inexpensive battery case for all fashions of iPhone 16 is noticeably wider and fatter than the Mophie Juice Pack however that’s as a result of it hosts a bigger battery, which implies you get extra recharge potential on the worth of the majority.
The iPhone expenses wirelessly inside the case, which implies much less stress on the port however the ensuing compromise signifies that charging is notably slower. That shouldn’t matter when you are on the highway and the capability will hold your iPhone going for longer.
Compatibility: iPhone 15, 15 Professional, 15 Professional Max
No wi-fi charging right here as a result of the Juice Pack is a protecting case with an inner battery. The iPhone is charged through a wired USB-C connector, so expenses sooner and extra effectively than a wireless-only energy financial institution.
Mophie has designed this battery case to be as slim as doable whereas nonetheless providing sufficient recharge energy to get your iPhone to over a half full battery. The opposite iPhone 15 battery case we examined, the Newdery Battery Case for iPhone 15, reviewed under, is available in two a lot bigger battery capacities (5K and 10K) however the circumstances themselves are a lot heavier and hulking.
It’s a two-piece design that matches the iPhone nicely, and presents sturdy safety from knocks, bumps and drops. The highest half did slip off a few instances in testing from a good trouser pocket however ought to fare higher from a coat or bag. In order for you a one-piece iPhone battery case select one of many Newdery battery circumstances, reviewed under.
The Mophie Juice Pack is accessible for all iPhone 15 fashions besides the 15 Plus. When you’ve got an earlier iPhone mannequin, search for choices with the Newdery battery circumstances under.
The Newdery Battery Case presents full safety and practically a full battery recharge, and this twin perform makes it a less expensive different to a MagSafe case and MagSafe battery pack. Nevertheless, some might discover the cumbersome design too chunky, though the case for the iPhone 15 Professional itself weighs simply 134g.
The 5000mAh Newdery Battery Instances scored round 95% in our exams, with the 10K battery circumstances reaching an incredible 168%.
These take a look at outcomes are from the iPhone 15 Professional fashions, however Newdery has battery circumstances for all of the latest iPhones. Newdery iPhone Battery Instances on Amazon US | Amazon UK | Amazon CA.
Some fashions are wi-fi appropriate themselves so may be charged itself on most Qi charging pads.
For those who need safety in addition to longer battery life, the Newdery Battery Case presents each in an inexpensive package deal. It’s less expensive than the Mophie Juice Pack reviewed above.
For those who don’t want a conveyable energy financial institution, try the finest MagSafe chargers that we now have examined. Additionally try our exams of the finest iPhone chargers for wired charging options, and naturally to refill your iPhone energy financial institution.
How we examined
MagSafe charger testing was carried out utilizing an iPhone 13 Professional, iPhone 15 Professional and 16 Professional, subscribed to a 5G community and WiFi, with display off and all default settings.
Our take a look at is an easy battery recharge shootout. We let our test-unit iPhone Professional (3095mAh battery capability) drain to simply 10% after which set the Battery Pack to work recharging the telephone.
We then assigned the charger a rating of no matter share it managed to cost the iPhone to and subtract the ten%; we take a look at every mannequin no less than twice.
It’s not a real-world take a look at of day-to-day use the place you’ll doubtless be utilizing your telephone for numerous duties (of various battery utilization) and in several environmental situations and community configurations.
Nevertheless it does give us a standard rating format that we will use to check totally different battery-pack fashions.
Why evaluating Watt Hours is best than Milliamp Hours
Telephone batteries are usually rated in Milliamp Hours (mAh) however this can be a measure {of electrical} cost, whereas a Watt Hour is the same as one watt of power consumed for one hour of time.
When evaluating battery capacities and the way a lot an influence pack will increase a telephone’s inner battery, power is extra necessary than electrical cost.
And mAh ignores a battery voltage, which determines the wattage (energy) of a battery.
If the mAh is similar, the upper the voltage, the better the precise saved energy.
For instance, Apple’s MagSafe Battery Pack is rated at simply 1460mAh nevertheless it has a better voltage potential (7.62V) than the iPhone (3.81V) or different battery packs, which means that it will probably present extra energy to an iPhone than its mAh suggests; in reality, it’s really 2920mAh.
To enter additional depth about this learn our function iPhone battery capacities in contrast that additionally lists all iPhones battery life in mAh and Wh.
Anatomy of a magnetic energy financial institution
TORRAS
Much more than a battery goes into the making of a magnetic energy financial institution.
In fact, the battery is a very powerful part, however the wi-fi charging coils and magnetic connection are very important for environment friendly and due to this fact quick and highly effective charging.
The transmitter coil transfers energy by electromagnetic induction.
The magnets should be set as much as precisely join the transmitting coils—right here on the ability financial institution— to the receiving coils, on this case contained in the iPhone.
The instance proven above is the Torras MagStall Wi-fi Energy Financial institution, reviewed in our chart. You’ll be able to see the varied elements, together with that energy financial institution’s rotating stand/deal with.
What about non-wireless energy banks?
Wi-fi charging—particularly magnetic wi-fi charging—is tremendous handy and does away with the necessity to carry round messy cables to attach your system to the battery pack.
However wired charging is sort of at all times sooner and never a lot of an inconvenience if you’re not out and about. Over on our sister website Tech Advisor I’ve reviewed the finest energy banks that features commonplace non-wireless battery packs that may be a good answer in addition to the ability banks reviewed above.
Do magnetic energy banks work when the iPhone is in a case?
Sure, most high quality iPhone circumstances are appropriate with MagSafe having their very own magnet ring to make sure an in depth connection between the ability financial institution’s magnetic charging coils and the iPhone’s personal. You’ll find precisely that are supported in our roundups of the finest iPhone 17 circumstances, finest iPhone 16 circumstances and finest iPhone 15 circumstances.
This weblog delves into the significance of Bartlett’s take a look at for validating homogeneity of error variances in pooled/mixed experiments. It explains the take a look at’s significance, offers step-by-step calculations, and highlights its software in agricultural analysis. Sensible examples and code snippets for numerous software program are included for complete understanding.
Estimated Studying Time: ~12 minutes.
Introduction
In experimental analysis, particularly in fields like agriculture, researchers usually conduct experiments beneath various circumstances equivalent to completely different instances, places, or environments. To attract extra complete and strong conclusions, combining or pooling the info from these experiments right into a single evaluation is a typical apply.
Pooled evaluation presents a number of advantages:
Elevated Statistical Energy: Pooling knowledge will increase the whole pattern dimension () and the levels of freedom for error, thereby lowering the Imply Sq. Error (MSE). This results in a smaller crucial F-value in ANOVA, enhancing the flexibility to detect smaller therapy variations. For example, pooling knowledge from three fully randomized design (CRD) experiments, every with 10 replicates (), ends in a decrease MSE in comparison with analyzing every experiment individually ( per experiment). This enchancment permits for the detection of refined therapy results which may in any other case stay non-significant.
Interplay Evaluation: Pooled evaluation facilitates the identification of interactions between remedies and environments, places, or years by the treatment-by-environment interplay time period. This offers worthwhile insights into the consistency of therapy efficiency throughout various circumstances and broadens the applicability of the findings.
Regardless of these benefits, pooled evaluation requires the error variances of the person experiments to be homogeneous. This can be a crucial assumption to make sure the validity of the outcomes and to keep away from deceptive conclusions.
This weblog offers an in depth clarification of Bartlett’s take a look at, a statistical technique used to evaluate the homogeneity of variances. It discusses the take a look at’s software in pooled experiments and guides researchers on easy methods to carry out it successfully.
The Significance of Homogeneous Error Variances in Pooled Evaluation
For researchers conducting pooled analyses, guaranteeing homogeneity of error variances is paramount. Error variance refers back to the portion of knowledge variability that experimental components can not clarify. In ANOVA-based pooled analyses, the belief of homogeneous error variances throughout experiments underpins the validity of the F-statistic. When this assumption is violated, Imply Sq. Error (MSE) calculations could also be distorted, undermining the reliability of outcomes and rising the probability of Kind II errors—failing to detect real therapy results. Addressing heterogeneous variances might require options equivalent to Welch’s ANOVA or variance-stabilizing transformations to make sure strong conclusions.
Illustrative Situation:
Think about an experiment evaluating the effectiveness of foliar purposes of fungicides to regulate Black Sigatoka illness in bananas beneath various environmental circumstances (e.g., completely different humidity ranges). The examine includes seven fungicides (Fungicides A, B, C, D, E, F, and G) utilized to 21 banana crops (three replicates per therapy). Utilizing a Utterly Randomized Design (CRD), the remedies are randomly assigned to the crops. Under is the person ANOVA for 3 distinct environments.
Bartlett’s take a look at checks if error variances throughout environments are homogeneous. In our pooled CRD experiment, it determines if the error variability in particular person experiments is constant. Homogeneity is essential for pooling knowledge; important variations in variances imply the info can’t be pooled reliably. Let’s proceed with Bartlett’s take a look at.
Hypotheses
The null speculation is that every one the inhabitants variances (okay populations being in contrast) are equal: H₀: σ₁² = σ₂² = … = σₖ²
The choice speculation is that the inhabitants variances aren’t all equal, which means at the very least one variance differs from the others. The take a look at doesn’t explicitly determine which one is completely different, solely that at the very least one is completely different.
System for Bartlett’s Take a look at
The take a look at statistic for Bartlett’s take a look at is calculated utilizing the next system: χ² = [N−K * ln(Sₚ²) – Σᵢ(nᵢ – 1) * ln(Sᵢ²)] / C
The place:
N = Σᵢnᵢ: Whole variety of observations throughout all teams
The correction issue is calculated utilizing the system:
For our instance:
Compute the Time period
Plug within the Values to Calculate :
The take a look at statistic is computed as:
For our instance:
Examine the Computed Worth
To find out whether or not to reject the null speculation, examine the computed worth with the crucial worth from the Chi-Sq. distribution desk for on the desired significance stage (, often 0.05).
In our instance, the calculated worth (0.157) is lower than the desk worth (5.99). In Excel, the crucial worth may be calculated utilizing the system:
On the 0.05 significance stage, this consequence signifies inadequate proof to reject the null speculation. Whereas this doesn’t verify that the variances are equal, it suggests there’s not sufficient knowledge to conclude that at the very least one variance differs.
Codes with their bundle and
respective software program for performing bartletts take a look at
Code
Package deal
Software program
bartlett.take a look at(values ~group)
stats
R
bartlett.take a look at(values, grouping)
automobile
R
PROC GLM; CLASS group; MODEL
worth=group; TEST HOV;
–
SAS
Navigate to Analyze >
Descriptive Statistics > Discover.
Underneath “Plots,” choose
“Take a look at for Homogeneity of Variances (Bartlett’s).”
SPSS
scipy.stats.bartlett(data1,
data2)
scipy.stats
Python
Conclusion
Bartlett’s take a look at is an important step in validating the belief of homogeneous error variances earlier than pooling knowledge in experimental evaluation. In pooled experiments carried out throughout completely different environments or circumstances, it ensures that variances are comparable, enabling the mixed evaluation to be each dependable and significant.
When Bartlett’s take a look at signifies homogeneous variances, pooling knowledge enhances statistical energy and offers a broader understanding of therapy results and interactions. Conversely, if variances are considerably completely different, different approaches equivalent to knowledge transformations must be used to keep up the validity of conclusions. By fastidiously assessing variance homogeneity, researchers can confidently carry out pooled analyses and draw strong inferences from their knowledge.
The weblog is written with nice effort and due analysis by Jignesh Parmar
In an astonishing feat of gravitational sleuthing, astronomers have discovered a mysterious, dense blob of invisible matter embedded in a galaxy whose gentle took 7.3 billion years to succeed in us.
Precisely what this blob may be is at the moment an open query, but it surely’s completely tiny for the gap at which it was detected – simply round one million occasions the mass of the Solar. That is the smallest object to be discovered primarily based on gravity at giant cosmic distances, by an element of about 100.
“That is the lowest-mass object identified to us, by two orders of magnitude, to be detected at a cosmological distance by its gravitational impact,” explains a staff led by astrophysicist Devon Powell on the Max Planck Institute for Astrophysics in Germany.
“This work demonstrates the observational feasibility of utilizing gravitational imaging to probe the million-solar-mass regime far past our native Universe.”
Primarily based on our observations of the Universe, there’s one thing on the market that emits no gentle and solely interacts with the remainder of the Universe by way of gravity.
We name this one thing darkish matter, and there are a number of candidate explanations for what it may be. The consistency of the matter – whether or not it is easy or clumpy – might help scientists slim it down. Nonetheless, as a result of darkish matter emits no gentle, mapping its distribution is difficult.
This brings us to gravity. Every part within the Universe with mass causes spacetime to bend round it – the larger the mass, the larger the spacetime curvature. Think about placing, say, a bowling ball on a trampoline. When you roll a marble throughout the stretched trampoline mat, it should observe the curved path across the bowling ball.
Now think about the bowling ball is a galaxy and the marble is a photon. A set of photons from a distant galaxy touring by way of the spacetime warped by the gravity of a more in-depth galaxy (the bowling ball) will attain us stretched, distorted, and magnified. That is what we name a gravitational lens.
These lenses are an excellent device for learning the distant Universe, since they amplify deep house in a means that know-how can not. However astronomers also can use that stretched and distorted distant gentle to map the distribution of matter within the foreground lens.
That is what Powell and his colleagues got down to do, utilizing an in depth community of telescopes, together with the Inexperienced Financial institution Telescope, the Very Lengthy Baseline Array, and the European Very Lengthy Baseline Interferometric Community, to residence in on a well known gravitational lens system referred to as JVAS B1938+666.
This method consists of a foreground galaxy at a light-travel time of about 7.3 billion years, and a extra distant galaxy at roughly 10.5 billion years’ light-travel time whose gentle grew to become stretched and quadrupled by the foreground galaxy.
The JVAS B1938+666 lens system, with the inset revealing the place of the blob. The white pixels present the tough form of the mass. (Keck/EVN/GBT/VLBA)
One of many photos of the lensed galaxy is a brilliant, smeared arc of sunshine; in that smeared arc, the researchers discovered a pinched type of dimple. This pinch, the researchers ascertained, couldn’t have been created by the lensing galaxy alone. As an alternative, the offender needs to be a clump of mass, a willpower made with a whopping confidence degree of 26 sigma.
“From the primary high-resolution picture, we instantly noticed a narrowing within the gravitational arc, which is the tell-tale signal that we had been onto one thing,” says astronomer John McKean of the College of Groningen within the Netherlands.
“Solely one other small clump of mass between us and the distant radio galaxy might trigger this.”
The mass emits no gentle – not in optical, radio, or infrared wavelengths. It is both utterly darkish or far too dim to see. Because of this there are a number of issues it might be. The main candidates are a clump of darkish matter or a dwarf galaxy that emits too little gentle for us to detect.
Both choice is believable right now, and additional analysis efforts are wanted to find out the id of the offender.
“Given the sensitivity of our information, we had been anticipating to seek out at the very least one darkish object, so our discovery is in keeping with the so-called ‘chilly darkish matter principle’ on which a lot of our understanding of how galaxies type is predicated,” Powell says.
“Having discovered one, the query now could be whether or not we are able to discover extra and whether or not their quantity will nonetheless agree with the fashions.”
Inside the course of every week, ABC completely capitulated to threats from the FCC and right-wing station homeowners, spectacularly screwed up the optics, utterly did not foresee the plain enterprise penalties, after which unconditionally surrendered six days later. I am unable to consider a extra humiliating week for a CEO of Bob Iger’s stature, however we’ll get to that subsequent time after we speak in regards to the enterprise facet of the story.
For now, let’s speak politics.
In some methods, we’re seeing individuals make each too little
and an excessive amount of of this story. When it comes to stifling free speech, it’s most likely much less
important than the firing of Washington Submit op-ed columnist Karen Attiah. It would even be much less
important than the Vichy water that Ezra Klein has been doling out at
the New York Occasions.
With respect to different features, nevertheless, this
is each large and unprecedented. Josh Marshall, whose monitor report is unequaled in these issues, has
argued that the important thing to understanding Trump is dominance and submission. I
would add catharsis, distraction, and probably feral disinformation,
however Marshall is definitely proper about the principle driver. Marshall has
termed this the “bitch slap principle” of politics, and that’s in regards to the
finest description I’ve seen.
The strategy of wanting
overwhelmingly dominant whereas making your opponent feel and look
helpless and weak usually works very properly, however it has a few main
downsides. First off, if it fails, you’ll be able to usually discover the meant roles
reversed, with the bully wanting small and ineffectual. On a considerably
extra refined stage, a give attention to shock-and-awe politics can undermine extra
low-key and infrequently devious ways, significantly “boiling the frog.” If
you begin with boiling water and taunt the frog as you’re throwing it
in, it’s more likely to discover the temperature change.
With the
Colbert firing, CBS—in its try to appease Trump and the
Ellisons—utilized a veneer of believable deniability. It was comically
clear, instantly asserting that the number-one late night time present was
hemorrhaging money (displaying that big hits like Forrest Gump
truly misplaced cash has all the time been the muse of Hollywood
accounting). However the guidelines of the trendy institution press insisted
that the clearly disingenuous declare be given equal protection and
just about no scrutiny.
By comparability, Kimmel’s suspension was an abuse of presidency energy so
flagrant it will make Richard Nixon blush, and it struck a nerve.
Appears fairly clear to me: “the First Modification forbids the federal government from utilizing coercion backed by threats of punishment to suppress speech.” Reward hyperlink. www.nytimes.com/2025/09/19/u…
“Regardless
of the reality or falsity of Kimmel’s comment, the federal government shouldn’t
function the arbiter of fact in public debate.” It’s all to straightforward for
the federal government to make use of a truth-policing energy “as a software to threaten and
punish disfavored audio system.”
The one particular person Bob Iger least needed to talk up spoke up.
Like we stated, dominance-based methods have penalties for missed photographs and so they are typically zero-sum video games. The professional–Kimmel/anti-Trump facet clearly received this final spherical, which signifies that another person misplaced. Clearly, everybody slapped ABC round, however neither Nexstar, Sinclair, nor the administration got here out of this wanting stronger.
Elliott Morris argues that the backlash confirmed that the CEOs of firms like Disney don’t notice how unpopular Trump truly is. He is perhaps proper, however one factor’s for sure: they notice it now greater than they did a number of days in the past.