Home Blog Page 673

Introduction to Bayesian Statistics in Finance and Algorithmic Buying and selling

0

[ad_1]

By Vivek Krishnamoorthy and Aacashi Nawyndder  

TL;DR

Bayesian statistics affords a versatile, adaptive framework for making buying and selling choices by updating beliefs with new market knowledge. In contrast to conventional fashions, Bayesian strategies deal with parameters as chances, making them best for unsure, fast-changing monetary markets.

They’re utilized in threat administration, mannequin tuning, classification, and incorporating knowledgeable views or different knowledge. Instruments like PyMC and Bayesian optimisation make it accessible for quants and merchants aiming to construct smarter, data-driven methods.

This weblog covers:


Need to ditch inflexible buying and selling fashions and actually harness the ability of incoming market data? Think about a system that learns and adapts, identical to you do, however with the precision of arithmetic. Welcome to the world of Bayesian statistics, a game-changing framework for algorithmic merchants. It’s all about making knowledgeable choices by logically mixing what you already know with what the market is telling you proper now.

Let’s discover how this will sharpen your buying and selling edge!

This strategy contrasts with the standard, or “frequentist,” view of likelihood, which frequently sees chances as long-run frequencies of occasions and parameters as mounted, unknown constants (Neyman, 1937).

Bayesian statistics, then again, treats parameters themselves as random variables about which we are able to have beliefs and replace them as extra knowledge is available in (Gelman et al., 2013). Truthfully, this feels tailored for buying and selling, would not it? In any case, market circumstances and relationships are infrequently set in stone. So, let’s leap in and see how you should utilize Bayesian stats to get a leg up within the fast-paced world of finance and algorithmic buying and selling.


Conditions

To completely grasp the Bayesian strategies mentioned on this weblog, it is very important first set up a foundational understanding of likelihood, statistics, and algorithmic buying and selling.

For a conceptual introduction to Bayesian statistics, Bayesian Inference Strategies and Equation Defined with Examples affords an accessible rationalization of Bayes’ Theorem and the way it applies to uncertainty and decision-making, foundational to making use of Bayesian fashions in markets.


What You may Be taught:

  • The core thought behind Bayesian pondering is updating beliefs with new proof.
  • Understanding Bayes’ Theorem: your mathematical software for perception updating.
  • Why Bayesian strategies are an amazing match for the uncertainties of economic markets.
  • Sensible examples of Bayesian statistics in algorithmic buying and selling:
  • Estimating mannequin parameters that adapt to new knowledge.
  • Constructing easy predictive fashions (like Naive Bayes for market course).
  • Incorporating knowledgeable views or different knowledge into your fashions.
  • The Execs, Cons, and Current Tendencies of Utilizing Bayesian Approaches in Quantitative Finance.

The Bayesian Fundamentals

Prior Beliefs, New Proof, Up to date Beliefs

Okay, let’s break down the basic magic of Bayesian statistics. At its core, it is constructed on a splendidly easy but extremely highly effective thought: our understanding of the world just isn’t static; it evolves as we collect extra data.

Give it some thought like this: you have bought a brand new buying and selling technique you are mulling over.

  • Prior Perception (Prior Chance): Primarily based in your preliminary analysis, backtesting on historic knowledge, or perhaps a hunch, you will have some preliminary perception about how worthwhile this technique is perhaps.  For example you assume there is a 60% likelihood it is going to be worthwhile. That is your prior.
  • New Proof (Probability): You then deploy the technique on a small scale or observe its hypothetical efficiency over just a few weeks of dwell market knowledge. This new knowledge is your proof. The chance operate tells you ways possible this new proof is, given completely different underlying states of the technique’s true profitability.
  • Up to date Perception (Posterior Chance): After observing the brand new proof, you replace your preliminary perception. If the technique carried out nicely, your confidence in its profitability would possibly enhance from 60% to, say, 75%. If it carried out poorly, it’d drop to 40%. This up to date perception is your posterior.

This entire strategy of tweaking your beliefs primarily based on new data is neatly wrapped up and formalised by what is known as the Bayes’ Theorem.

Bayes’ Theorem: The Engine of Bayesian Studying

So, Bayes’ Theorem is the precise formulation that ties all these items collectively. You probably have a speculation (let’s name it H) and a few proof (E), the theory seems to be like this:

Bayes’ Theorem:

( P(H mid E) = frac{P(E mid H) cdot P(H)}{P(E)} )

The place:

  • P(H|E) is the Posterior Chance: The likelihood of your speculation (H) being true after observing the proof (E). That is what you need to calculate; your up to date perception.
  • P(E|H) is the Probability: The likelihood of observing the proof (E) in case your speculation (H) have been true. For instance, in case your speculation is “this inventory is bullish,” how possible is it to see a 2% worth enhance right now?
  • P(H) is the Prior Chance: The likelihood of your speculation (H) being true earlier than observing the brand new proof (E). That is your preliminary perception.
  • P(E) is the Chance of the Proof (additionally referred to as Marginal Probability or Normalising Fixed): The general likelihood of observing the proof (E) below all attainable hypotheses. It is calculated by summing (or integrating) P(E|H) × P(H) over each attainable H. This ensures the posterior chances sum as much as 1.

Let’s attempt to make this much less summary with a fast buying and selling situation.

Instance: Is a Information Occasion Bullish for a Inventory?

Suppose an organization is about to launch an earnings report.

  • Speculation (H): The earnings report will probably be considerably higher than anticipated (a “constructive shock”).
  • Prior P(H): Primarily based on analyst chatter and up to date sector efficiency, you imagine there is a 30% likelihood of a constructive shock. So, P(H) = 0.30.
  • Proof (E): Within the hour earlier than the official announcement, the inventory worth jumps 1%.
  • Probability P(E|H): You recognize from previous expertise that if there is a genuinely constructive shock brewing, there is a 70% likelihood of seeing such a pre-announcement worth leap attributable to insider data or some sharp merchants catching on early. So, P(E|H) = 0.70.
  • Chance of Proof P(E): This one’s a bit of extra concerned as a result of the worth may leap for different causes, too, proper? Possibly the entire market is rallying, or it is only a false hearsay. For example:
    • The likelihood of the worth leap if it is a constructive shock (P(E|H)) is 0.70 (as above).
    • The likelihood of the worth leap if it is not a constructive shock (P(E|not H)) is, say, 0.20 (it is much less possible, however attainable).
    • Since P(H) = 0.30, then P(not H) = 1 – 0.30 = 0.70.
    • So, P(E) = P(E|H)P(H) + P(E|not H)P(not H) = (0.70 * 0.30) + (0.20 * 0.70) = 0.21 + 0.14 = 0.35.

Now we are able to calculate the Posterior ( P(H mid E) ):

( P(H mid E) = frac{0.70 instances 0.30}{0.35} = frac{0.21}{0.35} = 0.60 )

Increase! After seeing that 1% worth leap, your perception that the earnings report will probably be a constructive shock has shot up from 30% to 60%! This up to date likelihood can then inform your buying and selling determination, maybe you are now extra inclined to purchase the inventory or regulate an current place.

After all, this can be a super-simplified illustration. Actual monetary fashions are juggling a considerably larger variety of variables and far more complicated likelihood distributions. However the lovely factor is, that core logic of updating your beliefs as new data is available in? That stays precisely the identical.

Supply


Why Bayesian Statistics Shines in Algorithmic Buying and selling

Monetary markets are a wild experience, stuffed with uncertainty, continuously altering relationships (non-stationarity, if you wish to get technical), and infrequently, not a number of knowledge for these actually uncommon, out-of-the-blue occasions. Bayesian strategies supply a number of benefits on this atmosphere:

  1. Handles Uncertainty Like a Professional: Bayesian statistics would not simply offer you a single quantity; it naturally offers with uncertainty by utilizing likelihood distributions for parameters, as a substitute of pretending they’re mounted, recognized values (Bernardo & Smith, 2000). This provides you a way more real looking image of what would possibly occur.
  2. Updating Beliefs with New Information: Algorithmic buying and selling methods continuously course of new market knowledge. Bayesian updating permits fashions to adapt dynamically. As an illustration, the volatility of an asset is not fixed; a Bayesian mannequin can replace its volatility estimate as new worth ticks arrive.
  3. Working with Small Information Units: Conventional frequentist strategies usually require giant pattern sizes for dependable estimates. Bayesian strategies, nevertheless, may give you fairly wise insights even with restricted knowledge, as a result of they allow you to usher in “informative priors” – mainly, your current information from specialists, comparable markets, or monetary theories (Ghosh et al., 2006). This can be a lifesaver while you’re making an attempt to mannequin uncommon occasions or new property that do not have a protracted historical past.
  4. Mannequin Comparability and Averaging:  Bayesian strategies present a extremely stable means (e.g., utilizing Bayes components or posterior predictive checks) to check completely different fashions and even common out their predictions. This usually results in extra strong and dependable outcomes (Hoeting et al., 1999).
  5. Lets You Weave in Qualitative Insights: Acquired a robust financial motive why a sure parameter ought to in all probability fall inside a particular vary? Priors offer you a proper strategy to combine that sort of qualitative hunch or knowledgeable opinion together with your exhausting quantitative knowledge.
  6. Clearer Interpretation of Chances: When a Bayesian mannequin tells you “there is a 70% likelihood this inventory will go up tomorrow,” it means precisely what it appears like: it’s your present diploma of perception. This is usually a lot extra easy to behave on than making an attempt to interpret p-values or confidence intervals alone (Berger & Berry, 1988).

Sensible Bayesian Purposes in Algorithmic Buying and selling

Alright, sufficient idea! Let’s get right down to brass tacks. How are you going to truly use Bayesian statistics in your buying and selling algorithms?

1. Adaptive Parameter Estimation: Conserving Your Fashions Recent

So many buying and selling fashions lean closely on parameters – just like the lookback window in your shifting common, the velocity of imply reversion in a pairs buying and selling setup, or the volatility guess in an choices pricing mannequin. However right here’s the catch: market circumstances are all the time shifting, so parameters that have been golden yesterday is perhaps suboptimal right now.

That is the place Bayesian strategies are tremendous helpful. They allow you to deal with these parameters not as mounted numbers, however as distributions that get up to date as new knowledge rolls in. Think about you are estimating the typical each day return of a inventory.

  • Prior: You would possibly begin with a obscure prior thought(e.g., a traditional distribution centred round 0 with a large unfold (normal deviation)) or a extra educated guess primarily based on how comparable shares within the sector have carried out traditionally.
  • Probability: As every new buying and selling day supplies a return, you calculate the chance of observing that return given completely different attainable values of the true common each day return.
  • Posterior: Bayes’ theorem combines the prior and chance to provide you an up to date distribution for the typical each day return. This posterior turns into the prior for the following day’s replace.It is a steady studying loop!

Scorching Development Alert: Strategies like Kalman Filters (that are inherently Bayesian) are extensively used for dynamically estimating unobserved variables, just like the “true” underlying worth or volatility, in noisy market knowledge (Welch & Bishop, 2006). One other space is Bayesian regression, the place the regression coefficients (e.g., the beta of a inventory) are usually not mounted factors however distributions that may evolve.
For extra on regression in buying and selling, you would possibly need to try how Regression is Utilized in Buying and selling.

Simplified Python Instance: Updating Your Perception a couple of Coin’s Equity (Assume Market Ups and Downs)

For example we need to get a deal with on the likelihood of a inventory worth going up (we’ll name it ‘Heads’) on any given day. This can be a bit like making an attempt to determine if a coin is honest or biased.

Python Code:

Output:

Preliminary Prior: Alpha=1, Beta=1
Noticed Information: 6 'up' days, 4 'down' days
Posterior Perception: Alpha=7, Beta=5
Up to date Estimated Chance of an 'Up' Day: 0.58
95% Credible Interval for p_up: (0.31, 0.83)
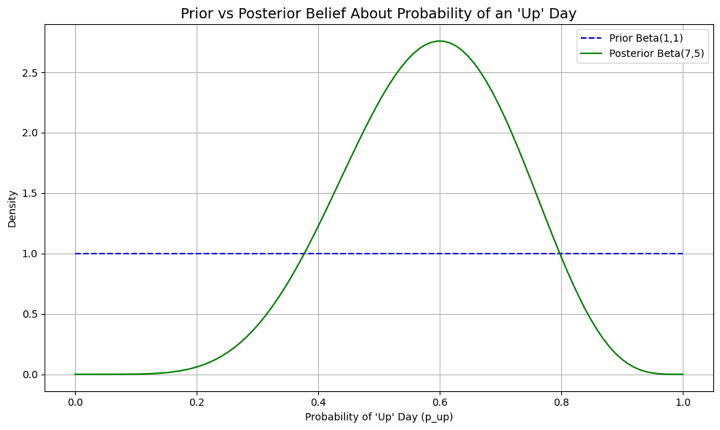
Prior vs posterior belief

On this code:

  • We begin off with a Beta(1,1) prior, which is uniform and suggests any likelihood of an ‘up’ day is equally possible.
  • Then, we observe 10 days of market knowledge with 6 ‘up’ days.
  • The posterior distribution turns into Beta(1+6, 1+4) = Beta(7, 5).
  • Our new level estimate for the likelihood of an ‘up’ day is 7 / (7+5) = 0.58, or 58%.
  • The credible interval offers us a variety of believable values.

The graph supplies a transparent visible for this belief-updating course of. The flat blue line represents our preliminary, uninformative prior, the place any likelihood for an ‘up’ day was thought-about equally possible. In distinction, the orange curve is the posterior perception, which has been sharpened and knowledgeable by the noticed market knowledge. The height of this new curve, centered round 0.58, represents our up to date, most possible estimate, whereas its extra concentrated form signifies our decreased uncertainty now that now we have proof to information us.

This can be a toy instance, but it surely exhibits the mechanics of how beliefs get up to date. In algorithmic buying and selling, this could possibly be utilized to the likelihood of a worthwhile commerce for a given sign or the likelihood of a market regime persisting.

2. Naive Bayes Classifiers for Market Prediction: Easy however Surprisingly Good!

Subsequent up, let’s speak about Naive Bayes. It is a easy probabilistic classifier that makes use of Bayes’ theorem, however with a “naive” (or to illustrate, optimistic) assumption that each one your enter options are unbiased of one another. Regardless of its simplicity, it may be surprisingly efficient for duties like classifying whether or not the following day’s market motion will probably be ‘Up’, ‘Down’, or ‘Sideways’ primarily based on present indicators. (Rish, 2001)

Right here’s the way it works (conceptually):

  • Outline Options: These could possibly be technical indicators (e.g., RSI < 30, MACD crossover), worth patterns (e.g., yesterday was an engulfing candle), and even sentiment scores from monetary information.
  • Accumulate Coaching Information: Collect historic knowledge the place you will have these options and the precise consequence (Up/Down/Sideways).
  • Calculate Chances from Coaching Information:
    • Prior Chances of Outcomes: P(Up), P(Down), P(Sideways) – merely the frequency of those outcomes in your coaching set.
    • Probability of Options given Outcomes: P(Feature_A | Up), P(Feature_B | Up), and many others. As an illustration, “What is the likelihood RSI < 30, given the market went Up the following day?”
  • Make a Prediction: For brand new knowledge (right now’s options):
    • Calculate the posterior likelihood for every consequence:
    • P(Up | Options) ∝ P(Up) * P(Feature_A | Up) * P(Feature_B | Up) * …
    • P(Down | Options) ∝ P(Down) * P(Feature_A | Down) * P(Feature_B | Down) * …
    • (And equally for Sideways)
    • The end result with the best posterior likelihood is your prediction.

Python Snippet Concept (Only a idea, you’d want sklearn for this):

Python Code:

Output:

Naive Bayes Classifier Accuracy (on dummy knowledge): 0.43

This accuracy rating of 0.43 signifies the mannequin accurately predicted the market’s course 43% of the time on the unseen take a look at knowledge. Since this result’s beneath 50% (the equal of random likelihood), it means that, with the present dummy knowledge and options, the mannequin doesn’t show predictive energy. In a real-world software, such a rating would sign that the chosen options or the mannequin itself is probably not appropriate, prompting a re-evaluation of the strategy or additional function engineering.

This little snippet offers you the fundamental movement. Constructing an actual Naive Bayes classifier for buying and selling takes cautious thought of which options to make use of (that is “function engineering”) and rigorous testing (validation). That “naive” assumption that each one options are unbiased may not be completely true within the messy, interconnected world of markets, but it surely usually offers you a surprisingly good place to begin or baseline mannequin.
Interested in the place to study all this? Don’t fear, pal, we’ve bought you lined! Try this course.

3. Bayesian Danger Administration (e.g., Worth at Danger – VaR)

You’ve got in all probability heard of Worth at Danger (VaR), it is a frequent strategy to estimate potential losses. However conventional VaR calculations can typically be a bit static or depend on simplistic assumptions. Bayesian VaR permits for the incorporation of prior beliefs about market volatility and tail threat, and these beliefs might be up to date as new market shocks happen. This will result in threat estimates which can be extra responsive and strong, particularly when markets get uneven.

As an illustration, if a “black swan” occasion happens, a Bayesian VaR mannequin can adapt its parameters far more rapidly to mirror this new, higher-risk actuality. A purely historic VaR, then again, would possibly take lots longer to catch up.

4. Bayesian Optimisation for Discovering Goldilocks Technique Parameters

Discovering these “good” parameters in your buying and selling technique (like the right entry/exit factors or the perfect lookback interval) can really feel like trying to find a needle in a haystack. Bayesian optimisation is a significantly highly effective method that may assist right here. It cleverly makes use of a probabilistic mannequin (usually a Gaussian Course of) to mannequin the target operate (like how worthwhile your technique is for various parameters) and selects new parameter units to check in a means that balances exploration (making an attempt new areas) and exploitation (refining recognized good areas) (Snoek et al., 2012). This may be far more environment friendly than simply making an attempt each mixture (grid search) or selecting parameters at random.

Scorching Development Alert:Bayesian optimisation is a rising star within the broader machine studying world and is extremely well-suited for fine-tuning complicated algorithmic buying and selling methods, particularly when operating every backtest takes a number of computational horsepower.

5. Weaving in Various Information and Skilled Hunches (Opinions)

Today, quants are more and more “different knowledge” sources, issues like satellite tv for pc photos, the overall temper on social media, or bank card transaction tendencies. Bayesian strategies offer you a extremely pure strategy to combine such numerous and infrequently unstructured knowledge with conventional monetary knowledge. You’ll be able to set your priors primarily based on how dependable or robust you assume the sign from another knowledge supply is.

And it is not nearly new knowledge varieties. What if a seasoned portfolio supervisor has a robust conviction a couple of explicit sector due to some geopolitical growth that is tough to quantify? That “knowledgeable opinion” can truly be formalised into a previous distribution, permitting it to affect the mannequin’s output proper alongside the purely data-driven alerts.


Current Trade Buzz in Bayesian Algorithmic Buying and selling

Whereas Bayesian strategies have been round in finance for some time, just a few areas are actually heating up and getting a number of consideration recently:

  1. Bayesian Deep Studying (BDL): You know the way conventional deep studying fashions offer you a single prediction however do not actually let you know how “certain” they’re? BDL is right here to alter that! It combines the ability of deep neural networks with Bayesian ideas to provide predictions with related uncertainty estimates (Neal, 1995; Gal & Ghahramani, 2016). That is essential for monetary purposes the place figuring out the mannequin’s confidence is as essential because the prediction itself. For instance, think about a BDL mannequin not simply predicting a inventory worth, but in addition saying it is “80% assured the worth will land between X and Y”.
  2. Probabilistic Programming Languages (PPLs): Languages like Stan, PyMC3 (Salvatier et al., 2016), and TensorFlow Chance are making it simpler for quants to construct and estimate complicated Bayesian fashions with out getting slowed down within the low-level mathematical particulars of inference algorithms like Markov Chain Monte Carlo (MCMC). This simpler entry is absolutely democratising using refined Bayesian strategies throughout the board (Carpenter et al., 2017).
  3. Subtle MCMC and Variational Inference: As our fashions get extra formidable, the computational grunt work wanted to suit them additionally grows. Fortunately, researchers are continuously cooking up extra environment friendly MCMC algorithms (like Hamiltonian Monte Carlo) and speedier approximate strategies like Variational Inference (VI) (Blei et al., 2017), making bigger Bayesian fashions tractable for real-world buying and selling.
    If you wish to study extra about MCMC, QuantInsti has a wonderful weblog on Introduction to Monte Carlo Evaluation.
  4. Dynamic Bayesian Networks for Recognizing Market Regimes: Monetary markets usually appear to flip between completely different “moods” or “regimes”, assume high-volatility vs. low-volatility durations, or bull vs. bear markets. Dynamic Bayesian Networks (DBNs) can mannequin these hidden market states and the chances of transitioning between them, permitting methods to adapt their conduct accordingly (Murphy, 2002).

The Upsides and Downsides: What to Hold in Thoughts

Like all highly effective software, Bayesian strategies include their very own set of execs and cons.

Benefits:

  • Intuitive framework for updating beliefs.
  • Quantifies uncertainty straight.
  • Works nicely with restricted knowledge by utilizing priors.
  • Permits incorporation of knowledgeable information.
  • Gives a coherent strategy to evaluate and mix fashions.

Limitations:

  • Selection of Prior: The choice of a previous might be subjective and may considerably affect the posterior, particularly with small datasets. A poorly chosen prior can result in poor outcomes. Whereas strategies for “goal” or “uninformative” priors exist, their appropriateness is commonly debated.
  • Computational Value: For complicated fashions, estimating the posterior distribution (particularly utilizing MCMC strategies) might be computationally intensive and time-consuming, which is perhaps a constraint for high-frequency buying and selling purposes.
  • Mathematical Complexity: Whereas PPLs are useful, a stable understanding of likelihood idea and Bayesian ideas remains to be wanted to use these strategies accurately and interpret outcomes.

Continuously Requested Questions

Q. What makes Bayesian statistics completely different from conventional (frequentist) strategies in buying and selling?
Bayesian statistics treats mannequin parameters as random variables with a and permits beliefs to be up to date with new knowledge. In distinction, frequentist strategies assume parameters are mounted and require giant knowledge samples. Bayesian pondering is extra dynamic and well-suited to the non-stationary, unsure nature of economic markets.


Q. How does Bayes’ Theorem assist in buying and selling choices? Are you able to give an instance?
Bayes’ Theorem is used to replace chances primarily based on new market data. For instance, if a inventory worth jumps 1% earlier than earnings, and previous knowledge suggests this usually precedes a constructive shock, Bayes’ Theorem helps revise your confidence in that speculation, turning a 30% perception into 60%, which may straight affect your commerce.


Q. What are priors and posteriors in Bayesian fashions, and why do they matter in finance?
A prior displays your preliminary perception (from previous knowledge, idea, or knowledgeable views), whereas a posterior is the up to date perception after contemplating new proof. Priors assist enhance efficiency in low-data or high-uncertainty conditions and permit integration of different knowledge or human instinct in monetary modelling.


Q. What varieties of buying and selling issues are finest suited to Bayesian strategies?
Bayesian strategies are perfect for:

  • Parameter estimation that adapts (instance, volatility, beta, shifting common lengths)
  • Market regime detection utilizing dynamic Bayesian networks
  • Danger administration (instance, Bayesian VaR)
  • Technique optimisation utilizing Bayesian Optimisation
  • Classification duties with Naive Bayes fashions
    These approaches assist construct extra responsive and strong methods.

Q. Can Bayesian strategies work with restricted or noisy market knowledge?
Sure! Bayesian strategies shine in low-data environments by incorporating informative priors. In addition they deal with uncertainty naturally, representing beliefs as distributions slightly than mounted values, essential when modelling uncommon market occasions or new property.


Q. How is Bayesian optimisation utilized in buying and selling technique design?
Bayesian optimisation is used to tune technique parameters (like entry/exit thresholds) effectively. As a substitute of brute-force grid search, it balances exploration and exploitation utilizing a probabilistic mannequin (instance, Gaussian Processes), making it good for expensive backtesting environments.


Q. Are easy fashions like Naive Bayes actually helpful in buying and selling?
Sure, Naive Bayes classifiers can function light-weight baseline fashions to foretell market course utilizing indicators like RSI, MACD, or sentiment scores. Whereas the belief of unbiased options is simplistic, these fashions can supply quick and surprisingly stable predictions, particularly with well-engineered options.


Q. How does Bayesian pondering improve threat administration?
Bayesian fashions, like Bayesian VaR (a, replace threat estimates dynamically as new knowledge (or shocks) arrive, not like static historic fashions. This makes them extra adaptive to unstable circumstances, particularly throughout uncommon or excessive occasions.


Q. What instruments or libraries are used to construct Bayesian buying and selling fashions?
Standard instruments embody:

  • PyMC and PyMC3 (Python)
  • Stan (through R or Python)
  • TensorFlow Chance
    These help strategies like MCMC and variational inference, enabling the event of every little thing from easy Bayesian regressions to Bayesian deep studying fashions.

Q. How can I get began with Bayesian strategies in buying and selling?
Begin with small tasks:

  • Take a look at a Naive Bayes classifier on market course.
  • Use Bayesian updating for a method’s win price estimation.
  • Attempt parameter tuning with Bayesian optimisation.
  • Then discover extra superior purposes and think about studying assets equivalent to Quantra’s programs on machine studying in buying and selling and EPAT for a complete algo buying and selling program with Bayesian strategies.

Conclusion: Embrace the Bayesian Mindset for Smarter Buying and selling!

So, there you will have it! Bayesian statistics affords an extremely highly effective and versatile strategy to navigate the unavoidable uncertainties that include monetary markets. By providing you with a proper strategy to mix your prior information with new proof because it streams in, it helps merchants and quants construct algorithmic methods which can be extra adaptive, strong, and insightful.

Whereas it is not a magic bullet, understanding and making use of Bayesian ideas may help you progress past inflexible assumptions and make extra nuanced, probability-weighted choices. Whether or not you are tweaking parameters, classifying market circumstances, keeping track of threat, or optimising your total technique, the Bayesian strategy encourages a mindset of steady studying, and that’s completely important for long-term success within the continuously shifting panorama of algorithmic buying and selling.

Begin small, maybe by experimenting with how priors influence a easy estimation, or by making an attempt out a Naive Bayes classifier. As you develop extra snug, the wealthy world of Bayesian modeling will open up new avenues for enhancing your buying and selling edge.

For those who’re severe about taking your quantitative buying and selling expertise to the following degree, think about Quantra’s specialised programs like “Machine Studying & Deep Studying for Buying and selling” to reinforce Bayesian strategies, or EPAT for complete, industry-leading algorithmic buying and selling certification. These equip you to sort out complicated markets with a major edge.

Continue learning, maintain experimenting!


Additional Studying

For a structured and utilized studying path with Quantra, begin with Python for Buying and selling: Fundamental, then transfer to Technical Indicators Methods in Python.

For machine studying, discover the Machine Studying & Deep Studying in Buying and selling: Novices studying observe, which supplies sensible hands-on insights into implementing fashions like Bayesian classifiers in monetary markets.

For those who’re a severe learner, you may take the Govt Programme in Algorithmic Buying and selling (EPAT), which covers statistical modelling, machine studying, and superior buying and selling methods with Python.


References


Disclaimer: This weblog put up is for informational and academic functions solely. It doesn’t represent monetary recommendation or a advice to commerce any particular property or make use of any particular technique. All buying and selling and funding actions contain important threat. At all times conduct your personal thorough analysis, consider your private threat tolerance, and think about looking for recommendation from a professional monetary skilled earlier than making any funding choices.

[ad_2]

10 Greatest Pc Programs After twelfth in India 2025

0

[ad_1]

At the moment laptop programs have gotten a brand new development in up to date instances. Such sorts of short-term programs are extremely popular for the tenth & twelfth class college students since after showing within the respective Board exams, college students can squeeze in the most effective laptop programs to enhance their odds of employability. These laptop programs are actually good for the tenth & twelfth college students since after their exams they’ve two to 3 months till the beginning of their subsequent class.

Suppose you’ve gotten accomplished your twelfth with an thrilling area ‘Computer systems’ or have any curiosity on this discipline, then there are a number of short-term programs that can lead you to a really perfect job. Right here, we’ve got searched the most effective Pc programs after the tenth or twelfth, proceed studying to search out the entire record right here, and choose the appropriate course for you.

10 Greatest Pc Programs After twelfth in India

1. Knowledge Entry Operator Course

Probably the most fundamental and short-term laptop programs that college students can select after twelfth, is designed to sharpen the scholar’s laptop typing & knowledge entry expertise that could be a course of to enter knowledge within the computerized database or spreadsheet.

This specific course is suitable for college kids who don’t search or need superior information of computer systems; it’s going to assist you to get entry-level knowledge entry or typing jobs within the firms.

The period of the course is mostly for six months however can differ from one institute to a different.

2. Programming Language Course

The programming language is called the bottom of the IT world. You are able to do nothing with out Programming. You could choose any language as per your alternative & understanding like C, C ++, PYTHON, JAVA, HACK, JAVASCRIPT, NET, ASP, RUBY, PERL, SQL, PHP, and extra. After doing the course, you’re going to get a job as a software program developer or Programmer.

However, for those who study at a sophisticated stage, then you’ll be able to create your software program or sport. Studying the programming language is the most effective laptop course that college students should contemplate after commencement for the Engineering graduates and one who will jam up with the strains of codes and create one thing actually good within the phrases of software program & internet purposes.

Additionally Learn: BCA vs B.Tech – Which is Higher?

3. MS Workplace Certificates Programme

MS Workplace is a 3 month to a six-month program the place college students will likely be taught concerning the distinguished apps of Microsoft Workplace equivalent to MS Phrase, MS Excel, MS Powerpoint, and MS Entry. College students will study to make use of the purposes regularly.

College students after getting the certificates or diploma within the Microsoft Workplace Certificates Programme will grow to be environment friendly on the office too. Certificates or Diploma holders are properly suited to the front-end jobs the place the computer systems are used equivalent to outlets, eating places, motels, and extra.

4. Pc-Aided Design & Drawing or CADD

College students with a technical background could go for the CADD short-term course. This course helps the scholars to study completely different CAD applications & Softwares equivalent to Fusion360, Infraworks, AutoCAD, and extra. The short-term and finest laptop course, identical to CADDD will enhance the know-how of an Engineering graduate whereas ITI diploma or diploma holders could simply land on drafting associated presents after their course completion.

5. Pc {Hardware} Upkeep

There are some college students who’re very a lot excited about {hardware} than software program. Suppose you do not need to go for the above fields, then that is one wonderful possibility. The course of laptop {hardware} upkeep is finished after your twelfth Pc. This course teaches you about {hardware} upkeep and different technical particulars.

6. Animation and VFX

The a part of designing, Animation, and VFX programs are shortly changing into the preferred laptop course that college students contemplate after twelfth when on the lookout for the sector of specialization. In response to the report, the animation trade in India is predicted to develop by 15 to twenty% to the touch USD 23bn by 2021. A lot of the cities in India present diploma programs on this discipline of Animation and VFX with a period of 6 months to 2 years.

Thus, for those who like to attract and permit your creativeness to go wild on paper, then you might be properly suited to the course.

7. Digital Advertising

College students who need to make their profession within the discipline than doing the digital advertising course would be the neatest thing after the twelfth. Digital advertising at this time is probably the most rising profession. There’re over 4 lakh jobs accessible within the Advertising area. Most enterprise house owners want the assistance of the digital advertising group for selling their manufacturers and companies.

The digital advertising trade is predicted to generate over 2 million jobs by an finish of 2020. Thus, the longer term on this trade is kind of promising. Irrespective of whether or not it’s a massive participant or a small start-up, firms wish to make investments massively in digital advertising actions. They’re on the lookout for individuals who will have the ability to develop & implement the digital advertising campaigns as per their wants.

8. Tally ERP 9

It’s the most effective laptop course to contemplate after twelfth commerce, however not only for the commerce college students, however any stream college students could be part of the course.

Tally Enterprise Useful resource Planning or Tally ERP is the software program that’s used to keep up accounts within the firm & ERP 9 is the newest model. It’s the certification and diploma laptop course the place it’s possible you’ll study monetary administration, taxation, account administration, and extra.

After the course completion, it’s possible you’ll work because the tally operator or assistant the place GST and Revenue tax returns are filed, and as a brisker you must do some fundamental works just like the purchases & gross sales entries and extra.

9. Cell App Growth

Cellphones or Smartphones at this time are an indispensable a part of all people’s lives. Proper from indulging in on-line procuring to meals ordering and taking part in video games, there’s an app for the whole lot these days. It’s a development, which has made cellular app growth the quickest rising profession paths.

The cellular app developer is mostly accountable for designing & constructing impactful cellular purposes for organizations that need to higher the client engagement practices.

These short-term programs after twelfth sometimes have a period of 6 months, though this may differ from one institute to a different.

10. Graphic Designing

Becoming a member of the Graphic Designing laptop course after your twelfth will offer you a tremendous platform to show your inventive expertise. With the onset of computer systems, the stream of design can be utilized in every single place & has acquired a number of purposes in numerous fields.

After the completion of this laptop course, the scholar has an choice to pursue many profession choices favored to design that embody;

Company or Company Graphics designer

  • Graphics designer (Freelance or impartial)
  • Model and Visible Id supervisor
  • Graphic designer (with magazines or web sites or media or publishing corporations)
  • Printing specialist
  • Artistic director

Wrapping Up

So, these are a number of the extremely most well-liked laptop programs by the scholars after the tenth and twelfth. Hope the record of programs has helped you to know your course choice after the twelfth. Ensure you select the most effective laptop course and many of the institutes are actually providing on-line lessons as a result of present pandemic. Better of Luck!

[ad_2]

On Hinton’s argument for superhuman AI.

0

[ad_1]

Might 30, 2023 · AGI opinion

Final week in Cambridge was Hinton bonanza. He visited the college city the place he was as soon as an undergraduate in experimental psychology, and gave a sequence of back-to-back talks, Q&A classes, interviews, dinners, and so forth. He was stopped on the road by random passers-by who recognised him from the lecture, college students and postdocs requested to take a selfie with him after his packed lectures.

Issues are very totally different from the final time I met Hinton in Cambridge: I used to be a PhD pupil, round 12 years in the past, in a Bayesian stronghold protected from deep studying affect. There was the same old electronic mail a couple of visiting tutorial, with a possibility to place your title down in the event you needed a 30 minute 1:1 dialog with him. He instructed us he discovered how the mind labored (once more)! The concept he shared again then would ultimately remodel to capsule networks. In fact everybody in our lab knew his work, however folks did not fairly go as loopy.

Whereas the craziness is partly defined by the success of deep studying, the Turing award, and so forth, it’s protected to say that his current change of coronary heart on AI existential danger performed a giant position, too. I’ve to say, given all of the press protection I already learn, I wasn’t anticipating a lot from the talks by means of content material. However I used to be fallacious there, the talks truly laid out a considerably technical argument. And it labored – some very good colleagues at the moment are contemplating a change of their analysis path in the direction of helpful AI.

I loved the talks, however did I purchase the arguments? I suppose I by no means actually do. So I assumed I will attempt my finest to put in writing it up right here, adopted by a pair factors of criticism I’ve been fascinated about since then. Although referring to many matters, together with subjective experiences and emotions LLMs might need, he very clearly stated he solely is certified to touch upon the variations between organic and digital intelligences, which he has studied for many years. Thus, I’ll deal with this argument, and whether or not this could, in itself, persuade you to alter or replace your views on AI and X-risk.

Abstract

  • Hinton compares intelligence on digital and analogue {hardware}.
  • Analogue {hardware} permits for decrease power price however at the price of mortality: algorithm and {hardware} are inseparable – the argument goes.
  • Digital intelligence has two benefits: aggregating studying from parallel experiences, and backpropagation which is implausible on analogue {hardware}
  • Hinton concludes these benefits can/will result in superhuman digital intelligence.
  • I critically consider the claims about each parallelism and the prevalence of backprop over biologically believable algorithms

Mortal Computation

For a very long time Hinton, and others, thought of our present neural network-based “synthetic brains”, which run on digital computer systems, to be inferior to organic brains. Digital neural networks fall quick on energy-efficiency: organic brains devour a lot much less power regardless that by some measures they’re orders of magnitude larger and extra advanced than at the moment’s digital neural networks.

Hinton subsequently got down to construct extra energy-efficient “brains” primarily based on analogue {hardware}. Digital computer systems, he argues, obtain good separation of software program and {hardware} by working on the stage of abstraction of discrete bits. This allows computation that runs on one pc to be precisely reproduced on another digital pc. On this sense, the software program is immortal: if the {hardware} dies, the algorithm can stay on on one other pc. This immortality comes at a excessive power value: guaranteeing digital computer systems work precisely, they devour numerous power.

That is in distinction with analogue {hardware}, which can comprise flaws and slight variations in conductances. Thus each analogue pc is barely totally different, and studying algorithms operating in them should adapt to the imperfections of analogue {hardware}.  Whereas they might devour rather a lot much less power, this additionally implies that a “mannequin” educated on one analogue machine can’t be simply ported to a different piece of {hardware} because it has tailored to the precise flaws and imprecisions of the chip it was educated on. Brains operating on analogue {hardware} are mortal: as soon as the {hardware} dies, the algorithm dies with it.

tldr: anaogue intelligence is power environment friendly however mortal, digital intelligence is immortal however energy-hungry

Benefits of digital brains

Hinton then realised that studying algorithms operating on digital units have benefits in comparison with “mortal” algorithms operating on analogue {hardware}.

Parallelism: Since computation is transportable, parallel copies of the identical mannequin could be run, and data/data could be exchanged between these copies utilizing high-bandwidth sharing of weights or gradient updates. Consequently, a digital “thoughts” may be performing tens of 1000’s of duties in parallel, then mixture the learnings from every of those parallel actions right into a single mind. In contrast, analogue brains can’t be parallelised this manner, as a result of the imprecision of {hardware} makes speaking details about the contents of the mannequin unimaginable. One of the best they will do is to “inform one another” what they discovered, and alternate info utilizing an inefficient type of data distillation.

Backpropagation: As well as, an additional benefit is that digital {hardware} permits for the implementation of algorithms like back-propagation. Hinton argued for a very long time that backpropagation appears biologically implausible, and can’t be carried out on analogue {hardware}. One of the best studying algorithms Hinton might provide you with for mortal computation is the forward-forward algorithm, which is resembles evolution methods. Its updates are rather a lot noisier in comparison with backpropagated gradients, and it actually would not scale to any first rate sized studying drawback.

These two observations: that digital computation could be parallelised, and permits a superior studying algorithm, backpropagation, which analogue brains can not implement, lead Hinton to conclude that digital brains will ultimately change into smarter than organic brains, and primarily based on current progress he believes this may occasionally occur a lot sooner he had beforehand thought, inside the subsequent 5-20 years.

Does the argument maintain water?

I can see quite a lot of methods wherein the brand new arguments laid out for why digital ‘brains’ shall be superior to organic ones might be attacked. Listed here are the 2 details of counterarguments:

How people be taught vs how Hinton’s brains be taught

Hinton’s argument truly critically hinges on synthetic neural networks being as environment friendly at studying from any single interplay as organic brains are. In spite of everything, it would not matter what number of parallel copies of an ML algorithm you run if the quantity of “studying” you get from every of these interactions is orders of magnitude smaller than what a human would be taught. So let’s take a look at this extra intently.

Hinton truly thought of a really restricted type of studying: imitation studying or distillation. He argues that when Alice teaches one thing to Bob, Bob will change the weights of his mind in order that he turns into extra more likely to say what Alice simply instructed her sooner or later. This can be how an LLM may be taught, nevertheless it’s not how people be taught from interplay. Let’s contemplate an instance.

As a non-native English speaker, I keep in mind once I first encountered the idea of irreversible binomials in English. I watched a language studying video whose content material was quite simple, one thing like:
“We at all times say apples and oranges, by no means oranges and apples.
We at all times say black and white, by no means white and black.
and so forth…”
Now, upon listening to this, I understood what this meant. I learnt the rule. Subsequent time I stated one thing about apples and oranges, I remembered that I should not say “oranges and apples”. Maybe I made a mistake, I remembered the rule exists, felt embarrassed, and doubtless generated some adverse reinforcement from which additional studying occurred. Listening to this one sentence modified how I apply this rule in plenty of particular circumstances, it did not make me extra more likely to go round and inform folks “We at all times say apples and oranges, by no means oranges and apples”, I understood tips on how to apply the rule to alter my behaviour in related circumstances.

Suppose you needed to show an LLM a brand new irreversible binomial, for instance that it ought to by no means say “LLMs and people”, it ought to at all times say “people and LLMs” as an alternative. With at the moment’s mannequin you might both

  • fine-tune on plenty of examples of sentences containing “people and LLMs”, or
  • present it RLHF situations the place a sentence containing “people and LLMs” was most well-liked by a human over the same sentence containing “LLMs and people”
  • or prepend the above rule to the immediate sooner or later, storing the rule in-context. (this one would not appear to be it might essentially work nicely)

In distinction, you’ll be able to merely inform this rule to a human, they may keep in mind it, recognise if the rule is related in a brand new scenario, and use it immediately, maybe even with out apply. This type of ‘metacognition’ – realizing what to be taught from content material, recognising if a mistake was made and studying from it – is at the moment is totally lacking from LLMs, though as I wrote above, maybe not for a really very long time.

Because of this, even when an LLM sat down with 10,000 physics lecturers concurrently, it would not essentially get 10,000 extra worth out of these interactions than a single organic mind spending time with a single physics trainer. That is as a result of LLMs be taught from examples, or from human preferences between numerous generated sentences, fairly than by understanding guidelines and later recalling them in related conditions. In fact, this may occasionally change very quick, this type of studying from instruction could also be attainable in LLMs, however the primary level is:

there’s a restrict to how a lot studying digital brains can extract from interacting with the world at the moment

The “it’ll by no means work” sort arguments

In one in every of his shows, Hinton reminded everybody that for a very long time, neural networks have been utterly dismissed: optimisation will get caught in a neighborhood minimal, we stated, they may by no means work. That turned out to be utterly false and deceptive, native minima will not be a limitation of deep studying in spite of everything.

But his present argument entails saying that “analogue brains” cannot have a studying algorithm nearly as good as backpropagation. That is largely primarily based on the proof that though he tried exhausting, he didn’t discover a biologically believable studying algorithm that’s as environment friendly as backpropagation in statistical studying. However what if that is simply what we at the moment suppose? In spite of everything the entire ML group might persuade ourselves that assist vector machines have been superior to neural networks? What if we prematurely conclude digital brains are superior to analogue brains simply because we’ve not but managed to make analogue computation work higher.

Abstract and Conclusion

To summarise, Hinton’s argument has two pillars:

  • that digital intelligence can create efficiencies over analogue intelligence by parallelism, aggregating studying from a number of interactions right into a single mannequin
  • and that digital intelligence permits basically extra environment friendly studying algorithms (backprop-based) which analogue intelligence can not match

As we’ve got seen, neither of those arguments are watertight, and each could be questioned. So how a lot credence ought to we placed on this?

I say it passes my bar for an attention-grabbing narrative. Nonetheless, as a story, I do not contemplate it a lot stronger than those we developed once we argued “strategies primarily based on non-convex optimisation will not work”, or “nonparametric ML strategies are finally superior to parametric ones”, or “very giant fashions will overfit”.

Whether or not LLMs, maybe LLMs with a small variety of bells and whistles used creatively will cross the ‘human stage’ bar (remedy most duties a human might accomplish by a text-based interface with the world)? I’m at the moment equally skeptical of the theoretically motivated arguments both means. I personally do not anticipate anybody to have the ability to produce a convincing sufficient argument that it is not attainable. I’m rather a lot much less skeptical about the entire premise than again in 2016 once I wrote about DeepMind’s pursuit of intelligence.

[ad_2]

Unlocking Non-public IP for Azure Software Gateway: Safety, Compliance, and Sensible Deployment

0

[ad_1]

If you’re chargeable for securing, scaling, and optimizing cloud infrastructure, this replace is for you. Based mostly on my current dialog with Vyshnavi Namani, Product Supervisor on the Azure Networking group, I’ll break down what non-public IP means in your setting, why it issues, and tips on how to get began. 


Software Gateway has lengthy been the go-to Layer 7 load balancer for internet site visitors in Azure. It manages, routes, and secures requests to your backend assets, providing SSL offloading and built-in Net Software Firewall (WAF) capabilities. However till now, public IPs had been the norm, which means publicity to the web and the necessity for additional safety layers.

With Non-public IP, your Software Gateway will be deployed completely inside your digital community (VNet), remoted from public web entry. This can be a enormous win for organizations with strict safety, compliance, or coverage necessities. Now, your site visitors stays inner, protected by Azure’s safety layers, and solely accessible to licensed entities inside your ecosystem.

🔒 No Public Publicity

With a private-only Software Gateway, no public IP is assigned. The gateway is accessible solely by way of inner networks, eliminating any direct publicity to the general public web. This removes a significant assault vector by preserving site visitors completely inside your trusted community boundaries.

📌 Granular Community Management

Non-public IP mode grants full management over community insurance policies. Strict NSG guidelines will be utilized (no particular exceptions wanted for Azure administration site visitors) and customized route tables can be utilized (together with a 0.0.0.0/0 path to drive outbound site visitors by on-premises or appliance-based safety checkpoints).

☑️ Compliance Alignment

Inner-only gateways assist meet enterprise compliance and knowledge governance necessities. Delicate purposes stay remoted inside non-public networks, aiding knowledge residency and stopping unintended knowledge exfiltration. Organizations with “no web publicity” insurance policies can now embody Software Gateway with out exception.

Architectural Concerns and Deployment Conditions

To deploy Azure Software Gateway with Non-public IP, it’s best to plan for the next:

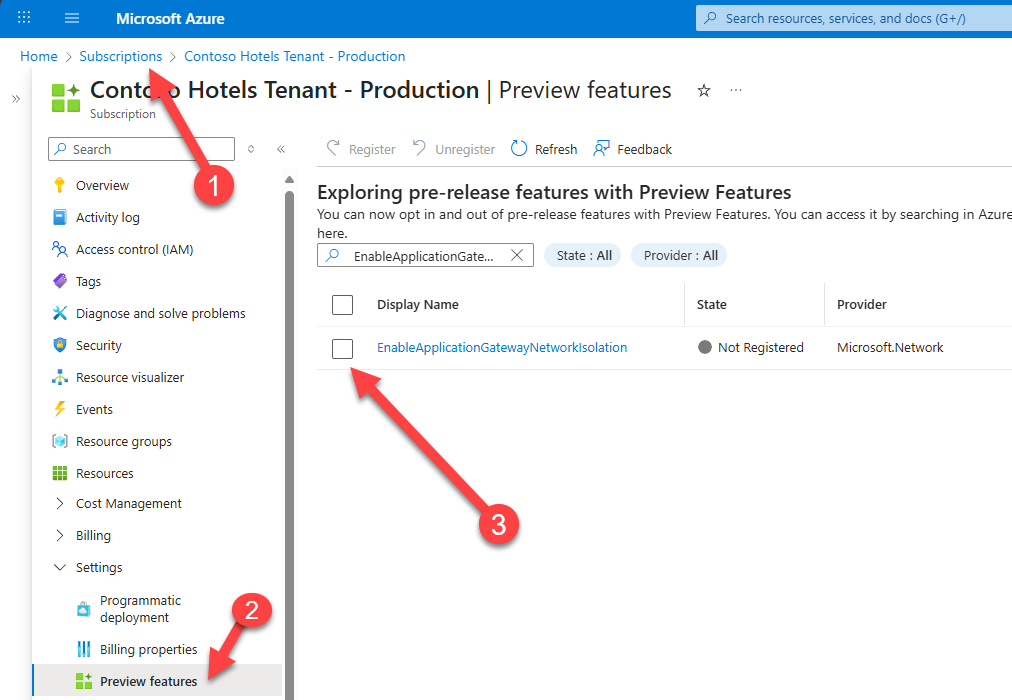
  • SKU & Characteristic Enablement: Use the v2 SKU (Standard_v2 or WAF_v2). The Non-public IP characteristic is GA however might require opt-in by way of the EnableApplicationGatewayNetworkIsolation flag in Azure Portal, CLI, or PowerShell.


  • Devoted Subnet: Deploy the gateway in a devoted subnet (no different assets allowed). Really useful measurement: /24 for v2. This permits clear NSG and route desk configurations.
  • NSG Configuration:
    • Inbound: Enable AzureLoadBalancer for well being probes and inner shopper IPs on required ports.
    • Outbound: Enable solely vital inner locations; apply a DenyAll rule to dam web egress.
  • Person-Outlined Routes (UDRs): Non-compulsory however really helpful for pressured tunneling. Set 0.0.0.0/0 to route site visitors by an NVA, Azure Firewall, or ExpressRoute gateway.
  • Shopper Connectivity: Guarantee inner shoppers (VMs, App Providers, on-prem customers by way of VPN/ExpressRoute) can attain the gateway’s non-public IP. Use Non-public DNS or customized DNS zones for identify decision.
  • Outbound Dependencies: For providers like Key Vault or telemetry, use Non-public Hyperlink or NAT Gateway if web entry is required. Plan NSG and UDRs accordingly.
  • Administration Entry: Admins should be on the VNet or linked community to check or handle the gateway. Azure handles control-plane site visitors internally by way of a administration NIC.
  • Migration Notes: Current gateways might require redeployment to change to private-only mode. Characteristic registration should be lively earlier than provisioning.

Listed below are a number of sensible eventualities the place deploying Azure Software Gateway with Non-public IP is very helpful:

🔐 Inner-Solely Net Purposes

Organizations internet hosting intranet portals, HR techniques, or inner dashboards can use Non-public IP to make sure these apps are solely accessible from inside the company community—by way of VPN, ExpressRoute, or peered VNets.

🏥 Regulated Industries (Healthcare, Finance, Authorities)

Workloads that deal with delicate knowledge (e.g., affected person information, monetary transactions) usually require strict community isolation. Non-public IP ensures site visitors by no means touches the general public web, supporting compliance with HIPAA, PCI-DSS, or authorities knowledge residency mandates.

🧪 Dev/Check Environments

Growth groups can deploy remoted environments for testing with out exposing them externally. This reduces danger and avoids unintentional knowledge leaks throughout early-stage improvement.

🌐 Hybrid Community Architectures

In hybrid setups the place on-prem techniques work together with Azure-hosted providers, Non-public IP gateways can route site visitors securely by ExpressRoute or VPN, sustaining internal-only entry and enabling centralized inspection by way of NVAs.

🛡️ Zero Belief Architectures

Non-public IP helps zero belief ideas by imposing least-privilege entry, denying web egress, and requiring specific NSG guidelines for all site visitors—splendid for organizations implementing segmented, policy-driven networks.

  1. Consider Your Workloads: Establish apps and providers that require internal-only entry.
  2. Plan Migration: Map out your VNets, subnets, and NSGs for a easy transition.
  3. Allow Non-public IP Characteristic: Register and deploy in your Azure subscription.
  4. Check Safety: Validate that solely meant site visitors flows by your gateway.

Non-public IP for Azure Software Gateway is an enchancment for safe, compliant, and environment friendly cloud networking. In case you’re an ITPRO managing infrastructure, now’s the time take a look at this characteristic and degree up your Azure structure.

Have questions or need to share your expertise? Drop a remark under.

Cheers!

Pierre

[ad_2]

The 2025 Information to Clever Knowledge Seize: From OCR to AI

[ad_1]


Your management staff is speaking about Generative AI. Your CIO has an AI-readiness initiative. The mandate from the highest is obvious: automate, innovate, and discover a aggressive edge with synthetic intelligence.

However you recognize the reality.

The crucial knowledge wanted to energy these AI initiatives is trapped in a 15-page scanned PDF from a brand new provider, a blurry picture of a invoice of lading, and an e-mail inbox overflowing with buy orders. The C-suite’s imaginative and prescient of an AI-powered future is colliding with the bottom reality of doc processing—and also you’re caught within the center.

This is not a novel downside. A surprising 77% of organizations admit their knowledge will not be prepared for AI, primarily as a result of it is locked on this actual form of info chaos. The largest hurdle to AI is not the accuracy of the mannequin; it is the enter.

This text is not about AI hype. It is concerning the foundational work of knowledge seize that makes all of it potential. We’ll break down learn how to resolve the enter downside, transferring from the brittle, template-based instruments of the previous to an clever system that delivers clear, structured, AI-ready knowledge with 95%+ accuracy.


The muse: Defining the what and why of information seize

To resolve an issue, we should first outline it accurately. The problem of managing paperwork has advanced far past easy paperwork. It’s a strategic knowledge downside that immediately impacts effectivity, price, and an organization’s means to innovate.

Core definitions and terminology

Data seize is the method of extracting info from unstructured or semi-structured sources and changing it right into a structured, machine-readable format.

To be exact, knowledge exists in three major varieties:

  • Unstructured knowledge: Info with no predefined knowledge mannequin, such because the textual content in an e-mail, the physique of a authorized contract, or a picture.
  • Semi-structured knowledge: Loosely organized knowledge that comprises tags or markers to separate semantic parts however doesn’t match a inflexible database mannequin. Invoices and buy orders are traditional examples.
  • Structured knowledge: Extremely organized knowledge that matches neatly right into a tabular format, like a database or a spreadsheet.

The objective of information seize is to rework unstructured and semi-structured inputs into structured outputs (like Markdown, JSON, or CSV) that can be utilized by different enterprise software program. In technical and tutorial circles, this complete course of is also known as Doc Parsing, whereas in analysis circles, it’s generally often known as Digital Knowledge Seize (EDC).

The strategic crucial: Why knowledge seize is a enterprise precedence

Efficient knowledge seize is not a back-office optimization; it’s the foundational layer for strategic initiatives, resembling digital transformation and AI-powered workflows.

Two realities of the fashionable enterprise drive this urgency:

  • The info explosion: Over 80% of all enterprise knowledge is unstructured, locked away in paperwork, photographs, and different hard-to-process codecs, in line with a number of trade analyses.
  • Fragmented know-how: This info chaos is compounded by a sprawling and disconnected know-how stack. The common group makes use of greater than 10 totally different info administration programs (e.g., ERP, CRM, file sharing), and research report that over half of those programs have low or no interoperability, leading to remoted knowledge silos.

This disjointed setup crammed with info chaos—the place crucial knowledge is trapped in unstructured paperwork and unfold throughout disconnected programs—makes a unified view of enterprise operations unattainable. This similar fragmentation is the first cause that strategic AI initiatives fail.

Superior purposes like Retrieval-Augmented Era (RAG) are significantly susceptible. RAG programs are designed to reinforce the accuracy and relevance of huge language fashions by retrieving info from a various array of exterior knowledge sources, together with databases, APIs, and doc repositories. The reliability of a RAG system’s output is solely depending on the standard of the information it could entry.

If the information sources are siloed, inconsistent, or incomplete, the RAG system inherits these flaws. It can retrieve fragmented info, resulting in inaccurate solutions, hallucinations, and in the end, a failed AI mission. Because of this fixing the foundational knowledge seize and structuring downside is the non-negotiable first step earlier than any profitable enterprise AI deployment.

The central battle: Handbook vs. automated processing

The choice of learn how to carry out knowledge seize has a direct and important influence on an organization’s backside line and operational capability.

  • Handbook knowledge seize: This conventional strategy includes human operators keying in knowledge. It’s basically unscalable. It’s notoriously gradual and liable to human error, with noticed error charges starting from 1% to 4%. A 2024 report from Ardent Companions discovered the typical all-inclusive price to course of a single bill manually is $17.61.
  • Automated knowledge seize: This contemporary strategy makes use of know-how to carry out the identical duties. Clever options ship 95%+ accuracy, course of paperwork in seconds, and scale to deal with tens of millions of pages with no proportional improve in price. The identical Ardent Companions report discovered that full automation reduces the per-invoice processing price to beneath $2.70—an 85% lower.

The selection is not about choice; it is about viability. In an ecosystem that calls for pace, accuracy, and scalability, automation is the logical path ahead.


The evolution of seize know-how: From OCR to IDP

The know-how behind automated knowledge seize has advanced considerably. Understanding this evolution is essential to avoiding the pitfalls of outdated instruments and appreciating the capabilities of recent programs.

The previous guard: Why conventional OCR fails

The primary wave of automation was constructed on a number of core applied sciences, with Optical Character Recognition (OCR) at its middle. OCR converts photographs of typed textual content into machine-readable characters. It was usually supplemented by:

  • Clever Character Recognition (ICR): An extension designed to interpret handwritten textual content.
  • Barcodes & QR Codes: Strategies for encoding knowledge into visible patterns for fast scanning.

The elemental flaw of those early instruments was their reliance on mounted templates and inflexible guidelines. This template-based strategy requires a developer to manually outline the precise coordinates of every knowledge discipline for a particular doc structure.

That is the know-how that created widespread skepticism about automation, as a result of it constantly fails in dynamic enterprise environments for a number of key causes:

  • It’s inefficient: A vendor shifting their emblem, including a brand new column, and even barely altering a font can break the template, inflicting the automation to fail and requiring pricey IT intervention.
  • It doesn’t scale: Creating and sustaining a novel template for each vendor, buyer, or doc variation is operationally unattainable for any enterprise with a various set of suppliers or purchasers.
  • It lacks intelligence: It struggles to precisely extract knowledge from complicated tables, differentiate between visually related however contextually totally different fields (e.g., Bill Date vs. Due Date), or reliably learn different handwriting.

In the end, this strategy compelled groups to spend extra time managing and fixing damaged templates than they saved on knowledge entry, main many to desert the know-how altogether.

The trendy answer: Clever Doc Processing (IDP)

Clever Doc Processing (IDP) is the AI-native successor to conventional OCR. As an alternative of counting on templates, IDP platforms use a mixture of AI, machine studying, and pc imaginative and prescient to know a doc’s content material and context, very similar to a human would.

The core engine driving fashionable IDP is commonly a kind of AI often known as a Imaginative and prescient-Language Mannequin (VLM). A VLM can concurrently perceive and course of each visible info (the structure, construction, and pictures on a web page) and textual knowledge (the phrases and characters). This twin functionality is what makes fashionable IDP programs basically totally different and vastly extra highly effective than legacy OCR.

A key technical differentiator on this course of is Doc Structure Evaluation (DLA). Earlier than trying to extract any knowledge, an IDP system’s VLM first analyzes the doc’s general visible construction to determine headers, footers, paragraphs, and tables. This means to fuse visible and semantic info is why IDP platforms, resembling Nanonets, can precisely course of any doc format from day one, without having a pre-programmed template. That is usually described as a “Zero-Shot” or “Immediate Studying” functionality, the place the mannequin learns and adapts to new codecs on the fly.

The efficiency leap enabled by this AI-driven strategy is immense. A 2024 examine centered on transcribing complicated handwritten historic paperwork—a activity far more difficult than processing typical enterprise invoices—discovered that fashionable multimodal LLMs (the engine behind IDP) had been 50 instances quicker and 1/fiftieth the fee of specialised legacy software program. Crucially, they achieved state-of-the-art accuracy “out of the field” with out the intensive, document-specific fine-tuning that older programs required to perform reliably.

Adjoining applied sciences: The broader automation ecosystem

IDP is a specialised software for turning unstructured doc knowledge into structured info. It usually works in live performance with different automation applied sciences to create an precise end-to-end workflow:

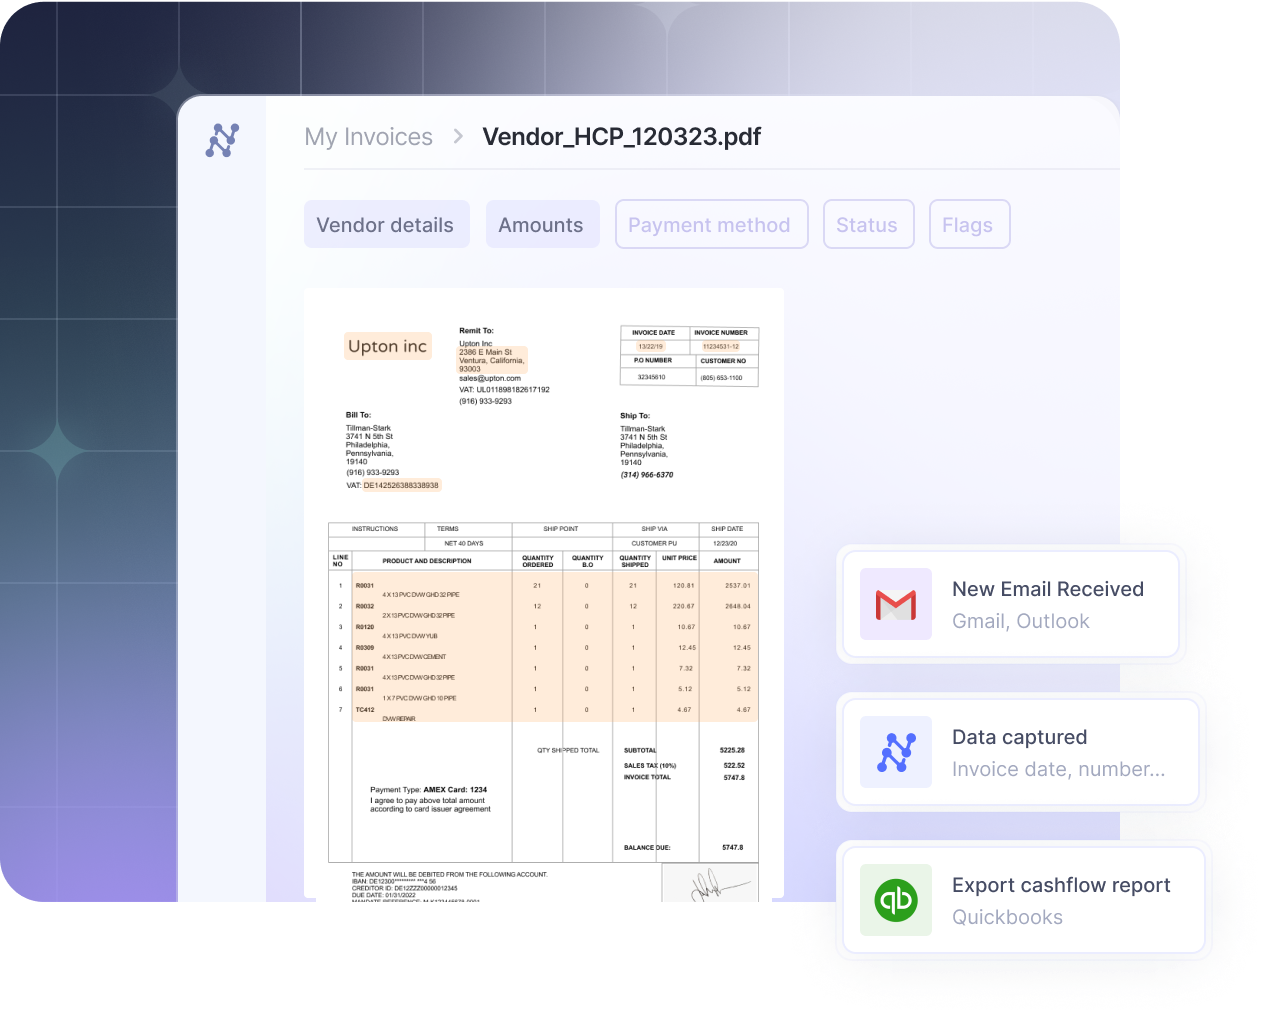
  • Robotic Course of Automation (RPA): RPA bots act as digital employees that may orchestrate a workflow. For instance, an RPA bot might be programmed to observe an e-mail inbox, obtain an bill attachment, ship it to an IDP platform for knowledge extraction, after which use the structured knowledge returned by the IDP system to finish a activity in an accounting utility.
  • Change Knowledge Seize (CDC): Whereas IDP handles unstructured paperwork, CDC is a extra technical, database-level technique for capturing real-time modifications (inserts, updates, deletes) to structured knowledge. It is a crucial know-how for contemporary, event-driven architectures the place programs like microservices want to remain synchronized immediately.

Collectively, these applied sciences type a complete automation toolkit, with IDP serving the important position of changing the chaotic world of unstructured paperwork into the clear, dependable knowledge that each one different programs rely upon.


The operational blueprint: How knowledge seize works in observe

Trendy clever knowledge seize will not be a single motion however a scientific, multi-stage pipeline. Understanding this operational blueprint is important for transferring from chaotic, guide processes to streamlined, automated workflows. The complete course of, from doc arrival to remaining knowledge supply, is designed to make sure accuracy, implement enterprise guidelines, and allow true end-to-end automation.

The trendy knowledge seize pipeline

An efficient IDP system operates as a steady workflow. This pipeline is commonly often known as a modular system for doc parsing and aligns with the information administration lifecycle required for superior AI purposes.

Step 1: Knowledge ingestion

The method begins with getting paperwork into the system. A versatile platform should assist a number of ingestion channels to deal with info from any supply, together with:

  • Electronic mail forwarding: Routinely processing invoices and different paperwork despatched to a devoted e-mail tackle (e.g., invoices@firm.com).
  • Cloud storage integration: Watching and mechanically importing information from cloud folders in Google Drive, OneDrive, Dropbox, or SharePoint.
  • API uploads: Permitting direct integration with different enterprise purposes to push paperwork into the seize workflow programmatically.

Step 2: Pre-processing and classification

As soon as ingested, the system prepares the doc for correct extraction. This includes automated picture enhancement, resembling correcting skew and eradicating noise from scanned paperwork.

Critically, the AI then classifies the doc. Utilizing visible and textual evaluation, it determines the doc sort—immediately distinguishing a US-based W-2 type from a UK-based P60, or an bill from a invoice of lading—and routes it to the suitable specialised mannequin for extraction.

Step 3: AI-powered extraction

That is the core seize step. As established, IDP makes use of VLMs to carry out Doc Structure Evaluation, understanding the doc’s construction earlier than extracting knowledge fields. This enables it to seize info precisely:

  • Headers and footers
  • Line objects from complicated tables
  • Handwritten notes and signatures

This course of works immediately on any doc format, eliminating the necessity for creating or sustaining templates.

Step 4: Validation and high quality management

Extracted knowledge is ineffective if it’s not correct. That is probably the most crucial step for reaching belief and enabling excessive charges of straight-through processing (STP). Trendy IDP programs validate knowledge in real-time by way of a sequence of checks:

  • Enterprise rule enforcement: Making use of customized guidelines, resembling flagging an bill if the total_amount doesn’t equal the sum of its line_items plus tax.
  • Database matching: Verifying extracted knowledge in opposition to an exterior system of document. This might contain matching a vendor’s VAT quantity in opposition to the EU’s VIES database, guaranteeing an bill complies with PEPPOL e-invoicing requirements prevalent in Europe and ANZ, or validating knowledge in accordance with privateness laws like GDPR and CCPA.
  • Exception dealing with: Solely paperwork that fail these automated checks are flagged for human evaluation. This exception-only workflow permits groups to focus their consideration on the small share of paperwork that require it.

This validation stage aligns with the Confirm step within the RAG pipeline, which confirms knowledge high quality, completeness, consistency, and uniqueness earlier than downstream AI programs use it.

Step 5: Knowledge integration and supply

The ultimate step is delivering the clear, verified, and structured knowledge to the enterprise programs the place it’s wanted. The info is usually exported in a standardized format, resembling JSON or CSV, and despatched on to its vacation spot by way of pre-built connectors or webhooks, thereby closing the loop on automation.

Construct vs. purchase: The position of open supply and foundational fashions

For organizations with deep technical experience, a construct strategy utilizing open-source instruments and foundational fashions is an choice. A staff may assemble a pipeline utilizing foundational libraries like Tesseract or PaddleOCR for the preliminary textual content recognition.

A extra superior start line can be to make use of a complete open-source library like our personal DocStrange. This library goes far past fundamental OCR, offering a robust toolkit to extract and convert knowledge from almost any doc sort—together with PDFs, Phrase paperwork, and pictures—into clear, LLM-ready codecs like Markdown and structured JSON. With choices for 100% native processing, it additionally affords a excessive diploma of privateness and management.

For the intelligence layer, a staff may then combine the output from DocStrange with a general-purpose mannequin, resembling GPT-5 or Claude 4.1, by way of an API. This requires subtle immediate engineering to instruct the mannequin to search out and construction the precise knowledge fields wanted for the enterprise course of.

Nevertheless, this construct path carries important overhead. It requires a devoted engineering staff to:

  • Handle the whole pipeline: Stitching the elements collectively and constructing all the mandatory pre-processing, post-processing, and validation logic.
  • Construct a person interface: That is probably the most crucial hole. Open-source libraries present no front-end for enterprise customers (like AP clerks) to handle the inevitable exceptions, making a everlasting dependency on builders for each day operations.
  • Deal with infrastructure and upkeep: Managing dependencies, mannequin updates, and the operational price of working the pipeline at scale.

A purchase answer from an IDP platform, resembling Nanonets’ business providing, productizes this complete complicated workflow. It packages the superior AI, a user-friendly interface for exception dealing with, and pre-built integrations right into a managed, dependable, and scalable service.

After extraction: The mixing ecosystem

Knowledge seize doesn’t exist in a vacuum. Its major worth is unlocked by its means to feed different core enterprise programs and break down info silos. Like we mentioned earlier, the largest problem is the dearth of interoperability between these programs.

An clever knowledge seize platform acts as a common translator, making a central level of management for unstructured knowledge and feeding clear info to:

  • ERP and Accounting Programs: For totally automated accounts payable, platforms supply direct integrations with software program resembling SAP, NetSuite, QuickBooks, and Xero.
  • Doc Administration Programs (DMS/ECM): For safe, long-term archival in platforms like SharePoint and OpenText.
  • Robotic Course of Automation (RPA) Bots: Offering structured knowledge to bots from distributors like UiPath or Automation Wherever to carry out rule-based duties.
  • Generative AI/RAG Pipelines: Delivering clear, verified, and structured knowledge is the non-negotiable first step to constructing a dependable inner data base for AI purposes.

The objective is to create a seamless move of data that allows true end-to-end course of automation, from doc arrival to remaining motion, with minimal to no human intervention.


The enterprise worth: ROI and purposes

The first worth of any know-how is its means to resolve concrete enterprise issues. For clever knowledge seize, this worth is demonstrated by way of measurable enhancements in price, pace, and knowledge reliability, which in flip assist strategic enterprise aims.

1. Measurable price discount

Probably the most important consequence of clever knowledge seize is the discount of operational prices. By minimizing the guide labor required for doc dealing with, organizations can obtain substantial financial savings. Actual-world implementation outcomes validate this monetary achieve.

For instance, UK-based Ascend Properties reported an 80% saving in processing prices after automating its upkeep invoices with Nanonets. This allowed the corporate to scale the variety of properties it managed from 2,000 to 10,000 with no proportional improve in administrative headcount.

2. Elevated processing velocity

Automating knowledge seize shrinks enterprise cycle instances from days to minutes. The Ardent Companions report additionally discovered that Finest-in-Class AP departments—these with excessive ranges of automation—course of and approve invoices in simply 3 days, in comparison with the 18-day common for his or her friends. This velocity improves money move administration and strengthens vendor relationships.

As a case instance, the worldwide paper producer Suzano Worldwide utilized Nanonets to scale back its buy order processing time from 8 minutes to only 48 seconds, a 90% discount in time that enabled quicker gross sales order creation of their SAP system.

3. Verifiable knowledge accuracy

Whereas guide knowledge entry is topic to error charges as excessive as 4%, fashionable IDP options constantly obtain 95%+ accuracy by eliminating human enter and utilizing AI for validation. This stage of information integrity is a crucial prerequisite for any strategic initiative that depends on knowledge, from enterprise intelligence to AI.

4. Strengthened safety and auditability

Automated programs create an immutable, digital audit path for each doc that’s processed. This supplies a transparent document of when a doc was obtained, what knowledge was extracted, and who accepted it. This auditability is important for assembly compliance with monetary laws just like the Sarbanes-Oxley Act (SOX) and knowledge privateness legal guidelines resembling GDPR in Europe and the CCPA in the US.

5. Scalable operations and workforce optimization

Clever knowledge seize decouples doc quantity from headcount. Organizations can deal with important progress without having to rent extra knowledge entry workers. Extra strategically, it permits for the optimization of the prevailing workforce. This aligns with a key development recognized in a 2023 McKinsey report, the place automation frees staff from repetitive guide and cognitive duties, permitting them to concentrate on higher-value work that requires superior technological, social, and emotional abilities.

Actual-world purposes throughout key industries

The worth of clever knowledge seize is realized within the tangible methods it streamlines core enterprise processes. Beneath are sensible knowledge extraction workflows for various industries, illustrating how info is reworked from disorganized paperwork into actionable knowledge in key enterprise programs.

a. Finance and Accounts Payable

That is among the many most typical and highest-impact use case.

The method earlier than IDP: Invoices arrive in an AP staff’s shared inbox. A clerk manually downloads every PDF, keys knowledge like vendor title, PO quantity, and line-item quantities into an Excel sheet, after which re-enters that very same knowledge into an ERP like NetSuite or SAP. This multi-step, guide course of is gradual, resulting in late fee charges and missed early-payment reductions.

The workflow with Clever Knowledge Seize:

  1. Invoices, together with these compliant with PEPPOL requirements within the EU and Australia or commonplace PDFs within the US, are mechanically fetched from a devoted inbox (e.g., invoices@firm.com).
  2. The IDP platform extracts and validates key knowledge—vendor title, bill quantity, line objects, and VAT/GST quantities.
  3. The system performs an automatic 2-way or 3-way match in opposition to buy orders and items receipt notes residing within the ERP system.
  4. As soon as validated, the information is exported immediately into the accounting system—QuickBooks, Xero, NetSuite, or SAP—to create a invoice that’s prepared for fee, usually with no human contact.

The end result: The AP automation answer supplier Augeo used this workflow to scale back the time its staff spent on bill processing from 4 hours per day to only half-hour—an 88% discount in guide work.

b. Logistics and Provide Chain

In logistics, pace and accuracy of documentation immediately influence supply instances and money move.

The method earlier than IDP: A driver completes a supply and will get a signed Proof of Supply (POD), usually a blurry picture or a multi-part carbon copy. A logistics coordinator on the again workplace manually deciphers the doc and keys the cargo ID, supply standing, and any handwritten notes right into a Transport Administration System (TMS). Delays or errors on this course of maintain up billing and cut back buyer visibility.

The workflow with Clever Knowledge Seize:

  1. Drivers add photographs of Payments of Lading (BOLs) and signed PODs by way of a cellular app immediately from the sector.
  2. The IDP system’s VLM engine immediately reads the often-distorted or handwritten textual content to extract the consignee, cargo IDs, and supply timestamps.
  3. This knowledge is validated in opposition to the TMS in real-time.
  4. The system mechanically updates the cargo standing to delivered, which concurrently triggers an bill to be despatched to the shopper and updates the customer-facing monitoring portal.

The end result: This workflow accelerates billing cycles from days to minutes, reduces disputes over supply instances, and supplies the real-time provide chain visibility that prospects now count on.

c. Insurance coverage and Healthcare

This sector is burdened by complicated, standardized varieties which can be crucial for affected person care and income cycles.

The method earlier than IDP: Workers at a clinic manually transcribe affected person knowledge from registration varieties and medical declare varieties (just like the CMS-1500 within the US) into an Digital Well being File (EHR) system. This gradual course of introduces a major danger of information entry errors that may result in declare denials or, worse, have an effect on affected person care.

The workflow with Clever Knowledge Seize:

  1. Scanned affected person varieties or digital PDFs of claims are ingested by the IDP system.
  2. The platform precisely extracts affected person demographics, insurance coverage coverage numbers, prognosis codes (e.g., ICD-10), and process codes.
  3. The system mechanically validates the information for completeness and might test coverage info in opposition to an insurer’s database by way of an API.
  4. Verified knowledge is then seamlessly pushed into the EHR or a claims adjudication workflow.

The end result: The end result of this automated workflow is a major discount in guide intervention and operational price. In response to McKinsey’s Finest-in-class digital doc processing: A payer perspective report, main healthcare payers use this sort of an strategy to automate 80 to 90 p.c of their claims consumption course of. This resulted in a discount of guide touchpoints by greater than half and cuts the fee per declare by 30 to 40 p.c. That is validated by suppliers like Outlined Bodily Remedy, which automated its CMS-1500 type processing with Nanonets and lowered its declare processing time by 85%.


The strategic playbook: Implementation and future outlook

Understanding the know-how and its worth is step one. The following is placing that data into motion. A profitable implementation requires a clear-eyed view of the challenges, a sensible plan, and an understanding of the place the know-how is headed.

Overcoming the implementation hurdles

Earlier than starting an implementation, it is important to acknowledge the first obstacles that trigger automation initiatives to fail.

  • The info high quality hurdle: That is probably the most important problem. As established in AIIM’s 2024 report, the first barrier to profitable AI initiatives is the standard of the underlying knowledge. The primary points are knowledge silos, redundant info, and an absence of information standardization throughout the enterprise. An IDP mission have to be seen as an information high quality initiative at first.
  • The organizational hurdle: The identical AIIM report highlights a major abilities hole inside most organizations, significantly in areas like AI governance and workflow course of design. This underscores the worth of adopting a managed IDP platform that doesn’t require an in-house staff of AI consultants to configure and preserve.
  • The mixing hurdle: With the typical group utilizing greater than 10 totally different info administration programs, making a seamless move of information is a serious problem. A profitable knowledge seize technique should prioritize options with strong, versatile APIs and pre-built connectors to bridge these system gaps.

A sensible plan for implementation

A profitable IDP implementation doesn’t require an enormous bang strategy. A phased, methodical rollout that proves worth at every stage is the simplest means to make sure success and stakeholder buy-in.

Part 1: Begin small with a high-impact pilot

As an alternative of trying to automate each doc course of without delay, choose a single, high-pain, high-volume workflow. For many organizations, that is AP bill processing. Step one is to determine a transparent baseline: calculate your present common price and processing time for a single doc in that workflow.

Part 2: Validate with a no-risk take a look at

De-risk the mission by proving the know-how’s accuracy in your particular paperwork earlier than making a major funding. Collect 20-30 real-world examples of your chosen doc sort, ensuring to incorporate the messy, low-quality scans and strange codecs. Use an IDP platform that provides a free trial to check its out-of-the-box efficiency on these information.

Part 3: Map the total workflow

Knowledge extraction is just one piece of the puzzle. To attain true automation, it’s essential to map the whole course of from doc arrival to its remaining vacation spot. This includes configuring the 2 most crucial elements of an IDP platform:

  • Validation guidelines: Outline the enterprise logic that ensures knowledge high quality (e.g., matching a PO quantity to your ERP knowledge).
  • Integrations: Arrange the connectors that can mechanically ship the clear knowledge to downstream programs.

Part 4: Measure and scale

As soon as your pilot workflow is stay, observe its efficiency in opposition to your preliminary baseline. The important thing metrics to observe are Accuracy Charge, Processing Time per Doc, and STP Charge (the share of paperwork processed with no human intervention). The confirmed ROI from this primary course of can then be used to construct the enterprise case for scaling the answer to different doc sorts and departments.

The longer term outlook: What’s subsequent for knowledge seize

The sector of clever knowledge seize continues to evolve quickly. As of August 2025, three key developments are shaping the way forward for the know-how:

  • Generative AI and RAG: The first driver for the way forward for knowledge seize is its position because the important gasoline for Generative AI. As extra corporations construct inner RAG programs to permit staff and prospects to “ask questions of their knowledge,” the demand for high-quality, structured info extracted from paperwork will solely intensify.
  • Multimodal AI: The know-how is transferring past simply textual content. As detailed within the Doc Parsing Unveiled analysis paper, the following technology of IDP is powered by superior VLMs that may perceive and extract info from photographs, charts, and tables inside a doc and clarify their relationship to the encircling textual content.
  • Agentic AI: This represents the following frontier, the place AI strikes from being a software that responds to a system that acts. In response to a 2025 PwC report, these AI brokers are designed to automate complicated, multi-step workflows autonomously. For instance, an AP agent could possibly be tasked with resolving an bill discrepancy. It will then independently retrieve the bill and PO, examine them, determine the mismatch, draft a clarification e-mail to the seller, and create a follow-up activity within the applicable system.

Conclusion: From a secular activity to a strategic enabler

Clever knowledge seize is not a easy digitization activity; it’s the foundational layer for the fashionable, AI-powered enterprise. The know-how has advanced from brittle, template-based OCR to clever, context-aware programs that may deal with the complexity and variety of real-world enterprise paperwork with verifiable accuracy and a transparent return on funding.

By fixing the enter downside, clever knowledge seize breaks down the data silos which have lengthy plagued companies, remodeling unstructured knowledge from a legal responsibility right into a strategic asset. For the pragmatic and skeptical professionals on the entrance traces of doc processing, the guarantees of automation are lastly changing into a sensible actuality.

Your subsequent steps

  1. Calculate your price of inaction. Establish your single most painful doc course of. Use the trade common of $17.61 per manually processed bill as a place to begin and calculate your present month-to-month price. That is the finances you’re already spending on inefficiency.
  2. Run a 15-minute accuracy take a look at. Collect 10 various examples of that downside doc. Use a free trial of an IDP platform to see what stage of accuracy you’ll be able to obtain by yourself information in minutes, with none customized coaching.
  3. Whiteboard one end-to-end workflow. Map the whole journey of a single doc, from its arrival in an e-mail inbox to its knowledge being usable in your ERP or accounting system. Each guide touchpoint you determine is a goal for automation. This map is your blueprint for reaching true straight-through processing.

FAQs

What’s the distinction between knowledge seize and OCR?

Optical Character Recognition (OCR) is a particular know-how that converts photographs of textual content into machine-readable characters. It’s a single, foundational part of a bigger course of.

Knowledge Seize (or extra precisely, Clever Doc Processing) is the entire, end-to-end enterprise workflow. This workflow contains ingestion, pre-processing, classification, knowledge extraction (which makes use of OCR as one among its instruments), automated validation in opposition to enterprise guidelines, and eventually, integration into different enterprise programs.

How does clever knowledge seize guarantee knowledge accuracy?

Clever knowledge seize makes use of a multi-layered strategy to make sure accuracy far past what easy OCR can present:

Contextual AI Extraction: Using VLMs permits the system to know the doc’s context, decreasing the chance of misinterpreting fields (e.g., complicated a “due date” with an “bill date”).

Confidence Scoring: The AI assigns a confidence rating to every extracted discipline, mechanically flagging low-confidence knowledge for human evaluation.

Automated Validation Guidelines: The system mechanically checks the extracted knowledge in opposition to your particular enterprise logic (e.g., confirming that subtotal + tax = whole quantity).

Database Matching: It could validate knowledge in opposition to exterior databases, resembling matching a purchase order order quantity on an bill in opposition to a listing of open POs in your ERP system.

What’s one of the best ways to seize knowledge from handwritten varieties?

One of the simplest ways to seize knowledge from handwritten varieties is to make use of a contemporary IDP answer powered by superior AI and multimodal Giant Language Fashions (LLMs). Whereas older know-how referred to as Clever Character Recognition (ICR) was used for this, a 2024 analysis paper titled Unlocking the Archives discovered that fashionable LLMs obtain state-of-the-art accuracy on handwritten textual content out-of-the-box. They’re 50 instances quicker and 1/fiftieth the price of specialised legacy software program, and they don’t require the impractical step of being educated on a particular individual’s handwriting to be efficient.

How do you calculate the ROI of automating knowledge seize?

The ROI is calculated by evaluating the overall price of your guide course of to the overall price of the automated course of. A easy framework is:

Calculate Your Handbook Price: Decide your price per doc (Time per doc x Worker hourly price) + Prices of fixing errors. A broadly used trade benchmark for a single bill is $17.61.

Calculate Your Automated Price: This contains the software program subscription charge plus the price of labor for dealing with the small share of exceptions flagged for guide evaluation. The benchmark for a totally automated bill is beneath $2.70.

Decide Month-to-month Financial savings: Whole Month-to-month Handbook Price – Whole Month-to-month Automated Price.

Calculate Payback Interval: Whole Upfront Implementation Price / Month-to-month Financial savings.

Can knowledge seize software program combine with ERP programs like SAP or NetSuite?

Sure. Seamless integration with Enterprise Useful resource Planning (ERP) and accounting programs is a crucial characteristic of any fashionable knowledge seize platform. That is important for reaching true end-to-end automation for processes like accounts payable. Main IDP options supply a mixture of pre-built connectors for fashionable programs like SAP, NetSuite, QuickBooks, and Xero, in addition to versatile APIs for customized integrations. This enables the clear, validated knowledge to move immediately into your system of document with none guide re-entry.

How does automated knowledge seize assist with GDPR and CCPA compliance?

Automated knowledge seize helps with compliance for laws like GDPR (within the EU) and CCPA (within the US) in a number of key methods:

Creates a Clear Audit Path: The system supplies an immutable digital log of each doc that’s processed, displaying what knowledge was accessed, by whom, and when. That is important for accountability.

Permits Knowledge Minimization: Platforms might be configured to solely extract mandatory knowledge fields and might mechanically redact or masks delicate Personally Identifiable Info (PII).

Strengthens Entry Management: Not like paper paperwork, digital knowledge might be protected with strict, role-based entry controls, guaranteeing that solely licensed personnel can view delicate info.

Supplies Safe Storage and Deletion: The info is dealt with in safe, encrypted environments, and platforms can implement knowledge retention insurance policies to mechanically delete knowledge in line with regulatory necessities.

[ad_2]

OxygenOS 16 set to roll out subsequent month, and these are the primary OnePlus telephones to get it

0

[ad_1]

What it is advisable know

  • OnePlus detailed its listing of gadgets getting ready to obtain its OxygenOS 16 replace, which is able to start rolling out in November.
  • The OnePlus 13, 13R, and 13s are first on the listing, joined by the OnePlus 12 sequence telephones and some tablets.
  • OnePlus will proceed its replace roll out in December earlier than a number of older, past-gen fashions get it in Q1 2026.

We’re all wrapped up within the newest OnePlus bulletins, concerning each OxygenOS 16 (Android 16) and Thoughts Area, however there’s extra to unravel: rollout dates.

At present (Oct 17), OnePlus detailed an inventory of its telephones getting ready to obtain its main OxygenOS 16 replace, and issues will start in November for its latest gadgets. The OnePlus 13 and OnePlus 12 are first on the listing to obtain the OxygenOS 16 replace in November, which incorporates the 13R, 13s, and the 12R. Nonetheless, the corporate states that its OnePlus Open, Pad 3, and Pad 2 are on deck for subsequent month, too.

[ad_2]

New smoothing algorithms in particles – Statisfaction

0

[ad_1]

Hello,
only a fast publish to announce that particles now implements a number of of the smoothing algorithms launched in our latest paper with Dang on the complexity of smoothing algorithms. Here’s a plot that compares their operating time for a given variety of particles:

All these algorithms are primarily based on FFBS (ahead filtering backward smoothing). The primary two aren’t new. O(N^2) FFBS is the classical FFBS algorithm, which as complexity O(N^2).

FFBS-reject makes use of (pure) rejection to decide on the ancestors within the backward step. In our paper, we clarify that the operating time of FFBS-reject is random, and will have an infinite variance. Discover how massive are the corresponding bins, and the big variety of outliers.

To alleviate this challenge, we launched two new FFBS algorithms; FFBS-hybrid tries to make use of rejection, however stops after N failed makes an attempt (after which change to the extra in depth, precise methodology). FFBS-MCMC merely makes use of a (single) MCMC step.

Clearly, these two variants runs quicker, however FFBS-MCMC wins the cake. This has to do with the inherent problem in implementing (effectively) rejection sampling in Python. I’ll weblog about that time in a while (hopefully quickly). Additionally, the operating time of FFBS-MCMC is deterministic and is O(N).

That’s it. If you wish to know extra about these algorithms (and different smoothing algorithms), take a look on the paper. The script that generated the plot above can be obtainable in particles (in folder papers/complexity_smoothing). This experiment was carried out on the identical mannequin as the instance as within the chapter on smoothing within the guide, primarily. I ought to add that, on this experiment, the Monte Carlo variance of the output is basically the identical for the 4 algorithms (so evaluating them solely by way of CPU time is honest).


Revealed by Nicolas Chopin

Professor of Statistics at ENSAE, IPP

[ad_2]

‘Nightmare’ calculation could also be too tough for even quantum computer systems

0

[ad_1]

Some issues are too onerous for even quantum computer systems

Yaroslav Kushta/Getty Photos

Researchers have recognized a “nightmare situation” calculation associated to unique kinds of quantum matter that may be not possible to resolve, even for a really environment friendly quantum pc.

With out the complexity of quantum states of matter, figuring out the section of a fabric could be comparatively easy. Take water, for instance – it’s easy to inform whether or not it’s in a stable or liquid section. The quantum model of this activity, nonetheless, could be a lot extra daunting. Thomas Schuster on the California Institute of Know-how and his colleagues have now confirmed figuring out quantum phases of matter can get too troublesome even for quantum computer systems.

They mathematically analysed a situation the place a quantum pc is introduced with a set of measurements a couple of quantum state of an object and has to establish its section. Schuster says this isn’t all the time an not possible drawback, however his staff proved for a considerable portion of quantum phases of matter – the extra unique family members of liquid water and ice, corresponding to “topological” phases that characteristic odd electrical currents – a quantum pc could have to calculate for an impossibly very long time. The state of affairs is just like the worst model of a lab experiment the place figuring out the properties of a pattern would require preserving an instrument on for billions or trillions of years.

This doesn’t make quantum computer systems virtually out of date for this activity. Schuster says these phases are unlikely to indicate up in precise experiments with supplies or quantum computer systems – they’re extra of a diagnostic for the place our understanding of quantum computation is presently missing than an imminent sensible risk. “They’re like a nightmare situation that may be very dangerous if it seems. It in all probability doesn’t seem, however we should always perceive it higher,” he says.

Invoice Fefferman on the College of Chicago in Illinois says this course of examine opens intriguing questions on what computer systems can do usually. “This can be saying one thing concerning the limits of computation extra broadly, that regardless of attaining dramatic speed-ups for sure particular duties, there’ll all the time be duties which can be nonetheless too onerous even for environment friendly quantum computer systems,” he says.

Mathematically, the brand new examine connects sides of quantum data science which can be utilized in quantum cryptography with concepts elementary to the physics of matter, so it might additionally assist advance each, he says.

Going ahead, the staff desires to broaden their evaluation to quantum phases of matter which can be extra energetic, or excited, that are recognized to be onerous to compute much more broadly.

Subjects:

[ad_2]

Understanding listeria: The refrigerator-resistant micro organism

0

[ad_1]

Widespread signs

Listeriosis typically begins with non-specific, flu-like or gastrointestinal signs.

Many wholesome individuals have solely delicate sickness (particularly when it causes gastrointestinal an infection). In these circumstances, onset is sudden (often 1–2 days after consuming) and lasts a number of days. Typical signs of delicate listerial gastroenteritis embody:

  • Excessive Fever
  • Chills
  • Muscle or joint aches (body-wide) and normal fatigue
  • Nausea
  • Vomiting
  • Watery diarrhea
  • Headache


These delicate signs alone don’t affirm listeriosis, however they typically precede the intense types. In actual fact, L. monocytogenes was proven to trigger outbreaks of febrile gastroenteritis. In such circumstances, practically all contaminated individuals had fever and lots of had diarrhea.

Invasive signs (sepsis/meningitis)

If listeria spreads into the bloodstream or central nervous system, signs turn into extra extreme:

  • Stiff neck
  • Photophobia (gentle sensitivity)
  • Indicators of meningitis if the mind/meninges are contaminated
  • Confusion, drowsiness or lack of steadiness (if encephalitis or brainstem an infection)
    Respiratory signs (e.g. cough, issue respiratory) generally happen in very unwell circumstances
  • Seizures or focal neurological deficits might happen in extreme CNS an infection
  • In pregnant girls, invasive an infection can result in
    • Untimely supply
    • Miscarriage
    • Stillbirth
    • An infection of the new child


In pregnant girls, signs might stay delicate or absent even when the fetus is contaminated. Typically the primary signal is fetal misery.

As a result of early signs could be very nonspecific (flu-like), listeriosis is commonly not suspected till it turns into invasive. Medical doctors ought to suspect listeriosis if a high-risk particular person (pregnant, aged, immunosuppressed) presents with unexplained fever and muscle aches or any indicators of meningitis, particularly after consuming high-risk meals.

When listeriosis progresses past these preliminary signs, severe issues can develop.

Problems

Invasive listeriosis could be life-threatening and should trigger lasting harm. Key issues embody:

  • Meningitis/encephalitis: Listeria generally causes bacterial meningitis or brainstem encephalitis (“rhombencephalitis”)
  • Sepsis and organ failure: If the micro organism invade the bloodstream, contaminated individuals can develop septic shock with multi-organ failure (kidneys, liver, lungs, coronary heart)
  • Being pregnant/neonatal: An infection throughout being pregnant regularly results in fetal or neonatal loss. Miscarriage (spontaneous abortion) and stillbirth are frequent outcomes. If infants are born alive, they could develop early-onset sepsis (inside 1–3 days of beginning) or late-onset meningitis (1–3 weeks)

Endocarditis, abscesses, different infections: Hardly ever, Listeria can infect the center valves (endocarditis), bones/joints (osteomyelitis), or eyes. Such focal infections may trigger extreme harm.


[ad_2]

Prediction intervals with gradient boosting machine

0

[ad_1]

Introduction
Machine studying strategies, reminiscent of ensemble resolution timber, are broadly used to foretell outcomes primarily based on information. Nevertheless, these strategies typically give attention to offering level predictions, which limits their potential to quantify prediction uncertainty. In lots of functions, reminiscent of healthcare and finance, the aim just isn’t solely to foretell precisely but in addition to evaluate the reliability of these predictions. Prediction intervals, which offer decrease and higher bounds such that the true response lies inside them with excessive chance, are a dependable instrument for quantifying prediction accuracy. A great prediction interval ought to meet a number of standards: it ought to provide legitimate protection (outlined under) with out counting on robust distributional assumptions, be informative by being as slim as attainable for every remark, and be adaptive—present wider intervals for observations which might be “troublesome” to foretell and narrower intervals for “straightforward” ones.

You might ponder whether it’s attainable to assemble a statistically legitimate prediction interval utilizing any machine studying methodology, with none distributional assumption reminiscent of Gaussianity, whereas the above standards are happy. Wait and see.

On this submit, I exhibit the way to use Stata’s h2oml suite of instructions to assemble predictive intervals by utilizing the conformalized quantile regression (CQR) strategy, launched in Romano, Patterson, and Candes (2019). The construction of the submit is as follows: First, I present a short introduction to conformal prediction, with a give attention to CQR, after which I present the way to assemble predictive intervals in Stata by utilizing gradient boosting regressions.

Conformal prediction
Conformal prediction (Papadopoulos et al. 2002; Vovk, Gammerman, and Shafer 2005; Lei et al. 2018; Angelopoulos and Bates 2023), also referred to as conformal inference, is a basic methodology designed to enrich any machine studying prediction by offering prediction intervals with assured distribution-free statistical protection. At a conceptual degree, conformal prediction begins with a pretrained machine studying mannequin (for instance, a gradient boosting machine) skilled on exchangeable or impartial and identically distributed information. It then makes use of held-out validation information from the identical data-generating distribution, known as calibration information, to outline a rating operate (S(hat y, y)). This operate assigns bigger scores when the discrepancy between the anticipated worth (hat y) and the true response (y) is larger. These scores are subsequently used to assemble prediction intervals for brand new, unseen observations ({bf X}_{textual content{new}}), the place ({bf X}_{textual content{new}}) is a random vector of predictors.

It may be proven that conformal prediction (mathcal{C}({bf X}_{textual content{new}})) gives legitimate prediction interval protection (Lei et al. 2018; Angelopoulos and Bates 2023) within the sense that

[
P{Y_{text{new}} in mathcal{C}({bf X}_{text{new}})} geq 1 – alpha tag{1}label{eq1}
]
the place (alpha in (0,1)) is a user-defined miscoverage or error fee. This property is named marginal protection, as a result of the chance is averaged over the randomness of calibration and unseen or testing information.

Though the conformal prediction strategy ensures legitimate protection eqref{eq1} with minimal distributional assumptions and for any machine studying methodology, our focus right here is on CQR (Romano, Patterson, and Candes 2019). It is without doubt one of the most generally used and really helpful approaches to assemble prediction intervals (Romano, Patterson, and Candes 2019; Angelopoulos and Bates 2023).

CQR
The publicity on this part intently follows Romano, Patterson, and Candes (2019) and Angelopoulos and Bates (2023). Take into account a quantile regression that estimates a conditional quantile operate (q_{alpha}(cdot)) of (Y_{textual content{new}}) given ({bf X}_{textual content{new}} = {bf x}) for every attainable realization of ({bf x}). We are able to use any quantile regression estimation methodology, reminiscent of gradient boosting machine with quantile or “pinball” loss to acquire (widehat q_{alpha}(cdot)). By definition, (Y_{textual content{new}}|{bf X}_{textual content{new}} = {bf x}) is under (q_{alpha/2}({bf x})) with chance (alpha/2) and above (q_{1 – alpha/2}({bf x})) with chance (alpha/2), so the estimated prediction interval ([widehat q_{alpha/2}(cdot), widehat q_{1 – alpha/2}(cdot)]) ought to have roughly (1-alpha)% protection. Sadly, as a result of the estimated quantiles may be inaccurate, such protection just isn’t assured. Thus, we have to conformalize them to have a legitimate protection eqref{eq1}. CQR steps may be summarized as follows:

  • Step 1. Break up information (mathcal{D}) right into a coaching (mathcal{D}_1) and calibration (mathcal{D}_2), and let (mathcal{D}_3) be the brand new, unseen testing information.
  • Step 2. Use (mathcal{D}_1) to coach any quantile regression estimation methodology (f) to estimate two conditional quantile features (hat q_{alpha_1}(cdot)) and (hat q_{alpha_2}(cdot)), for (alpha_1 = alpha/2) and (alpha_2 = 1 – alpha/2), respectively. For instance, when the miscoverage fee (alpha = 0.1), we acquire (hat q_{0.05}(cdot)) and (hat q_{0.95}(cdot)).
  • Step 3. Use calibration information (mathcal{D}_2) to compute conformity scores (S_i), for every (i in mathcal{D}_2), that quantify the error made by the interval ([hat q_{alpha_1}({bf x}), hat q_{alpha_2}({bf x})]).
    [
    S_i = max {hat q_{alpha_1}({bf x}_i) – Y_i, Y_i – hat q_{alpha_2}({bf x}_i)}
    ]
  • Step 4. Given new unseen information ({bf X}_{textual content{new}} subset mathcal{D}_3), assemble the prediction interval for (Y_{textual content{new}}),
    [
    mathcal{C}({bf X}_{text{new}}) = Big[hat q_{alpha_1}({bf X}_{text{new}}) – q_{1 – alpha}(S_i, mathcal{D}_2), hat q_{alpha_2}({bf X}_{text{new}}) + q_{1 – alpha}(S_i, mathcal{D}_2)Big]
    ]
    the place the empirical quantile of conformity scores
    [ label{eq:empquantile}
    q_{1 – alpha}(S_i, mathcal{D}_2) = frac{lceil (|mathcal{D}_2|+1)(1 – alpha) rceil}{|mathcal{D}_2|} tag{2}
    ]
    and (|mathcal{D}_2|) is the variety of observations of the calibration information and (lceil cdot rceil) is the ceiling operate.

The instinct behind the conformity rating, computed in step 3, is the next:

  • If (Y_{textual content{new}} < q_{alpha_1}({bf X}_{textual content{new}})) or (Y_{textual content{new}} > q_{alpha_2}({bf X}_{textual content{new}})), the scores given by (S_i = |Y_{textual content{new}} – q_{alpha_1}({bf X}_{textual content{new}})|) or (S_i = |Y_{textual content{new}} – q_{alpha_2}({bf X}_{textual content{new}})|) symbolize the magnitude of the error incurred by this error.
  • Then again, if (q_{alpha_1}({bf X}_{textual content{new}}) leq Y_{textual content{new}} leq q_{alpha_2}({bf X}_{textual content{new}})), the computed rating is at all times nonpositive.

This fashion, the conformity rating accounts for each undercoverage and overcoverage.

Romano, Patterson, and Candes (2019) confirmed that below the exchangeability assumption, steps 1–4 assure the legitimate marginal protection eqref{eq1}.

Implementation in Stata
On this part, we use the h2oml suite of instructions in Stata to assemble predictive intervals utilizing conformalized gradient boosting quantile regression. H2O is a scalable and distributed machine studying and predictive analytics platform that permits us to carry out information evaluation and machine studying. For particulars, see the Stata 19 Machine Studying in Stata Utilizing H2O: Ensemble Determination Bushes Reference Handbook.

We think about the Ames housing dataset (De Cock 2011), ameshouses.dta, additionally utilized in a Kaggle competitors, which describes residential homes offered in Ames, Iowa, between 2006 and 2010. It comprises about 80 housing (and associated) traits, reminiscent of house dimension, facilities, and placement. This dataset is usually used for constructing predictive fashions for house sale worth, saleprice. Earlier than placing the dataset into an H2O body, we carry out some information manipulation in Stata. As a result of saleprice is right-skewed (for instance, sort histogram saleprice), we use its log. We additionally generate a variable, houseage, that calculates the age of the home on the time of a gross sales transaction.

. webuse ameshouses

. generate logsaleprice = log(saleprice)

. generate houseage = yrsold - yearbuilt

. drop saleprice yrsold yearbuilt

Subsequent, we initialize a cluster and put the information into an H2O body. Then, to carry out step 1, let’s cut up the information into coaching (50%), calibration (40%), and testing (10%) frames, the place the testing body serves as a proxy for brand new, unseen information.

. h2o init
(output omitted)

. _h2oframe put, into(home) 

Progress (%): 0 100

. _h2oframe cut up home, into(prepare calib check) cut up(0.5 0.4 0.1)
> rseed(1)

. _h2oframe change prepare

Our aim is to assemble a predictive interval with 90% protection. We outline three native macros in Stata to retailer the miscoverage fee (alpha = 1- 0.9 = 0.1) and decrease and higher bounds, (0.05) and (0.95), respectively. Let’s additionally create a worldwide macro, predictors, that comprises the names of our predictors.

. native alpha = 0.1

. native decrease = 0.05

. native higher = 0.95

. international predictors overallqual grlivarea exterqual houseage garagecars 
> totalbsmtsf stflrsf garagearea kitchenqual bsmtqual

We carry out step 2 by pretraining gradient boosting quantile regression by utilizing the h2oml gbregress command with the loss(quantile) possibility. For illustration, I tune solely the variety of timber (ntrees()) and maximum-depth (maxdepth()) hyperparameters, and retailer the estimation outcomes by utilizing the h2omlest retailer command.

. h2oml gbregress logsaleprice $predictors, h2orseed(19) cv(3, modulo) 
> loss(quantile, alpha(`decrease')) ntrees(20(20)80) maxdepth(6(2)12) 
> tune(grid(cartesian))

Progress (%): 0 100

Gradient boosting regression utilizing H2O

Response: logsaleprice
Loss:     Quantile .05
Body:                                 Variety of observations:
  Coaching: prepare                                 Coaching =    737
                                          Cross-validation =    737
Cross-validation: Modulo               Variety of folds     =      3

Tuning data for hyperparameters

Methodology: Cartesian
Metric: Deviance

-------------------------------------------------------------------
                 |                      Grid values
 Hyperparameters |         Minimal          Most        Chosen
-----------------+-------------------------------------------------
 Variety of timber |              20               80              40
 Max. tree depth |               6               12               8
-------------------------------------------------------------------

Mannequin parameters

Variety of timber      =  40             Studying fee       =     .1
              precise =  40             Studying fee decay =      1
Tree depth:                            Pred. sampling fee =      1
           Enter max =   8             Sampling fee       =      1
                 min =   6             No. of bins cat.    =  1,024
                 avg = 7.5             No. of bins root    =  1,024
                 max =   8             No. of bins cont.   =     20
Min. obs. leaf cut up =  10             Min. cut up thresh.  = .00001
Metric abstract
-----------------------------------
           |                 Cross-
    Metric |   Coaching  validation
-----------+-----------------------
  Deviance |   .0138451    .0259728
       MSE |   .1168036    .1325075
      RMSE |   .3417654    .3640158
     RMSLE |   .0259833    .0278047
       MAE |   .2636412    .2926809
 R-squared |   .3117896    .2192615
-----------------------------------

. h2omlest retailer q_lower

The very best-selected mannequin has 40 timber and a most tree depth of 8. I exploit this mannequin to acquire predicted decrease quantiles on the calibration dataset by utilizing the h2omlpredict command with the body() possibility. We’ll use these predicted values to compute conformity scores in step 3.

. h2omlpredict q_lower, body(calib)

Progress (%): 0 100

For simplicity, I exploit the above hyperparameters to run gradient boosting quantile regression for the higher quantile. In follow, we have to tune hyperparameters for this mannequin as effectively. As earlier than, I predict the higher quantiles on the calibration dataset and retailer the mannequin.

. h2oml gbregress logsaleprice $predictors, h2orseed(19) cv(3, modulo) 
> loss(quantile, alpha(`higher')) ntrees(40) maxdepth(8)

Progress (%): 0 1.2 100

Gradient boosting regression utilizing H2O

Response: logsaleprice
Loss:     Quantile .95
Body:                                 Variety of observations:
  Coaching: prepare                                 Coaching =    737
                                          Cross-validation =    737
Cross-validation: Modulo               Variety of folds     =      3

Mannequin parameters

Variety of timber      =  40             Studying fee       =     .1
              precise =  40             Studying fee decay =      1
Tree depth:                            Pred. sampling fee =      1
           Enter max =   8             Sampling fee       =      1
                 min =   5             No. of bins cat.    =  1,024
                 avg = 7.2             No. of bins root    =  1,024
                 max =   8             No. of bins cont.   =     20
Min. obs. leaf cut up =  10             Min. cut up thresh.  = .00001

Metric abstract
-----------------------------------
           |                 Cross-
    Metric |   Coaching  validation
-----------+-----------------------
  Deviance |   .0132103    .0218716
       MSE |   .1190689    .1365112
      RMSE |   .3450637    .3694742
     RMSLE |   .0268811    .0287084
       MAE |   .2567844    .2841911
 R-squared |   .2984421    .1956718
-----------------------------------

. h2omlest retailer q_upper

. h2omlpredict q_upper, body(calib)

Progress (%): 0 100

To compute conformity scores as in step 3, let’s use the _h2oframe get command to load the estimated quantiles and the logarithm of the gross sales worth from the calibration body calib into Stata. As a result of the information in Stata’s reminiscence have been modified, I additionally use the clear possibility.

. _h2oframe get logsaleprice q_lower q_upper utilizing calib, clear

Then, we use these variables to generate a brand new variable, conf_scores, that comprises the computed conformity scores.

. generate double conf_scores = 
> max(q_lower - logsaleprice, logsaleprice - q_upper)

To assemble conformalized prediction intervals from step 4, we have to compute empirical quantiles eqref{eq:empquantile}, which may be executed in Stata by utilizing the _pctile command. Determine 1a exhibits the distribution of conformity scores, and the crimson vertical line signifies the empirical quantile eqref{eq:empquantile}, which is the same as 0.031.

. native emp_quantile = ceil((1 - 0.1) * (_N + 1))/ _N * 100

. _pctile conf_score, percentiles(`emp_quantile')

. native q = r(r1)

. di `q'
.03104496

Subsequent, I restore each fashions that estimated decrease and higher quantiles and procure their predictions on the testing body check.

. h2omlest restore q_lower
(outcomes q_lower are energetic now)

. h2omlpredict q_lower, body(check)

Progress (%): 0 100

. h2omlest restore q_upper
(outcomes q_upper are energetic now)

. h2omlpredict q_upper, body(check)

Progress (%): 0 100

I then load these predictions from the testing body into Stata and generate decrease and higher bounds for prediction intervals. As well as, I additionally load the logsaleprice and houseage variables. We’ll use these variables for illustration functions.

. _h2oframe get logsaleprice houseage q_lower q_upper utilizing check, clear

. generate double conf_lower = q_lower - `q'

. generate double conf_upper = q_upper + `q'

Determine 1b shows the prediction intervals for every remark within the testing body. We are able to see that the computed interval is adaptive, that means for “troublesome” observations, for instance, outliers, the interval is vast and vice versa.


(a) Histogram of conformity scores
graph1
(b) Prediction intervals for the testing dataset

Determine 1: (a) Histogram of conformity scores (b) CQR-based prediction intervals for the testing dataset

Under, I record a small pattern of the prediction intervals and the true log of sale worth response.

. record logsaleprice conf_lower conf_upper in 1/10

     +----------------------------------+
     | logsal~e   conf_lo~r   conf_up~r |
     |----------------------------------|
  1. | 11.67844   11.470275   12.052485 |
  2. |  12.6925   12.002838   12.773621 |
  3. | 11.31447   11.332932   12.058372 |
  4. | 11.64833   11.527202   12.099679 |
  5. | 12.10349   11.640463   12.401743 |
     |----------------------------------|
  6. |  11.8494   11.621721   12.231588 |
  7. |  11.8838   11.631179   12.045645 |
  8. | 12.06681   11.931026   12.204194 |
  9. | 12.12811   11.852887   12.375453 |
 10. | 11.65269   11.569664   12.066292 |
     +----------------------------------+

For 9 out of 10 observations, the responses belong to the respective predictive intervals. We are able to compute the precise common protection of the interval within the testing body, which I do subsequent by producing a brand new variable, in_interval, that signifies whether or not the response logsaleprice is within the prediction interval.

. generate byte in_interval = 0

. substitute in_interval = 1 if inrange(logsaleprice, conf_lower, conf_upper)
(124 actual adjustments made)

. summarize in_interval, meanonly

. native avg_coverage = r(imply)

. di `avg_coverage' * 100
90.510949

We are able to see that the precise common protection is 90.5%.

References
Angelopoulos, A. N., and S. Bates. 2023. Conformal prediction: A delicate introduction. Foundations and Traits in Machine Studying 16: 494–591. https://doi.org/10.1561/2200000101.

De Cock, D. 2011. Ames, Iowa: Different to the Boston housing information as an finish of semester regression mission. Journal of Statistics Training 19: 3. https://doi.org/10.1080/10691898.2011.11889627.

Lei, J., M. G’Promote, A. Rinaldo, R. J. Tibshirani, and L. Wasserman. 2018. Distribution-free predictive inference for regression. Journal of the American Statistical Affiliation 113: 1094–1111. https://doi.org/10.1080/01621459.2017.1307116.

Papadopoulos, H., Okay. Proedrou, V. Vovk, and A. Gammerman. 2002. “Inductive confidence machines for regression”. In Machine Studying: ECML 2002. Lecture Notes in Pc Science, edited by T. Elomaa, H. Mannila, H. Toivonen, vol. 2430: 345–356. Berlin: Springer. https://doi.org/10.1007/3-540-36755-1_29.

Romano, Y., E. Patterson, and E. Candes. 2019. “Conformalized quantile regression”. In Advances in Neural Data Processing Programs, edited by H. Wallach, H. Larochelle, A. Beygelzimer, F. d’Alché-Buc, E. Fox, and R. Garnett, vol. 32. Crimson Hook, NY: Curran Associates, Inc. https://proceedings.neurips.cc/paper_files/paper/2019/file/5103c3584b063c431bd1268e9b5e76fb-Paper.pdf.

Vovk, V., A. Gammerman, and G. Shafer. 2005. Algorithmic Studying in a Random World. New York: Springer. https://doi.org/10.1007/b106715.


[ad_2]