Home Blog Page 667

Approximate statistical exams for evaluating binary classifier error charges utilizing H2OML

0

[ad_1]

Motivation

You will have simply skilled a gradient boosting machine (GBM) and a random forest (RF) classifier in your information utilizing Stata’s new h2oml command suite. Your GBM mannequin achieves 87% accuracy on the testing information, and your RF mannequin, 85%. It seems as if GBM is the popular classifier, proper? Not so quick.

Why accuracy alone isn’t sufficient

Accuracy, space underneath the curve, and root imply squared error are in style metrics, however they supply solely level estimates. These numbers replicate how nicely a mannequin carried out on one particular testing pattern, however they don’t account for the variability that may come up from pattern to pattern. In different phrases, they don’t reply this key query: Will the distinction in efficiency between these strategies maintain on the inhabitants stage, or may it have occurred by likelihood solely on this explicit testing dataset?

When evaluating strategies like GBM and RF, a number of share factors in efficiency may not be compelling on their very own. With out contemplating how a lot the outcomes may differ throughout completely different samples, it’s arduous to inform whether or not one methodology persistently outperforms the opposite or whether or not the noticed distinction is only a product of random variation within the information. Statistical exams are important on this regard, as they supply a framework for assessing whether or not the noticed variations are prone to persist within the inhabitants.

Introduction

A typical follow in machine studying for evaluating classifiers is to separate the dataset into both a three-way holdout (coaching, validation, and testing units) or a two-way holdout (coaching and testing units). The validation set (for three-way splits) or cross-validation (for two-way splits) is used to tune the mannequin, whereas the testing set evaluates the ultimate efficiency. For particulars, see Mannequin choice in machine studying in [H2OML] Intro.

Nonetheless, a refined however crucial downside of counting on a single take a look at set is random variation within the collection of the testing information. Particularly, even when two classifiers carry out identically on the complete inhabitants, one could seem superior due to likelihood fluctuations within the sampled testing information. That is particularly problematic with small testing units.

To deal with this, statistical exams are beneficial within the literature (Dietterich 1998; Alpaydin 1998; Raschka 2018). On this submit, we discover the next query: Given two machine studying strategies and a coaching set, how can we take a look at whether or not the classifiers exhibit the identical error charge on unseen information?

We concentrate on two exams: the McNemar take a look at (Mcnemar 1947) and the mixed (5 occasions 2) cross-validated ((5 occasions 2) CV) F take a look at (Alpaydin 1998). Utilizing Stata and its h2oml suite, we’ll show their utility. The submit is structured as follows: First, we introduce each exams conceptually; then, we transition to sensible implementation in Stata.

Statistical exams

In binary classification, the efficiency of a mannequin might be evaluated utilizing the misclassification error charge, which is the proportion of incorrect predictions amongst all predictions. Let true positives (TP) and true negatives (TN) characterize the variety of appropriately categorized optimistic and detrimental instances, respectively. Let false positives (FP) and false negatives (FN) characterize the variety of misclassified optimistic and detrimental instances. The misclassification error charge is outlined as
[
e = frac{text{FP} + text{FN}}{text{TP} + text{TN} + text{FP} + text{FN}} tag{1}label{eq:errrate}
]

Conversely, the accuracy of the mannequin, which measures the proportion of right predictions, is given by
[
text{acc} = frac{text{TP} + text{TN}}{text{TP} + text{TN} + text{FP} + text{FN}} = 1 – e tag{2}label{eq:accuracy}
]

For particulars, see [H2OML] metric_option. These metrics are basic for assessing the standard of predictions made by strategies similar to RFs or GBMs.

McNemar’s Check

McNemar’s take a look at is a nonparametric take a look at for paired comparisons that can be utilized to evaluate whether or not two classification strategies differ in efficiency on the identical testing set.

Let (n_{ij}) denote the variety of situations for which classifier A’s (for instance, GBM) prediction was (i) ((i=1) for proper prediction or (i=0) for incorrect prediction) and classifier B’s (for instance, RF) prediction was (j) ((j=1) for proper prediction or (j=0) for incorrect prediction). The (2 occasions 2) contingency desk is

Desk 1: Info wanted to conduct McNemar’s take a look at for evaluating two binary classifiers’ error charges

B incorrectB right
A incorrect (n_{00}) (n_{01})
An accurate(n_{10})(n_{11})

We have an interest within the off-diagonal components: (n_{01}) (A is wrong, B is right) and (n_{10}) (A is right, B is wrong). These values characterize the disagreements between classifiers.

The null speculation (H_0) is that the 2 classifiers have the identical error charge:
[
H_0 : P(text{A incorrect, B correct}) = P(text{A correct, B incorrect})
quad text{or} quad n_{01} = n_{10}
]

Beneath the null speculation, the variety of disagreements (n_{01} + n_{10}) follows a binomial distribution with equal chance of both final result. For giant pattern sizes, the binomial distribution might be approximated by a chi-squared distribution with 1 diploma of freedom.

The McNemar take a look at statistic is
[
chi^2 = frac{(n_{01} – n_{10})^2}{n_{01} + n_{10}}
]

This statistic is roughly chi-squared distributed with 1 diploma of freedom underneath the null speculation. See Unstratified matched case–management information (mcc and mcci) in [R] epitab for extra particulars.

Mixed 5 x 2 CV F take a look at

The ( 5times 2) CV F take a look at is a statistical methodology for evaluating the efficiency of two supervised classification strategies. It’s designed to check the null speculation
[
H_0: text{The two classifiers have equal generalization error}
]
and is constructed upon Dietterich’s (5times 2) CV paired t take a look at (Dietterich 1998). Alpaydin (1998) recognized instability within the unique take a look at because of the arbitrary selection of certainly one of 10 attainable take a look at statistics and proposed a mixed F take a look at that aggregates over all of them for robustness.

We carry out 5 replications of 2-fold cross-validation, yielding 10 distinct take a look at units. Let (p_i^{(j)}) denote the distinction in error charges between the 2 classifiers on fold (j = 1, 2) of replication (i = 1, dots, 5). That’s,
[
p_i^{(j)} = e_{i,A}^{(j)} – e_{i,B}^{(j)} = text{acc}_{i,B}^{(j)} – text{acc}_{i,A}^{(j)} tag{3} label{eq:pij}
]
the place ( e_{i,A}^{(j)} ) and ( e_{i,B}^{(j)} ) are the misclassification error charges of classifiers A and B, respectively, on the (j)th fold of the (i)th replication [as defined in eqref{eq:errrate}] and ( textual content{acc}_{i,A}^{(j)} ) and ( textual content{acc}_{i,B}^{(j)} ) are the corresponding accuracy values [as defined in eqref{eq:accuracy}].

For every replication (i), we compute the typical,
[
bar{p}_i = frac{p_i^{(1)} + p_i^{(2)}}{2}
]
and the estimate of the variance:
[
s_i^2 = (p_i^{(1)} – bar{p}_i)^2 + (p_i^{(2)} – bar{p}_i)^2 = frac{(p_i^{(1)} – p_i^{(2)})^2 }{2} tag{4} label{eq:var}
]

Authentic 5 x 2 CV t take a look at (for reference)

Dietterich (1998) proposed the t statistic:

[
t = frac{p_1^{(1)}}{sqrt{ frac{1}{5} sum_{i=1}^{5} s_i^2 }}
]

This makes use of only one of the ten attainable (p_i^{(j)}) values, which introduces randomness primarily based on the selection of fold order.

Mixed 5 x 2 CV F-test derivation

To enhance robustness, the mixed F take a look at aggregates all 10 squared variations (p_i^{(j)}) and all 5 variances (s_i^2).

Outline
[
N = sum_{i=1}^{5} sum_{j=1}^{2} left( p_i^{(j)} right)^2
quadtext{and}quad
M = sum_{i=1}^{5} s_i^2 tag{5} label{eq:NandM}
]

Beneath the null speculation and the belief of independence (approximate), now we have
[
F = frac{N / 10}{M / 5} = frac{ sum_{i=1}^{5} sum_{j=1}^{2} left( p_i^{(j)} right)^2}{2 sum_{i=1}^{5} s_i^2} tag{6} label{eq:Fstat}
]

This statistic is roughly F-distributed with ((10, 5)) levels of freedom.

In abstract, the mixed (5times 2) CV F take a look at improves upon Dietterich’s unique t take a look at by

  • utilizing all 10-fold variations as an alternative of simply 1,
  • lowering sensitivity to the order of folds or replications, and
  • offering higher management of sort I error and improved statistical energy.

Implementation in Stata

We start our evaluation by loading attrition.dta and producing a brand new variable, logincome, that shops the log of month-to-month revenue. It is a frequent transformation used to normalize skewed variables earlier than modeling.

. use https://www.stata.com/customers/assaad_dallakyan/attrition, clear
. gen logincome = log(monthlyincome)

We then initialize the H2O cluster utilizing h2o init and put the present dataset into an H2O body, attrition, and make it the present H2O body.

. h2o init
. _h2oframe put, into(attrition) present

We break up attrition.dta into coaching (70%) and testing (30%) frames utilizing random seed 19 for reproducibility. Then we set prepare as the present working body for mannequin coaching.

. _h2oframe break up attrition, into(prepare take a look at) break up(0.7 0.3) rseed(19) exchange
. _h2oframe change prepare

For comfort, we outline a world macro, predictors, that features the whole set of predictors for the mannequin. These cowl a variety of non-public and job-related options, similar to training, job satisfaction, work-life steadiness, and demographic particulars.

. world predictors age training employeenumber environmentsat
> jobinvolvement jobsatisfaction logincome numcompaniesworked 
> efficiency relationshipsat totalworkingyears worklifebalance
> yearsatcompany yearsincurrentrole yearswithcurrmanager
> businesstravel gender jobrole maritalstatus

McNemar’s take a look at

We first prepare a GBM classifier utilizing the coaching dataset. As soon as the mannequin is skilled, we specify that the take a look at body needs to be used for subsequent postestimation instructions, show the confusion matrix, and generate predictions. These predicted lessons are saved in variable attrition_gbm within the testing body take a look at, and the mannequin is saved underneath the title gbm for future comparability. For simplicity, for each the GBM and RF classifiers, we used the default values for all hyperparameters and didn’t carry out tuning. Nonetheless, in real-world purposes, we might extra probably need to examine one of the best fashions obtained after hyperparameter tuning; see Hypereparameter tuning in [H2OML] Intro for extra particulars about tuning.

. h2oml gbbinclass attrition $predictors, h2orseed(19)
(output omitted)

. h2omlpostestframe take a look at
(testing body take a look at is now energetic for h2oml postestimation)

. h2omlestat confmatrix

Confusion matrix utilizing H2O
Testing body: take a look at

           |      Predicted
 attrition |         No        Sure |  Whole  Error    Fee
-----------+-----------------------+----------------------
        No |        318         33 |    351     33    .094
       Sure |         48         32 |     80     48      .6
-----------+-----------------------+----------------------
     Whole |        366         65 |    431     81    .188

Observe: Chance threshold .254 that maximizes F1 metric
      used for classification.


. h2omlpredict attrition_gbm, class

Progress (%): 0 100

. h2omlest retailer gbm

Throughout all 431 observations within the testing dataset, there have been 81 misclassifications, giving an total error charge of 0.188.

We repeat the identical process for a RF classifier. The predictions are saved in variable attrition_rf, and the mannequin is saved as rf.

. h2oml rfbinclass attrition $predictors, h2orseed(19)
(output omitted)

. h2omlpostestframe take a look at
(testing body take a look at is now energetic for h2oml postestimation)

. h2omlestat confmatrix

Confusion matrix utilizing H2O
Testing body: take a look at

           |      Predicted
 attrition |         No        Sure |  Whole  Error    Fee
-----------+-----------------------+----------------------
        No |        276         75 |    351     75    .214
       Sure |         29         51 |     80     29    .362
-----------+-----------------------+----------------------
     Whole |        305        126 |    431    104    .241

Observe: Chance threshold .21 that maximizes F1 metric
      used for classification.


. h2omlpredict attrition_rf, class

Progress (%): 0 100

. h2omlest retailer rf

Throughout all 431 observations within the testing dataset, there have been 104 misclassifications, giving an total error charge of 0.241. At first look, it seems that GBM outperforms RF when it comes to predictive accuracy (0.188 versus 0.241 error charges). Nonetheless, this distinction will not be indicative of a distinction within the inhabitants. This highlights the significance of supplementing accuracy metrics with correct statistical testing, as we do subsequent with McNemar’s take a look at and the 5×2 CV F take a look at.

To carry out McNemar’s take a look at, we convey the take a look at information and predictions again into Stata (by way of _h2oframe get) for additional statistical evaluation. We encode the string-valued categorical predictions and final result into numeric variables and drop the unique string variations.

. clear
. _h2oframe get attrition attrition_gbm attrition_rf utilizing take a look at
. encode attrition, gen(nattrition)
. encode attrition_gbm, gen(nattrition_gbm)
. encode attrition_rf, gen(nattrition_rf)
. drop attrition attrition_gbm attrition_rf

The following step is to provide a three-way desk that cross-tabulates true values with each mannequin predictions. From the outcomes, we determine the counts wanted (proven in desk 1) for McNemar’s take a look at and retailer them in native macros.

. desk (nattrition_gbm) (nattrition nattrition_rf ), nototal

---------------------------------------------------
               |              nattrition
               |         No               Sure
               |   nattrition_rf     nattrition_rf
               |      No      Sure       No      Sure
---------------+-----------------------------------
nattrition_gbm |
  No           |     303       17       41        8
  Sure          |       9       22        5       26
---------------------------------------------------
. native n00 = 22 + 41  // Nb. of obs. misclassified by each GBM and RF
. native n01 = 17 + 5   // Nb. of obs. misclassified by RF however not by GBM
. native n10 = 9 + 8    // Nb. of obs. misclassified by GBM however not by RF
. native n11 = 303 + 26

We then run mcci to compute the McNemar statistic utilizing these frequencies.

. mcci `n00' `n01' `n10' `n11'

                 |        Controls        |
Circumstances            |   Uncovered   Unexposed  |      Whole
-----------------+------------------------+-----------
         Uncovered |        63          22  |         85
       Unexposed |        17         329  |        346
-----------------+------------------------+-----------
           Whole |        80         351  |        431

McNemar's chi2(1) =      0.64    Prob > chi2 = 0.4233
Precise McNemar significance chance       = 0.5224

The outcome doesn’t present proof to reject the null speculation, suggesting no efficiency distinction.

For fashions which are computationally costly to coach, Dietterich (1998) beneficial McNemar’s take a look at as the strategy of selection. For fashions that may be skilled a number of occasions (for instance, 10 occasions), he beneficial the (5times 2) CV (t) take a look at as a result of it’s barely extra highly effective than McNemar’s take a look at. Subsequent, we describe the right way to implement the (5times 2) CV (F) take a look at in Stata, which is an improved model of the (5 occasions 2) CV (t) take a look at.

Mixed 5 x 2 CV F take a look at

We begin by switching to the body that comprises the complete dataset (attrition). We then initialize scalars to build up (N) and (M) [see eqref{eq:NandM}] which are used to compute the F statistic in eqref{eq:Fstat}.

. _h2oframe change attrition
. scalar N = 0
. scalar M = 0

We’ll then carry out 5 iterations, the place in every iteration, we randomly break up the dataset into two equal halves, prepare and take a look at. To make sure reproducibility, we first set a seed in Stata after which generate pseudo–random numbers utilizing runiformint(). We extract digits from this quantity to type a brand new seed, which we move to H2O’s pseudo-random-number generator by way of the rseed() possibility of the _h2oframe break up command. Observe that this process differs from the one we suggested in opposition to within the [R] set seed entry. On this case, as a result of H2O’s pseudo-random-number generator is unrelated to Stata’s, there isn’t a threat of the generator converging to a cycle. We then prepare GBM and RF on every half and consider them on the opposite, recording their accuracy (computed by way of the h2omlestat threshmetric command). We compute the distinction in efficiency for every fold ((p_i^{(j)}, j = 1, 2)) and retailer them in scalars pi1 and pi2. Then we calculate the variance and accumulate squared variations and variances throughout all replications. These are then used to calculate the F statistic.

. set seed 19
. forvalues i = 1(1)5 {
  2.         native split_seed = runiformint(1, 50000)
  3.         _h2oframe break up attrition, into(prepare take a look at) break up(0.5 0.5) rseed(`split_seed') exchange
  4.         quietly {
  5.                 _h2oframe change prepare
  6.                 h2oml gbbinclass attrition $predictors, h2orseed(19) validframe(take a look at)
  7.                 h2omlestat threshmetric
  8.                 scalar accA_1 = r(threshmetric)[4,1]   // Accuracy of A (GBM) on 1st fold
  9.
.                    h2oml rfbinclass attrition $predictors, h2orseed(19) validframe(take a look at)
 10.                 h2omlestat threshmetric
 11.                 scalar accB_1 = r(threshmetric)[4,1]   // Accuracy of B (RF) on 1st fold
 12.
.                    _h2oframe change take a look at
 13.                 h2oml gbbinclass attrition $predictors, h2orseed(19) validframe(prepare)
 14.                 h2omlestat threshmetric
 15.                 scalar accA_2 = r(threshmetric)[4,1]   // Accuracy of A (GBM) on 2nd fold
 16.
.                    h2oml rfbinclass attrition $predictors, h2orseed(19) validframe(prepare)
 17.                 h2omlestat threshmetric
 18.                 scalar accB_2 = r(threshmetric)[4,1]   // Accuracy of B (RF) on 2nd fold
 19.
                     // Compute the distinction in efficiency
.                    scalar pi1 = accA_1 - accB_1                   // Equation (2)
 20.                 scalar pi2 = accA_2 - accB_2
 21.                 scalar variance = (pi1 - pi2)^2 / 2            // Equation (3)
 22.                 scalar N = N + pi1^2 + pi2^2                   // Equation (4)
 23.                 scalar M = M + variance                        // Equation (4)
 24.         }
 25. }
. scalar f_stat = N / (2 * M)                                       // Equation (5)
. scalar p_value = Ftail(10, 5, f_stat)
. di p_value
.19382379

The results of this take a look at corroborates the results of McNemar’s take a look at. There’s not proof to recommend that the strategies carry out in a different way.

References
Alpaydin, E. 1998. Mixed 5x2cv f take a look at for evaluating supervised classification studying algorithms mixed 5x2cv f take a look at for evaluating supervised classification studying algorithms.
https://api.semanticscholar.org/CorpusID:6872443.

Dietterich, T. G. 1998. Approximate statistical exams for evaluating supervised classification studying algorithms. Neural Computation 10: 1895–1923. https://doi.org/10.1162/089976698300017197.

Mcnemar, Quinn. 1947. Observe on the sampling error of the distinction between correlated proportions or percentages. Psychometrika 12: 153–157. https://doi.org/10.1007/BF02295996.

Raschka, S. 2018. Mannequin analysis, mannequin choice, and algorithm choice in machine studying. arXiv:1811.12808 [cs.LG]. https://doi.org/10.48550/arXiv.1811.12808.


[ad_2]

Predicting the 2025 Oscar Winners with Machine Studying – The Official Weblog of BigML.com

0

[ad_1]

It’s that point of the yr when the anticipation and hypothesis in regards to the upcoming Academy Awards fills the airwaves and makes for juicy web chatter. In contrast to final yr’s heavyweight nominees, Barbie and Oppenheimer (aka Barbenheimer), this yr we have now extra of a degree enjoying discipline probably delivering shock winners. This Sunday’s 97th Academy Awards might be hosted by Conan O’Brien from the Dolby Theatre at Ovation Hollywood. As soon as once more, we’re blissful to do our half at BigML and publish our Machine Studying predictions as they’ve change into an annual custom.

Emilia Pérez, the polarizing French-directed, Spanish-language musical a few trans Mexican gangster, leads the 2025 Oscars with 13 nominations, which isn’t solely a report for a non-English-language movie but in addition is only one shy of the all-time report for any movie! Earlier non-English-language report holders had been Crouching Tiger, Hidden Dragon and Roma with 10 nominations. The Brutalist and Depraved, tied with 10 noms every full this yr’s high three designated motion pictures. It is usually fascinating that among the many studios, Netflix leads with 16 nominations. How occasions change!

Different fascinating tidbits from the nominee discipline embody the Brazilian entry I’m Nonetheless Right here‘s star Fernanda Torres, who repeated her mom Fernanda Montenegro’s Finest Actress class nomination from 1999 for Central Station. In the meantime, Timothée Chalamet, adopted within the footsteps of James Dean because the youngest two-time Finest Actor nominee. This yr additionally marks the primary time two musicals, in Depraved and Emilia Pérez, have been nominated for greatest image since 1968.

The Knowledge and Fashions

As we have now carried out since 2018, our crew has collected the related information factors about this yr’s nominees and generated a brand new set of Machine Studying fashions for every award class. This makes your job a lot simpler must you resolve to make your individual ML-powered predictions. Merely clone the Films 2001-2025 public dataset from the BigML gallery and use it at the side of the extensive number of modeling sources of the BigML platform. Don’t have a BigML account but? You may simply create a free one right here in lower than a minute!

The most recent model of our dataset covers 1,377 motion pictures nominated for varied awards from 2001 to 2025 and 299 options for each together with:

Films (Oscars 2001-2025) Public Dataset

As within the final yr, we up to date the betting odds from varied on-line websites for extra predictive energy. This information level applies just for the main award classes: Finest Image, Finest Director, Finest Actor, Finest Actress, Finest Supporting Actor and Finest Supporting Actress. Our OptiML fashions from final yr confirmed that historic odds are fairly essential in predicting Oscar winners. In fact, the info fields capturing the outcomes of high film trade awards for the yr to be predicted proceed to reign supreme when it comes to sign to noise ratio.

As a reminder, OptiML (our in style AutoML function) mechanically finds the best-performing supervised fashions for you. When the person OptiML mannequin search executions completed for every award class, our engineering crew constructed Fusions, by combining the highest performing fashions from every OptiML search primarily based on the phi-coefficient metric. This implies completely different modeling methods might partake within the ultimate predictions, which in flip could make the ensuing predictions extra strong and arguably much less noisy on account of equal weight averaging. This yr we selected to utilize the highest 10 fashions (vs. final yr’s high 5 or the prior yr’s high 20) to discover a blissful medium between tightening the predictions and avoiding fewer probably overfitted fashions.

Finest Music Authentic Tune OptiML Proven Executing

As soon as our Fusion fashions had been created, we made Batch Predictions in opposition to the films produced within the yr 2024 (slated for the 2025 Oscars), which we had break up apart right into a separate dataset from our essential dataset talked about above.

As traditional, given BigML’s emphasis on white-box fashions with full explainability, we will dig deeper into fashions and predictions for added introspection as wanted. For instance, you may navigate to any Fusion mannequin’s partial dependence plot to see how varied information fields interaction in figuring out whether or not a given film or particular person nominee will win the Oscar.

The 2025 Predictions

With out additional ado, we transfer on to this years predictions with the more than likely winner together with different nominees in the identical class sorted by lowering scores. Remember the fact that these scores are usually not supposed so as to add as much as 100. The fashions are telling us how a film/artist with a given set of traits will probably do in a given award class primarily based on 25 years of historic information on that specific award. That evaluation is made unbiased of the opposite competing nominees for a similar award this yr. In different phrases, a excessive rating might be interpreted as that nominee’s general profile trying fairly just like the previous winners of that class.

2025 Finest Image Decide: ANORA
  • Anora is the clear favourite to win the largest prize of the evening.
2025 Finest Director Decide: SEAN BAKER
  • This prediction normally goes hand-in-hand with the Finest Image and that factors out to Sean Baker because the victor.
2025 Finest Actress Decide: DEMI MOORE
  • Get able to see actual competitors right here. Nobody must be shocked if Mikey Madison pulls it off with the Anora momentum from different classes behind her, however our Fusion fashions put Demi Moore a step forward for what could possibly be a profession second for her.
2025 Finest Actor Decide: ADRIAN BRODY
  • Adrian Brody is anticipated to stroll away with the golden statue probably marking the height second of the evening for The Brutalist followers.
2025 Finest Supporting Actress Decide: ZOE SALDANA
  • Zoe Saldana is as stable as favorites come. Total, our fashions predict Emilia Perez received’t have as a lot to indicate for its large tally of 13 nominations, however this class is the exception.
2025 Finest Supporting Actor Decide: KIERAN CULKIN
  • We predict Kieran Culkin might be topped on this class with a snug margin and it received’t be something close to A Actual Ache for him!
2025 Finest Authentic Screenplay Decide: ANORA
  • Prior years have proven screenplay awards might be tough to foretell. Anora appears to be within the lead right here however don’t be shocked if The Brutalist or The Substance find yourself edging out.
2025 Finest Tailored Screenplay Decide: NICKEL BOYS
  • Nickel Boys is our darkish horse decide of the evening and we’re sticking to it even powerful Conclave and Emilia Perez make for severe competitors.

Along with the favored awards above, three years in the past we added 11 extra classes which might be extra technical in nature. Up to now we have now a reasonably good monitor report with these so we proceed predicting them for you as follows.

  • Finest Cinematography: THE BRUTALIST (NOTE: DUNE: PART TWO is a detailed 2nd.)
  • Finest Costume Design: WICKED
  • Finest Movie Enhancing: WICKED (NOTE: Though THE BRUTALIST and CONCLAVE are virtually in a lifeless warmth with WICKED.)
  • Finest Sound: DUNE: PART TWO
  • Finest Visible Results: DUNE: PART TWO
  • Finest Make-up and Hairstyling: THE SUBSTANCE (NOTE: EMILIA PEREZ is a detailed 2nd right here, and WICKED a detailed third.)
  • Finest Music, Authentic Tune: “EL MAL”, EMILIA PEREZ
  • Finest Music, Authentic Rating: EMILIA PEREZ (NOTE: CONCLAVE is a detailed 2nd right here, and WICKED a detailed third.)
  • Finest Manufacturing Design: WICKED (NOTE: CONCLAVE is a considerably aggressive 2nd.)
  • Finest Worldwide Function Movie: EMILIA PEREZ (NOTE: I’M STILL HERE is a detailed 2nd right here.)
  • Finest Animated Function Movie: THE WILD ROBOT

This concludes our 2025 Oscars predictions. Now it’s your flip to observe in our footsteps constructing your fashions as you prepare for Sunday’s ceremony, which has a promising lineup of prime time leisure. As traditional, we’ll observe up with a publish early subsequent week to grade our predictions. Till then, good luck to all of the nominees!

[ad_2]

Unlocking Fast Wins with AI: Strategizing for Quick Enterprise Outcomes

0

[ad_1]

AI is right here to remain, and we all know it! Main gamers are on a continuing transfer to establish apt alternatives with AI —implementations that supply fast outcomes. However the dilemma begins when corporations begin defining the true targets, undertaking measurement, prices, and ofcourse, the outcomes. That’s the place fast wins with AI are available – It’s sensible. It’s low-risk. It’s budget-friendly. And its USP – You see outcomes quick.

Fast Wins with AI is a instrument with the objective to simplify or automate primary duties that may assist you save time and be environment friendly with out requiring you to grow to be a tech wizard in a single day.How can we use this modern haul? Let’s discover.

What Are Fast Wins with AI?

Small initiatives which have excessive influence – that about sums up the technique of Fast Wins with AI. The objective of any enterprise is to get the job executed on time -the quicker the higher. Fast wins are precisely that. You’re employed on a couple of ache factors in your corporation that influence the large image. Assume automating buyer enquiries or streamlining stock administration.
These initiatives are small tweaks that carry main upgrades to the best way issues work. They’re comparatively straightforward to implement, cost-efficient and present worth rapidly.

Fast wins are about beginning small however considering strategically. For instance, you wish to revamp your provide chain with AI. You can begin off with predicting inventory ranges for a single product line first. You possibly can steadily work your method as much as the entire provide chain. This offers you an opportunity to handle adjustments at a micro stage earlier than you apply it to all the provide chain.

On this method, you decide initiatives that align with your corporation objectives, with minimal disruption, and provide you with a style of AI’s energy. It’s like attempting a brand new recipe earlier than committing to a full-course menu change.

Energy Your Enterprise Development With AI We Can Assist You Strategize a Friction-Free AI Adoption Journey

What Are the High Advantages?

Why trouble with fast wins? As a result of they pack a punch with out the headache of a full-scale AI transformation. Listed here are a few of the prime advantages:

  • Fast Outcomes: Fast Wins imply fast outcomes. You will note a distinction in effectivity and buyer satisfaction inside weeks.
  • Price-Efficient: Fast Wins assist you get monetary savings by utilizing already obtainable information in your database. You don’t have to spend tens of millions on new methods.
  • Low Threat: With Fast wins, you can begin small. That method, you received’t be taking up an enormous loss in case your undertaking fails.
  • Builds Confidence: Seeing AI provide you with ends in one space can construct your confidence in it and assist you develop its makes use of in your corporation.
  • Aggressive Edge: You need to use AI to make small changes in your corporation. This helps you get forward of your opponents who nonetheless have handbook processes.

Having your first response time dropping by 37% or 52% quicker ticket resolutions are the sorts of wins that make AI really feel like a game-changer.

How To Obtain Fast Enterprise Wins Utilizing AI

You’ll find the precise quick-win alternative with out throwing AI at each downside. Right here’s a step-by-step information to being strategic with these golden alternatives and a few skilled tricks to make the method straightforward:

1: Discover Ache Factors:
You can begin by the place your corporation is lagging. Is your customer support staff drowning in repetitive questions? Are you shedding out on gross sales due to gradual pricing selections? You may make a listing of processes that appear time-consuming or clunky.

Skilled Tip: One of the simplest ways to discover a ache level could be by having a look at your information. For instance, in case your customer support staff spends 20 hours every week answering queries, you could have discovered an space to work on.

2: Discover the Proper AI Software:
What’s it that you just actually wish to obtain with AI? Actually take into consideration that first. Then come the instruments that can assist you obtain it.
Efficient question dealing with? Chatbots may also help. Need assistance with establishing pricing mannequin? Predictive analytics could possibly be the instrument you want.

Skilled Tip: Initiatives with clear and measurable outcomes – that must be on the prime of your precedence checklist. Go particular – cut back buyer response time by 30٪, enhance gross sales by 5%. This can get you to the outcomes quicker.

3: Begin with Present Information: Your CRM, gross sales information, or web site analytics are goldmines for AI insights so use this information to get a fast win.

Skilled Tip: Clear your information earlier than you begin. This can optimize the method for you.

4: Select The Proper Instruments: You possibly can decide instruments that can assist you in the easiest way potential. These instruments may also develop with your corporation so that you just don’t have to spend so much to scale up or down. You need to use instruments like chatbots and cloud options to attain this.

Skilled Tip: It is advisable select a vendor that can assist you easily implement these instruments and information you in the event you want it. Firms like Fingent create customized AI options and may wager the very best match for your corporation.

5: Check and Be taught: Your undertaking is now able to launch. You possibly can measure the outcomes and tweak the undertaking as wanted. This helps you make sure that you could have what works completely for you.

Skilled Tip: Loop your staff in to observe AI efficiency. Whenever you examine in in your undertaking usually, you possibly can know for certain that you just’re getting the very best out of your funding.

Actual-World Use Instances and Case Research

Let’s carry this to life with some examples. Fast wins with AI are already reworking companies throughout industries. Listed here are a couple of methods corporations are making it occur:

Uber Boosts Worker Productiveness With AI

Uber makes use of AI brokers that assist workers be extra productive. It helps them to avoid wasting time and be extra environment friendly at what they do. The corporate launched new initiatives that helped with communication with customers by making it transient and summarized. It additionally makes use of floor context from earlier interactions in order that the front-line workers may be simpler of their processes and useful to clients.

PODS and the “World’s Smartest Billboard.”

PODS labored with an promoting company Tombras to create the “World’s Smartest Billboard.” They used Google Gemini to design a marketing campaign on its vans. The clincher is that it might adapt to completely different areas in New York Metropolis and will change primarily based on obtainable information in real-time. It was in a position to attain 299 neighbourhoods in simply 29 hours and created greater than 6000 distinctive headlines!

Skilled Monitoring by UPS

UPS constructed a reproduction of its distribution community. Now, employees in addition to clients can see the placement of their packages at any given time.

Checkout How AI Is Reworking Software program Improvement with AI

Learn Extra!

Addressing Inefficiencies and Decreasing Prices With Fingent

Fingent, an organization identified for crafting customized AI options, helped a personal jet constitution agency that was battling inefficiencies in its methods resulting from off-the-shelf software program. The challenges of this agency have been:

  • Restricted Integration
  • Guide Processes
  • Expensive “Empty Leg” Flights (planes that fly with out passengers)

Fingent created an AI answer personalized to this firm’s wants and turned issues round. They constructed a platform that built-in with instruments like Avinode and Airmail. These instruments helped automate e-mail monitoring and storing to identify high-value alternatives (like journeys inside the subsequent 30 days). The AI additionally adjusted costs for purchasers in real-time which helped the agency with competitors.
The outcome was phenomenal. The agency might now plan flights flawlessly and this eradicated empty legs. The instruments additionally streamlined reserving processes which enhanced buyer satisfaction.

These are excellent examples of how AI initiatives that focus on an organization’s ache factors can ship fast wins with out it being heavy on the pocket.

Weblog : Constructing Belief in Al: Enabling Companies to Strategize an Moral Al Future

Widespread FAQs About Fast Wins with AI

Listed here are some frequent questions companies ask when getting began with AI:

1: Are AI instruments costly?

A: By no means. Fast wins are designed in a method that helps you handle prices successfully. You don’t have to spend so much as a result of these instruments use already present information out of your database and are inexpensive.

2: Does my staff must be skilled with tech to make use of these instruments?

A: No, they don’t must be! These AI instruments are very consumer pleasant and you probably have companion, like Fingent, who can information you thru the method and assist you implement it, then that’s the easiest way to go about it.

3: Can Small companies use AI?

A: Most positively. Actually, small companies profit quite a bit from AI as these instruments are scalable. They use already present information in your organization database, so it’s gentle on the pocket and low-risk, too.

4: By when are you able to begin seeing outcomes?

A: This relies on the AI undertaking you’ve chosen to implement. A chatbot can go stay in a few week however in the event you’re coping with one thing just a little extra advanced that wants effective tuning, like predictive analytics, it may well take a month at finest.

5: How do I do know if AI could be the precise alternative for my enterprise?

A: To know this, you possibly can check out the methods in place at your corporation. If there’s something that strikes you as being data-driven or gradual with repetitive processes, you possibly can then automate these duties utilizing an AI implementation technique. This can positively save lots of time and enhance effectivity.

Get Began With Fast Wins With AI

The important thing to success with fast wins? Begin small. Keep targeted. Attain out. Don’t go it alone. Get assist from the consultants.

Your first step: Determine one or two ache factors in your corporation. Then, see the completely different AI instruments that may assist you with it. You don’t must AI options simply suit your wants and may be personalized to fit your particular wants. Fingent has helped many small companies discover the very best answer to their necessities by crafting customized instruments that ship outcomes quick.
Try our AI options to find alternatives with AI, or contact us now and let’s talk about your undertaking.

[ad_2]

Weak-for-Robust (W4S): A Novel Reinforcement Studying Algorithm that Trains a weak Meta Agent to Design Agentic Workflows with Stronger LLMs

[ad_1]

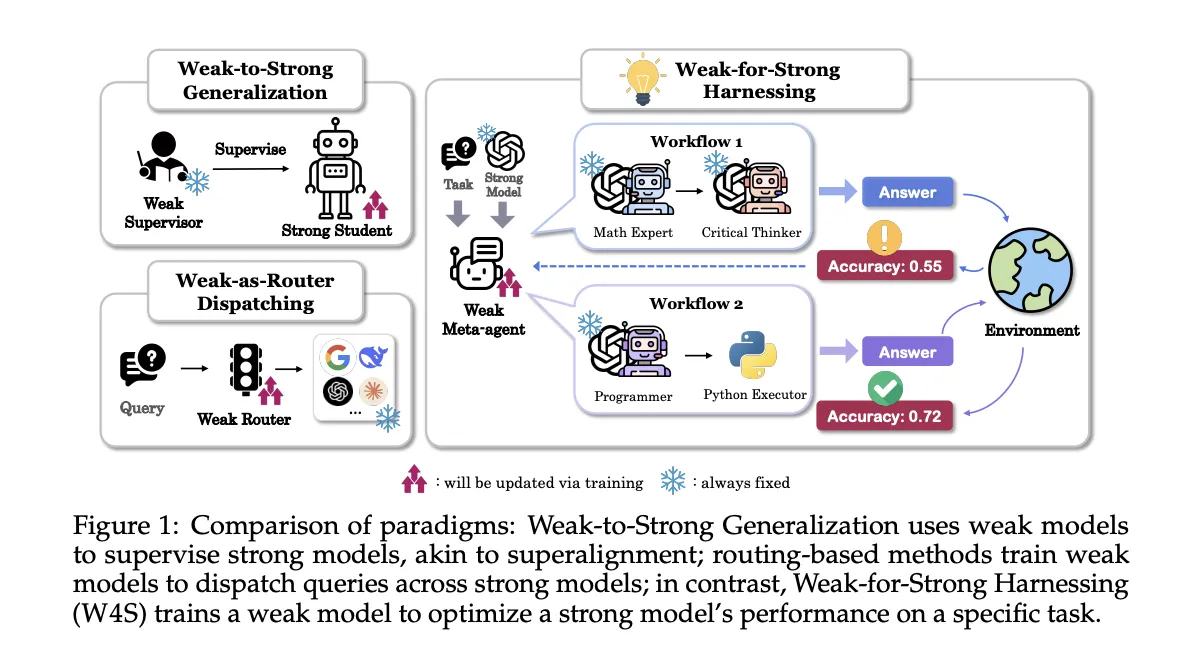
Researchers from Stanford, EPFL, and UNC introduce Weak-for-Robust Harnessing, W4S, a brand new Reinforcement Studying RL framework that trains a small meta-agent to design and refine code workflows that decision a stronger executor mannequin. The meta-agent doesn’t fantastic tune the sturdy mannequin, it learns to orchestrate it. W4S formalizes workflow design as a multi flip Markov resolution course of, and trains the meta-agent with a way known as Reinforcement Studying for Agentic Workflow Optimization, RLAO. The analysis crew stories constant good points throughout 11 benchmarks with a 7B meta-agent educated for about 1 GPU hour.

https://arxiv.org/pdf/2504.04785

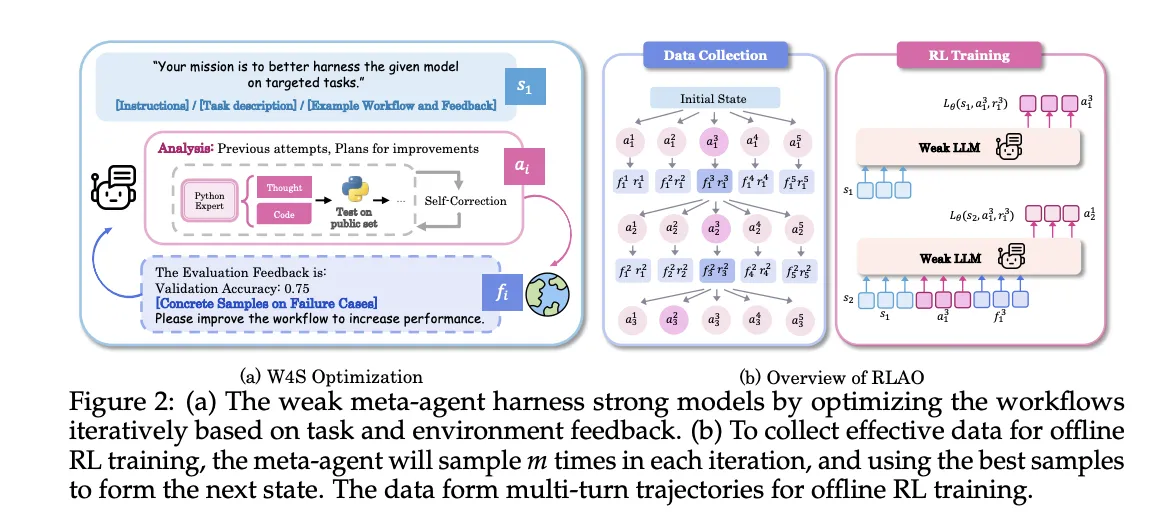
W4S operates in turns. The state accommodates process directions, the present workflow program, and suggestions from prior executions. An motion has 2 parts, an evaluation of what to alter, and new Python workflow code that implements these modifications. The setting executes the code on validation gadgets, returns accuracy and failure instances, and gives a brand new state for the following flip. The meta-agent can run a fast self test on one pattern, if errors come up it makes an attempt as much as 3 repairs, if errors persist the motion is skipped. This loop offers studying sign with out touching the weights of the sturdy executor.

https://arxiv.org/pdf/2504.04785


W4S runs as an iterative loop

  • Workflow technology: The weak meta agent writes a brand new workflow that leverages the sturdy mannequin, expressed as executable Python code.
  • Execution and suggestions: The sturdy mannequin executes the workflow on validation samples, then returns accuracy and error instances as suggestions.
  • Refinement: The meta agent makes use of the suggestions to replace the evaluation and the workflow, then repeats the loop.

Reinforcement Studying for Agentic Workflow Optimization (RLAO)

RLAO is an offline reinforcement studying process over multi flip trajectories. At every iteration, the system samples a number of candidate actions, retains the very best performing motion to advance the state, and shops the others for coaching. The coverage is optimized with reward weighted regression. The reward is sparse and compares present validation accuracy to historical past, a better weight is given when the brand new consequence beats the earlier finest, a smaller weight is given when it beats the final iteration. This goal favors regular progress whereas controlling exploration price.

https://arxiv.org/pdf/2504.04785

Understanding the Outcomes

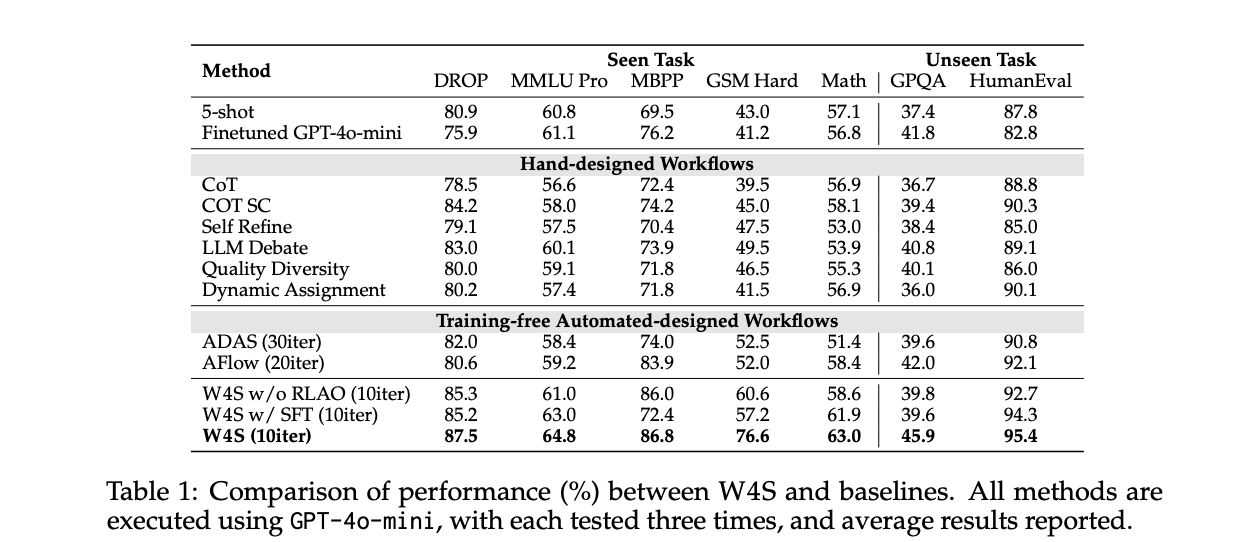
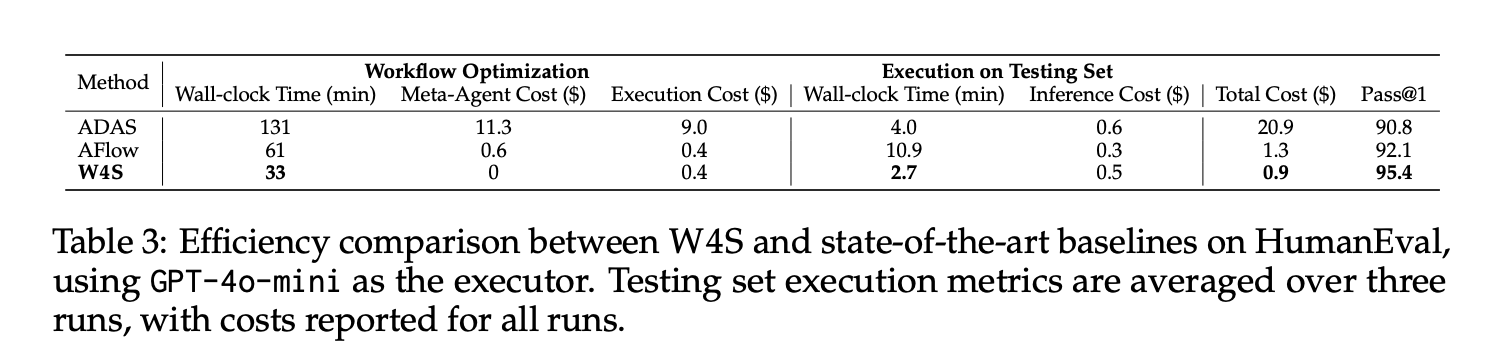
On HumanEval with GPT-4o-mini as executor, W4S achieves Move@1 of 95.4, with about 33 minutes of workflow optimization, zero meta-agent API price, an optimization execution price of about 0.4 {dollars}, and about 2.7 minutes to execute the take a look at set at about 0.5 {dollars}, for a complete of about 0.9 {dollars}. Beneath the identical executor, AFlow and ADAS path this quantity. The reported common good points towards the strongest automated baseline vary from 2.9% to 24.6% throughout 11 benchmarks.

On math switch, the meta-agent is educated on GSM Plus and MGSM with GPT-3.5-Turbo as executor, then evaluated on GSM8K, GSM Onerous, and SVAMP. The paper stories 86.5 on GSM8K and 61.8 on GSM Onerous, each above automated baselines. This means that the discovered orchestration transfers to associated duties with out re coaching the executor.

Throughout seen duties with GPT-4o-mini as executor, W4S surpasses coaching free automated strategies that don’t be taught a planner. The examine additionally runs ablations the place the meta-agent is educated by supervised fantastic tuning quite than RLAO, the RLAO agent yields higher accuracy below the identical compute funds. The analysis crew embrace a GRPO baseline on a 7B weak mannequin for GSM Onerous, W4S outperforms it below restricted compute.

Iteration budgets matter. The analysis crew units W4S to about 10 optimization activates principal tables, whereas AFlow runs about 20 turns and ADAS runs about 30 turns. Regardless of fewer turns, W4S achieves greater accuracy. This means that discovered planning over code, mixed with validation suggestions, makes the search extra pattern environment friendly.

https://arxiv.org/pdf/2504.04785

Key Takeaways

  • W4S trains a 7B weak meta agent with RLAO to put in writing Python workflows that harness stronger executors, modeled as a multi flip MDP.
  • On HumanEval with GPT 4o mini as executor, W4S reaches Move@1 of 95.4, with about 33 minutes optimization and about 0.9 {dollars} complete price, beating automated baselines below the identical executor.
  • Throughout 11 benchmarks, W4S improves over the strongest baseline by 2.9% to 24.6%, whereas avoiding fantastic tuning of the sturdy mannequin.
  • The tactic runs an iterative loop, it generates a workflow, executes it on validation knowledge, then refines it utilizing suggestions.
  • ADAS and AFlow additionally program or search over code workflows, W4S differs by coaching a planner with offline reinforcement studying.

W4S targets orchestration, not mannequin weights, and trains a 7B meta agent to program workflows that decision stronger executors. W4S formalizes workflow design as a multi flip MDP and optimizes the planner with RLAO utilizing offline trajectories and reward weighted regression. Reported outcomes present Move@1 of 95.4 on HumanEval with GPT 4o mini, common good points of two.9% to 24.6% throughout 11 benchmarks, and about 1 GPU hour of coaching for the meta agent. The framing compares cleanly with ADAS and AFlow, which search agent designs or code graphs, whereas W4S fixes the executor and learns the planner.


Take a look at the Technical Paper and GitHub Repo. Be happy to take a look at our GitHub Web page for Tutorials, Codes and Notebooks. Additionally, be happy to comply with us on Twitter and don’t overlook to hitch our 100k+ ML SubReddit and Subscribe to our Publication. Wait! are you on telegram? now you possibly can be a part of us on telegram as properly.


Michal Sutter is a knowledge science skilled with a Grasp of Science in Knowledge Science from the College of Padova. With a stable basis in statistical evaluation, machine studying, and knowledge engineering, Michal excels at reworking complicated datasets into actionable insights.

[ad_2]

This $1,499 MacBook Professional is now underneath $300

0

[ad_1]

[ad_2]

Rouse, Russel, & Campbell (2025) is a curated listing of Psi Chi journals which can be good for Intro Stats.

0

[ad_1]

This summer time, the Psi Chi Journal of Psychology Analysis printed Rouse, Russel, and Campbell’s Past the textbook: Psi Chi Journal articles in introductory psychology programs.

It’s a curated listing of paywall-free Psi Chi articles, largely with scholar co-authors, which can be peer-reviewed and of an acceptable writing degree and size to make use of in an Introduction to Psychology course. The authors present the next data for every of the articles:

Along with being acceptable for Into Psych, these articles are additionally good for Intro Stats. In my courses, I emphasize the power to learn and write easy consequence sections. A technique I’d evaluate this ability is by exhibiting my college students Outcomes sections from printed analysis and asking them to determine the take a look at statistics, impact measurement, and different related data. This collection of articles options clear and concise outcomes sections for t-tests, ANOVA, factorial ANOVA, regression, and correlation. I created a spreadsheet that features all of the articles, hyperlinks to the articles, and the precise analyses utilized in every article. 

When you like this instance, take a look at my W.W. Norton & Co. textbook, Psychological Statistics for Everybody. 

[ad_2]

Rainbow-on-a-chip’ might assist preserve AI vitality calls for in test — and it was created by chance

0

[ad_1]

A lab accident has led engineers to construct a chip that fires a rainbow of highly effective laser beams — and it might assist knowledge facilities higher handle skyrocketing volumes of synthetic intelligence (AI) knowledge.

The brand new photonics chip incorporates an industrial-grade laser supply paired with a exactly engineered optical circuit that shapes and stabilizes the sunshine earlier than splitting it into a number of, evenly spaced colours.

[ad_2]

How has heart problems contributed to the agricultural–city life expectancy hole? – IJEblog

0

[ad_1]

Leah Abrams

In america, rural residents don’t stay so long as their city counterparts. This disparity has been widening for many years. Round 1970, city life expectancy was 70.9 years, in contrast with 70.5 in rural areas, however by 2005–2009, the distinction was larger (78.8 versus 76.8 years). In our analysis lately revealed within the IJE, we discovered that the hole in life expectancy could be even wider at present if declines in heart problems (CVD) mortality had not dramatically slowed round 2010.

CVD, which incorporates all types of coronary heart illness, coronary heart failure, atherosclerosis and hypertension, is the main reason for loss of life within the US. Its mortality price had been quickly declining for many years, because of decreased smoking, higher hypertension management and use of statins, thrombolysis and stents. Nevertheless, round 2010, this decline stagnated.

On the identical time, enhancements in nationwide life expectancy stalled. In prior analysis, we confirmed that CVD mortality stagnation is the principle offender, much more so than latest will increase in drug overdose deaths. Nevertheless, little was recognized concerning the function of CVD mortality tendencies in latest rural–city life expectancy variations.

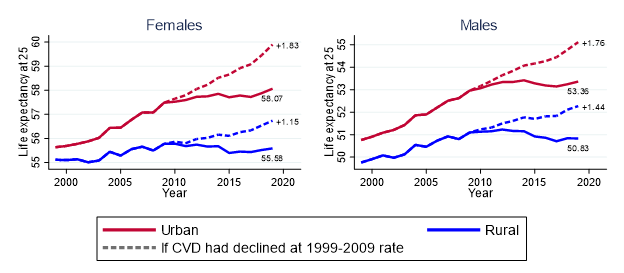
Utilizing Facilities for Illness Management and Prevention knowledge on all 51,998,560 deaths within the US throughout 1999–2019, we first in contrast, over time, rural and concrete life expectancy at age 25. We discovered that, from 1999 to 2009, the hole between city and rural counties grew. City life expectancy elevated 1.19 years extra in ladies and 0.86 extra in males in contrast with rural life expectancy. Extra lately (2010–2019), when total US life expectancy stalled, rural counties skilled declines in life expectancy (–0.20 years for ladies and –0.30 years for males), whereas city counties noticed modest will increase (0.55 years for ladies and 0.29 years for males). The agricultural–city hole continued to develop throughout 2010–2019, however its tempo was slower than in 1999–2009.

What would rural and concrete life expectations have been if CVD mortality had continued its decline moderately than stagnating? To seek out out, we estimated life expectations at age 25 beneath hypothetical situations. This confirmed that, if CVD mortality had not stagnated, rural life expectancy throughout 2010–2019 would have elevated by 1.15 years in ladies and 1.44 years in males, in contrast with the true modifications. This implies that CVD mortality stagnation was a fundamental driver of the post-2010 decline in rural life expectancy. The impact on city life expectancy was even larger (1.83 years in ladies and 1.76 years in males). CVD mortality stagnation’s influence on life expectancy is nearly as giant because the impact of the COVID-19 pandemic – 1.87 years. Total, if CVD mortality had continued to say no at its pre-2010 tempo, the agricultural–city life expectancy hole could be even larger than it’s now.

Rural and concrete life expectations at age 25 years beneath noticed and hypothetical situations

Apparently, a lot of the impact of CVD mortality stagnation on life expectancy in each city and rural areas is attributable to slowing enhancements in mortality amongst adults aged over 65 years. That is shocking as a result of total life expectancy is influenced extra by deaths at youthful ages, and there’s rising concern about elevated mortality in midlife. Nevertheless, so many CVD deaths happen in outdated age that slowing mortality declines on this group are a driving pressure of total life expectancy tendencies.

A continued decline of CVD mortality throughout the US, particularly in older adults, can be important to enhance life expectancy. As a result of the agricultural–city hole was rising shortly whereas CVD mortality was robustly declining, efforts to rejuvenate that decline aren’t more likely to cut back this distinction until an emphasis is positioned on rural well being. Proof means that sustained community-wide applications focusing on CVD danger elements like hypertension and hyperlipidemia, in addition to behavioural modifications like smoking cessation and elevated bodily exercise, can successfully cut back rural CVD mortality. For widespread and sustained enhancements in cardiovascular well being and life expectancy, it’s going to even be necessary to handle extra upstream elements that form poor well being in rural areas, corresponding to static incomes, meals insecurity and low ranges of well being care entry.

Learn extra:

Abrams LR, Myrskyla M, Mehta NK. The rising rural–city divide in US life expectancy: contribution of heart problems and different main causes of loss of life. Int J Epidemiol 2021; 11 August. doi: 10.1093/ije/dyab158.


Leah R Abrams, PhD, MPH, is a Sloan Postdoctoral Fellow on the Harvard Middle for Inhabitants and Improvement Research. Her analysis pertains to fairness in ageing, work/retirement, psychological well being and mortality. Twitter: @LeahRAbrams


[ad_2]

Delivering the UK’s carbon targets by 2050 will contain structural shifts within the UK financial system – and public coverage has a vital function to play

0

[ad_1]

Yesterday, the UK’s Local weather Change Committee (CCC) launched their seventh Carbon Finances Report, setting out an emissions goal for 2038 to 2042, and suggestions to get there. It demonstrates the size of change wanted throughout vitality technology, main vitality consuming applied sciences, and the alternatives made by households and companies to maintain the UK on observe to fulfill web zero.

Decarbonising the financial system will rework elements of the financial system reasonably than the financial system as a complete

Whereas modifications inside these elements of the financial system might be substantial, the CCC is correct to level out that almost all of the modifications are inside sure sectors equivalent to energy technology, reasonably than transformational throughout the financial system as a complete.

Until Carbon Seize Utilization and Storage (CCUS) turns into extra price aggressive than at present anticipated, greening the financial system by 2050 might be an existential problem for the oil & fuel sector, and can change the degrees of capital expenditure, financial exercise, employment and expertise necessities in various sectors equivalent to vitality provide, agriculture, family heating and motorized vehicle upkeep. Whereas sources of vitality (for transport, heating and different functions) will change, the basics of financial exercise in most different sectors won’t.

Public coverage may have a key function in delivering a simply transition to web zero for probably the most susceptible in society
There may be clearly a significant function for public coverage in delivering the transition in a approach that doesn’t drawback probably the most susceptible in society.

Earlier work carried out by Cambridge Econometrics as a part of the Centre for Analysis into Vitality Demand Options (CREDS) has demonstrated that totally different coverage pathways will be utilised to ship a decarbonised financial system, and that there are financial (and potential equality) advantages to delivering it in a approach that helps low-income households.

As ever, a lot of the satan is within the element – for instance, overcoming the break up incentives drawback of bettering vitality effectivity in rented properties, the place the owner pays for the effectivity measures whereas the tenant accrues the advantages of decrease vitality payments.

As one other instance, a lot of the CCC’s pitch round the advantages of decarbonisation centres on the potential for decrease vitality payments; however the UK electrical energy market has just lately skilled (mercifully brief) intervals of extraordinarily excessive costs, pushed by excessive costs demanded by mixed cycle fuel turbine peaker vegetation.

The long run GB electrical energy market will have to be designed in such a approach as to minimise the affect that such intervals of excessive costs (largely inevitable in an electrical energy system dominated by variable renewables) have on costs confronted by shoppers.

It’s important to assume holistically in regards to the prices and advantages of delivering a decarbonised financial system, reasonably than focusing solely on monetary prices

Lastly, the CCC report highlights that the size of further capital expenditure required to ship the decarbonised UK financial system by 2050 is smaller than it beforehand estimated. An financial system that’s powered by electrical energy, reasonably than fossil fuels, is powered by domestically produced items reasonably than imports, creating jobs and financial alternative inside our personal borders. However there are different causes to assume that the transition might be helpful to the UK financial system at giant.

Earlier evaluation carried out by the staff at Cambridge Econometrics estimating the macroeconomic impacts of the Sixth Carbon Finances. While this was not up to date for the most recent Carbon Finances, this evaluation is insightful and essential for public coverage growth as a result of it demonstrates clearly the distinction between system prices (broadly what’s measured by the CCC) and the macro-level outcomes which reveal long-term financial development.

  • Giant-scale funding in new energy technology capability, and in new manufacturing websites, will act as a short-term stimulus (significantly in building and manufacturing), in addition to offering long-term employment alternatives.
  • Switching to extra vitality environment friendly applied sciences equivalent to from combustion engines to electrical motors; from fuel boilers to warmth pumps; and from blast furnaces to electrical arc furnaces, means much less moving into for a similar output, which may bolster financial productiveness in the long run –  assuming that the change in vitality content material as an enter is mirrored in the price of that vitality content material.
  • The remainder of the world will decarbonise over time, because the financial advantages (on the micro and macro ranges) change into clear. Decarbonising the UK financial system is critical to make sure that the UK stays aggressive on the worldwide scale, and provides a chance for growing experience that may subsequently be exported to different international locations which might be decarbonising at a slower tempo.

These impacts spotlight why it’s important to take a wider macroeconomic view of how modifications in capital and working expenditure will affect the long-term growth of the financial system.

They’ll present essential supporting proof for the way decarbonising the financial system cannot solely restrict the devastating impacts of local weather change, however may help wider coverage goals of bolstering financial development within the UK, and the way it’s distributed throughout the nation.

Cambridge Econometrics has the econometric modelling instruments and coverage analysis experience that will help you deal with these points; the potential advantages from the transition to web zero, how they is perhaps distributed throughout the nation and the inhabitants, and the way coverage can assist to form these outcomes. Get in contact when you’d like to higher perceive these points.


[ad_2]

Is it Time to Un-Sass?

0

[ad_1]

A number of weeks in the past, I participated in Entrance Finish Research Corridor. Entrance Finish Research Corridor is an HTML and CSS targeted assembly held on Zoom each two weeks. It is a chance to study from each other as we share our widespread curiosity in these two constructing blocks of the Net. Some weeks, there’s extra targeted dialogue whereas different weeks are extra open ended and members will ask questions or carry up matters of curiosity.

Joe, the moderator of the group, often begins the dialogue with one thing he has been eager about. On this specific assembly, he requested us about Sass. He requested us if we used it, if we favored it, after which to share our expertise with it. I had deliberate to reply the query however the dialog drifted into one other matter earlier than I had the possibility to reply. I noticed it as a chance to put in writing and to share among the issues that I’ve been eager about just lately.

Beginnings

I began utilizing Sass in March 2012. I had been listening to about it via various things I learn. I consider I heard Chris Coyier speak about it on his then-new podcast, ShopTalk Present. I had been concerned with redesigning my private web site and I assumed it might be an important probability to study Sass. I purchased an e-book model of Pragmatic Information to Sass after which put what I used to be studying into follow as I constructed a brand new model of my web site. The e-book steered utilizing Compass to course of my Sass into CSS. I selected to make use of SCSS syntax as an alternative of indented syntax as a result of SCSS was much like plain CSS. I assumed it was necessary to remain near the CSS syntax as a result of I may not at all times have the possibility to make use of Sass, and I needed to proceed to construct my CSS expertise.

It was very straightforward to stand up and operating with Sass. I used a GUI device referred to as Scout to run Compass. After some frustration attempting to replace Ruby on my laptop, Scout gave me an atmosphere to stand up and going shortly. I didn’t even have to make use of the command line. I simply pressed “Play” to inform my laptop to observe my information. Later I realized learn how to use Compass via the command line. I favored the simplicity of that device and want that not less than one among at the moment’s construct instruments included that very same simplicity.

I loved utilizing Sass out of the gate. I favored that I used to be capable of create reusable variables in my code. I may arrange colours and typography and have consistency throughout my code. I had not deliberate on utilizing nesting a lot however after I attempted it, I used to be hooked. I actually favored that I may write much less code and handle all of the relationships with nesting. It was nice to have the ability to nest a media question inside a selector and never should hunt for it in one other place in my code.

Quick-forward a bit…

After my profitable first expertise utilizing Sass in a private venture, I made a decision to begin utilizing it in my skilled work. And I inspired my teammates to embrace it. One of many issues I favored most about Sass was that you might use as little or as a lot as you favored. I used to be nonetheless writing CSS however now had the superpower that the completely different helper features in Sass enabled.

I didn’t get as deep into Sass as I may have. I used the Sass @prolong rule extra at first. There are a number of options that I didn’t reap the benefits of, like placeholder selectors and for loops. I’ve by no means been one to rely a lot on shortcuts. I take advantage of only a few of the shortcuts on my Mac. I’ve dabbled in issues like Emmet however are likely to shortly abandon them as a result of I’m simply use to writing issues out and haven’t developed the muscle reminiscence of utilizing shortcuts.

Is it time to un-Sass?

By my depend, I’ve been utilizing Sass for over 13 years. I selected Sass over Much less.js as a result of I assumed it was a greater route to go on the time. And my wager paid off. That is among the tough issues about working within the technical area. There are a number of good instruments however some find yourself rising to the highest and others fall away. I’ve been fairly lucky that a lot of the selections I’ve made have gone the way in which that they’ve. All of the businesses I’ve labored for have used Sass.

Originally of this 12 months, I lastly jumped into constructing a prototype for a private venture that I’ve been eager about for years: my very own reminiscence keeper. One of many few issues that I favored about Fb was the Recollections function. I loved visiting that web page every day to recollect what I had been doing on that particular day in years previous. However I felt at instances that Fb was not giving me all of my reminiscences. And my life doesn’t simply occur on Fb. I additionally needed a technique to view reminiscences from different days in addition to simply the present date.

As I began constructing my prototype, I needed to maintain it easy. I didn’t need to should arrange any construct instruments. I made a decision to put in writing CSS with out Sass.

Okay, in order that was my intention. However I quickly realized that that I used to be utilizing nesting. I had been engaged on it a few days earlier than I spotted it.

However my code was working. That’s once I realized that the native nesting in CSS works a lot the identical nesting in Sass. I had adopted the dialogue about implementing nesting in native CSS. At one level, the syntax was going to be very completely different. To be trustworthy, I misplaced monitor of the place issues had landed as a result of I used to be persevering with to make use of Sass. Native CSS nesting was not a giant concern to me proper then.

I used to be amazed once I realized that nesting works simply the identical means. And it was in that second that I started to surprise:

Is that this lastly the time to un-Sass?

I need to give credit score the place credit score is due. I’m borrowing the time period “un-Sass” from Stu Robson, who is definitely in the course of writing a collection referred to as “Un-Sass’ing my CSS” as I began eager about scripting this publish. I really like the time period “un-Sass” as a result of it’s straightforward to recollect and so spot on to explain what I’ve been eager about.

Here’s what I’m considering:

Customized Properties

I knew that so much about what I favored about Sass had began to make its means into native CSS. Customized properties had been one of many first issues. Customized properties are extra highly effective than Sass variables as a result of you may assign a brand new worth to a customized property in a media question or in a theming system, like gentle and darkish modes. That’s one thing Sass is unable to do since variables grow to be static as soon as they’re compiled into vanilla CSS. It’s also possible to assign and replace customized properties with JavaScript. Customized properties additionally work with inheritance and have a broader scope than Sass variables.

So, yeah. I discovered that not solely was I already pretty aware of the idea of variables, because of Sass, however the native CSS model was rather more highly effective.

I first used CSS Customized Properties when constructing two completely different themes (gentle and darkish) for a shopper venture. I additionally used them a number of instances with JavaScript and favored the way it gave me new potentialities for utilizing CSS and JavaScript collectively. In my new job, we use customized properties extensively and I’ve fully converted to utilizing them in any new code that I write. I made use of customized properties extensively once I redesigned my private website final 12 months. I took benefit of it to create a lightweight and darkish theme and I utilized it with Utopia for typography and spacing utilities.

Nesting

When Sass launched nesting, it simplified the writing of CSS code since you write model guidelines inside one other model rule (often a guardian). Which means you now not needed to write out the total descendent selector as a separate rule. You might additionally nest media queries, function queries, and container queries.

This skill to group code collectively made it simpler to see the relationships between guardian and youngster selectors. It was additionally helpful to have the media queries, container queries, or function queries grouped inside these selectors moderately than grouping all of the media question guidelines collectively additional down within the stylesheet.

I already talked about that I stumbled throughout native CSS nesting when writing code for my reminiscence keeper prototype. I used to be very excited that the specification prolonged what I already knew about nesting from Sass.

Two years in the past, the nesting specification was going to require you to begin the nested question with the & image, which was completely different from the way it labored in Sass.

.footer {
  a { colour: blue }
}
/* 2023 */
.footer {
  & a { colour: blue } /* This was legitimate then */
}

However that modified someday within the final two years and also you now not want the ampersand (&) image to put in writing a nested question. You may write simply as you had been writing it in Sass. I’m very glad about this transformation as a result of it means native CSS nesting is rather like I’ve been writing it in Sass.

/* 2025 */
.footer {
  a { colour: blue } /* As we speak's legitimate syntax */
}

There are some variations within the native implementation of nesting versus Sass. One distinction is that you just can’t create concatenated selectors with CSS. If you happen to love BEM, you then in all probability made use of this function in Sass. Nevertheless it doesn’t work in native CSS.

.card {
  &__title {}
  &__body {}
  &__footer {}
}

It doesn’t work as a result of the & image is a dwell object in native CSS and it’s at all times handled as a separate selector. Don’t fear, if you happen to don’t perceive that, neither do I. The necessary factor is to know the implication – you can’t concatenate selectors in native CSS nesting.

In case you are concerned with studying a bit extra about this, I’d recommend Kevin Powell’s, “Native CSS Nesting vs. Sass Nesting” from 2023. Simply know that the details about having to make use of the & image earlier than a component selector in native CSS nesting is old-fashioned.

I by no means took benefit of concatenated selectors in my Sass code so this is not going to have an effect on my work. For me, nesting is native CSS is equal to how I used to be utilizing it in Sass and is among the the explanation why to think about un-Sassing.

My recommendation is to watch out with nesting. I’d recommend attempting to maintain your nested code to 3 ranges on the most. In any other case, you find yourself with very lengthy selectors which may be harder to override elsewhere in our codebase. Maintain it easy.

The color-mix() perform

I favored utilizing the Sass colour module to lighten or darken a colour. I’d use this most frequently with buttons the place I needed the hover colour to be completely different. It was very easy to do with Sass. (I’m utilizing $colour to face in for the colour worth).

background-color: darken($colour, 20%);

The color-mix() perform in native CSS permits me to do the identical factor and I’ve used it extensively up to now few months since studying about it from Chris Ferdinandi.

background-color: color-mix(in oklab, var(--color), #000000 20%);

Mixins and features

I do know that a number of builders who use Sass make in depth use of mixins. Previously, I used a good variety of mixins. However a number of the time, I used to be simply pasting mixins from earlier initiatives. And lots of instances, I didn’t make as a lot use of them as I may as a result of I’d simply plain overlook that I had them. They had been at all times good helper features and allowed me to not have to recollect issues like clearfix or font smoothing. However these had been additionally methods that I discovered myself utilizing much less and fewer.

I additionally utilized features in Sass and created a number of of my very own, principally to do some math on the fly. I primarily used them to transform pixels into ems as a result of I favored with the ability to outline my typography and spacing as relative and creating relationships in my code. I additionally had written a perform to covert pixels to ems for customized media queries that didn’t match throughout the breakpoints I usually used. I had realized that it was a a lot better follow to make use of ems in media queries in order that layouts wouldn’t break when a consumer used web page zoom.

At present, we do not need a technique to do mixins and features in native CSS. However there’s work being finished so as to add that performance. Geoff wrote in regards to the CSS Features and Mixins Module.

I did a little bit experiment for the use case I used to be utilizing Sass features for. I needed to calculate em items from pixels in a customized media question. My customary follow is to set the physique textual content measurement to 100% which equals 16 pixels by default. So, I wrote a calc() perform to see if I may replicate what my Sass perform offered me.

@media (min-width: calc((600 / 16) * 1em));

This tradition media question is for a minimal width of 600px. This is able to work primarily based on my setting the bottom font measurement to 100%. It may very well be modified.

Uninterested in tooling

One more reason to think about un-Sassing is that I’m merely drained of tooling. Tooling has gotten an increasing number of advanced over time, and never essentially with a greater developer expertise. From what I’ve noticed, at the moment’s tooling is predominantly geared in direction of JavaScript-first builders, or anybody utilizing a framework like React. All I would like is a device that’s straightforward to arrange and preserve. I don’t need to should study a posh system with the intention to do quite simple duties.

One other concern is dependencies. At my present job, I wanted so as to add some new content material and types to an older WordPress website that had not been up to date in a number of years. The positioning used Sass, and after a little bit of digging, I found that the earlier developer had used CodeKit to course of the code. I renewed my Codekit license in order that I may add CSS to model the content material I used to be including. It took me a bit to get the settings right as a result of the settings within the repo weren’t saving the processed information to the right location.

As soon as I lastly received that set, I continued to come across errors. Dart Sass, the engine that powers Sass, launched modifications to the syntax that broke the present code. I began refactoring a considerable amount of code to replace the positioning to the right syntax, permitting me to put in writing new code that will be processed. 

I spent about 10 minutes trying to refactor the older code, however was nonetheless getting errors. I simply wanted so as to add a number of traces of CSS to model the brand new content material I used to be including to the positioning. So, I made a decision to go rogue and write the brand new CSS I wanted instantly within the WordPress template. I’ve had comparable experiences with different legacy codebases, and that’s the type of factor that may occur once you’re tremendous reliant on third-party dependencies. You spend extra time attempting to refactor the Sass code so you may get to the purpose the place you may add new code and have it compiled.

All of this has left me bored with tooling. I’m fortune sufficient at my new place that the tooling is all arrange via the Django CMS. However even with that system, I’ve run into points. For instance, I attempted utilizing a combination of proportion and pixels values in a minmax() perform and Sass was attempting to guage it as a math perform and the items had been incompatible.

grid-template-columns: repeat(auto-fill, minmax(min(200px, 100%), 1fr));

I wanted to have the ability to escape and never have Sass attempt to consider the code as a math perform:

grid-template-columns: repeat(auto-fill, minmax(unquote("min(200px, 100%)"), 1fr));

This isn’t an enormous ache level but it surely was one thing that I needed to take a while to analyze that I may have been utilizing to put in writing HTML or CSS. Fortunately, that’s one thing Ana Tudor has written about.

All of those completely different ache factors lead me to be bored with having to mess with tooling. It’s another excuse why I’ve thought of un-Sassing.

Verdict

So what’s my verdict — is it time to un-Sass?

Please don’t hate me, however my conclusion is: it relies upon. Perhaps not the definitive reply you had been on the lookout for.

However you in all probability are usually not stunned. You probably have been working in internet improvement even a brief period of time, that there are only a few definitive methods of doing issues. There are a number of completely different approaches, and simply because another person solves it in another way, doesn’t imply you’re proper and they’re flawed (or vice versa). Most issues come all the way down to the venture you’re engaged on, your viewers, and a bunch of different elements.

For my private website, sure, I wish to un-Sass. I need to kick the construct course of to the curb and get rid of these dependencies. I’d additionally like for different builders to have the ability to view supply on my CSS. You may’t view supply on Sass. And a part of the explanation I write on my website is to share options which may profit others, and making code extra accessible is a pleasant upkeep enhancement.

My private website doesn’t have a really giant codebase. I may in all probability simply un-Sass it in a few days or over a weekend.

However for bigger websites, just like the codebase I work with at my job. I wouldn’t recommend un-Sassing it. There may be means an excessive amount of code that must be refactored and I’m unable to justify the associated fee for that sort of effort. And truthfully, it’s not one thing I really feel motivated to deal with. It really works simply superb the way in which that it’s. And Sass remains to be an excellent device to make use of. It’s not “breaking” something.

Your venture could also be completely different and there is likely to be extra positive factors from un-Sassing than the venture I work on. Once more, it relies upon.

The way in which ahead

It’s an thrilling time to be a CSS developer. The language is continuous to evolve and mature. And every single day, it’s incorporating new options that first got here to us via different third-party instruments resembling Sass. It’s at all times a good suggestion to cease and re-evaluate your know-how selections to find out in the event that they nonetheless maintain up or if extra trendy approaches could be a greater means ahead.

That doesn’t imply now we have to return and “repair” all of our previous initiatives. And it may not imply doing a whole overhaul. Plenty of newer methods can dwell facet by facet with the older ones. We have now a mixture of each Sass variables and CSS customized properties in our codebase. They don’t work in opposition to one another. The beauty of internet applied sciences is that they construct on one another and there’s often backward compatibility.

Don’t be afraid to attempt new issues. And don’t decide your previous work primarily based on what at the moment. You probably did one of the best you might given your talent degree, the constraints of the venture, and the applied sciences you had out there. You can begin to include newer methods proper alongside the previous ones. Simply construct web sites!

[ad_2]