It’s exhausting to maintain up with the ever-changing developments of the style world. What’s “in” one minute is commonly out of fashion the subsequent season, probably inflicting you to re-evaluate your wardrobe.
Staying present with the most recent style types could be wasteful and costly, although. Roughly 92 million tons of textile waste are produced yearly, together with the garments we discard once they exit of fashion or now not match. However what if we may merely reassemble our garments into no matter outfits we needed, adapting to developments and the methods our our bodies change?
A group of researchers at MIT’s Pc Science and Synthetic Intelligence Laboratory (CSAIL) and Adobe are trying to deliver eco-friendly, versatile clothes to life. Their new “Refashion” software program system breaks down style design into modules — basically, smaller constructing blocks — by permitting customers to attract, plan, and visualize every component of a clothes merchandise. The instrument turns style concepts right into a blueprint that outlines how one can assemble every part into reconfigurable clothes, equivalent to a pair of pants that may be reworked right into a gown.
With Refashion, customers merely draw shapes and place them collectively to develop a top level view for adaptable style items. It’s a visible diagram that exhibits how one can minimize clothes, offering a simple strategy to design issues like a shirt with an attachable hood for wet days. One may additionally create a skirt that may then be reconfigured right into a gown for a proper dinner, or maternity put on that matches throughout completely different phases of being pregnant.
“We needed to create clothes that take into account reuse from the beginning,” says Rebecca Lin, MIT Division of Electrical Engineering and Pc Science (EECS) PhD pupil, CSAIL and Media Lab researcher, and lead writer on a paper presenting the undertaking. “Most garments you purchase as we speak are static, and are discarded whenever you now not need them. Refashion as an alternative makes probably the most of our clothes by serving to us design objects that may be simply resized, repaired, or restyled into completely different outfits.”
Modules à la mode
The researchers carried out a preliminary person examine the place each designers and novices explored Refashion and had been in a position to create garment prototypes. Individuals assembled items equivalent to an uneven high that could possibly be prolonged right into a jumpsuit, or remade into a proper gown, typically inside half-hour. These outcomes counsel that Refashion has the potential to make prototyping clothes extra approachable and environment friendly. However what options would possibly contribute to this ease of use?
Its interface first presents a easy grid in its “Sample Editor” mode, the place customers can join dots to stipulate the boundaries of a clothes merchandise. It’s basically drawing rectangular panels and specifying how completely different modules will join to one another.
Customers can customise the form of every part, create a straight design for clothes (which is perhaps helpful for much less form-fitting objects, like chinos) or maybe tinkering with considered one of Refashion’s templates. A person can edit pre-designed blueprints for issues like a T-shirt, fitted shirt, or trousers.
One other, extra artistic route is to alter the design of particular person modules. One can select the “pleat” characteristic to fold a garment over itself, just like an accordion, for starters. It’s a helpful strategy to design one thing like a maxi gown. The “collect” choice provides an artsy flourish, the place a garment is crumpled collectively to create puffy skirts or sleeves. A person would possibly even go along with the “dart” module, which removes a triangular piece from the material. It permits for shaping a garment on the waist (maybe for a pencil skirt) or tailor to the higher physique (fitted shirts, as an illustration).
Whereas it might sound that every of those elements must be sewn collectively, Refashion allows customers to attach clothes by extra versatile, environment friendly means. Edges could be seamed collectively through double-sided connectors equivalent to steel snaps (just like the buttons used to shut a denim jacket) or Velcro dots. A person may additionally fasten them in pins known as brads, which have a pointed aspect that they stick by a gap and cut up into two “legs” to connect to a different floor; it’s a useful strategy to safe, say, an image on a poster board. Each connective strategies make it straightforward to reconfigure modules, ought to they be broken or a “match examine” requires a brand new look.
As a person designs their clothes piece, the system routinely creates a simplified diagram of how it may be assembled. The sample is split into numbered blocks, which is dragged onto completely different elements of a 2D model to specify the place of every part. The person can then simulate how their sustainable clothes will look on 3D fashions of a variety of physique varieties (one also can add a mannequin).
Lastly, a digital blueprint for sustainable clothes can prolong, shorten, or mix with different items. Due to Refashion, a brand new piece could possibly be emblematic of a possible shift in style: As a substitute of shopping for new garments each time we wish a brand new outfit, we will merely reconfigure current ones. Yesterday’s scarf could possibly be as we speak’s hat, and as we speak’s T-shirt could possibly be tomorrow’s jacket.
“Rebecca’s work is at an thrilling intersection between computation and artwork, craft, and design,” says MIT EECS professor and CSAIL principal investigator Erik Demaine, who advises Lin. “I’m excited to see how Refashion could make customized style design accessible to the wearer, whereas additionally making garments extra reusable and sustainable.”
Fixed change
Whereas Refashion presents a greener imaginative and prescient for the way forward for style, the researchers be aware that they’re actively enhancing the system. They intend to revise the interface to help extra sturdy objects, stepping past customary prototyping materials. Refashion could quickly help different modules, like curved panels, as properly. The CSAIL-Adobe group may additionally consider whether or not their system can use as few supplies as doable to reduce waste, and whether or not it may assist “remix” outdated store-bought outfits.
Lin additionally plans to develop new computational instruments that assist designers create distinctive, customized outfits utilizing colours and textures. She’s exploring how one can design clothes by patchwork — basically, slicing out small items from supplies like ornamental materials, recycled denim, and crochet blocks and assembling them into a bigger merchandise.
“This can be a nice instance of how computer-aided design may also be key in supporting extra sustainable practices within the style trade,” says Adrien Bousseau, a senior researcher at Inria Centre at Université Côte d’Azur who wasn’t concerned within the paper. “By selling garment alteration from the bottom up, they developed a novel design interface and accompanying optimization algorithm that helps designers create clothes that may bear an extended lifetime by reconfiguration. Whereas sustainability typically imposes further constraints on industrial manufacturing, I’m assured that analysis just like the one by Lin and her colleagues will empower designers in innovating regardless of these constraints.”
Lin wrote the paper with Adobe Analysis scientists Michal Lukáč and Mackenzie Leake, who’s the paper’s senior writer and a former CSAIL postdoc. Their work was supported, partially, by the MIT Morningside Academy for Design, an MIT MAKE Design-2-Making Mini-Grant, and the Pure Sciences and Engineering Analysis Council of Canada. The researchers introduced their work just lately on the ACM Symposium on Person Interface Software program and Expertise.
Furthermore, many organizations already function in multicloud or hybrid cloud environments, which makes reaching full independence logistically and operationally advanced. Even when an organization transitions some workloads to sovereign clouds, it’s possible {that a} multicloud technique will nonetheless retain particular dependencies on US platforms. Such a technique can cut back geopolitical and regulatory dangers, nevertheless it introduces larger operational complexity, which prices extra and requires superior cloud administration experience.
Forrester’s evaluation accurately highlights these obstacles, nevertheless it misses the ambition and capability already current in Europe’s rising sovereign cloud ecosystem. Whereas change could also be gradual and piecemeal for many industries, the mandatory instruments and platforms can be found at the moment. Finally, it’s as much as enterprises to determine whether or not they transfer ahead.
How the EU can acquire independence
Addressing the technical, monetary, and operational challenges of decreasing dependence on US-based cloud suppliers requires a structured strategy, clear targets, and sensible steps. First, EU organizations have to give attention to detailed planning and useful resource budgeting. Cloud sovereignty comes at a price, and companies should allocate sources rigorously to make sure every step of the migration course of is financially viable. Understanding the full price of possession is important. This contains preliminary migration prices, personnel coaching, long-term operational bills, and investments in expertise improvement for managing new techniques.
What are the important thing steps to construct an AI in Python?
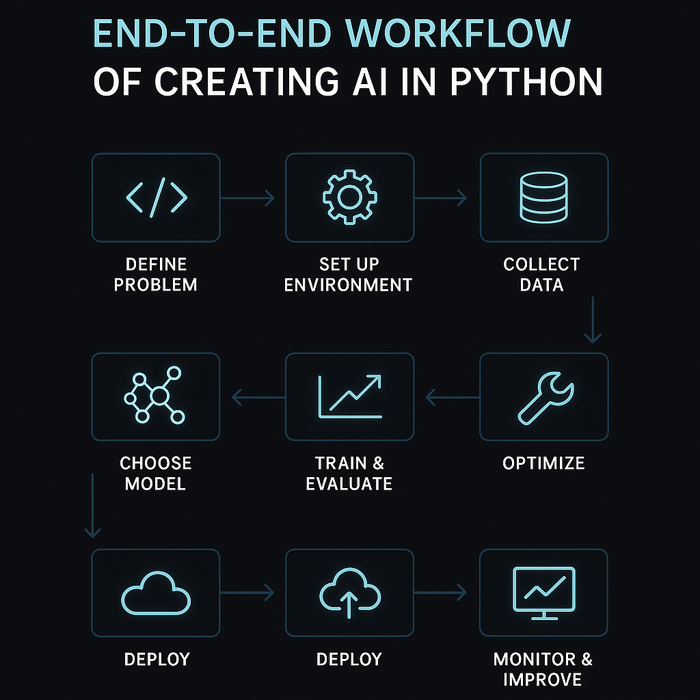
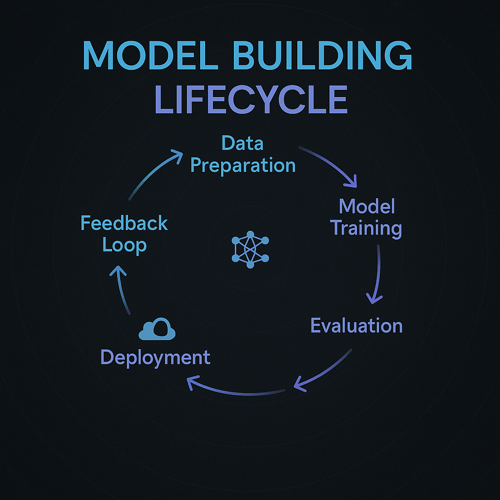
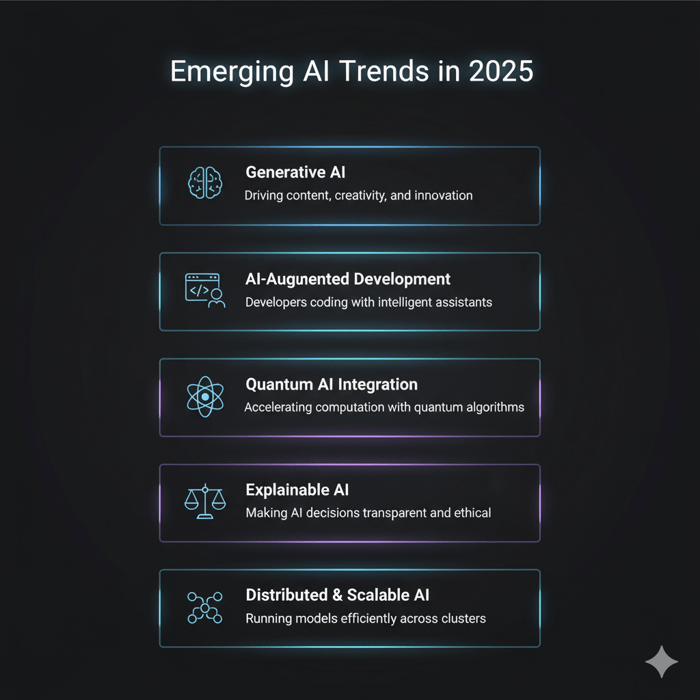
Any AI venture includes understanding the distinction between synthetic intelligence and machine studying, organising a strong atmosphere with the suitable libraries, gathering and making ready information, choosing the proper fashions, coaching and testing them, tuning hyperparameters, and eventually placing the answer into use in the actual world. Your initiatives will all the time be on the leading edge in the event you use moral and explainable AI and regulate rising applied sciences like generative AI, quantum integration, and AI‑augmented growth.
Why Is Python Nonetheless the Finest Language for AI?
Python is the hottest language for AI growth as a result of it’s versatile, has an enormous ecosystem of AI libraries, and options easy-to-read syntax. Python makes it simple to modify between duties, whether or not you are constructing a easy chatbot or a production-ready deep studying system. Individuals in command of AI usually talk about how Python accelerates growth and encourages experimentation—Andrew Ng continuously talks about fast prototyping, and Python’s use of Jupyter Notebooks and prebuilt libraries illustrates this properly.
When Python is used with methods like Clarifai, its function turns into much more necessary within the realm of readability and pace. Clarifai not solely supplies mannequin inference companies, however it additionally makes it simpler to handle difficult pipelines, which makes AI growth go extra easily. This put up offers you a full plan for making AI in Python, from the bottom as much as deployment, with helpful recommendation, new concepts, and actual‑world examples.
What Are AI, ML, and DL? Getting the Fundamentals Down
The primary aim of AI is to make machines assume and see like individuals do. Machine studying learns patterns from information with out being instructed to take action, whereas deep studying makes use of neural networks with quite a few layers to study difficult correlations by itself, very similar to the human mind. Figuring out the variations between these approaches helps you decide the perfect one to your process: customary algorithms could carry out properly with structured information, whereas deep studying works greatest with photos and pure language.
Skilled Recommendation
Andrew Ng says that the important thing to good AI is higher information, not simply greater fashions. This highlights the significance of specializing in each information high quality and mannequin design.
Fei‑Fei Li, a pioneer in pc imaginative and prescient, notes that deep studying works as a result of it will possibly study hierarchical representations—vital for duties like object recognition or language interpretation.
How Can I Get Began with Python AI?
What Libraries and Instruments Do I Want to start out?
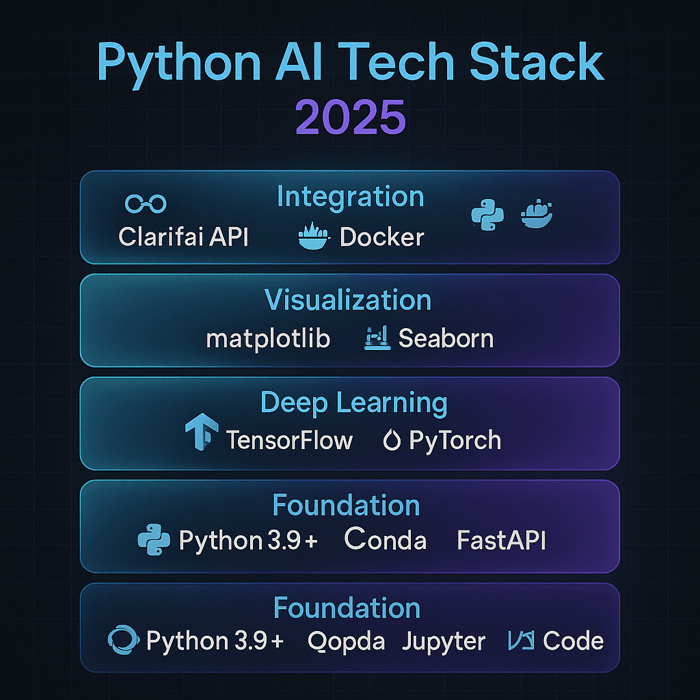
The very first thing it’s essential to do is set up Python (model 3.9 or increased), create a digital atmosphere, and select an IDE like Jupyter Pocket book or VS Code. NumPy, pandas, scikit‑study, TensorFlow or PyTorch, and visualization libraries like matplotlib and Seaborn are among the most necessary packages. Clarifai’s mannequin inference API works completely with Python and allows you to use pre-trained fashions for footage, textual content, and video.
Setting Up the Primary Surroundings
Set up important packages with pip:
pip set up numpy pandas scikit-learn tensorflow matplotlib seaborn
How Do I Choose the suitable Improvement Surroundings?
To eradicate dependency issues and guarantee reproducibility, use digital environments like Conda. Jupyter Notebooks are nice for exploring and explaining, whereas VS Code’s plugins assist with debugging and code completion. Clarifai’s native runners make it simple to check fashions offline with little setup, which is nice for fast prototyping.
Skilled Recommendation
Wes McKinney, the creator of pandas, says that constant information processing instruments are what make machine studying workflows efficient. Utilizing pandas ensures the pipeline from ingestion to mannequin coaching flows easily.
Rachel Thomas, co-founder of quick.ai, emphasizes the significance of easy-to-use instruments and recommends interactive environments that encourage experimentation—precisely what Jupyter Notebooks present.
How Ought to I Put together and Clear My Information
Why Is Information Preparation So Essential?
It doesn’t matter how superior your mannequin is; unhealthy information yields unhealthy outcomes. Information preparation means gathering the suitable information, cleansing it by coping with lacking values and outliers, and guaranteeing the courses are balanced. Tokenization and lemmatization convert textual content into machine-readable codecs, whereas picture duties usually want normalization and augmentation to extend variety.
The place Can I Discover High quality Datasets?
Sources like Kaggle, the UCI Machine Studying Repository, and Google Dataset Search present wealthy datasets. Clarifai additionally gives datasets designed for coaching and testing fashions. At all times test the licensing to make sure information is used appropriately.
How Can I Engineer Options Successfully?
Use pandas to reshape tabular information and scikit‑study’s preprocessing instruments to scale and encode options. NLTK or spaCy handles textual content normalization, whereas TensorFlow’s ImageDataGenerator simplifies picture augmentation.
Skilled Recommendation
Cassie Kozyrkov, Google’s principal determination scientist, observes that information high quality is the brand new code high quality. Spending time cleansing and analyzing information usually yields greater beneficial properties than tweaking mannequin parameters.
Jerome Friedman, co-author of The Components of Statistical Studying, says that function engineering is each an artwork and a science—area data is essential to discovering helpful patterns.
How Can I Choose the Finest Mannequin for My Drawback?
What mannequin sorts exist for AI in Python?
For structured information, you should use linear regression, logistic regression, determination timber, random forests, and help vector machines (SVMs). Deep studying fashions resembling convolutional neural networks (CNNs) for photos, recurrent neural networks (RNNs) for sequences, and transformers deal with unstructured information successfully. Generative fashions like GANs and VAEs are perfect for creating artificial textual content or graphics.
How Can I construct an easy AI Chatbot?
A rule-based chatbot is a basic first venture:
Arrange greetings, farewells, and a vocabulary of key phrases linked to responses.
Use a whereas loop to parse person enter and choose matching responses.
Randomly select a goodbye phrase when the person ends the session.
Though easy, this venture teaches person interplay and move management.
How Can I Construct a Generative AI Mannequin?
A contemporary venture includes making a Generative Adversarial Community (GAN) or an RNN-based textual content generator. The steps embrace:
Arrange TensorFlow/Keras, NumPy, and matplotlib.
Put together and increase the dataset (for instance, utilizing MNIST).
Outline the structure: create a generator and discriminator, or an RNN with consideration.
Practice the mannequin utilizing the suitable loss features and optimizers (resembling Adam), and make use of methods to forestall overfitting.
Consider utilizing metrics like Inception Rating or FID.
Generate new content material and refine primarily based on suggestions.
Clarifai’s mannequin inference and compute orchestration companies deal with intensive computation, making it simpler to coach and deploy fashions at scale.
Skilled Opinions
Ian Goodfellow, creator of GANs, advises specializing in stability throughout coaching, since GANs may be difficult to tune. This includes cautious design of loss features and hyperparameters.
Yoshua Bengio highlights that consideration mechanisms improve sequence-to-sequence fashions by letting them deal with probably the most related elements of the enter, which improves the standard of generated textual content.
How Do I Practice and Take a look at My Fashions?
What Does the Coaching Course of Contain?
Coaching means feeding enter information into the mannequin, computing a loss, after which updating the parameters utilizing backpropagation and gradient descent. Repeat this over a number of epochs till the mannequin converges. Monitoring is essential: use validation units to look at for overfitting and apply dropout to take care of generalization.
What Is the Finest Method to Consider My fashions?
For classification, consider with accuracy, precision, recall, and F1-score.
For regression, use imply squared error (MSE) and root imply squared error (RMSE).
Generative fashions require specialised metrics like Inception Rating and FID.
Code-generation fashions ought to be assessed by purposeful correctness, cyclomatic complexity, and maintainability indices.
Clarifai’s native runners simplify analysis by offering instruments to calculate these metrics and visualize ends in actual time.
Skilled Opinions
Sebastian Raschka, writer of Python Machine Studying, emphasizes: all the time preserve a validation set separate out of your coaching information. This helps keep away from overfitting and supplies extra real looking efficiency estimates.
David H. Hubel, Nobel Prize-winning neuroscientist, reminded us that understanding the human visible system conjures up higher analysis metrics—past easy accuracy—for pc imaginative and prescient fashions.
How Do I Optimize and Tune My Fashions?
Why Ought to You Tune Hyperparameters?
Hyperparameters—like studying fee, batch dimension, variety of layers, and activation features—have a big effect on mannequin efficiency. Methods resembling grid search, random search, and Bayesian optimization assist discover optimum combos. Python’s scikit‑study consists of GridSearchCV, and frameworks like Optuna or Clarifai’s orchestration instruments automate this course of.
What About Automated Machine Studying (AutoML)?
AutoML platforms like PyCaret and AutoKeras select and fine-tune fashions routinely. These instruments democratize AI by dealing with algorithm choice and hyperparameter optimization, making fast prototyping simpler.
Skilled Recommendation
James Bergstra, an early advocate of random search, demonstrated that it usually outperforms exhaustive grid search by exploring a wider vary of settings.
Clarifai’s product group suggests utilizing Clarifai’s orchestration platform for large-scale experiments, because it streamlines hyperparameter sweeps throughout a number of compute nodes.
How Do I Deploy My AI Mannequin?
What Are the Finest Methods to Deploy?
Relying in your wants:
Flask, Django, or FastAPI can serve fashions through REST APIs.
Docker containers guarantee constant deployment throughout environments; pair them with Kubernetes for scalability.
Cloud platforms like AWS SageMaker, Google AI Platform, and Azure ML provide infrastructure for scaled manufacturing use.
Clarifai’s compute orchestration simplifies deploying massive fashions, whether or not on-premises or within the cloud.
How Do I Combine Superior AI Brokers and LLMs?
With the rise of LLM-based brokers, frameworks like LangChain and LlamaIndex enable Python purposes to leverage pre-trained language fashions for chatbots, summarization, and content material creation. Clarifai’s platform can join customized pipelines with these frameworks and run inference at scale.
Insights from Consultants
Jeff Dean, head of Google AI, notes that inferencing effectivity is vital for manufacturing fashions and urges builders to contemplate deployment price and latency.
Chris Mattmann, an open-source advocate, stresses that containerization and orchestration (Docker and Kubernetes) are important for reproducible AI workflows.
Why Do I Have to Perceive Explainable AI and Ethics?
What Does “Explainable AI” Imply?
Explainable AI (XAI) goals to supply human-understandable causes for mannequin predictions. Instruments like LIME and SHAP present how every function contributes to a single prediction, which builds belief and aids debugging.
Why Are Ethics Essential in AI?
If information isn’t fastidiously curated, AI methods can inadvertently exacerbate biases or violate privateness. Frameworks like IBM AI Equity 360 and strategies like AI TRiSM emphasize equity, transparency, and robustness. Clarifai’s platform assists by providing auditing and mannequin governance instruments.
Recommendation from Consultants
Timnit Gebru, co-founder of the Distributed AI Analysis Institute, stresses that bias prevention have to be prioritized early in growth.
Ilya Sutskever, CTO of OpenAI, notes that interpretability will decide public belief and regulators’ consolation with AI methods.
What New Traits Ought to I Hold an Eye On?
How Is Generative AI Altering?
Generative fashions like GANs and VAEs now energy purposes in drug discovery, music, artwork, and textual content era. As these platforms grow to be extra accessible, each hobbyists and enterprises can take benefit. Clarifai’s generative AI applied sciences assist broaden these capabilities with minimal extra work.
What Does AI-Augmented Improvement Imply?
AI-augmented growth makes use of instruments like GitHub Copilot and Clarifai’s code help to hurry up coding and debugging, boosting productiveness. Builders will more and more depend on AI for writing code, assessments, and even designing structure.
What Function Does Python Play in Quantum Computing?
Python libraries resembling Qiskit and Cirq enable builders to experiment with quantum algorithms. Whereas quantum machine studying remains to be younger, it guarantees important speedups in optimization and information processing.
What About Scalable AI and Democratized Instruments?
Libraries like Dask and PySpark allow distributed computation throughout clusters, whereas frameworks resembling Horovod and TensorFlow Distributed facilitate multi‑GPU coaching. Clarifai’s compute orchestration integrates these instruments, enabling enterprise-level scaling with out heavy setup.
Insights from Consultants
Yann LeCun believes the way forward for AI lies in self-supervised studying and environment friendly coaching, requiring large-scale distributed methods.
Anima Anandkumar, NVIDIA’s Director of Machine Studying, advocates multi-node coaching for scaling deep studying and continuously highlights frameworks like Horovod.
What Do Case Research Reveal About Python AI?
How Nicely Do AI Code Mills Work?
A 2025 MDPI examine examined six AI code-generation fashions, together with GPT‑3.5, GPT‑4, and Claude. The analysis discovered appreciable discrepancies amongst fashions by way of syntax accuracy, purposeful correctness, and code complexity. This exhibits the significance of benchmarking a number of fashions earlier than adopting them in manufacturing.
What Are Finest Practices for Scalable AI Options?
A 2024 paper titled “Constructing Scalable AI Options with Python” emphasizes distributed machine studying, mannequin parallelism, and cloud-native deployment. Instruments like Dask, PySpark, Horovod, and cloud companies (AWS, Google Cloud, Azure) are essential for dealing with massive datasets and complicated fashions. Clarifai’s managed compute pipelines allow you to scale equally whereas abstracting infrastructure complexities.
Insights from Consultants
Researchers stress {that a} complete analysis of complexity and maintainability measures is essential for choosing the proper fashions.
In addition they observe that distributed computing is now necessary for large-scale AI—a key purpose Clarifai invests closely in cloud integration and orchestration.
FAQs About Constructing AI in Python
Q1: Do I must know plenty of math to make AI? It helps to know linear algebra and chance, however many Python libraries simplify the exhausting elements. Begin with simple initiatives and study extra math as you go.
Q2: How are TensorFlow and PyTorch completely different? TensorFlow is most well-liked in manufacturing contexts for deployment capabilities, whereas PyTorch is praised for its intuitive, Pythonic interface. Each help high-performance GPU coaching and have massive communities.
Q3: What can I do to hurry up coaching by myself pc? Use batch normalization, modify studying charges, and leverage GPU acceleration when accessible. Clarifai’s native runner can deal with heavy computation with out complicating your code.
This autumn: Do you have to use a pre-trained mannequin or develop one from scratch? Pre-trained fashions work greatest when your drawback is just like the info they had been skilled on. They take much less time and wish much less information. Practice from scratch for distinctive information or specialised duties.
Q5: How can I be certain that my mannequin is truthful? Use instruments like LIME and SHAP for interpretability and equity toolkits like IBM AI Equity 360 to seek out and repair biases. At all times look at your information sources and have selections for unintended bias.
Conclusion: What’s Subsequent in Python AI?
Constructing AI utilizing Python is a continually evolving journey that features studying fundamentals, organising a strong atmosphere, fastidiously making ready information, choosing and coaching applicable fashions, optimizing efficiency, and deploying options ethically and effectively. New developments—resembling generative AI, AI-augmented growth, quantum integration, and scalable distributed computing—guarantee Python stays central to AI innovation.
Clarifai’s compute orchestration, mannequin inference, and native runners can energy each step of this journey—from testing to manufacturing—permitting you to innovate with out worrying about infrastructure. Whether or not you’re constructing a small chatbot or enterprise-scale AI pipelines, the mixture of Python and Clarifai gives an unbeatable basis for achievement.
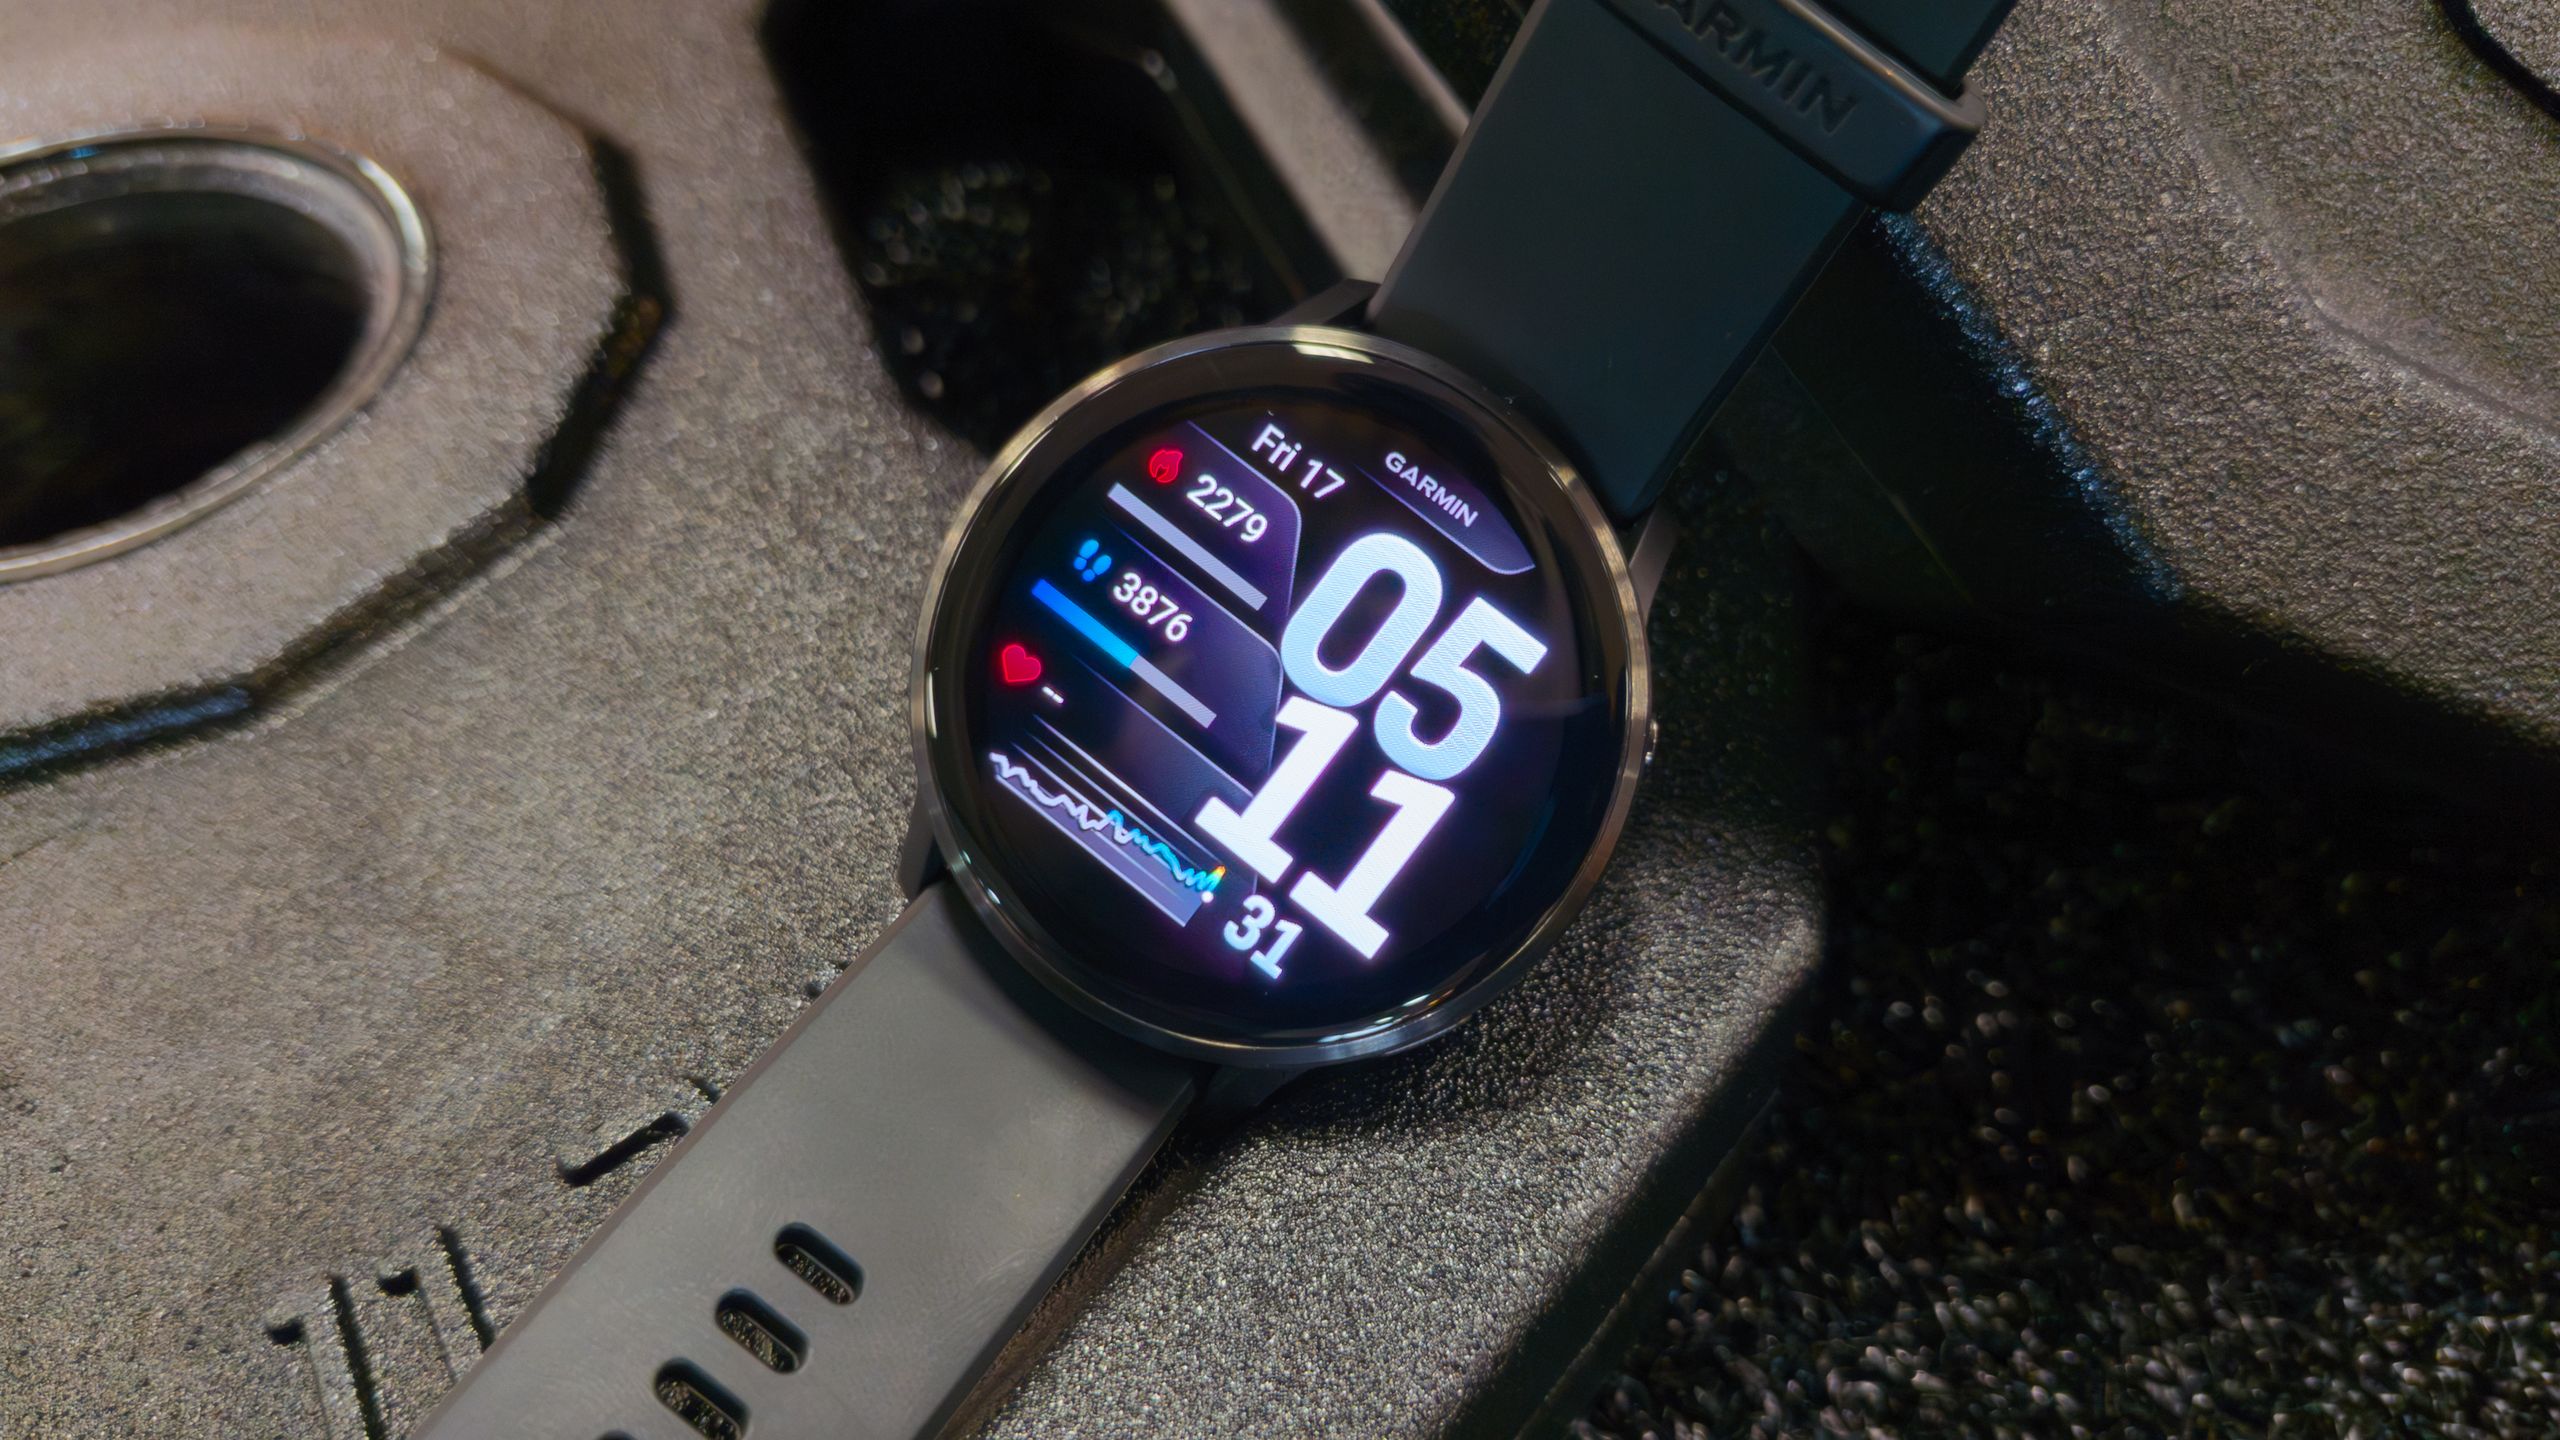
It has been two years for the reason that Venu 3 was launched, and the Venu 4 is following up with a brand new look and a few new options. Nonetheless, Garmin saved the Elevate sensor largely the identical, which is not essentially a nasty factor. As we have seen with the Venu X1, this sensor manages to be fairly correct.
I have been utilizing the Garmin Venu 4 for a few weeks as my principal exercise wearable. I’ve in contrast it to the Garmin Venu 3 to see how issues have modified (if in any respect), and towards the Pixel Watch 3 to see the way it stacks up towards my favourite smartwatch.
Health options I like
(Picture credit score: Derrek Lee / Android Central)
In contrast to the Forerunner sequence, the Garmin Venu 4 is extra of an all-rounder, which means there’s an general give attention to health, not simply operating. Due to this fact, Garmin has stuffed a bunch of health options into the watch, constructing on high of earlier fashions whereas making it preferrred for anybody to strap one on and simply go.
There are many helpful and new coaching options that can assist you get probably the most out of your exercises, however the one I pay most consideration to is Coaching Readiness. This takes into consideration numerous components, together with sleep, restoration time, and acute load, to find out how onerous it’s best to push your self in upcoming exercises. In idea, this can be a good option to keep away from overexerting your self, which might negatively have an effect on your efficiency.
(Picture credit score: Derrek Lee / Android Central)
The Venu 4 additionally helps extra teaching, which has allowed me to expertise a greater mixture of exercises to vary up my regular routine. This feels way more tailor-made and diverse, and followers of the Venu sequence ought to discover this convenient. Weightlifters equivalent to myself may even benefit from the watch’s capacity to rely reps and units extra precisely than even the Venu 3, which interprets to extra correct train and muscle categorization in post-workout stats.
You will additionally obtain extra diverse instructed exercises if you do not have a training plan enabled, which is a pleasant evolution of the Morning Report on the Vivoactive 6.
(Picture credit score: Derrek Lee / Android Central)
After every exercise, the Venu 4 supplies a abstract of the exercise, which incorporates metrics like coaching load, which gauges the depth of your exercise. You will additionally see a quantity that signifies your restoration time, which instantly impacts your coaching readiness. That is mainly your downtime between strenuous actions, together with sleep. It is Garmin’s means of telling you to relax.
Get the newest information from Android Central, your trusted companion on the earth of Android
Coronary heart charge
(Picture credit score: Derrek Lee / Android Central)
As coronary heart charge sensors, smartwatches are pretty dependable, however in the end, they’re imperfect. How properly the watch detects your coronary heart charge can depend upon a variety of issues, together with the match, placement, cleanliness, and even the kind of band. And whereas Garmin’s Elevate V5 coronary heart charge monitor on the Venu 4 has confirmed itself through the years, it isn’t infallible.
Generally, the Venu 4 seemed to be in keeping with expectations throughout my exercises. I have been figuring out with smartwatches lengthy sufficient to know roughly what the readings ought to be. Nonetheless, there are occasions after I’ll discover that the watch will take a second to truly get there, as you’ll be able to see within the charts under:
As you’ll be able to see within the first chart, the Venu 4 stayed properly under the Pixel Watch 3 throughout my run. I seen this in real-time, and could not decide why the readings have been so off, as each watches have been match snugly on my wrists. Luckily, the watch appeared to appropriate itself as soon as my tempo quickened, but it surely positively threw me off throughout my run.
Subsequent runs didn’t seem to have any main discrepancies, and each watches have been largely in keeping with one another. Nonetheless, issues bought a bit of bizarre when testing the Venu 4 towards the Venu 3 throughout my HIIT exercises.
Picture 1 of 3
(Picture credit score: Android Central)
(Picture credit score: Android Central)
(Picture credit score: Android Central)
HIIT exercises are typically extra diverse than runs, so my coronary heart charge was far and wide. Nonetheless, the Venu 4 skilled just a few brief but vital dips throughout a few of my exercises, which the Venu 3 didn’t. What makes it extra fascinating is that the 2 smartwatches use the identical Elevate sensor, so I am undecided the place these dips got here from, however happily, the Venu 4 was capable of appropriate itself a lot of the time.
For probably the most half, the Venu 4 coronary heart charge sensor will probably be on the mark, with just a few anticipated minor blips right here and there.
Step counter
(Picture credit score: Derrek Lee / Android Central)
I took the Garmin Venu 4 on two abridged variations of my typical strolling take a look at, strolling for a complete of two,000 steps on every event. I in contrast the step counts with the Google Pixel Watch 4, Venu 3, and the Oura Ring 4 whereas utilizing a guide step counter on my telephone to trace my steps. The outcomes have been pleasantly shocking, notably for the Venu fashions.
Swipe to scroll horizontally
Step take a look at
Check 1
Check 2
Garmin Venu 4
2,000
2,016
Garmin Venu 3
—
2,000
Google Pixel Watch 3
1,998
—
Oura Ring 4
1,935
1,944
As you’ll be able to see, on each events, the Venu 4 or Venu 3 hit precisely 2,000 steps, which is kind of spectacular. The Venu 4 was a giant hit on the second take a look at, however not by a substantial quantity. In the meantime, the Pixel Watch 3 got here shut throughout its take a look at, because it was off by simply two. The Oura Ring 4, in the meantime, was off by an analogous quantity on every event, counting 65 and 56 steps fewer than anticipated.
(Picture credit score: Android Central)
Whereas I have not had a chance to place the Venu 4 via its paces to actually take a look at the brand new dual-frequency GPS, the step take a look at exhibits that even throughout a brief stroll, the Venu 4 (blue) seems typically extra secure than the Venu 3 (orange), as seen within the map above.
Vertict
(Picture credit score: Derrek Lee / Android Central)
Regardless of some hiccups, the Venu 4 appears like a well-rounded health companion, because of acquainted options and {hardware} in addition to newer options and insights. Whereas it could’ve been good to see an upgraded Elevate sensor, the Venu 4 proves that it nonetheless has some life in it but. And with new coaching options, customers ought to be capable of get extra out of their exercises to optimize their efficiency.
Pierre Fermat conjectured that the F(n) have been prime for all n, and they’re for n = 0, 1, 2, 3, and 4, however Leonard Euler factored F(5), exhibiting that it isn’t prime.
Tangent numbers
The nth tangent quantity is outlined by the Taylor collection for tangent:
One other approach to put it’s that the exponential producing operate for T(n) is tan(z).
Fermat primes and tangent numbers
Right here’s a exceptional connection between Fermat numbers and tangent numbers, found by Richard McIntosh as an undergraduate [1]:
F(n) is prime if and provided that F(n) doesn’t divide T(F(n) − 2).
That’s, the nth Fermat quantity is prime if and provided that it doesn’t divide the (F(n) − 2)th tangent quantity.
We might duplicate Euler’s evaluation that F(5) shouldn’t be prime by exhibiting that 4294967297 doesn’t divide the 4294967295th tangent quantity. That doesn’t sound very sensible, however it’s attention-grabbing.
Replace: To see simply how impractical the outcome on this put up could be for testing whether or not a Fermat quantity is prime, I discovered an asymptotic estimate of tangent numbers on OEIS, and estimated that the 4294967295th tangent quantity has about 80 billion digits.
[1] Richard McIntosh. A Obligatory and Ample Situation for the Primality of Fermat Numbers. The American Mathematical Month-to-month, Vol. 90, No. 2 (Feb., 1983), pp. 98–99
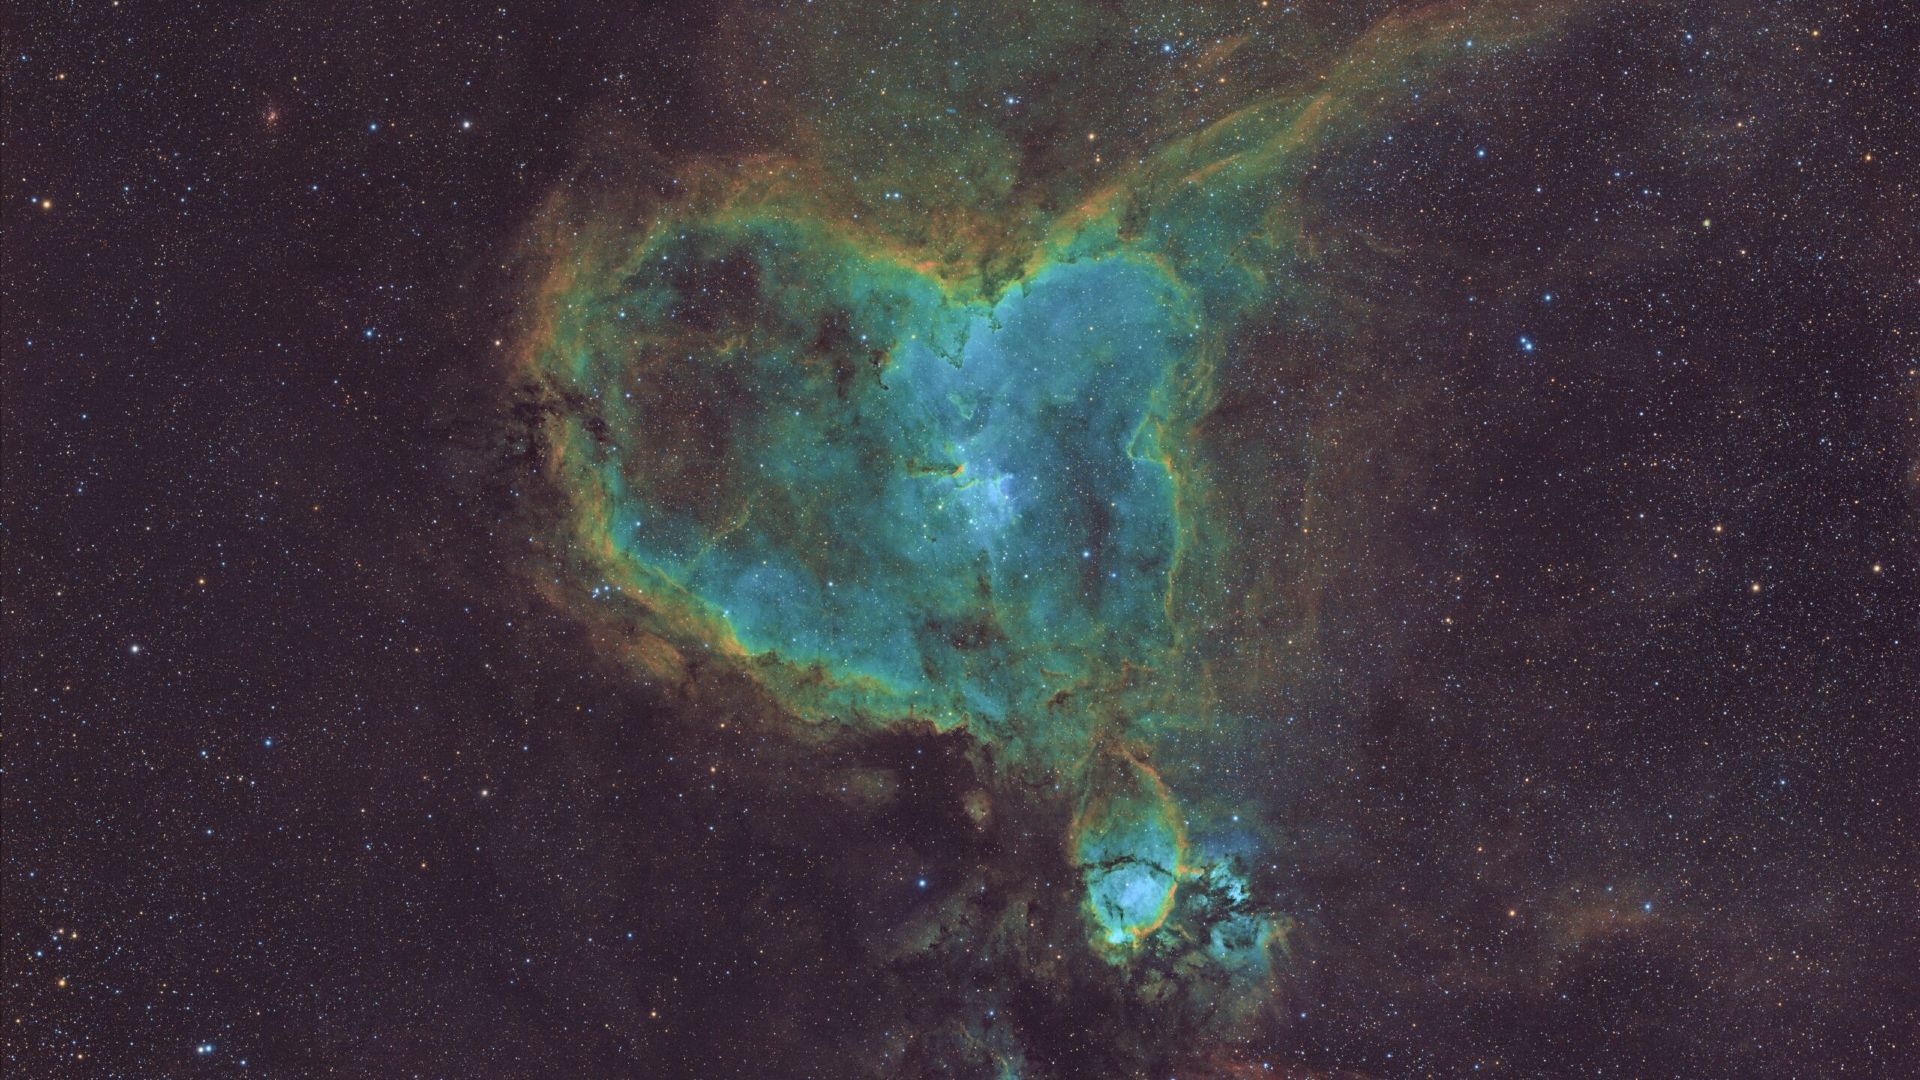
The Coronary heart Nebula (IC 1805) shines within the constellation Cassiopeia. (Picture credit score: Ronald Brecher)
Astrophotographer Ronald Brecher has captured a colourful view of the Coronary heart Nebula (IC 1805), which is positioned some 6,000 light-years from Earth within the Perseus spiral arm of the Milky Approach.
The Coronary heart Nebula is a colossal star-forming area named for its resemblance to a cartoonish illustration of the human coronary heart. The middle of the nebula performs host to a inhabitants of energetic younger stars which are busily sculpting dense pillars of mud with their radiation. It may be discovered simply 5 levels away from the brilliant star Segin within the constellation Cassiopeia — roughly the width of your three center fingers held at arm’s size — which will be discovered excessive above the northern horizon round midnight in October.
Hanging beneath the huge cosmic coronary heart is a knot of mud and fuel recognized informally because the Fishhead Nebula, because of its vaguely oval define and a darkish mud filament that provides it the looks of an aquatic creature.
Brecher collected gentle from the distant nebula scene from his residence in Guelph, Canada utilizing an astronomy digicam mounted on a Sky-Watcher Esprit 70 EDX refractor telescope over the course of over 40 hours in September earlier this 12 months.
The colourful scene was captured with the assistance of a set of astrophotography filters, every of which have been designed to seize particular wavelengths of sunshine that have been subsequently assigned particular person colours in the course of the publish processing section. The top result’s an impressive snapshot of deep area, created from particles of sunshine that had travelled 1000’s of years to succeed in their vacation spot.
Editor’s Be aware: If you want to share your astrophotography with Area.com’s readers, then please ship your photograph(s), feedback, and your identify and site to spacephotos@area.com.
Breaking area information, the newest updates on rocket launches, skywatching occasions and extra!
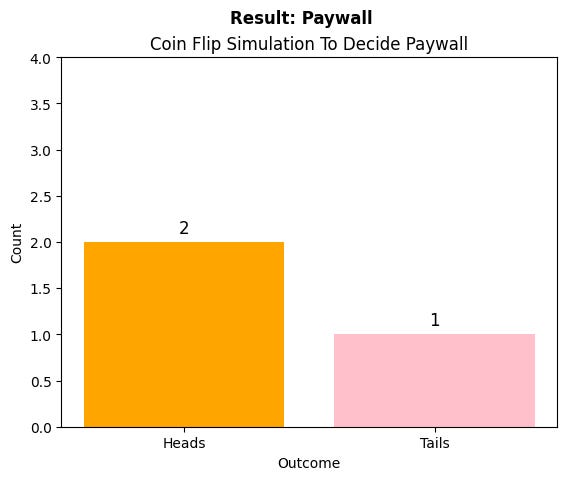
I’m going to be attempting to re-enter writing about econometrics. I’ve just a few papers I must work by means of intently, and it’s only a good time to maintain retooling extra typically. I additionally need to give my subscribing readers extra worth for being a subscriber, and due to this fact am simply going to return to my randomized paywalls. And immediately, I had Cosmos as soon as once more flip a coin 3 times to see if I’d be paywalling and certainly, immediately is a randomized paywall day!
However earlier than I do, I wished to inform you a bit of about what this put up is about. This put up goes to be half 1 in a few posts that exhibits the precise circumstances below which you’ll establish utilizing diff-in-diff each an unweighted causal impact and a inhabitants weighted causal impact. I’m going to point out you this formally utilizing one thing I’ve been engaged on. After which I’m going to point out you in a subsequent put up code and output from a simulation that illustrates it. However the punch line is that this:
simply because parallel traits holds with mixture knowledge doesn’t imply it can maintain with inhabitants weighted knowledge. The circumstances below which each maintain and never maintain is what this collection is about.
So with that, let’s go! Thanks once more for all of your help! Please take into account changing into a paying subscriber. Provide curves slope upwards and after a protracted hiatus of paywalling, I’m going to be going again to doing so and writing about econometrics, and new papers I’m investing time in, notably as I put together for my new programs subsequent spring at Harvard (together with a PhD course).
What’s NoSQL, and what are the very best NoSQL databases? These are the frequent questions that the majority corporations and builders often ask. These days, the necessities for NoSQL databases are rising as the normal relational databases should not sufficient to deal with the present necessities of the administration.
It’s as a result of now the businesses have tens of millions of consumers and their particulars. Dealing with this colossal knowledge is hard; therefore it requires NoSQL. These databases are extra agile and supply scalable options; additionally, they’re a more sensible choice to deal with the huge knowledge of the shoppers and discover essential insights.
Thus, on this article, we’ll discover out the very best NoSQL databases with the assistance of our checklist.
What’s NoSQL Database?
If you happen to belong to the information science subject, you will have heard that NoSQL databases are non-relational databases. This may occasionally sound unclear, and it may turn into difficult to know if you’re only a brisker on this subject.
The NoSQL is the brief illustration of the Not Solely SQL which will additionally imply it may deal with relational databases. On this database, the information doesn’t break up into many different tables. It retains it associated in any method to make a single knowledge construction. Thus, when there’s huge knowledge, the person doesn’t should expertise the person lag. Additionally they don’t want to rent pricey professionals who use important strategies to current these knowledge within the easiest type. However for this, the corporate wants to decide on the very best NoSQL database, and professionals additionally have to study the identical.
8 Finest NoSQL Databases in 2024
1. Apache HBase
Apache HBase is an open-source database, and it’s a sort of Hadoop database. Its characteristic is that it may simply learn and write the huge knowledge that an organization has saved. It’s designed to deal with the billions of rows and columns of the corporate’s knowledge. This database is predicated on a giant desk: a distribution warehouse or knowledge assortment system developed to construction the information the corporate receives.
That is in our checklist of finest NoSQL databases as a result of it has the performance of scalability, constant studying of information, and plenty of extra.
2. MongoDB
MongoDB can be a terrific database primarily based on general-purpose distribution and primarily developed for the builders who use the database for the cloud. It shops the information in paperwork reminiscent of JSON. It’s a a lot highly effective and environment friendly database out there available in the market. MongoDB helps varied strategies and strategies to investigate and interpret the information. You possibly can search the graphs, textual content, and any geographical search. If you happen to use it, then you definitely additionally get an added benefit of high-level safety of SSL, encryption, and firewalls. Thus it can be the very best NoSQL database to contemplate for what you are promoting and studying goal.
3. Apache CouchDB
If you’re searching for a database that gives easy accessibility and storage options, you may take into account Apache CouchDB. It’s a single node database, and you may as well get it without cost as it’s open supply. You may as well scale it while you assume it matches, and it may retailer your knowledge within the cluster of nodes and a number of the out there servers. It has JSON knowledge format assist and an HTTP protocol that may combine with the HTTP proxy of the servers. It’s also a safe database you can select from as a result of it’s designed contemplating the crash-resistant characteristic.
4. Apache Cassandra
Apache Cassandra is one other lovely open supply and NoSQL database out there at present. It was initially developed by Fb but additionally bought a promotion from Google. This database is obtainable virtually in all places and likewise can scale as per the necessities of the customers. It will possibly easily deal with the hundreds of concurrent knowledge requests each second and likewise deal with the petabyte info or knowledge. Together with Fb, Netflix, Coursera, and Instagram, greater than 400 corporations use Apache Cassandra NoSQL database.
5. OrientDB
It’s also a great and open supply NoSQL database that helps varied fashions like a graph, doc, and worth mannequin. This database is written within the programming language Java. It will possibly present the connection between managed information and the graph. It’s a dependable and safe database appropriate for giant buyer base customers as properly. Furthermore, its graph version is able to visualizing and interacting with intensive knowledge.
6. RavenDB
RavenDB is a database that’s primarily based on the doc format and has options of NoSQL. You may as well use its ACID characteristic that ensures knowledge integrity. It’s a scalable database, and therefore in the event you assume your buyer base is getting enormous in tens of millions, you may scale it as properly. You possibly can set up it on permission and likewise use it within the cloud format with the cloud providers provided by Azure and Internet Providers of Amazon.
7. Neo4j
If you happen to had been looking for a NoSQL database that may deal with not solely the information. But additionally an actual relationship between them, then it’s the excellent database for you. With this database, you may retailer the information safely and re-access these in such a quick and inconvenient method. Each knowledge saved accommodates a singular pointer. On this database, you additionally get the characteristic of Cypher Queries that provides you a a lot sooner expertise.
8. Hypertable
Hypertable can be a NoSQL and open supply database that’s scalable and might seem in virtually all relational DBs. It was primarily developed to resolve scalability, and it’s primarily based on the Google Massive Desk. This database was written within the C++ programming language, and you should utilize it in Mac OS and Linux. It’s appropriate for managing large knowledge and might use varied strategies to brief the out there knowledge. It may be a terrific alternative in the event you count on to get most effectivity and price effectivity from the database.
Conclusion
Thus, on this article, we realized about some finest NoSQL databases and people which are safe, extensively out there, extensively used, and open supply. Right here we mentioned the database, together with MongoDB, OrientDB, Apache HBase, and Apache Cassandra. So, in the event you like this checklist of finest NoSQL databases, remark down and point out the title of the NoSQL database that you simply assume we’ve got missed and that must be included.
Embedding-based retrieval, also referred to as dense retrieval, has turn out to be the go-to methodology for contemporary methods. Neural fashions map queries and paperwork to high-dimensional vectors (embeddings) and retrieve paperwork by nearest-neighbor similarity. Nevertheless, latest analysis reveals a stunning weak spot: single-vector embeddings have a basic capability restrict. Briefly, an embedding can solely characterize a sure variety of distinct related doc combos. When queries require a number of paperwork as solutions, dense retrievers begin to fail, even on quite simple duties. On this weblog, we’ll discover why this occurs and look at the alternate options that may overcome these limitations.
Single-Vector Embeddings And Their Use In Retrieval
In dense retrieval methods, a question is fed via a neural mannequin to provide a single vector. This mannequin is commonly a transformer or different language mannequin. The produced vector captures the that means of the textual content. For instance, paperwork about sports activities may have vectors close to one another. In the meantime, a question like “greatest trainers” can be near shoe-related docs. At search time, the system encodes the person’s question into its embedding and finds the closest doc.
Sometimes, the dot-product or cosine similarity returns the top-k related paperwork. This differs from older sparse strategies like BM25 that match key phrases. Embedding fashions are well-known for dealing with paraphrases and semantics. For instance, looking “canine footage” can discover “pet pictures” even when the phrases differ. These generalize properly to new information as a result of they leverage pre-trained language fashions.
These dense retrievers energy many functions like net search engines like google and yahoo, query answering methods, advice engines, and extra. Additionally they lengthen past plain textual content; multimodal embeddings map photographs or code to vectors, enabling cross-modal search.
Nevertheless, retrieval duties have turn out to be extra complicated, particularly duties that mix a number of ideas or require returning a number of paperwork. A single vector embedding will not be at all times in a position to deal with queries. This brings us to a basic mathematical constraint that limits what single-vector methods can obtain.
Theoretical Limits of Single Vector Embeddings
The difficulty is an easy geometric truth. A set-size vector area can solely understand a restricted variety of distinct rating outcomes. Think about you’ve got n paperwork and also you need to specify, for each question, which subset of ok paperwork ought to be the highest outcomes. Every question could be considered selecting some set of related docs. The embedding mannequin interprets every doc into a degree in ℝ^d. Additionally, every question turns into a degree in the identical area; the dot merchandise decide relevance.
It may be proven that the minimal dimension d required to characterize a given sample of query-document relevance completely is decided by the matrix rank (or extra particularly, the sign-rank) of the “relevance matrix,” indicating which docs are related to which queries.
The underside line is that, for any specific dimension d, there are some doable query-document relevance patterns {that a} d-dimensional embedding can’t characterize. In different phrases, irrespective of the way you practice or tune the mannequin, in the event you ask for a sufficiently massive variety of distinct combos of paperwork to be related collectively, a small vector can’t discriminate all these instances. In technical phrases, the variety of distinct top-k subsets of paperwork that may be produced by some question is upper-bounded by a perform of d. As soon as the variety of calls for made by the question exceeds the flexibility to make use of the embedding to retrieve, some combos can merely by no means be retrieved accurately.
This mathematical limitation explains why dense retrieval methods battle with complicated, multi-faceted queries that require understanding a number of unbiased ideas concurrently. Fortuitously, researchers have developed a number of architectural alternate options that may overcome these constraints.
Various Architectures: Past Single-Vector
Given these basic limitations of single-vector embeddings, a number of various approaches have emerged to handle extra complicated retrieval eventualities:
Cross-Encoders (Re-Rankers): These fashions take the question and every doc collectively and collectively rating them, often by feeding them as one sequence right into a transformer. As a result of cross-encoders immediately mannequin interactions between question and doc, they don’t seem to be restricted by a hard and fast embedding dimension. However these are computationally costly.
Multi-Vector Fashions: These broaden every doc into a number of vectors. For instance, ColBERT-style fashions index each token of a doc individually, so a question can match on any mixture of these vectors. This massively will increase the efficient representational capability. Since every doc is now a set of embeddings, the system can cowl many extra mixture patterns. The trade-offs listed here are index measurement and design complexity. Multi-vector fashions usually want a particular retrieval index like Most Similarity or MaxSim, and may use much more storage.
Sparse Fashions:Sparse strategies like BM25 characterize textual content in very high-dimensional areas, giving them sturdy capability to seize various relevance patterns. They excel when queries and paperwork share phrases, however their trade-off is heavy reliance on lexical overlap, making them weaker for semantic matching or reasoning past precise phrases.
Every various has trade-offs, so many methods use hybrids: embeddings for quick retrieval, cross-encoders for re-ranking, or sparse fashions for lexical protection. For complicated queries, single-vector embeddings alone usually fall brief, making multi-vector or reasoning-based strategies obligatory.
Conclusion
Whereas dense embeddings have revolutionized info retrieval with their semantic understanding capabilities, they don’t seem to be a common answer, as the basic geometric constraints of single-vector representations create actual limitations when coping with complicated, multi-faceted queries that require retrieving various combos of paperwork. Understanding these limitations is essential for constructing efficient retrieval methods, and fairly than viewing this as a failure of embedding-based strategies, we must always see it as a chance to design hybrid architectures that leverage the strengths of various approaches.
The way forward for retrieval lies not in any single methodology, however in clever combos of dense embeddings, sparse representations, multi-vector fashions, and cross-encoders that may deal with the complete spectrum of data wants as AI methods turn out to be extra refined and person queries extra complicated.
I’m a Information Science Trainee at Analytics Vidhya, passionately engaged on the event of superior AI options akin to Generative AI functions, Massive Language Fashions, and cutting-edge AI instruments that push the boundaries of expertise. My position additionally entails creating participating instructional content material for Analytics Vidhya’s YouTube channels, creating complete programs that cowl the complete spectrum of machine studying to generative AI, and authoring technical blogs that join foundational ideas with the newest improvements in AI. By means of this, I goal to contribute to constructing clever methods and share information that evokes and empowers the AI group.
Login to proceed studying and luxuriate in expert-curated content material.
As companies combine AI-powered machines into their operations, how people work together — or ought to work together — with these enterprise AI methods is revealing. Living proof: When OpenAI CEO Sam Altman, in response to a social media put up, remarked that saying “please” and “thanks” to ChatGPT most likely accounted for tens of tens of millions of “well-spent” {dollars} in electrical energy prices, it set off a spirited debate about whether or not generative AI customers ought to prioritize politeness or preserve computing energy.
The query of how customers have interaction with AI-powered platforms will doubtless turn out to be much more advanced as agentic AI — digital brokers able to taking motion independently towards a selected objective — turns into extra extensively obtainable and often used.
Firms more and more acknowledge that AI’s best enterprise worth is not going to come from automating rote duties, however from augmenting human considering to unravel advanced issues. Making this pivot is a enterprise crucial: Right this moment, about eight in 10 firms say they are not but seeing important bottom-line impression on the enterprise stage from generative AI, in line with McKinsey.
A lot has been written about how the rise of AI will enhance the worth of uniquely human abilities like inventive problem-solving or communication. Whereas that is true, it is solely the start of how abilities might want to morph and develop to match shifting employer expectations. As companies turn out to be extra AI-dependent, people is not going to solely must successfully collaborate with each other but in addition develop new abilities to collaborate with AI and finally handle it
Whether or not brainstorming inventive options, diagnosing patterns in messy information, or helping with strategic decision-making, AI will more and more turn out to be a collaborator, not only a device. Certain, getting there would require investing in AI, however extra importantly, the brand new paradigm would require investing within the people who will use it.
Abilities Middleware for AI and Human Collaboration
Middleware within the software program context is the connective tissue between totally different functions or platforms. It permits totally different platforms to “discuss” to one another, breaking down siloed data and creating new methods for present instruments to work collectively.
Bolstering human abilities to help collaboration has lengthy been a part of the training and improvement area, most frequently constructing on an present ability set. However relating to working with brokers as companions, all staff begin from sq. one. The labor pressure might want to construct a abilities middleware: the set of competencies that may facilitate AI’s integration into extra cognitively advanced duties.
This abilities middleware is not simply technical proficiency, like immediate engineering or understanding AI mannequin limitations (although these are vital). It additionally features a extra nuanced mixture of communication, judgment, moral reasoning, and process delegation. It requires understanding the strengths and weaknesses of varied agentic AI platforms to find out which ought to be deployed for particular duties or tasks. In essence, it is the identical sort of ability set that good managers use to coordinate high-performing groups — solely now, a few of these group members is perhaps AI brokers.
As AI brokers are more and more capable of independently guide conferences, seek for data, and comply with workflows to carry out extra advanced duties, the enterprise worth of AI will enhance. It can transfer from changing low-cognitive duties to extra advanced drawback fixing, however provided that people have the talents to make use of AI to reinforce their decision-making, in addition to the talents to successfully handle AI brokers.
Growing Abilities By means of Utilized Observe
So, how ought to firms put together their workforce for a world the place managers oversee not simply human groups, but in addition AI brokers?
Staff might want to develop a spread of latest abilities involving truth-finding and discernment. This consists of analyzing the outputs of each human-created and AI-developed analysis and information gathering workouts, akin to surveys, experiments or automated information assortment by AI methods. A part of this ability set entails recognizing hallucinations and algorithmic bias in AI outputs. Whereas AI will be capable to spot patterns in giant information units, people might want to decide which patterns are related and significant, separating legitimate correlations from random noise.
These will not be capabilities that may be mastered by instructor-led coaching or by a self-serve video library. Growing the middleware abilities might want to occur in context, by utilized follow.
The Case for Constructing AI Abilities By means of Volunteering
As I do know by my work on the Taproot Basis, a robust, but typically ignored avenue for gaining utilized follow is thru skills-based volunteering. By deploying their skilled experience to assist nonprofits and social enterprises, staff can acquire invaluable experience.
These tasks typically function in a constrained setting, restricted by each funds and time. The constraints could make AI an vital a part of a venture, giving volunteers an opportunity to develop new workflows or different options that benefit from AI to assist meet the nonprofit’s mission.
One other profit? Professional bono work presents utilized studying with real-world penalties and better stakes, which is nearer to the expertise of a job than project-based studying rooted in a hypothetical situation or a low-risk, low-reward bonus venture that is not core to the success of a company.