Home Blog Page 649

Dynamic use of id, conduct, & posture knowledge in SSE

0

[ad_1]

Cisco Safe Entry brings adaptive, contextual, identity-driven safety to each connection.

Safety used to start out with IP addresses and finish with firewall guidelines. That world is historical past.

At this time, IPs are disposable, units roam, and customers spin up from wherever on the planet. But many SSE options nonetheless deal with safety as primarily a community subject and don’t adequately embrace id as foundational.

Cisco’s altering that. Identification is the brand new perimeter, and with Cisco Identification Intelligence, Safe Entry brings steady, adaptive entry selections to each person, system, and utility.

Most SSE platforms assume a person is only a login. Authenticate as soon as, and also you’re good for the session. However id and identity-based dangers aren’t static. Belief ranges shift. Person conduct fluctuates. Posture modifications. Danger will increase. Attackers love to cover behind trusted credentials that haven’t been adjusted to mirror these dynamic modifications.

A non-identity-aware SSE can’t sustain as a result of it treats id as static versus a residing sign. It fails to correlate alerts from logins, behaviors, and units that deviate from typical patterns or pointers.

When id, conduct, and posture verifications keep static, attackers transfer sooner.

Cisco Safe Entry integrates with Cisco Identification Intelligence (CII) to make SSE identity-focused, risk-aware and self-adjusting. Insurance policies can allow entry selections to evolve dynamically primarily based on reside id knowledge, not guesswork.

In September of this yr, Cisco prolonged Safe Entry integration with CII past person belief ranges being seen within the Safe Entry dashboard. Insurance policies for ZTNA-protected non-public visitors can now outline when a person’s entry must be blocked or reauthenticated, primarily based on a person belief profile that adjusts dynamically with person conduct and posture. For instance, a coverage could outline that when a person’s belief degree is untrusted, entry must be blocked.

As a safeguard, directors have the choice to bypass blocking an untrusted person, for a selected period of time. Take into account an government who’s touring to a convention. She connects to an airport Wi-Fi community which she doesn’t usually use, with an IP handle that’s questionable, to log right into a delicate/important utility, and she or he not too long ago needed to reset her password.

These occasions mixed would make her seem “untrusted.” This feature permits an administrator to bypass the block, restore the chief’s entry, so she will be able to proceed her convention actions.

The administrator could allow, for all ZTNA-protected non-public visitors, a functionality that prompts reauthentication in accordance with person belief degree. At decrease person belief ranges, reauthentication will happen extra regularly. For instance, let’s say a person doing her work and has a belief degree of “favorable,” however over time, conduct or posture modifications trigger her belief degree to lower to “impartial.” This could immediate her reauthentication to happen extra regularly.

With this functionality, Safe Entry is more and more utilizing dynamic belief knowledge to counterpoint the group’s capability to implement least-privilege entry controls, heighten safety, and cut back danger.

Safe Entry’s Person and Entity Conduct Analytics (UEBA), additionally out there in September this yr, can detect anomalous file operations and unimaginable journey that might point out an insider risk. That risk could come from an precise insider with malicious intent or an outsider impersonating a sound person.

Directors can set Safe Entry insurance policies to detect when file uploads, downloads, or deletes exceed the extent deemed acceptable for a corporation. Moreover, Safe Entry can detect unimaginable journey, equivalent to a person making an attempt to login from San Jose and Paris at instances that aren’t potential, suggesting a stolen credential.

Directors now have clear visibility into these dangerous behaviors which will point out account compromise or malicious conduct through detailed UEBA studies and “prime dangerous customers” within the dashboard principal display.

We are going to proceed increasing UEBA such that sooner or later, the behavioral/analytics knowledge will inform automated motion (as chosen by the shopper and outlined in coverage) to extend safety safety.

Cisco Safe Entry steady system posture function, launched in September, permits organizations to detect any discount in endpoint posture compliance throughout a reside session and rapidly react by ending the session to keep away from undue danger. For instance, if the native firewall is disabled half manner via a session, Safe Entry will determine the motion and might routinely terminate the session.

This functionality supplies a fast response to any change that represents an elevated endpoint danger in the course of ongoing person actions.  The detection and adaptive response are captured and offered within the person’s exercise logs for directors.

At this time, Safe Entry is enriched with id intelligence, person and entity conduct analytics (UEBA), and steady system posture evaluation. Organizations can profit now from highly effective options—equivalent to insurance policies that alter entry primarily based on belief profiles, detection of anomalous person conduct, and automatic responses to dangerous system modifications—empowering them to implement granular, risk-aware safety at scale.

Trying forward, continued Cisco innovation will carry these capabilities nearer collectively, leading to ever-more refined adaptive entry controls that enhance the power to reply swiftly to threats, tailor entry insurance policies for evolving safety wants, and cut back enterprise danger. Our dedication to enriching Safe Entry functionality is unwavering, as is our dedication to assist our prospects stay a step (or two or three steps) forward in right now’s dynamic risk panorama.

Click on right here to study extra about Safe Entry and its many capabilities.


We’d love to listen to what you assume! Ask a query and keep related with Cisco Safety on social media.

Cisco Safety Social Media

LinkedIn
Fb
Instagram
X


[ad_2]

Establish Which Course of Is Blocking a File in Home windows

0

[ad_1]

Once you see the error “The method can’t entry the file as a result of it’s being utilized by one other course of,” you should utilize a number of built-in or free instruments to seek out out which course of is locking the file or folder.

Utilizing Useful resource Monitor

Useful resource Monitor is constructed into Home windows:

  • Press Win + R, kind resmon, and press Enter. This can open Useful resource Monitor.
  • Go to the CPU tab.
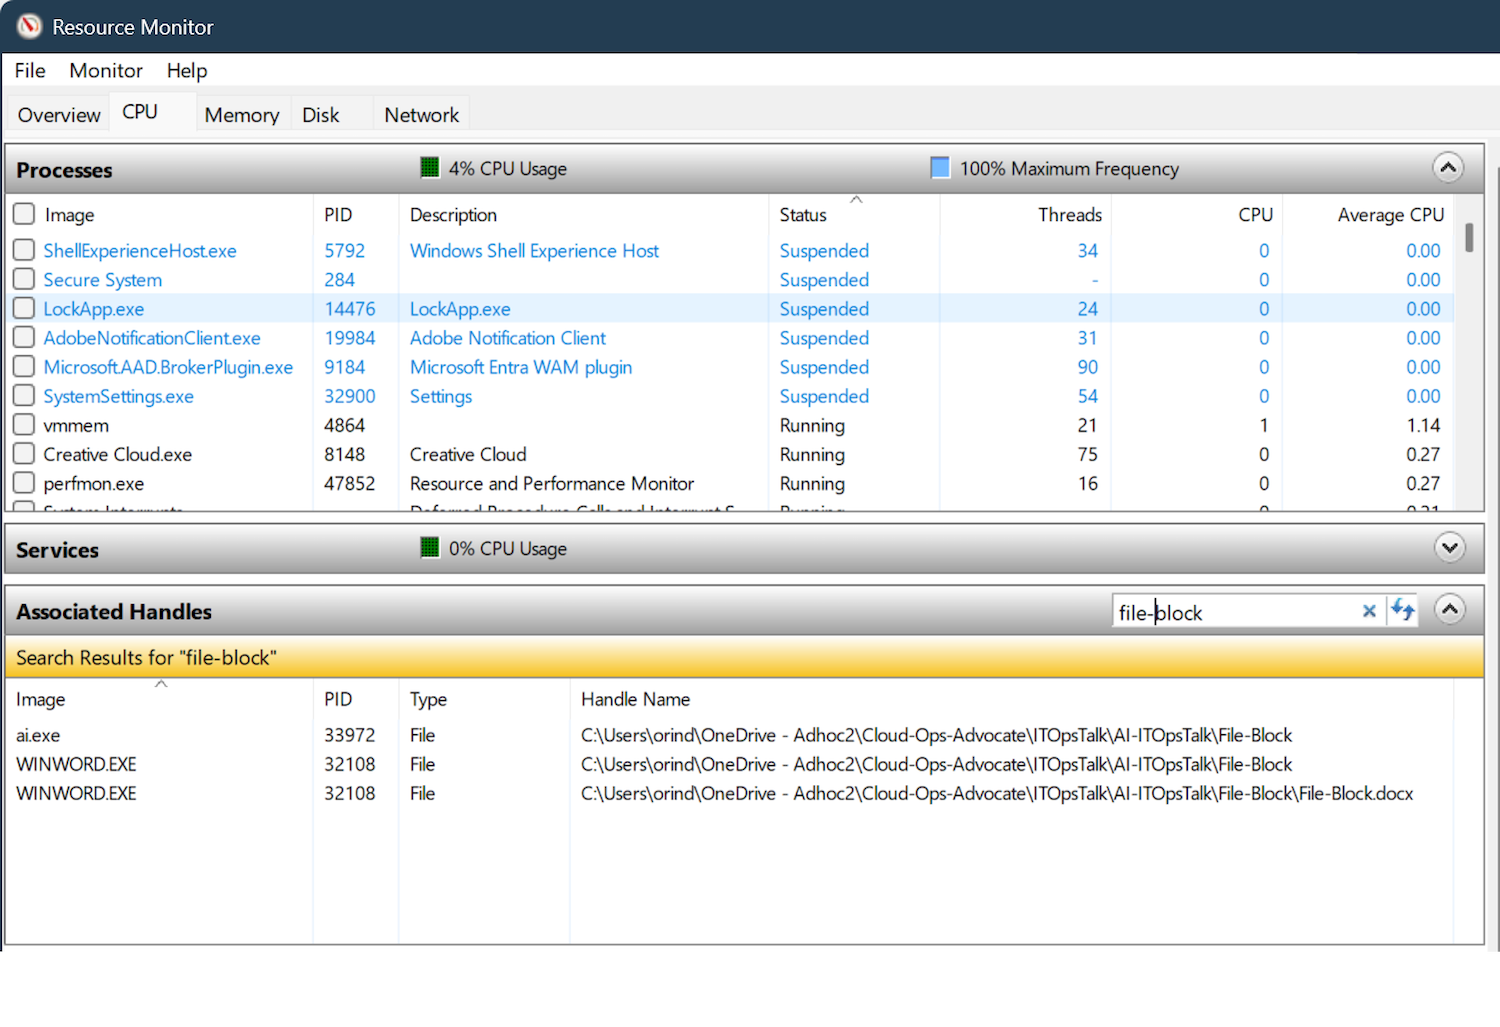
  • Within the Related Handles part, use the search field to enter a part of the file or folder identify.

  • The outcomes will present which processes are utilizing the file. Test the Picture and PID columns to determine the method.
  • You’ll be able to right-click the method and choose Finish Course of if essential (be cautious when ending processes).

Utilizing Course of Explorer

Course of Explorer is a free device from Microsoft Sysinternals:

  • Obtain and run Course of Explorer as administrator. You’ll be able to purchase Course of Explorer utilizing the next WingGet command:
Winget set up Microsoft.Sysinternals.ProcessExplorer
  • In Course of Explorer, Press Ctrl + F or go to Discover > Discover Deal with or DLL.
  • Kind a part of the file or folder identify and click on Search.
  • The device will checklist all processes at the moment utilizing the file. Click on an entry to focus on the method in the principle window.
  • You’ll be able to right-click the deal with and choose Shut Deal with to launch the file (use with warning).

Utilizing Command Line Instruments

  • openfiles: Run openfiles /question in Command Immediate (might require enabling with openfiles /native on and a restart). This reveals which information are open and by which course of. You’d must allow the native on choice earlier than the file received locked after all.
  • deal with.exe: Obtain from Sysinternals. You’ll be able to purchase Deal with.exe with the next WinGet command:
winget set up Microsoft.Sysinternals.Deal with
  • Run deal with.exe to checklist processes utilizing the file.


[ad_2]

Posit AI Weblog: Hugging Face Integrations

[ad_1]

We’re blissful to announce the primary releases of hfhub and tok are actually on CRAN.
hfhub is an R interface to Hugging Face Hub, permitting customers to obtain and cache recordsdata
from Hugging Face Hub whereas tok implements R bindings for the Hugging Face tokenizers
library.

Hugging Face quickly turned the platform to construct, share and collaborate on
deep studying functions and we hope these integrations will assist R customers to
get began utilizing Hugging Face instruments in addition to constructing novel functions.

We even have beforehand introduced the safetensors
bundle permitting to learn and write recordsdata within the safetensors format.

hfhub

hfhub is an R interface to the Hugging Face Hub. hfhub at the moment implements a single
performance: downloading recordsdata from Hub repositories. Mannequin Hub repositories are
primarily used to retailer pre-trained mannequin weights along with another metadata
essential to load the mannequin, such because the hyperparameters configurations and the
tokenizer vocabulary.

Downloaded recordsdata are ached utilizing the identical structure because the Python library, thus cached
recordsdata will be shared between the R and Python implementation, for simpler and faster
switching between languages.

We already use hfhub within the minhub bundle and
within the ‘GPT-2 from scratch with torch’ weblog publish to
obtain pre-trained weights from Hugging Face Hub.

You need to use hub_download() to obtain any file from a Hugging Face Hub repository
by specifying the repository id and the trail to file that you simply need to obtain.
If the file is already within the cache, then the perform returns the file path imediately,
in any other case the file is downloaded, cached after which the entry path is returned.

weblog publish ‘What are Massive Language Fashions? What are they not?’.

When utilizing a pre-trained mannequin (each for inference or for fantastic tuning) it’s very
necessary that you simply use the very same tokenization course of that has been used throughout
coaching, and the Hugging Face staff has performed a tremendous job ensuring that its algorithms
match the tokenization methods used most LLM’s.

tok offers R bindings to the 🤗 tokenizers library. The tokenizers library is itself
applied in Rust for efficiency and our bindings use the extendr undertaking
to assist interfacing with R. Utilizing tok we will tokenize textual content the very same manner most
NLP fashions do, making it simpler to load pre-trained fashions in R in addition to sharing
our fashions with the broader NLP neighborhood.

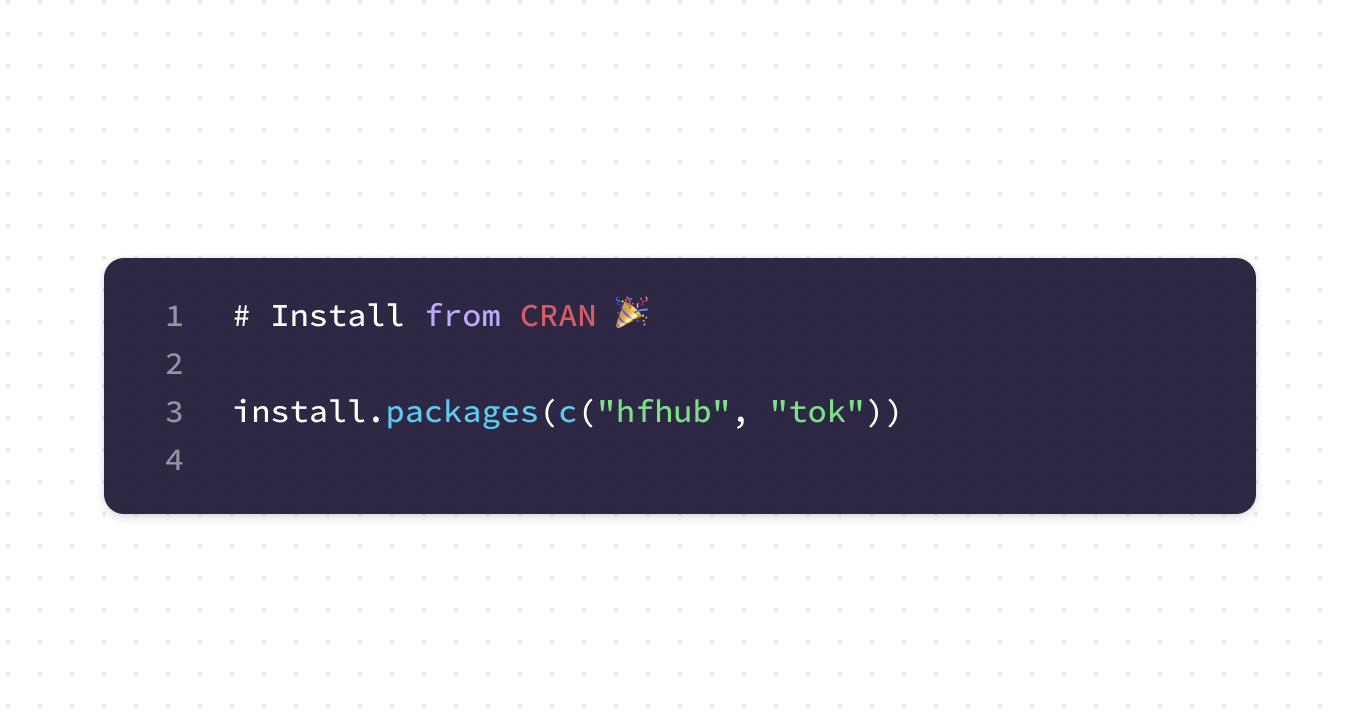
tok will be put in from CRAN, and at the moment it’s utilization is restricted to loading
tokenizers vocabularies from recordsdata. For instance, you may load the tokenizer for the GPT2
mannequin with:

Keep in mind that you may already host
Shiny (for R and Python) on Hugging Face Areas. For example, we’ve constructed a Shiny
app that makes use of:

  • torch to implement GPT-NeoX (the neural community structure of StableLM – the mannequin used for chatting)
  • hfhub to obtain and cache pre-trained weights from the StableLM repository
  • tok to tokenize and pre-process textual content as enter for the torch mannequin. tok additionally makes use of hfhub to obtain the tokenizer’s vocabulary.

The app is hosted at on this House.
It at the moment runs on CPU, however you may simply change the the Docker picture if you would like
to run it on a GPU for sooner inference.

The app supply code can also be open-source and will be discovered within the Areas file tab.

Trying ahead

It’s the very early days of hfhub and tok and there’s nonetheless loads of work to do
and performance to implement. We hope to get neighborhood assist to prioritize work,
thus, if there’s a characteristic that you’re lacking, please open a difficulty within the
GitHub repositories.

Reuse

Textual content and figures are licensed underneath Inventive Commons Attribution CC BY 4.0. The figures which were reused from different sources do not fall underneath this license and will be acknowledged by a notice of their caption: “Determine from …”.

Quotation

For attribution, please cite this work as

Falbel (2023, July 12). Posit AI Weblog: Hugging Face Integrations. Retrieved from https://blogs.rstudio.com/tensorflow/posts/2023-07-12-hugging-face-integrations/

BibTeX quotation

@misc{hugging-face-integrations,
  writer = {Falbel, Daniel},
  title = {Posit AI Weblog: Hugging Face Integrations},
  url = {https://blogs.rstudio.com/tensorflow/posts/2023-07-12-hugging-face-integrations/},
  12 months = {2023}
}

[ad_2]

Hackers launch mass assaults exploiting outdated WordPress plugins

0

[ad_1]

A widespread exploitation marketing campaign is focusing on WordPress web sites with GutenKit and Hunk Companion plugins weak to critical-severity, previous safety points that can be utilized to attain distant code execution (RCE).

WordPress safety agency Wordfence says that it blocked 8.7 million assault makes an attempt in opposition to its clients in simply two days, October 8 and 9.

The marketing campaign expoits three flaws, tracked as CVE-2024-9234, CVE-2024-9707, and CVE-2024-11972, all rated essential (CVSS 9.8).

CVE-2024-9234 is an unauthenticated REST-endpoint flaw within the GutenKit plugin with 40,000 installs that permits putting in arbitrary plugins with out authentication.

CVE-2024-9707 and CVE-2024-11972 are missing-authorization vulnerabilities within the themehunk-import REST endpoint of the Hunk Companion plugin (8,000 installs) which may additionally result in putting in arbitrary plugins.

An authenticated attacker can leverage the vulnerabilities to introduce one other weak plugin that permits distant code execution.

  • CVE-2024-9234 impacts GutenKit 2.1.0 and earlier
  • CVE-2024-9707 impacts Hunk Companion 1.8.4 and older
  • CVE-2024-11972 impacts Hunk Companion 1.8.5 and former variations

Fixes for the three vulnerabilities turned accessible in Gutenkit 2.1.1, launched in October 2024, and Hunk Companion 1.9.0, launched in December 2024. Nevertheless, regardless of the seller fixing them virtually a 12 months in the past, many web sites proceed to make use of weak variations.

Number of blocked attacks
Variety of blocked assaults
Supply: Wordfence

Wordfence’s observations based mostly on the assault information point out that  researchers say that risk actors are internet hosting on GitHub a malicious plugin in a .ZIP archive referred to as ‘up’.

The archive incorporates obfuscated scripts that permit importing, downloading, and deleting recordsdata, and altering permissions. One of many scripts that’s protected with a password, disguised as a part of the All in One search engine optimization plugin, is used to mechanically log within the attacker as an administrator.

The attackers use these instruments to keep up persistence, steal or drop recordsdata, execute instructions, or sniff non-public information dealt with by the location.

When attackers can not immediately attain a full admin backdoor through the put in package deal, they usually set up the a weak ‘wp-query-console’ plugin that may be leveraged for unauthenticated RCE.

Wordfence has listed a number of IP addresses that drive excessive volumes of those malicious requests, which may also help create defenses in opposition to these assaults.

As an indicator of compromise, the researchers say that directors ought to search for /wp-json/gutenkit/v1/install-active-plugin and /wp-json/hc/v1/themehunk-import requests within the web site entry logs.

They need to additionally examine the directories /up, /background-image-cropper, /ultra-seo-processor-wp, /oke, and /wp-query-console, for any rogue entries.

Administrator are beneficial to maintain all plugins on their web sites up to date to the newest model accessible from the seller.

46% of environments had passwords cracked, almost doubling from 25% final 12 months.

Get the Picus Blue Report 2025 now for a complete take a look at extra findings on prevention, detection, and information exfiltration tendencies.

[ad_2]

Scientists put together for the subsequent Carrington Occasion

0

[ad_1]

Governmental catastrophe preparedness isn’t restricted to crises that originate right here on Earth. Actually, specialists know that a number of the most disruptive and unpredictable occurrences start on the floor of the solar. For weeks now, emergency planners on the European House Company (ESA) in Darmstadt, Germany, have been conducting take a look at runs to enhance response capabilities for a cataclysmic photo voltaic storm. And whereas in the present day’s digitally interconnected world implies that such an occasion would inevitably disrupt world techniques, researchers are working to make sure humanity has the most important lead time potential to keep away from a worst case state of affairs.

Photo voltaic storms are semiregular occasions by which the solar belches gargantuan plumes of energized mud and gasoline in the direction of the planet at speeds as quick as 2 million miles per hour. These waves can disrupt the Earth’s magnetosphere and generate the majestic hues seen throughout aurora occasions. The results go far past a blinding present within the evening sky. Geomagnetic storms can simply scramble satellite tv for pc constellations, energy grids, communications arrays, and primarily every other digital or geospatial-related infrastructure.

One other Carrington Occasion

Though a extreme photo voltaic storm made headlines final 12 months, a 166-year-old occasion nonetheless stays for probably the most highly effective bombardment on document. In August 1859, what’s now generally known as the Carrington Occasion struck Earth with sufficient cosmic pressure to supply Northern Lights as far south as Central America whereas additionally frying early telegraph techniques. The Carrington Occasion was unhealthy sufficient virtually two centuries in the past, however such a robust photo voltaic storm in the present day might hobble a society reliant on electronics, world positioning techniques, and telecommunications. 

One of many greatest points could be how the tens of hundreds of satellites above our heads may reply. Presently, the ESA is readying the November 4 launch of Sentinel-1D, the primary of two orbital payloads supposed to offer a relentless stream of floor imagery of the Earth. In line with Sentinel-1D’s deputy spacecraft operations supervisor Thomas Ormston, there may be at present solely a lot specialists can do to guard that form of multimillion greenback undertaking.

“Ought to such an occasion happen, there aren’t any good options. The aim could be to maintain the satellite tv for pc protected and restrict the harm as a lot as potential,” Ormston stated in an announcement.

The coaching state of affairs’s planners didn’t maintain again throughout their runthrough. In line with the ESA, the workshop centered on a simulated X45-class flare—a Carrington Occasion-level state of affairs that includes X-ray and ultraviolet radiation that will disrupt radar, communications, and GPS knowledge roughly eight minutes after launching from the solar.

ESA astronaut Thomas Pesquet photographed these inexperienced swirls of aurora borealis rom the Worldwide House Station in August, 2021. Credit score: ESA

Three waves of vitality

Sadly, such an emergency wouldn’t embody a single burst of cosmic vitality. About 10-20 minutes later, a second wave of high-energy particles together with protons, electrons, and alpha particles would strike Earth at practically the velocity of sunshine, frying Sentinel-1D’s onboard electronics and inflicting probably everlasting harm. Lead simulation officer Gustavo Baldo Carvalho defined that whereas the primary blast would doubtless take observers abruptly, they knew what was in retailer for them.

“As soon as they regained composure, they knew a countdown had begun. Within the subsequent 10 to 18 hours, a coronal mass ejection would strike, they usually needed to brace for it,” he stated.

It’s the third strike that will show most expensive. That is the second when a coronal mass ejection (CME) reaches Earth at a velocity of round 1,242 mph and triggers a large geomagnetic storm. Much like the Carrington Occasion or final 12 months’s bursts, observers on the bottom could be handled to a colourful aurora present. However that will doubtless be little compensation in comparison with electrical grids collapsing, powerlines surging, and satellites falling out of orbit.

“Ought to such a storm happen, satellite tv for pc drag might enhance by 400 % with native peaks in atmospheric density,” defined ESA house climate modelling coordinator Jorge Amaya. “This not solely impacts collision dangers but additionally shortens satellite tv for pc lifetimes as a consequence of elevated gas consumption to compensate for the orbit decay.”

Amaya added that whereas low-Earth orbit satellites might obtain some quantity of atmospheric safety, a Carrington-level state of affairs “would go away no spacecraft protected.”

He in contrast the ESA’s coaching state of affairs to planning for a pandemic. 

“We’ll really feel its actual impact on our society solely after the occasion, however we have to be prepared and have plans in place to react in a second’s discover,” stated Amaya.

Virgil solar probe in middle of illustration with sun on the left and Earth on the right
The ESA plans to launch its Virgil house climate monitor in 2031. Credit score: ESA

Planning for the long run

It’s removed from hopeless, nevertheless. The Sentinel-1D coaching provided the primary likelihood to run via a dire occasion in collaboration with the ESA’s House Climate Workplace. Within the meantime, the ESA is constant with its Distributed House Climate Sensor System (D3S) that can deploy a brand new satellite tv for pc array that gives up-to-date knowledge sources. In the meantime, the company is gearing up for the Virgil mission scheduled to launch in 2031. As soon as accomplished, Virgil will monitor for harmful photo voltaic occasions from the “facet” of the solar. At that angle, the system can alert groups on Earth to photo voltaic occasions quicker than ever, permitting engineers time to organize weak techniques with a bigger window than ever earlier than.

“The dimensions and number of the impacts pushed us and our techniques to the restrict, however the group mastered the problem and that taught us that if we are able to handle that we are able to handle any real-life contingency,” stated Ormston.


2025 Home of the Future awards header

2025 Dwelling of the Future Awards


Andrew Paul is a employees author for In style Science.


[ad_2]

Did you hear the one in regards to the large bubble threatening to take down the economic system?

0

[ad_1]

Usually, you’ll count on buyers to be extra simply spooked as speak of a bubble turned more and more ubiquitous, however regardless of the buyers of 2025 are, it’s definitely not skittish. Even the worst financial or political information solely chases them away for, at finest, a day.

After all, this isn’t a standard bubble in any sense. Its magnitude dwarfs even the dot-com bubble. It was preceded by a stage of gods-or-ashes hype in contrast to something I’ve ever seen. The individuals behind it have unprecedented wealth and energy. It’s hitting a market that has run out of “subsequent huge issues” and is determined for the subsequent one. Maybe most vital, the executives operating the world’s largest corporations have determined to pump trillions of {dollars} into the expertise.

Regardless of the purpose, we have now now reached the purpose the place the concept that OpenAI, Nvidia, and so on. are a bubble has change into so widespread which you can see it all over the place—from tales in The Wall Road Journal and The Monetary Instances to segments on late-night speak reveals.


For followers of Adam Ruins Every thing, Adam Conover additionally covers a lot of the identical materials bu in higher depth. 

Within the late Twenties, having your doorman provide inventory ideas was famously an indicator that it was time to get out of the market. Maybe within the 2020s it is having comics use the bubble as a punchline. 

[ad_2]

From datasets to framesets and alias variables: Knowledge administration advances in Stata

0

[ad_1]

The purpose of this weblog is to explain two novel options launched in Stata 18 (launched in 2023): 1) framesets and a couple of) alias variables throughout frames. These options allow Stata to take care of a multiplicity of probably very giant datasets effectively and conveniently. Framesets permit you to bundle, save on file, and cargo in reminiscence a set of associated frames that maintain datasets. Alias variables permit you to entry variables in different frames as in the event that they have been half of the present body, with little or no reminiscence overhead.

Knowledge administration in Stata

When Stata 1.0 was launched in 1985, information have been organized in a tabular type as observations (rows) and variables (columns) and have been known as a dataset. Datasets have been stored fully in reminiscence (then measured in kilobytes) and saved on disk as .dta information. Knowledge sorts, like integers, actual numbers, and particularly strings, have been frugally managed. A lot of the maiden 44 instructions have been for information administration, together with the nonetheless inescapable generate, substitute, and checklist. This underlying framework has remained the bedrock for the 17 variations of Stata that adopted: datasets are nonetheless stored as tables fully in reminiscence, with strongly typed languages to course of the information. This makes Stata quick and permits billions of observations to be processed in milliseconds. Nevertheless, holding complete datasets in reminiscence is restrictive with very giant datasets. Nonetheless, leveraging on the outstanding development of inexpensive reminiscence, Stata’s information administration capabilities stored getting greater, stronger, and quicker. On this weblog, I focus on new options for dealing with giant datasets, specifically, frames, framesets, and alias variables. I describe these options intimately within the subsequent three sections. In an appendix on the finish of this weblog, I present an outline of how Stata’s information administration capabilities have grown over time.

Frames: A framework for a number of datasets

With giant and sophisticated information, there may be typically have to work with a number of, and probably enormous, datasets concurrently. It’s possible you’ll wish to multitask and work with numerous datasets for numerous tasks. Or you might be working with a set of associated datasets and wish to consolidate statistics throughout them. There are Stata instructions, like protect and restore, that allow you to modify from one dataset to a different. However these require some cautious coding and entail a time penalty for saving and restoring datasets to and from disk.

In Stata 16 (2019), a brand new framework for dealing with a number of datasets was launched: frames. A number of datasets will be stored in reminiscence in a number of frames. For instance, right here is how one can create a body with body create, make that body the present (working) body with body change, and cargo a dataset into it:

. body create auto

. body change auto

. sysuse auto
(1978 car information)

You can also make a replica of a body and rename a body:

. body copy auto auto1

. body rename auto1 automobiles

Names of datasets and frames that maintain them will be totally different. Additionally, even when there are a number of frames in reminiscence, you’ll be able to interactively work with one body (the present body) at a time. You may determine the present body with pwf (print working body):

. pwf
  (present body is auto)

You all the time work with the present body, by default. That stated, the body prefix functionality lets you run a command on a body aside from the present one. For instance, you’ll be able to generate a brand new variable, say, newvar (with random values right here), in body automobiles:

. body automobiles: generate newvar = runiform()

You may also use frlink to create a hyperlink between the present body and one other body. As an illustration, you’ll be able to create a one-to-one hyperlink (by specifying 1:1) between present body auto and body automobiles by matching the observations on variable make (that retains makes of automobiles):

. frlink 1:1 make, body(automobiles)
(all observations in body auto matched)

You may delete a body (if it’s not the present one) with body drop:

. body drop automobiles

You may reset frames with

. frames reset

That can reset Stata to a state the place a single, empty body is in reminiscence.

You are able to do extra with frames: copy information variables and observations with body put, add new observations with body publish, and so forth.

Word that instructions associated to frames and framesets work precisely the identical approach whether or not you kind body or frames; they’re synonymous. For a very good introduction on frames, see assist frames intro.

Stata helps as much as 100 frames. Identical to particular person datasets, all frames are stored fully in reminiscence. This makes working with frames, too, very quick. But it surely assumes you’ll be able to match all frames information in reminiscence, a constraint that motivated the 2 new options in Stata 18.

New in Stata 18: Framesets

Stata 18 provides a pure evolution of the frames idea: customers can now save on disk, in a memory-efficient approach, a set of frames. A brand new information file format is launched for framesets: .dtas, the plural of .dta.

For instance, let’s create three frames and cargo into them three totally different datasets (associated to life expectancy):

. body create life0

. body create life1

. body create life2

. body life0: sysuse lifeexp
(Life expectancy, 1998)

. body life1: sysuse uslifeexp
(U.S. life expectancy, 1900-1999)

. body life2: sysuse uslifeexp2
(U.S. life expectancy, 1900-1940)

It can save you these three frames in a single frameset file, say, life.dtas, with

. frames save life, frames(life0 life1 life2)
file life.dtas saved

You may later reset or clear all frames and cargo frames saved in life.dtas with

. frames reset

. frames use life
  life0  68 x 6; Life expectancy, 1998
  life1  100 x 10; U.S. life expectancy, 1900-1999
  life2  41 x 2; U.S. life expectancy, 1900-1940

When working with a set of frames, it’s important to contemplate a variety of elements. For instance, what if the frames you wish to load from disk have the identical names as these in reminiscence? Which body turns into the present body when a frameset is loaded? What should you attempt to load a beforehand linked body that doesn’t exist anymore?

I present frames describe, which takes inventory of frames and the variables they maintain, each in reminiscence and on disk. For instance, the next provides a (quick) description of frames in frameset life.dtas:

. frames describe utilizing life, quick

-------------------------------------------------------------------------------
Body: life0

Incorporates information                                 Life expectancy, 1998
 Observations:            68                  26 Aug 2023 20:06
    Variables:             6
Sorted by:
-------------------------------------------------------------------------------

-------------------------------------------------------------------------------
Body: life1

Incorporates information                                 U.S. life expectancy, 1900-1999
 Observations:           100                  26 Aug 2023 20:06
    Variables:            10
Sorted by: 12 months
-------------------------------------------------------------------------------

-------------------------------------------------------------------------------
Body: life2

Incorporates information                                 U.S. life expectancy, 1900-1940
 Observations:            41                  26 Aug 2023 20:06
    Variables:             2
Sorted by: 12 months
-------------------------------------------------------------------------------

Frameset instructions additionally retailer quite a few r-results to maintain observe of what’s taking place, for instance, the subset of frames being saved or loaded, whether or not information in every body has modified in reminiscence, and so forth.

As with .dta information, we offer the low-level description of .dtas information. assist dtas offers all the main points wanted to produce other software program learn and write .dtas information.

The syntax and choices of frameset instructions observe, fairly naturally, these of dataset instructions, like save, use, and describe. For instance, dataset and frameset instructions deal with, in the identical approach, issues like labels, empty datasets, the extent of element in describing datasets, and so forth.

Stata makes use of its native zipfile to compress frameset information in frames save, and unzipfile to extract information in frames use. The person can specify the compression stage for frames save. This may be carried out in two methods: by the complevel(#) choice or by set dtascomplevel #. # is an integer between 0 and 9—0 means no compression and 9 means most compression. The default is 1. For instance, life.dtas will be saved and changed on disk with most compression by typing

. frames save life, frames(life0 life1 life2) complevel(9) substitute
file life.dtas saved

Word that frames and framesets are constructed on prime of datasets. Meaning you’ll be able to hold working with datasets in precisely the identical approach as you probably did earlier than, if frames and framesets should not of sensible curiosity to you. The one factor you most likely have to know is that once you use a dataset, it goes right into a body by default—and this body is, unsurprisingly, named default. On the finish of the day, even with frames, you interactively work with one dataset or one body at any given time.

New in Stata 18: Alias variables throughout frames

On this part, I describe how alias variables can be utilized to entry variables throughout frames in a memory-efficient method.

Two datasets in numerous frames will be associated by having matching variables. As talked about earlier, you’ll be able to hyperlink frames with frlink by matching observations within the present body with observations within the associated body, primarily based on frequent variables.

After creating hyperlinks with frlink, you should use fralias add to outline variable aliases—names that reference variables in a linked body.

Right here is an instance of including an alias variable. First, let’s arrange the auto and automobiles frames in reminiscence as we did above.

. clear all

. body create auto

. body change auto

. sysuse auto
(1978 car information)

. body copy auto automobiles

. body automobiles: generate newvar = runiform()

. pwf
 (present body is auto)

The 2 frames are the identical, apart from variable newvar added to automobiles. From the present body auto, you’ll be able to create a one-to-one hyperlink with automobiles, primarily based on frequent variable make:

. frlink 1:1 make, body(automobiles)
(all observations in body auto matched)

Now, an alias variable, say, newvar, will be created in present body auto to entry variable newvar in automobiles:

. fralias add newvar, from(automobiles)
(1 variable aliased from linked body)

Right here the alias variable has the identical title because the variable it factors to. However it may be totally different. We’ll present how within the subsequent instance.

In essence, fralias add defines references from the present body to variables in linked frames. The references allow you to work with the linked variables with out copying them within the present body. These references eat little or no reminiscence; the variables are literally saved solely in a single body or dataset however will be made obtainable in numerous frames.

Listed below are just a few extra feedback about frlink, on which fralias is based. While you use frlink, a brand new variable is created within the present body. It references the linked body. By default, the brand new variable is known as after the linked body. However a unique variable title will be generated with choice generate().

Additionally, the matching of observations with frequent variables carried out by frlink will be one to at least one or many to at least one. Somewhat usefully, frlink may even deal with variables which might be frequent in numerous frames however with totally different names. Moreover, frlink can match teams of variables utilizing wildcard * in variable names. Ought to there be modifications in information, or frames renamed, hyperlinks will be rebuilt with frlink rebuild or dropped by dropping the hyperlink variable.

Alias variables created by fralias add are handled like another variable in your dataset, with the caveat that you’re not allowed to alter their values. For a given alias variable, should you change the corresponding variable’s values within the linked body the place they reside, the modified values are robotically obtainable the following time you employ the alias variable. So altering the variables in a single body is enough, and the change is mirrored in all frames that reference them.

Alias variables enable many frames to have the identical variable as if it belongs to all of them, however the variable is saved in just one body. This avoids creating duplicates of variables or utilizing costly instructions like merge or frget. The latter, for instance, copies variables from a linked body with a big reminiscence footprint, particularly with costly information sorts like double and string. In distinction, alias variables, being mere references in reminiscence, have small, fastened reminiscence footprints. Utilizing alias variables is due to this fact reminiscence environment friendly and helps afford holding all frames in reminiscence, which retains Stata fast and nimble.

Instance of frameset and alias variable

On this part, I present a extra full instance and delve into further options of frameset and alias variable instructions.

Suppose you might be engaged on a undertaking concerning the revenue stage within the state of Texas in the USA and wish to analyze the information at individual and county stage (every United States state includes counties).

You might be utilizing two Stata datasets: individuals.dta and txcounty.dta. You may load the 2 datasets in two frames, say, individuals and counties, as follows:

. clear all

. body create individuals

. body change individuals

. webuse individuals

. body create counties

. body change counties

. webuse txcounty
(Median revenue in Texas counties)

You may describe the 2 frames with the body prefix:

. body individuals: describe

Incorporates information from https://www.stata-press.com/information/r18/individuals.dta
 Observations:            20
    Variables:             3                  16 Apr 2022 13:36
                                              (_dta has notes)
----------------------------------------------------------------------
Variable      Storage   Show    Worth
    title         kind    format    label      Variable label
----------------------------------------------------------------------
personid        byte    %9.0g                 Individual ID
countyid        byte    %9.0g                 County ID
revenue          float   %9.0g                 Family revenue
----------------------------------------------------------------------
Sorted by:

. body counties: describe

Incorporates information from https://www.stata-press.com/information/r18/txcounty.dta
 Observations:             8                  Median revenue in Texas counties
    Variables:             2                  30 Dec 2022 06:13
                                              (_dta has notes)
-------------------------------------------------------------------------------
Variable      Storage   Show    Worth
    title         kind    format    label      Variable label
-------------------------------------------------------------------------------
countyid        byte    %9.0g      cty        County ID
median_income   float   %9.0g                 Family median revenue
-------------------------------------------------------------------------------
Sorted by:

With clear all above, we robotically began with an empty working body known as default. We then added two frames on prime of default. We are able to checklist the frames in reminiscence and determine the present body with

. frames dir
  counties  8 x 2; Median revenue in Texas counties
  default   0 x 0
  individuals   20 x 3; individuals.dta

. pwf
  (present body is counties)

counties is the present body as a result of it’s the final body we modified to. If we wish to work with individuals, we’ve to alter to that body:

. body change individuals

As a result of frames individuals and counties have frequent variable countyid, we are able to use frlink to hyperlink present body individuals to border counties, primarily based on countyid. As a result of many individuals belong to the identical county, the matching right here is many to at least one (m:1):

. frlink m:1 countyid, body(counties)
(all observations in body individuals matched)

The matching variables wouldn’t have to have the identical title. It’s slightly straightfoward to do the linking in such instances. assist frlink has the main points.

Word that the frlink command above created a brand new variable in individuals and is known as counties. It’s named after the linked body. Choice generate() might have been utilized in frlink to create a unique variable title. The values of the brand new variable are matching statement numbers in counties.

Now you can use frames save to save lots of, on disk, body individuals and all different frames linked to it by specifying choice linked; all frames are saved in file myproject.dtas:

. frames save myproject, frames(individuals) linked
file myproject.dtas saved

Word that solely body counties is linked to the present body on this case, given the frlink command above. So counties can be saved in myproject.dtas, apart from individuals.

Subsequent, you’ll be able to reset all frames in reminiscence and later remind your self what’s there in myproject.dtas with frames describe (we use choice easy for a compact description):

. frames reset

. frames describe utilizing myproject, easy

--------------------------------------------
Body: individuals
personid  countyid  revenue    counties
--------------------------------------------

--------------------------------------------
Body: counties
countyid       median_income
--------------------------------------------

You may later load all frames saved in myproject.dtas in reminiscence with frames use:

. frames use myproject, frames(_all)
  counties  8 x 2; Median revenue in Texas counties
  individuals   20 x 4

Word that, at this level, the present body is default, as pwf reveals:

. pwf
 (present body is default)

Though two frames have been loaded in reminiscence, the present body (default on this case) didn’t change with frames use. To work with one of many loaded frames, say, individuals, it’s important to explicitly specify it because the working body:

. body change individuals

Subsequent, you wish to examine incomes of particular person individuals to the median revenue of the county. The median revenue is accessible in body counties. We all know that individuals is linked to counties primarily based on the frlink command above. We are able to confirm the present linkages from the present body (individuals) with

. frlink dir
  (1 frlink variable discovered)
  -----------------------------------------------------------------------------
  counties created by frlink m:1 countyid, body(counties)
  -----------------------------------------------------------------------------
  Word: Sort "frlink describe varname" to seek out out extra, together with whether or not the
  variable continues to be legitimate.

To entry variable median_income in body counties, you’ll be able to add an alias variable, say, median, to reference the variable as follows:

. fralias add median = median_income, from(counties)
(1 variable aliased from linked body)

You may describe the alias variable with

. fralias describe median

----------------------------------------------------
Alias    Sort    Goal          Hyperlink       Body
----------------------------------------------------
median   float   median_income   counties   counties
----------------------------------------------------

Now you can run analyses in body individuals that embody variable median. Very merely right here, yow will discover the ratio of particular person revenue to the corresponding county median revenue:

. generate ratio = revenue/median

Word that alias variable median merely references median_income in counties, which consumes little reminiscence. So you’ll be able to work with the variable as if it have been a part of the body, with little or no reminiscence overhead. However you can not change the variable; it may be modified solely in body counties. Any change within the variable will likely be obtainable in all frames that reference it.

Abstract

On this publish, I described two information administration options not too long ago launched in Stata: framesets and alias variables. Whereas sticking to fundamental ideas that make information processing in Stata easy, intuitive, and quick (like holding the whole dataset in reminiscence), we stored augmenting Stata’s capabilities in information administration. The potential to deal with giant and sophisticated datasets look a leap in Stata 16 with the introduction of frames: a number of, and presumably associated, datasets will be concurrently stored in reminiscence as frames. In Stata 18, we adopted up with a pure evolution of frames: the flexibility to save lots of a number of datasets or frames in a single, compressed file and later restore the saved frames in reminiscence. We launched a brand new file format, the .dtas file. We additionally offered alias variables that allow entry to variables in linked frames. Alias variables throughout frames is a strong software that conveniently and effectively permits entry to variables in numerous frames with out spending reminiscence by producing copies of the variables or utilizing costly instructions to mix very huge datasets.

Appendix: A abstract of Stata’s information administration capabilities

On this part, I describe the important thing stations alongside Stata’s journey in information administration. This offers a context for the current options launched. Whereas the core design and ideas that make Stata intuitive and quick haven’t modified, the information administration capabilities have constantly made main strides to deal with more and more giant and sophisticated datasets. Listed below are the highlights.

  • The restrict within the variety of observations had grown steadily, to over a billion within the MP (multiprocessor) model of Stata 14 (2015) and to over a trillion presently. Terabytes of reminiscence at the moment are supported. The utmost variety of variables was elevated to 120,000 in Stata/MP 15 (2017). Different information maxima additionally stored rising: size of assorted names, variety of choices for a command, size of worth labels, macros, and so forth. In apply, with computerized reminiscence administration launched in Stata 12 (2011) and enhanced in Stata 14 (2015), the utmost dimension limits, just like the variety of observations and variables, are primarily constrained by how a lot reminiscence is accessible. assist limits will inform you extra.
  • Earlier than Stata 13 (2013), strings have been restricted to 244 characters. Stata 13 launched a brand new information kind known as strL (lengthy strings), which elevated the utmost size of strings to 2 billion characters. This enabled studying giant information into strings and writing lengthy strings to information. Thus, a wide range of information might be dealt with in Stata instructions and features: Phrase paperwork, JPEG pictures, plain textual content ASCII, EBCDIC, binary, VARCHARs (variable character fields), BLOBs (binary giant objects), CLOBs (character giant object strings), and extra. assist datatypes has extra particulars.
  • Stata regularly launched help for an more and more huge number of specialised information: longitudinal/panel, survival/period, time sequence, survey, discrete alternative, spatial, and a number of imputations (to deal with lacking information).
  • All editions of Stata can be found on all main working techniques and {hardware} platforms—with full compatibility. Stata datasets, applications, and different information will be shared throughout editions and platforms with out translation.
  • With Stata/MP, the multiprocessor version of Stata launched in model 9 (2005), huge speedup was achieved. As much as 64 cores/processors will be supported. Subsequently, many instructions and built-in routines have been modified to reap the benefits of parallelization, wherever potential—from information administration duties like including variables and sorting to evaluation duties like regression and different computationally intense estimation instructions.
  • Knowledge will be imported from, and exported to, a rising variety of common file codecs, together with Excel, SAS, SPSS, dBase—apart from normal codecs like comma-separated values (.csv) and stuck column information. Stata offers help for JDBC and ODBC and database merchandise like Oracle, MySQL, Amazon Redshift, Snowflake, Microsoft SQL Server, and DB2. Stata additionally offers entry to information repositories just like the Federal Reserve Financial Knowledge, Wharton Analysis Knowledge Companies, Haver Analytics, Worldwide Statistical Classification of Ailments and Associated Well being Issues (ICD-9 and ICD-10).
  • Stata’s interoperability capabilities additionally made important inroads. There was rising integration with different improvement platforms like Java, Python, and H2O (for machine studying and predictive analytics). Stata turned internet conscious in model 8 (2003) with instructions like webuse. Thereafter, Stata made strides to seamlessly and effectively entry and interoperate with information sources and platforms over the Web and the Cloud.
  • The graphics-driven information editor was launched in Stata 8 (2003) after which constantly improved. Spreadsheet enhancing capabilities, like reside view of knowledge, including and altering observations/variables/cells, importing information, and copying and pasting, have been repeatedly enhanced.
  • Stata 14 (2015) launched help for Unicode (UTF-8). Subsequently, Stata added help for a number of languages in its interface, menus, and dialogs. Moreover English, Stata speaks Chinese language, Japanese, Korean, Spanish, and Swedish.
  • Mata is a programming language launched in Stata 9 (2005) with highly effective matrix capabilities. The matrices could include parts of or complete datasets. In truth, Mata matrices will be made with views of Stata datasets and frames and may have as much as 281 trillion rows and columns, if the pc has enough reminiscence. Mata is compiled and may be very environment friendly. It may possibly run as much as 40 instances quicker than Stata’s interpreted languages and is helpful for CPU and memory-intensive numerical strategies involving giant vectors and matrices.
  • To deal with bigger and extra advanced tasks, Stata launched a Challenge Supervisor in launch 13 (2013) to prepare information and evaluation information underneath a number of tasks.
  • Stata 16 (2019) launched frames. This offers the flexibility to maintain a number of datasets in reminiscence and work with them concurrently. Increase on the framework for frames, two new options (the main focus of this weblog) have been launched in Stata 18 (2023): the flexibility to save lots of and cargo units of frames (or framesets) and the flexibility to entry variables in numerous frames by alias variables.

Reference

Cox, N. J. 2015. A brief historical past of Stata on its thirtieth anniversary. In Thirty Years with Stata: A Retrospective, ed. E. Pinzon, 135–147. School Station, TX: Stata Press.

Assets

[D] frames
[D] frames intro
[D] frames save
[D] frames use
[D] frames describe
set dtascomplevel
[D] frlink
[D] fralias

https://www.stata.com/new-in-stata/frameset/
https://www.stata.com/new-in-stata/alias-variables-across-frames/
https://www.stata.com/options/overview/multiple-datasets-in-memory/
https://www.stata.com/options/data-management/

[ad_2]

Detecting Anomalies in Idealista’s Information – The Official Weblog of BigML.com

0

[ad_1]

At BigML we love knowledge. Recently, Idealista printed this weblog publish describing some evaluation of properties positioned in some cities of Spain. The information was additionally included, and was dated 2018. As a part of our staff lives there and summertime instills a playful disposition, we jumped to our platform to play with it a bit and created some anomaly detectors. This publish is merely an outline of our work and the outcomes we simply discovered.

Describing the Information

The repository that was referenced within the publish incorporates a number of knowledge information, however we targeted on those that comprise sale data, just like the ID, worth, unitary worth, variety of bedrooms, and so forth. They seek advice from properties positioned in Madrid, Barcelona, and Valencia and their location is among the accessible variables. Sadly, the info was not in good plain CSV information, so despite the fact that we’re completely keen on Python, we had been compelled to make use of R to extract them; however that was a minor setback. As soon as created, the one transformation we did was eradicating a geolocation discipline with duplicated data and we had been able to work.

The Work within the Platform

Ranging from one of many CSVs, we dived into BigML. First, we uploaded the three information, one per metropolis, by dragging and dropping them and checked the kinds inferred mechanically within the first one. Solely a few date fields that had been written in a personalized format wanted some consideration, so we configured these to be correctly parsed. After that, you simply create a dataset that summarizes the knowledge and an anomaly detector to assign the anomaly rating, a quantity that ranges from 0 to 1 to point completely regular or very anomalous, respectively. All of that is obtained by utilizing 1-clicks in our Dashboard (no code wanted!).

Understanding the Anomalies

Every file has its personal excellent anomalies, and each anomaly is taken into account so due to a distinct set of causes. The next picture exhibits an inventory of the best anomalies discovered within the Valencia_Sale.csv file. The instance describes the fields that contributed extra to the primary discovered anomaly, that are proven in the correct column: being a duplex with a north orientation, a doorman, a terrace, and a swimming pool.

That property just isn’t actually the standard flat that one can discover in Valencia. Taking a look at the remainder of the attributes of that property one discovers that’s an remoted home with air-con, a elevate, a field room, and a wardrobe, so it actually stands out from the remainder of the crammed flats of a dense metropolis. Wanting on the remaining high anomalies, all of them seek advice from duplexes, most of them studios, with a lot of commodities, so our anomaly detectors discovered primarily unusual luxurious flats or homes.

Anomalies Distribution

We’ve mentioned a few of the related anomalies that we detected within the knowledge and their particular person properties, however we all know nothing as far as to their distribution of these anomalies. Do they group beneath some situations? To investigate that, we merely compute a batch anomaly rating in 1-click. That provides a brand new column to our dataset, containing the anomaly rating for every row. Their distribution can then be drawn as a histogram, exhibiting how there’s a small tail of fairly anomalous properties on the market.

In all circumstances, the tail appears to start out round 0.6 and people rows with larger values would be the ones that we contemplate anomalous.

Our Summer time App

Following the summer time spirit, that evokes us to have interaction in all form of initiatives, we determined to construct an app to indicate up these outcomes. Having the location for these properties, we had been curious to know whether or not these anomalies had been distributed evenly all through the town or, quite the opposite, appeared extra ceaselessly in some neighborhoods. Geolocation could be useful, so we simply downloaded the batch anomaly rating dataset and used Streamlit and Mapbox to create a easy visualization on a map.

And voilà! We see that anomalies seem extra ceaselessly in some neighborhoods. As an illustration, in Barcelona we see them within the higher facet city, the place luxurious flats and homes had been constructed, or within the sea shore. The latter additionally occurs in Valencia, the place we discover them in and outdated poor neighborhood by the ocean facet that’s just lately being gentrified. The distribution of anomalies on a map (and even by home windows of time) is an fascinating indicator of modifications and is a meta-anomaly perception by itself. In case you are acquainted with any of those cities, you may need to examine the reside app right here.

My Summer time Pocket book

Analyzing this knowledge has been a refreshing mission that took only a small period of time and led to a pleasant instance of what anomalies data can reveal. Actually, the automation offered by the BigML platform through scriptify helped us to breed the method finished by point-and-click within the Dashboard on one of many information to the remainder. Utilizing that we might repeat it in parallel and at scale for each metropolis. After all, we have to stroll the final mile and produce the knowledge given by the Machine Studying fashions to the area atmosphere, on this case the town maps. This integration within the area of software is usually key for the customers to see the actual energy of Machine Studying fashions… and on this case, it was additionally enjoyable to do and good to have a look at!

[ad_2]

Salesforce AI Analysis Introduces WALT (Net Brokers that Study Instruments): Enabling LLM brokers to Mechanically Uncover Reusable Instruments from Any Web site

[ad_1]

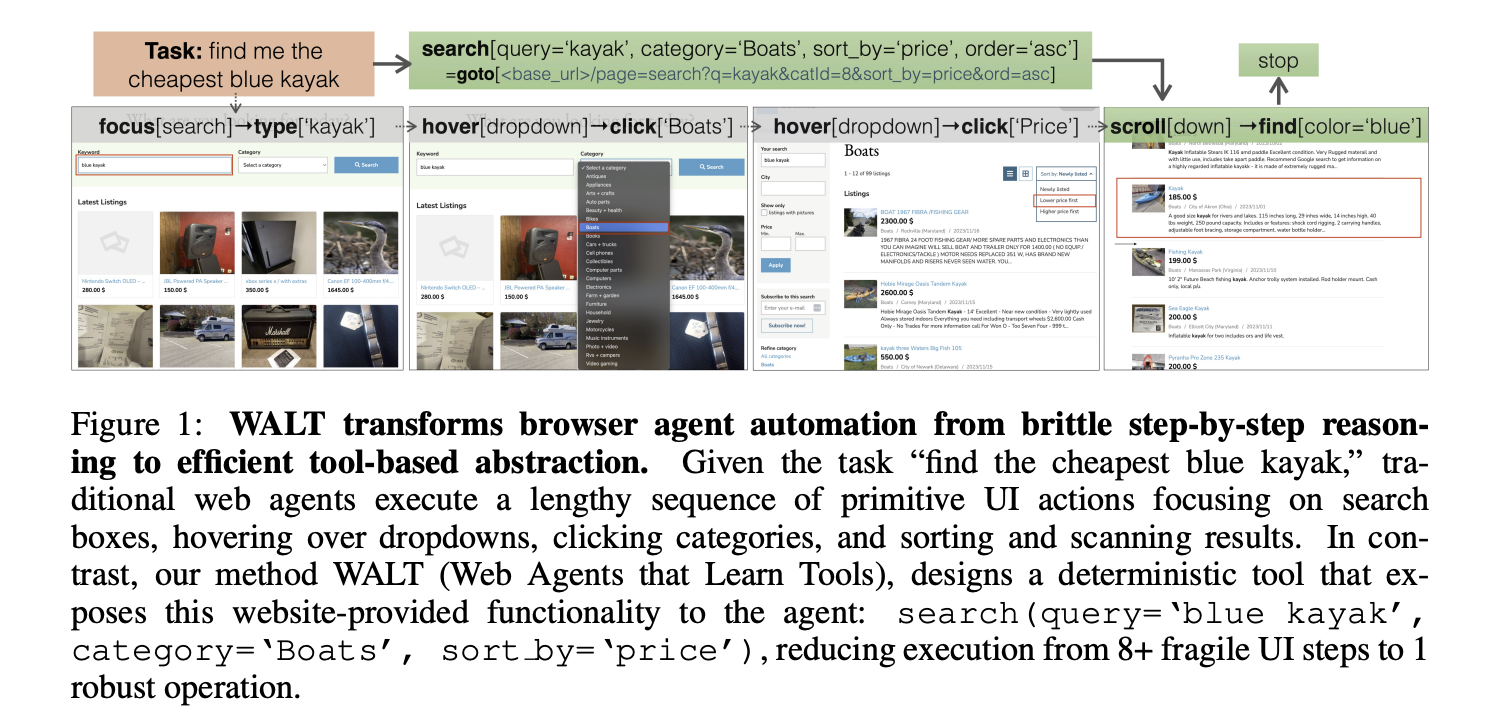
A staff of Salesforce AI researchers launched WALT (Net Brokers that Study Instruments), a framework that reverse-engineers latent web site performance into reusable invocable instruments. It reframes browser automation round callable instruments slightly than lengthy chains of clicks. Brokers then name operations resembling search, filter, type, post_comment, and create_listing. This reduces dependence on giant language mannequin step-by-step reasoning and will increase determinism throughout execution.

https://arxiv.org/pdf/2510.01524

What WALT builds?

Net brokers typically fail when layouts shift or when duties require lengthy sequences. WALT targets this failure mode by mining web site performance offline, then exposing it as instruments that encapsulate navigation, choice, extraction, and non-compulsory agentic steps. Instruments carry contracts within the type of schemas and examples. At runtime, an agent composes a brief program with a number of software calls to finish a process. The design objective is increased success with fewer steps and fewer reliance on free type reasoning.

Pipeline in two phases

The pipeline has discovery and development with validation. In discovery, WALT explores an internet site and proposes software candidates that map to widespread targets resembling discovery, content material administration, and communication. In development and validation, WALT converts traces to deterministic scripts, stabilizes selectors, makes an attempt URL promotion when attainable, induces an enter schema, and registers a software solely after finish to finish checks move. This shifts as a lot work as attainable into steady URL and type operations and leaves agentic grounding for the circumstances that really require it.

https://arxiv.org/pdf/2510.01524

Outcomes on VisualWebArena and WebArena

On VisualWebArena, WALT studies a median success charge of 52.9 p.c with per cut up outcomes of 64.1 p.c on Classifieds, 53.4 p.c on Purchasing, and 39.0 p.c on Reddit. The desk lists baselines resembling SGV at 50.2 p.c and ExaCT at 33.7 p.c. Human efficiency is 88.7 p.c on common.

On WebArena, WALT reaches 50.1 p.c common throughout GitLab, Map, Purchasing, CMS, Reddit, and Multi. The desk reveals WALT forward of prior strategies with a 9 level margin over one of the best talent induction baseline. Human efficiency is 78.2 p.c.

https://arxiv.org/pdf/2510.01524

Effectivity and ablations

Instruments cut back motion rely by an element close to 1.4 on common relative to a matched agent with out instruments. On the Classifieds cut up, ablations present constant beneficial properties when instruments are used throughout completely different agent backbones. WALT with GPT 5 mini data 7 p.c increased success and 27 p.c fewer steps, whereas a human demonstration technique yields 66.0 p.c success. The absolutely autonomous WALT reaches 64.1 p.c with 5 p.c fewer steps than the human demonstration case. Multimodal DOM parsing provides 2.6 p.c absolute enchancment. Exterior verification provides 3.3 p.c whereas growing checks. Throughout elements, WALT data 21.3 p.c fewer steps than baseline insurance policies.

https://arxiv.org/pdf/2510.01524

Design decisions that implement determinism

WALT prefers URL degree operations when the positioning exposes question parameters or routes for search and filtering. When pages require dynamic grounding, the software script inserts bounded agentic steps resembling content material extraction or look forward to web page load. Selector stabilization and schema validation cut back drift when websites change. The tactic retains the fraction of agentic operations low in found software units and biases towards deterministic actions like navigation, enter, and click on.

Key Takeaways

  1. Method: WALT discovers and validates website-native capabilities, then exposes them as callable instruments with enter schemas, selector stabilization, and URL promotion, lowering brittle step sequences to deterministic operations.
  2. Outcomes — VisualWebArena: Common success charge 52.9%, with 64.1% on Classifieds, 53.4% on Purchasing, and 39.0% on Reddit, outperforming a number of baselines reported within the paper.
  3. Outcomes — WebArena: Common success charge 50.1% throughout GitLab, Map, Purchasing, CMS, Reddit, and Multi, displaying constant beneficial properties over skill-induction and search-based baselines.
  4. Effectivity and Ablations: Toolization cuts steps by about 1.4x, with 21.3% fewer actions on common. Multimodal DOM parsing provides +2.6% absolute success, and exterior verification provides +3.3%.

WALT is a helpful pivot from step sequence brokers to performance grounded instruments. The framework reverse engineers latent web site performance into reusable invocable instruments throughout discovery, content material administration, and communication. By selling UI traces to deterministic instruments with schema validation and URL operations, WALT lifts net agent success to 52.9 p.c on VisualWebArena and 50.1 p.c on WebArena, whereas reducing actions by about 21.3 p.c. The discharge ships a CLI, walt uncover, walt agent, and MCP serving for integration.


Try the Paper and GitHub Web page. Be happy to take a look at our GitHub Web page for Tutorials, Codes and Notebooks. Additionally, be at liberty to observe us on Twitter and don’t neglect to hitch our 100k+ ML SubReddit and Subscribe to our Publication. Wait! are you on telegram? now you may be a part of us on telegram as nicely.


Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is dedicated to harnessing the potential of Synthetic Intelligence for social good. His most up-to-date endeavor is the launch of an Synthetic Intelligence Media Platform, Marktechpost, which stands out for its in-depth protection of machine studying and deep studying information that’s each technically sound and simply comprehensible by a large viewers. The platform boasts of over 2 million month-to-month views, illustrating its reputation amongst audiences.

[ad_2]

What to observe on Apple TV+: Schedule, reveals record and new releases

0

[ad_1]

[ad_2]