All kinds of loopy issues have been instructed concerning 3I/ATLAS, the third recognized interstellar object that we have found. Some are merely conspiracy theories about it being an alien spacecraft, whereas others have been well-thought out strategies, like utilizing Martian-based probes to watch the comet because it streaked previous the purple planet.
A brand new paper pre-published on arXiv and accepted for publication by the Analysis Notes of the American Astronomical Society by Samuel Grand and Geraint Jones, of the Finnish Meteorological Institute and ESA respectively, falls into the latter class, and suggests using two spacecraft already en path to their separate locations to probably detect ions from the thing’s spectacular tail that has shaped because it approaches the Solar.
These two spacecraft are Hera and Europa Clipper – each of that are on their solution to missions in drastically totally different elements of the photo voltaic system. Hera is on its solution to Didymos-Dimorphos, the binary asteroid that was impacted by the DART mission in 2022. Europa Clipper, as its identify suggests, is on its solution to Europa, one in all Jupiter’s 4 Galilean moons, intending to review its ice.
However, as luck would have it, each spacecraft are going to cross “downwind” of 3I/IATLAS within the subsequent two weeks. Hera can have a window between October twenty fifth and November 1st, whereas Europa Clipper can have a window between October thirtieth and November sixth.
Just a few weeks is not an entire lot of time to arrange a speedy experiment to run a take a look at that neither spacecraft had been designed for. However generally science means doing the most effective with what you have got, and on this case, these two spacecraft are our greatest wager to review the tail of an interstellar comet.
That tail has been persistently rising for the reason that comet’s discovery in early June. Latest reviews of its “gushing” water point out how large the tail has turn out to be, leaving a wake of water particles, however probably extra importantly, ions, behind it. The comet additionally just lately moved out of view from Earth-based techniques, although assumedly its tail will proceed to develop till it reaches perihelion on October twenty ninth.
Because the paper explains, ending up in a part of its tail is not so simple as passing straight behind it because it strikes by the photo voltaic system – the photo voltaic wind pushes the particles out farther from the Solar, following a curved path away from the comet. The pace at which the wind hits these particles performs a significant position in the place they might be, and due to this fact the place precisely the spacecraft must cross by to gather information on the tail straight.
Get the world’s most fascinating discoveries delivered straight to your inbox.
To make these estimates, the authors used a mannequin referred to as “Tailcatcher” that estimates the place the trail of the cometary ions will go primarily based on totally different wind speeds. It then calculated the “minimal miss distance” for a given spacecraft for the central axis of the comet’s tail. Sadly, the mannequin is simply as correct because the photo voltaic wind information, which usually is simply collected definitively ex submit facto – and positively not sufficient time to assist with this potential mission goal.
Even with the most effective estimates of this system, the 2 spacecraft could be hundreds of thousands of km away from the central axis – round 8.2 million for Hera and eight million for Europa Clipper. Nevertheless, that’s nonetheless inside vary of with the ability to accumulate information on the ions from the tail straight as they will unfold over hundreds of thousands of kilometers from very lively comets like 3I/ATLAS.
The draw back of this plan is that at the least one of many spacecraft – Hera – would not have any devices that would probably detect both the ions anticipated within the tail, nor the magnetic “draping construction” that characterizes what the comet’s environment does to the magnetic subject carried by the photo voltaic wind. Nevertheless, Europa Clipper does – it is plasma instrument and magnetometer are precisely what could be wanted to straight detect these ions and magnetic subject modifications.
Appearing on this little bit of serendipity is tough to say the least – but it surely’s additionally very time constrained. It is unclear whether or not the mission controllers for Hera, or maybe extra importantly, Europa Clipper, will see the message in time to do something about their potential journey by the coma. But when they do, they is perhaps the primary in human historical past to straight pattern and interstellar comet’s tail – and would not that be one thing to brag about that had nothing to do with their unique meant mission?
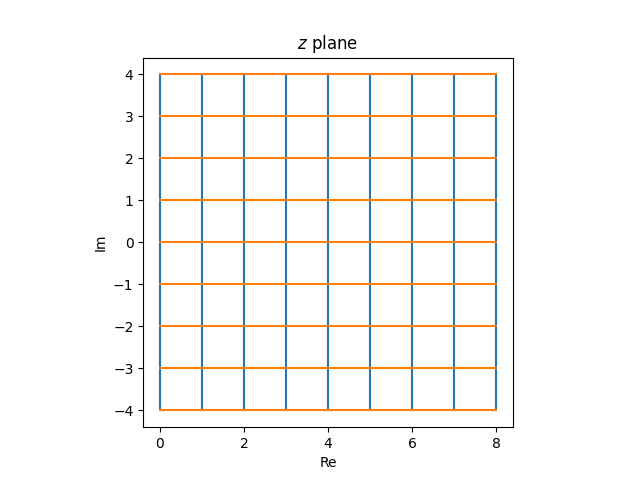
The Smith chart from electrical engineering is the picture of a Cartesian grid beneath the perform
f(z) = (z − 1)/(z + 1).
Extra particularly, it’s the picture of a grid in the suitable half-plane.
This submit will derive the essential mathematical properties of this graph however won’t go into the purposes. Stated one other approach, I’ll clarify the way to make a Smith chart, not the way to use one.
We’ll use z to indicate factors in the suitable half-plane and w to indicate the picture of those factors beneath f. We’ll converse of strains within the z airplane and the circles they correspond to within the w airplane.
Möbius transformations
Our perform f is a particular case of a Möbius transformation. There’s a theorem that claims Möbius transformation map generalized circles to generalized circles. Right here a generalized circle means a circle or a line; you’ll be able to consider a line as a circle with infinite radius. We’re going to get loads of mileage out of that theorem.
Picture of the imaginary axis
The perform f maps the imaginary axis within the z airplane to the unit circle within the w airplane. We are able to show this utilizing the theory above. The imaginary axis is a line, so it’s picture is both a line or a circle. We are able to take three factors on the imaginary axis within the z airplane and see the place they go.
Once we decide z equal to 0, i, and −i from the imaginary axis we get w values of −1, i, and −i. These three w values don’t line on a line, so the picture of the imaginary axis have to be a circle. Moreover, three factors uniquely decide a circle, so the picture of the imaginary axis is the circle containing −1, i, and −i, i.e. the unit circle.
Picture of the suitable half-plane
The imaginary axis is the boundary of the suitable half-plane. Since it’s mapped to the unit circle, the suitable half-plane is both mapped to the inside of the unit circle or the outside of the unit circle. The purpose z = 1 goes to w = 0, and so the suitable half-plane is mapped contained in the unit circle.
Pictures of vertical strains
Let’s take into consideration what occurs to vertical strains within the z airplane, strains with fixed constructive actual half. The pictures of those strains within the w airplane have to be both strains or circles. And because the right-half airplane will get mapped contained in the unit circle, these strains should get mapped to circles.
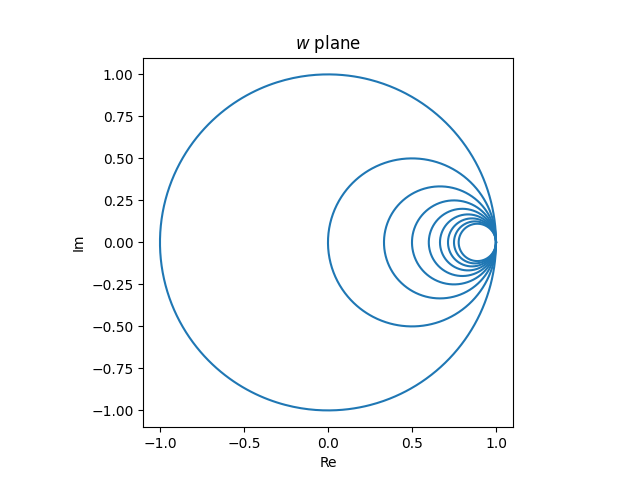
We are able to say somewhat extra. All strains comprise the purpose ∞, and f(∞) = 1, so the picture of each vertical line within the z airplane is a circle within the w airplane, contained in the unit circle and tangent to the unit circle at w = 1. (Tossing round ∞ is a bit casual, however it’s straightforward to make rigorous.)
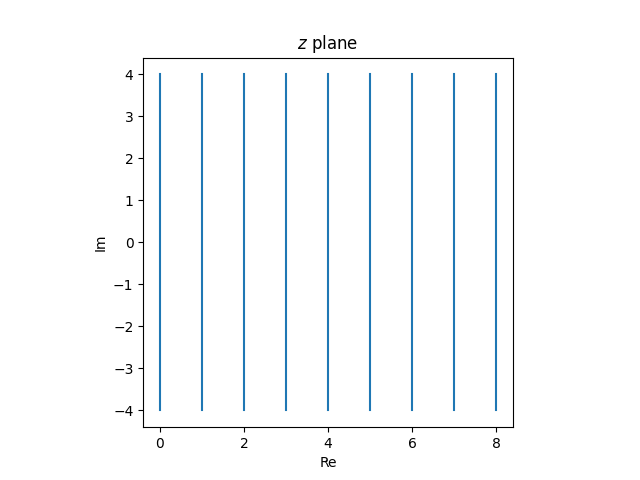
The vertical strains within the z airplane
map to tangent circles within the w airplane.
Pictures of horizontal strains
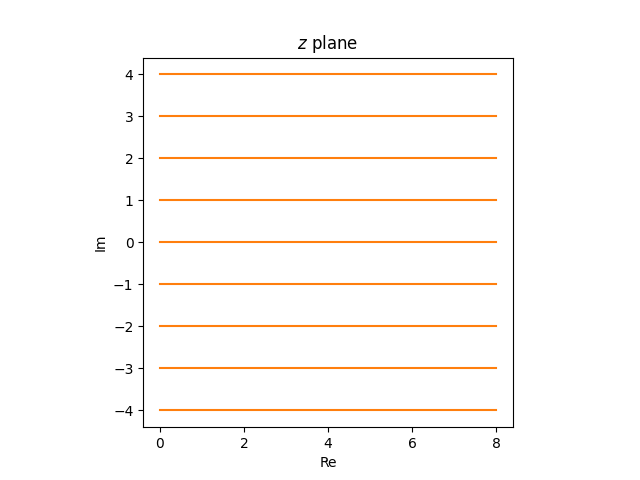
Subsequent, let’s take into consideration horizontal strains within the z airplane, strains with fixed imaginary half. The picture of those strains is both a line or a circle. Which is it? The picture of a line is a line if it accommodates ∞, in any other case it’s a circle. Now f(z) = ∞ if and provided that z = −1, and so the picture of the true axis is a line, however the picture of each different horizontal line is a circle.
Since f(∞) = 1, the picture of each horizontal line passes by 1, simply as the photographs of all of the vertical strains passes by 1.
Since horizontal strains lengthen previous the suitable half-plane, the picture circles lengthen previous the unit circle. The a part of the road with constructive actual half will get mapped contained in the unit circle, and the a part of the road with detrimental actual half will get mapped exterior the unit circle. Specifically, the picture of the constructive actual axis is the interval [−1, 1].
Möbius transformations are conformal maps, and they also protect angles of intersection. Since horizontal strains are perpendicular to vertical strains, the circles which can be the photographs of the horizontal strains meet the circles which can be the photographs of vertical strains at proper angles.
The horizontal rays within the z airplane
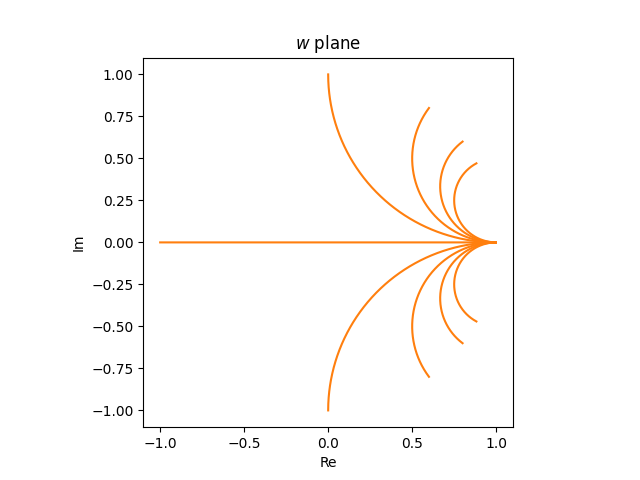
turn out to be partial circles within the w airplane.
If we have been to have a look at horizontal strains reasonably than rays, i.e. if we prolonged the strains into the left half-plane, the photographs within the w airplane could be full circles.
Now let’s put our photos collectively. The grid
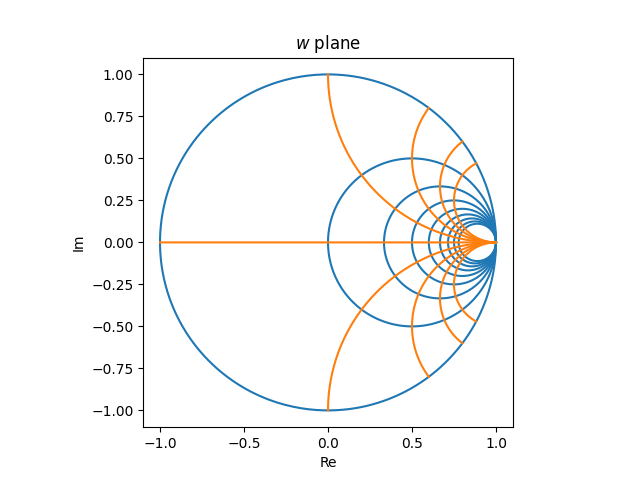
within the z airplane turns into the next within the w airplane.
An evenly spaced grid within the z airplane turns into a really inconsistently spaced graph within the w airplane. Issues are crowded on the suitable hand aspect and sparse on the left. A useable Smith chart must be roughly evenly crammed in, which implies it must be the picture of an inconsistently crammed in grid within the z airplane. For instance, you’d want extra vertical strains within the z airplane with small actual values than with giant actual values.
The journey started in 1912 when Alexis Alexeieff launched a brand new genus for sure amoeboid kinds. He named it Naegleria in honor of Nägler’s analysis on amoebae that endure a biflagellate stage.
The particular pathogen liable for PAM, Naegleria fowleri, was first recognized in 1965 by Malcolm Fowler and Rodney F. Carter in Australia. They recorded the primary human circumstances, highlighting the lethal nature of the an infection.
In 1970, additional analysis utilizing mice helped isolate the pathogen, and it was formally named Naegleria fowleri in honor of Fowler, who recognized the illness from human mind tissue samples.
Milestones
The time period ‘major amoebic meningoencephalitis’ was coined in 1966 by Butt to tell apart this an infection from different sorts of meningoencephalitis.
Through the years, developments in diagnostic instruments have considerably improved our means to detect and perceive PAM. Amoeba cultures cerebrospinal fluid (CSF) and advances in molecular diagnostics, corresponding to polymerase chain response (PCR), immunofluorescence, and enzyme-linked immunosorbent assay (ELISA) enhanced the pace and accuracy of prognosis.
Imaging strategies like CT and MRI scans additionally play an important position in assessing the extent of mind harm.
Cultural influence and consciousness
Naegleria fowleri has not been related to any Nobel Prizes or landmark achievements in drugs, and little has been recognized about it for a very long time.
Nevertheless, this brain-eating amoeba was featured in an episode of the well-known American medical drama ‘Home M.D.,’ which elevated public consciousness of mind an infection and highlighted the damaging nature of the an infection.
As a teaser for our upcoming (2024-07-23) digital studying group session on Bayesian macro / time collection econometrics, this put up replicates a basic paper by Sims & Uhlig (1991) contrasting Bayesian and Frequentist inferences for a unit root. Within the put up I’ll give attention to explaining and implementing the authors’ simulation design. Within the studying group session (and presumably a future put up) we’ll discuss extra concerning the paper’s implications for the Bayesian-Frequentist debate and relate it to more moderen work by Mueller & Norets (2016). We’ll even be joined by particular visitor Frank Schorfheide who will assist information us by the current literature on Bayesian approaches to VARs, together with Giannone et al (2015) and (2019). Should you’re an Oxford scholar or workers member, you may join the studying group right here. In any other case, ship me an electronic mail and I’ll add you manually.
A Easy Instance
To set the stage for Sims & Uhlig (1991), think about the next easy instance: (X_1, X_2, dots X_{100} sim textual content{Regular}(mu, sigma^2)) the place (mu) is unknown however (sigma) is understood to equal (1). Let (bar{X} = frac{1}{100} sum_{i=1}^{100} X_i) be the pattern imply. Then (bar{X} pm 0.2) is an approximate 95% Frequentist confidence interval for (mu). In phrases: amongst 95% of the potential datasets that we might doubtlessly observe, the interval (bar{X} pm 0.2) will cowl the true, unknown worth of (mu); within the remaining (5%) of datasets, the interval won’t cowl (mu).
The Frequentist interval circumstances on (mu) and treats (bar{X}) as random. In distinction, a Bayesian credible interval circumstances on (bar{X}) and treats (mu) as random. This doesn’t require us to consider that (mu) is “actually” random. Bayesian reasoning merely makes use of the language of likelihood to precise uncertainty about any amount that we can’t observe. Let (bar{x}) be the noticed worth of (bar{X}). Beneath a obscure prior for (mu), e.g. a Regular(0, 100) distribution, the 95% Bayesian highest posterior density interval for (mu) is roughly (bar{x} pm 0.2). In phrases: on condition that we have now noticed (bar{X} = bar{x}), there’s a 95% likelihood that (mu) lies within the interval (bar{x} pm 0.2).
The comforting factor about this instance is that, no matter whether or not we select a Bayesian or Frequentist perspective, our inference stays the identical: compute the pattern imply, then add and subtract (0.2). Because of this the Frequentist interval inherits all the great properties of Bayesian inferences, and the Bayesian interval has appropriate Frequentist protection. This equivalence between Bayesian and Frequentist strategies crops up in lots of easy examples, particularly in conditions the place the pattern dimension is giant. However in additional advanced settings, the 2 approaches may give radically completely different solutions. And to move off a standard mis-understanding, this isn’t as a result of Bayesians use priors. Within the restrict as we accumulate increasingly more knowledge, the affect of the prior wanes. The important thing distinction is that Bayesian inference adheres to the chance precept, whereas frequent Frequentist strategies don’t.
A Not-so-simple Instance
Sims & Uhlig think about the AR(1) mannequin [
y_t = rho y_{t-1} + varepsilon_t, quad varepsilon_t sim text{iid Normal}(0, 1)
]
and the conditional most chance estimator given the preliminary (y_0), specifically [
widehat{rho} = frac{sum_{t=1}^T y_{t-1} y_t}{sum_{t=1}^T y_{t-1}^2}.
]
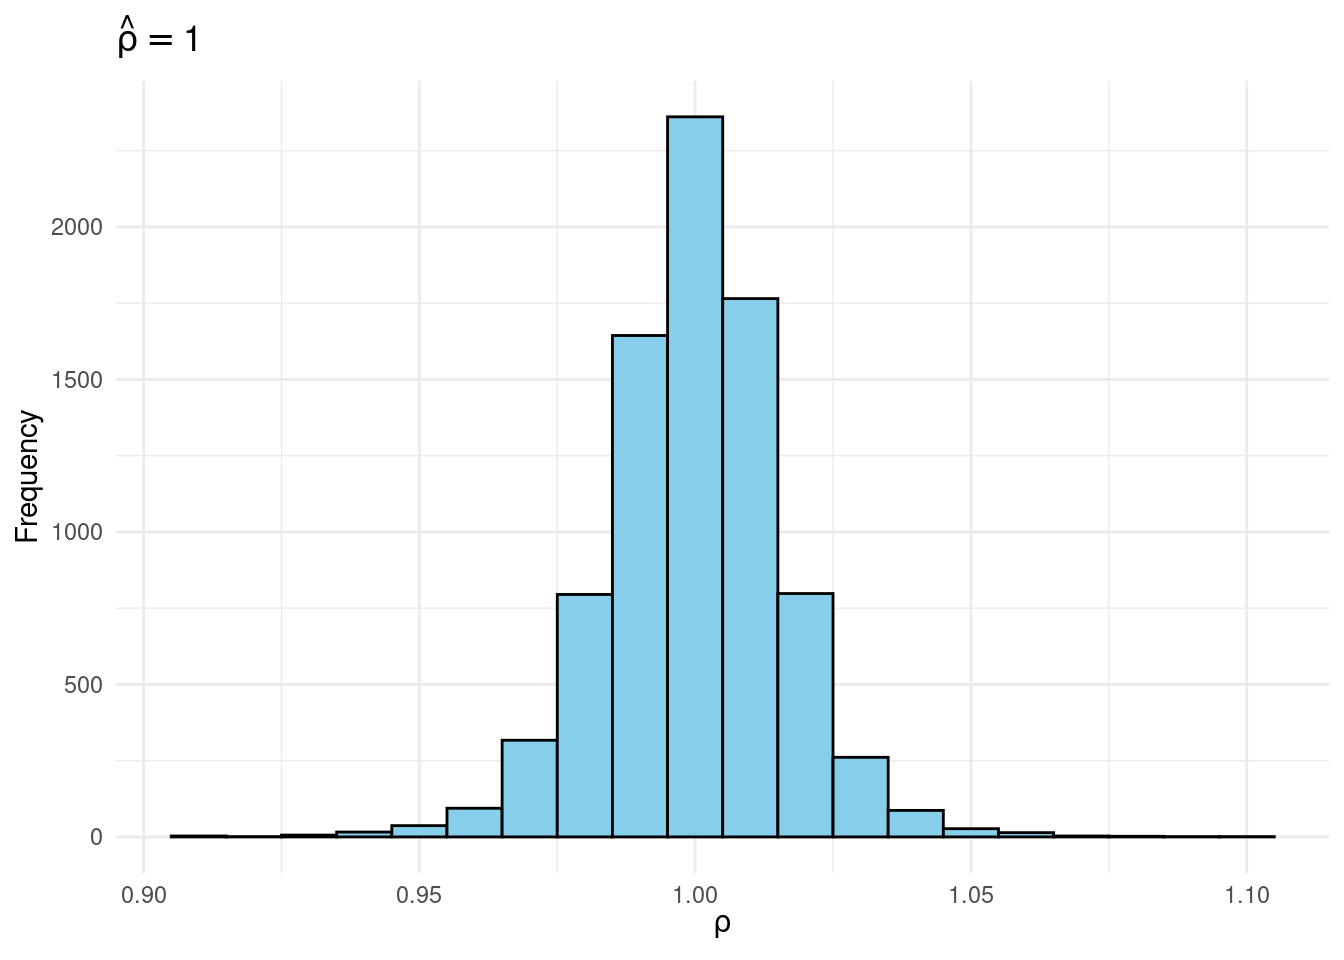
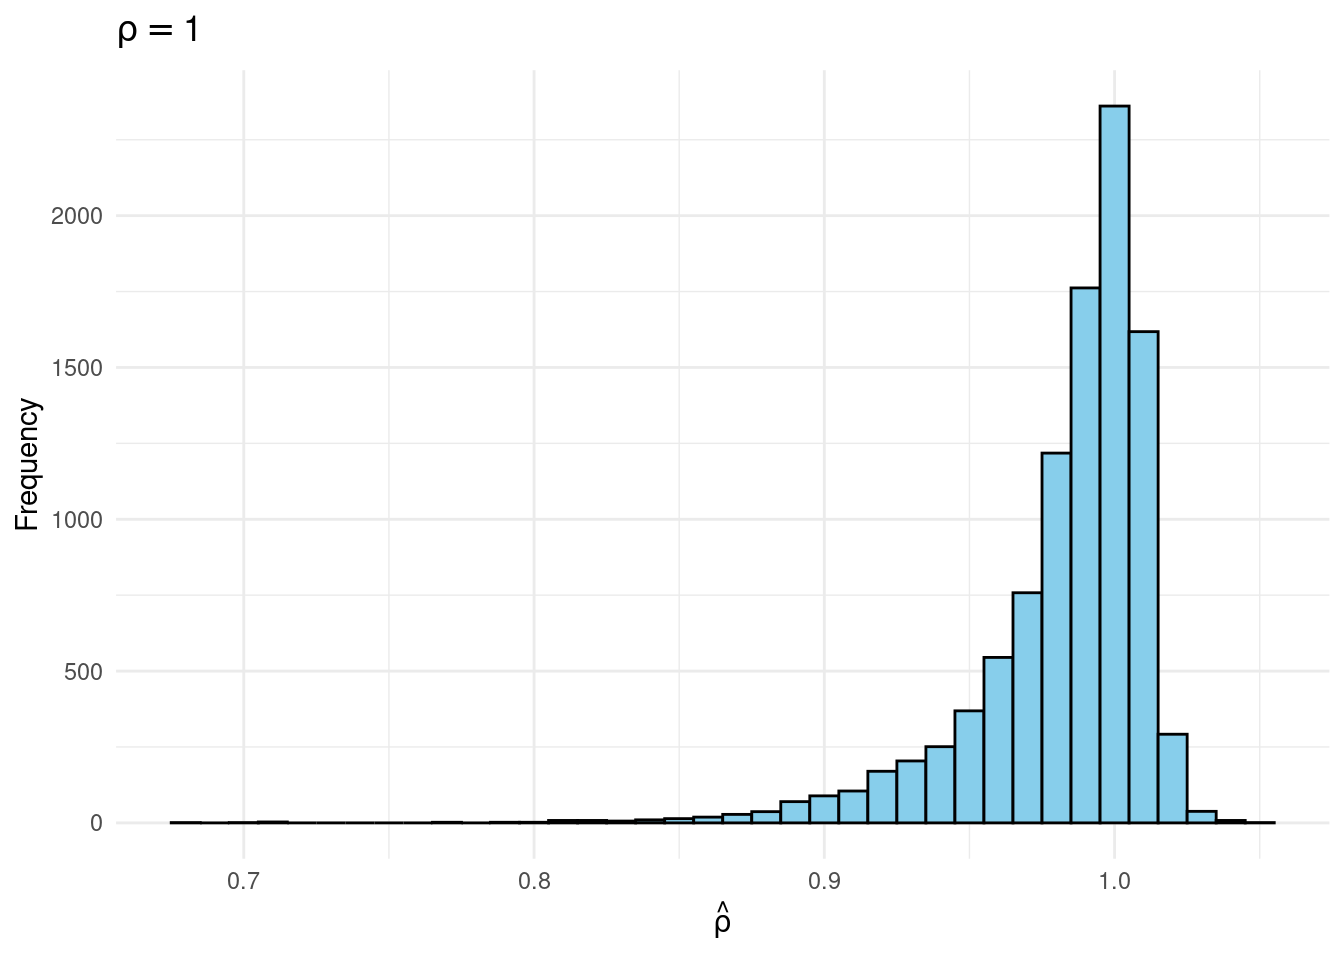
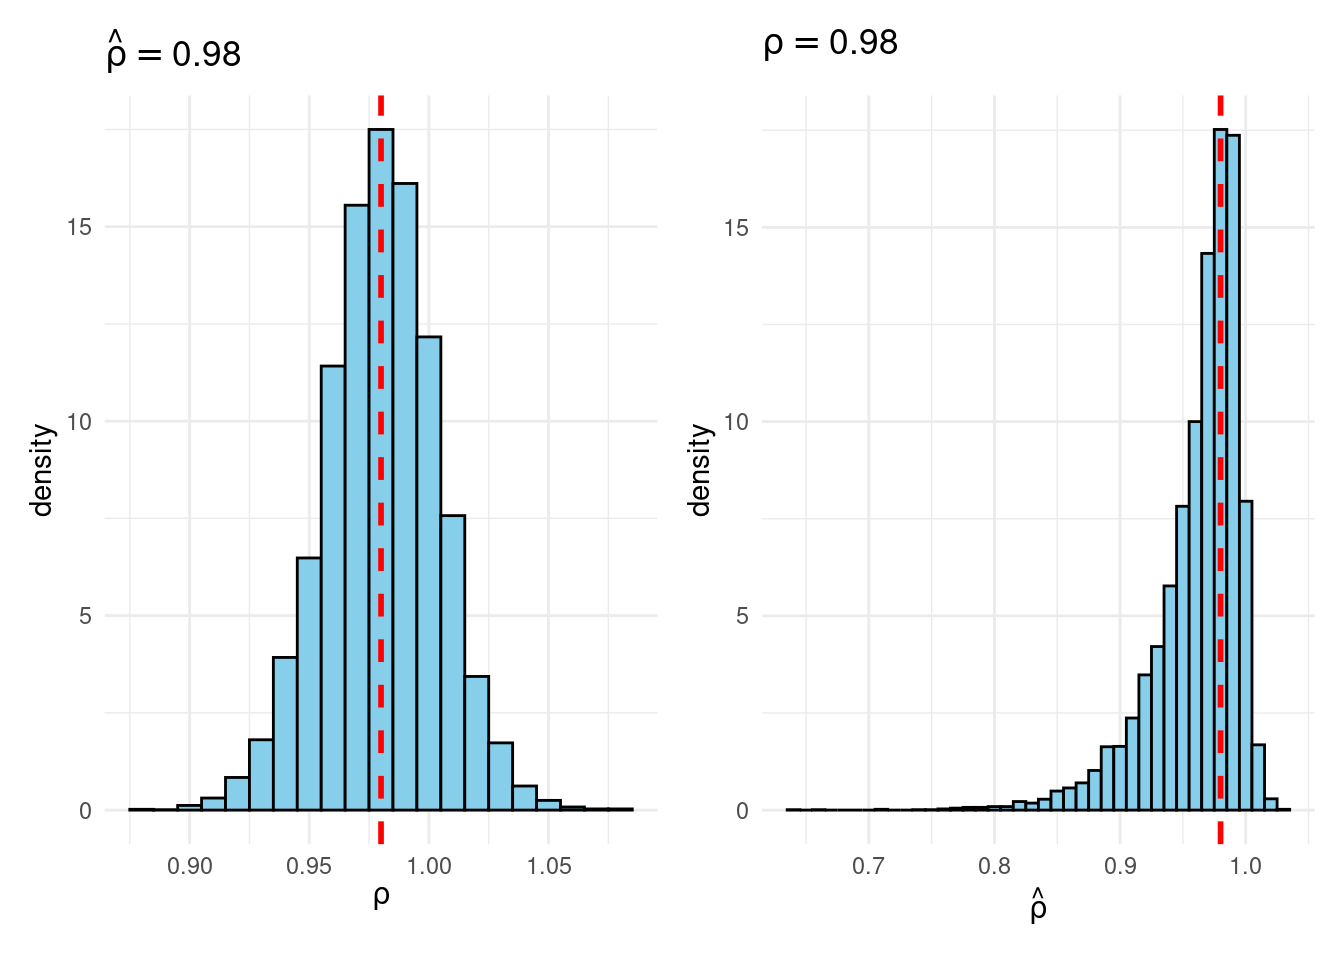
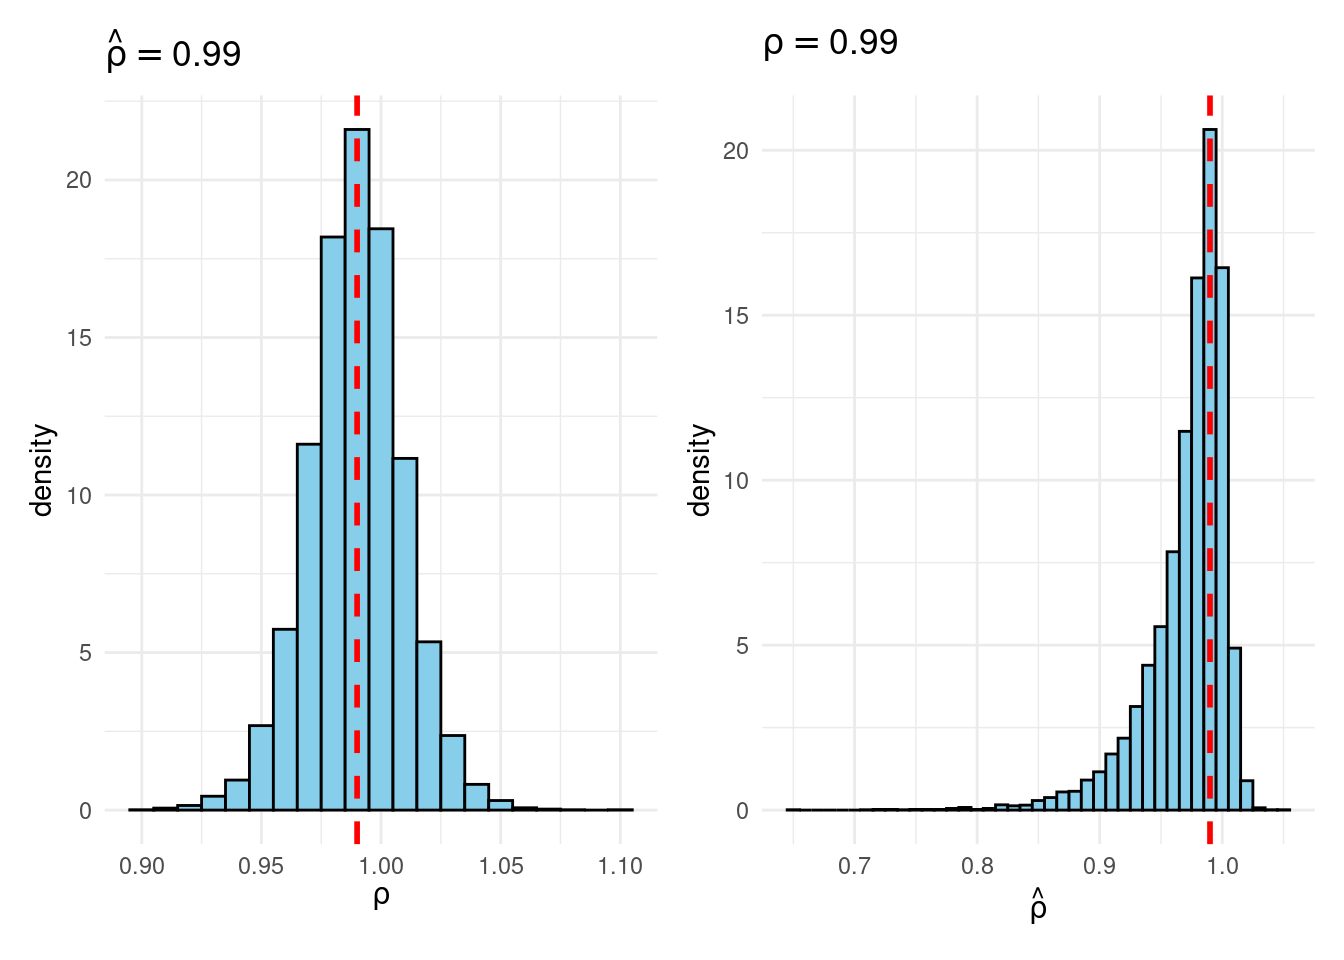
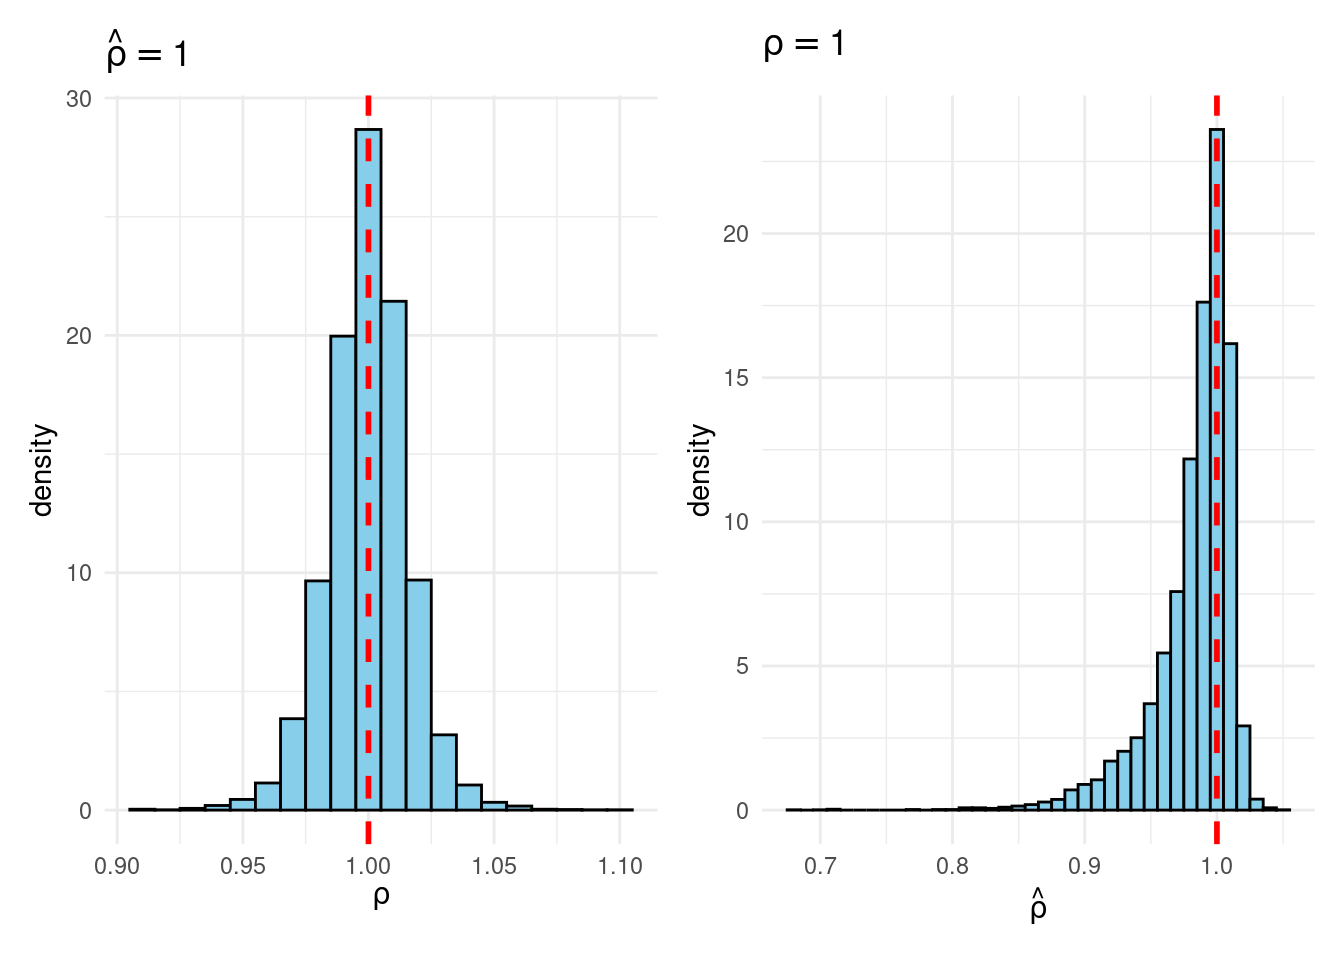
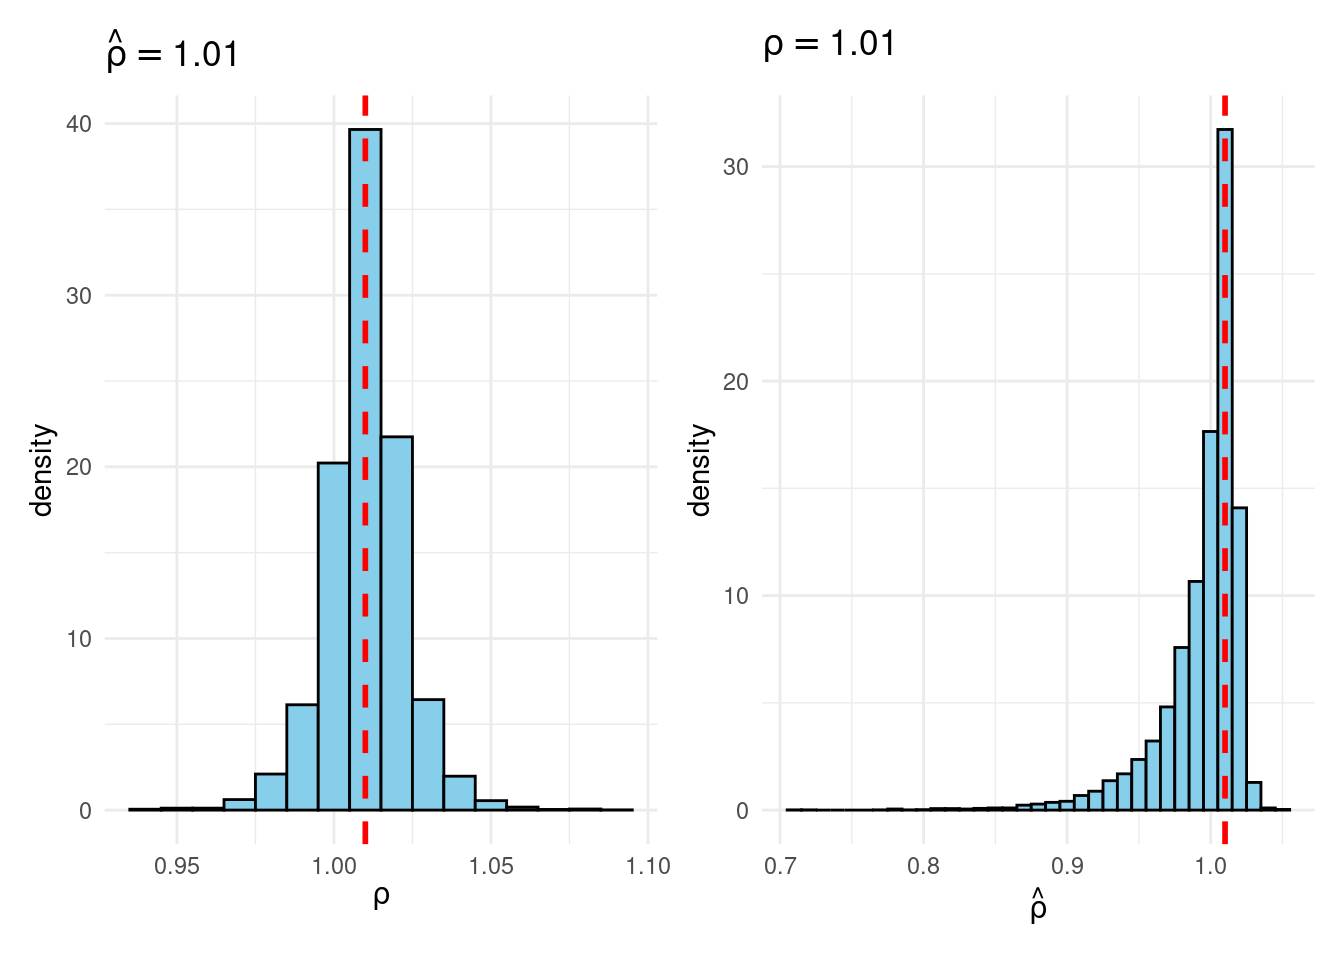
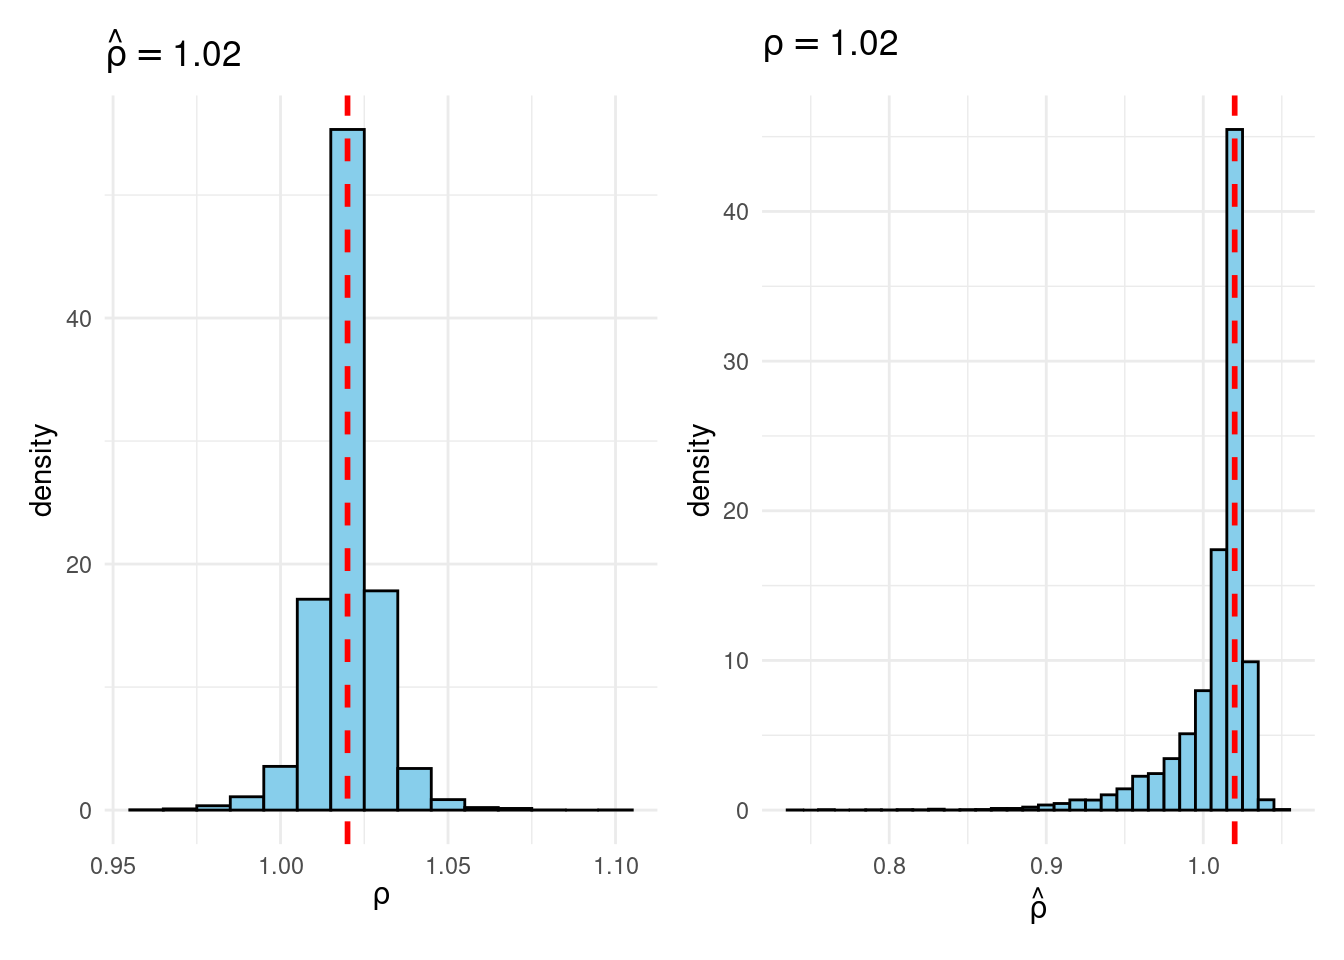
Their simulation contrasts the Frequentist sampling distribution of (widehat{rho}|rho) with the Bayesian posterior distribution of (rho|widehat{rho}) below a flat prior on (rho). When (rho) is close to one, these two distributions differ markedly: whereas the Bayesian posterior is all the time symmetric and centered at (widehat{rho} = widehat{rho}), the Frequentist sampling distribution is very skewed when (rho) is shut to 1. This exhibits that the Bayesian-Frequentist equivalence we present in our easy inhabitants imply instance from above breaks down fully on this extra advanced instance.
Sims & Uhlig argue that the Bayesian posterior gives a way more smart and helpful characterization of the knowledge contained within the knowledge and after studying the paper, I’m inclined to agree. My replication code follows under, together with plots of the joint distribution of ((rho, widehat{rho})) below a uniform prior for (rho) and the conditional distributions (widehat{rho}|rho=1) (Frequentist Sampling Distribution) and (rho|widehat{rho} = 1) (Bayesian Posterior).
The Replication
#-------------------------------------------------------------------------------
# Sims, C. A., & Uhlig, H. (1991). Understanding unit rooters: A helicopter tour
#
# (See additionally: Instance 6.10.6 from Poirier "Intermediate Statistics and 'Metrics")
#-------------------------------------------------------------------------------
# Within the subsequent part we are going to proceed to assemble, by Monte Carlo, an estimated
# joint pdf for rho and hat{rho} below a uniform prior pdf on rho. We select
# 31 values of rho, from 0.8 to 1.1 at intervals of 0.01. We draw 10000 100 x 1
# iid N(0,1) vectors of random variables to make use of a realizations of epsilon. For
# every of the 10000 epsilon vectors and every of the 31 rho values, we
# assemble a y vector with y(0) = 0, y(t) generated by equation (1).
#
# Equation (1): y(t) = rho y(t-1) + epsilon(t), t = 0, ..., T
#
# For every of those y vectors, we assemble hat{rho}. Utilizing as bins the
# intervals [-infty, 0.795), [0.795, 0.805), [0.805, 0.815), etc. we construct
# a histogram that estimates the pdf of hat{rho} for each fixed rho value.
# When these histograms are lined up side by side, they form a surface that is
# the joint pdf for rho and hat{rho} under a flat prior on rho.
#-------------------------------------------------------------------------------
set.seed(1693)

library(tidyverse)
library(tictoc)
library(patchwork)

draw_rho_hat <- function(rho) {
# Carry out the simulation once for a fixed value of rho; return rho_hat
  nT <- 100
  y <- rep(0, nT + 1)
  for (t in 2:(nT + 1)) {
    y[t] <- rho * y[t - 1] + rnorm(1)
  }
  y_t <- y[-1]
  y_tminus1 <- y[-length(y)]
  sum(y_t * y_tminus1) / sum(y_tminus1^2)
}

# Operate to run the simulation for a hard and fast worth of rho (10000 occasions)
run_sim <- (rho) map_dbl(1:1e4, (i) draw_rho_hat(rho))

tic()
foo <- run_sim(0.9)
toc() # ~0.6 seconds on my machine
## 0.595 sec elapsed
# Full sequence of rho values from Sims & Uhlig (1991)
rho <- seq(from = 0.8, to = 1.1, by = 0.01)

tic()
outcomes <- tibble(rho = rho,
                  rho_hat = map(rho, run_sim)) # Listing columns
toc() # ~17 seconds on my machine (1991 was a very long time in the past!)
## 16.814 sec elapsed
# The outcomes tibble makes use of a listing column for rho_hat. That is handy for
# making histograms of the frequentist sampling distribution (rho fastened) however
# not for making histograms of the Bayesian posterior (rho_hat) fastened. For the
# latter, we are going to use the unnest() perform to "develop" the checklist column rho_hat
# into a daily column. That is the "joint" distribution of rho and rho_hat.
joint <- outcomes |>
  unnest(rho_hat)

joint |>
  ggplot(aes(x = rho, y = rho_hat)) +
  geom_density2d_filled() +
  coord_cartesian(ylim = c(0.8, 1.1)) + # Prohibit rho_hat axis
  labs(title = "Joint Distribution",
       x = expression(rho),
       y = expression(hat(rho))) +
  theme_minimal()
# Operate that makes the previous two plots, places them side-by-side and lets
# the person specify the worth of rho/rho_hat that we situation on:
plot_Bayes_vs_Freq <- (r) >
    ggplot(aes(x = rho_hat)) +
    geom_histogram(aes(y = after_stat(density)),
                   binwidth = 0.01, fill = "skyblue", coloration = "black") +
    geom_vline(xintercept = r, coloration = "purple", linetype = "dashed", linewidth = 1) +
    labs(title = bquote(rho == .(spherical(r, 3))),
         x = expression(hat(rho))) +
    theme_minimal()

  p1 + p2


plot_Bayes_vs_Freq(0.98)
We revisit scene-level 3D object detection because the output of an object-centric framework able to each localization and mapping utilizing 3D oriented bins because the underlying geometric primitive. Whereas present 3D object detection approaches function globally and implicitly depend on the a priori existence of metric digicam poses, our technique, Rooms from Movement (RfM) operates on a group of un-posed pictures. By changing the usual 2D keypoint-based matcher of structure-from-motion with an object-centric matcher primarily based on image-derived 3D bins, we estimate metric digicam poses, object tracks, and eventually produce a world, semantic 3D object map. When a priori pose is offered, we will considerably enhance map high quality via optimization of world 3D bins in opposition to particular person observations. RfM reveals sturdy localization efficiency and subsequently produces maps of upper high quality than main point-based and multi-view 3D object detection strategies on CA-1M and ScanNet++, regardless of these international strategies counting on overparameterization via level clouds or dense volumes. Rooms from Movement achieves a normal, object-centric illustration which not solely extends the work of Cubify Something to full scenes but additionally permits for inherently sparse localization and parametric mapping proportional to the variety of objects in a scene.
For hours on Monday, tens of millions of customers and greater than 1,000 corporations discovered themselves unable to hook up with the web. Social media platforms Reddit and Snapchat have been hit, as have been banks Lloyds Financial institution and Halifax. Even youngsters have been affected, with common video games Fortnite and Roblox knocked offline. Sen. Elizabeth Warren (D-Mass.) took to X, describing the occasion as one which broke “the complete web” and calling for a breakup of Massive Tech.
“Networking is definitely a foundational element of AWS providers,” stated Corey Beck, director of cloud applied sciences at DataStrike and a former senior options architect at AWS. “When it stumbles in a area like US-East-1, the results go method past; it ripples by EC2, S3, DynamoDB, RDS, and just about each service that relies on them.”
But for a lot of others, it was enterprise as normal. It is because the outage affected solely AWS prospects — and particular ones at that. The supply of the outage was a DNS failure on the AWS knowledge heart cluster generally known as US-EAST-1. It is the most important of the supplier’s clusters, and one which powers a lot of AWS’s web entry — however not all of it. And any enterprise or particular person who runs Microsoft or Google merchandise was not affected in any respect.
The outage launched mass conversations, starting from the usual narrative on overdependency on single suppliers to the necessity for higher testing protocols earlier than rollout. In a really perfect world, this scale of disruption would by no means occur once more. However CIOs cannot depend on crossed figures and dream eventualities. They should decide what duty is on their shoulders in relation to weathering a future outage — and resolve whether or not the pace and effectivity good points of utilizing a single supplier will outweigh the focus threat of counting on that main cloud vendor.
Whereas politicians mentioned monopolies and customers complained about web site inaccessibility, IT leaders noticed the outage as a name for higher redundancy. The argument is sort of clear: By constructing in backups and failover capability, corporations can unfold out their reliance on anybody level of their infrastructure. To not accomplish that, some specialists argued, could be working on the edge.
“Gamblers would possibly select to threat a core enterprise functionality by working it in a dangerous method,” stated Jon Brown, senior analyst for knowledge safety, IT operations and sustainability at Omdia. “Personally, I might advise on security, because the failure of a poorly protected, high-profile, mission-critical utility can result in a resume-generating occasion, which most of us attempt to keep away from. There’s nothing extra vital than your buyer and transaction knowledge.”
This will appear apparent, however a thousand corporations nonetheless misplaced digital performance on Monday. Why weren’t they higher ready? One reply is that whereas redundancy is not new, it additionally is not very horny. In a discipline filled with innovation and development, redundancy is about slowing down, checking your work, and taking the most secure route. It is not stunning if some corporations are extra enthusiastic about investing in new AI capabilities than implementing failsafe protocols. Neither is it essentially mistaken.
“Generally, the smarter play is to simply accept restricted disruption threat and redirect assets towards innovation, like AI or knowledge modernization,” argued Chris Hutchins, founder and CEO of Hutchins Information Technique Consulting. “Nevertheless it should be an knowledgeable threat, not an assumed one.”
Based on Hutchins, if there are areas of the enterprise that CIOs can afford to pause within the occasion of a uncommon outage, the rewards from single-sourcing — value financial savings, tighter integration and specialised experience — might outweigh the operational threat. Tiago Azevedo, CIO at OutSystems, agreed on the necessity to see this as a monetary calculation, made on a person foundation. Somewhat than being a default requirement, he stated he sees redundancy as a focused resilience funding. CIOs need not defend each inch of their enterprise to the identical diploma, so long as the important thing areas are considerably bolstered.
“The extent ought to mirror system criticality: manufacturing or customer-facing methods benefit multi-region or multi-provider protection, whereas improvement and take a look at environments can tolerate transient downtime,” he stated. “The target is not to remove all threat however to align resilience spending with the potential value of disruption.”
Mapping out the Mission-Crucial
To find out the place CIOs ought to direct redundancy efforts, IT leaders argued that there must be honesty and understanding round what facets of infrastructure are literally elementary to enterprise operations. An outage can occur at any time, each inside inside methods and at any third-party supplier, that means that CIOs cannot delay taking strategic motion.
Over time, an organization could possibly introduce redundancy at a extra complete stage throughout all infrastructure, however this may not take advantage of monetary sense. As Hitchens described it, “redundancy that is not tied to a transparent restoration goal shortly turns into technical debt.” So, it is crucial that CIOs do an audit of their enterprise dependencies, figuring out single factors of failure, and ordering methods primarily based on their influence on operations and belief.
“It is very important make investments the place failure creates actual threat, not simply minor inconvenience, or noise,” he added.
This can look totally different for corporations of various sizes, however significantly for corporations inside totally different sectors. Some industries, equivalent to healthcare or finance, require the next stage of redundancy throughout the board just because the stakes are higher; lack of entry to affected person data or monetary info might have extreme repercussions when it comes to security and public belief, that are far past inconvenience or frustration.
Brown known as out organizations which can be “born within the cloud” as being significantly susceptible, whereas Azevedo stated he noticed extra stress placed on “always-on” industries equivalent to e-commerce. Industries which can be extra extremely regulated may additionally must cope with higher expectations in relation to resilience and redundancy; finance, for instance. The EU not too long ago handed DORA (Digital Operations Resilience Act) to make sure that monetary entities can “face up to, reply to, and get well” from know-how disruptions.
One Supplier, however Diversified Dependencies
Within the wake of the AWS outage, critics have been fast to name for a diversification of web companions, preaching the necessity for stronger and extra quite a few rivals to AWS. And as a part of their redundancy methods, CIOs might want to examine how reliant they’re on particular suppliers, to allow them to decide their threat within the occasion of an outage.
However this is not so simple as tracing third-party contracts, counting how usually one title seems, and shifting some operations away from too-dominant suppliers. If a corporation has partnered predominantly with one supplier, it is in all probability for good purpose. As Hitchens defined, working with a single supplier can speed up innovation and simplify administration, providing visibility, native integrations and unified tooling.
“The profit is effectivity; the danger is dependency,” he stated.
He added that he has no difficulty with CIOs persevering with with single-provider methods — so long as they govern them “with eyes broad open.” In observe, this may increasingly contain constructing portability into knowledge, establishing exit and failover plans, and testing restoration outdoors the ecosystem.
Brown argued that the outage is not actually a touch upon the problem of the only supplier within the first place; if organizations had constructed redundancy into their single-provider ecosystems, they may have averted most of this disruption. It is because a single supplier would not must equate to a single dependency. By using totally different areas and availability zones, CIOs can unfold their threat. In any case, the AWS outage affected solely US-EAST-1. Brown stated he believes that this strategy delivers 99% of the resilience advantages, whereas additionally being considerably extra sensible and cost-effective than a multi-provider technique.
“Cross-provider failover sounds nice on paper, however introduces substantial complexity,” he stated. “The bottom line is architecting for failure inside your chosen ecosystem.”
On this article, we’ll deal with Gated Recurrent Items (GRUs)- a extra simple but highly effective different that’s gained traction for its effectivity and efficiency.
Whether or not you’re new to sequence modeling or trying to sharpen your understanding, this information will clarify how GRUs work, the place they shine, and why they matter in in the present day’s deep studying panorama.
In deep studying, not all information arrives in neat, impartial chunks. A lot of what we encounter: language, music, inventory costs, unfolds over time, with every second formed by what got here earlier than. That’s the place sequential information is available in, and with it, the necessity for fashions that perceive context and reminiscence.
Recurrent Neural Networks (RNNs) have been constructed to sort out the problem of working with sequences, making it doable for machines to observe patterns over time, like how folks course of language or occasions.
Nonetheless, conventional RNNs are likely to lose observe of older data, which might result in weaker predictions. That’s why newer fashions like LSTMs and GRUs got here into the image, designed to higher maintain on to related particulars throughout longer sequences.
What are GRUs?
Gated Recurrent Items, or GRUs, are a kind of neural community that helps computer systems make sense of sequences- issues like sentences, time collection, and even music. In contrast to normal networks that deal with every enter individually, GRUs bear in mind what got here earlier than, which is essential when context issues.
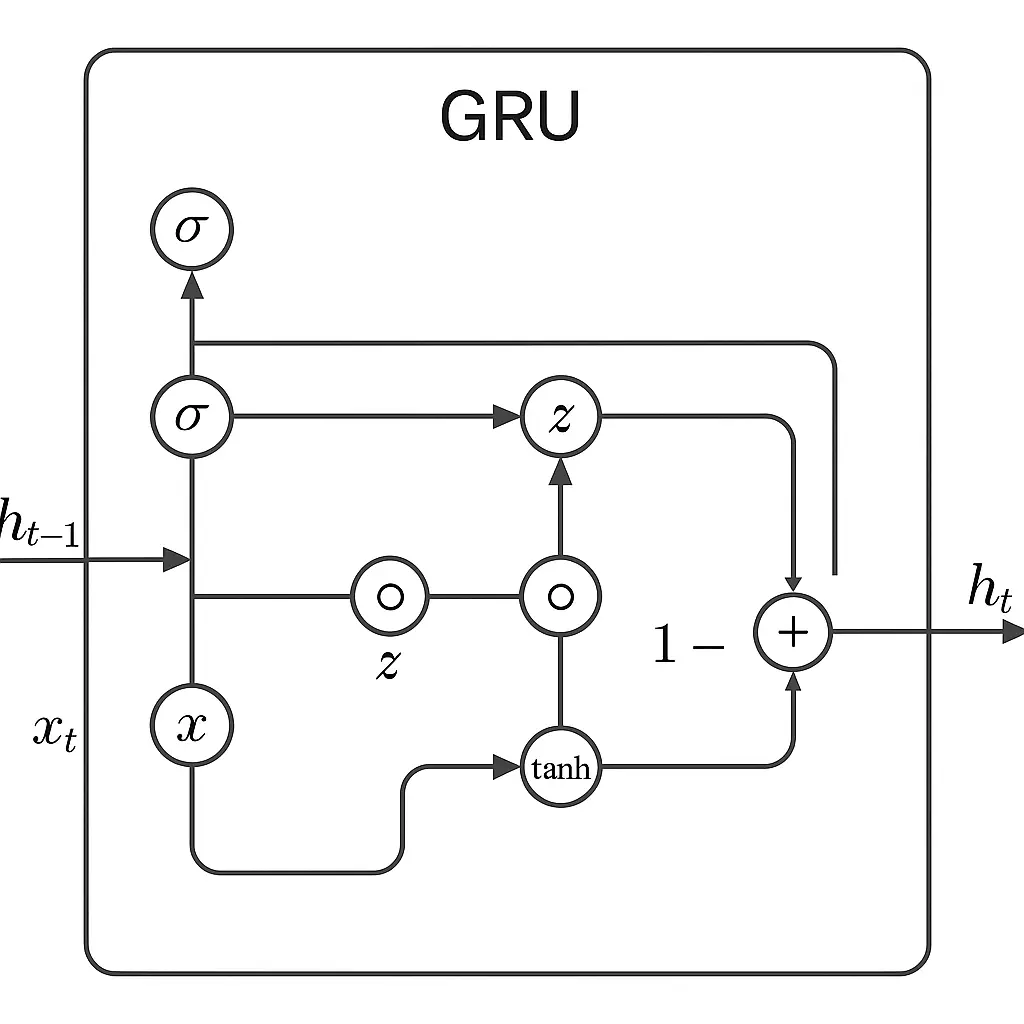
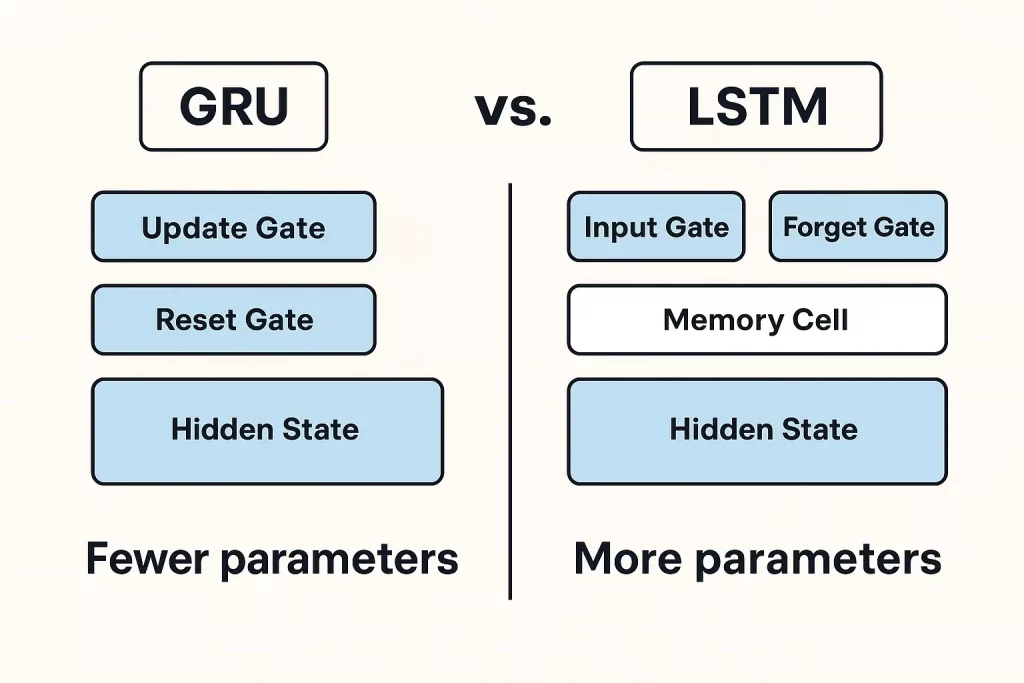
GRUs work by utilizing two major “gates” to handle data. The replace gate decides how a lot of the previous ought to be saved round, and the reset gate helps the mannequin work out how a lot of the previous to overlook when it sees new enter.
These gates permit the mannequin to deal with what’s vital and ignore noise or irrelevant information.
As new information is available in, these gates work collectively to mix the outdated and new neatly. If one thing from earlier within the sequence nonetheless issues, the GRU retains it. If it doesn’t, the GRU lets it go.
This stability helps it study patterns throughout time with out getting overwhelmed.
In comparison with LSTMs (Lengthy Quick-Time period Reminiscence), which use three gates and a extra advanced reminiscence construction, GRUs are lighter and quicker. They don’t want as many parameters and are normally faster to coach.
GRUs carry out simply as effectively in lots of instances, particularly when the dataset isn’t large or overly advanced. That makes them a stable alternative for a lot of deep studying duties involving sequences.
Total, GRUs provide a sensible mixture of energy and ease. They’re designed to seize important patterns in sequential information with out overcomplicating issues, which is a top quality that makes them efficient and environment friendly in real-world use.
GRU Equations and Functioning
A GRU cell makes use of a couple of key equations to resolve what data to maintain and what to discard because it strikes by way of a sequence. GRU blends outdated and new data based mostly on what the gates resolve. This permits it to retain sensible context over lengthy sequences, serving to the mannequin perceive dependencies that stretch throughout time.
GRU Diagram
Benefits and Limitations of GRUs
Benefits
GRUs have a popularity for being each easy and efficient.
One in every of their largest strengths is how they deal with reminiscence. They’re designed to carry on to the vital stuff from earlier in a sequence, which helps when working with information that unfolds over time, like language, audio, or time collection.
GRUs use fewer parameters than a few of their counterparts, particularly LSTMs. With fewer shifting elements, they practice faster and want much less information to get going. That is nice when quick on computing energy or working with smaller datasets.
In addition they are likely to converge quicker. Which means the coaching course of normally takes much less time to succeed in an excellent stage of accuracy. When you’re in a setting the place quick iteration issues, this is usually a actual profit.
Limitations
In duties the place the enter sequence may be very lengthy or advanced, they could not carry out fairly in addition to LSTMs. LSTMs have an additional reminiscence unit that helps them cope with these deeper dependencies extra successfully.
GRUs additionally wrestle with very lengthy sequences. Whereas they’re higher than easy RNNs, they’ll nonetheless lose observe of knowledge earlier within the enter. That may be a problem in case your information has dependencies unfold far aside, like the start and finish of a protracted paragraph.
So, whereas GRUs hit a pleasant stability for a lot of jobs, they’re not a common repair. They shine in light-weight, environment friendly setups, however would possibly fall quick when the duty calls for extra reminiscence or nuance.
Purposes of GRUs in Actual-World Situations
Gated Recurrent Items (GRUs) are being broadly utilized in a number of real-world purposes attributable to their skill to course of sequential information.
In pure language processing (NLP), GRUs assist with duties like machine translation and sentiment evaluation.
These capabilities are particularly related in sensible NLP initiatives like chatbots, textual content classification, or language era, the place the power to grasp and reply to sequences meaningfully performs a central position.
In time collection forecasting, GRUs are particularly helpful for predicting tendencies. Suppose inventory costs, climate updates, or any information that strikes in a timeline
GRUs can choose up on the patterns and assist make sensible guesses about what’s coming subsequent.
They’re designed to hold on to simply the correct quantity of previous data with out getting slowed down, which helps keep away from widespread coaching points.
In voice recognition, GRUs assist flip spoken phrases into written ones. Since they deal with sequences effectively, they’ll modify to totally different talking kinds and accents, making the output extra dependable.
Within the medical world, GRUs are getting used to identify uncommon patterns in affected person information, like detecting irregular heartbeats or predicting well being dangers. They will sift by way of time-based information and spotlight issues that docs may not catch straight away.
GRUs and LSTMs are designed to deal with sequential information by overcoming points like vanishing gradients, however they every have their strengths relying on the scenario.
When to Select GRUs Over LSTMs or Different Fashions
Each GRUs and LSTMs are recurrent neural networks used for the processing of sequences, and are distinguished from one another by each complexity and computational metrics.
Their simplicity, that’s, the less parameters, makes GRUs practice quicker and use much less computational energy. They’re subsequently broadly utilized in use instances the place pace overshadows dealing with massive, advanced reminiscences, e.g., on-line/reside analytics.
They’re routinely utilized in purposes that demand quick processing, resembling reside speech recognition or on-the-fly forecasting, the place fast operation and never a cumbersome evaluation of information is crucial.
Quite the opposite, LSTMs assist the purposes that may be extremely dependent upon fine-grained reminiscence management, e.g. machine translation or sentiment evaluation. There are enter, overlook, and output gates current in LSTMs that improve their capability to course of long-term dependencies effectively.
Though requiring extra evaluation capability, LSTMs are usually most well-liked for addressing these duties that contain intensive sequences and sophisticated dependencies, with LSTMs being knowledgeable at such reminiscence processing.
Total, GRUs carry out greatest in conditions the place sequence dependencies are average and pace is a matter, whereas LSTMs are greatest for purposes requiring detailed reminiscence and sophisticated long-term dependencies, although with a rise in computational calls for.
Way forward for GRU in Deep Studying
GRUs proceed to evolve as light-weight, environment friendly parts in fashionable deep studying pipelines. One main pattern is their integration with Transformer-based architectures, the place
GRUs are used to encode native temporal patterns or function environment friendly sequence modules in hybrid fashions, particularly in speech and time collection duties.
GRU + Consideration is one other rising paradigm. By combining GRUs with consideration mechanisms, fashions acquire each sequential reminiscence and the power to deal with vital inputs.
These hybrids are broadly utilized in neural machine translation, time collection forecasting, and anomaly detection.
On the deployment entrance, GRUs are perfect for edge units and cellular platforms attributable to their compact construction and quick inference. They’re already being utilized in purposes like real-time speech recognition, wearable well being monitoring, and IoT analytics.
GRUs are additionally extra amenable to quantization and pruning, making them a stable alternative for TinyML and embedded AI.
Whereas GRUs might not change Transformers in large-scale NLP, they continue to be related in settings that demand low latency, fewer parameters, and on-device intelligence.
Conclusion
GRUs provide a sensible mixture of pace and effectivity, making them helpful for duties like speech recognition and time collection prediction, particularly when assets are tight.
LSTMs, whereas heavier, deal with long-term patterns higher and go well with extra advanced issues. Transformers are pushing boundaries in lots of areas however include greater computational prices. Every mannequin has its strengths relying on the duty.
Staying up to date on analysis and experimenting with totally different approaches, like combining RNNs and a spotlight mechanisms will help discover the correct match. Structured packages that mix idea with real-world information science purposes can present each readability and route.
Nice Studying’s PG Program in AI & Machine Studying is one such avenue that may strengthen your grasp of deep studying and its position in sequence modeling.
By growing a brand new theoretical relation describing simply how compact neutron stars — that are the remnants of huge stars which have gone supernova — can get, researchers have discovered a method to take a look at the properties of nuclear physics below very excessive circumstances.
Because the collapsed core of a huge star, a neutron star is a small however extremely dense object, packing as much as 3 times the mass of our solar right into a small quantity. Fashions predict that neutron stars are a couple of dozen or so miles throughout, however their actual radius has at all times been unclear.
“Measuring the properties of neutron-star matter is certainly very laborious and it is because whereas we are able to measure the mass of a neutron star very precisely, it is rather laborious to measure its radius precisely,” Luciano Rezzolla, a professor of theoretical astrophysics on the College of Frankfurt, informed House.com.
Rezzolla and his Frankfurt colleague, Christian Ecker, have now made issues slightly clearer with their new research into the compactness of neutron stars.
There are a number of the reason why it is tough to find out the radius of a neutron star. One impediment is that every one the identified neutron stars are very distant, however the principle problem revolves round what physicists name the equation of state. This describes the density and strain inside the inside of a neutron star, from which the radius and different properties may be precisely derived.
The difficulty is, the circumstances inside a neutron star are so excessive that they push our understanding of nuclear physics to the restrict. A spoonful of neutron star materials can weigh billion tons. Beneath that intense strain, atoms are crushed and positively charged protons merge with negatively charged electrons to provide an object stuffed with neutrons.
However on the coronary heart of a neutron star, unique physics could prevail: for instance, “unusual” matter particles known as hyperons could exist, or maybe the immense gravity causes even neutrons to mush collectively and pressure the quark particles they’re constructed from move nearly freely. There is not any method to take a look at any of this, nevertheless, as a result of scientists are unable to copy the circumstances inside a neutron star in a laboratory on Earth. It is simply too excessive.
Breaking house information, the newest updates on rocket launches, skywatching occasions and extra!
So, reasonably than there being one equation of state for neutron stars, there’s a complete listing of attainable equations of state, one for every mannequin describing attainable circumstances inside a neutron star.
To evaluate how compact a neutron star can turn out to be, Rezzolla and Ecker thought of tens of 1000’s of equations of state. To make issues extra manageable, nevertheless, they checked out solely essentially the most huge neutron star attainable in every case.
“A well known end result on the whole relativity is that for every equation of state there’s a most mass allowed,” stated Rezzolla. “Any mass bigger than the utmost mass would result in a black gap. We all know from observations that the utmost mass allowed needs to be someplace between two and three photo voltaic lots.”
Rezzolla and Ecker had been shocked to seek out that an higher restrict exists for the compactness of a neutron star, and that based mostly on this, the ratio between the neutron star’s mass and its radius is at all times smaller than 1/3.
This ratio may be decided due to what are often called geometrized models, that are generally used within the physics of common relativity and permit mass to be expressed in size reasonably than weight.
“As a result of we set an higher restrict on the compactness, we are able to set a decrease restrict on the radius,” stated Rezzolla. “As soon as we measure a neutron star’s mass, let’s imagine that its radius needs to be bigger than 3 times its mass.”
Rezzolla and Ecker additionally discovered that this ratio holds for all equations of state no matter what their most mass is. This would possibly at first appear stunning since one would routinely suppose that essentially the most huge neutron stars can be essentially the most compact as a result of they’d have stronger gravity attempting to make them contract. As an alternative, the unique nuclear physics at play inside neutron stars appears to override this and stability issues out.
The relation is derived partially from the rules of quantum chromodynamics, or QCD, which is the idea of how the sturdy pressure binds particles known as quarks to kind particles reminiscent of neutrons. The sturdy pressure is carried by particles known as gluons (the identify coming from the truth that they glue quarks collectively) and QCD is the quantum area idea that governs them, giving them a quantum quantity whimsically often called “colour cost.”
Rezzolla and Ecker utilized sure normal assumptions based mostly on QCD to derive their compactness relation — they describe it as QCD leaving an “imprint” on the inside construction of neutron stars. Which means that if it ever turns into attainable to measure the radius of a neutron star exactly, then any deviation from this relation can be a giant clue that one thing is amiss with our understanding of QCD.
“If we had been to see a violation of this end result, reminiscent of a neutron star with a compactness better than 1/3, then this may point out that there’s something improper within the QCD assumptions that we have now employed,” stated Rezzolla.
It could be that we can’t have to attend an excessive amount of longer to have the ability to make an correct statement of a neutron star’s radius, whereby this relation and QCD may subsequently be examined. Rezzolla describes the prospects as “optimistic” and cites the NICER (Neutron star Inside Composition Explorer) experiment on the Worldwide House Station, and likewise measurements from gravitational wave occasions, a few of which contain the merger of a black gap with a neutron star. Solely in a single case thus far, GW 170817, have two neutron stars been concerned in a merger.
“If we may solely see extra occasions like GW 170817, we may set a lot tighter constraints on the attainable radii of neutron stars,” stated Rezzolla.
Rezzolla and Ecker’s analysis is revealed in a on the pre-print paper repository arXiv.
Working as an information analyst has at all times concerned a sure sort of knowledge sorcery: discovering sense in numbers. However now, in a decentralized and remote-first world, knowledge analyst jobs have been remodeled. Somewhat than hunkering down along with your crew and a mountain of knowledge, you’re extra more likely to be working throughout time zones, with knowledge retrieved from disparate techniques, below the strain of rapidly approaching deadlines, and with little or no in-person assist.
The top outcome? Analysts are anticipated to supply polished insights on the push of a button, then distill technical output into business-friendly studies and dashboards to make sense to all stakeholders, from executives on video name to coworkers glancing at a PDF replace on their telephones. On the similar time, you’re juggling the technical calls for of the function and gentle abilities mandatory to speak, pivot, and troubleshoot in a hybrid world.
In brief, you’ll want to mix core knowledge analytical experience with a mixture of communication, folks abilities, and contextual understanding to do effectively. That will help you with this, listed here are the important abilities all distant knowledge analysts want.
Key Expertise You Must Thrive as a Distant Information Analyst
Documentation and Reporting Expertise
Working with distant knowledge evaluation, it isn’t sufficient to crunch numbers; it is very important package deal findings right into a report in a approach that’s polished, sharable, and simple for international groups to entry. Easy abilities like understanding how one can convert to PDF format might be extraordinarily highly effective. PDF format helps maintain your studies, charts, and visualizations constant in format and design, whatever the system or working system your crew members use.
Strong documentation practices prolong to crafting well-organized studies, sustaining model management, and leveraging collaborative instruments to maintain stakeholders on the identical web page. With distributed groups, the power to current findings in a cultured, universally accessible format ensures readability and understanding throughout various teams.
Analytical and Crucial Considering Expertise
The subsequent set of abilities to be skilled as an information analyst is sound analytical and significant considering abilities. With the intention to be the very best at your distant job, you want to have the ability to analyze massive units of knowledge after which be capable to spot traits, patterns, and anomalies within the knowledge.
This implies having the ability to ask questions primarily based on the information that’s accessible to you and in addition to give you hypotheses and draw conclusions primarily based on the knowledge you have got in entrance of you. It’s one of these analytical and significant considering that helps a distant knowledge analyst to unravel issues in a approach that’s each logical and systematic, which means the insights you create shall be each actionable and can result in key enterprise selections being made.
Statistical Proficiency
As with every analyst place, a elementary facet of being a distant knowledge analyst is statistical strategies and instruments. The usage of these strategies shouldn’t be misplaced in translation, and also you’ll must know the basics corresponding to regression evaluation, likelihood distributions, and speculation testing, that are the cornerstone of statistical evaluation in the case of making sense of your knowledge for enterprise use.
As for instruments, you’re more likely to see many analysts use software program corresponding to R for statistical evaluation, so this specific programming language is one that can take you far as a distant knowledge analyst. Equally, Python has turn into an information science darling of late because it’s extra versatile and comes with a big ecosystem of knowledge libraries written particularly for it.
Information Administration and Manipulation
Equally essential, an information analyst ought to be an professional in all types of knowledge administration and knowledge manipulation. You ought to be assured in the case of working with databases and know how one can question them to extract the information you want.
To this finish, SQL, or Structured Question Language, is usually used to entry relational databases, and one of these data shall be a must have for anybody pursuing an information analyst profession. Analysts could even spend nearly all of their time simply cleansing and making ready knowledge for evaluation, so know your knowledge wrangling methods and instruments to actually succeed at this job.
Information Visualization Expertise
As a distant knowledge analyst, having nice knowledge visualization abilities can also be a should. After all of the exhausting work of analyzing knowledge units, it’s then essential to speak your findings in a approach that’s each simply comprehensible and consumable in order that non-data of us could make sense of all of it. This implies the power to create efficient charts, graphs, and knowledge dashboards utilizing whichever instrument is at your disposal.
Bear in mind, an information visualization is nearly at all times more practical at speaking than an enormous spreadsheet or desk stuffed with figures. In most company settings the place you’re more likely to see knowledge analysts at work, key stakeholders could or could not have a technical background, so one of these skillset is especially wanted by employers, even when you’re a brand new knowledge analyst.
Communication Expertise are Key
Along with the technical abilities described above, communication abilities are additionally essential. As a distant knowledge analyst, you will have to speak your findings to a variety of audiences, from translating knowledge insights into the top-line enterprise impacts to easily speaking the ‘story’ in a approach that’s straightforward to digest for extra technical of us.
Writing is a key element of this work as effectively, so additionally, you will want to arrange studies/documentation which can be clear and concise. The power to tailor communications to a variety of audiences (assume executives to the advertising crew) is a vital a part of a distant knowledge analyst’s communication function.
Showcasing examples of the place you have got demonstrated to be an excellent listener, sturdy collaborator (understanding a teammate’s tackle a tough dataset or working throughout totally different time zones to achieve a objective) might be an effective way to garner belief/buy-in from key stakeholders.
Downside-Fixing Expertise
Downside-solving abilities are one other key high quality for this distant function. The info units you could encounter as an information analyst could also be incomplete or ambiguous, enterprise priorities can shift rapidly, and the sector of knowledge evaluation itself continues to see new applied sciences/instruments being developed that may change the established order.
Downside-solving abilities are constructed up over time by being curious and experimenting. For instance, you’ll have a lacking knowledge set that you want to work on. You’ll must supply the knowledge from a number of locations, check totally different assumptions and possibly even observe down a coworker in a unique time zone that can assist you discover the information. Repetition of this course of over time can construct up your instinct; you’ll begin to acknowledge frequent patterns, anticipate challenges and discover artistic methods to utilize imperfect knowledge.
Your potential to be versatile, troubleshoot challenges, and discover artistic options as they arrive up is essential to your success on this function. Employers could search for knowledge analyst candidates who can show initiative and take a proactive strategy to problem-solving that leads to constructive outcomes for the enterprise.
Enterprise Understanding
Lastly, an excellent working understanding of your online business or company context might be the defining high quality that helps you stand out as an information analyst working remotely. Information evaluation isn’t carried out in a vacuum, it’s completed with the aim of underpinning and transferring ahead enterprise goals and techniques.
For instance, an information analyst in a retail firm could discover product classes which can be underperforming, but when they’re unaware of timing like seasonal advertising campaigns or stock stocking cycles, their strategies might fall brief. Equally, an information analyst in a healthcare setting should additionally bear in mind affected person workflows, regulatory limitations, or hospital employees rosters to make data-driven suggestions which can be really actionable.
Because of this, being an incredible knowledge analyst additionally means having the subject material data and consciousness of the trade you might be working in, whether or not it’s finance, healthcare, retail, or the general public service. This context lets you body your evaluation in a fashion that’s aligned with related enterprise goals, and may also help you present high-level enterprise insights which can be really helpful.
Thriving as a Distant Information Analyst in a Decentralized World
It’s vital to notice that distant knowledge evaluation goes past crunching numbers and spreadsheets. It additionally wants adaptability, communication, and a concentrate on the bigger goals of a enterprise. By growing technical competencies corresponding to statistical data and knowledge visualization abilities, in addition to gentle skills corresponding to problem-solving and a grasp of enterprise rules, knowledge analysts can have a big impression no matter their location.
Analysts who can hyperlink knowledge to enterprise objectives in a decentralized world shall be in excessive demand. These are the individuals who can rework knowledge into methods and the professionals who’re more than likely to succeed in consequence.
Initially, AI analysis targeted on simulating human pondering, solely sooner. At the moment, we have reached a degree the place AI “pondering” amazes even human consultants. As an ideal instance, DeepMind’s AlphaZero revolutionised chess technique by demonstrating that successful does not require preserving items—it is about attaining checkmate, even at the price of short-term losses.
This idea of “delayed gratification” in AI technique sparked curiosity in exploring reinforcement studying for buying and selling purposes. This text explores how reinforcement studying can remedy buying and selling issues that may be not possible via conventional machine studying approaches.
Stipulations
Earlier than exploring the ideas on this weblog, it’s necessary to construct a powerful basis in machine studying, notably in its utility to monetary markets.
Additionally, overview Unsupervised Studying to know clustering and anomaly detection, essential for figuring out patterns with out labelled information.
Regardless of sounding complicated, reinforcement studying employs a easy idea all of us perceive from childhood. Keep in mind receiving rewards for good grades or scolding for misbehavior? These experiences formed your habits via constructive and detrimental reinforcement.
Like people, RL brokers be taught for themselves to attain profitable methods that result in the best long-term rewards. This paradigm of studying by trial-and-error, solely from rewards or punishments, is called reinforcement studying (RL).
How you can Apply Reinforcement Studying in Buying and selling
In buying and selling, RL will be utilized to varied aims:
Maximising revenue
Optimising portfolio allocation
The distinguishing benefit of RL is its capability to be taught methods that maximise long-term rewards, even when it means accepting short-term losses.
Contemplate Amazon’s inventory value, which remained comparatively secure from late 2018 to early 2020, suggesting a mean-reverting technique may work nicely.
Nevertheless, from early 2020, the worth started trending upward. Deploying a mean-reverting technique at this level would have resulted in losses, inflicting many merchants to exit the market.
An RL mannequin, nevertheless, might recognise bigger patterns from earlier years (2017-2018) and proceed holding positions for substantial future income—exemplifying delayed gratification in motion.
How is Reinforcement Studying Completely different from Conventional ML?
Not like conventional machine studying algorithms, RL does not require labels at every time step. As an alternative:
The RL algorithm learns via trial and error
It receives rewards solely when trades are closed
It optimises technique to maximise long-term rewards
Conventional ML requires labels at particular intervals (e.g., hourly or each day) and focuses on regression to foretell the following candle proportion returns or classification to foretell whether or not to purchase or promote a inventory. This makes fixing the delayed gratification drawback notably difficult via standard ML approaches.
Parts of Reinforcement Studying
This information focuses on the conceptual understanding of Reinforcement Studying parts somewhat than their implementation. For those who’re concerned with coding these ideas, you’ll be able to discover the Deep Reinforcement Studying course on Quantra.
Actions
Actions outline what the RL algorithm can do to resolve an issue. For buying and selling, actions may be Purchase, Promote, and Maintain. For portfolio administration, actions could be capital allocations throughout asset lessons.
Coverage
Insurance policies assist the RL mannequin resolve which actions to take:
Exploration coverage: When the agent is aware of nothing, it decides actions randomly and learns from experiences. This preliminary part is pushed by experimentation—attempting totally different actions and observing the outcomes.
Exploitation coverage: The agent makes use of previous experiences to map states to actions that maximise long-term rewards.
In buying and selling, it’s essential to take care of a stability between exploration and exploitation. A easy mathematical expression that decays exploration over time whereas retaining a small exploratory likelihood will be written as:
Right here, εₜ is the exploration price at commerce quantity t, okay controls the speed of decay, and εₘᵢₙ ensures we by no means cease exploring completely.
Right here,
is the exploration price at commerce quantity t, okay controls the speed of decay, and
ensures we by no means cease exploring completely.
State
The state supplies significant info for decision-making. For instance, when deciding whether or not to purchase Apple inventory, helpful info may embody:
Technical indicators
Historic value information
Sentiment information
Basic information
All this info constitutes the state. For efficient evaluation, the info needs to be weakly predictive and weakly stationary (having fixed imply and variance), as ML algorithms typically carry out higher on stationary information.
Rewards
Rewards signify the top goal of your RL system. Frequent metrics embody:
Revenue per tick
Sharpe Ratio
Revenue per commerce
Relating to buying and selling, utilizing simply the PnL signal (constructive/detrimental) because the reward works higher because the mannequin learns sooner. This binary reward construction permits the mannequin to give attention to persistently making worthwhile trades somewhat than chasing bigger however probably riskier features.
Atmosphere
The surroundings is the world that permits the RL agent to look at states. When the agent applies an motion, the surroundings processes that motion, calculates rewards, and transitions to the following state.
RL Agent
The agent is the RL mannequin that takes enter options/state and decides which motion to take. As an illustration, an RL agent may take RSI and 10-minute returns as enter to find out whether or not to go lengthy on Apple inventory or shut an current place.
Placing It All Collectively
Let’s examine how these parts work collectively:
Step 1:
State & Motion: Apple’s closing value was $92 on Jan 24, 2025. Based mostly on the state (RSI and 10-day returns), the agent offers a purchase sign.
Atmosphere: The order is positioned on the open on the following buying and selling day (Jan 27) and stuffed at $92.
Reward: No reward is given because the commerce continues to be open.
Step 2:
State & Motion: The subsequent state displays the most recent value information. On Jan 27, the worth reached $94. The agent analyses this state and decides to promote.
Atmosphere: A promote order is positioned to shut the lengthy place.
Reward: A reward of two.1% is given to the agent.
Date
Closing value
Motion
Reward (% returns)
Jan 24
$92
Purchase
–
Jan 27
$94
Promote
2.1
Q-Desk and Q-Studying
At every time step, the RL agent must resolve which motion to take. The Q-table helps by exhibiting which motion will give the utmost reward. On this desk:
Rows signify states (days)
Columns signify actions (maintain/promote)
Values are Q-values indicating anticipated future rewards
Instance Q-table:
Date
Promote
Maintain
23-01-2025
0.954
0.966
24-01-2025
0.954
0.985
27-01-2025
0.954
1.005
28-01-2025
0.954
1.026
29-01-2025
0.954
1.047
30-01-2025
0.954
1.068
31-01-2025
0.954
1.090
On Jan 23, the agent would select “maintain” since its Q-value (0.966) exceeds the Q-value for “promote” (0.954).
Making a Q-Desk
Let’s create a Q-table utilizing Apple’s value information from Jan 22-31, 2025:
Date
Closing Value
% Returns
Cumulative Returns
22-01-2025
97.2
–
–
23-01-2025
92.8
-4.53%
0.95
24-01-2025
92.6
-0.22%
0.95
27-01-2025
94.8
2.38%
0.98
28-01-2025
93.3
-1.58%
0.96
29-01-2025
95.0
1.82%
0.98
30-01-2025
96.2
1.26%
0.99
31-01-2025
106.3
10.50%
1.09
If we have purchased one Apple share with no remaining capital, our solely selections are “maintain” or “promote.” We first create a reward desk:
State/Motion
Promote
Maintain
22-01-2025
0
0
23-01-2025
0.95
0
24-01-2025
0.95
0
27-01-2025
0.98
0
28-01-2025
0.96
0
29-01-2025
0.98
0
30-01-2025
0.99
0
31-01-2025
1.09
1.09
Utilizing solely this reward desk, the RL mannequin would promote the inventory and get a reward of 0.95. Nevertheless, the worth is anticipated to extend to $106 on Jan 31, leading to a 9% achieve, so holding could be higher.
To signify this future info, we create a Q-table utilizing the Bellman equation:
The place:
s is the state
a is a set of actions at time t
a’ is a selected motion
R is the reward desk
Q is the state-action desk that is always up to date
γ is the training price
Beginning with Jan 30’s Maintain motion:
The reward for this motion (from R-table) is 0
Assuming γ = 0.98, the utmost Q-value for actions on Jan 31 is 1.09
The Q-value for Maintain on Jan 30 is 0 + 0.98(1.09) = 1.068
Finishing this course of for all rows offers us our Q-table:
Date
Promote
Maintain
23-01-2025
0.95
0.966
24-01-2025
0.95
0.985
27-01-2025
0.98
1.005
28-01-2025
0.96
1.026
29-01-2025
0.98
1.047
30-01-2025
0.99
1.068
31-01-2025
1.09
1.090
The RL mannequin will now choose “maintain” to maximise Q-value. This strategy of updating the Q-table is named Q-learning.
In real-world situations with huge state areas, constructing full Q-tables turns into impractical. To beat this, we are able to use Deep Q Networks (DQNs)—neural networks that be taught Q-tables from previous experiences and supply Q-values for actions when given a state as enter.
Expertise Replay and Superior Methods in RL
Expertise Replay
Shops (state, motion, reward, next_state) tuples in a replay buffer
Trains the community on random batches from this buffer
Advantages: breaks correlations between samples, improves information effectivity, stabilises coaching
Double Q-Networks (DDQN)
Makes use of two networks: major for motion choice, goal for worth estimation
Reduces overestimation bias in Q-values
Extra secure studying and higher insurance policies
Different Key Developments
Prioritised Expertise Replay: Samples necessary transitions extra steadily
Dueling Networks: Separates state worth and motion benefit estimation
Distributional RL: Fashions your entire return distribution as an alternative of simply the anticipated worth
Rainbow DQN: Combines a number of enhancements for state-of-the-art efficiency
Gentle Actor-Critic: Provides entropy regularisation for strong exploration
These methods handle elementary challenges in deep RL, enhancing effectivity, stability, and efficiency throughout complicated environments.
Challenges in Reinforcement Studying for Buying and selling
Kind 2 Chaos
Whereas coaching, the RL mannequin works in isolation with out interacting with the market. As soon as deployed, we do not know the way it will have an effect on the market. Kind 2 chaos happens when an observer can affect the state of affairs they’re observing. Though tough to quantify throughout coaching, we are able to assume the RL mannequin will proceed studying after deployment and alter accordingly.
Noise in Monetary Information
RL fashions may interpret random noise in monetary information as actionable indicators, resulting in inaccurate buying and selling suggestions. Whereas strategies exist to take away noise, we should stability noise discount towards a possible lack of necessary information.
Conclusion
We have launched the basic parts of reinforcement studying methods for buying and selling. The subsequent step could be implementing your personal RL system to backtest and paper commerce utilizing real-world market information.
For a deeper dive into RL and to create your personal reinforcement studying buying and selling methods, take into account specialised programs in Deep Reinforcement Studying on Quantra.
When you’re comfy with the foundational ML ideas, you’ll be able to discover superior reinforcement studying and its function in buying and selling via extra structured studying experiences. Begin with the Machine Studying & Deep Studying in Buying and selling studying monitor, which presents hands-on tutorials on AI mannequin design, information preprocessing, and monetary market modelling.
For these searching for a sophisticated, structured method to quantitative buying and selling and machine studying, the Government Programme in Algorithmic Buying and selling (EPAT) is a superb alternative. This program covers classical ML algorithms (resembling SVM, k-means clustering, choice bushes, and random forests), deep studying fundamentals (together with neural networks and gradient descent), and Python-based technique growth. Additionally, you will discover statistical arbitrage utilizing PCA, various information sources, and reinforcement studying utilized to buying and selling.
Upon getting mastered these ideas, you’ll be able to apply your information in real-world buying and selling utilizing Blueshift. Blueshift is an all-in-one automated buying and selling platform that gives institutional-grade infrastructure for funding analysis, backtesting, and algorithmic buying and selling. It’s a quick, versatile, and dependable platform, agnostic to asset class and buying and selling type, serving to you flip your concepts into investment-worthy alternatives.
Disclaimer: All investments and buying and selling within the inventory market contain threat. Any choice to position trades within the monetary markets, together with buying and selling in inventory or choices or different monetary devices, is a private choice that ought to solely be made after thorough analysis, together with a private threat and monetary evaluation and the engagement {of professional} help to the extent you consider needed. The buying and selling methods or associated info talked about on this article is for informational functions solely.