TL;DR: Get Keeprix All-in-One Streaming Video Downloader lifetime entry for simply $95.99 (reg. $159.99) and obtain movies out of your streaming platforms in as much as 4K for offline viewing.
Keeprix All-in-One Streaming Video Downloader lets you will have that endlessly for a one-time $95.99 (reg. $159.99); For a one-time cost, you get lifetime entry to software program that allows you to obtain movies from a lot of at this time’s hottest streaming platforms and social media websites for offline playback.
Keeprix helps downloads from providers together with Netflix, Amazon Prime Video, Disney+, Hulu, Max, Paramount+, YouTube, and TikTok, saving movies in MP4 or MKV codecs for simple playback by yourself units. It additionally helps resolutions as much as 4K for suitable content material, so your downloads can look simply nearly as good offline as they do on-line.
Past downloading, Keeprix consists of options that make constructing a private media library simpler. Queue up a number of movies with batch processing, handle downloads in a single place, and luxuriate in ad-free offline playback at any time when it’s handy.
Should you’d slightly spend your subsequent flight, commute, or lodge keep watching as an alternative of ready for a connection, that is the way you do it.
A humpback whale photographed in a rowdy group off the coast of Brazil in August 2003 was seen once more in September 2025, this time alone, off japanese Australia. The 2 places sit about 15,100 kilometres aside, and that hole is now the best distance ever recorded between two sightings of the identical humpback whale.
The match is considered one of two described in a research printed in Royal Society Open Science in Might 2026, led by researchers at Griffith College working with groups in Brazil and america. Collectively the 2 whales are the primary onerous proof that people transfer between the japanese Australian and Brazilian breeding populations in each instructions, throughout two ocean basins that lie virtually on reverse sides of the planet.
Two pictures, 22 years aside
The whales weren’t tracked by satellite tv for pc or fitted with tags. They have been recognized the way in which humpback whales have been catalogued for many years, from the underside of their tails.
Each humpback carries a novel association of form, pigment and scarring on the ventral floor of its flukes, the 2 lobes of its tail. A transparent {photograph} of that floor works like a fingerprint. The research drew on 19,283 high-quality fluke pictures collected between 1984 and 2025, taken by skilled researchers and whale-watching passengers alike and pooled by means of Happywhale, a world citizen-science database.
An automatic image-recognition system flagged potential matches throughout the Australian and Brazilian catalogues, and a skilled researcher then confirmed each by eye. Out of practically 20,000 particular person whales, the method turned up simply two that had been photographed on each side of the world.
Every of these two whales already carried a number of identification codes from totally different regional catalogues, a document of what number of separate analysis teams and volunteers had logged the identical animal over time earlier than anybody linked the 2 oceans. The affirmation in every case was checked independently by researchers in each areas.
The record-setter, catalogued as IBJ-1386, was first photographed on 7 August 2003 on the Abrolhos Financial institution off Bahia, Brazil, the nation’s major humpback nursery, in a aggressive group of 9 adults slapping the water. Twenty-two years later, on 22 September 2025, it surfaced alone in Hervey Bay, Queensland, and lifted its tail for a digicam as a whale-watching boat headed again to port.
The second whale was first seen in Hervey Bay in 2007 and once more in 2013, then photographed swimming off São Paulo, Brazil, in 2019. The straight-line distance between these two breeding grounds is about 14,200 kilometres, greater than a 3rd of the way in which across the planet. Each gaps beat the earlier document for a humpback, a 13,046-kilometre separation between Colombia and Zanzibar reported in 2024.
A distance between sightings, not a single swim
The 15,100-kilometre determine is straightforward to misinterpret, and several other early headlines did, calling it the longest whale migration ever recorded. It’s not the size of 1 journey. It’s the great-circle distance between two dots on a map, photographed 22 years aside.
The researchers are specific in regards to the distinction. Picture identification captures solely the place a whale began and the place it ended up, by no means the trail in between. Given the years that handed between sightings, every animal would have accomplished many annual spherical journeys between polar feeding grounds and tropical breeding grounds, so the true distance it swam is unknown and virtually definitely far bigger than the separation on the map. What the research establishes is a document for the way far aside the identical particular person has ever been documented, not a single record-breaking journey.
The intercourse of each whales can be unknown. The 2003 animal was in a aggressive group, a setting most frequently made up of males, however the group didn’t affirm it and warns towards studying the matches as proof of male or feminine wandering. With solely two people and no genetic sexing, the paper leaves that query open.
Why a whale would cross between oceans
The almost definitely rationalization factors south, to Antarctica. Humpbacks from totally different Southern Hemisphere breeding populations feed in overlapping stretches of the Southern Ocean, and a whale that follows an unfamiliar group again north might, in precept, find yourself on a completely new breeding floor, maybe for the remainder of its life.
That concept, the “Southern Ocean Alternate” speculation, was proposed in 2021 to elucidate earlier hints of blending between populations. The brand new Australia-to-Brazil matches match it and stretch it additional, exhibiting the connection can flip up between breeding grounds separated by the widest east-to-west hole between any populated Southern Hemisphere websites.
The authors word {that a} warming Southern Ocean, with shrinking sea ice and shifts within the distribution of Antarctic krill, the whales’ major prey, might make such wanderings extra doubtless over time. They current this as a risk to look at somewhat than a demonstrated trigger. Two whales can’t present a development, and the research doesn’t declare one.
Uncommon sufficient to matter, too uncommon to depend
No matter drives them, these crossings are vanishingly uncommon. Two matches amongst 19,283 whales works out to about 0.01 p.c of recognized people, or roughly one each twenty years within the mixed four-decade dataset. At that price, the exchanges make no measurable distinction to the dimensions of both inhabitants.
They will nonetheless matter biologically. Even an occasional traveller can carry genes between in any other case separate shares, serving to keep genetic variety, and male humpbacks are identified to unfold new music kinds throughout ocean basins a lot as musical traits transfer by means of human populations. A single whale settling in a brand new breeding floor might seed each a gene and a tune.
Each the Brazilian and japanese Australian populations have rebounded strongly since business whaling ended. The Brazilian inventory has grown by an estimated 7 to 10 p.c a yr for the reason that Nineteen Sixties, when looking had reduce it to some p.c of its authentic numbers, and the japanese Australian group reached roughly 24,500 animals by 2015. A bigger, recovering inhabitants produces extra of those uncommon wanderers, which is a part of why long-term picture catalogues are solely now beginning to catch them. Whether or not the crossings develop extra widespread because the Southern Ocean retains altering is the open query, and answering it is going to take the identical sluggish accumulation of tail pictures, contributed by scientists and vacationers alike, that linked these two whales within the first place.
Right now, we announce the supply of Claude Opus 5 on Amazon Bedrock and Claude Platform on AWS. Claude Opus 5 is Anthropic’s most superior Opus mannequin and the primary within the fifth era. It’s a significant step ahead, offering enhancements throughout the workflows that groups run in manufacturing comparable to agentic coding, data work, visible understanding, and long-running duties. In response to Anthropic, Claude Opus 5 matches Claude Fable 5’s top-tier intelligence in lots of domains at Opus-tier pricing.
On Amazon Bedrock, Claude Opus 5 advantages from zero knowledge retention (ZDR) by default, delivering top-tier intelligence with out compromising enterprise knowledge governance. Claude Opus 5 is powered by Bedrock’s next-generation inference engine, letting you construct inside your present AWS setting, preserve enterprise safety and regional knowledge residency, and scale inference with zero operator entry.
Claude Opus 5 can also be out there by Claude Platform on AWS, which helps zero knowledge retention on request and offers you entry to Anthropic’s native platform expertise and capabilities by the AWS Console. Construct, take a look at, and deploy with the identical APIs, options, and console expertise you get working with Anthropic straight, unified with AWS billing and authentication.
This put up covers Opus 5’s enhancements and sensible steering for AI engineers integrating the mannequin into agentic techniques and manufacturing inference workloads on Amazon Bedrock. See the documentation for Claude Platform on AWS.
What makes Claude Opus 5 completely different
In response to Anthropic, Claude Opus 5 delivers a step-change in coding. It understands and navigates codebases like an skilled engineer and writes production-quality code whereas adapting its technique as it really works. It powers reliable long-running brokers that work for hours and even in a single day, discovering paths round obstacles, recovering from errors, and reaching their aims. For skilled work, it brings deeper reasoning to lengthy paperwork and better accuracy to complicated evaluation, with the biggest features on document-heavy enterprise duties. Collectively, this provides as much as frontier functionality at Opus-tier economics.
Use instances
Claude Opus 5 is a robust match for industries the place precision, reliability, and deep reasoning matter most. For monetary companies groups, it powers monetary workflows with deeper reasoning and end-to-end understanding of context. It handles compliance-sensitive work with extra readability and focus. For agent and workflow automation, it pushes again on flawed directions and breaks complicated jobs into sub-agents that want much less oversight. In productiveness work, it handles report constructing and auditing, doc drafting, and structured evaluation with excessive consistency. It runs multi-day tasks and produces professional-grade outputs.
Claude Opus 5 additionally improves on Claude Opus 4.8’s cyber capabilities throughout the board, from coding to cyber safety. In higher-risk areas, Opus 5 might fall again to Opus 4.8. Customers are notified when this occurs, and fallbacks may be configured when utilizing the APIs.
Getting began with Claude Opus 5 on Amazon Bedrock
Anthropic SDK put in: pip set up anthropic[bedrock]
IAM permissions: bedrock:InvokeModel, bedrock:InvokeModelWithResponseStream, and bedrock:CreateInference
Right here’s a fast instance utilizing the AWS SDK for Python (Boto3):
import boto3
import json

# Create a Bedrock Runtime consumer
bedrock_runtime = boto3.consumer(
    service_name="bedrock-runtime",
    region_name="us-east-1"
)

# Invoke Claude Opus 5
response = bedrock_runtime.invoke_model(
    modelId="world.anthropic.claude-opus-5",
    contentType="software/json",
    settle for="software/json",
    physique=json.dumps({
        "anthropic_version": "bedrock-2023-05-31",
        "max_tokens": 4096,
        "messages": [
            {
                "role": "user",
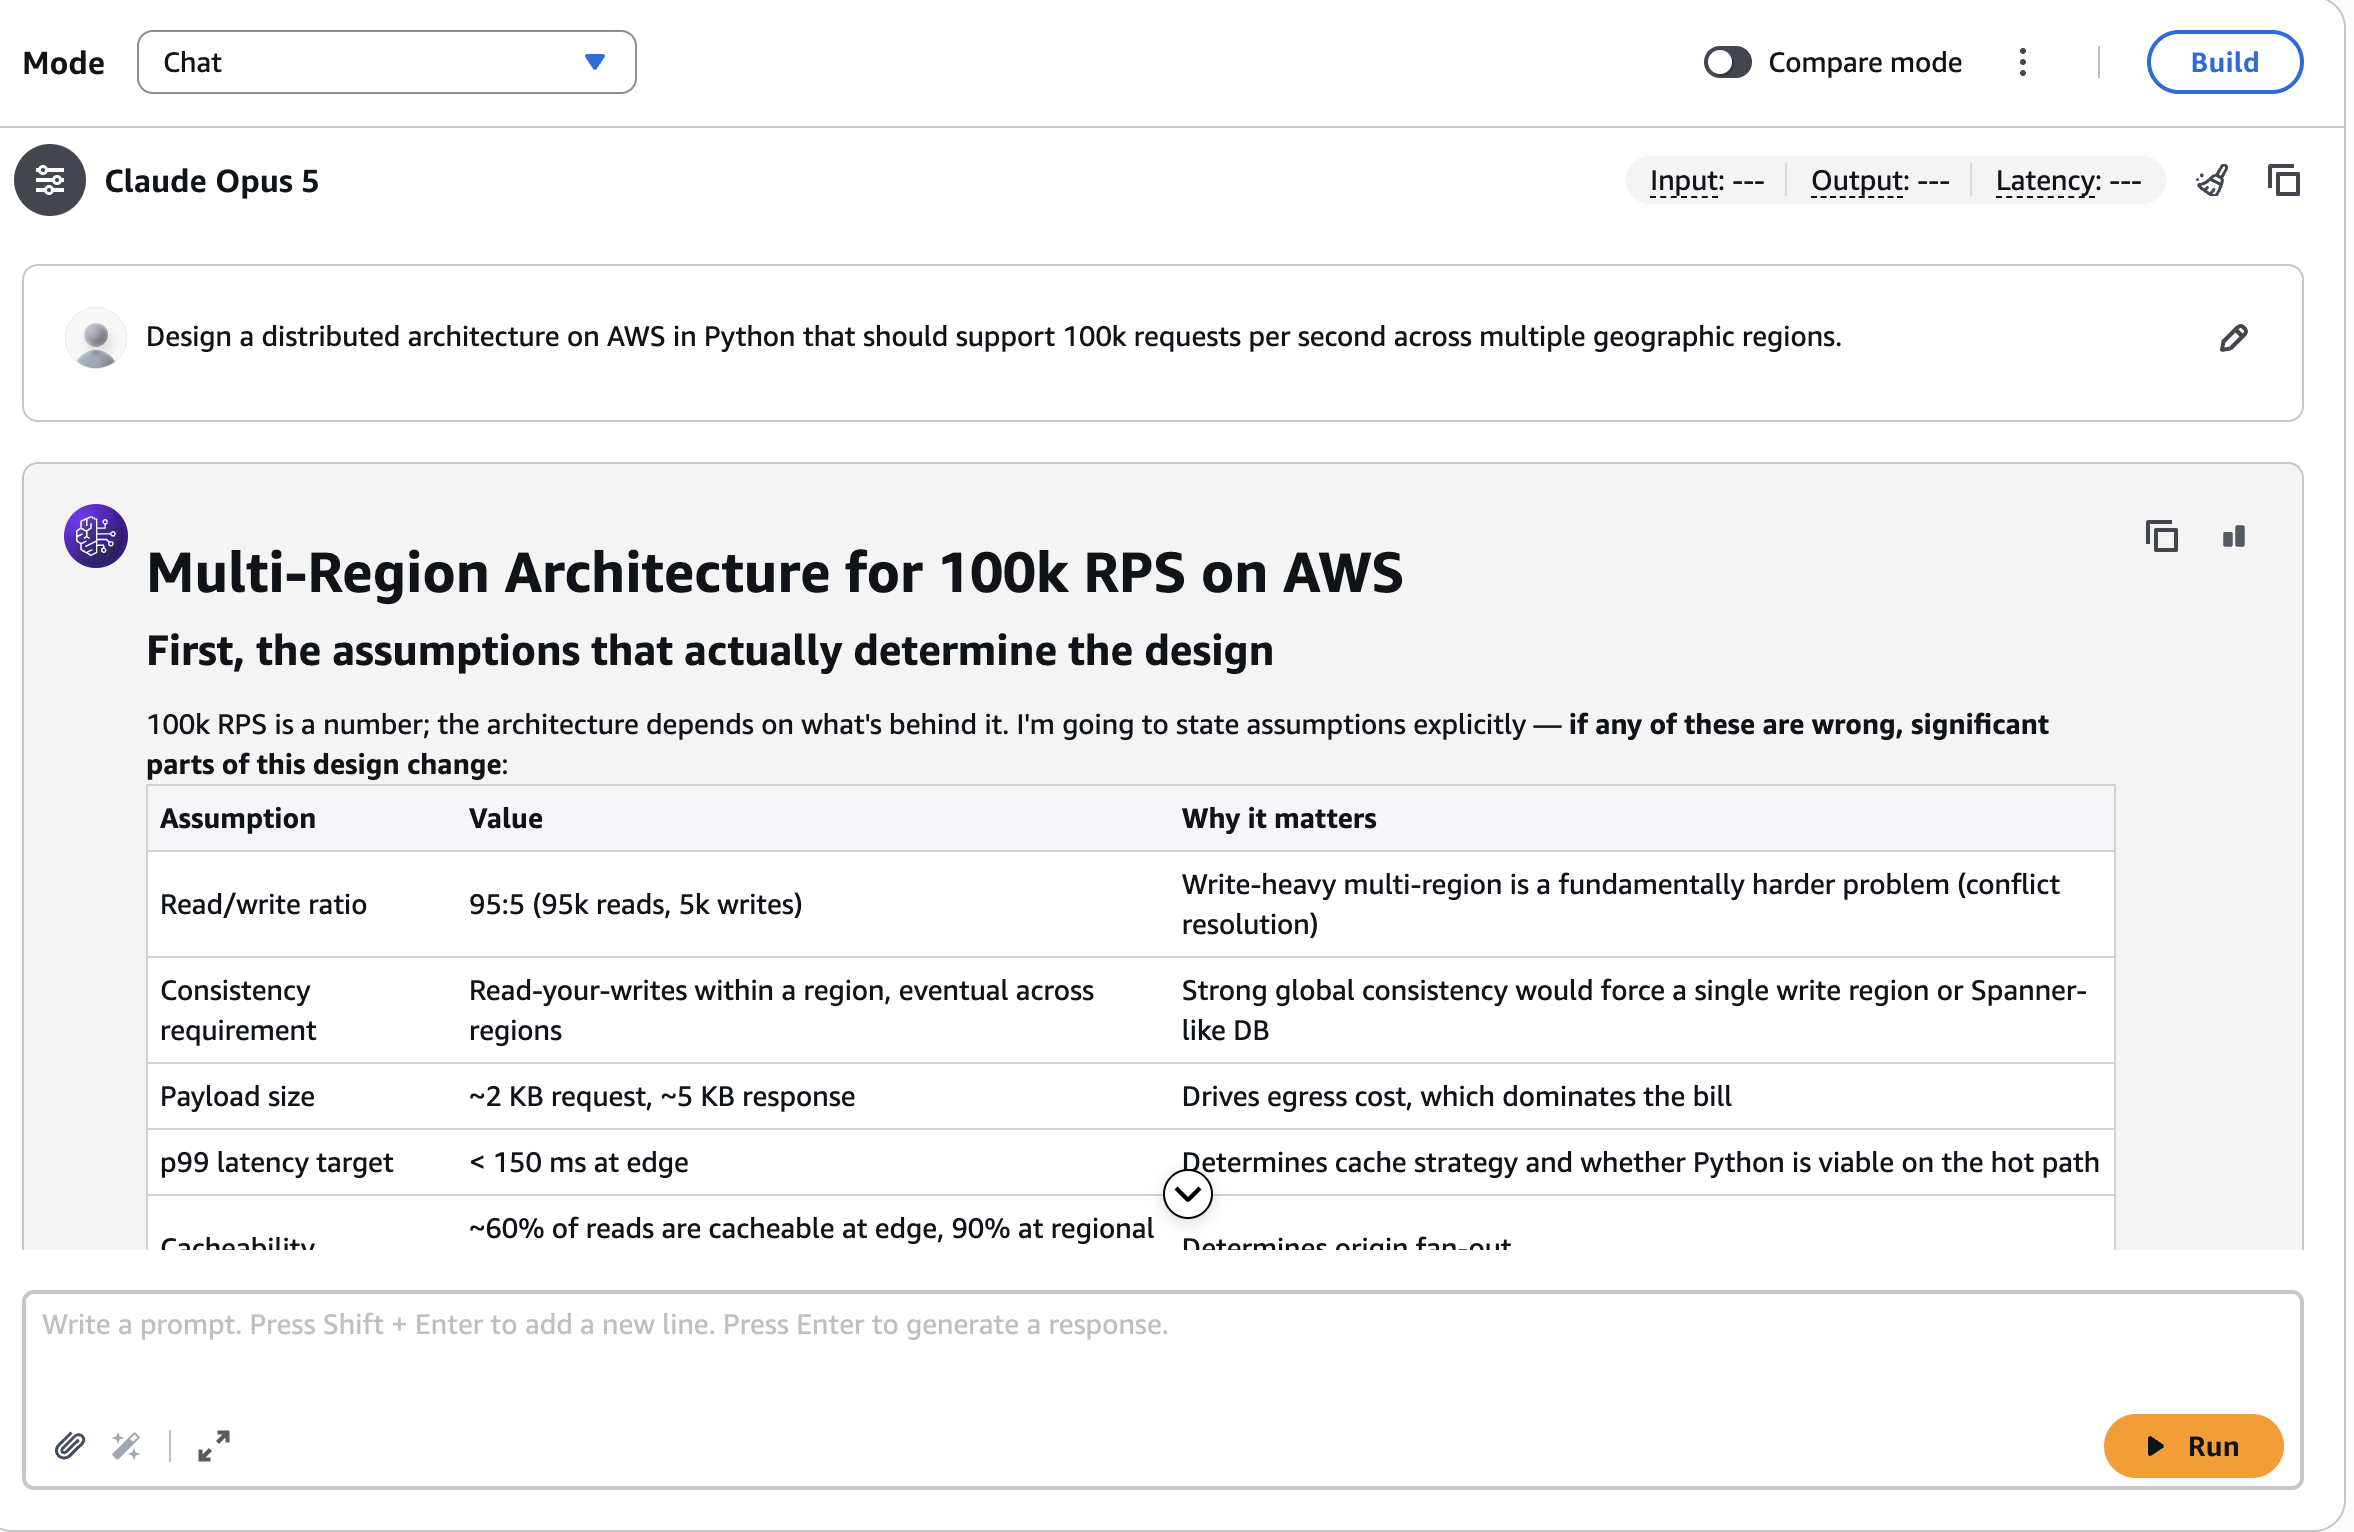
                "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions."
            }
        ]
    })
)

end result = json.masses(response["body"].learn())
print(end result["content"][1]["text"])
You too can use Claude Opus 5 with the Amazon Bedrock Converse API for a unified multi-model expertise:
import boto3

bedrock_runtime = boto3.consumer("bedrock-runtime", region_name="us-east-1")

response = bedrock_runtime.converse(
    modelId="world.anthropic.claude-opus-5",
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "text": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions."
                }
            ]
        }
    ],
    inferenceConfig={
        "maxTokens": 4096
    }
)

if 'output' in response:
    blocks = response['output']['message']['content']
    print('n'.be a part of(b.get('textual content', '') for b in blocks if 'textual content' in b))
You too can use Claude Opus 5 with the Anthropic Messages API utilizing the anthropic[bedrock] SDK bundle for a streamlined expertise:
from anthropic import AnthropicBedrockMantle

# Initialize the Bedrock Mantle consumer (makes use of SigV4 auth routinely)
mantle_client = AnthropicBedrockMantle(aws_region="us-east-1")

# Create a message utilizing the Messages API
message = mantle_client.messages.create(
    mannequin="anthropic.claude-opus-5",
    max_tokens=4096,
    messages=[
        {"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions"}
    ]
)

print(message.content material[1].textual content)
Claude Opus 5 helps including and eradicating instruments mid-conversation by tool_addition and tool_removal content material blocks on function: "system" messages, as a substitute of re-sending the complete top-level instruments array. See Bedrock documentation for extra particulars.
Availability
Claude Opus 5 is on the market as we speak on Amazon Bedrock in Areas together with US East (N. Virginia), Asia Pacific (Melbourne), Europe (Eire), and Europe (Stockholm). See Bedrock documentation for the complete record of supported Areas. Claude Opus 5 can also be out there on the Claude Platform on AWS in North America, South America, Europe, and Asia Pacific.
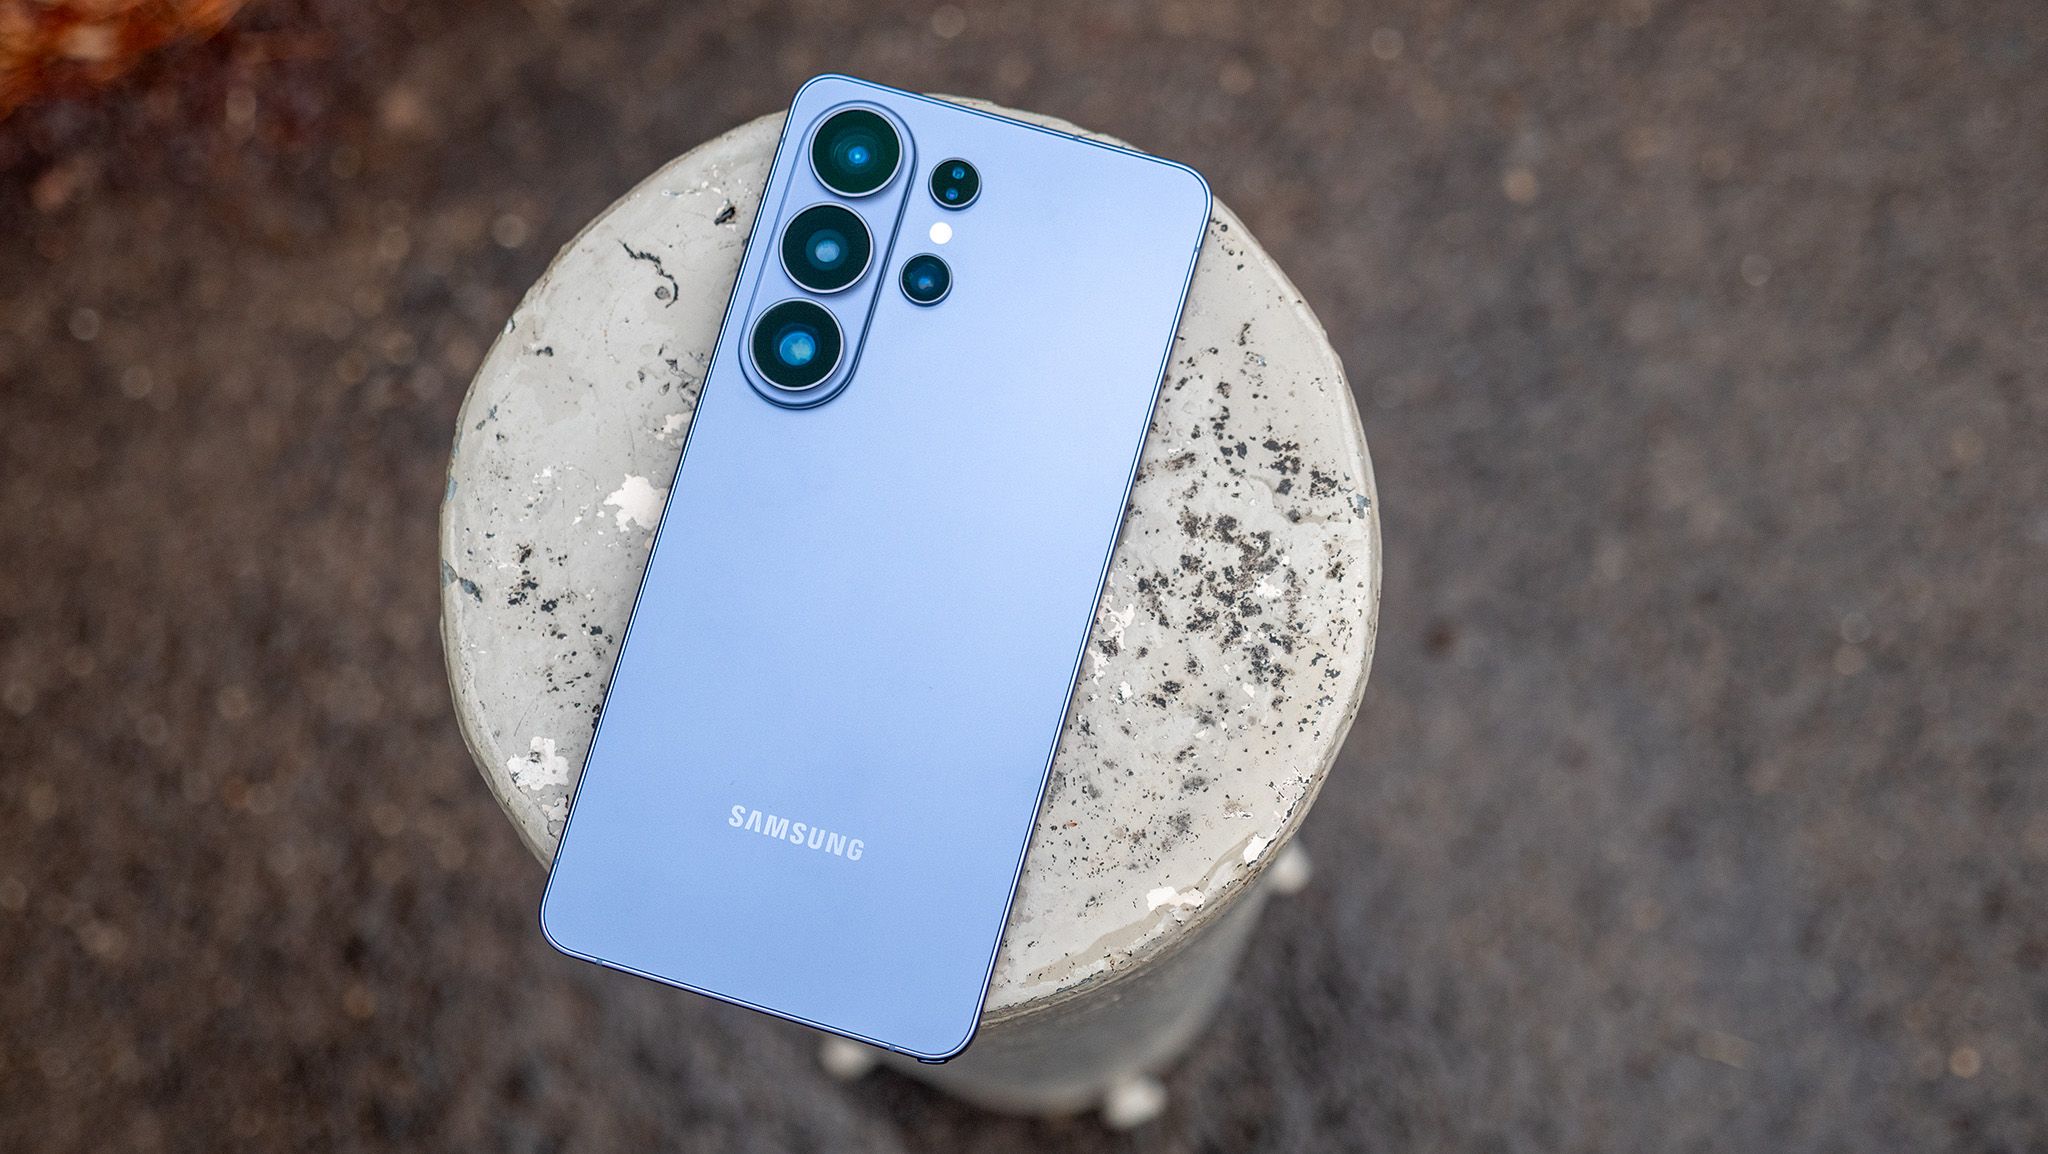
Rumors declare the Galaxy S27 and S27 Plus are being “examined” with a Sony digicam sensor, not Samsung’s ISOCELL.
Whereas this modification has been alleged, the sensor would possibly solely ship 50MP to the primary lenses for each telephones.
One other rumor claims that Samsung is testing silicon-carbon battery tech for the Galaxy S27 collection after delivering it for its 2026 foldables.
Samsung has had an eventful week with Galaxy Unpacked dropping main reveals. Settling again into issues, rumors are surfacing about its subsequent flagship telephone upgrades.
Rumors have began from a few totally different sources this week. The primary stems from Galaxy Membership (Dutch), claiming the Galaxy S27 and Galaxy S27 Plus might obtain digicam tech from a brand new firm (through GSMArena). Samsung usually swaps its in-house Exynos chips for Qualcomm when its telephones launch in different markets (markets that are not Korea or Europe). Now, rumors declare Samsung would possibly forgo its digicam sensor, ISOCELL, in favor of Sony’s.
The publication cites data from an unnamed supply, stating this swap to Sony is being “examined” for the S27 and S27 Plus’ predominant sensor. Early assessments present this sensor would arrive as 50MP, and that is provided that testing goes effectively and we see this by means of to fruition. Galaxy S27 rumors do not finish there, as tipster Lanzuk on Naver (Korean) states the telephones might get a well-recognized battery improve.
Newest Movies FromAndroid Central
Lanzuk claims silicon-carbon battery tech is at present “present process utility testing” for Samsung’s subsequent telephones. Whereas it is easy to get excited early, Lanzuk says there are nonetheless a variety of transferring components. For one, the battery capability has supposedly not elevated. Nevertheless, this may very well be as a result of collection’ early levels, as “nothing is finalized.”
Adjustments aplenty
(Picture credit score: Nicholas Sutrich / Android Central)
Digital camera rumors have not been shy about Samsung’s S27 collection. Particularly, there have been studies about the Galaxy S27 Extremely’s modifications, which say it might sport an ISOCELL HP6 sensor. Whereas that is an “improve,” the machine was nonetheless rumored to supply 200MP with this newer sensor. Let’s not overlook in regards to the alleged “Galaxy S27 Professional.” Phrase has it that Samsung might roll out 4 Galaxy S collection telephones subsequent 12 months, with the “Professional” being the brand new child on the block.
The S27 Professional might function cameras nearer to the Extremely expertise, however with “solely new sensors” to modify issues up. The battery rumor for the S27 collection is attention-grabbing. We have heard rumors about Samsung probably “catching up” to its competitors with higher, larger batteries. After all, we’re speaking about silicon-carbon batteries, however nothing’s for sure. What is sure—good to see, too—is that Samsung’s newest foldables rock this new tech.
Android Central’s Take
It looks like we’re transferring into a singular timeline for Samsung. Its foldables have gotten a battery improve we have been ready on. It might’ve been higher—cell capability, in fact. Samsung remains to be fairly far underneath its competitors. I suppose having silicon-carbon tech is best than not.
Get the most recent information from Android Central, your trusted companion on the earth of Android
Breakthroughs, discoveries, and DIY suggestions despatched six days every week.
By signing up, you affirm you’re 16+, will obtain newsletters and promotional content material and conform to our Phrases of Use and acknowledge the information practices in our Privateness Coverage. You might unsubscribe at any time.
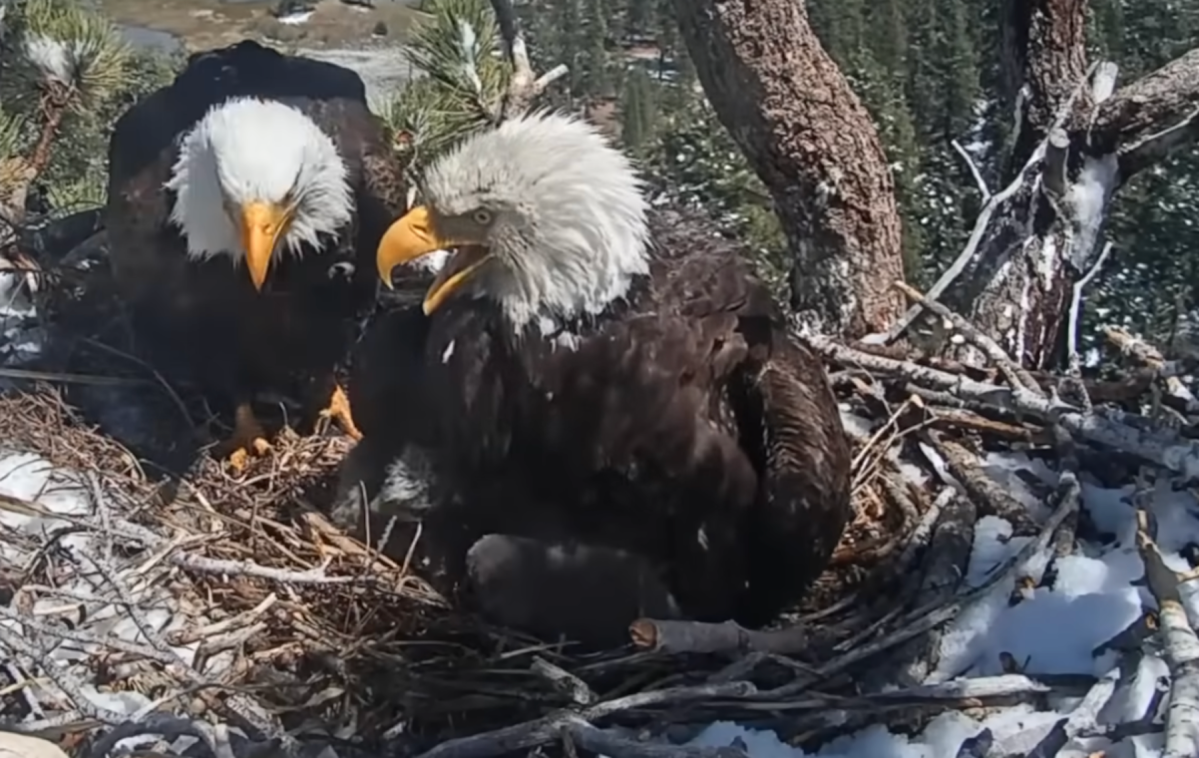
The land bald eagles Jackie and Shadow depend on for survival will stay intact. On Friday, Mates of Large Bear Valley (FOBBV), the non-profit behind the pair’s 24/7 dwell cam, introduced that they reached a objective of elevating $10 million to buy land round Large Bear Lake within the San Bernardino Mountains.
A $5.5 million donation from Anna and Greg Brockman pushed the fundraiser to its objective forward of a July 31 deadline. Greg Brockman is the co-founder and President of OpenAI, the corporate behind ChatGPT. Earlier than the Brockmans’ donation, greater than 25,000 donations had raised virtually half of the mandatory funds.
7-24-26 Moon Camp: GOAL MET
“Greg and I are grateful to all those that championed saving the house of those majestic eagles, Jackie and Shadow,” Anna Brockman mentioned in an announcement. “Like many individuals world wide, we love watching them be superb companions to 1 one other and lift their younger. They encourage perseverance and a way of connectedness to one thing better, to nature. We’re proud to be supportive. We’re so appreciative of the San Bernardino Mountains Land Belief and everybody who got here collectively to protect this unbelievable ecosystem, the life it’s going to assist maintain, and the forest that might be protected for generations to come back.”
The land that might be bought with the $10 million is called Moon Camp. This stretch of land has been a goal of luxurious housing and marina builders for greater than 20 years. The land sits lower than a mile from Jackie and Shadow’s nest, and borders a part of the lake that’s dwelling to all the fish that the eagles and their chicks depend on for sustenance. It additionally homes an undisturbed forest that helps birds, squirrels, and different animals, in addition to the ash-gray indian paintbrush (Castilleja cinerea), a uncommon and threatened endemic plant solely discovered right here.
Buying Moon Camp was a ardour undertaking for Sandy Steers, FOBBV’s former govt director and fierce advocate for Jackie and Shadow. Steers died on February 11 after a battle with most cancers. She was life-long wildlife activist, and helped launch the livecams again in 2015 and in addition served as FOBBV’s resident bald eagle professional.
Steers and the San Bernardino Mountain Land Belief negotiated a restricted buy settlement with the land’s proprietor, developer RCK Properties, earlier this 12 months.
“Sandy handed away proper after the settlement was signed, so we’re doing this in her honor,” Jenny Voisard, media supervisor for FOBBV, instructed Standard Science earlier this 12 months. “She put all of that on her shoulders as a result of she needed to save lots of every part.”
“We’re past grateful for the tireless help of so many individuals these previous six months,” Voisard mentioned. “It is a particular group that has an actual love for Jackie and Shadow’s wellbeing together with nature.”
Whereas information of the fundraiser is joyful for the hundreds of people that have tuned into watch Jackie and Shadow through the years, it comes at a worrisome time for the bald eagle pair. Mother Jackie is presently at a rehabilitation heart in Ojai, California, after being discovered injured following an altercation with two subadult bald eagles. Dad Shadow has been caring for his or her 2026 eaglets, Luna and Sandy, on his personal since Jackie’s rescue. The chicks will probably absolutely fledge within the coming weeks.
Disclosure: Ziff Davis, Standard Science’s mum or dad firm, filed a lawsuit towards OpenAI in April 2025, alleging it infringed Ziff Davis copyrights in coaching and working its AI techniques.
2026 Standard Science Residence of the Future Awards
39 merchandise that may enhance your on a regular basis life.
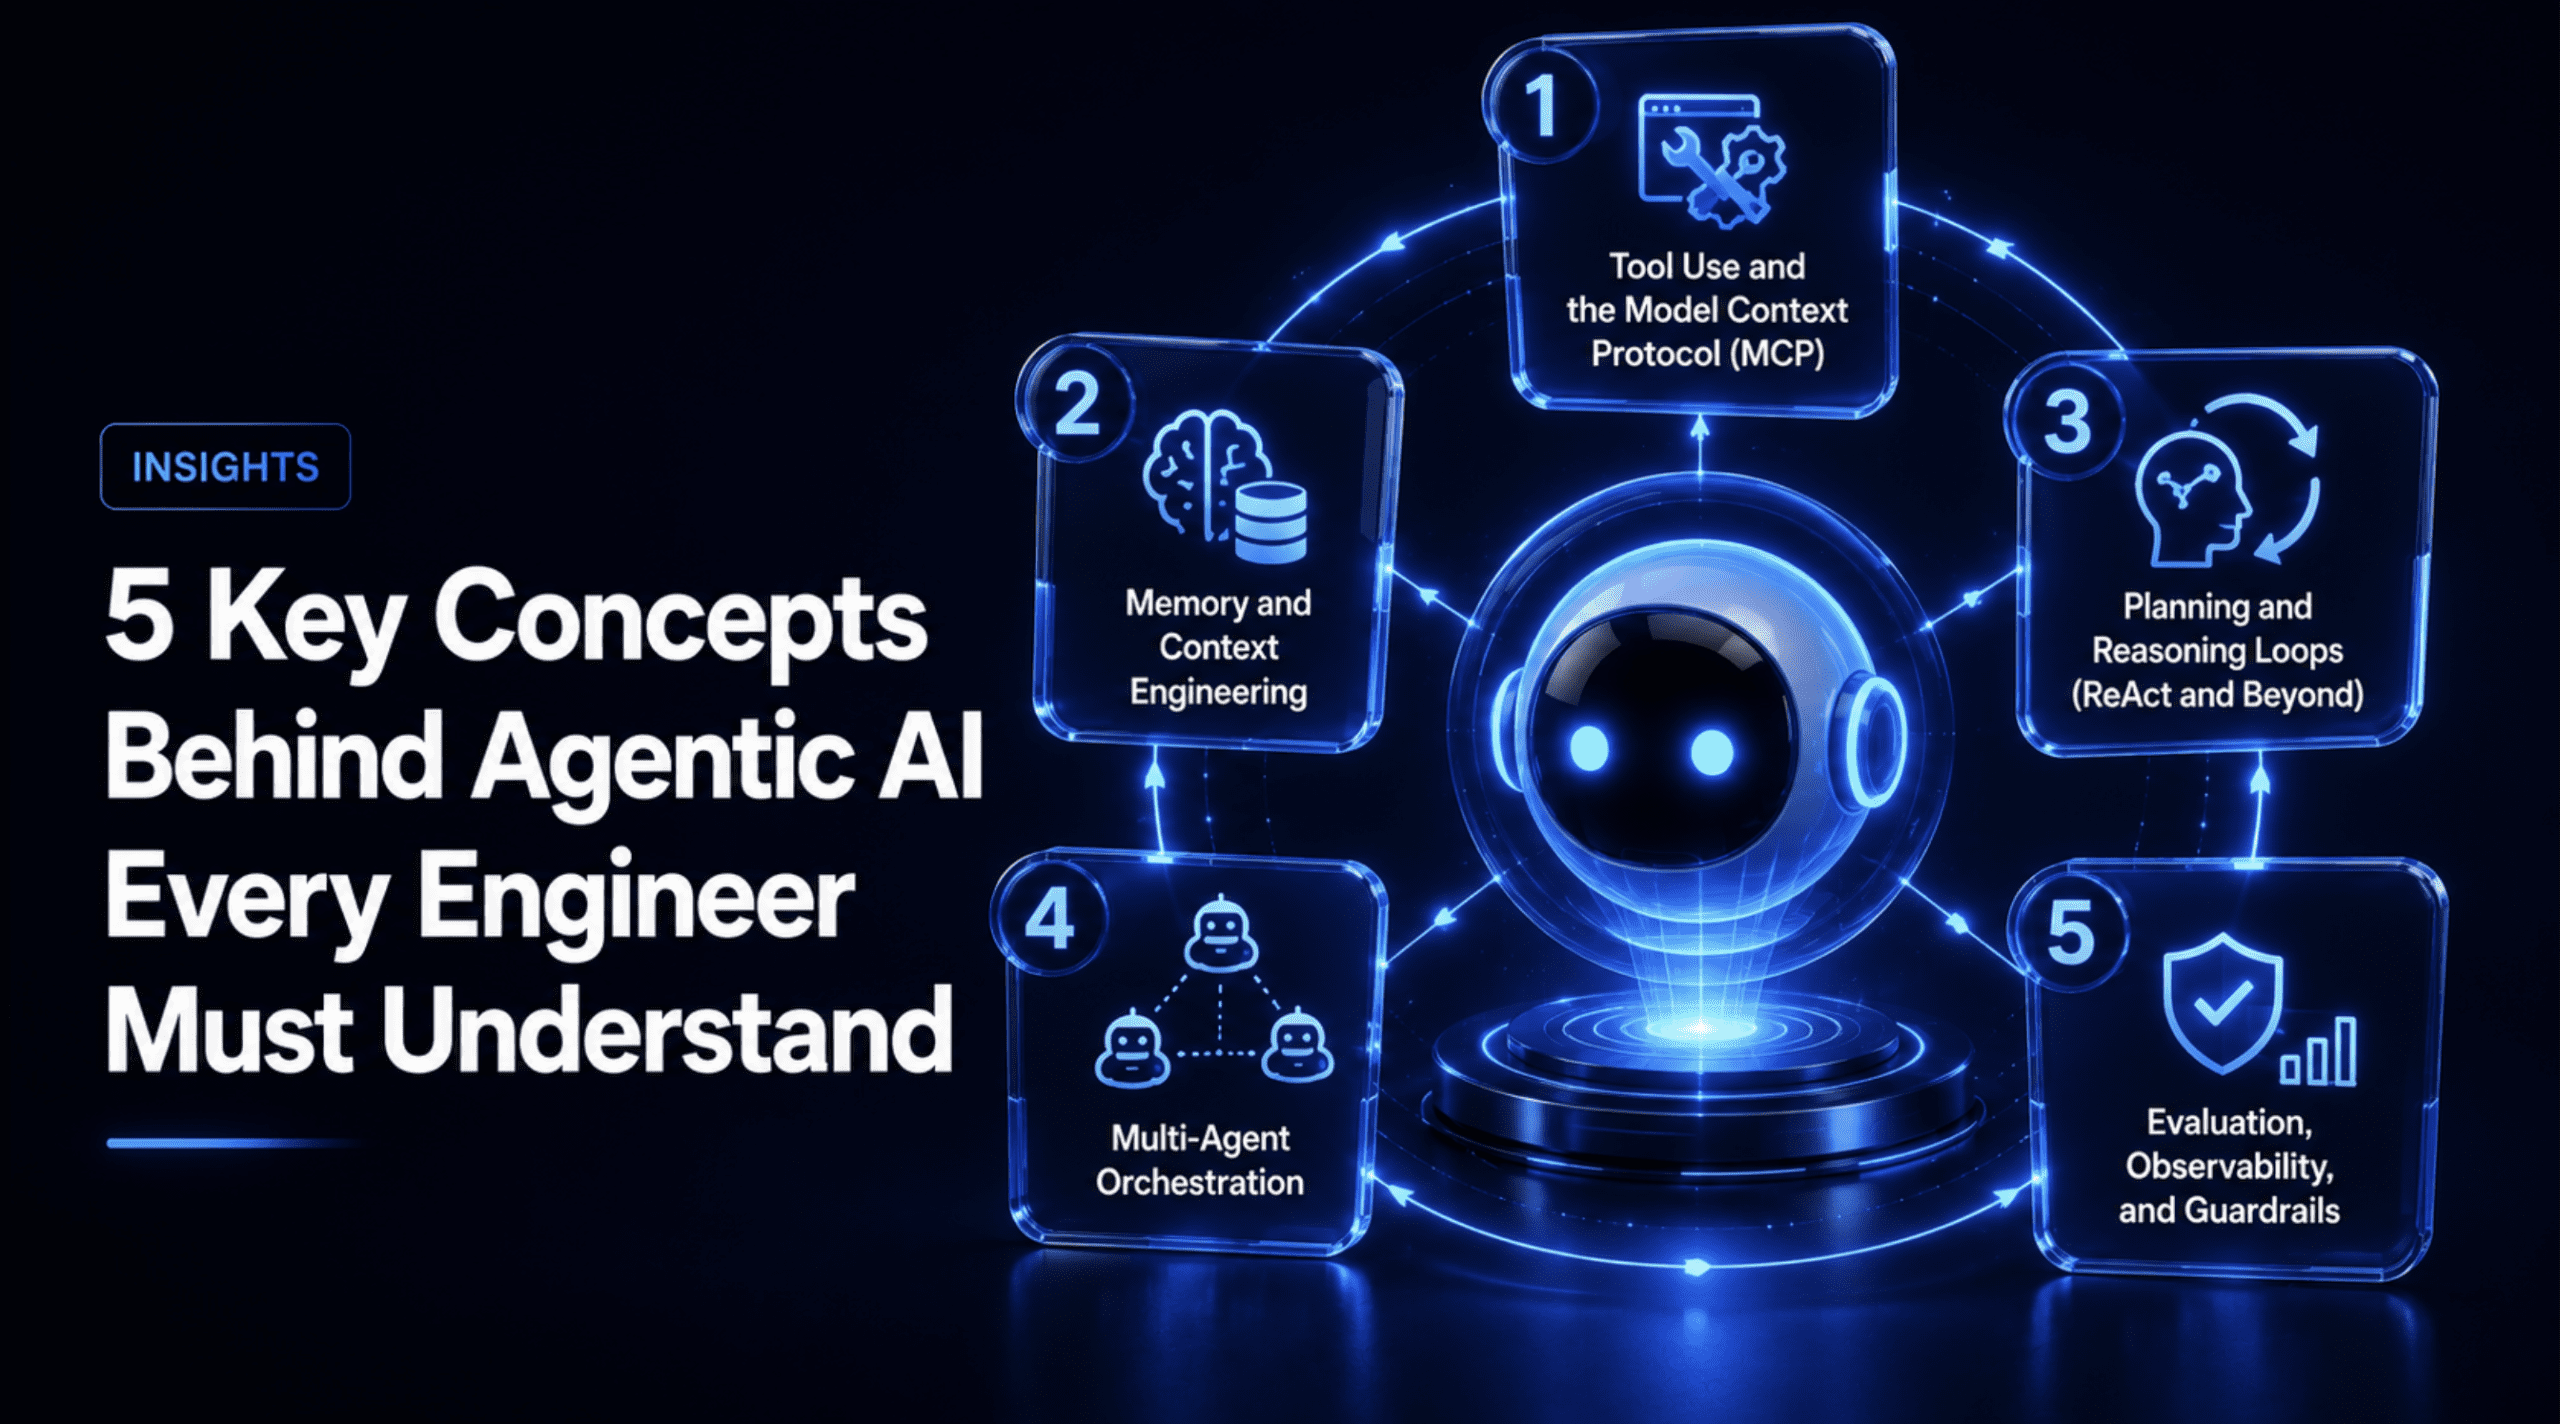
In the event you ask a chatbot to search out you a lodge in London, it will provide you with an inventory of names and allow you to do the remaining. In the event you ask an agent, it checks availability, compares costs throughout websites, books the room, and emails you the affirmation. That hole between “telling you one thing” and “doing one thing in your behalf” is all the story of agentic AI, and it is why the time period has gone from a analysis footnote to a line merchandise in nearly each engineering roadmap for 2026.
The arduous half is not the pitch. Everybody will get the pitch. The arduous half is that “agentic AI” is now a stand-in for 5 or 6 distinct engineering concepts that get mashed collectively in advertising decks, and should you do not separate them, you find yourself with an agent that may’t keep in mind a dialog, cannot discuss to the instruments it wants, or works tremendous in a demo and falls aside the second actual site visitors hits it. Roughly 88% of AI brokers constructed at this time by no means make it to manufacturing, and a big chunk of that failure has nothing to do with the underlying mannequin. It comes down as to if the engineering staff understood these 5 ideas earlier than they began constructing.
This text walks by the 5 concepts that really maintain agentic programs collectively: how brokers attain exterior themselves to make use of instruments, how they keep in mind something in any respect, how they resolve what to do subsequent, how a number of brokers work as a staff as an alternative of stepping on one another, and the way anybody is aware of if the entire thing is definitely working. Assets and frameworks are linked all through, so you possibly can go deeper on whichever piece issues most to what you are constructing.
# 1. Device Use and the Mannequin Context Protocol
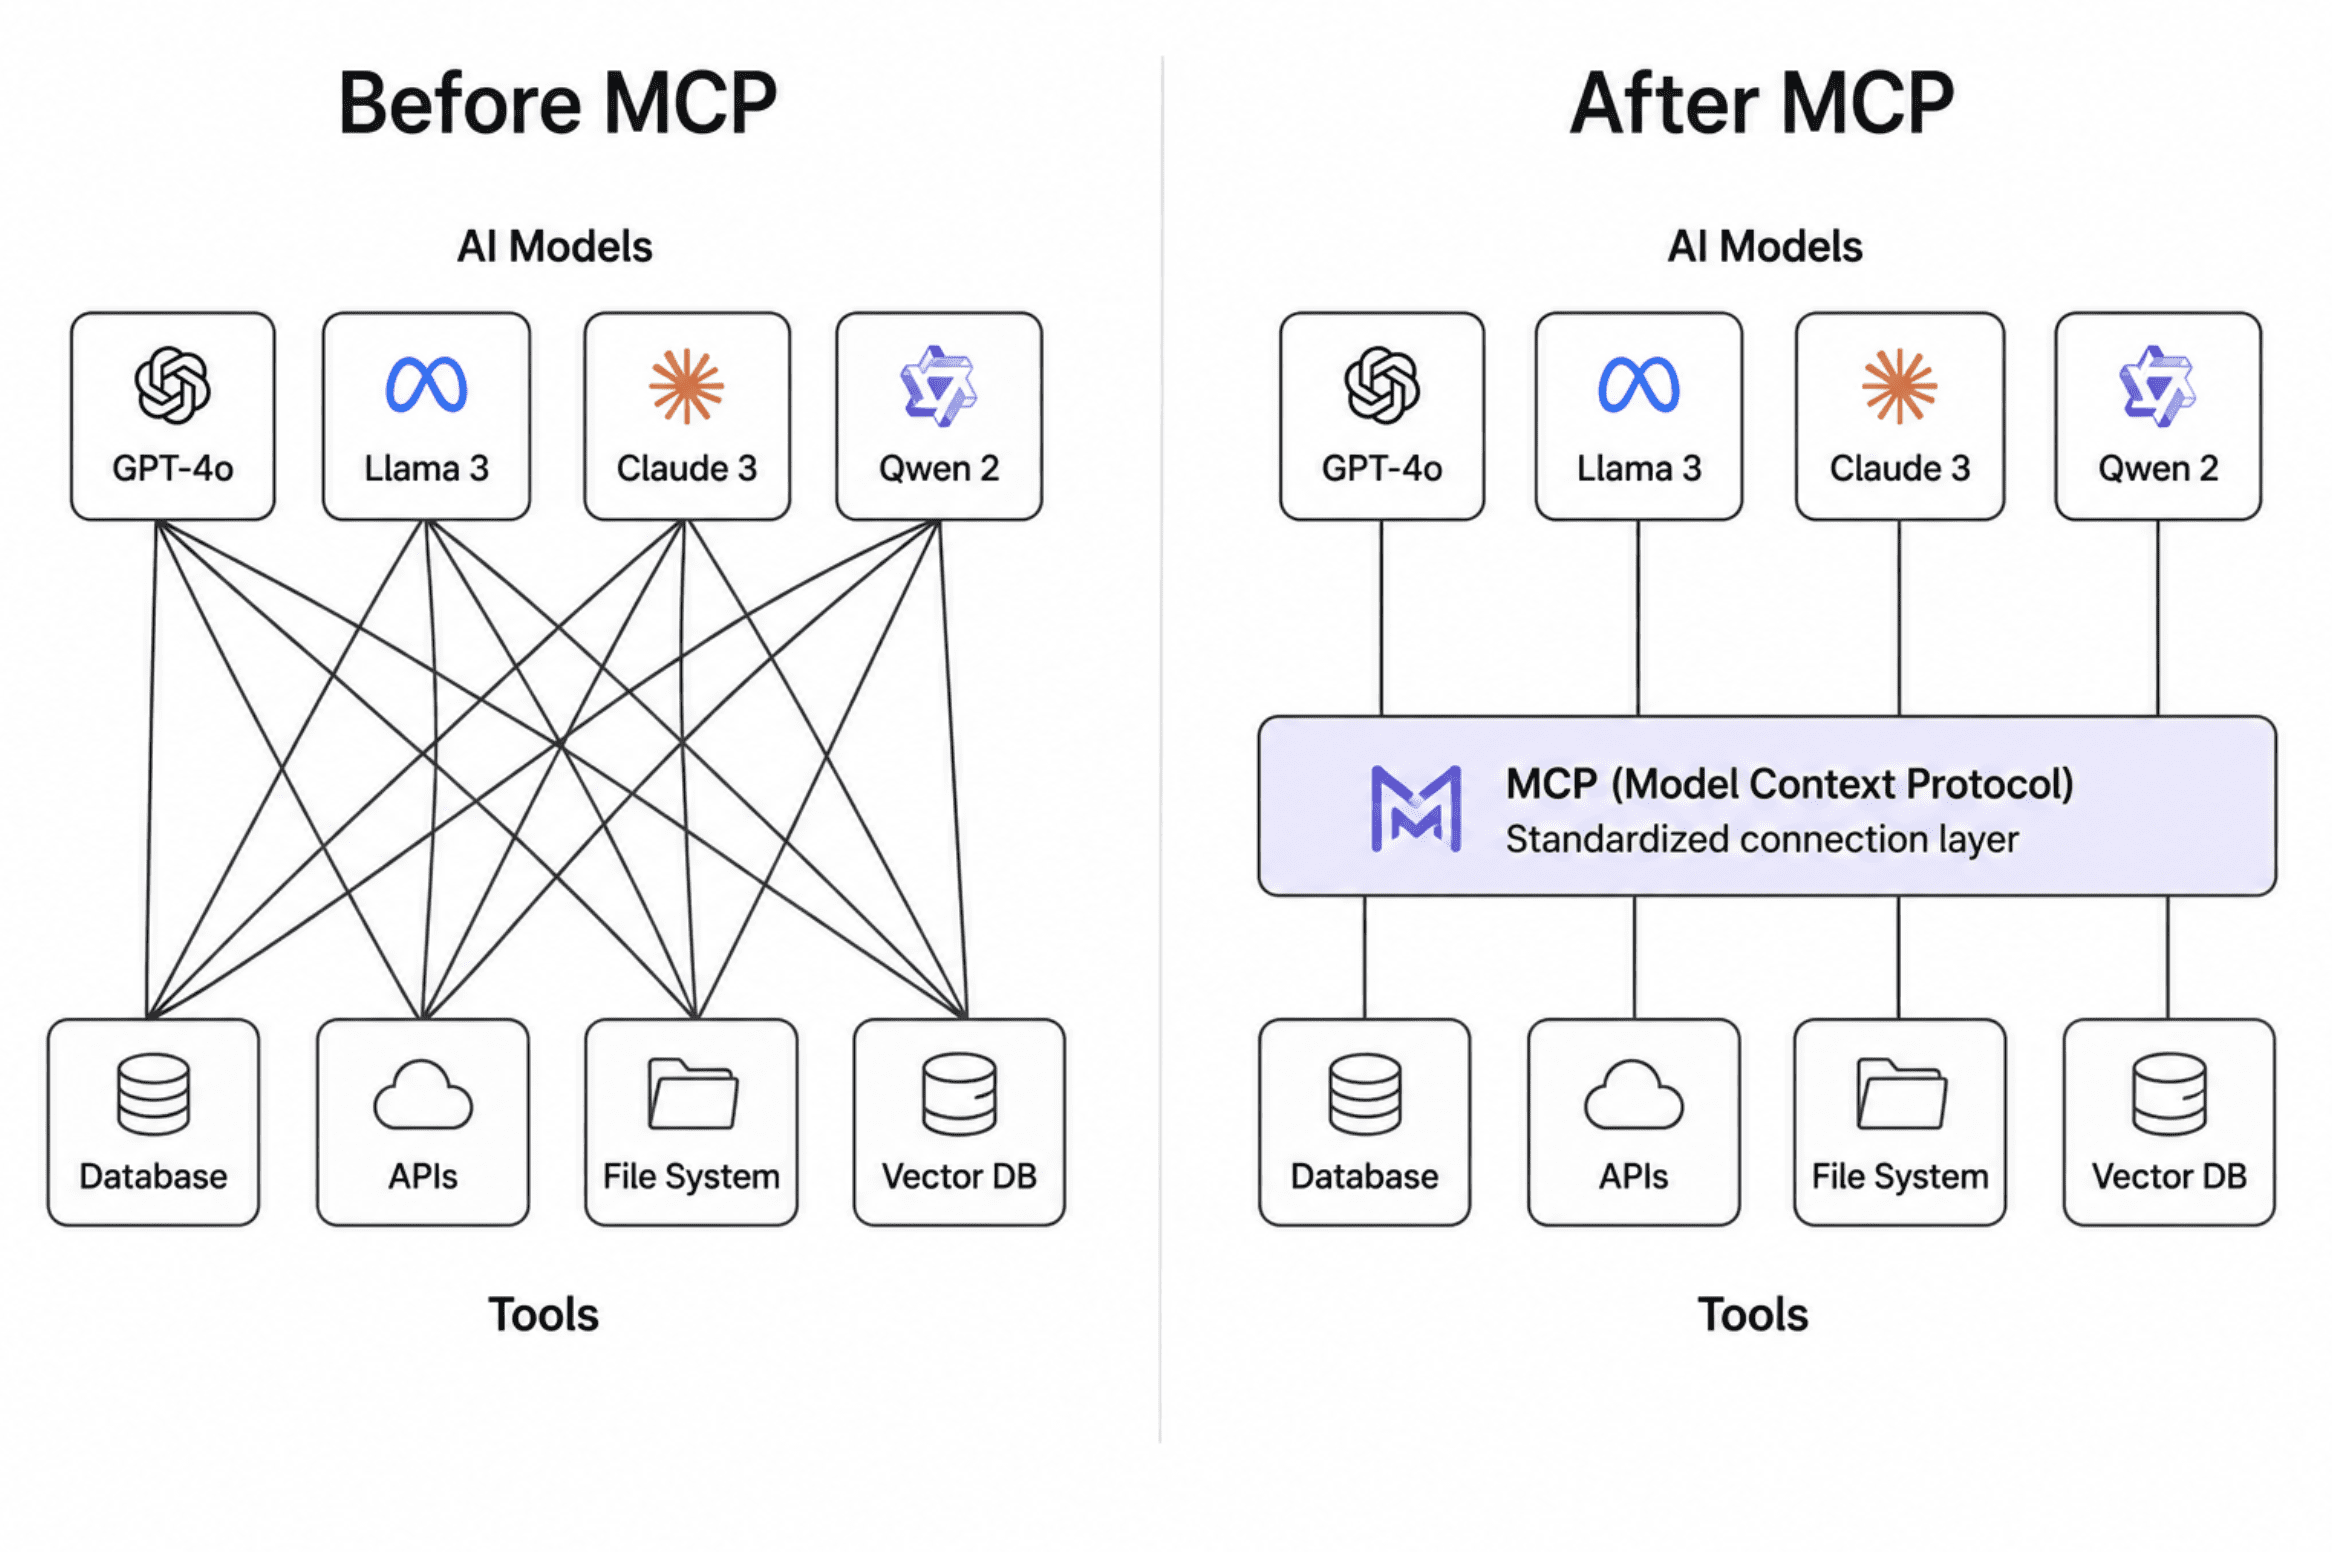
An massive language mannequin (LLM) by itself can solely generate textual content. The second you need to test a database, name an API, learn a file, or ship an e mail, you want a bridge between the mannequin’s reasoning and the surface world. That bridge is what individuals imply by “device use,” and for years, constructing it meant writing a customized integration for each single mixture of mannequin and repair. Ten AI purposes and 100 instruments used to imply one thing near a thousand brittle, one-off integrations.
Anthropic launched the Mannequin Context Protocol (MCP) in November 2024 to unravel precisely this drawback, and the adoption curve since then has been arduous to overstate. By March 2026, the official SDKs have been pulling in 97 million month-to-month downloads, up from roughly 100,000 within the first month after launch — a bounce that took the React npm bundle three years to succeed in and MCP about sixteen months. In December 2025, Anthropic donated MCP to the newly shaped Agentic AI Basis below the Linux Basis, with OpenAI and Block becoming a member of as co-founders and AWS, Google, Microsoft, Cloudflare, and Bloomberg as supporting members, which is the form of transfer that turns a vendor’s protocol into shared infrastructure no one can quietly deprecate.
What issues for an engineer is not the obtain depend, although. It is what the protocol really standardizes: a mannequin can ask any MCP-compliant server what it is able to, then name its instruments utilizing the identical JSON-RPC sample each time, no matter who constructed the server. The consumer discovers out there instruments by the server’s functionality manifest and invokes them by sending commonplace requests, which suggests you cease rebuilding the identical plumbing for each new integration. In the event you’re connecting an agent to Slack, Notion, GitHub, or a database, there’s an actual likelihood somebody already constructed and revealed the MCP server for it. The official MCP registry and group directories like PulseMCP are good beginning factors earlier than you write a customized integration from scratch.
The sincere caveat price figuring out: MCP is not free. It provides real token overhead in comparison with a direct API name, and for high-throughput pipelines the place each token counts, loads of groups in 2026 are sticking with lean CLI-based or direct calls as an alternative. MCP earns its place if you want OAuth dealt with correctly, if you’re serving a number of tenants with strict knowledge boundaries, or when non-engineers in your staff have to plug an agent right into a device with out writing an SDK integration themselves.
# 2. Reminiscence and Context Engineering
Each LLM name is stateless by default. The mannequin has no concept what occurred 5 minutes in the past until you set it again in entrance of it. For a single question-and-answer change, that is tremendous. For an agent dealing with a buyer over a number of classes, operating a multi-day analysis job, or managing a undertaking that spans weeks, a mannequin that forgets all the things between calls is principally ineffective, regardless of how good it’s within the second.
That is the place reminiscence stopped being an afterthought and have become its personal self-discipline. Three years in the past, agent reminiscence meant stuffing dialog historical past into the context window and hoping the mannequin saved observe. That is not how critical programs are constructed. Reminiscence is now handled as its personal architectural part, separate from the context window, with its personal benchmarks and a measurable hole between approaches that really work and ones that do not.
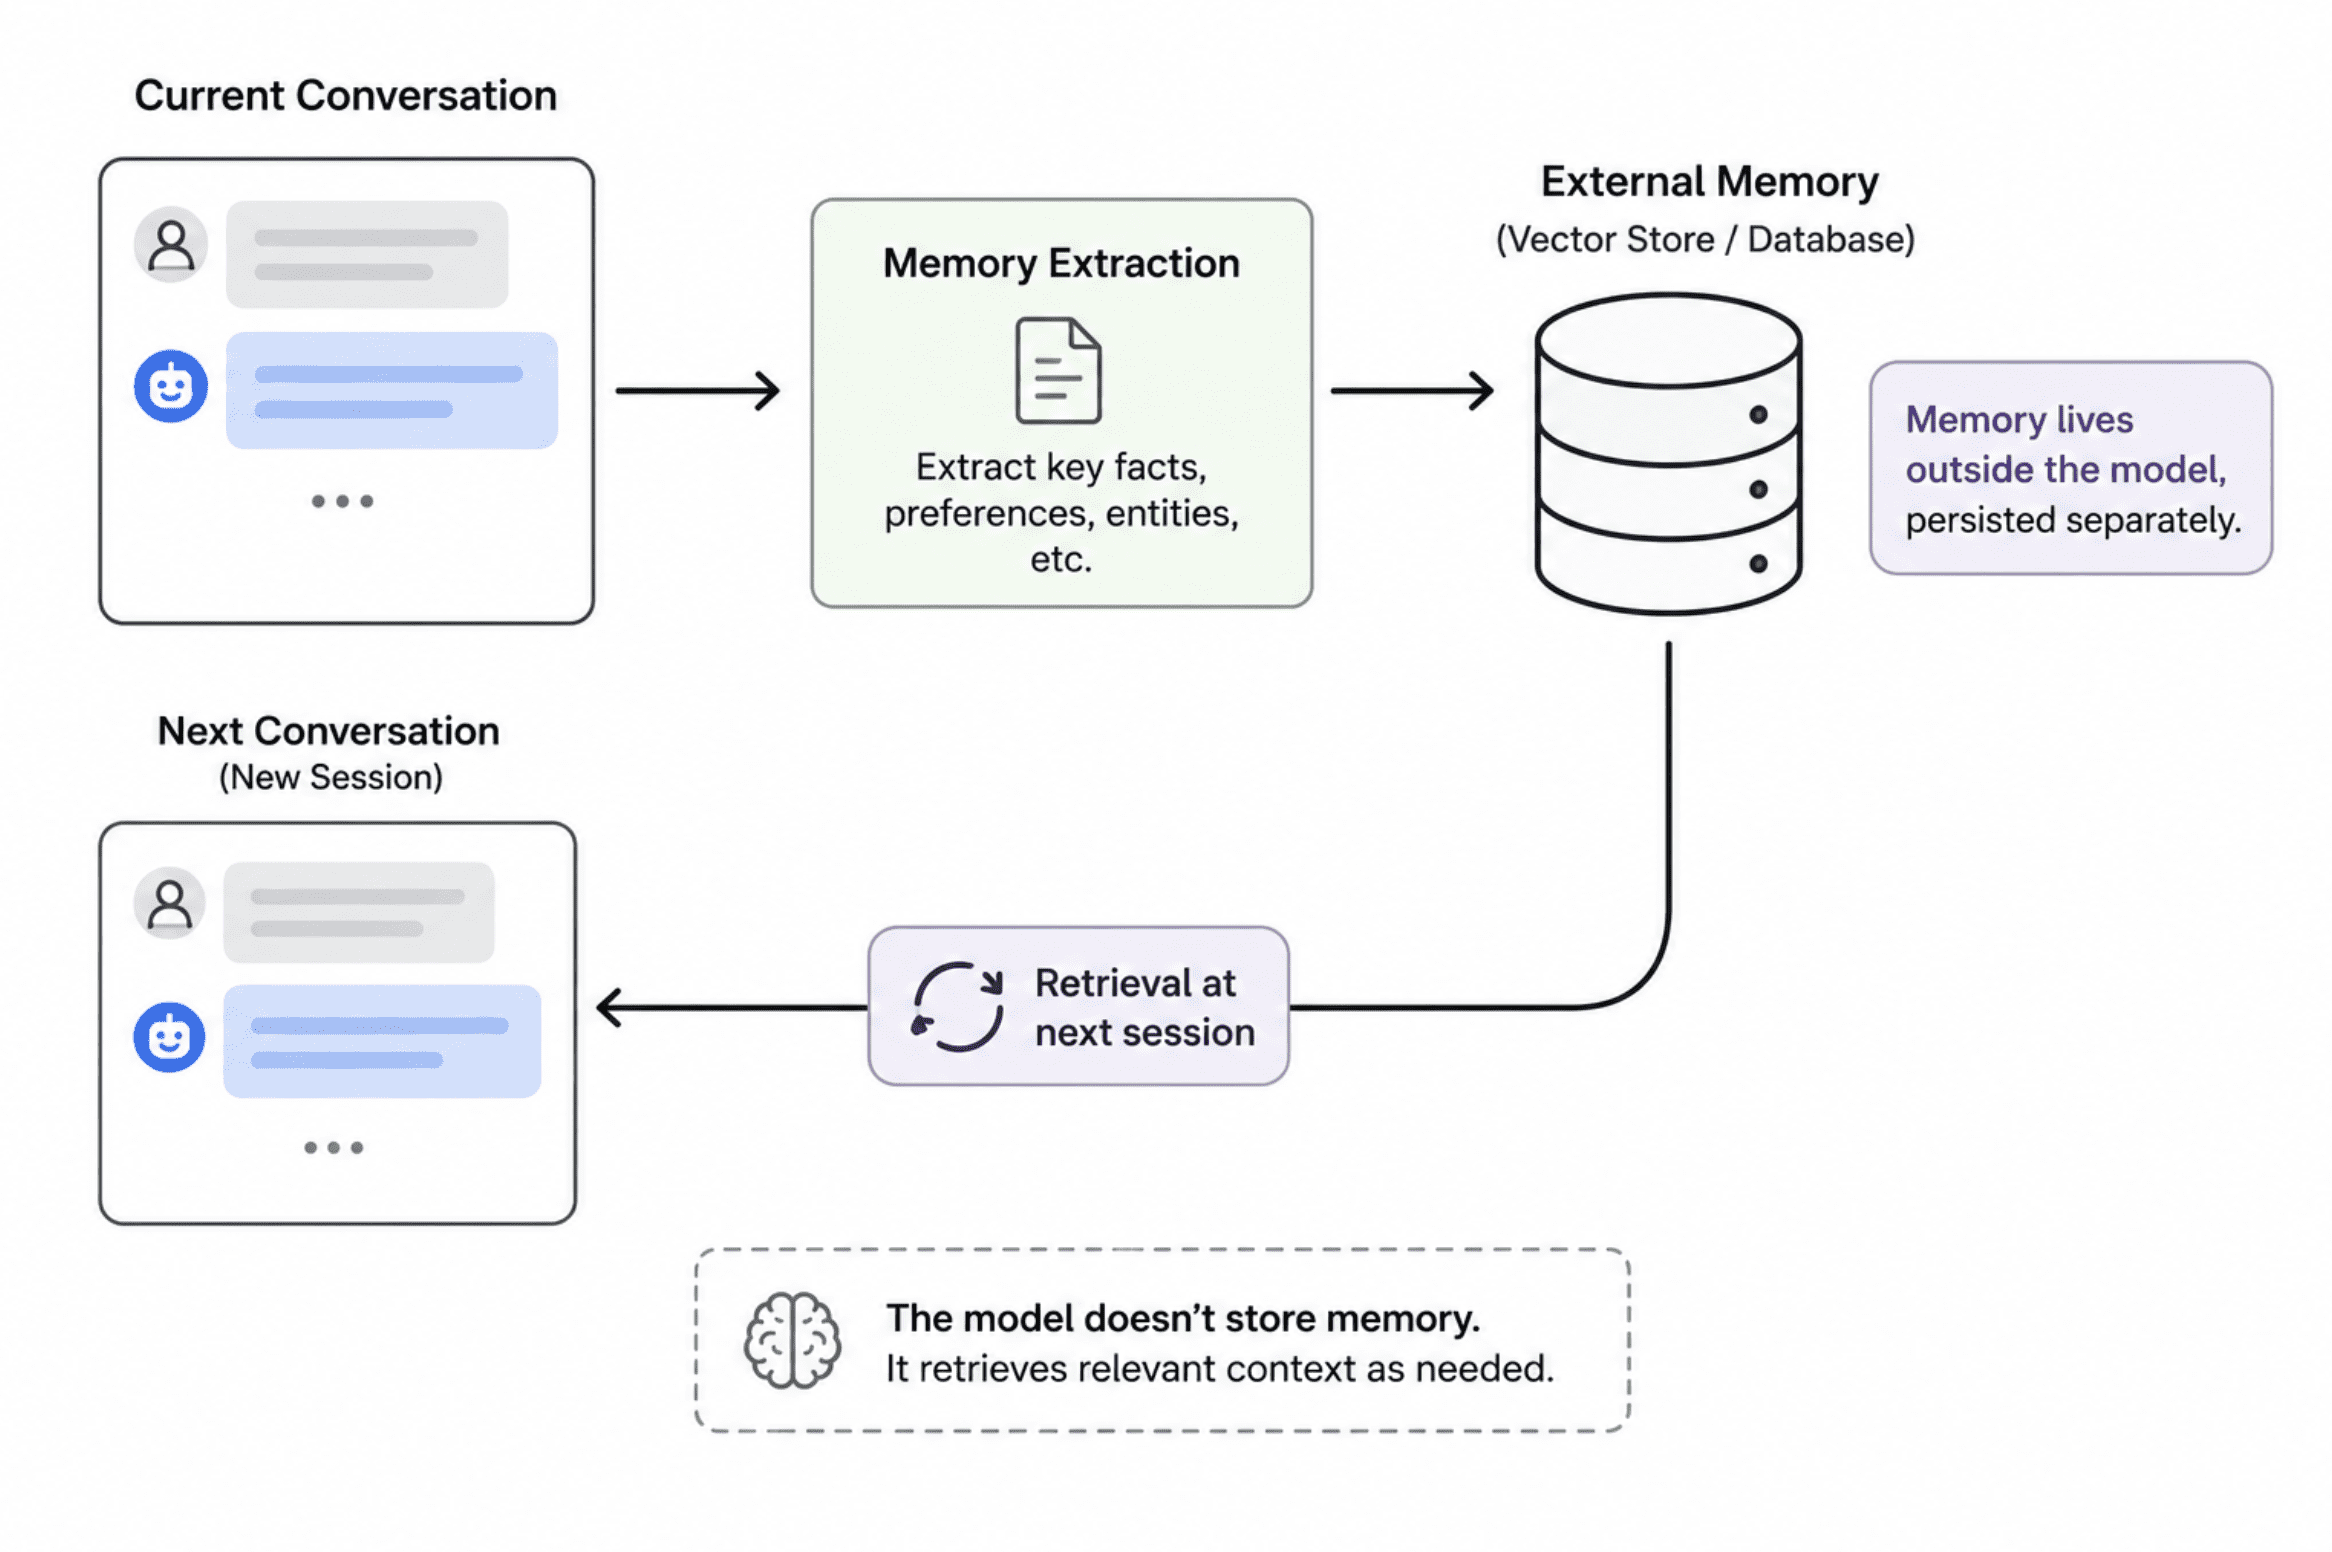
The mechanics are pretty easy when you see them laid out. Throughout a dialog, a reminiscence layer extracts the info price maintaining and shops them in a vector database, tagged by person, session, and agent. When a brand new session begins, the system retrieves no matter is related utilizing a mixture of semantic similarity, key phrase matching, and entity matching, then quietly injects solely that slice into the mannequin’s context earlier than it responds. The agent seems to be prefer it remembers you. What’s really occurring is a focused retrieval step operating earlier than each reply.
Instruments like Mem0, Zep (constructed on a temporal data graph referred to as Graphiti), and Letta have change into the default beginning factors relatively than one thing groups construct from scratch. The distinction between them is usually about what sort of reminiscence you want. Mem0 is the simpler, broader possibility for drop-in personalization. Zep scores noticeably larger on temporal reasoning — the form of question like “how did this buyer’s habits change after the pricing replace” — as a result of it tracks info with a begin and finish validity window relatively than simply storing the latest or most comparable entry.
The time period you will hear alongside reminiscence now could be “context engineering,” and it is price understanding why that phrase changed “immediate engineering” in a variety of conversations. Context high quality, not quantity, has change into the true limiting issue for LLM brokers. Most groups do not come near utilizing the total context window their fashions technically help, and the precise problem is deciding on, compressing, and structuring the knowledge that genuinely drives the mannequin’s selections relatively than simply dumping all the things in. An even bigger context window does not repair a sloppy retrieval technique. It simply offers sloppiness extra room to cover.
# 3. Planning and Reasoning Loops
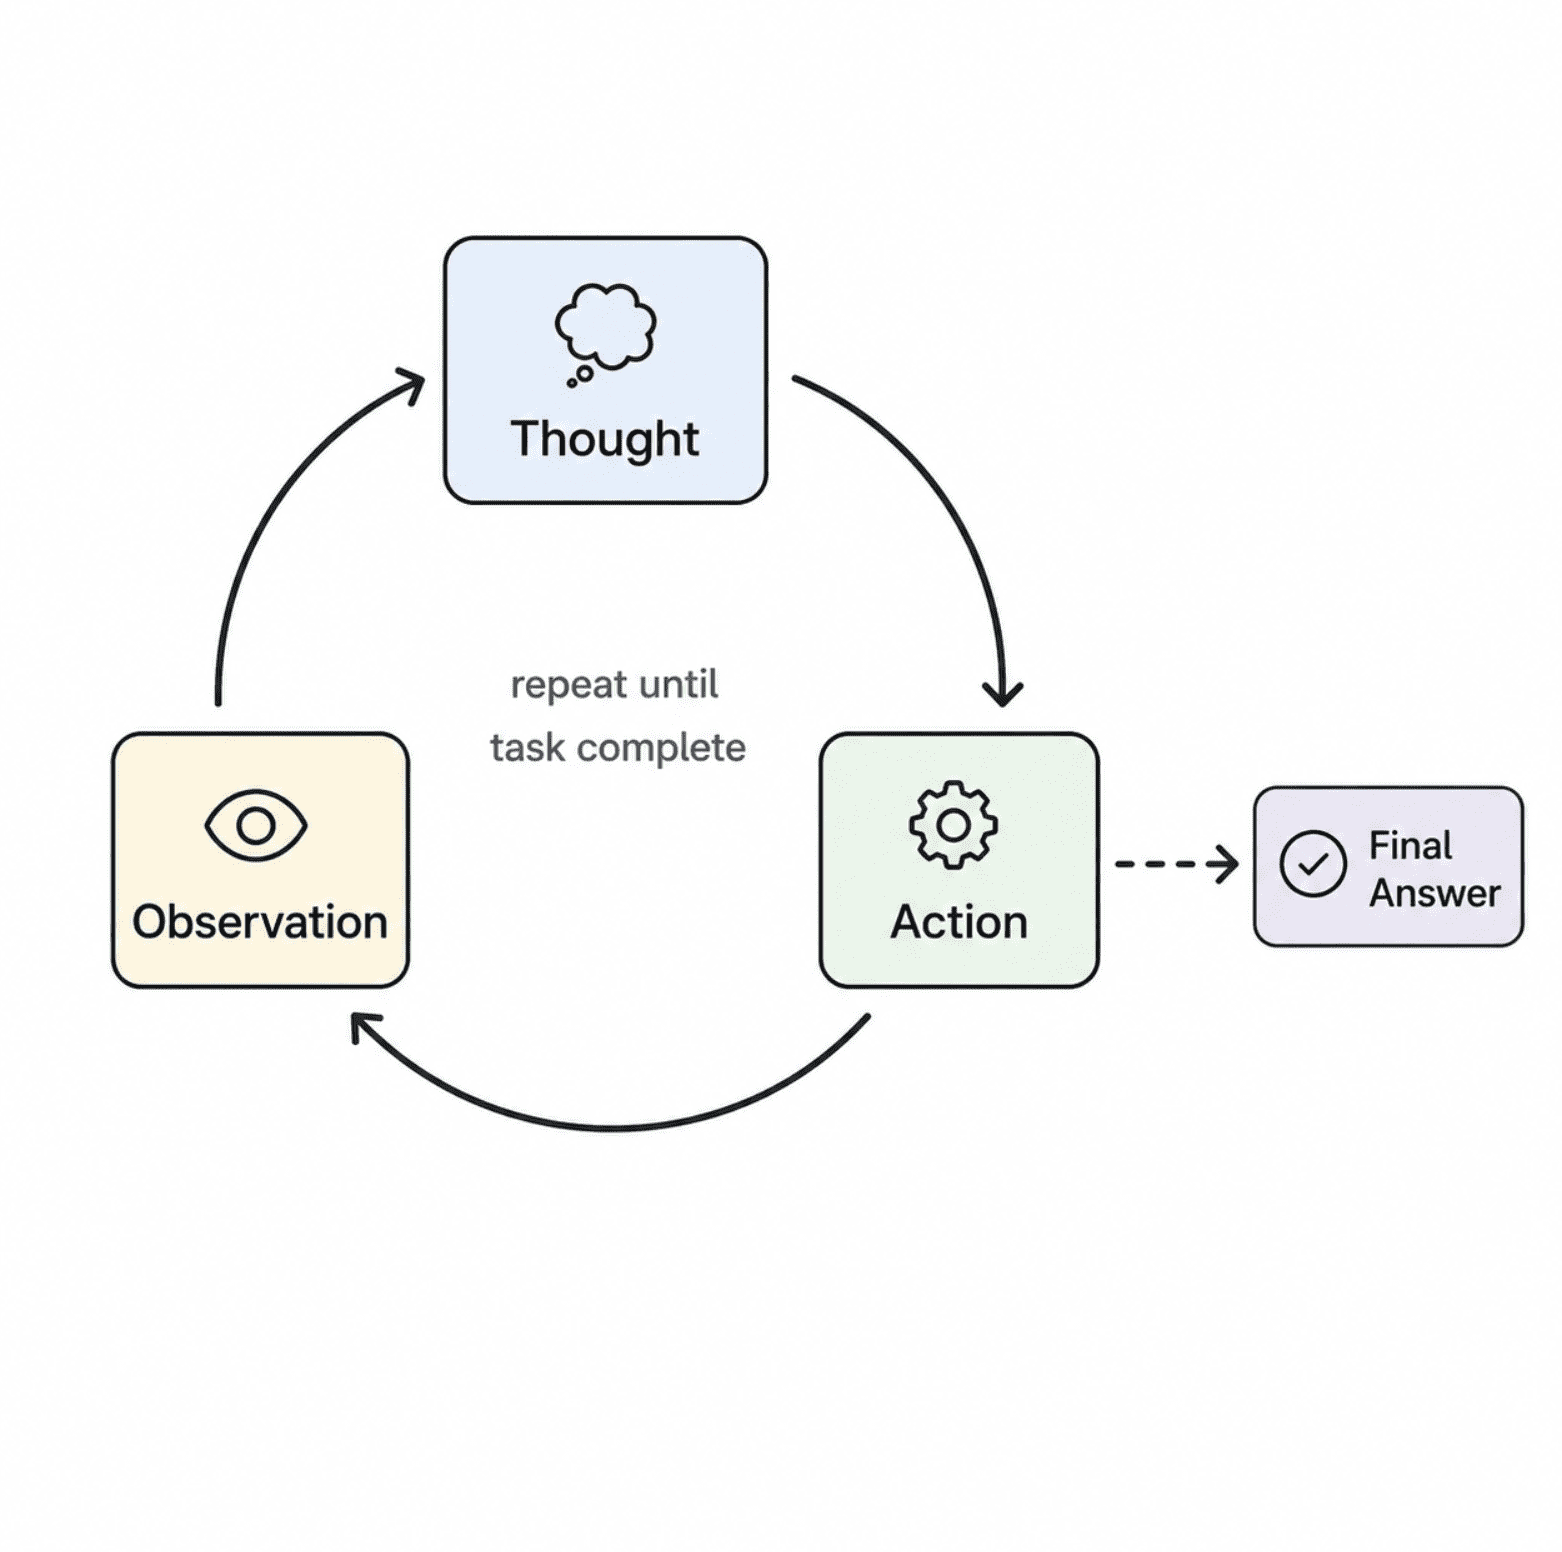
A chatbot solutions as soon as and stops. An agent has to resolve what to do, do it, take a look at what occurred, and resolve once more — typically dozens of occasions in a row — with out a human prompting it at each step. That loop is the precise mechanical distinction between “AI that talks” and “AI that works,” and nearly each agent framework you will encounter at this time is a few variation on the identical core sample.
That sample has a reputation and a selected origin. In late 2022, researchers from Google and Princeton revealed ReAct: Synergizing Reasoning and Performing in Language Fashions, which proposed having the mannequin interleave reasoning steps with actions relatively than treating them as separate duties. The construction is straightforward to explain: the mannequin produces a thought, takes an motion primarily based on that thought, observes the end result, and produces one other thought primarily based on what it simply noticed. On benchmarks involving query answering and interactive decision-making, this strategy beat each pure imitation studying and pure reinforcement studying by a large margin whereas needing just one or two examples to work.
What’s modified since 2022 is not the core loop; it is how a lot construction sits round it. Chain-of-thought, ReAct-style reasoning, and few-shot prompting was once the entire toolkit. By 2026, this has developed into what individuals name context engineering, which is about designing all the info surroundings across the mannequin relatively than simply the immediate that kicks off the loop. Trendy agent frameworks add retry logic, self-correction when a device name fails, and specific job decomposition so a imprecise purpose like “analysis this market and summarize the aggressive panorama” will get damaged into steps the mannequin can really confirm separately.
That is additionally the place reliability issues are inclined to floor first. A reasoning loop that runs unchecked can burn by tokens quick, get caught retrying the identical failed motion, or wander away the unique purpose fully. Knowledge from manufacturing traces exhibits {that a} significant share of LLM name failures in agent programs come from exceeded price limits throughout precisely these sorts of repeated, looping calls — which is a helpful reminder that the planning loop is not only a reasoning idea; it is one thing it’s important to finances and monitor like some other piece of infrastructure.
# 4. Multi-Agent Orchestration
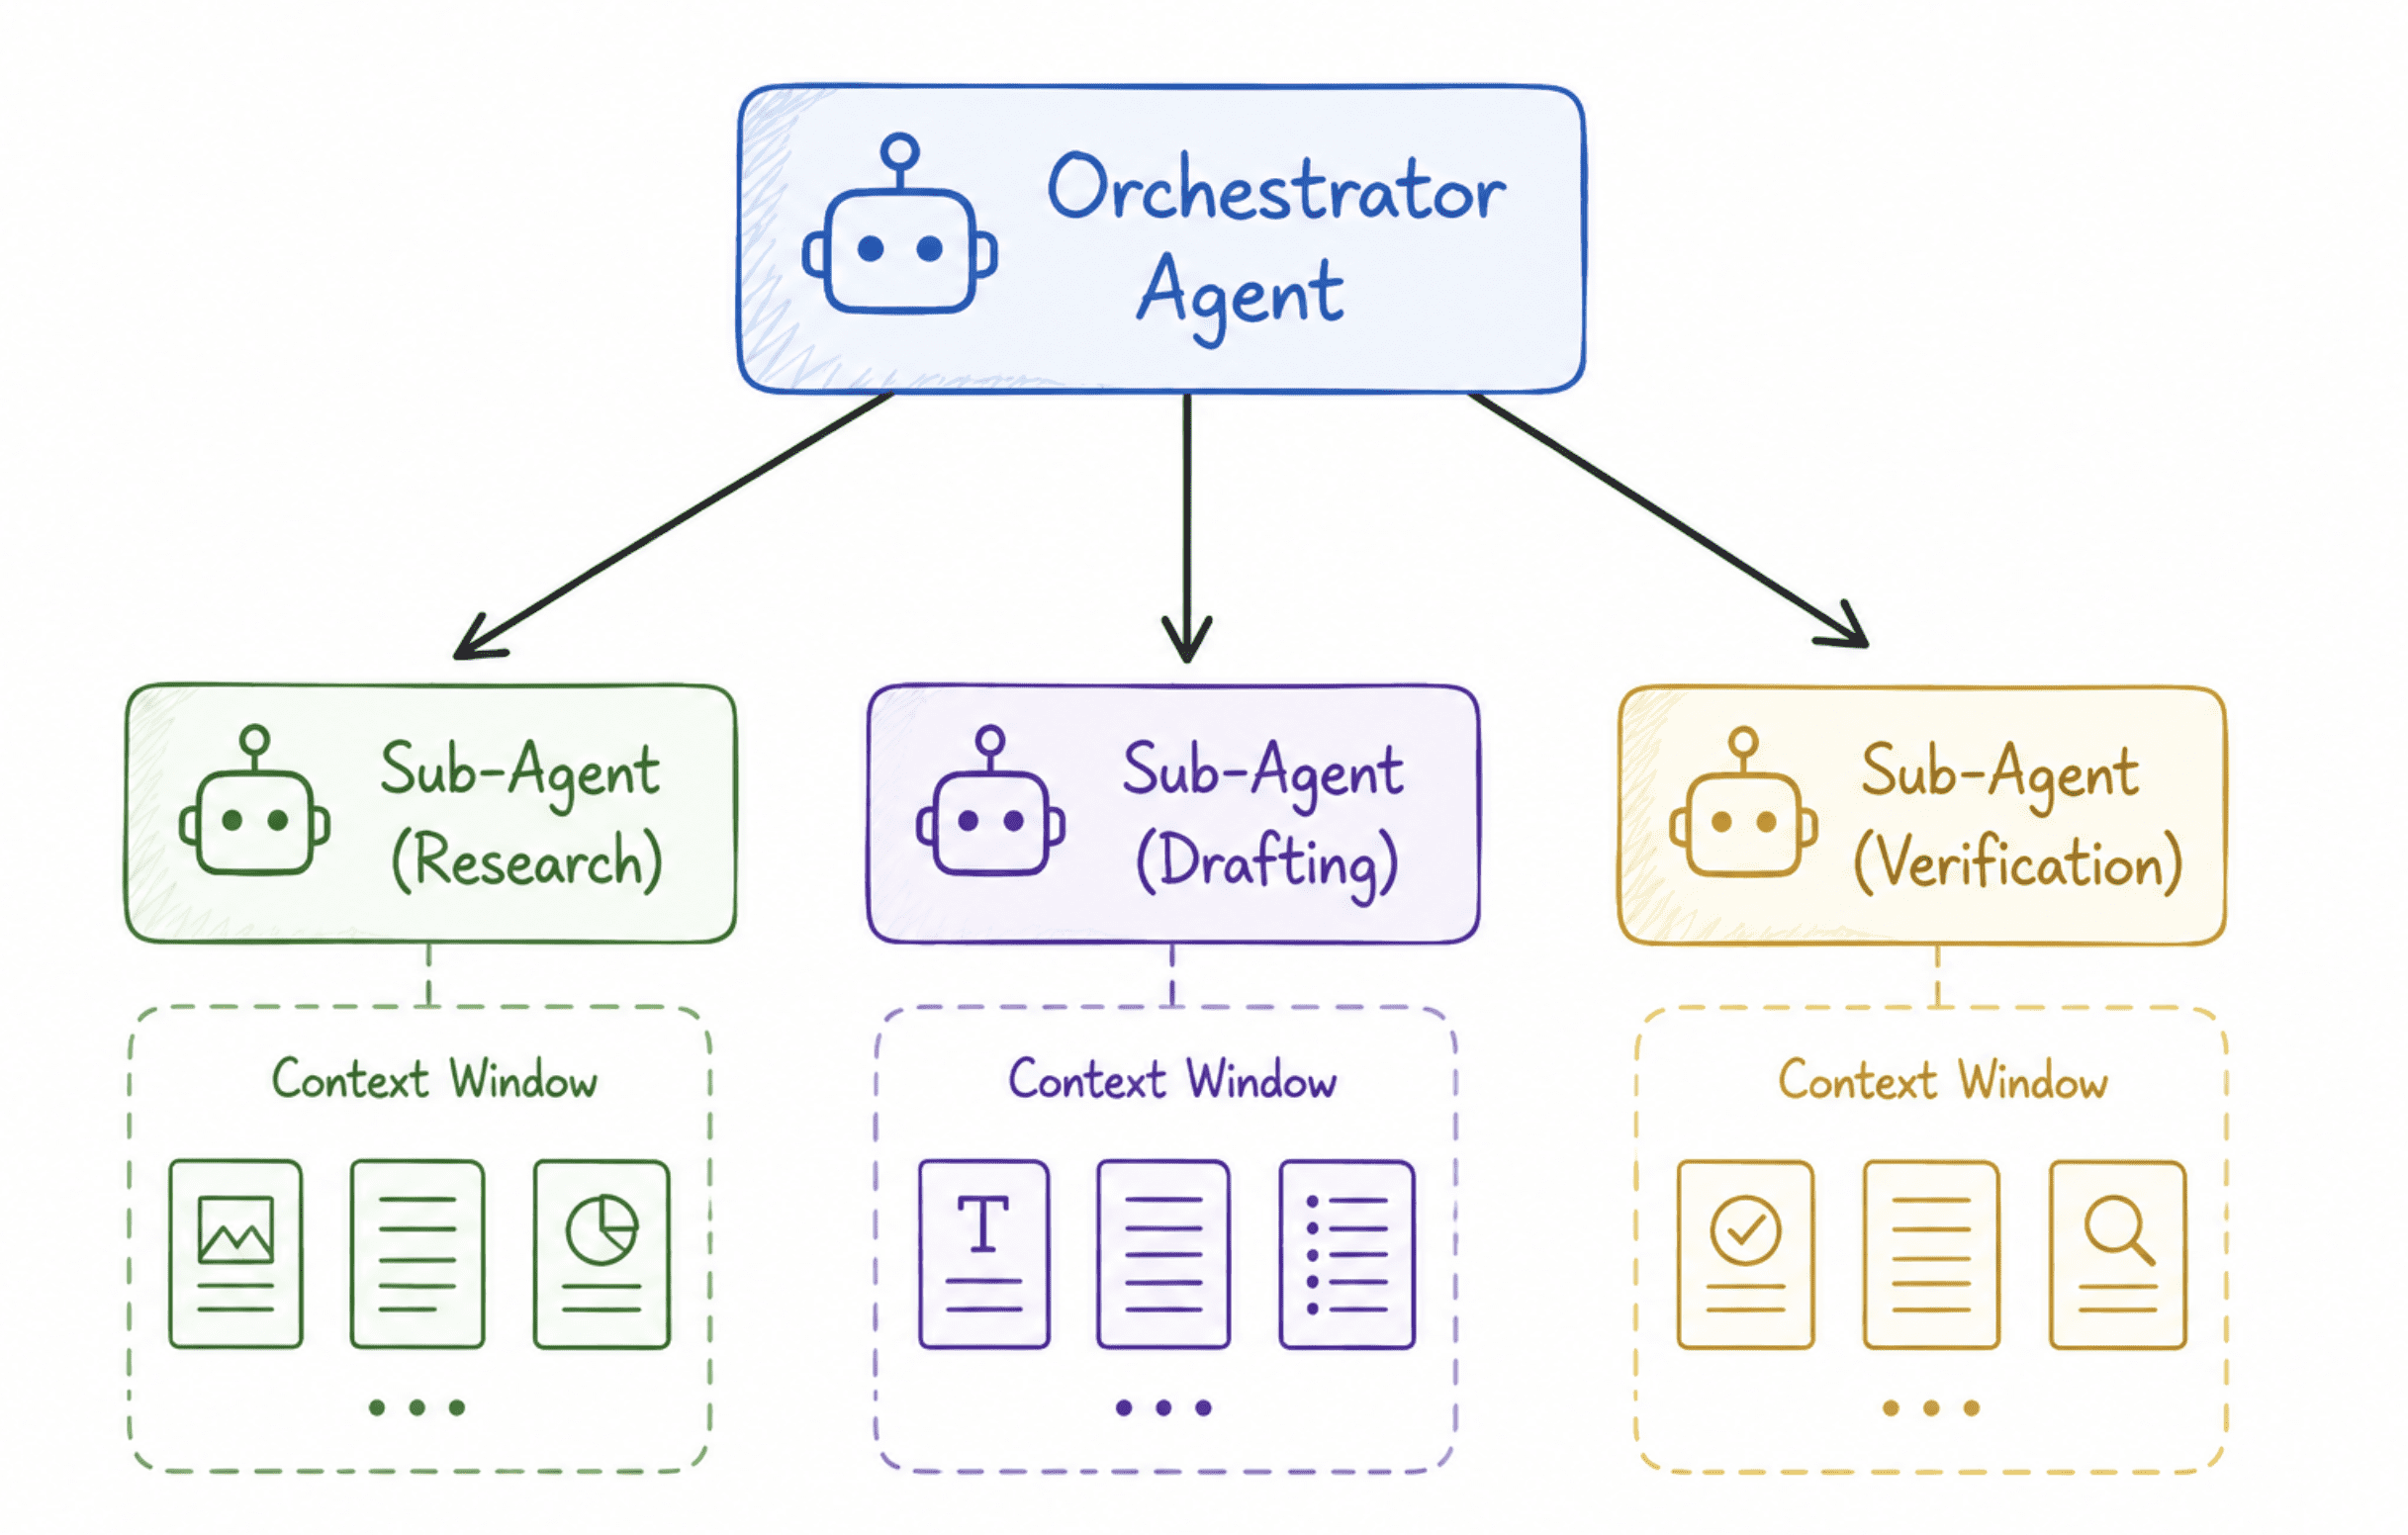
A single agent with a single context window has a ceiling. Feed it a whole codebase, a protracted analysis transient, and a set of enterprise guidelines , and someplace in there, it begins dropping observe of particulars, particularly those buried in the course of all that context. The repair that is change into commonplace in 2026 is not an even bigger mannequin. It is splitting the work throughout a number of brokers, every with its personal centered context, coordinated by one thing sitting above them.
In the event you’re selecting easy methods to construct this your self, the framework panorama has settled into a couple of clear lanes relatively than dozens of competing choices. LangGraph has the steepest studying curve of the most important choices however gives probably the most management and probably the most mature manufacturing readiness, with built-in checkpointing and specific state administration. CrewAI is the best to choose up, structuring multi-agent work round roles and duties, and is probably the most intuitive alternative when work splits naturally into specialist roles. AutoGen leads in analysis and tutorial settings with versatile conversational patterns between brokers, although manufacturing adoption trails the opposite two. None of those is universally “finest.” The correct choose depends upon whether or not your staff wants fine-grained management or quick time-to-prototype.
The opposite half of this idea is letting brokers constructed on completely different frameworks discuss to one another in any respect, which is a separate drawback from giving one agent entry to instruments. Google launched the Agent2Agent (A2A) protocol in April 2025 particularly for this, and it is now housed below the Linux Basis as an open-source undertaking. The place MCP standardizes how an agent talks to instruments, A2A standardizes how brokers discuss to different brokers, letting them uncover one another’s capabilities and collaborate on a job with out exposing their inside reminiscence or logic to 1 one other. The 2 protocols are designed to enhance one another relatively than compete, and seeing each named in a system’s structure is changing into a traditional factor to anticipate by mid-2026.
# 5. Analysis, Observability, and Guardrails
That is the idea that decides whether or not all the things above really ships, and it is the one engineers are inclined to underinvest in as a result of it is the least thrilling a part of the construct. The numbers clarify why it may’t keep an afterthought. Roughly 88% of AI brokers fail to succeed in manufacturing, however the ones that do make it return a median 171% ROI. That is not a small hole. It is the distinction between a undertaking that will get quietly shelved and one which turns into a real aggressive benefit, and the hole is usually closed by engineering self-discipline relatively than a greater mannequin.
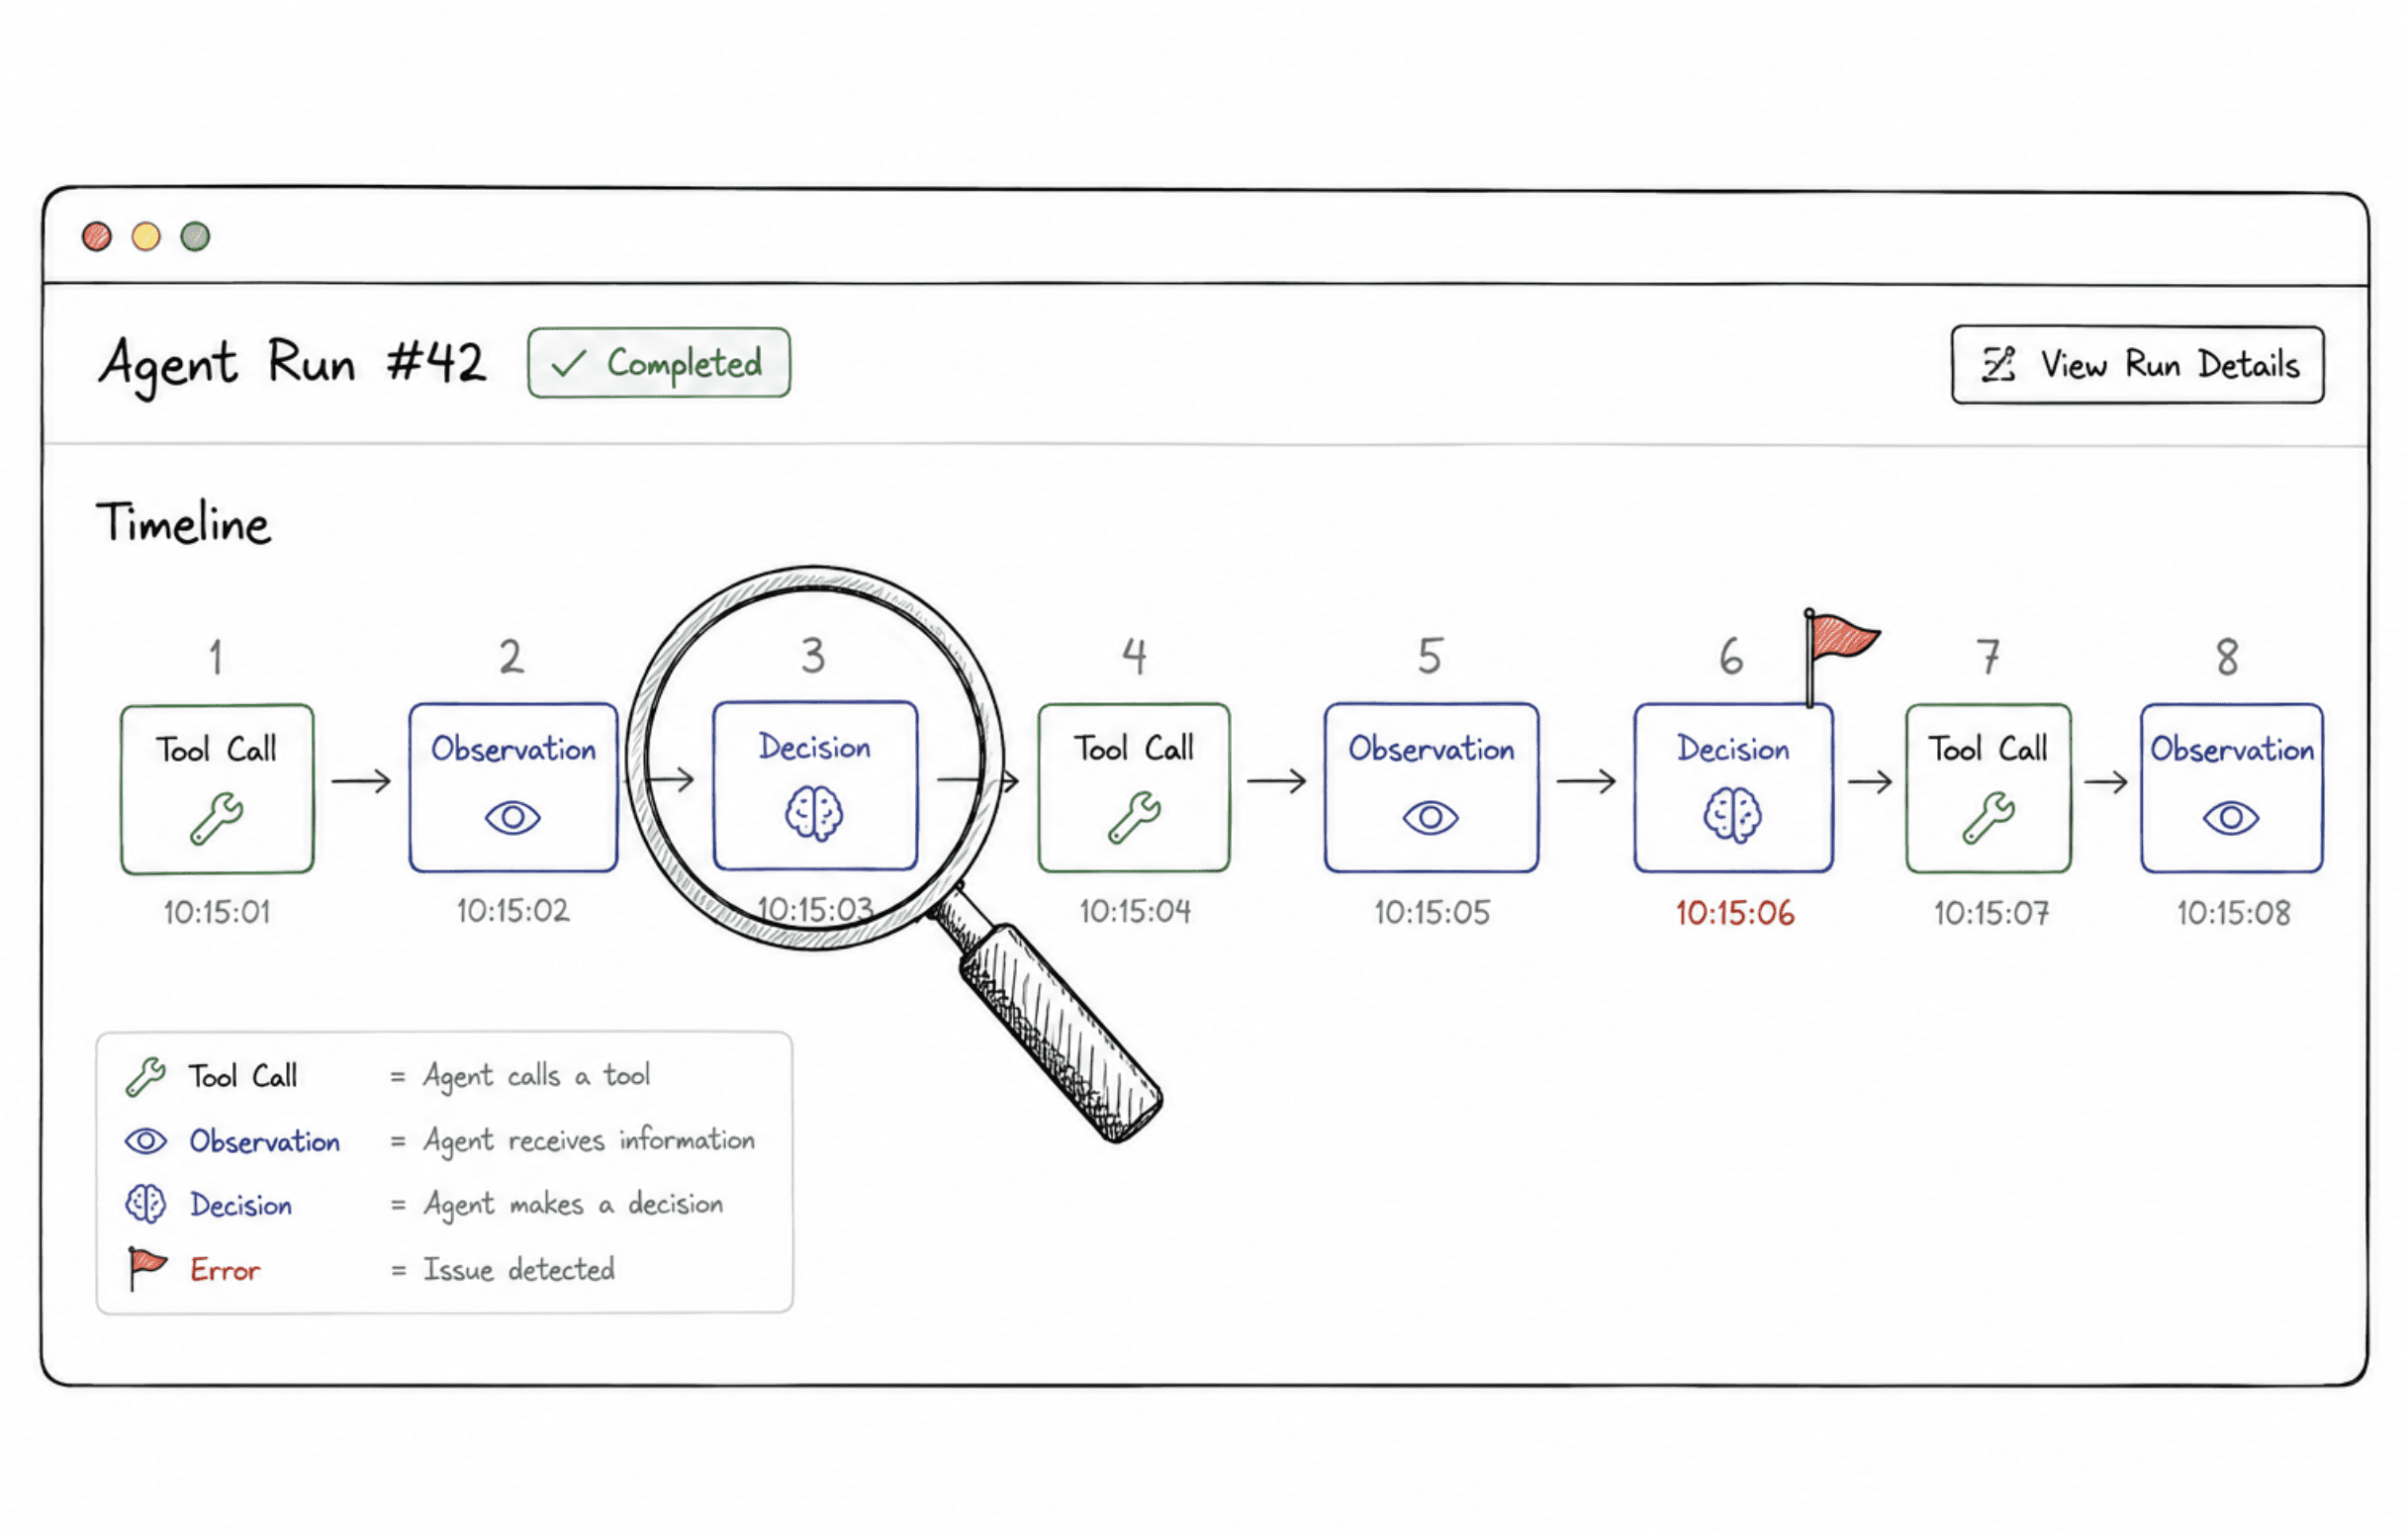
What does that self-discipline really appear to be in follow? It begins with tracing — the power to see precisely what an agent did at each step, which device it referred to as, what it noticed, and the place it went fallacious. LangSmith, paired with LangGraph, has change into a typical alternative for this sort of framework-agnostic tracing and systematic debugging in manufacturing, and comparable tooling exists throughout the opposite main frameworks. With out this, debugging an agent that misbehaved in manufacturing means guessing, as a result of you haven’t any report of the reasoning that led it there.
Analysis is the second half, and it is distinct from tracing. Tracing tells you what occurred. Analysis tells you whether or not it was really good. Microsoft’s newer tooling on this area, as an example, features a rubric evaluator that mechanically generates analysis standards primarily based on an agent’s particular context, then scores its efficiency in opposition to weighted dimensions for a extra nuanced high quality view than a easy move or fail. The broader trade has additionally began standardizing the place precisely in an agent’s lifecycle you place security checks. One rising strategy defines 5 validation checkpoints throughout an agent’s run, overlaying enter, the mannequin’s personal reasoning, inside state, device execution, and remaining output — expressed as a conveyable, versionable coverage relatively than scattered customized code.
None of this replaces human judgment; it simply tells you the place to level it. Gartner has predicted that greater than 40% of agentic AI tasks can be canceled by the top of 2027, with escalating prices, unclear enterprise worth, and insufficient danger controls as the primary drivers, and each a type of failure modes is one thing analysis and observability are constructed to catch early — earlier than they flip right into a canceled undertaking as an alternative of a fixable bug.
# Wrapping Up
None of those 5 ideas works nicely in isolation. An agent with useful gizmo entry however no reminiscence forgets each lesson it simply realized. An agent with a strong reasoning loop however no orchestration hits a wall the second the duty will get too large for one context window. An agent that does the entire above however has no analysis layer is a black field you are hoping behaves itself in manufacturing. The engineers getting actual worth out of agentic AI in 2026 aren’t those who picked the flashiest framework. They’re those who understood how device use, reminiscence, planning, orchestration, and analysis match collectively as one system, and constructed accordingly.
In the event you’re ranging from scratch, you do not want all 5 mastered earlier than you write a line of code. Choose one well-scoped job, wire up a single agent with MCP for device entry and a fundamental reminiscence layer, watch the way it causes by a couple of actual runs, and solely attain for multi-agent orchestration as soon as a single agent genuinely cannot deal with the scope. Analysis ought to be there from day one, not bolted on after one thing breaks. That order, greater than any particular framework alternative, is what separates the brokers that make it to manufacturing from the 88% that do not.
Shittu Olumide is a software program engineer and technical author enthusiastic about leveraging cutting-edge applied sciences to craft compelling narratives, with a eager eye for element and a knack for simplifying complicated ideas. You may as well discover Shittu on Twitter.
public class ProductService
{
    personal readonly IDbContextFactory _factory;
    public ProductService(IDbContextFactory manufacturing unit)
        => _factory = manufacturing unit;
    public async Job GetByIdAsync(int id)
    {
        await utilizing var context = await _factory.CreateDbContextAsync();
        return await context.Merchandise.FindAsync(id);
    }
    public async Job UpdateStockQuantityAsync(int id, int updateQuantity)
    {
        await utilizing var context = await _factory.CreateDbContextAsync();
        var product = await context.Merchandise.FindAsync(id);
        if (product is null) return;
        product.Amount += updateQuantity;
        await context.SaveChangesAsync();
    }
}
Be aware that ProductService has two strategies, GetByIdAsync and UpdateStockQuantityAsync. An occasion of the DbContext class is created regionally in every of those strategies. Now, suppose you may have two threads, T1 and T2, that execute these strategies concurrently. That’s, thread T1 executes the GetByIdAsync methodology whereas thread T2 executes the UpdateStockQuantityAsync methodology. As a result of every of those strategies is executed in isolation, they’ll have their very own context, connection, and change-tracking data, and there can be no mutable state, so that you don’t have to implement thread synchronization in both of those strategies.
Contemplate the next code that executes a learn operation and an replace operation in two separate duties.
The Job.WhenAll methodology runs the 2 duties in parallel and waits till each have completed. The rationale this method is thread-safe, and won’t create concurrency errors, is that every of those two strategies creates its personal DbContext occasion internally. Subsequently the learn operation and the replace operation use impartial DbContext situations.
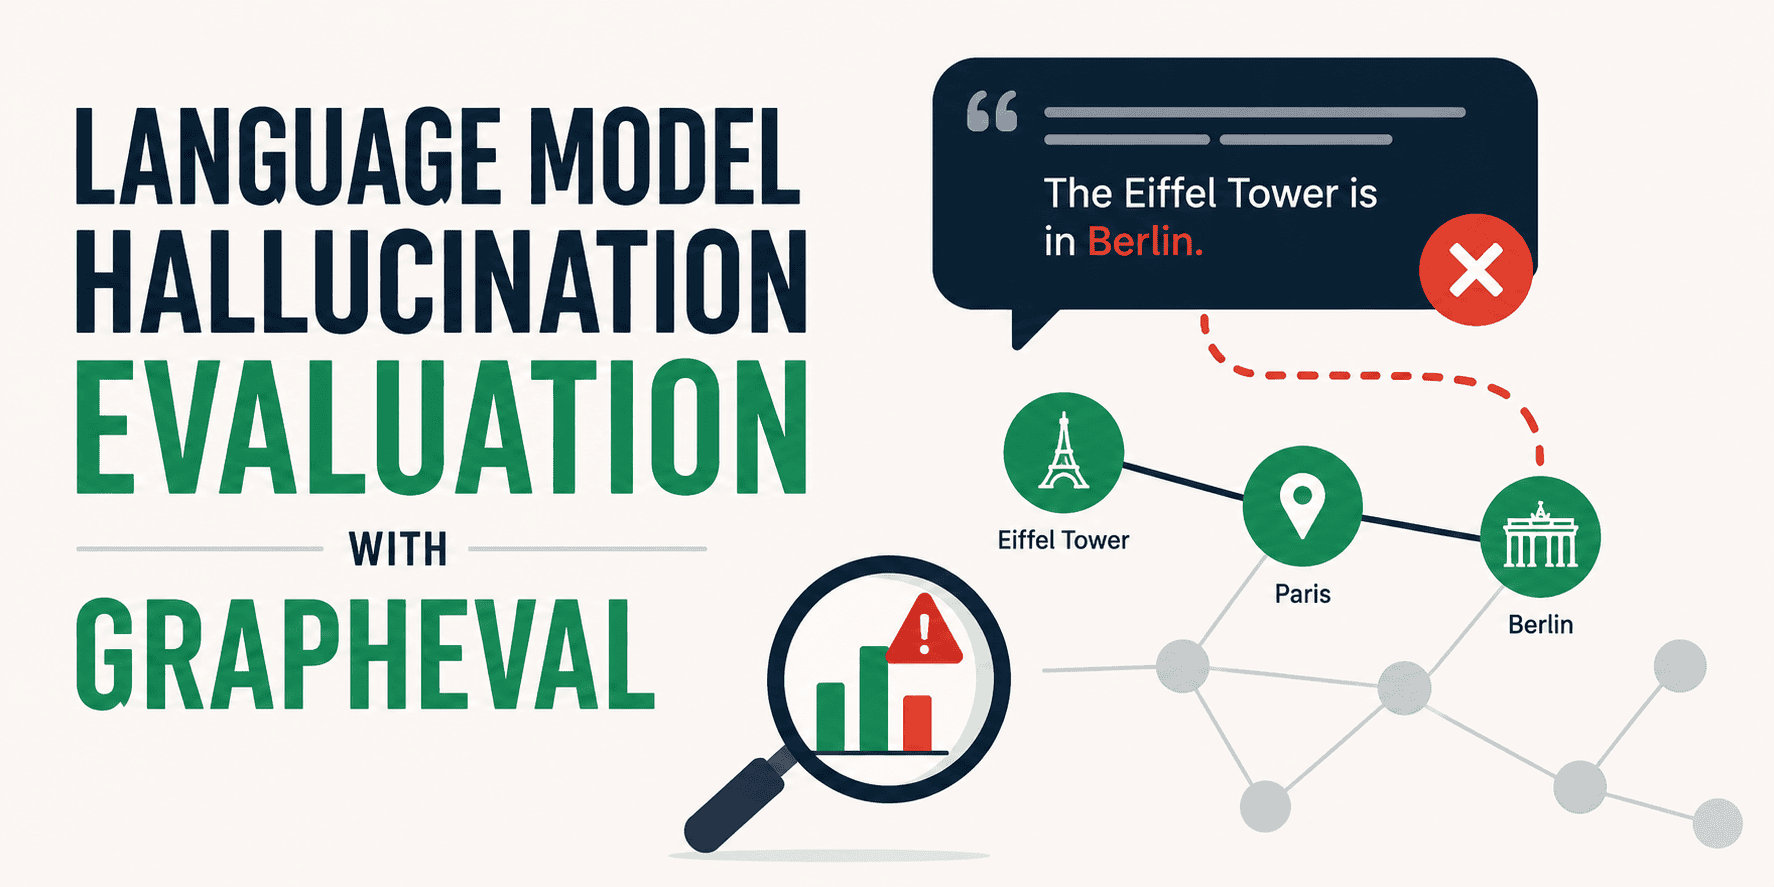
Hallucinations are one of many best-known issues that giant language fashions (LLMs) might expertise when producing responses. They happen when a mannequin produces a response that’s factually incorrect, nonsensical, or just made up, usually because of the mannequin’s lack of inner data on the matter.
Whereas many options have arisen in recent times to deal with the issue of mannequin hallucinations, methodological analysis frameworks for internally diagnosing them have been comparatively much less studied. One latest examine by Amazon researchers proposes utilizing data graphs as a method to investigate and detect hallucinations occurring in LLMs. The framework offered within the examine is called GraphEval.
On this article, we are going to take a delicate, sensible strategy as an instance the conceptual constructing blocks of GraphEval by means of a simulation-based, light-weight code instance that you would be able to simply strive in your machine.
# GraphEval in a Nutshell
GraphEval leverages data graphs to establish and sign hallucinations in LLM-generated outputs. In contrast to classical efficiency metrics that present single scores to judge elements like accuracy, certainty, and so forth, GraphEval applies a two-stage analysis course of that emphasizes explainability, particularly, offering insights into the place precisely the hallucination happened.
To do that, GraphEval considers two phases:
Developing a data graph from the generated mannequin response. The graph consists of semantic triples of the shape (Topic, Relationship, Object), the place topics and objects correspond to nodes, and relationships correspond to the sides connecting these nodes.
Evaluating every triple within the constructed data graph in opposition to a supply context (a ground-truth physique of data) by means of a pure language inference (NLI) mannequin. Any triple that can not be entailed by the context in keeping with the NLI engine — as a result of it’s contradictory or impartial — is flagged as a hallucination.
# Illustrating GraphEval By a Code Instance
Earlier than beginning the code that simulates the appliance of the GraphEval framework, let’s ensure now we have the required libraries put in:
!pip set up -q transformers networkx matplotlib torch
The aim of the code instance we’re about to stroll by means of is to demystify how the GraphEval methodology works, so we are going to change the phases that will demand a heavy computational burden in a real-world setting with simulated, light-weight options.
Accordingly, we are going to simulate a ground-truth data base (context) assumed to comprise factual info. In a manufacturing setting, this ground-truth data would stem, for example, from retrieving related paperwork from the vector database of a retrieval-augmented era (RAG) system. For simplicity, right here we instantly create a ground-truth context and retailer it in source_context.
# The bottom-truth context supplied to the LLM
source_context = (
    "GraphEval is a hallucination analysis framework primarily based on representing info "
    "in Information Graph (KG) buildings. It acts as a pre-processing step and makes use of "
    "out-of-the-box NLI fashions to detect factual inconsistencies."
)
Now, let’s suppose the next is the unique LLM response to a person immediate like “clarify succinctly what GraphEval is”. To provoke the primary stage of the analysis course of, we’d ask an auxiliary LLM to construct the data graph from that response. Each the response and the follow-up immediate used to acquire the data graph are proven under:
# The generated response we wish to consider (comprises a hallucination)
llm_output = (
    "GraphEval is an analysis framework that makes use of Information Graphs. "
    "It requires a extremely costly, enterprise-level server farm to function."
)

# Immediate template that will theoretically be handed to an area/free LLM (e.g. Mistral-7B)
KG_EXTRACTION_PROMPT = f"""
You're an knowledgeable info extractor. Extract the core info from the next textual content as a Information Graph.
Return the output strictly as a Python record of tuples within the format: (Topic, Relationship, Object).

Textual content: {llm_output}
"""
As soon as once more, for the sake of simplicity and to bypass the in any other case heavy computational load of working a large LLM domestically, let’s suppose the next graph triples are obtained:
# Simulated extraction to bypass the heavy computational load of working a large LLM domestically
extracted_triples = [
    ("GraphEval", "is", "evaluation framework"),
    ("GraphEval", "uses", "Knowledge Graphs"),
    ("GraphEval", "requires", "expensive enterprise server farm")
]

print("Extracted Triples:")
for t in extracted_triples:
    print(t)
Output:
Extracted Triples:
('GraphEval', 'is', 'analysis framework')
('GraphEval', 'makes use of', 'Information Graphs')
('GraphEval', 'requires', 'costly enterprise server farm')
We intentionally added a triple that’s essentially a hallucination (no enterprise server farm wanted in any respect!), so we will exhibit how the next NLI course of utilized to the data graph reveals it.
Sufficient simulated steps for right now. Let’s get into the true motion for the following stage: the NLI course of. The following piece of code is key to leveraging the concepts behind GraphEval. It makes use of a pre-trained NLI mannequin from Hugging Face — the mannequin is publicly out there, so no entry token is required to obtain it — to check every triple in opposition to the ground-truth context. If no entailment is “predicted” by the NLI mannequin for a given triple, it’s labeled as a hallucination.
from transformers import pipeline

# Loading the open-source NLI mannequin
print("Loading DeBERTa NLI mannequin...")
nli_evaluator = pipeline("text-classification", mannequin="cross-encoder/nli-deberta-v3-small")

def evaluate_triple(context, triple):
    topic, relation, obj = triple
    speculation = f"{topic} {relation} {obj}"

    # Checking if the context entails the speculation
    consequence = nli_evaluator({"textual content": context, "text_pair": speculation})

    # NLI fashions usually output: 'entailment', 'impartial', or 'contradiction'
    label = consequence['label'].decrease()

    # In GraphEval, something aside from 'entailment' is flagged as a hallucination
    is_hallucinated = label != 'entailment'

    return is_hallucinated, label, speculation

# Operating the analysis pipeline
evaluation_results = []

print("n--- GraphEval Outcomes ---")
for t in extracted_triples:
    is_hallucinated, nli_label, speculation = evaluate_triple(source_context, t)
    evaluation_results.append((is_hallucinated, nli_label))

    standing = "🚨 HALLUCINATION" if is_hallucinated else "✅ GROUNDED"
    print(f"{standing} | Triple: {t} | NLI Output: {nli_label}")
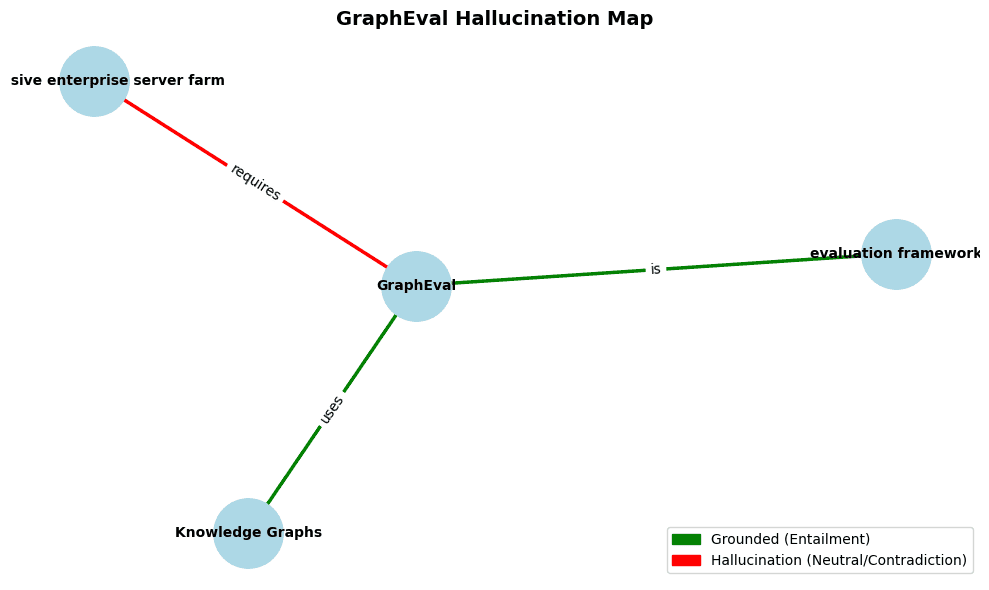
As we anticipated, the final triple within the data graph is detected as a hallucination.
To complete with a visible contact, we will additionally show the data graph of the unique LLM response alongside the detection outcomes:
import networkx as nx
import matplotlib.pyplot as plt
import matplotlib.patches as mpatches

def visualize_grapheval(triples, eval_results):
    G = nx.DiGraph()
    edge_colors = []

    for (triple, res) in zip(triples, eval_results):
        sub, rel, obj = triple
        is_hallucinated = res[0]

        G.add_node(sub)
        G.add_node(obj)
        G.add_edge(sub, obj, label=rel)

        # Colour-code the sides primarily based on the NLI analysis
        edge_colors.append('pink' if is_hallucinated else 'inexperienced')

    # Arrange the plot
    plt.determine(figsize=(10, 6))
    pos = nx.spring_layout(G, seed=42)

    # Draw nodes
    nx.draw_networkx_nodes(G, pos, node_color="lightblue", node_size=2500)
    nx.draw_networkx_labels(G, pos, font_size=10, font_weight="daring")

    # Draw edges and labels
    nx.draw_networkx_edges(G, pos, edge_color=edge_colors, width=2.5, arrowsize=20)
    edge_labels = nx.get_edge_attributes(G, 'label')
    nx.draw_networkx_edge_labels(G, pos, edge_labels=edge_labels, font_color="black")

    # Add legend
    green_patch = mpatches.Patch(coloration="inexperienced", label="Grounded (Entailment)")
    red_patch = mpatches.Patch(coloration="pink", label="Hallucination (Impartial/Contradiction)")
    plt.legend(handles=[green_patch, red_patch], loc="decrease proper")

    plt.title("GraphEval Hallucination Map", fontsize=14, fontweight="daring")
    plt.axis('off')
    plt.tight_layout()
    plt.present()

# Render the data graph
visualize_grapheval(extracted_triples, evaluation_results)
Ensuing visualization:
# Closing Remarks
GraphEval is an analysis methodology proposed to assist detect and localize the basis reason for hallucinations in LLM outputs. This text turned its key rules and methodological phases right into a simulated sensible state of affairs to raised perceive its usefulness and its key implications for potential implementation in manufacturing methods.
Iván Palomares Carrascosa is a pacesetter, author, speaker, and adviser in AI, machine studying, deep studying & LLMs. He trains and guides others in harnessing AI in the true world.
The takeaway: There was a degree not way back when Intel was in a lot hassle {that a} takeover of the corporate appeared inevitable. Now, Workforce Blue has turned its enterprise round to the purpose the place it is simply skilled its quickest progress in 15 years, but it surely’s come at a really excessive value.
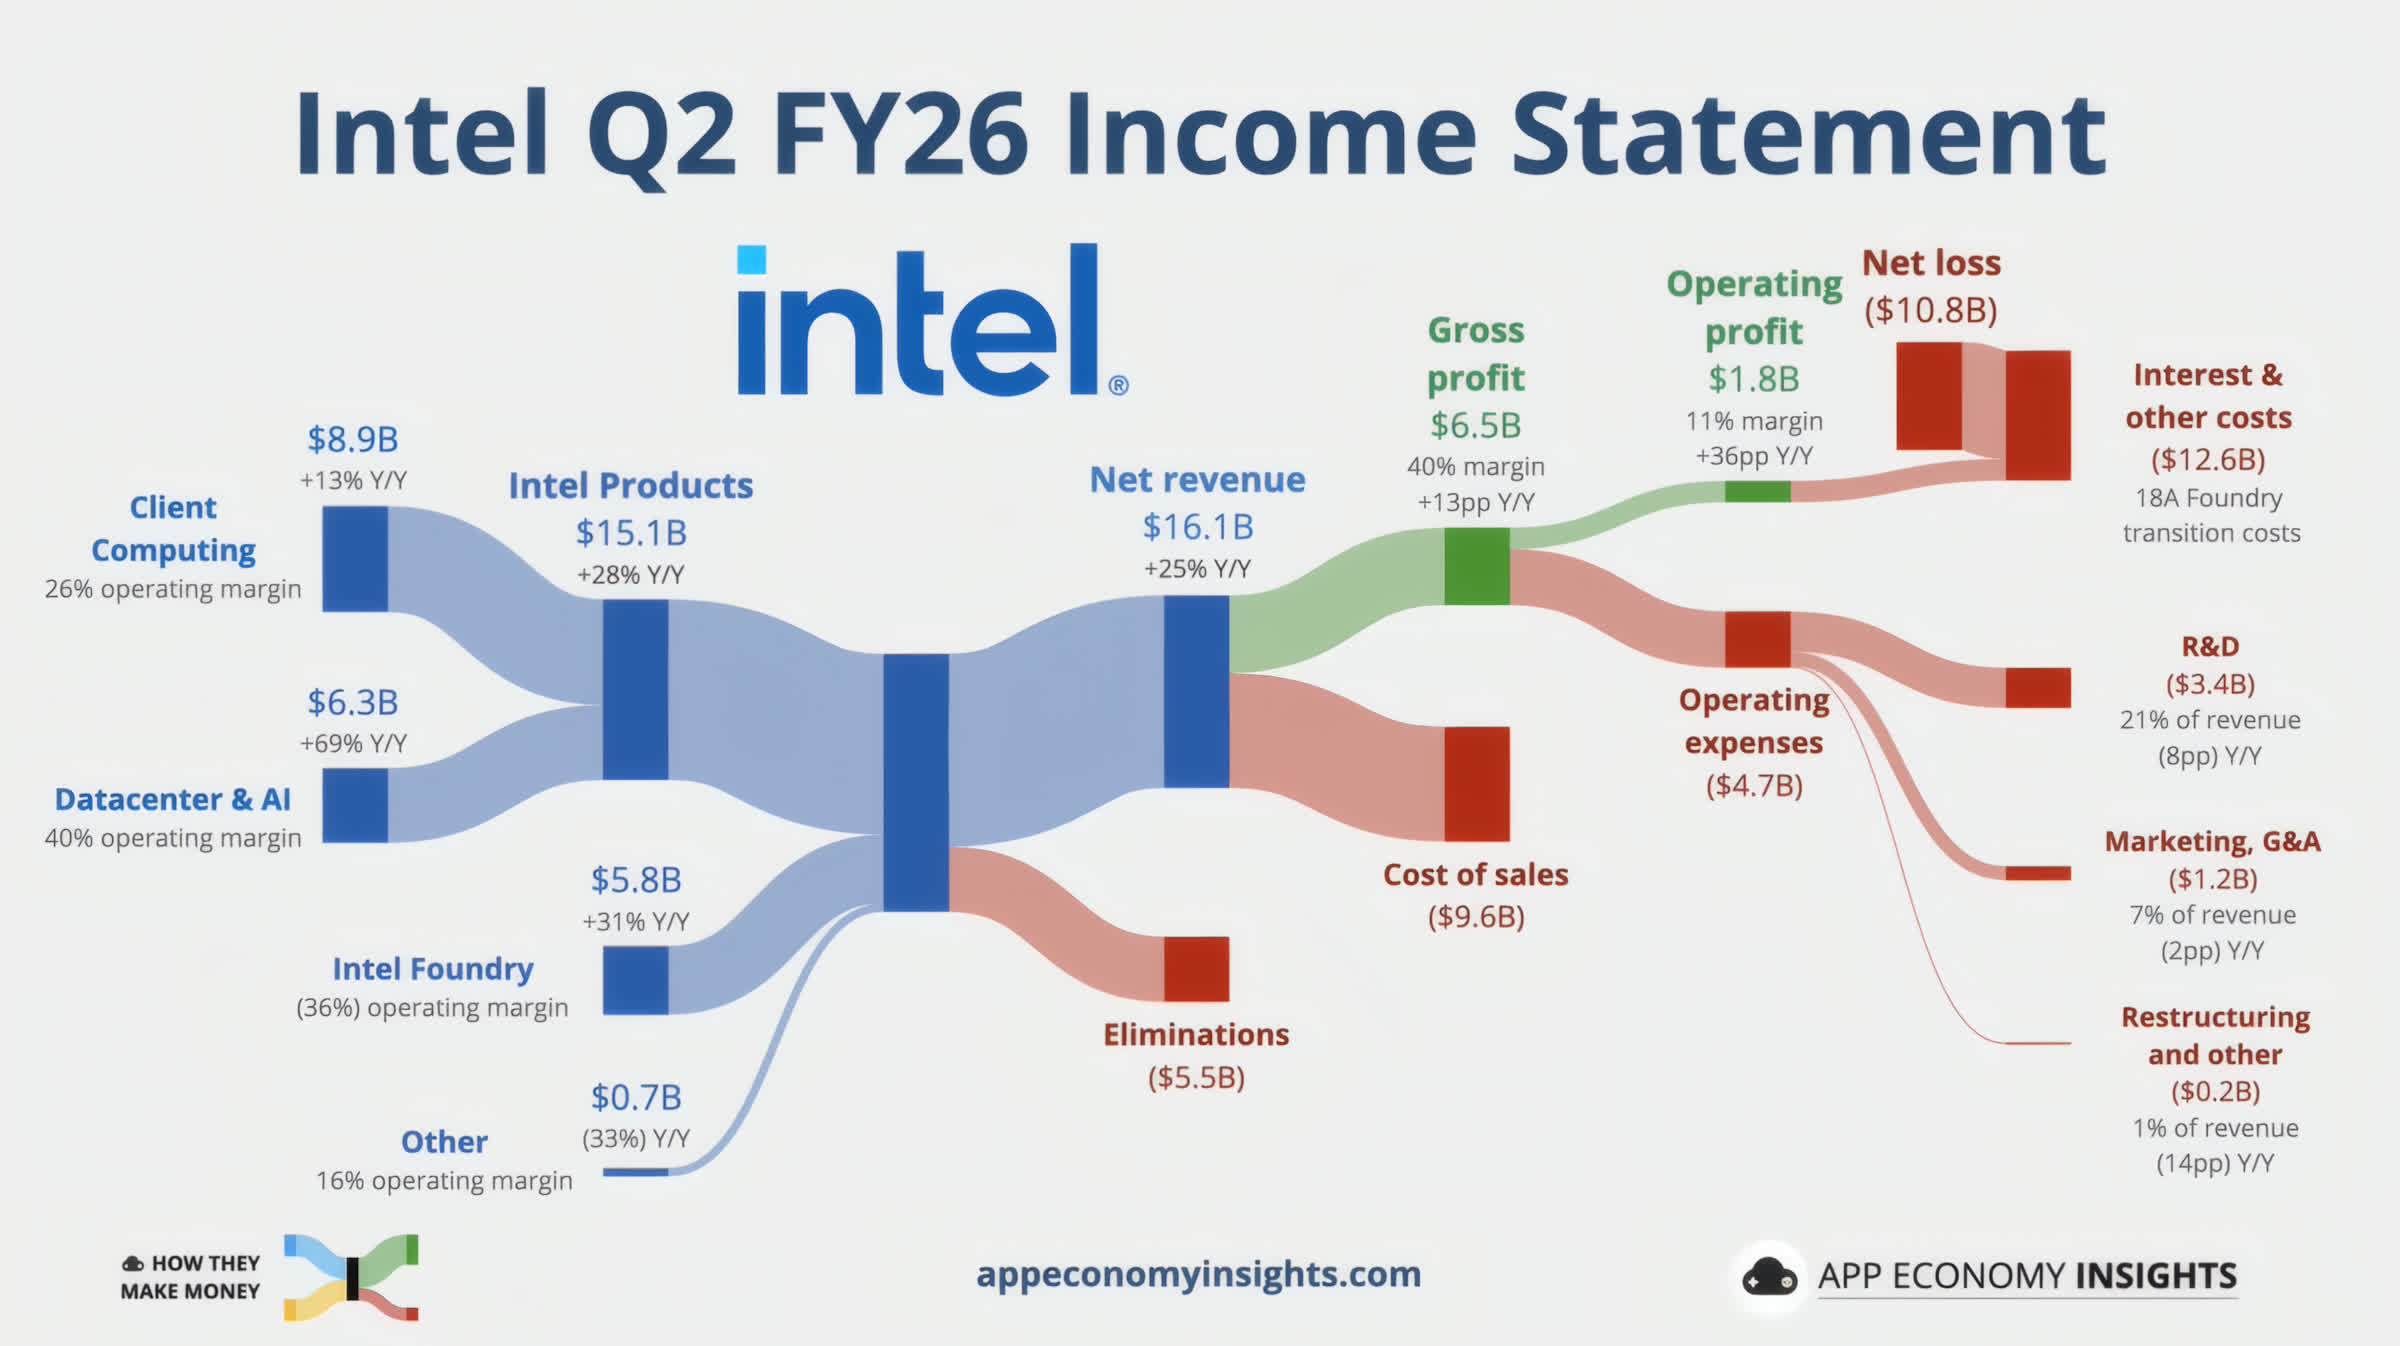
Intel reported second-quarter income of $16.1 billion, up 25% yr over yr and effectively forward of Wall Avenue’s expectations. Adjusted earnings reached $0.42 per share, virtually double analysts’ forecasts, whereas the corporate expects current-quarter gross sales of between $15.8 billion and $16.8 billion.
Courtesy of the Monetary Occasions
As with so many tech giants, Intel’s greatest contributor was its Information Heart and AI division. Income from the unit jumped 59% to $6.3 billion as demand for CPUs used alongside AI accelerators continued to surge. The Consumer Computing and Bodily AI group grew 13% to $8.9 billion, whereas foundry income elevated 31% to $5.8 billion.
However the AI increase can also be creating issues for Intel’s conventional PC enterprise. Reminiscence producers have redirected capability towards high-margin data-centre merchandise, contributing to the well-documented shortages and rising costs for shopper {hardware}. Intel expects PC demand to be weaker than regular in the course of the second half of 2026 and the market to say no by a low-double-digit proportion for the total yr.
The outcomes mark an unimaginable flip round in fortunes in comparison with latest years, when Intel’s server CPU shipments had fallen to a 14-year low. The corporate recorded an $18.8 billion annual web loss in 2024, its first since 1986, and the foundry division misplaced greater than $13 billion. Studies that Qualcomm may purchase Intel and that TSMC may take management of its manufacturing operations now not sounded far-fetched – even our latest ‘AMD to purchase Intel‘ April Fools’ joke was plausible sufficient to persuade lots of people.
However the newest outcomes got here with caveats. Intel did submit an $11 billion GAAP web loss, although this was primarily on account of a $12.5 billion mark-to-market cost linked to shares held in escrow underneath the US authorities’s funding deal. On an adjusted foundation, the corporate made a $2.2 billion revenue.
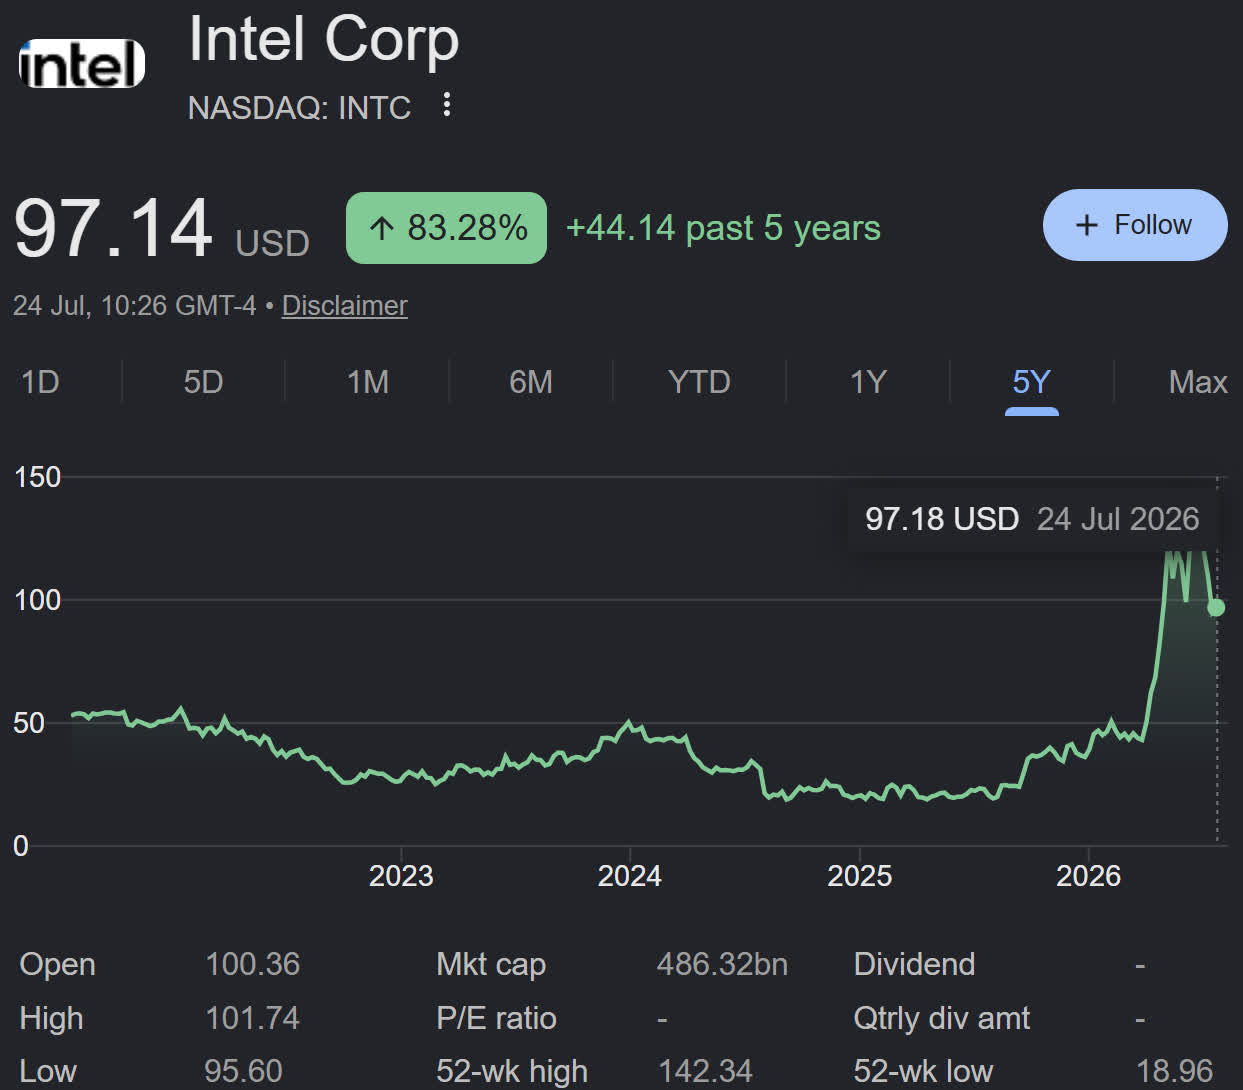
Intel’s share worth has surged this yr
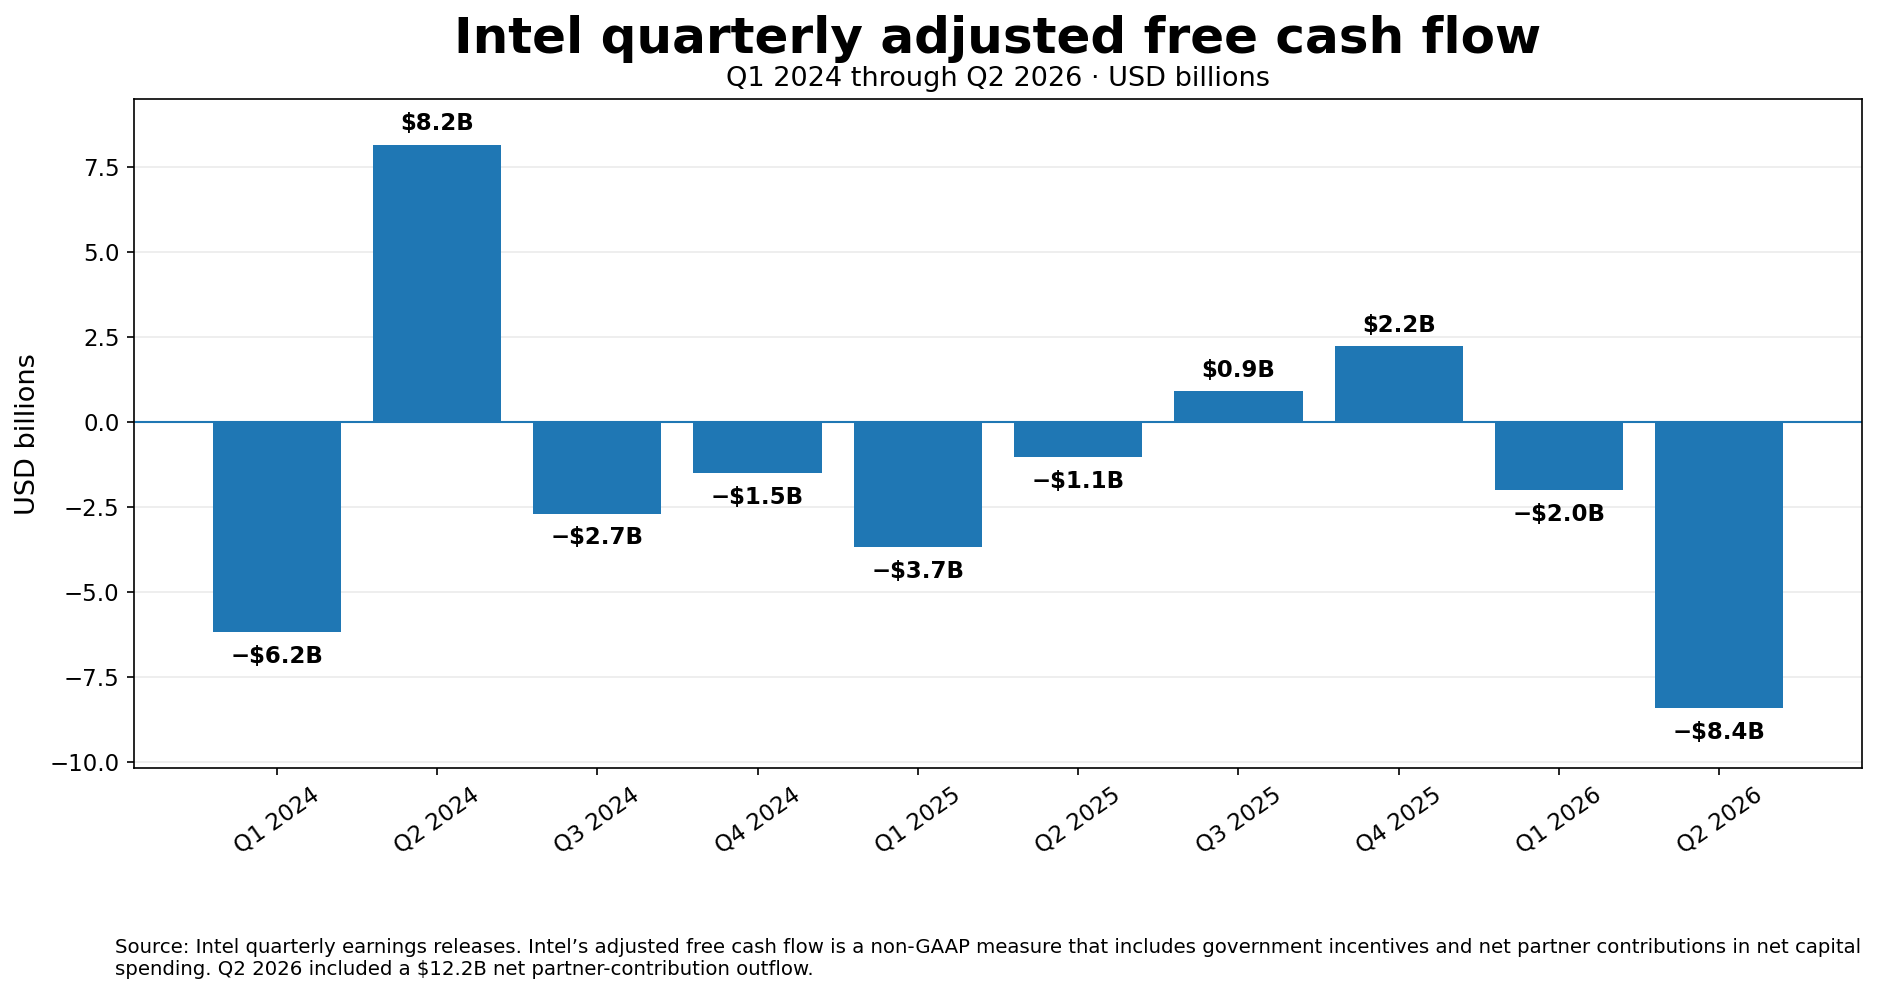
Intel additionally recorded destructive adjusted free money circulate of $8.4 billion, in contrast with destructive $1.1 billion a yr earlier. Nevertheless, the determine was closely affected by a $12.2 billion web outflow associated to companion contributions and $617 million in finance lease funds. The underlying enterprise generated $7 billion in working money circulate in the course of the quarter.
However, Intel is about to spend significantly extra. It raised its 2026 capital expenditure forecast from $18 billion to greater than $20 billion and warned that subsequent yr’s complete shall be “considerably above” this yr’s degree. The cash will go towards gear, clean-room area, substrates, and increasing manufacturing capability.
Intel will not be alone in seeing booming AI-related progress accompanied by destructive money circulate. Google lately reported its first destructive free money circulate since going public, at $5.9 billion, as annual capital spending heads towards $205 billion. Tesla additionally recorded destructive free money circulate of $1.1 billion whereas getting ready to spend as much as $25 billion this yr.
Intel’s foundry operation continues to battle, shedding $2.1 billion in the course of the quarter and nonetheless missing the key exterior clients wanted to justify its large investments. However after years of delays, layoffs, shrinking market share, and questions on its very survival, CEO Lip-Bu Tan’s “New Intel” is lastly starting to resemble the business large it as soon as was.
Local weather change has now turn into an issue for the entire photo voltaic system. On Friday, wildfires in Spain overran one in all three observatories the US Nationwide Aeronautics and Area Administration makes use of to attach with spacecraft, together with Voyager 1, the James Webb Area Telescope, and the lately accomplished Artemis mission across the Moon.
Spain declared a wildfire emergency as a number of blazes burned uncontrolled close to Madrid, with evacuation orders in place for 60,000 folks. The affected space contains Robledo de Chavela, a municipality close to the Deep Area Communications Advanced run by NASA.
Dramatic photos captured by information photographers confirmed the radio telescopes surrounded by smoke and hearth. A NASA spokesperson mentioned in an e-mail to WIRED that the company efficiently evacuated all personnel.
They added that whereas the fireplace has now handed by way of the observatory complicated, it stays unclear what impression the flames might have had on the delicate tools inside. “Any potential injury will likely be assessed when it’s secure to take action,” the spokesperson mentioned. They add that if situations permit, a website evaluation might occur as quickly as Saturday.
For now, NASA mentioned it has “seamlessly transitioned help for mission operations to the Goldstone Deep Area Communications Advanced in California, making certain continuity of service and uninterrupted help for spacecraft communications.”
The ability in Spain, together with the others in Canberra, Australia, and Goldstone, California, make up what NASA calls the “largest and most delicate scientific telecommunications system on the planet.” The community permits NASA to transmit info from Earth to spacecraft, together with essentially the most distant human-made object in our photo voltaic system, Voyager 1. It’s additionally used to switch information from the James Webb Area Telescope and ship instructions to different house autos. Oh, and the websites additionally contribute to radio astronomy observations. Suffice to say, it’s an important assortment of devices for understanding the photo voltaic system.
Spain is way from the one nation going through a wildfire disaster. Blazes are additionally burning uncontrolled in France, the place beachgoers noticed skies flip orange and waves of ash washing ashore as firefighters labored to cease flames from spreading into the eponymous capital of the Bordeaux wine area.
“We realized in the course of the afternoon that, following the wind shift, it had turn into a big, self-sustaining hearth that’s extraordinarily tough to carry beneath management,” French inside minister Laurent Nunez advised nationwide tv channel Tf1. “It’s now transferring east, towards the Bordeaux metropolitan space. We’re going to reorganize our response so we are able to battle it from the bottom and stop it from advancing.”
Roughly 200,000 folks have been advised to evacuate throughout the 2 nations.
Europe has seen report excessive temperatures this summer season, pushed by repeated warmth domes tenting over the continent and the UK, in addition to local weather change. Scorching climate can dry out vegetation, priming forests to burn when hit by an errant spark. Related tales have performed out in different elements of the world lately, from Ontario, Canada, to the US Pacific Northwest.
Cooler climate is predicted to reach within the Mediterranean over the weekend, which ought to assist firefighters get a deal with on the blazes. However the respite will likely be brief: Temperatures are anticipated to shoot up once more on Monday and preserve climbing all through the week, finally reaching as much as 10 levels Celsius (18 levels Fahrenheit) above regular. That would worsen any wildfires in Spain or France which will nonetheless be burning—or assist spark new ones.