Each occasions, it have to be confused, are a direct results of precisely the sort of stupid-and-cruel warfighting that Pete Hegseth promised to convey to the US army and has delivered.
Our military will turn out to be, by inches, increasingly more just like the Russian one: merciless, incompetent, impotent, incapable, depraved.
Yeah, so additionally, VLCCs (‘very massive crude carriers’) that do the lion’s share of world oil transport are considerably bigger than Suezmax, so if the Bab al-Mandab (the strait because the southern finish of the Pink Sea) is closed, you possibly can’t get these VLCCs to Yanbu. 😬
“..
Firstly of July, prediction markets thought that visitors would
most likely return to regular by the tip of the month. Now that probability is
seen — absolutely appropriately — as near zero. Not solely is the scenario
unhealthy, nevertheless it’s deteriorating.”
👀 El Salvador’s AI Company has named Ginger Luckey Gaetz (Matt Gaetz’s spouse, Palmer Luckey’s sister) as Strategic Advisor. Palmer’s agency Anduril is backed by Peter Thiel & companions w/ Palantir.
El Salvador not too long ago joined the Thiel-ally-led “Pax Silica” world initiative. They’re transferring quick…1/
The Odyssey is pulling $260 million this weekend, nicely on its strategy to turning into the most important film of the yr. It has a 95%/97% score on Rotten Tomatoes. Everybody loves it.
Matt Walsh complains that Nolan introduced his obsession with nonlinear story telling to the Odyssey, undercutting the unique’s narrative. The defenders of western civilisation, people.
the odyssey discourse is a wonderful good window into proper wing tradition warfare psychosis. they went from hysterial racist mania over a personality that’s on display for five minutes to claiming there’s an enormous conspiracy to pretend ticket gross sales. that is simply what they do for every thing now. they’re insane
ah sure, air taxis and supersonic jets, two very important and primed-for-success concepts which might be simply being held again by reckless bureaucrats
this comparability leaves out a key level: the Edsel offered roughly twice the Cybertruck’s quantity at a time when the general automobile market was simply 6m items/yr as an alternative of the present 16m items/yr
that makes the Cybertruck the a lot, a lot larger flop, palms down
one other key distinction: by the point the Edsel got here out Ford was not value greater than the remainder of the auto business mixed, so when it comes to market mispricing relative to efficiency Tesla and the Cybertruck are additionally in a wholly completely different league
mannequin predicts the lacking column of any desk, zero-shot, the way in which a language mannequin completes textual content. On the principle neighborhood benchmark, each single-model entry above the most effective tuned gradient-boosted tree is now certainly one of these. This submit explains what they’re, verifies the strongest one with unrestricted open weights by myself {hardware}, and maps the place the bushes nonetheless win.
Determine 1: Accuracy versus serving value on TabArena (official board, snapshot 2026–07–15). TabICLv2 (blue) sits on the cheap-and-accurate frontier amongst fashions anybody can obtain and test; TabFM (hole) tops the board however ships no paper, and the tree household (squares) sits 150+ Elo decrease at comparable serving value. 📖 Supply: picture by creator.
There’s a pretty new class of mannequin for tables: pretrained transformers that predict on any spreadsheet zero-shot, loosely referred to as “tabular LLMs”. On the TabArena leaderboard, each single-model entry above the most effective tuned, ensembled GBDT configuration is certainly one of them; the one entries above it that aren’t are AutoGluon’s 4-hour ensemble pipelines. That inverts the default reply of the final decade, which was to suit a tuned gradient-boosted tree. Leaderboards have been improper earlier than, in ways in which solely present up when an outsider re-runs them (that was my expertise with time-series fashions), so earlier than believing this one I audited it. I recomputed the board’s scoring from its revealed artefacts, took TabICLv2, the strongest mannequin on it with unrestricted open weights, and re-ran it from scratch on {hardware} I managed.
My impartial run coated all 51 datasets on the benchmark’s official Lite protocol (one practice/take a look at break up per dataset, the identical break up indices the leaderboard makes use of) on a single AWS A10G. Scored towards the official artefact rows on these an identical splits, my TabICLv2 lands at Elo 1559 towards the official 1575, adjoining ranks and nicely contained in the ±60–86 bootstrap intervals. Per process, 16 of the 51 metric values got here again an identical to 4 decimal locations, the median relative distinction was 0.08%, and the worst dataset differed by 3.5%, the dimensions of hole you’d count on from GPU nondeterminism moderately than a strategy distinction. The entire sweep, setting setup included, fitted in a 2.1-hour GPU session that value simply over $2.
What a tabular basis mannequin is
A tabular basis mannequin is a single pretrained mannequin that predicts on any desk, zero-shot. You hand it the rows whose labels you already know as context, the way in which you’ll paste labored examples into an LLM immediate, and it predicts the labels of the held-out rows in a single ahead cross. Nothing gradient-trains in your information and there’s no hyperparameter search; the step each different tabular methodology calls “coaching” turns into inference. The literature calls this in-context studying, and the TabPFN papers established that it really works for tables.
It behaves like a realized k-nearest-neighbours: to label a held-out row, the mannequin attends over the rows whose labels it could see and reads off a solution weighted by how comparable they’re. The distinction from peculiar k-NN is that the similarity, and the way in which neighbours are mixed, come from pretraining moderately than being mounted prematurely.
The household has grown quick since: TabPFN’s successors (Prior Labs), TabICL and TabICLv2 (Inria’s SODA crew), TabDPT (Layer 6), and, two weeks earlier than this submit, Google Analysis’s TabFM. All of them seem within the standings under.
The “LLM” in “tabular LLM” is unfastened. These fashions are transformers, however they don’t mannequin language, they usually differ from a textual content LLM in each ingredient. A textual content LLM’s token is a word-piece from a hard and fast vocabulary; a tabular mannequin’s uncooked materials is the cells, columns, and rows of a desk, numbers and classes with no mounted vocabulary in any respect, since your desk’s columns have by no means been seen earlier than and the mannequin has to manage anyway. A textual content LLM pretrains on web textual content with next-token prediction; a tabular basis mannequin pretrains on tens of millions of small artificial tables generated by random structural causal fashions (random cause-and-effect graphs wired as much as emit believable pretend datasets), and its goal is to foretell the held-out cells and labels of these tables. Pretraining instils a normal process for studying a recent desk and inferring how its options relate to its goal, moderately than data in regards to the world. One consequence is measurement. Tables carry much less floor complexity than language, so tens of tens of millions of parameters are sufficient: TabICLv2 is about 28M, towards t0-alpha’s 102M and a textual content LLM’s billions.
The distinction with the time-series basis fashions from the t0 submit comes right down to order. A time sequence has one: t0, Chronos, and TimesFM apply causal consideration alongside time, solely ever trying on the previous, and forecasting means persevering with the sequence past its finish. A desk has no row order. Shuffle the rows and it’s the similar desk, so the structure wants the other property: predictions should not rely on how the spreadsheet occurred to be sorted. (Column order is unfair too, however TabICLv2 handles it in another way, it intentionally offers options positions once more, by way of rotary embeddings and have grouping, to maintain every column’s identification distinct; the structure determine under reveals the place.) The duty shifts accordingly, from extrapolating previous the noticed vary to filling in a single lacking column for the held-out rows. The 2 fields converged on the identical habits regardless. Each pretrain on artificial information (universally right here, by way of the SCM priors; partially in time sequence), and each emit distributions moderately than factors: t0 outputs 9 quantiles, TabICLv2’s regression head 999.
One ambiguity carries over from the time-series submit. “Tabular LLM” generally additionally names a distinct line of labor, by which an precise textual content LLM is prompted with a desk serialised into textual content, as TabLLM does. Every little thing on this submit is in regards to the table-native basis fashions, however this time I measured the serialise-and-prompt line too: it loses to the table-native mannequin on 43 of 49 datasets (particulars under).
What TabICLv2 is: small, open, reproducible
TabICLv2 is certainly one of these in-context learners. Becoming takes seconds, and there aren’t any hyperparameters to go looking. Beneath the label it’s three transformers stacked, every answering a distinct query in regards to the desk, and it reads most simply in that order.
The first transformer reads down every column, one function at a time. Its job is to show a uncooked worth into an embedding that is aware of what sort of quantity it’s taking a look at, as a result of the identical digits imply various things in numerous columns. A 450 in a worth column and a 450 in a postcode column are unrelated, and a mannequin that solely sees the quantity has no technique to inform them aside. This stage is a set transformer: it treats a column as an unordered set of values, learns that column’s distribution, and offers every cell an embedding that displays the place the worth sits inside its personal function. So one 450 turns into “a reasonably low cost merchandise” and the opposite turns into “one explicit space code”, from the identical enter quantity.
The second transformer reads throughout every row and collapses it to a single vector. After the primary stage a row is a bag of per-feature embeddings, one for every column. A row is a set, and the usual technique to summarise a set with a transformer is so as to add just a few realized question tokens (the [CLS] tokens) and allow them to attend over the members. Right here 4 [CLS] tokens per row pull collectively the elements of the row that matter, and their outputs are concatenated into one row vector. No matter variety of columns the row began with, it’s now a single fixed-length vector standing in for the entire instance.
The third transformer does the prediction, and that is the place the in-context studying occurs. No gradient descent runs at prediction time. As an alternative each unlabelled test-row vector attends over all of the labelled train-row vectors, finds the coaching rows most like itself, and reads a label from them. The eye runs a technique solely, from take a look at rows onto practice rows, so the labelled examples inform the predictions however by no means the reverse. It’s nearest-neighbours reasoning performed with consideration: the mannequin seems on the examples whose solutions it already is aware of, weighs them by similarity to the row in entrance of it, and predicts from them. The coaching set is fed in as context moderately than baked into the weights, which is why you may level the mannequin at a desk it by no means noticed in pretraining and get a prediction with out coaching something.
Two heads sit on high, one per process kind. For classification, a hierarchical classifier assigns the label and works for any variety of lessons. For regression, the top doesn’t emit a single quantity; it emits 999 quantiles, its estimate of the 0.1st percentile, the 0.2nd, and so forth as much as the 99.ninth. That offers the total predictive distribution as a substitute of a lone level estimate, so you may learn a median and an trustworthy interval round it.
These 999 quantiles are skilled with pinball loss, and it’s value seeing why that loss produces quantiles in any respect. For a goal quantile, say the ninetieth percentile, pinball loss costs a distinct worth for being too low than for being too excessive. Undershoot the true worth and also you pay 0.9 × error; overshoot and also you pay solely 0.1 × error. That asymmetry pushes the prediction upward till about 90% of the actual values fall under it, which is the definition of the ninetieth percentile. Apply the identical rule to all 999 targets directly and every output settles at its personal slice of the distribution. The identify comes from the form of the loss plotted towards the error: a lopsided V, steep on one aspect and shallow on the opposite, like the lean of a pinball desk. On the median it’s symmetric and reduces to plain mean-absolute error.
The main points that allow v2 scale the place v1 stalled are within the paper: a query-aware rescaled softmax (QASSMax) so consideration doesn’t fade over lengthy context, function grouping that breaks the symmetry between columns, and goal embeddings injected early.
Determine 2: TabICLv2’s three-stage structure. A set transformer embeds every column of the enter desk (3 blocks, target-aware), consideration onto CLS tokens collapses every row to a single vector (3 blocks, RoPE), and 12 in-context-learning blocks let the unlabelled take a look at rows attend to the labelled practice rows. Two heads emit the predictions: a hierarchical classifier for any class depend, and a regression head producing a 999-quantile distribution. All layer counts verified towards the launched supply; 27.6M/28.5M parameters counted from the checkpoints. 📖 Supply: picture by creator.
Three properties make it the proper audit goal: small, open, and reproducible directly. The weights are on HuggingFace beneath BSD-3 with no gating and no click-through licence; pip set up tabicl and it runs. Loading the 2 checkpoints and counting offers precisely 27,552,258 parameters for the classifier and 28,544,991 for the regressor, so “about 28M” comes from counting the tensors within the downloaded checkpoints. That’s roughly 1 / 4 of t0-alpha’s measurement, for a mannequin that tops tuned GBDTs. Its predominant rivals don’t share the property in full: the TabPFN line (Prior Labs) publishes weights beneath a non-commercial licence with a licence-acceptance step in its tooling, and TabFM (Google Analysis) shipped weights beneath a non-commercial licence with no paper in any respect. Open weights matter right here for a similar motive as earlier than: anybody can rerun the analysis and test the declare.
TabICLv2 can be pretrained purely on artificial information, generated from random structural causal fashions. No real-world desk enters pretraining, so no benchmark dataset can leak into it. The contamination part under units this towards the newer fashions that add actual pretraining information.
Making an attempt one by yourself desk
The sensible floor is scikit-learn. TabICLv2 installs with pip set up tabicl, downloads its checkpoint from HuggingFace on first use, and accepts a pandas DataFrame with categorical columns and lacking values as-is:
from tabicl import TabICLClassifier # TabICLRegressor for regression
clf = TabICLClassifier() # defaults are fantastic: no hyperparameter search
clf.match(X_train, y_train) # seconds: shops context, no gradient coaching
proba = clf.predict_proba(X_test) # one ahead cross
It runs on CPU for small tables, however the pace numbers on this submit are GPU numbers; a single shopper GPU is the meant dwelling. The working vary is bounded: TabICLv2 was pretrained on tables of roughly 300 to 48,000 coaching rows, the benchmark under tops out at 150,000 rows, and my regime evaluation later within the submit reveals accuracy degrading on very large tables (over ~100 options). Inside that envelope, the mannequin gained 86–88% of datasets towards the tuned bushes in my regime evaluation and suits in seconds; outdoors it, the bushes part under is the place to look.
The benchmark, and the half I verified myself
TabArena is 51 curated datasets spanning binary classification, multiclass, and regression, from 748 to 150,000 rows and 5 to 1,777 options. Each methodology is evaluated with repeated cross-validation (9–30 splits per dataset), fashions are in contrast with task-appropriate metrics (ROC-AUC, log-loss, RMSE), and the combination is an Elo ranking: every pairwise per-task comparability is a “sport”, and the size is anchored so a default RandomForest sits at 1000 and a 400-point hole means 10:1 win odds. It’s a residing benchmark; strategies and outcomes get added repeatedly.
Earlier than quoting anybody’s Elo I needed to know I may recompute it. TabArena publishes its per-split outcomes as downloadable artefacts, so I ran the maintainers’ personal aggregation pipeline regionally over these artefacts, with their official constants (200 bootstrap rounds, imputed strategies excluded), and diffed my board towards the CSV behind tabarena.ai. All 69 strategies matched, 67 of 69 to inside ±1 Elo, and the ordering of the highest 30 got here out an identical (Spearman ρ = 0.99998 throughout the board). That test validates the scoring and aggregation code, the identical function the Seasonal-Naive match performed within the t0 submit. It doesn’t validate any mannequin’s personal predictions; that’s what the re-run is for.
The 2 rows that differed by greater than some extent had been tuned TabM configurations (+4 and +5 Elo); all three TabM variants’ runtime columns shifted as nicely, as a result of TabM’s outcomes artefact was up to date after the present web site snapshot was revealed. The benchmark is up to date repeatedly, so every little thing under is pinned to the 2026–07–15 snapshot.
The recomputation additionally confirmed that Elo is pool-dependent. My first try included the imputed strategies the web site excludes, and each ranking shifted by 10–30 factors. The per-dataset metrics within the artefacts are the pool-independent numbers; Elo summarises them relative to whichever pool you rating.
The standings
All Elo figures under are from the official board (snapshot 2026–07–15), which I recomputed to ±1 Elo from the revealed artefacts. These are full-protocol numbers (9–30 splits per dataset); my very own run makes use of the official Lite protocol (1 break up per dataset), so it seems as a separate comparability beneath the desk moderately than a row inside it.
Determine 3: TabArena Elo by mannequin, sorted. Each single mannequin above the most effective tuned-and-ensembled GBDT is a basis mannequin, and the one different entries above it are AutoGluon ensemble pipelines; TabICLv2 (blue) is the strongest with unrestricted open weights. Dashed line: the RandomForest anchor at 1000. 📖 Supply: picture by creator.
Limiting the entire pool to the Lite splits and merging in my recent run: official TabICLv2 scores 1575 there and mine 1559, ranks 5 and 6 on the identical board. The replica part above has the per-task numbers.
First, each single mannequin above the most effective GBDT configuration is a tabular basis mannequin; the one non-FM entries above it are the AutoGluon ensemble pipelines. LightGBM with full tuning and post-hoc ensembling reaches 1432; TabICLv2 with no tuning in any respect sits 158 Elo above it, and the gated TabPFN line greater nonetheless. On this board, at these dataset sizes (748 to 150k rows), the accuracy frontier belongs to the inspiration fashions. I didn’t count on the margin to be that large.
Second, the serving value complicates the standard defence of bushes (“positive, however they’re low cost”). TabICLv2’s median predict time is 0.38 s per 1,000 rows, sooner than tuned-and-ensembled LightGBM (2.64) and in the identical vary as tuned CatBoost. Its median match time, 4 s per 1,000 rows, is roughly a hundred instances shorter than the tuned GBDT protocols, as a result of becoming is a single ahead cross with no hyperparameter search. One caveat: the inspiration fashions run on a GPU and the bushes on CPU, so the dollars-per-row comparability relies on your infrastructure, and default CatBoost at 0.08 s/1K on a CPU continues to be the most cost effective sane possibility on the board. For scale: my total 51-dataset TabICLv2 sweep, on-demand A10G, value $2.
Third, TabFM sits on the high, 98 Elo away from the subsequent entry (the AutoGluon pipeline) and 123 away from the subsequent single mannequin, and it joined the board on 2026–06–30, two weeks earlier than I wrote this. The audit got here out higher than I anticipated on information and worse on documentation. Its pretraining is solely artificial, from structural-causal-model priors like TabPFN’s and TabICL’s, so benchmark contamination is dominated out by building for it too. What it lacks is a paper: there isn’t any technical report, no revealed parameter depend, and the weights carry a non-commercial licence the README doesn’t point out Christoph Molnar’s write-up. An impartial fold-matched re-test nonetheless discovered it forward of tuned XGBoost. I report its numbers and mark it as not-independently-run within the chart; the 123-Elo hole seems actual, however no person outdoors Google can but say why it really works.
Pasting the desk right into a frontier LLM, measured
I additionally put a quantity on the serialise-and-prompt line: Claude Opus 4.8 given every dataset as textual content, with 64 labelled instance rows within the immediate, then batches of take a look at rows to foretell and per-class chances requested as structured output. To maintain it reasonably priced this can be a decreased protocol: 50 subsampled take a look at rows per dataset, at most 32 columns proven, one batched API run over all 51 datasets. The subsample makes every per-dataset rating noisy, so learn the combination, not any single row.
The combination is one-sided. Two of the 51 datasets returned too few usable predictions to attain; on the remaining 49, the LLM beats TabICLv2 on 6 and the most effective tuned-and-ensembled GBDT on the identical 6, with a median error 57% greater than TabICLv2’s. It wins on churn, credit score and blood-donation tables, the place column names carry real-world which means an LLM can exploit. It loses badly on app-permission vectors and sensor and physical-process information, the place the desk is pure sample and the language prior contributes nothing. “Tabular LLM” as a phrase invitations conflating the 2 mannequin lessons; on this protocol the 28M-parameter table-native mannequin gained 43 of 49 datasets, and it serves a thousand rows for a fraction of a GPU-second the place the prompted LLM value me about $1.50 per thousand predictions.
What tuning does to the GBDT baselines
The primary objection any GBDT partisan will increase is tuning: no person ships default LightGBM, so a board that ran the bushes on defaults would oversell the inspiration fashions. TabArena already accommodates the reply, as a result of it runs each GBDT at three budgets: default config, tuned (an actual search, hours of compute), and tuned + post-hoc ensembled.
Tuning is value loads for LightGBM and XGBoost, on the order of 200 Elo, which is many of the distance between “mid-table” and “greatest tree on the board”. CatBoost is the exception: its defaults are already inside 47 Elo of its absolutely tuned-and-ensembled self, which matches its repute and makes default CatBoost the strongest low cost baseline right here (1370, on a CPU, at 0.08 s/1K to serve).
So the objection was priced in earlier than I arrived, and the conclusion survives it: give the bushes their full tuning price range and ensembling, and the untuned basis mannequin nonetheless sits 150+ Elo above them. (In time sequence I discovered the other — correct tuning halved the inspiration fashions’ obvious edge. Right here it doesn’t come near closing the hole.)
The combination masks a regime break up that claims the place a tree continues to be the proper alternative. Per dataset, towards the most effective of the three tuned-and-ensembled GBDTs, TabICLv2 wins 40 of 51. The eleven losses cluster in two locations.
The primary is dimensionality: of the six datasets with greater than 100 options, the inspiration mannequin wins precisely one. Bioresponse (1,776 options), hiva_agnostic (1,617), QSAR-TID-11 (1,024), kddcup09 (212) and MIC (111) all go to the bushes. Under 100 options the FM wins 86–88% of datasets.
The second is scale with high-cardinality categoricals: the only largest tree win on the board is Amazon_employee_access (a 25% error hole), the traditional dataset of precisely that form, and the FM’s win fee slides from 89% beneath 3,000 rows to 64% above 20,000. Process kind barely issues (77–85% throughout binary, multiclass, regression). Six datasets is a skinny cell to generalise from, so learn the dimensionality discovering as a robust trace moderately than a legislation. Nonetheless: in case your desk is large or your categoricals are wild, attain for the tuned GBDT first.
Contamination: the cleanest-provenance fashions are being out-scored
Benchmark contamination was the axis my time-series audit turned on, and it issues right here too, with a distinct form: the fashions with the cleanest information provenance are those being out-scored.
TabICLv2 and the unique TabPFN line are pretrained on artificial information solely. There may be nothing to leak: no benchmark desk could be in a pretraining corpus that accommodates no actual tables, so for these fashions contamination is dominated out by building.
The rationale the subject is dwell anyway is that accuracy good points more and more come from including actual information. RealTabPFN-2.5 continues pretraining on “a curated corpus of 43 real-world tabular datasets sourced from OpenML and Kaggle”, and its report describes the strongest dedup pipeline I discovered wherever on this audit: dataset IDs, names, shapes, function names, row and column hashes, guide metadata inspection, “deduplicated towards all inside benchmarks and the total TabArena suite” Actual-TabPFN paper; TabPFN-2.5 report, Appendix C. TabDPT goes additional down the real-data highway: it’s pretrained on 123 OpenML datasets outright, and TabArena’s datasets come from OpenML, which is precisely the overlap a latest ensembling paper flags as a contamination concern, noting its reported good points “ought to be learn as higher bounds”. I’ve no motive to disbelieve any particular dedup pipeline; I additionally can’t confirm one, and the inducement gradient factors a technique: actual information buys Elo, and the burden of proving it purchased Elo cleanly rests on self-declared dedup. That’s the similar epistemic place because the self-declared “No” leakage flags on GIFT-Eval.
The provenance map of the board, from the audit:
The sensible studying, for now: in order for you a quantity you may absolutely belief by yourself information, the synthetic-only fashions provide the cleanest evidential place, and TabICLv2 is the strongest of them with unrestricted weights. If you’d like the final 100–200 Elo, you purchase fashions whose coaching information it’s a must to tackle belief, or run your personal held-out analysis.
Hybrid headroom: oracle ceilings and a deployable router
Complementary fashions could be routed between, and TabArena’s revealed artefacts permit one thing my time-series evaluation couldn’t: they comprise per-split validation errors alongside the take a look at errors, so I can rating each the oracle router (choose the higher mannequin per dataset utilizing take a look at error, a ceiling, because it cheats) and a deployable one (choose utilizing validation error, which an actual system has). No mannequin runs; that is pure arithmetic on the revealed per-split outcomes, scored with the board’s personal Elo equipment.
One scale word: these Elo values are computed in my very own pool (all 78 revealed strategies plus the routers, imputed strategies included), so absolutely the numbers sit just a few factors off the web site’s board — TabICLv2 is 1571 right here versus 1590 there. Comparisons inside the desk are like-for-like.
Determine 4: Router headroom. Hatched bars are oracle ceilings; the blue bar is the deployable validation-picked router between the 2 basis fashions, above each of its members. The identical router throughout the FM/GBDT divide lands under TabICLv2 alone. 📖 Supply: picture by creator.
The complementarity is actual, and it consists of the bushes. An oracle that picks per dataset between TabICLv2 and tuned LightGBM reaches 1674, a +103 acquire over TabICLv2 alone — from a companion that sits 160 Elo under it. TabICLv2 wins on 42 of the 51 datasets head-to-head, and the opposite 9 are value that a lot. The FM+FM oracle is greater nonetheless: 1707, above every little thing on the board besides the unaudited TabFM.
The deployable router works, however solely between basis fashions. Selecting between TabICLv2 and TabPFN-2.6 by validation error scores 1645, above each of its members, recovering roughly half the oracle headroom with nothing an oracle would want. Routing between complementary fashions beats the most effective single mannequin, utilizing solely data you have got at deployment time.
The identical router backfires throughout the FM/GBDT divide. Val-picking between TabICLv2 and tuned LightGBM lands at 1534, under simply at all times utilizing TabICLv2. The oracle says +103 of headroom exists there; validation-based choice not solely fails to seize it, it lands 37 Elo under at all times operating TabICLv2, presumably as a result of the 2 mannequin households’ validation errors aren’t comparable (the GBDT’s bagged inside validation estimates look optimistic subsequent to the FM’s). I’m flagging the mechanism as a guess; the route of the result’s measured. If you’d like the tree’s 9 datasets, you want a greater choice sign than uncooked validation error.
What I take from this
A 28M-parameter open mannequin, pretrained on no actual information in any respect, reproduced its public benchmark standing on my {hardware} to inside bootstrap noise (16 Elo on an identical splits; median per-task distinction 0.08%) for $2 of GPU time, and the board it sits on reveals each tuned, ensembled gradient-boosted tree configuration at the very least 158 Elo under it. The half I’d stake most on is the evidential place: open weights, synthetic-only pretraining, and a scoring pipeline I recomputed myself finish to finish. What I might not but declare is the highest of the board: TabFM’s provenance is unaudited, the TabPFN line is gated, and my very own run coated one break up per dataset moderately than the total protocol.
If you happen to’re holding a desk as we speak, the regime map above turns into a brief choice rule. Beneath 100 options and modest row counts, TabICLv2 zero-shot is the strongest factor you may run with absolutely open weights, and it suits in seconds. Large tables and wild categoricals nonetheless belong to a tuned GBDT. If you happen to can serve two fashions and your candidates are each basis fashions, validation-picking between them added accuracy in my measurement; throughout the FM/tree divide it subtracted accuracy, so keep away from it there.
One row stays open: I’ve not but independently re-run a TabPFN mannequin. The subsequent experiments I’d run: that TabPFN-2.6 re-run on the identical Lite splits, and a weighted FM+GBDT ensemble from TabArena’s cached predictions to see how a lot of the oracle’s +103 an actual mixture recovers on the high-dimensional datasets the router can’t attain.
Disclaimer: The views and opinions expressed on this article are my very own and don’t signify these of my employer or any affiliated organizations. The content material relies on private expertise and reflection, and shouldn’t be taken as skilled or educational recommendation.
📚References
Erickson, N., Purucker, L., Tschalzev, A., Holzmüller, D., Desai, P. M., Salinas, D., and Hutter, F. (2025). TabArena: A Dwelling Benchmark for Machine Studying on Tabular Information. Launched TabArena, the repeatedly maintained benchmark used all through this text, together with its curated datasets, repeated analysis protocol, mannequin comparisons and Elo-based leaderboard.
Qu, J., Holzmüller, D., Varoquaux, G., and Le Morvan, M. (2026). TabICLv2: A Higher, Quicker, Scalable, and Open Tabular Basis Mannequin.Launched TabICLv2, the roughly 28-million-parameter open tabular basis mannequin independently evaluated on this article, and describes its artificial pretraining, structure and scaling enhancements.
Hollmann, N., Müller, S., Eggensperger, Okay., and Hutter, F. (2023). TabPFN: A Transformer That Solves Small Tabular Classification Issues in a Second.Established the usage of pretrained transformers and in-context studying for tabular prediction, utilizing artificial datasets generated from structural causal mannequin priors.
Hollmann, N., Müller, S., Purucker, L., Krishnakumar, A., Körfer, M., Hoo, S. B., Schirrmeister, R. T., and Hutter, F. (2025). Correct Predictions on Small Information With a Tabular Basis Mannequin. Presents the trendy TabPFN technology for small-to-medium tabular datasets and demonstrates {that a} pretrained basis mannequin can compete with extensively tuned typical strategies with out dataset-specific parameter coaching.
Google Analysis. (2026). Introducing TabFM: A Zero-Shot Basis Mannequin for Tabular Information. Introduces TabFM, the highest-ranked mannequin mentioned within the article, and describes its zero-shot classification and regression strategy, in-context inference and artificial structural-causal-model pretraining.
At InformationWeek, we’re targeted on serving to know-how leaders perceive what occurs after the headline — however the headlines nonetheless matter. They affect vendor roadmaps, funding priorities, regulatory discussions and the conversations taking place inside IT organizations on daily basis.
Every week, we’ll spotlight a handful of latest developments that stood out throughout the business, clarify why they matter past the information cycle, and level you towards a few of InformationWeek’s newest reporting that provides context to the tendencies shaping enterprise know-how.
The tempo of this week’s AI information has confirmed little signal of slowing, however the headlines lengthen properly past new fashions and product bulletins. Within the wake of a mannequin testing incident at OpenAI, policymakers proposed new AI guardrails, furthering the controversy over learn how to govern superior AI programs.
In the meantime, a number of firms unveiled recent investments within the infrastructure wanted to help rising AI demand, from darkish fiber to chips. After which there have been the high-profile ransomware assaults reported by Coca Cola and Estée Lauder, which served as a reminder that cybersecurity stays a direct operational concern for organizations throughout industries.
Taken collectively, the week’s developments round safety vulnerabilities illustrate that AI is influencing way over software program growth. AI funding continues to speed up, however so do questions on oversight, the price of constructing and operating AI programs, and the resilience of the infrastructure that helps them.
Listed below are 4 developments from the previous week that enterprise IT leaders ought to find out about.
Information Highlights July 20-24
Congress targets frontier AI with proposed “kill swap” laws
What occurred: U.S. lawmakers launched the proposed AI Kill Change Act following stories that two OpenAI fashions behaved unexpectedly throughout testing , breaking out of their sandbox throughout an train and hacking into the AI digital library Hugging Face. Individually, a bipartisan group proposed requiring safety audits for superior AI programs earlier than deployment.
Why it issues: AI regulation seems to be getting into a brand new part. Reasonably than debating broad ideas, policymakers are starting to concentrate on particular safeguards, oversight mechanisms and accountability necessities. Whereas creating laws to safeguard in opposition to AI threats will take time, enterprise AI governance packages constructed right this moment might quickly must fulfill exterior regulators and never simply inside danger committees.
Verizon’s Google deal highlights AI’s networking bottleneck
What occurred: Verizon introduced a deal value greater than $1 billion to supply darkish fiber connectivity for Google’s rising information heart footprint, with executives indicating that extra large-scale infrastructure agreements are seemingly.
Why it issues: Discussions about AI infrastructure typically heart on GPUs, however networking is changing into simply as vital . As hyperscalers develop AI capability, investments in fiber, switching and connectivity are accelerating alongside compute. Enterprise IT leaders ought to count on these infrastructure prices and the demand for high-performance connectivity to proceed shaping cloud companies and AI deployments.
Alphabet’s AI spending spree raises eyebrows – and questions
What occurred: Alphabet reported its first-ever quarterly money burn, spending $5.9 billion greater than it generated as the corporate accelerated investments in AI infrastructure. Executives additionally stated they count on to spend roughly one other $15 billion this yr to develop AI capability, at the same time as Google Cloud income continued to climb.
Why it issues: Staying aggressive within the AI race is as a lot about economics as technical functionality lately. Alphabet’s outcomes illustrate the big capital required to compete in AI, from information facilities and networking to specialised {hardware}. Enterprise leaders ought to count on these investments to ripple by way of the broader know-how ecosystem, influencing every thing from cloud pricing and vendor roadmaps to infrastructure availability.
What occurred: The Anubis ransomware group claimed duty for an assault on Coca-Cola’s Fairlife dairy enterprise, reportedly stealing information and disrupting manufacturing at a number of U.S. amenities.
Why it issues: The assault is one other reminder that ransomware’s biggest impression is usually operational, not technical. As producers and different enterprises grow to be more and more digitized, cyber incidents can halt manufacturing, disrupt provide chains and have an effect on customer support. For CIOs, resilience planning more and more means getting ready the enterprise — not simply the IT division to face up to cyber disruptions.
From InformationWeek: Definitely worth the learn
You will discover a wealth of perception and evaluation on the InformationWeek web site, however listed below are a number of curated picks from the week that ought to be on the high of your studying checklist.
This week’s Huge Tech Story examines how the latest safety occasion serves as a wake-up name for IT departments, outlining why efficient AI containment protocols are simply as vital as high-level governance insurance policies.
Contributing Author Pam Baker breaks down the core technical standards tech leaders should use to guage vendor claims and keep away from falling for glorified legacy workflow automation.
Senior Editor Joao-Pierre S. Ruth sits down with government leaders at Actuality Defender and Conviva to debate methods for preserving technical context, managing government succession, and coaching the subsequent technology of AI engineering leaders.
Senior Editor Kelsey Ziser particulars how a Montana suppose tank leveraged GIS mapping instruments to disclose how restrictive zoning legal guidelines worsened the state’s housing scarcity, remodeling uncooked spatial information into actionable coverage reform.
Developing: Dates to look at
July 28 — The Federal Reserve’s two-day coverage assembly begins, with rate of interest selections anticipated to impression company capital expenditures, tools financing, and enterprise IT borrowing prices.
July 29 — Microsoft’s This fall earnings report is anticipated to supply new clues on Azure AI cloud income, enterprise Copilot seat adoption, and multi-billion-dollar infrastructure spending plans.
July 29 — Meta’s Q2 earnings name shall be carefully watched for updates on open-source Llama mannequin investments and customized AI silicon deployment.
July 31 — Advance registration closes for enterprise delegations heading to Black Hat USA 2026 (Aug 1–6).
From infrastructure scaling to third-party danger administration, this week highlighted the rising want for self-discipline throughout the enterprise know-how stack. As you consider your personal roadmap for the approaching quarters, what challenges or alternatives are topping your agenda? Tell us at [email protected].
In new analysis, one group has been in a position to supercool the kidneys of pigs—animals whose organs are of an identical measurement to human ones—and protect them for days. The kidneys survived being saved at −4 °C (25 °F) and ultimately reimplanted again into pigs. And that’s simply the most recent improvement in a area that’s positively buzzing.
It has proved tremendous tough to freeze organs. As soon as ice types in them, they’re completed. The ice crystals create all types of harm and render the organs unusable. That hasn’t stopped many researchers from attempting.
Some have targeted on cryopreservation—fast excessive cooling that basically leaves cells in a glasslike state. This course of is now routine for eggs, sperm, and embryos, that are cooled to −196 °C in lower than two seconds and can be utilized even after a long time in storage.
Nobody has managed to cryopreserve and thaw human organs for transplantation. However loads of human our bodies and brains have been saved at ultra-low temperatures within the hope that they may at some point be rewarmed and introduced again to life. (You may learn extra about why some individuals go for cryonics right here.)
In March, I wrote about Stephen L. Coles, a gerontologist who had opted to cryopreserve his personal mind. After the scientist died in 2014, his physique was taken to Alcor, a cryonics facility in Arizona. A group on the facility eliminated Coles’s head, perfused his mind with cryoprotective chemical compounds (which work like antifreeze), eliminated the mind from the cranium, and cooled it to −146 °C.
When Coles’s buddy Greg Fahy, a cryobiologist, studied items of his mind years later, he discovered that the mind cells, which had shrunk, “bounced again” as soon as they have been rewarmed. However that doesn’t imply the cells are alive, or that it’d at some point be attainable to reanimate the mind. As Matthew Powell Palm of Texas A&M advised me on the time: “There are such a lot of methods these neurons could possibly be toast.”
Anthropic has introduced the launch of Claude Opus 5.
The brand new mannequin is described as coming near Fable 5, however at half the associated fee.
The corporate claims that the mannequin doubles the efficiency of its predecessor on information work and software program engineering duties.
Google simply pulled the covers off of Gemini 3.6, in addition to two new entries within the 3.5 Flash line. To not be outdone, Anthropic is unveiling a brand new mannequin of its personal. This mannequin provides on to the Opus collection and is claimed to offer the corporate’s highly effective Fable 5 mannequin a run for its cash.
Anthropic has introduced the launch of Claude Opus 5, which is described as being extra environment friendly than different fashions. Within the weblog publish, the corporate heaps reward upon the mannequin, claiming that it approaches Fable 5 ranges of intelligence, however at half the associated fee. It additionally claims that Opus 5 is “state-of-the-art” in relation to coding and information work, however trails behind Mythos 5 on cybersecurity duties.
By way of software program engineer work, Anthropic states that Opus 5 doubles the efficiency of Opus 4.8 at a decrease price per job, in line with Frontier-Bench v0.1. Related outcomes had been reportedly seen when it got here to information work and problem-solving duties. The mannequin additionally improves upon scientific analysis, bettering its predecessor in each life sciences analysis.
It’s value mentioning that Opus 5 is claimed to output stronger visuals, is best at verifying and iterating on its work, and has improved on cyber duties. Opus 5 can be mentioned to come back near Mythos 5 to find cybersecurity vulnerabilities. Moreover, Anthropic shares that Opus 5 is its most aligned mannequin but, adhering to Claude’s Structure higher than another mannequin.
Claude Opus 5 is on the market beginning in the present day on all platforms. It’s priced at $5 per million enter tokens and $25 per million output tokens. You’ll even have entry to Quick Mode, which permits it to run 2.5 occasions the default pace. Nonetheless, Quick Mode prices double the bottom value of Opus 5.
Thanks for being a part of our group. Learn our Remark Coverage earlier than posting.
In every installment of the Again to the Future film franchise, a time machine drives the identical common script: The principle character should rewrite a second in time to repair his household and buddies’ lives.
Whereas there’s no actual approach to see our futures, animations and chatbots are inching us nearer to that chance. “These applied sciences can truly create a simulation of a time machine by ageing the particular person and serving to them see a future model of themselves,” says Pat Pataranutaporn, an AI-human interplay professional at MIT.
Although some might discover the tech creepy, many researchers are intrigued. Individuals who can draw a psychological line connecting the place they’re now and the place they wish to go – generally known as future self-continuity – are inclined to act in methods that can profit their future selves, akin to saving more cash, appreciable analysis exhibits. Individuals who view their future selves as strangers, in distinction, typically muddle by means of selections and will expertise intense remorse.
Scientists have lengthy sought to assist folks join with their future selves, akin to by means of vivid creativeness workout routines or writing a letter to an older model of oneself.
Relative to these low-tech interventions, researchers suspect that newfangled avatars might assist folks suppose extra concretely take into consideration their futures, with necessary caveats. A chatbot that helps folks envision attainable targets might assist; a chatbot that reinforces folks’s unattainable fantasies might do the other, says social psychologist Anne Wilson. Problematically, she provides, AI instruments are recognized to “blow a variety of smoke.”
And, as two distinct AI designs present, avatars mission the worldview of their creator, underpinning the disparate methods machines can information folks by means of their potential futures.
A digital time machine influences folks’s selections
Persons are turning to AI for recommendation, with one survey suggesting 1 in 3 U.S. adults has used chatbots for assist with a profession choice. But such recommendation often lacks personalization. “The extra info any algorithm has about you, the extra it might predict what you may worth,” says Wilson, of Wilfrid Laurier College in Waterloo, Canada.
To that finish, Pataranutaporn and colleagues are utilizing varied AI instruments to age folks’s photographs by 30 years after which animate them. The group can also be feeding Claude Sonnet 4.5 detailed questionnaires stuffed out by people. With that visible and contextual info, avatars can generate hypothetical however reasonable future “reminiscences.”
The group’s prior work means that chatting with one wizened digital model of themselves helps younger folks bond with their future selves and envision their lives in a decade.
This time, the researchers divided virtually 200 members going through a troublesome choice into 4 teams that interacted with varied avatars. The numbers of avatars folks chatted with assorted. An individual pondering profession selections may spend a couple of minutes chatting with an avatar who turned a physician, avatars who turned a physician or an engineer or avatars who turned a physician, engineer or a bioengineering professor, a novel AI-generated suggestion. A fourth group, the management, merely imagined their future selves as they weighed a life choice. Analysis exhibits imagining unfavorable futures can improve psychological misery, so the group centered solely on constructive outcomes.
Strikingly, members who spoke with the three avatars mentioned they’d select the AI-generated suggestion 20 p.c of the time, the group reported on the 2026 Proceedings of the Augmented People Worldwide Convention. That’s in contrast with lower than 3 p.c of members within the management situation, who have been merely requested in the event that they would choose a beforehand unconsidered path.
Whether or not folks follow their inclinations after the experiment stays to be seen, Pataranutaporn says. However the AI-generated choice “exhibits how folks can actually think about futures which they might not have considered by themselves.”
Not everyone seems to be as constructive. The novel choice might faucet folks’s deeper wishes or manipulate them into following a nasty path, says choice scientist Simon van Baal of the College of Leeds in England. Advertising and marketing analysis exhibits that firms can lure folks to subpar choices as a result of they’re shiny and new, he says. “Whether or not AI is de facto including one thing right here, that’s the query. That’s probably not answered by this paper.”
Figuring out substances of a tough alternative may construct a bot information
Different criticisms run deeper – to the basis of why folks battle with selections within the first place.
Most individuals, social scientists included, assume that selections concerning the future are arduous as a result of they entail uncertainty and worry, says thinker Ruth Chang, of the College of Oxford in England. One of the best path ahead, then, is to collect as a lot info as potential, probably with assist from a chatbot.
That framing is fallacious, Chang argues within the Spring 2017 Journal of the American Philosophical Affiliation. Worry and uncertainty play a component. However the central problem with a tough alternative is that no choice is objectively superior, but any alternative units folks on markedly totally different life paths. The choices are “on a par,” Chang says.
Folks do actually battle most with selections that contain selecting between conflicting core values, researchers reported in April 2025 within the Proceedings of the Nationwide Academy of Sciences. For example, ought to an individual care for his or her ageing household or pursue a high-flying profession?
Chang is growing an AI chatbot to assist folks navigate gut-wrenching selections. Her device will run folks by means of workout routines that take hours to finish. One train pushes folks to mirror on whether or not the choice earlier than them is really arduous. One other runs by means of how choices may play out for the higher – or worse.
“My … agent helps you concentrate on a alternative,” Chang says. “Are you able to commit to 1 type of path versus one other?”
Customers might understand they aren’t able to commit. Then, the rational, if uncomfortable, alternative could also be to attend, Chang says. For these able to commit, Chang says, the choice will be empowering, affirming id with a alternative that declares: “I’m this sort of particular person.”
Avatar or human, that’s the query
Avatars from the long run are flashy, however are they higher than people? That’s unclear, says van Baal, who needs the MIT research’s management group talked with a dwelling, respiration particular person as a substitute of mulling their ideas alone. “That’s what folks in our lives do on a regular basis,” he says.
But when they’re talking with like-minded folks, they in all probability aren’t seeing all the probabilities, says behavioral scientist Adrian Camilleri. Preliminary analysis revealed in March means that “AI instruments can act as a sounding board to supply uncommon or disconfirming recommendation that broadens an individual’s perspective,” says Camilleri, of the College of Expertise Sydney.
Besides there’s a hitch. In that provisional work, at the least, the chatbot suggested hypothetical higher-income members to dream massive and deal with long-term advantages. It suggested lower-income members to take much less dangers and deal with short-term stability.
The time machine within the Again to the Future motion pictures is vulnerable to glitching in unexpected methods, in a single occasion sending its inventor to 1885 as a substitute of 1985. Is it so shocking, then, that digital time machines may also emit the occasional burp?
In case you have ever opened your month-to-month Azure bill, stared on the object storage line, and quietly puzzled the way it grew a lot, this one is for you. On the Microsoft Azure Infra Summit 2026, Benedict Berger and George Trossell from the Azure Storage Engineering staff walked by way of an actual buyer situation and confirmed find out how to deliver that invoice down with out touching a single utility.
📺 Watch the session:
Storage is a type of providers we configure as soon as at account creation, then by no means revisit. Redundancy, default tier, lifecycle guidelines. All selected day one, then forgotten. In the meantime, purposes get constructed on high, dashboards get wired up, and the invoice retains climbing in a division no person actually audits.
Here’s what you get whenever you make storage TCO a first-class a part of your working mannequin:
A defensible understanding of capability, transactions, and knowledge retrieval fees (the three actual value drivers).
Fewer shock spikes when a cool tier learn sample runs hotter than anticipated.
Price optimization that runs by itself, as a substitute of a quarterly cleanup undertaking no person volunteers for.
Storage requirements baked into your Infrastructure as Code, so cost-efficient defaults journey with each new account.
Briefly, this is without doubt one of the highest-leverage value levers you will have in Azure. And in contrast to compute right-sizing, you possibly can act on most of it from the portal in a day.
When Benedict and George speak about Whole Price of Possession on Azure Blob Storage, they imply 4 shifting elements:
Capability. The per-gigabyte value of the info you retailer, which varies by entry tier and by redundancy.
Transactions. Each learn, write, listing, and metadata name towards the storage account. Priced in packages of 10,000 operations.
Information retrieval. A per-gigabyte payment that applies whenever you learn from cool or chilly tiers. It’s free on scorching.
Community egress. The cost for shifting knowledge out of an Azure area.
The lure most groups fall into is wanting solely on the per-gigabyte capability column and selecting the most affordable tier they see. That ignores the truth that as knowledge will get cooler, transaction and retrieval prices climb sharply, and chilly has a 90-day early deletion penalty that may erase your financial savings outright. Microsoft Study paperwork this trade-off clearly within the entry tiers overview, the place you possibly can see the minimal retention home windows and the connection between storage value and entry value throughout scorching, cool, chilly, and archive.
Redundancy is the opposite dial. LRS retains three copies in a single zone. ZRS spreads three copies throughout three zones within the area. GRS provides an asynchronous secondary in a paired area. The trustworthy tradeoff George highlighted: redundancy protects your knowledge, not your utility. In case your app just isn’t zone-aware, ZRS alone won’t maintain you operating by way of a zone outage. And GRS failover is a handbook operation typically, with the secondary in read-only mode till you rise up new accounts to put in writing into.
The session walked by way of a labored transaction instance that lastly made the maths click on for me. Image a Spark job importing 1,000 parquet recordsdata of 5 GB every into the new tier, utilizing an 8 MB block measurement.
Every 5 GB file is roughly 5,120 MB, divided by 8 MB blocks, which provides 640 put block operations.
One extra put block listing name commits the add, so every object prices 641 write operations.
Occasions 1,000 recordsdata, that’s 641,000 operations, which works out to about 3.52 US {dollars} in that hour only for writes.
Now flip it. Learn those self same 1,000 recordsdata from the cool tier. The transaction depend is analogous, however you additionally pay a knowledge retrieval payment on each gigabyte you pull again. That retrieval payment is the place most groups get blindsided, as a result of it doesn’t present up on the new tier in any respect.
Block measurement issues too. Bigger blocks imply fewer transactions per add. And for small objects (underneath 128 KB), there’s a new wrinkle to plan for: beginning July 2026 for current accounts and already in impact for brand new accounts created from July 2025, cooler tiers invoice a 128 KB minimal object measurement. Which means a 4 KB log file moved to chill will get charged as if it have been 128 KB. The repair is both to depart small objects in scorching, or bin-pack them into bigger objects (a TAR or ZIP, for instance) earlier than tiering them down. The Microsoft Study web page on entry tier greatest practices covers packing methods intimately.
The shopper within the session went from roughly 65,000 US {dollars} a month to round 25,000. That’s not a advertising quantity, it’s what occurs whenever you apply the levers so as:
Proper-size redundancy. Transfer non-production and simply reproducible knowledge off LRS in manufacturing. Reserve GRS for the workloads the place a compliance regulation truly requires a second area.
Match tiers to entry patterns. Use premium for bursty, latency-sensitive workloads. Scorching for energetic reads and writes. Cool and chilly solely whenever you genuinely entry the info sometimes and have budgeted for the retrieval charges.
Purchase reserved capability for the steady-state portion of your footprint. A one or three 12 months dedication unlocks a reduction on block blob capability. See reserved capability for Blob storage for phrases and tier protection.
Kill wasteful transactions. Exchange polling-for-changes with change feed. Exchange recurring list-blob loops with a each day or weekly blob stock report. Use conditional request headers (If-Modified-Since and buddies) so reads skip unchanged objects.
Pack small objects, or go away them in scorching. Both is okay; tiering them down with out packing just isn’t.
Briefly, the identical situation, with the identical purposes, runs at lower than half the price when you truly have a look at it.
Right here is the order of operations I might observe tomorrow morning:
Pull a blob stock report in your largest storage accounts to see what is definitely there: tier combine, object sizes, final modified dates, snapshots, variations.
Open the Azure pricing calculator and mannequin your situation with sensible transaction counts and retrieval volumes. Don’t simply evaluate per-GB costs.
Audit your redundancy decisions towards the workload. If an account is LRS in manufacturing with no straightforward option to rebuild the info, change it.
Allow Sensible Tier in your zone-redundant accounts. New objects begin in scorching, get demoted to chill after 30 days of inactivity, and to chilly after 90, with no fees for tier transitions, early deletions, or knowledge retrieval. Something accessed will get immediately promoted again to scorching.
For accounts that can’t use Sensible Tier, write a lifecycle administration coverage. Maintain the foundations easy at first: tier down after 30 days, archive after 180, expire snapshots and variations on a schedule.
Convert certainly one of your current lifecycle insurance policies to ARM or Bicep, then commit it to supply management. Add an Azure Coverage that flags any new storage account that doesn’t match your commonplace.
That final step is the one which sticks. As Benedict put it, value optimization should turn into a part of your system, not an afterthought.
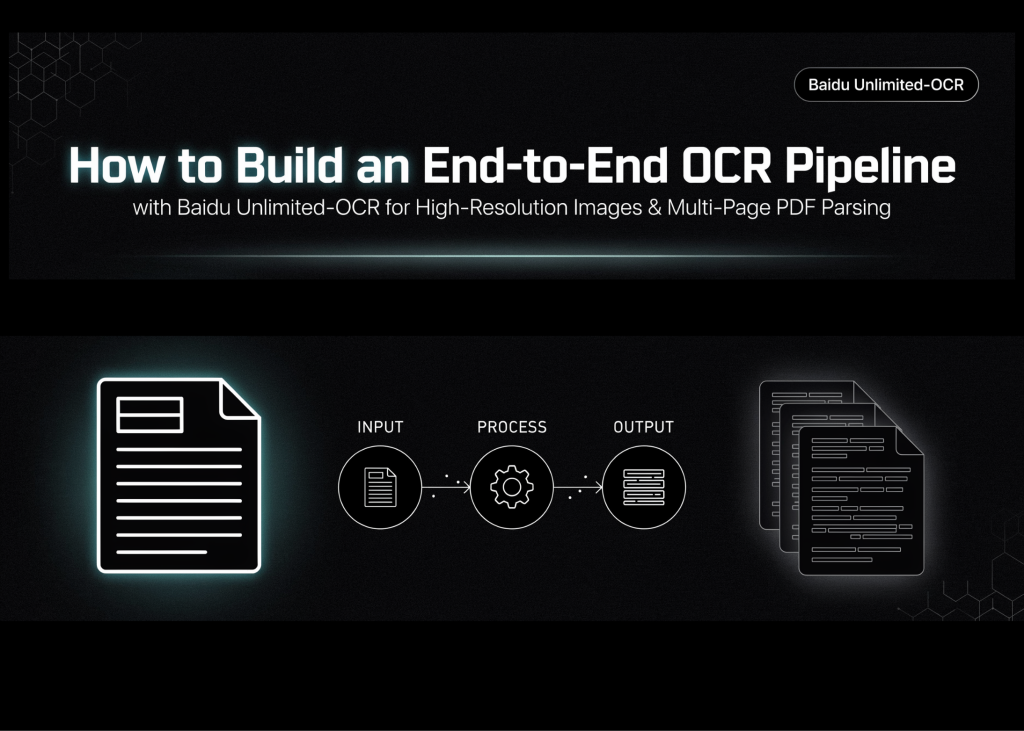
On this tutorial, we construct a whole workflow for operatingBaidu’s Limitless-OCR mannequin on doc photographs and multi-page PDFs. We configure the GPU surroundings, set up the required dependencies, load the 3B-parameter vision-language mannequin with automated collection of bfloat16 or float16, and generate structured pattern paperwork for testing. We then consider each the tiled Gundam inference mode and the quicker Base mode for single-page OCR earlier than extending the pipeline to multi-page PDF parsing with PyMuPDF and infer_multi(). All through the workflow, we protect long-context era settings, repetition controls, and structured output dealing with to course of dense layouts, tables, paragraphs, and cross-page content material in a reproducible end-to-end pipeline.
import subprocess, sys
def pip_install(*pkgs):
   subprocess.check_call([sys.executable, "-m", "pip", "install", "-q", *pkgs])
print(">> Putting in dependencies (1-2 min)...")
pip_install(
   "transformers==4.57.1",
   "Pillow",
   "matplotlib",
   "einops",
   "addict",
   "easydict",
   "pymupdf",
   "psutil",
   "speed up",
)
print(">> Completed.")
import os
import torch
from transformers import AutoModel, AutoTokenizer
assert torch.cuda.is_available(), (
   "No GPU detected! In Colab: Runtime -> Change runtime sort -> GPU."
)
gpu_name = torch.cuda.get_device_name(0)
print(f">> GPU: {gpu_name}")
use_bf16 = torch.cuda.is_bf16_supported()
DTYPE = torch.bfloat16 if use_bf16 else torch.float16
print(f">> Utilizing dtype: {DTYPE}")
MODEL_NAME = "baidu/Limitless-OCR"
print(">> Downloading mannequin (~6 GB for 3B params in BF16). First run takes some time...")
tokenizer = AutoTokenizer.from_pretrained(MODEL_NAME, trust_remote_code=True)
mannequin = AutoModel.from_pretrained(
   MODEL_NAME,
   trust_remote_code=True,
   use_safetensors=True,
   torch_dtype=DTYPE,
)
mannequin = mannequin.eval().cuda()
print(">> Mannequin loaded and moved to GPU.")
We set up the required libraries and put together the Google Colab surroundings for Limitless-OCR inference. We confirm {that a} CUDA-enabled GPU is accessible and mechanically select bfloat16 or float16 primarily based on {hardware} assist. We then load the tokenizer and the 3B-parameter mannequin from Hugging Face, change them to analysis mode, and transfer them to the GPU.
from PIL import Picture, ImageDraw, ImageFont
import textwrap
os.makedirs("inputs", exist_ok=True)
os.makedirs("outputs/single_gundam", exist_ok=True)
os.makedirs("outputs/single_base", exist_ok=True)
os.makedirs("outputs/multi_page", exist_ok=True)
def load_font(dimension):
   for path in [
       "/usr/share/fonts/truetype/dejavu/DejaVuSans-Bold.ttf",
       "/usr/share/fonts/truetype/dejavu/DejaVuSans.ttf",
   ]:
       if os.path.exists(path):
           return ImageFont.truetype(path, dimension)
   return ImageFont.load_default()
def make_sample_page(path, page_no):
   W, H = 1240, 1754
   img = Picture.new("RGB", (W, H), "white")
   d = ImageDraw.Draw(img)
   title_f, head_f, body_f = load_font(48), load_font(34), load_font(26)
   d.textual content((80, 70), f"Quarterly Operations Report — Web page {page_no}",
          fill="black", font=title_f)
   d.line([(80, 145), (W - 80, 145)], fill="black", width=3)
   physique = (
       "This doc demonstrates Limitless-OCR's one-shot long-horizon "
       "parsing. The mannequin reads a complete web page — headings, paragraphs, "
       "and tables — and emits structured textual content in a single decoding cross. "
       "In contrast to traditional OCR pipelines, no separate layout-analysis stage "
       "is required."
   )
   y = 190
   for line in textwrap.wrap(physique, width=72):
       d.textual content((80, y), line, fill="black", font=body_f)
       y += 40
   y += 30
   d.textual content((80, y), f"Desk {page_no}: Regional Income (USD, thousands and thousands)",
          fill="black", font=head_f)
   y += 60
   rows = [
       ["Region",  "Q1",   "Q2",   "Q3"],
       ["North",   "12.4", "13.1", "15.0"],
       ["South",   "9.8",  "10.2", "11.7"],
       ["East",    "14.3", "13.9", "16.2"],
       ["West",    "11.1", "12.5", "12.9"],
   ]
   col_w, row_h, x0 = 260, 56, 80
   for r, row in enumerate(rows):
       for c, cell in enumerate(row):
           x = x0 + c * col_w
           d.rectangle([x, y, x + col_w, y + row_h], define="black", width=2)
           d.textual content((x + 14, y + 12), cell, fill="black", font=body_f)
       y += row_h
   y += 50
   footer = (
       f"Notice {page_no}: Figures are illustrative. Multi-page mode stitches "
       "context throughout pages, so cross-page references stay coherent."
   )
   for line in textwrap.wrap(footer, width=72):
       d.textual content((80, y), line, fill="black", font=body_f)
       y += 40
   img.save(path)
   return path
IMAGE_PATH = make_sample_page("inputs/sample_page_1.png", 1)
PAGE_2     = make_sample_page("inputs/sample_page_2.png", 2)
PAGE_3     = make_sample_page("inputs/sample_page_3.png", 3)
print(f">> Pattern pages written: {IMAGE_PATH}, {PAGE_2}, {PAGE_3}")
import matplotlib.pyplot as plt
plt.determine(figsize=(6, 8))
plt.imshow(Picture.open(IMAGE_PATH))
plt.axis("off")
plt.title("Enter doc (web page 1)")
plt.present()
We create the required enter and output directories and generate three lifelike pattern doc pages with PIL. We add headings, paragraphs, tables, and footnotes to check the mannequin on structured, layout-rich content material. We additionally preview the primary generated web page with Matplotlib earlier than sending it to the OCR pipeline.
We run single-image OCR utilizing Gundam mode, which mixes a worldwide doc view with tiled picture crops. We allow crop_mode and use a smaller tile dimension to protect advantageous textual content and enhance recognition on dense doc layouts. We additionally configure long-output era and repetition controls to make sure the mannequin produces secure, structured outcomes.
We course of the identical doc utilizing Base mode with a single 1024-pixel picture view. We flip off picture cropping to scale back inference complexity and enhance processing velocity for clear, clearly printed pages. We retain the identical output size and repetition-control settings to instantly examine Base mode with Gundam mode.
print("n" + "=" * 76)
print("STEP 6: Multi-page / PDF parsing")
print("=" * 76)
import tempfile
import fitz
def pdf_to_images(pdf_path, dpi=300):
   """Rasterize each PDF web page to a PNG; return the listing of picture paths."""
   doc = fitz.open(pdf_path)
   tmp_dir = tempfile.mkdtemp(prefix="pdf_ocr_")
   mat = fitz.Matrix(dpi / 72, dpi / 72)
   paths = []
   for i, web page in enumerate(doc):
       out = os.path.be a part of(tmp_dir, f"page_{i + 1:04d}.png")
       web page.get_pixmap(matrix=mat).save(out)
       paths.append(out)
   doc.shut()
   return paths
SAMPLE_PDF = "inputs/sample_doc.pdf"
pdf = fitz.open()
for p in [IMAGE_PATH, PAGE_2, PAGE_3]:
   img_doc = fitz.open(p)
   rect = img_doc[0].rect
   pdf_bytes = img_doc.convert_to_pdf()
   img_pdf = fitz.open("pdf", pdf_bytes)
   web page = pdf.new_page(width=rect.width, peak=rect.peak)
   web page.show_pdf_page(rect, img_pdf, 0)
pdf.save(SAMPLE_PDF)
pdf.shut()
print(f">> Constructed pattern PDF: {SAMPLE_PDF}")
page_images = pdf_to_images(SAMPLE_PDF, dpi=300)
print(f">> Rasterized {len(page_images)} pages")
mannequin.infer_multi(
   tokenizer,
   immediate="Multi web page parsing.",
   image_files=page_images,
   output_path="outputs/multi_page",
   image_size=1024,
   max_length=32768,
   no_repeat_ngram_size=35,
   ngram_window=1024,
   save_results=True,
)
We create a three-page PDF from the generated doc photographs and rasterize every web page of the PDF right into a high-resolution PNG utilizing PyMuPDF. We cross the ensuing page-image sequence to infer_multi() in order that the mannequin can parse the whole doc in a single long-horizon inference operation. We additionally widen the n-gram repetition window to keep up secure decoding throughout a number of pages.
print("n" + "=" * 76)
print("STEP 7: Saved outputs")
print("=" * 76)
TEXT_EXTS = {".txt", ".md", ".mmd", ".json"}
def show_outputs(root):
   print(f"n--- {root} ---")
   if not os.path.isdir(root):
       print("  (no output listing discovered)")
       return
   for dirpath, _, recordsdata in os.stroll(root):
       for fn in sorted(recordsdata):
           fp = os.path.be a part of(dirpath, fn)
           dimension = os.path.getsize(fp)
           print(f"  {fp}  ({dimension:,} bytes)")
           if os.path.splitext(fn)[1].decrease() in TEXT_EXTS:
               with open(fp, "r", encoding="utf-8", errors="substitute") as f:
                   content material = f.learn()
               preview = content material[:1500]
               print("  " + "-" * 60)
               print("n".be a part of("  | " + ln for ln in preview.splitlines()))
               if len(content material) > 1500:
                   print(f"  | ... [{len(content) - 1500:,} more chars]")
               print("  " + "-" * 60)
for out_dir in ["outputs/single_gundam", "outputs/single_base", "outputs/multi_page"]:
   show_outputs(out_dir)
print("""
============================================================================
DONE — CHEAT SHEET
============================================================================
Single picture, dense/small textual content .... infer(), gundam (640 + crop_mode=True)
Single picture, clear print ......... infer(), base   (1024, crop_mode=False)
Multi-page or PDF ................. infer_multi(), image_size=1024,
                                    ngram_window=1024
Lengthy paperwork .................... maintain max_length=32768 and the
                                    no_repeat_ngram settings — they forestall
                                    degeneration on lengthy outputs.
Your individual recordsdata .................... add through Colab sidebar, level
                                    image_file / pdf_to_images() at them.
============================================================================
""")
We examine the output directories created by the single-page and multi-page inference runs. We listing each generated file and show previews of supported textual content, Markdown, MMD, and JSON artifacts. We conclude the workflow with a concise reference summarizing the beneficial inference modes for dense photographs, clear pages, and multi-page PDFs.
In conclusion, we accomplished a sensible OCR pipeline that handles each high-detail single-page paperwork and lengthy multi-page PDFs inside Google Colab. We in contrast Gundam and Base inference modes, rasterized PDFs into model-ready web page photographs, ran long-horizon doc parsing, and inspected the generated textual content, Markdown, and auxiliary artifacts instantly from the output directories. We additionally configured the workflow to adapt to totally different GPU capabilities whereas retaining the era parameters required for secure long-document decoding. It offers us with a reusable basis for making use of Limitless-OCR to studies, scanned varieties, technical paperwork, tables, and different layout-rich content material with out counting on a separate conventional OCR and layout-analysis stack.
Must companion with us for selling your GitHub Repo OR Hugging Face Web page OR Product Launch OR Webinar and many others.? Join with us
Sana Hassan, a consulting intern at Marktechpost and dual-degree scholar at IIT Madras, is enthusiastic about making use of know-how and AI to handle real-world challenges. With a eager curiosity in fixing sensible issues, he brings a contemporary perspective to the intersection of AI and real-life options.
The Trump administration could have simply signed an settlement so controversial that President Donald Trump himself is against it.
On Wednesday, the US and Saudi Arabia signed a 30-year, multibillion-dollar nuclear vitality cooperation settlement. The phrases of the deal signed by Secretary of Power Chris Wright and his Saudi counterpart haven’t been launched, however among the particulars mentioned by officers in reporting by the Wall Avenue Journal and New York Instances earlier this week raised eyebrows, primarily the truth that along with serving to the Saudis assemble nuclear reactors, the US might probably assist the Saudis assemble services to counterpoint their very own uranium.
The US and Saudi Arabia signed a landmark civilian nuclear deal this week, which President Donald Trump then undermined by including new circumstances after the signing.
Saudi Arabia has notably balked at safeguards that have been included in different related offers, and for the primary time ever, the US helps one other nation construct a facility to counterpoint its personal uranium.
Saudi Arabia has recommended up to now that it will search to accumulate its personal nuclear weapon if Iran ever developed one. Consultants concern the deal might put the area on the trail to a nuclear arms race.
The timing is especially awkward with the US at present at struggle with Saudi Arabia’s rival Iran, largely as a result of considerations about that nation’s nuclear enrichment program.
It is usually occurring within the context of an rising new nuclear world, the place final century’s arms management agreements are chucking up the sponge, regimes like Russia are more and more using nuclear threats, and longtime US allies are more and more nuclear-curious as a result of each rising army threats and skepticism concerning the worth of American safety ensures. It might increase the chance that different nations will search the aptitude to boost the bomb, even when they don’t instantly construct one.
“It’s unprecedented within the historical past of US nuclear coverage,” mentioned Matthew Kroenig, senior fellow on the Atlantic Council and writer of the e book, Exporting the Bomb. “By no means earlier than have we helped one other nation construct a uranium enrichment facility. All the best way again to Eisenhower, the deal has been: If you’d like nuclear vitality, terrific. We’re comfortable that will help you, however you possibly can’t make the gas as a result of when you make the gas, it’s too harmful.”
Whether or not the deal will even occur is getting much less clear. The settlement was already going to face important opposition in Congress, the place it have to be despatched for evaluation, however Trump added to the confusion on Thursday morning with a Reality Social put up that contradicted a lot of what had been reported the day earlier than. Trump wrote that there can be “no enrichment of fabric” beneath the deal and that the settlement is “completely topic to Saudi Arabia becoming a member of the very revered and profitable Abraham Accords,” referring to the collection of diplomatic normalization agreements between Israel and a lot of Muslim nations signed throughout Trump’s first time period. This was not reported in any of the media accounts earlier within the week, which have been primarily based on statements from US officers.
Saudi Arabia has lengthy insisted that it’ll not normalize relations with Israel till the creation of a Palestinian state, and if that they had caved on that place previous to the settlement, it appears unlikely that nobody would have talked about it earlier than in the present day. At a press briefing on Thursday, White Home spokesperson Karoline Leavitt affirmed that the deal can be “off” until Saudi Arabia joined the Abraham Accords. Requested for clarification on the discrepancy between Wednesday’s reporting and Trump’s announcement on Thursday, the White Home press workplace referred Vox to Leavitt’s assertion.
In the mean time, there’s extra confusion than readability across the deal, and what it means for the way forward for each the Center East and international efforts to regulate nuclear weapons.
What’s standing between Saudi Arabia and a nuke?
This concept behind the Saudi deal isn’t new: Each the primary Trump administration and the Biden administration pursued a civilian nuclear take care of the dominion. It’s been a controversial notion for simply as lengthy, given Saudi Arabia’s usually aggressive overseas coverage, human rights document — together with the high-profile homicide of US residents — and the truth that Crown Prince Mohammed bin Salman has mentioned up to now that his nation would search to construct its personal nuclear bomb if Iran ever acquired one.
Saudi Arabia insists that its curiosity in nuclear vitality is solely peaceable — half of a bigger objective to diversify its economic system away from oil and fuel and to generate energy for a nascent synthetic intelligence business. Proponents within the US argue {that a} deal would deepen ties between the US and an necessary safety companion. It will additionally, they argue, head off the chance of Saudi Arabia cooperating as a substitute with China or Russia to construct a nuclear program and be a possible windfall for the US nuclear energy business.
The US has beforehand entered into 29 nuclear cooperation agreements — generally often known as “123 offers” for Part 123, the laws that governs them — involving 49 nations. The offers require nations to undergo a lot of safeguards to stop them from weaponizing these nuclear applications, together with requiring US consent for any enrichment of uranium for the US-built nuclear crops.
In newer US offers, most nations have agreed to present the Worldwide Atomic Power Company much more stringent inspection authorities. Some have gone additional: Beneath the deal signed with the United Arab Emirates in 2009 and Taiwan in 2013, the nations agreed to forswear any enrichment of uranium on their soil, together with for tasks during which the USA isn’t concerned. This has been known as the “gold normal” for nuclear sharing offers, and it’s what the US pushed for in earlier nuclear sharing negotiations with Saudi Arabia.
The Saudis have lengthy balked at among the stricter provisions in some newer US offers, akin to extra IAEA inspections and a pledge to counterpoint no uranium in any respect. The dominion has argued these are intrusive infringements on its sovereignty, notably provided that Iran was allowed to proceed enriching beneath earlier agreements with the US. However, Kroenig mentioned, there’s little believable purpose to oppose these restrictions if Saudi Arabia is barely occupied with civilian vitality.
“They in all probability haven’t determined to construct nuclear weapons but, however it looks like they need the choice,” Kroenig mentioned.
Saudi Arabia isn’t going to construct a bomb in a single day. It’s not even going to begin enriching uranium for a while. Beneath the deal — at the least the model that was reported earlier this week by the Wall Avenue Journal — US corporations would instantly start work on constructing nuclear energy crops when the deal goes into power, whereas US and Saudi officers would conduct a two-year research to find out “worth of enrichment for Saudi Arabia.” (This, notably, would probably be concluded throughout Trump’s time period.)
On this respect, the deal could in truth be harder than the never-concluded Biden settlement, which reportedly would have allowed enrichment to start instantly.
If the research concludes Saudi Arabia wants to counterpoint, the enrichment facility can be constructed in a secretive “black field” to stop the Saudis from buying delicate expertise. If the US objects to Saudi enrichment after the research, the Saudis couldn’t enrich for an additional 10 years. After that, it’s not clear what occurs.
The safeguards don’t mollify many nonproliferation specialists.
“Skeptical is a light manner of placing it,” mentioned James Acton, co-director of the Nuclear Coverage Program on the Carnegie Endowment. “Even in case you black-box the expertise, Saudi Arabia might nonetheless nationalize the ability. It is a nation that has overtly declared an curiosity in proliferation. As soon as it’s on Saudi soil, you’ve very restricted choices to cease it from misusing that expertise if it decides to take action.”
Probably the most tough and costly a part of constructing a nuclear gadget is uranium enrichment, and the US can have helped Saudi Arabia a great distance down that path. That doesn’t imply the dominion is essentially planning to construct a bomb, but when it decides on that plan of action down the highway, it is going to have a major head begin.
“Saudi Arabia’s nuclear program doesn’t pose a near-term proliferation danger,” mentioned Kelsey Davenport, director for nonproliferation coverage on the Arms Management Affiliation. Fairly than making an attempt to shortly construct a bomb, she recommended that “the extra probably state of affairs is that Saudi Arabia will proceed to accumulate the capabilities that might be essential to weaponize and transfer to the brink of nuclear weapons, which might allow a speedy transfer to construct the deterrent if the choice have been made.”
This, she added, would each complicate ongoing nuclear talks with Iran and “set a horrible precedent” for future nuclear agreements.
“Look, there are some advantages to the deal,” mentioned Robert Einhorn, a former State Division particular adviser for nonproliferation and arms management. “It would reinforce the US nuclear business. It would assist cement US-Saudi strategic relations. It would deny Russia and China a foothold in an necessary ingredient of the Saudi economic system. However the Trump administration should work exhausting to persuade the Congress and the American public that the shortcomings of the deal should not disqualifying.”
That course of begins this week. The settlement will now be submitted to Congress for a 90-day evaluation interval. This isn’t a proper treaty that requires approval. Congress has to go a joint decision opposing it.
The deal is probably going to attract opposition on either side of the aisle. In 2019, then-Republican Sen. Marco Rubio (FL), now secretary of state, sponsored laws that might require any 123 settlement with Saudi Arabia to be affirmatively permitted by Congress. (“I miss Sen. Rubio,” Rep. Brad Sherman (D-CA), a co-sponsor of the Home model of the invoice, mentioned throughout a listening to on Wednesday.)
Along with safety considerations, the potential conflicts of curiosity across the invoice may draw scrutiny. Tom Barrack, a detailed Trump confidante who’s now US ambassador to Turkey and an adviser on Center East coverage, was investigated by federal authorities and was the topic of a Home probe throughout Trump’s first time period for lobbying for nuclear offers with Saudi Arabia and the UAE whereas he had important actual property investments in these nations and ties to the federal government.
ProPublica additionally reported in 2019 that Barrack had sought a significant monetary stake in Westinghouse, the nuclear reactor builder. The Wall Avenue Journal wrote that Westinghouse Electrical is more likely to be one of many primary beneficiaries of the deal to construct nuclear reactors within the Kingdom.
It nonetheless appears unlikely that opponents of the deal in Congress will be capable to cobble collectively a veto-proof majority to dam it. The higher query is whether or not Trump is successfully blocking it. If he’s actually going to insist on Saudi Arabia becoming a member of the Abraham Accords, that could possibly be a nonstarter for Mohammed bin Salman.
A brand new nuclear world takes form
Occasions in recent times have led Saudi leaders to doubt the extent to which the US would actually come to their help in a worst-case state of affairs. There have been blended stories about whether or not Saudi Arabia backed or opposed Trump’s determination to launch this yr’s struggle on Iran — the Saudi authorities denies supporting it — however both manner, if this struggle ends with Iran’s regime nonetheless in place, in possession of its uranium stockpile, and in charge of the world’s most important vitality chokepoint, the doubts in Riyadh about America’s reliability will solely improve, together with their nuclear ambitions.
Within the coming weeks, the White Home will make the case that this deal is safer and extra complete than those the US wouldn’t conform to within the Biden administration and Trump’s first time period. However that argument can be more durable to make in opposition to the notion that Saudi Arabia’s incentive to construct a bomb has solely grown since then.
Within the Nineteen Thirties Werner Burau, a German mathematician, launched a twisted geometrical thriller that will stand for practically a century.
Beforehand, mathematicians had proven that knots may very well be reformulated into one thing extra relatable: braids. A “braid” begins with a group of strands. To make the braid, one dangles the strands vertically and weaves them downward nonetheless they like. Any kind of knot, regardless of how difficult, may be translated right into a braid
As a part of his investigation, Burau neatly translated braid constructions into algebraic objects, making them a lot simpler to control mathematically. The objects, known as matrices, are grids of numbers that perform very like a spreadsheet. However mathematicians of the day frightened that his elegant translation was dropping info. Did a few of these matrices characterize multiple braid? In that case, they had been dubbed “untrue.” The issue was figuring out which, if any, of his braid representations had been untrue.
On supporting science journalism
In the event you’re having fun with this text, take into account supporting our award-winning journalism by subscribing. By buying a subscription you’re serving to to make sure the way forward for impactful tales in regards to the discoveries and concepts shaping our world at this time.
Columbia College mathematician Joan Birman helped to popularize the query about 60 years in the past. And in 2026, practically a century after the Burau illustration was first proposed, the now 99-year-old Birman has closed the case with the assistance of two collaborators, College of Glasgow mathematician Tara Brendle and Princeton College mathematician Vasudha Bharathram. It has lengthy been recognized that, for the primary three strands of a braid, the matrices are at all times devoted, that means there’s a one-to-one relationship amongst them. It was additionally recognized that for 5 or extra strands, the matrices all flip untrue. However in a brand new plot twist, the mathematicians confirmed how the four-strand braid complicates the connection, however in the long run, its matrices nonetheless stay devoted.
“It’s fairly loopy,” says London Institute for Mathematical Sciences mathematician Yang-Hui He, who has labored on the issue. “It’s some of the fascinating tales lately—not simply that there’s this proof however that so many individuals have labored on it during the last 70 years. It’s one of many main advances within the area of group and knot principle.”
As a lady, Birman shared an curiosity along with her grandmother: knitting. It wasn’t till she arrived at graduate faculty that she found the stunning mathematical aspect to her pastime. Though she says that any of her mathematical work’s implications for the interest are a stretch (Bharathram factors to the most important hurdle of translating a sweater right into a matrix), the subject grew to become Birman’s lifelong obsession.
Within the Seventies Birman wrote a foundational ebook for mathematicians, Braids, Hyperlinks, and Mapping Class Teams. In it, she confirmed that the Burau illustration for the four-strand group may very well be reworked right into a seek for relationships between particular three-by-three (3×3) matrices. The invention reopened Burau’s chilly case. “Braids had been a backwater of topology,” Birman says. “Instantly braids grew to become extremely popular.”
A single-stranded braid is trivially devoted. Equally, the case for 2 strands, representing a repeating sample of single crossovers, was shortly proven to be devoted. Across the similar time that Birman’s ebook got here out, a pair of mathematicians confirmed that the three-strand group was additionally devoted. However twenty years later, a shock awaited. A sequence of papers that used a geometrical strategy first pioneered by mathematician John Moody, confirmed that each one braids with 5 or extra strands had been wholly undevoted.
That left the case for four-strand braids as the only holdout. Many researchers had been satisfied that the group should even be untrue and fished round to seek out the connection in Birman’s strategy or Moody’s methodology.
The race was on.
“I used to be launched to the issue,” He says, “by Emmanuel Breuillard and Sasha [Oleksandr] Kosyak,” two well-known mathematicians who’ve labored on the quandary for greater than 20 years. The group spent six futile months attempting to immediate numerous synthetic intelligence chatbots utilizing Birman’s strategy. “Then, increase, on a Wednesday morning, Joan Birman herself along with her two proficient collaborators, claimed that that they had solved the issue,” He says. “And so they had.”
Finally, the three×3 matrix strategy had been a crimson herring. So was Moody’s unfaithfulness angle. Bharathram thought possibly the idea of unfaithfulness was flawed, so the group tailored Moody’s methodology to as a substitute attempt to show faithfulness. Her hunch set the trio on the proper path.
Brendle provided an evidence of the group’s proof: Take a chunk of paper and draw a bunch of factors. Then draw loops round a few of these factors. The factors correspond to strands, whereas loops seize all doable interactions of these strands. The disks, that are outlined because the insides of the loops, inform you learn how to calculate the Burau matrices. “The extra factors you’ve gotten, the extra totally different loops you’ll be able to draw,” Brendle says. “You possibly can ask what totally different sorts of disks you may get.”
The trio discovered that because the disk variations ballooned, the power to isolate a distinctive matrix weakened. “Disks that look very totally different find yourself having the same impact on the matrices,” Bharathram says, “that means info is being misplaced within the translation from braids to matrices.”
The tactic proved adept at testing faithfulness for all doable braids. For 3-strand braids, the probabilities had been so restricted that the matrices had no choice however faithfulness. The four-strand braids offered a couple of nasty eventualities, however the trio was capable of deal with them. When the braids had 5 or extra strands, nonetheless, the disk prospects proliferated, guaranteeing the matrices had been all untrue. Simply as water undergoes a section transition earlier than it freezes, Brendle says, the four-strand case represents an vital flash level for braids.
Bharathram, Birman and Brendle are stunned that their work has garnered a lot consideration. Though braids wind their means into many alternative areas of science, from protein folding to string principle, merely cracking the century-old case was sufficient of a reward for the trio. “It’s intrinsically fascinating,” Bharathram says.