Get the Well-liked Science every day e-newsletter💡
Breakthroughs, discoveries, and DIY suggestions despatched six days per week.
By signing up, you verify you’re 16+, will obtain newsletters and promotional content material and comply with our Phrases of Use and acknowledge the information practices in our Privateness Coverage. You could unsubscribe at any time.
It’s not one thing anybody actually needs to consider, however what occurs to these 1000’s of digital images in your cellphone within the occasion of your passing? Few of us may even be bothered to again up our images, a lot much less safe their posthumous legacy. However the thought of “private results” has modified over time from bodily objects you put on or carry round to a complete digital previous and current sitting in your smartphone. The truth is, 75 % of Gen Zers are already desirous about it.
As a substitute of somebody claiming possession over grandma’s couch-cushion-sized picture album charting the household’s historical past all the best way again to the Nice Despair, we now have terabytes of group images, lunch portraits, and selfies that your loved ones might wish to preserve and treasure. And like something involving end-of-life preparation, it requires a plan.
Plenty of platforms and repair suppliers like Apple, Google, and Fb do assist you to add what’s generally known as a “Legacy Contact.” As soon as activated, these capabilities generate an entry key that may be shared together with your chosen contact or contacts. To request entry, they might want to present the entry key and add a replica of your demise certificates. Your legacy contact additionally doesn’t must have an Apple account or machine themselves. There could also be cut-off dates, nonetheless–for instance, within the case of Apple, legacy contacts have three years to realize approval to entry recordsdata, notes, messages, movies, images, and different knowledge. For Google–the place it’s generally known as “Inactive Account Supervisor,” it may be set for any interval between 3 and 18 months.
It’s additionally turning into increasingly frequent for individuals to call a Digital Executor to their final will and testomony. These will be arrange simply by means of providers corresponding to Everplans and are much like making a Legacy Contact, however this individual has a extra of an lively position in archiving and preserving your digital legacy.
A Digital Executor can archive your private recordsdata, images, movies, and different content material you’ve created, delete specified recordsdata out of your laptop or different units and even erase complete exhausting drives at your route, and may shut specified on-line accounts to cease funds. As well as, a Digital Executor will be requested to take care of accounts, switch income-generating platforms (like a private web site) to your heirs, and different providers.
On the finish of the day, it’s a superb behavior to regularly back-up treasured images and knowledge on a separate exhausting drive. It’s additionally a superb behavior to periodically create exhausting copies–both printing significant images or creating curated books primarily based on particular occasions like holidays, graduations, or only a notably nice summer season. At finest it’ll offer you peace of thoughts do you have to lose or harm your cellphone and, at worst, it prevents your digital legacy from being locked away out of your family members ceaselessly.
2026 Well-liked Science Dwelling of the Future Awards
39 merchandise that can enhance your on a regular basis life.
Knowledge science case examine interviews should not nearly writing code. They check the way you suppose by an issue, analyze knowledge, make choices, and clarify your method in a method that solves an actual enterprise problem.
On this information, you’ll study a easy framework known as SCOPE that you should utilize to method nearly any knowledge science case examine. We’ll additionally work by 5 full examples, together with two Generative AI case research to point out you apply the framework, write the code, consider the outcomes, and current your resolution with confidence.
What Interviewers Are Really Evaluating
Interviewers hardly ever care whether or not you decide the “greatest” algorithm. They watch the way you cause underneath ambiguity. A case examine is a stay audition for the way you’d behave as a colleague on a messy, actual venture.
Your objective is to point out structured pondering, sound judgment, and clear communication. The mannequin is only one small piece of a a lot bigger story.
The 4 Dimensions of a Case Examine Scorecard
Most firms grade candidates throughout 4 repeated dimensions. Understanding them helps you allocate your time and a focus in the course of the session.
Drawback structuring: Do you break an open drawback into clear, solvable components?
Technical depth: Are you able to defend your modeling and analysis selections?
Communication readability: Do you clarify concepts merely to combined audiences?
Enterprise judgment: Do your choices map to actual enterprise influence?
Why “Getting the Proper Mannequin” Is the Least Vital Half?
Interviewers assume many candidates can practice a classifier. What separates folks is framing, assumptions, and trade-off reasoning round that classifier. A logistic regression with clear justification typically scores larger than a tuned ensemble with no story. Reasoning wins over uncooked accuracy in nearly each loop.
The SCOPE Framework: A Repeatable System for Any Case Examine
SCOPE offers you a constant path by any case examine immediate. It stands for State of affairs, Make clear knowledge, Define method, Prototype, and Clarify. You apply the identical 5 steps whether or not the case is churn, forecasting, or a GenAI assistant.
The framework prevents panic. As an alternative of guessing, you progress by predictable phases that mirror actual venture work.
Why You Want a Framework within the First Place?
Sample matching breaks the second a case seems unfamiliar. A framework travels with you into any area or drawback kind. It additionally indicators maturity to interviewers. You seem like somebody who has shipped tasks, not somebody memorizing options.
S- State of affairs: Make clear the Enterprise Context
Begin by understanding the enterprise, not the info. Ask why this drawback issues and who feels the ache as we speak. This stage takes two or three minutes however shapes all the things that follows.
Inquiries to ask earlier than touching knowledge: What choice does this mannequin help?
Mapping enterprise KPIs to a knowledge drawback: Translate “cut back churn” right into a prediction goal.
Figuring out stakeholders and success standards: Study who makes use of the output and the way.
C- Make clear the Knowledge Panorama
Subsequent, perceive what knowledge exists and the way reliable it’s. Good candidates probe knowledge high quality earlier than assuming a clear desk seems. This step exposes leakage dangers and lacking indicators early.
Assessing knowledge availability and high quality: Examine quantity, freshness, and label reliability.
Asking “what knowledge don’t we have now?”: Lacking knowledge typically defines the actual limitation.
Dealing with constraints: Tackle privateness, latency, and quantity trade-offs immediately.
O- Define Your Strategy
Now design your resolution as a pipeline earlier than writing code. Clarify your reasoning out loud so interviewers observe your logic. State the best method first, then justify added complexity.
Selecting between classical ML, deep studying, and GenAI: Match the software to the duty.
Structuring the answer as a pipeline: Ingest, clear, function, mannequin, consider, deploy.
Stating assumptions and trade-offs upfront: Make your reasoning absolutely clear.
P- Prototype and Validate
Construct a baseline rapidly, then enhance intentionally. A baseline anchors each later comparability and prevents wasted effort. Select metrics that replicate actual enterprise value, not default accuracy.
Beginning with a baseline: A easy mannequin reveals whether or not the issue is learnable.
Selecting metrics that match enterprise value: Weigh false positives in opposition to false negatives.
Defining “adequate” earlier than you begin: Set a goal so you understand when to cease.
E – Clarify and Suggest
Lastly, translate outcomes right into a suggestion. Interviewers desire a choice, not a desk of numbers. Shut each case with subsequent steps and sincere caveats.
Framing outcomes as enterprise choices: Report {dollars} saved, not simply F1 scores.
Speaking trade-offs to non-technical stakeholders: Use plain language and analogies.
Proposing subsequent steps and iteration plans: Present how you’d enhance model two.
Now we have now understood what the “SCOPE” stands for now we’ll transfer to the Case research.
Churn prediction is the traditional knowledge science case examine. A subscription enterprise needs to know which prospects will cancel quickly. You could predict churn early sufficient for the retention crew to behave. This instance reveals the complete SCOPE stream with actual code and output.
Drawback Assertion and Enterprise Context
A streaming firm loses 5% of subscribers every month. Every saved buyer is price roughly 200 {dollars} in yearly income. The retention crew can name at most 500 prospects per week.
That final constraint issues most. It means precision on the high of your ranked record beats uncooked recall.
Making use of SCOPE to the Drawback
You first outline churn exactly, then design options that seize conduct. Clear definitions stop leakage and align the mannequin with the enterprise.
Defining Churn Window and Remark Interval
Churn means no energetic subscription throughout the subsequent 30 days. You observe conduct over the prior 90 days to construct options. This hole prevents utilizing future info throughout coaching.
Behavioral options like watch time predict churn greatest. Demographic options add small carry, and transactional options seize fee friction. You mix all three into one modeling desk.
Code Walkthrough
The code beneath builds dummy knowledge, explores it, and trains two fashions. Every block prints output so you possibly can observe the outcomes.
The information reveals reasonable imbalance. Round 38% of consumers churn, so accuracy alone would mislead us.
Gradient Boosted Mannequin with SHAP Explainability
from sklearn.ensemble import GradientBoostingClassifier
from sklearn.metrics import average_precision_score

gb = GradientBoostingClassifier(random_state=42)
gb.match(X_train, y_train)
proba = gb.predict_proba(X_test)[:, 1]

print("PR-AUC:", spherical(average_precision_score(y_test, proba), 3))

# Easy function significance as a SHAP stand-in
importances = pd.Collection(gb.feature_importances_, index=X.columns)
print("nFeature significance:")
print(importances.sort_values(ascending=False).spherical(3))
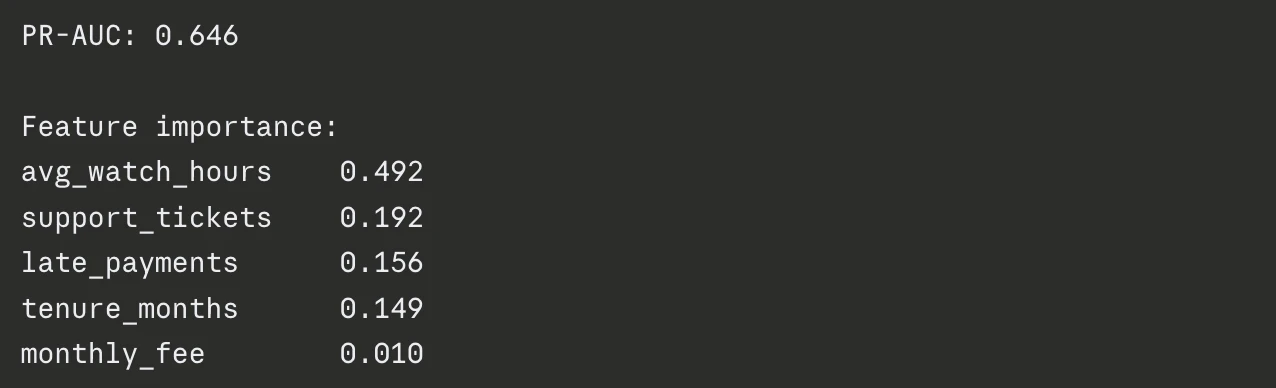
Output:
Low watch time drives churn most, adopted by help tickets. This matches enterprise instinct and makes the mannequin straightforward to elucidate.
Current This in 5 Minutes
Your presentation ought to inform a decent story. Interviewers keep in mind narrative much better than metric tables.
Opening with the Enterprise Influence: Begin with cash. Say the mannequin helps retention brokers name the five hundred riskiest prospects every week, defending income.
Strolling Via the Pipeline: Describe your steps briefly: outline churn, construct options, baseline, then increase. Preserve the technical element proportional to the viewers.
Closing with a Advice and Caveats: Suggest rating prospects by churn chance, not exhausting labels. Be aware that watch time drives threat, so declining engagement ought to set off outreach.
Instance 2 – Demand Forecasting for Stock Optimization (Time Collection)
Forecasting circumstances check whether or not you respect time. Random splits leak the long run, so it’s essential to deal with temporal order rigorously. A retailer needs each day demand forecasts to keep away from stockouts and overstock.
Drawback Assertion and Enterprise Context
A retailer shares perishable items with a three-day shelf life. Understocking loses gross sales, and overstocking creates waste. Every unit of forecast error prices about 4 {dollars} in mixed waste and misplaced margin.
Accuracy issues, however so does bias. Constant over-forecasting is dearer than random noise right here.
Making use of SCOPE to the Drawback
You first examine the sequence construction, then select a horizon that matches ordering cycles. Understanding seasonality prevents naive errors.
Decomposing Seasonality, Development, and Exterior Alerts: Demand reveals weekly seasonality and a gentle upward development. Holidays and promotions add exterior spikes. You mannequin these indicators explicitly as options.
Code Walkthrough
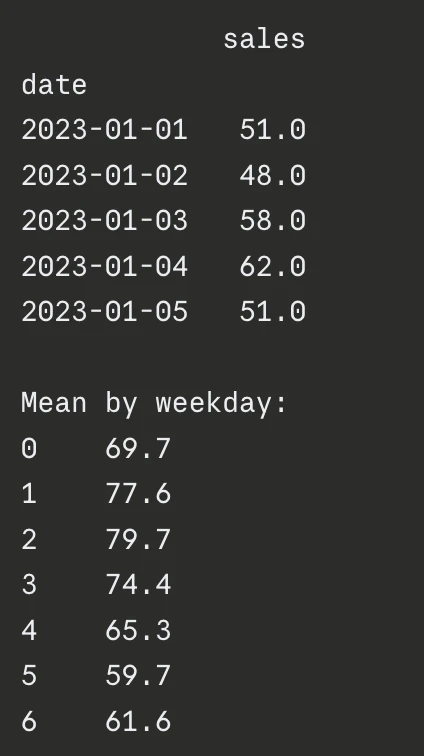
The code creates an artificial gross sales sequence with development and seasonality. It then evaluates a mannequin utilizing time-aware backtesting.
Code + Output: Time Collection EDA and Stationarity Checks
Code Instance: Backtesting with Rolling-Window Analysis
n = len(feat)
errors = []
for fold in vary(3):
   test_end = n - fold * 30
   test_start = test_end - 30
   tr = feat.iloc[:test_start]
   te = feat.iloc[test_start:test_end]
   m = GradientBoostingRegressor(random_state=7).match(tr[cols], tr["sales"])
   p = m.predict(te[cols])
   errors.append(mean_absolute_error(te["sales"], p))

errors = errors[::-1]  # oldest window first
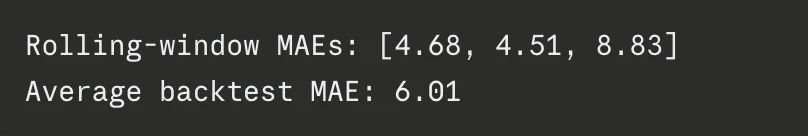
print("Rolling-window MAEs:", [round(e, 2) for e in errors])
print("Common backtest MAE:", spherical(np.imply(errors), 2))
Output:
Errors keep in an inexpensive band throughout home windows. This tells the interviewer the mannequin generalizes over time.
Current This in 5 Minutes
Forecasting tales ought to join error to value. Interviewers need operational influence, not statistical jargon.
Framing Forecast Error as Greenback Value: Translate the MAE into cash. Say 9 models of error instances 4 {dollars} equals about 36 {dollars} of waste per day per product.
Discussing Mannequin Monitoring and Drift: Clarify that demand patterns shift after promotions. Suggest weekly retraining and alerts when error exceeds a set threshold.
Instance 3 – RAG-Powered Inner Data Assistant (GenAI)
GenAI case research now seem in lots of loops. Firms need assistants that reply questions from inner paperwork. Retrieval Augmented Technology, or RAG, grounds the mannequin in actual content material.
This instance reveals scope, construct, and consider a RAG system.
Drawback Assertion and Enterprise Context
A help crew wastes hours looking inner wikis. Management needs an assistant that solutions coverage questions immediately. Solutions should cite sources and keep away from making issues up.
Belief issues greater than fluency right here. A assured improper reply prices greater than a sluggish appropriate one.
Making use of SCOPE to the Drawback
You scope the doc set, then select an method that matches the constraints. RAG often beats fine-tuning for altering inner data.
Scoping the Doc Corpus and Question Sorts: The corpus holds round 2,000 coverage paperwork. Queries are factual and particular, like refund home windows or go away insurance policies. This favors exact retrieval over artistic technology.
Selecting Between Positive-Tuning vs. RAG vs. Immediate Engineering: Positive-tuning bakes data in however ages rapidly. RAG retains data contemporary by retrieving present paperwork. You decide RAG as a result of insurance policies change typically.
You measure faithfulness, relevance, and pace. Faithfulness checks whether or not solutions match sources. Relevance checks retrieval high quality, and latency guards consumer expertise.
Code Walkthrough
The code builds a tiny doc retailer and a retrieval operate. It makes use of easy embeddings so you possibly can run it with out exterior companies.
Code + Output: Doc Chunking and Embedding Pipeline
from sklearn.feature_extraction.textual content import TfidfVectorizer

docs = [
   "Refunds are processed within 14 business days of approval.",
   "Employees receive 20 paid leave days per calendar year.",
   "Password resets require manager approval for admin accounts.",
   "Expense reports must be submitted before the 5th of each month.",
   "Remote work is allowed up to three days per week.",
]

# TF-IDF stands in for a manufacturing embedding mannequin right here
vectorizer = TfidfVectorizer()
doc_vecs = vectorizer.fit_transform(docs)

print("Embedded", len(docs), "paperwork into form", doc_vecs.form)
Output: Embedded 5 paperwork into form (5, 42)
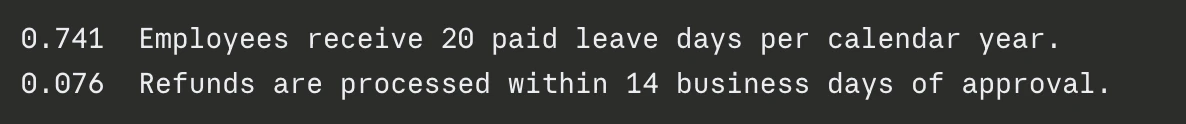
Every doc turns into a sparse vector throughout 42 vocabulary phrases. Actual programs use dense encoders like OpenAI or open-source fashions as a substitute.
Code + Output: Vector Retailer Setup with FAISS/ChromaDB
from sklearn.metrics.pairwise import cosine_similarity

def retrieve(question, ok=2):
   q = vectorizer.rework([query])
   sims = cosine_similarity(q, doc_vecs)[0]
   high = sims.argsort()[::-1][:k]
   return [(docs[i], spherical(float(sims[i]), 3)) for i in high]

outcomes = retrieve("What number of paid go away days do staff obtain?")
for textual content, rating in outcomes:
   print(f"{rating}  {textual content}")
Output:
Code + Output – Retrieval Chain with LangChain and Analysis Metrics
def rag_answer(question):
   context = retrieve(question, ok=1)[0][0]
   # In manufacturing, this context feeds an LLM immediate
   return f"Based mostly on coverage: {context}"

def faithfulness(reply, supply):
   # Fraction of supply phrases current within the reply
   src_words = set(supply.decrease().break up())
   ans_words = set(reply.decrease().break up())
   return spherical(len(src_words & ans_words) / len(src_words), 2)

question = "When are refunds processed?"
supply = retrieve(question, ok=1)[0][0]
reply = rag_answer(question)

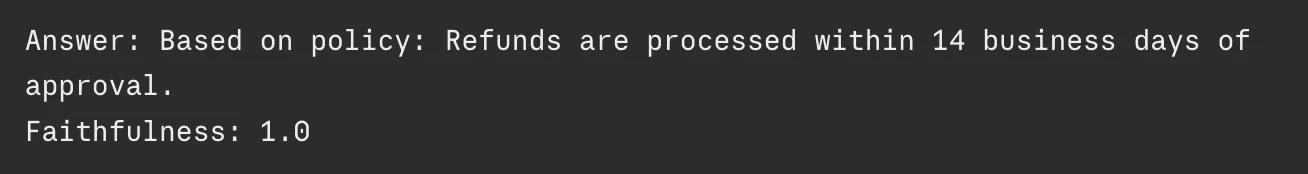
print("Reply:", reply)
print("Faithfulness:", faithfulness(reply, supply))
Output:
The reply grounds absolutely within the retrieved supply. A faithfulness rating of 1.0 reveals no invented content material.
Current This in 5 Minutes
RAG circumstances want clear, non-technical framing. Panels typically embody product and help leaders.
Explaining RAG to a Non-Technical Panel: Evaluate RAG to an open-book examination. The mannequin reads related pages, then solutions, as a substitute of guessing from reminiscence.
Discussing Failure Modes: Hallucination, Retrieval Misses, Stale Knowledge: Title the dangers brazenly. Unhealthy retrieval causes improper solutions, and outdated paperwork mislead customers. Suggest citations and freshness verify as safeguards.
Instance 4 – A/B Check Evaluation for a Product Launch (Experimentation)
Experimentation circumstances check statistical rigor. A product crew launches a brand new checkout stream and needs proof it really works. You could design and analyze the check accurately.
This instance covers energy evaluation, testing, and segmentation.
Drawback Assertion and Enterprise Context
An e-commerce website checks a redesigned checkout web page. The crew hopes to carry conversion from 10% to 11%. A improper name may damage income for tens of millions of customers.
Statistical self-discipline protects that call. You keep away from peeking and management for confounders.
Making use of SCOPE to the Drawback
You select the unit and metric first, then guard in opposition to frequent threats. Cautious design prevents deceptive conclusions.
Selecting the Randomization Unit and Major Metric: You randomize by consumer, not by session. Conversion fee is the first metric, and income per consumer is a guardrail.
Figuring out Threats: Novelty Impact, Community Results, Simpson’s Paradox: New designs typically trigger short-term novelty spikes. Segments can even reverse combination traits, referred to as Simpson’s paradox. You propose for each.
Code Walkthrough
The code computes pattern dimension, runs each checks, and segments outcomes. It makes use of artificial conversion knowledge for 2 teams.
Code + Output: Energy Evaluation and Pattern Measurement Calculation
from statsmodels.stats.energy import NormalIndPower
from statsmodels.stats.proportion import proportion_effectsize

impact = proportion_effectsize(0.11, 0.10)
evaluation = NormalIndPower()
n = evaluation.solve_power(effect_size=impact, alpha=0.05, energy=0.8, ratio=1)
print("Required pattern dimension per group:", int(np.ceil(n)))
Output: Required pattern dimension per group: 14745
You want about 14,700 customers per group. This tells the crew how lengthy to run the check earlier than deciding.
Code + Output – Segmented Evaluation and Guardrail Metrics
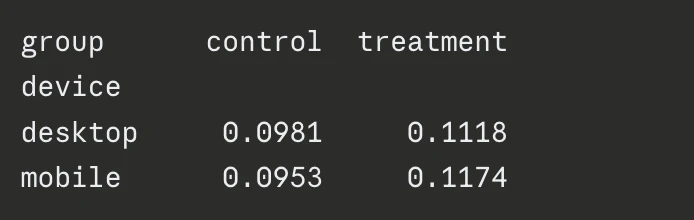
The therapy wins on each units. This consistency guidelines out a Simpson’s paradox reversal.
Current This in 5 Minutes
Experiment outcomes want a decision-focused story. Interviewers desire a clear ship-or-not verdict.
Telling the Story: What We Examined, What We Discovered, What We Ought to Do:
Say you examined a brand new checkout, discovered a 1.8-point carry, and advocate delivery. Add that you’d monitor income for 2 weeks after launch.
Errors That Sink Case Examine Interviews
Even sturdy candidates journey on predictable errors. Avoiding these errors typically issues greater than intelligent modeling. The part beneath lists the traps that almost all typically finish interviews early.
Learn them as a pre-interview guidelines. Every one maps to a step within the SCOPE framework.
Leaping to fashions earlier than understanding the issue: You optimize the improper goal confidently.
Treating GenAI as magic: You ignore retrieval, analysis, and failure modes.
Ignoring knowledge leakage and lookahead bias: Your scores look nice however by no means generalize.
Over-engineering when a easy heuristic wins: You waste time and add fragile complexity.
Optimizing a metric the enterprise ignores: You enhance accuracy whereas income stays flat.
Presenting a pocket book walkthrough as a substitute of a story: You bore the panel with cells.
Conclusion
Case examine interviews reward structured pondering over flashy fashions. The SCOPE framework offers you a dependable path from enterprise context to a assured suggestion. Follow it throughout classification, forecasting, GenAI, and experimentation till the stream feels pure.
Bear in mind the core shift: cease asking “which mannequin ought to I construct” and begin asking “which enterprise drawback am I fixing.” Mix that mindset with clear code and a powerful narrative, and you’ll stand out in any aggressive hiring loop.
Continuously Requested Questions
Q1. What does the SCOPE framework assist with?
A. It supplies a structured method to fixing any knowledge science case examine, from understanding the issue to presenting suggestions.
Q2. What do interviewers worth most in case examine interviews?
A. Structured pondering, sound judgment, clear communication, and enterprise reasoning over selecting probably the most superior mannequin.
Q3. Why is enterprise context necessary earlier than analyzing knowledge?
A. Understanding the enterprise drawback ensures the answer aligns with stakeholder objectives and real-world influence.
Howdy! I am Vipin, a passionate knowledge science and machine studying fanatic with a powerful basis in knowledge evaluation, machine studying algorithms, and programming. I’ve hands-on expertise in constructing fashions, managing messy knowledge, and fixing real-world issues. My objective is to use data-driven insights to create sensible options that drive outcomes. I am desirous to contribute my abilities in a collaborative surroundings whereas persevering with to study and develop within the fields of Knowledge Science, Machine Studying, and NLP.
Login to proceed studying and revel in expert-curated content material.
TL;DR:Unlock hidden macOS settings, customise your Mac, and fine-tune system options with a lifetime MacPilot license for simply $39.99 (MSRP $99).
Customizing macOS past the fundamentals usually means looking out boards or copying Terminal instructions. MacPilot simplifies the method by placing tons of of superior settings into one easy-to-use app, and a lifetime license is on sale for $39.99 (MSRP $99).
Customise macOS with out Terminal
MacPilot is like having a hacker mode on your Mac while not having a coding diploma. With a couple of clicks, you’ll be able to:
Reveal hidden system settings: Present hidden information in Finder, disable the startup chime, and tweak icon animations
Supercharge your Dock: Add spacers, good stacks, and hidden menu choices
Optimize efficiency: Run upkeep instruments, clear cache, and restore system information
Get deep system insights: View detailed specs on {hardware}, RAM speeds, community ports, and extra
Whether or not you’re a developer, inventive professional, or simply somebody who desires their Mac operating at peak effectivity, MacPilot places superior customization at your fingertips — with out the headache of Terminal instructions.
I’ve had only a few issues with any inflatable sleeping pad I’ve examined. Some have misplaced air, however I’ve by no means had one deflate fully (knock on wooden). That mentioned, there are some tips to getting one of the best evening’s sleep and having a nice journey.
Don’t inflate your pad along with your mouth: For one factor, a few of these pads are large, and it’s only a ache, but additionally your breath is heat and moist and also you’re injecting into nylon, which is a recipe for mildew and mould. This fear could also be considerably overblown—just a few folks have lower open pads they’ve inflated by mouth for years and located no signal of mould—however contemplating what a ache it’s to do anyway, it appears simpler to simply keep away from it. Most producers embrace some form of pump sack today, which makes fast work of inflating your pad. There are additionally motorized pumps that solely weigh an oz. or two, just like the Flextail pump.
Don’t over-inflate: Insulated sleeping pads work by placing air and materials between you and the chilly floor, however that doesn’t imply that you must inflate it till it’s taut. It varies by pad. I typically discover that one of the best methodology is to inflate it taut, after which begin to let loose air, mendacity down to check it till you get to the place it feels snug. The draw back to this methodology is that your pad isn’t that thick and also you’re extra more likely to backside out in the event you let loose an excessive amount of air. I discover this isn’t a lot of a problem for abdomen or again sleepers, however in the event you’re a facet sleeper it would take a while to search out the candy spot between consolation and heat.
Carry a patch package: Most sleeping pads today embrace a patch package. I not often deliver these kits and as an alternative carry a small roll of Tenacious Tape ($6), which is able to remedy rips and tears in every part from sleeping pads to tents. Ensure that to check a small piece of tape in your pad beforehand to verify the tape sticks, and convey an alcohol wipe to scrub the affected space.
Girls want larger R-value pads: Girls typically have decrease physique mass than males, which suggests girls ought to add roughly 1 R-value to get the identical quantity of insulation in the identical scenario. (I additionally suggest upping the R-value in the event you’re a chilly sleeper normally.)
Sleeping bag scores assume R5 pads: Most temp scores you see on sleeping baggage are true provided that you’re utilizing a sleeping pad with an R-value of 5 or larger (in addition they assume you’re sporting a base layer). In case your pad is much less, you will want to regulate your sleeping bag temp score accordingly. For instance, utilizing your 30 diploma quilt with a R4 pad will seemingly go away you chilly in the event you encounter freezing temps. In that scenario you’d wish to both up the R-value of the pad, or deliver a hotter sleeping bag.
Constructing a deep learning-based explainable next-best-product suggestion system helps banking establishments predict which product a buyer wants subsequent. Banks maintain huge quantities of buyer knowledge, together with transaction histories, product possession data, demographic profiles, and behavioral patterns. Translating this knowledge into actionable, customized product suggestions stays a major problem. Conventional rule-based programs and collaborative filtering approaches usually fail to seize the complicated temporal patterns in buyer product adoption journeys.
On this submit, we current the structure and design choices behind a Subsequent-Finest-Product (NBP) suggestion system utilizing Amazon SageMaker AI and PyTorch. We clarify the reasoning behind a multi-tower neural community structure, how realized consideration gives per-customer explainability, and the way AWS companies work collectively to take this answer from analysis to manufacturing. That is an architectural overview, not a step-by-step deployment information. Whether or not you’re constructing suggestion programs for monetary companies or different domains with heterogeneous buyer knowledge, the architectural patterns described right here may also help you design extra correct and interpretable fashions.
Conditions
To comply with together with the architectural patterns and code examples on this submit, you want:
This answer requires an AWS Identification and Entry Administration (IAM) execution position with entry to the next AWS companies. Create insurance policies with least-privilege permissions scoped to solely the sources wanted for this answer.
SageMaker AI – Create, describe, begin, cease, and delete coaching jobs, processing jobs, batch remodel jobs, fashions, endpoints, endpoint configurations, pipelines, experiments, and monitoring schedules. InvokeEndpoint for real-time inference.
Amazon S3 – Learn and write entry to the information bucket. Create and delete bucket. Record, add, obtain, and delete objects.
AWS Glue – Create, run, and delete ETL jobs. Create and delete crawlers. Create and delete Knowledge Catalog databases and tables.
CloudWatch – Learn and write entry to log teams, log streams, and metrics. Delete log teams throughout cleanup.
IAM – Create and delete roles. Connect and detach insurance policies. PassRole (restricted to the named execution position ARN, scoped to sagemaker.amazonaws.com and glue.amazonaws.com).
For steerage on writing least-privilege IAM insurance policies for SageMaker AI, see Identification-based coverage examples for SageMaker AI.
Required packages to create this recommender system:
Python 3.11+
PyTorch 2.9+
Pandas 2.3+
NumPy 2.3+
scikit-learn 1.7+
Dask 2025.11+
We suggest utilizing a digital surroundings and scanning dependencies for recognized vulnerabilities utilizing instruments like pip-audit earlier than deployment.
Fundamental understanding of deep studying ideas (embeddings, recurrent networks, consideration mechanisms)
Be aware: Deploying this answer creates billable AWS sources together with SageMaker AI coaching jobs (ml.g5.12xlarge GPU cases), SageMaker AI endpoints, Amazon S3 storage, and AWS Glue jobs. Observe the clear up directions on the finish of this submit to keep away from ongoing costs.
Resolution overview
The answer makes use of a multi-tower deep studying structure with 4 specialised neural community towers, every processing a special side of buyer knowledge. The towers are fused utilizing a realized consideration mechanism that gives each excessive accuracy and per-customer explainability.
The next diagram illustrates the high-level structure of the answer.
The structure addresses a typical problem in banking: predicting which product a buyer is almost certainly to buy subsequent from a number of product classes (comparable to bank cards, deposits, insurance coverage, loans, and mortgages), whereas offering explainable outcomes that fulfill regulatory necessities.
Tech stack
The next desk summarizes the expertise decisions and their roles within the answer.
Part
Know-how
Goal
ETL & Knowledge Processing
AWS Glue (PySpark)
Serverless Spark-based ETL for knowledge unification, service mapping, characteristic engineering at scale
This answer makes use of PyTorch for dynamic computation graphs (wanted for variable-length sequences with pack_padded_sequence), speedy iteration throughout a number of architectural phases, and native integration with SageMaker AI coaching jobs and inference containers.
Why Parquet on Amazon S3?
The answer shops knowledge as Snappy-compressed Parquet on Amazon Easy Storage Service (Amazon S3). Parquet’s columnar format permits column pruning (studying a fraction of a large file), predicate pushdown (skipping irrelevant row teams), 3-5× compression over CSV, and sort preservation with out re-parsing on each learn.
Why AWS Glue for ETL?
The venture makes use of AWS Glue jobs operating on PySpark for serverless, auto scaling knowledge processing. AWS Glue gives native Spark integration, the DynamicFrame API for versatile schemas, computerized Knowledge Catalog registration, job bookmarks for incremental processing, and pay-per-DPU value effectivity.
Knowledge pipeline structure
The information pipeline consists of two phases: an AWS Glue ETL job for knowledge unification, adopted by an Amazon SageMaker Processing job for ML-specific characteristic engineering.
Knowledge unification with AWS Glue
Banking knowledge usually arrives from a number of supply programs with inconsistent schemas. The AWS Glue ETL job normalizes schemas, maps uncooked transaction sorts to unified service classes, combines all knowledge right into a single chronological document per buyer, and engineers temporal options. The processed output is written as Parquet to Amazon S3 and registered within the AWS Glue Knowledge Catalog.
ML-specific characteristic engineering with Amazon SageMaker Processing
After the AWS Glue job produces the unified historical past, an Amazon SageMaker Processing job creates product adoption sequences per buyer, computes time-windowed transaction aggregations (throughout 7, 30, 60, 180, and 365-day home windows) utilizing Dask for parallelism, and pads sequences to a set size for mannequin enter.
Dealing with massive scale knowledge
For giant datasets that exceed out there reminiscence, the answer makes use of a parallel chunked processing technique with PyArrow for metadata inspection, ProcessPoolExecutor for parallel chunk processing, express rubbish assortment between batches, and incremental merging to keep away from reminiscence spikes.
import gc
from concurrent.futures import ProcessPoolExecutor

chunksize = 5_000_000
n_workers = 4

for batch_start in vary(0, total_chunks, n_workers):
    with ProcessPoolExecutor(max_workers=n_workers) as executor:
        futures = [
            executor.submit(process_chunk_range, input_path, output_path, i, start_row, end_row)
            for i in range(batch_start, min(batch_start + n_workers, total_chunks))
        ]
        for future in futures:
            future.consequence()
    gc.acquire()  # Pressure rubbish assortment between batches
Be aware: When working with actual buyer knowledge, see the Safety concerns part for steerage on PII dealing with, regulatory compliance, and knowledge governance.
Mannequin structure
The mannequin makes use of a multi-tower method the place every tower makes a speciality of processing one kind of buyer knowledge, adopted by an attention-based fusion mechanism.
Why multi-tower over a single community?
Various kinds of buyer knowledge have basically totally different constructions. Sequences are ordered lists of discrete IDs. Transactions are numerical aggregations. Demographics are a mixture of categorical and numerical options. Behavioral segments are categorical codes.
Forcing all these by the identical layers wastes mannequin capability. As an alternative, the structure makes use of 4 specialised towers, every designed for its knowledge kind:
Tower
Enter Sort
Structure
Output
Sequence Tower
Product adoption historical past (padded to mounted size)
nn.Embedding → 2-layer GRU → Fusion with energetic product rely
64-dim vector
Transaction Tower
Time-windowed transaction options
2-layer MLP (128 → 64) with ReLU and Dropout
64-dim vector
Buyer Tower
Demographics, revenue, household, account options
2-layer MLP (128 → 64) with ReLU and Dropout
64-dim vector
Behavioral Tower
Segmentation codes, loyalty, utilization patterns
2-layer MLP (128 → 64) with ReLU and Dropout
64-dim vector
Sequence Tower: Capturing temporal patterns
The Sequence Tower processes the shopper’s product adoption historical past utilizing a 2-layer Gated Recurrent Unit (GRU). That is the core architectural part as a result of it captures the order by which clients undertake merchandise, not simply which merchandise they personal.
GRU has two gates (reset, replace) versus LSTM’s three (enter, overlook, output), leading to roughly 33% fewer parameters. For brief sequences (20 gadgets or fewer), GRU performs comparably to LSTM whereas coaching quicker. The replace gate’s interpolation mechanism additionally creates a pure residual-like gradient path.
Why pack_padded_sequence?
Buyer sequences have variable lengths. Packing tells the GRU to disregard padding tokens, stopping the mannequin from studying noise from zero-padded positions.
Tower Consideration Mechanism: Discovered fusion with explainability
As an alternative of straightforward concatenation, the structure makes use of a realized consideration mechanism to fuse tower outputs. That is what gives per-customer explainability with out requiring post-hoc interpretation strategies like SHAP or LIME.
The tower weights are per-customer. A buyer with wealthy transaction historical past will get a excessive transaction tower weight, whereas a brand new buyer with few transactions however clear demographics will get a excessive buyer tower weight. This adaptivity improves accuracy and gives pure explainability for relationship managers and regulators.
Context-Conscious Fusion: Residual blocks for secure coaching
The weighted tower outputs move by a fusion community with residual connections. Residual connections assist with gradient circulation throughout coaching and permit the community to be taught identification mappings when extra depth just isn’t wanted.
Banking regulators require mannequin explainability. Relatively than counting on post-hoc strategies, the structure features a Characteristic Significance Module that produces per-customer significance scores summing to 1.0 as a part of the ahead move.
This produces outputs like: “For this buyer, 40% of the advice was pushed by their product sequence, 30% by transaction patterns, 20% by demographics, 10% by behavioral section.” Relationship managers can use this to tailor their conversations with every buyer.
Coaching technique
The next desk summarizes the coaching configuration and the rationale behind every selection.
Normal for multi-class classification, numerically secure
LR Scheduler
ReduceLROnPlateau (issue=0.5, endurance=3)
Mechanically halves LR when validation loss plateaus
Gradient Clipping
max_norm=1.0
Prevents gradient explosion with GRU and a spotlight
Early Stopping
endurance=5
Stops coaching when validation loss stops bettering
Batch Measurement
32
Matches comfortably in A10G’s VRAM
Knowledge Cut up
80% practice / 10% validation / 10% check
Normal break up for reproducibility
All random seeds are mounted (PyTorch, NumPy, CUDA) for full reproducibility throughout coaching runs.
The coaching course of makes use of SageMaker AI with ml.g5.12xlarge cases. The SageMaker AI Python SDK gives a PyTorch Estimator that packages the coaching code, provisions GPU cases, runs coaching, and shops mannequin artifacts to Amazon S3 mechanically.
The mannequin is evaluated utilizing metrics that instantly map to enterprise worth:
Metric
What It Measures
Enterprise Relevance
Prime-1 Accuracy
Actual prediction accuracy
“Did the mannequin predict the precise proper product?”
Prime-3 Accuracy
Right product in prime 3
“Is the precise product within the brief listing for the connection supervisor?”
Prime-5 Accuracy
Right product in prime 5
“Is it within the suggestion carousel?”
MRR (Imply Reciprocal Rank)
Common reciprocal rank of appropriate product
“How excessive up is the proper product on common?”
Weighted F1
Per-class precision/recall stability
“Does the mannequin predict all product sorts nicely?”
The manufacturing mannequin achieved sturdy efficiency throughout all metrics, with the proper product constantly showing within the top-3 suggestions. The characteristic significance module confirmed that the sequence tower (product adoption historical past) contributes probably the most sign, adopted by transaction patterns, buyer demographics, and behavioral segmentation.
Inference and deployment
The inference pipeline helps each batch scoring and real-time predictions utilizing SageMaker AI.
For batch scoring, SageMaker AI Batch Remodel processes your complete buyer base nightly, producing top-k suggestions with explainability scores for every buyer. Outcomes are saved as JSON on Amazon S3 for consumption by CRM programs and relationship supervisor dashboards.
For real-time predictions, a SageMaker AI real-time endpoint serves on-demand suggestions when a buyer logs into the cellular banking app or a relationship supervisor opens a buyer profile.
Every suggestion contains:
Product ID and likelihood rating.
Characteristic significance breakdown: share contribution from every tower.
Confidence indicator: primarily based on likelihood distribution entropy.
def generate_batch_recommendations(mannequin, dataloader, top_k=5):
    with torch.no_grad():
        for batch in dataloader:
            outputs, feature_importance = mannequin(
                batch['sequence'], batch['seq_length'],
                batch['active_count'], batch['transaction'],
                batch['customer'], batch['behavioral']
            )
            possibilities = F.softmax(outputs, dim=1).cpu().numpy()
            # Generate top-k suggestions with explainability scores
For steerage on securing endpoints with IAM authentication, price limiting, and digital non-public cloud (VPC) isolation, see the Safety concerns part.
Be aware: The code snippets on this submit illustrate architectural patterns and aren’t production-ready. For manufacturing, add enter validation (tensor shapes, NaN checks, sequence size bounds and so on.), error dealing with, and inference logging. Configure Amazon SageMaker Mannequin Monitor to alert on enter distribution drift.
Key design choices
Why multi-tower over a single community? A single community would want to concurrently learn to course of sequences, mixture transactions, encode demographics, and interpret behavioral segments. Separate towers let every concentrate on its knowledge kind, then the attention-based fusion learns how you can mix them optimally per buyer.
Why GRU for manufacturing over Transformers? Transformers excel on lengthy sequences (100+). For sequences of 20 gadgets or fewer, GRU is ample, gives clearer interpretability than transformer consideration maps, avoids quadratic consideration computation, and produces a smaller mannequin (~5 MB in comparison with ~15 MB).
Why realized tower weights as an alternative of concatenation? With concatenation, the mannequin treats all towers equally for each buyer. With realized consideration weights, the mannequin adapts per buyer: a buyer with wealthy transaction historical past will get excessive transaction tower weight, whereas a brand new buyer will get excessive demographic tower weight.
Why time-windowed transaction options? Totally different time home windows seize totally different indicators: 7 days captures speedy intent, 30 days captures month-to-month patterns, 180 days captures seasonal patterns, and three hundred and sixty five days captures annual patterns. A buyer who abruptly will increase transaction frequency within the final 7 days has totally different intent than one with regular exercise over three hundred and sixty five days.
Operational concerns
All random seeds are mounted throughout PyTorch, NumPy, and CUDA for deterministic coaching. Mannequin artifacts, hyperparameters, and knowledge variations are tracked by Amazon SageMaker Experiments.
Amazon SageMaker Mannequin Monitor detects knowledge drift (adjustments in enter characteristic distributions), mannequin drift (degradation in prediction high quality), and potential bias (over-reliance on demographic options).
The Amazon SageMaker Pipelines workflow retrains the mannequin month-to-month with the newest buyer knowledge. The pipeline automates the complete workflow: knowledge processing, coaching, analysis, and conditional deployment (deploying provided that metrics enhance over the present manufacturing mannequin).
Safety concerns
When deploying this answer with actual banking knowledge, implement least-privilege IAM roles scoped to solely the required SageMaker AI, Amazon S3, AWS Glue, and CloudWatch actions.
Encrypt knowledge at relaxation utilizing AWS Key Administration Service (AWS KMS) buyer managed keys on S3 buckets and SageMaker AI coaching volumes, and implement TLS for all knowledge in transit by way of S3 bucket insurance policies.
Deploy coaching jobs and endpoints in non-public VPC subnets with no web gateway, use VPC endpoints (AWS PrivateLink) for AWS service communication, and set enable_network_isolation=True on coaching jobs.
Safe inference endpoints with AWS Signature Model 4 signing, and take into account Amazon Cognito and Amazon API Gateway for client authentication and price limiting.
For knowledge governance, assess regulatory obligations (PCI-DSS, GDPR, CCPA), implement knowledge minimization, and outline retention insurance policies.
Allow AWS CloudTrail for API audit logging and S3 versioning for mannequin artifact integrity.
CloudWatch log teams created by SageMaker AI and AWS Glue.
You possibly can delete these sources by the AWS Administration Console or utilizing the AWS Command Line Interface (AWS CLI).
Warning: Deleting these sources is irreversible. Earlier than continuing:
Export any mannequin artifacts or analysis outcomes you might want to retain.
Confirm that deletion aligns along with your knowledge retention insurance policies and regulatory necessities.
Delete all S3 object variations if versioning is enabled.
Take away IAM roles and insurance policies created for this answer.
Deleting S3 buckets completely removes all coaching knowledge, mannequin artifacts, and batch remodel outcomes.
Conclusion
This submit confirmed how you can construct a Subsequent-Finest-Product suggestion system for banking utilizing PyTorch and SageMaker AI. The multi-tower structure with realized consideration fusion achieves excessive prediction accuracy whereas offering the explainability required by banking regulators.
The important thing takeaways are:
Specialised towers for various knowledge sorts outperform monolithic architectures for heterogeneous banking knowledge.
Discovered tower consideration gives each accuracy positive factors and per-customer explainability with out post-hoc interpretation strategies.
SageMaker AI gives the end-to-end infrastructure for coaching, mannequin administration, and inference at scale.
You possibly can adapt this multi-tower structure to your individual product catalog and buyer knowledge. To get began, discover the SageMaker AI documentation. For added examples of PyTorch on AWS, see PyTorch on AWS. If you want assist constructing a suggestion system to your group, contact an AWS consultant.
This is the reason cloud monetary administration has grow to be such an essential self-discipline. Firms should be much more considerate about how they decide to cloud sources, how they mannequin their future consumption, and the way they construct flexibility into their cloud methods. The times of assuming you may at all times resell your manner out of an overcommitment are successfully over, not less than with AWS.
For Azure and Google Cloud, the resale panorama is barely completely different, however the identical common ideas apply. These suppliers have their very own capability switch insurance policies and, like AWS, these insurance policies can change at any time. Firms ought to perceive their choices earlier than making giant, dedicated purchases and construct contingency plans in case their precise utilization diverges from their projections—or if resale insurance policies change.
The underside line is that reselling unused reserved cloud cases is much extra difficult than it sounds. The market shouldn’t be as open because it as soon as was, the choices are restricted, and the suppliers themselves maintain many of the playing cards. My consumer received burned, and I doubt they would be the just one. Firms that wish to optimize their cloud spending ought to concentrate on correct forecasting, considerate dedication sizing, and ongoing optimization quite than counting on resale as a security valve. That method labored at one level, however these days are largely gone.
Our professional reviewers spend hours testing and evaluating services and products so you possibly can select one of the best for you. Discover out extra about how we check.
This 12 months, Soundcore brings each delicate enhancements and awe-inspiring upgrades that each pair of earbuds available on the market needs to be replicating. And I don’t say that evenly. Whereas nonetheless not market-leading, they’ve even improved their weakest level: lively noise-canceling power.
Total, I’ve been fully floored by what Soundcore has been in a position to accomplish, so let’s get to it, and I’ll inform you why the Soundcore Liberty 5 Professional and Liberty 5 Professional Max are extra than simply an improve over the 5; they’re a “must-have.”
Swipe to scroll horizontally
Soundcore Liberty 5 Professional specs
Classes
Liberty 5 Professional
Liberty 5 Professional Max
Conectivity
Bluetooth® 6.1, Multipoint assist for as much as 3 units
Bluetooth® 6.1, Multipoint assist for as much as 3 units
Case
0.96 TFT Contact display screen
1.78″ AMOLED display screen, Display wallpaper, AI recording/transcriptions/face-to-face translations
Drive items
9.2mm Wool-Paper Diaphragm Drivers
9.2mm Wool-Paper Diaphragm Drivers
Codec assist
SBC, AAC, LDAC
SBC, AAC, LDAC
Dolby Atmos assist
Sure
Sure
Battery life
As much as 6.5 hours (ANC on), 28 hours with case
As much as 4 hours, 17 hours all options on
As much as 6.5 hours (ANC on), 28 hours with case
As much as 4 hours, 17 hours all options on
Charging
Wi-fi & USB-C, 1 hr for earbuds, 3 hrs for case + earbuds full cost; 5 minutes charging for as much as 4 hrs playtime
Wi-fi & USB-C, 1 hr for earbuds, 3 hrs for case + earbuds full cost; 5 minutes charging for as much as 4 hrs playtime
Sturdiness
IP55
IP55
App assist
Android, iOS
Android, iOS
Audio tuning
8-band EQ (app), HearID 5.0 for customized sound
8-band EQ (app), HearID 5.0 for customized sound
Microphone
8 mics + 2 VPU + AI Massive Mannequin
8 mics + 2 VPU + AI Massive Mannequin
Colours
Midnight Black, Pearl White, Pearl Blue, Rose Gold
Titanium Gold, Midnight Black
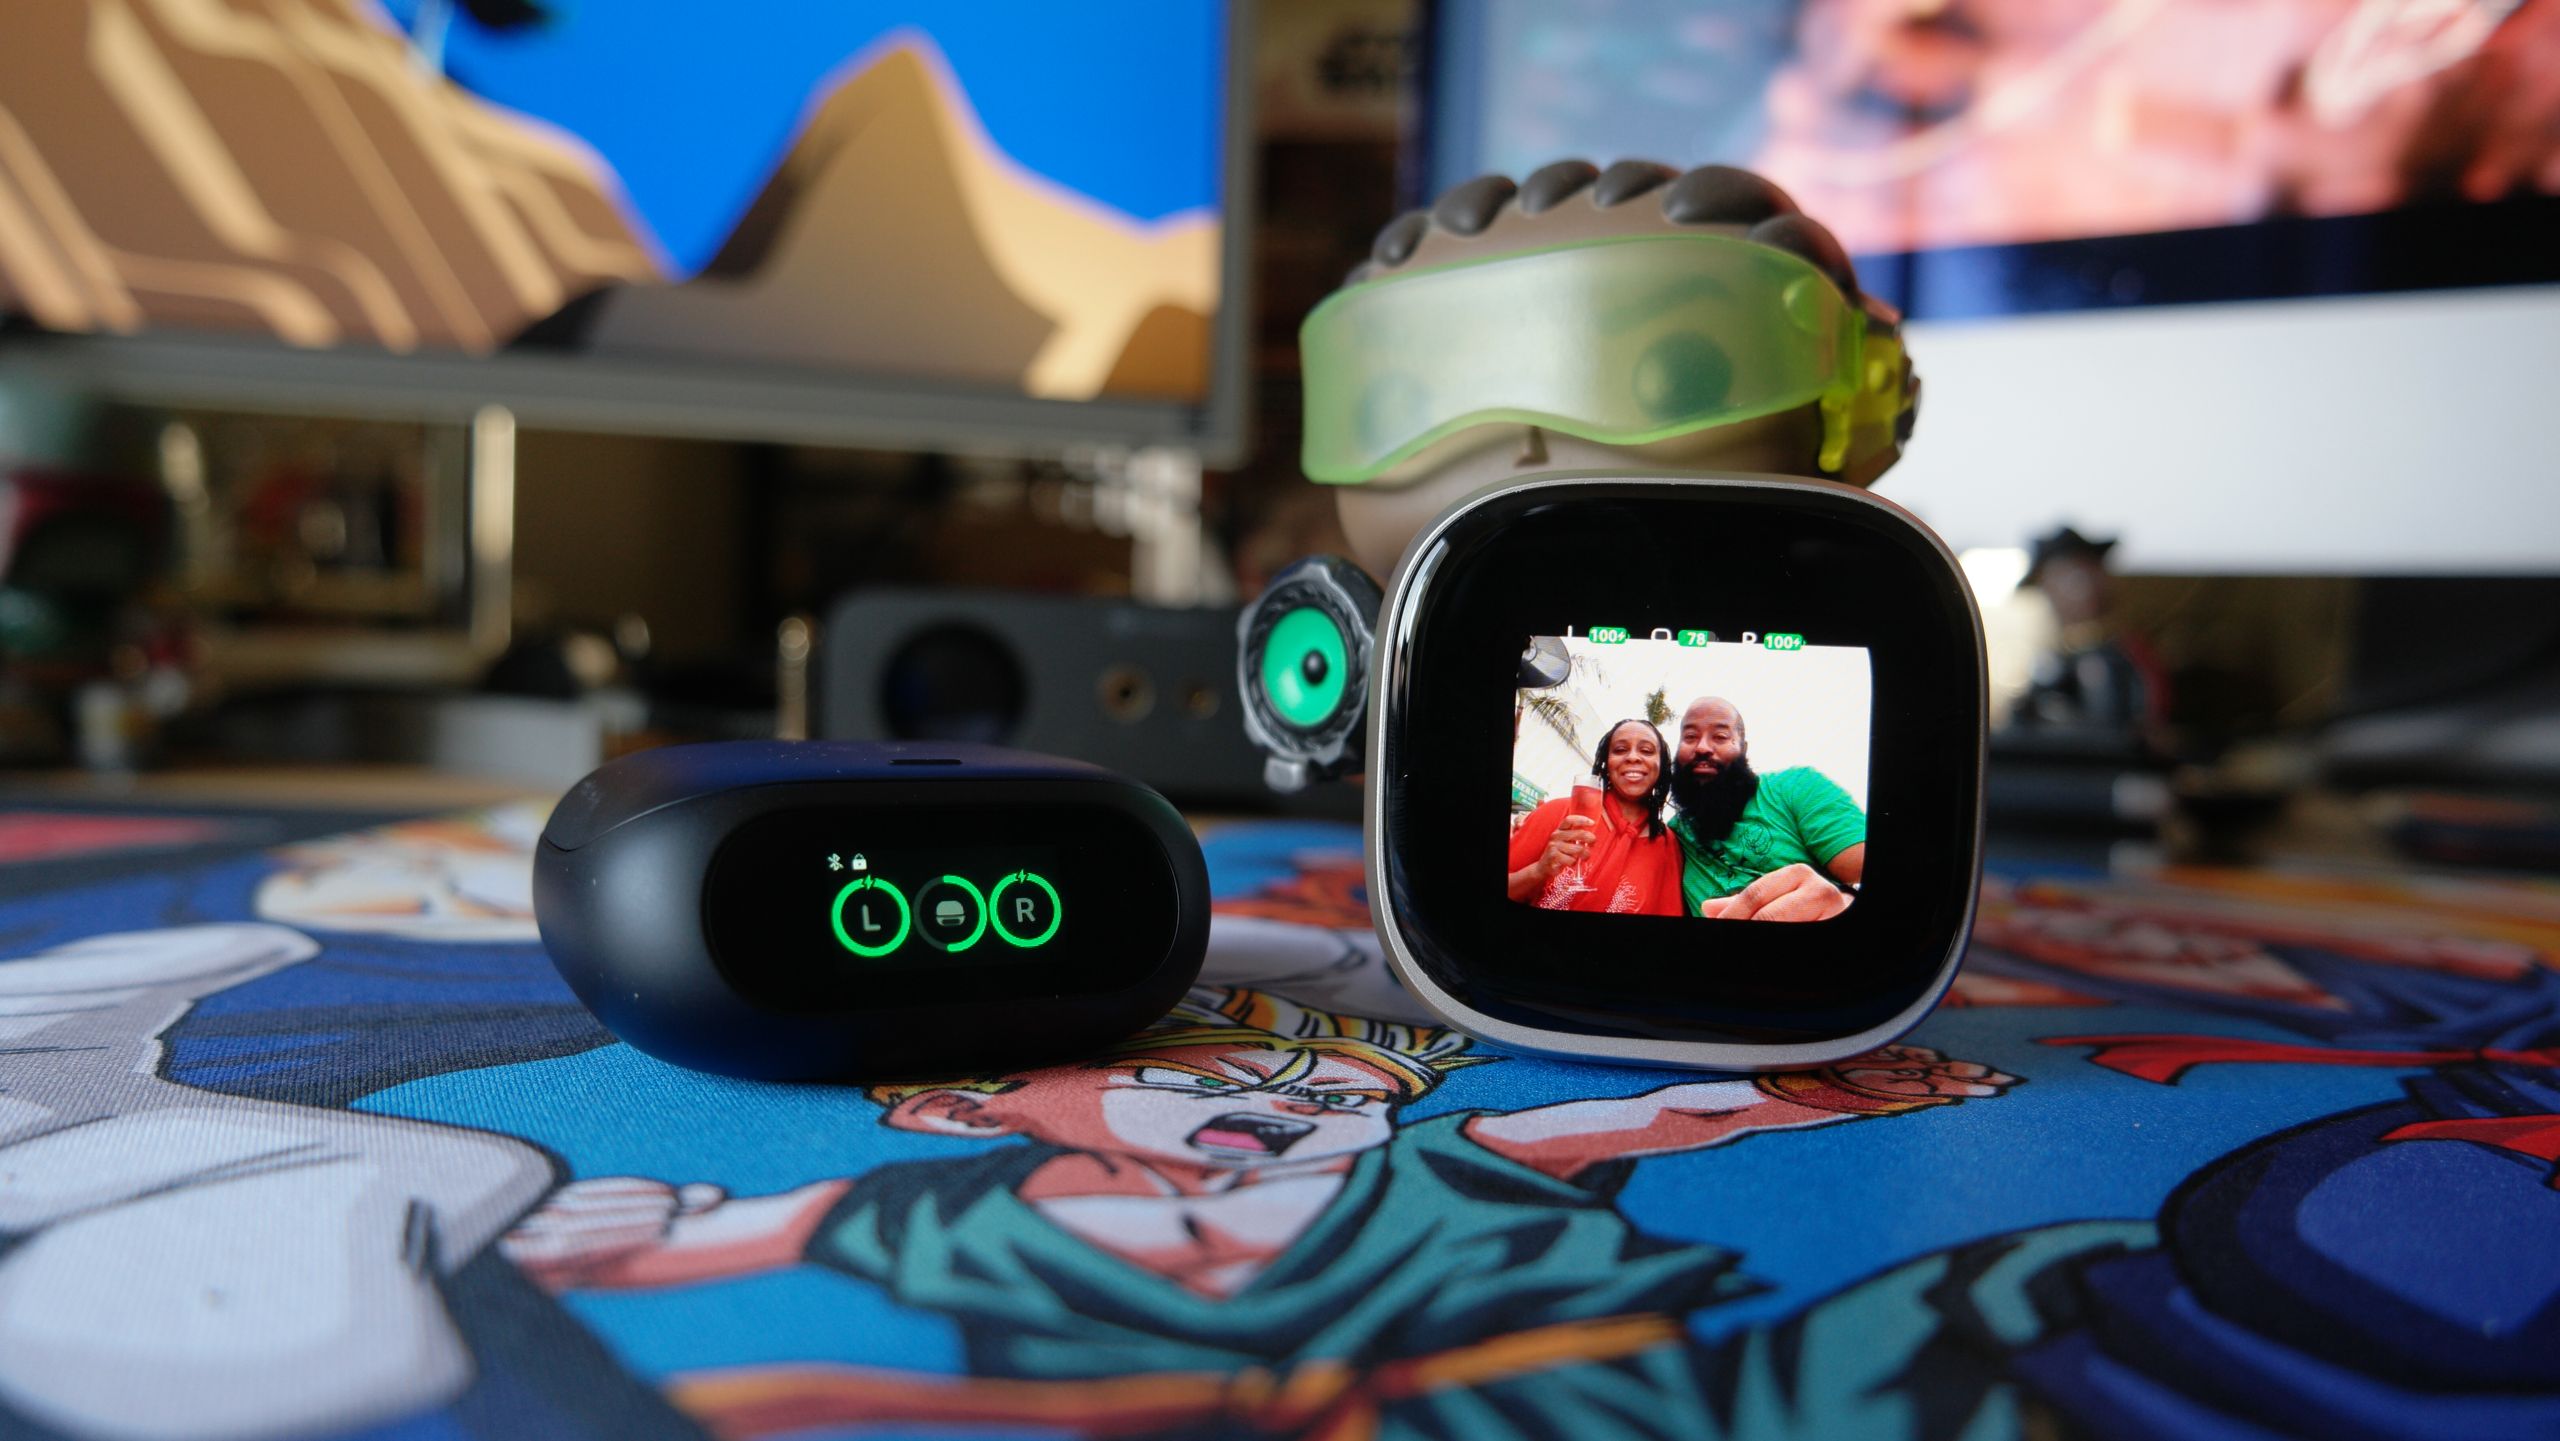
Soundcore Liberty 5 Professional vs Professional Max: Visible variations
Liberty 5 Professional Max (L), Liberty 5 Professional (R) (Picture credit score: @tshakaarmstrong)
I began my overview interval with the pricier, new Liberty 5 Professional Max, however I’ve been utilizing each Professional fashions interchangeably. Each new instances’ lids slide up just like the Liberty 5, and now they’ve exterior “good shows.” Although the scale of each new Professional fashions are comparable, the Professional Max is taller and brighter, due to its 1.78-inch AMOLED good show (the Professional’s is .96 inches).
Newest Movies FromAndroid Central
(Picture credit score: @tshakaarmstrong)
Each shows are responsive and straightforward to learn in direct daylight. The Professional Max lets you add wallpaper, each stills and animations, which show on the display screen when it’s awake. Utilizing the case, swiping left or proper permits you to management ANC modes, EQ, and playback. Swiping up from the underside offers you entry to all of the apps, and swiping down from the highest brings up quick-access shortcuts for varied settings. All of that with out pulling out your cellphone.
The one draw back is that whereas the case is pocketable for a 6 ’ 215lb man like me (it matches in my pants coin pocket), it will likely be massive for others with smaller frames while you evaluate it to the Pixel Buds or Galaxy Buds 3 Professional instances (see comparability within the gallery above).
Liberty 5 Professional Max (L), Liberty 5 Professional (Heart), Liberty 5 (R) (Picture credit score: @tshakaarmstrong)
This 12 months, the brand new Liberty 5 Professional fashions have been redesigned so that they’re not stem-style earbuds; as an alternative, they’ve an earbud with a “surfboard” sitting over the bottom. And, like some surfboards, the brand new fashions have rear fins which are available in three completely different sizes, together with the one already put in.
The fins, together with loads of eartip choices, made it simple to get the precise match. And it’s a locked-in match that feels as safe as my favourite health club earbuds, the Powerbeats Match!
Get the most recent information from Android Central, your trusted companion on the earth of Android
Soundcore Liberty 5 Professional Max with earfin eliminated (Picture credit score: @tshakaarmstrong)
When putting the earbuds in my ears, the thought is to twist barely to get the earfins to lock in. Not doing that, they’ve a looser match, however they nonetheless really feel fairly safe, and that’s how I’ve worn them more often than not. For the health club, I simply twist and lock in, and so they’re nice!
Usually, I hate the match of oval-shaped eartips and haven’t discovered them comfy throughout fairly just a few earbuds I’ve examined over time, however with the Liberty 5 Professional fashions, they really feel excellent.
Thoughts-blowing, record-setting name high quality
In accordance with Soundcore, the brand new Liberty 5 Professional fashions earned a Guinness World Information title for the readability of their calls, and after my testing, I consider them! Essentially the most fascinating side of my time with the Professional and Professional Max has been the decision high quality enabled by the brand new Anker Thus AI audio chip embedded within the earbuds.
At some point throughout my 45-minute commute house, I gave my pal a name utilizing an iPhone 16 Professional Max with the Liberty 5 Professional linked. He’s a broadcast engineer who intimately is aware of the ins and outs of audio and video.
We chatted your entire time I used to be driving, and once I made it house, I requested him the place he thought I used to be calling him from. He informed me it appeared like I used to be in a quiet room and my voice sounded nice.
The audio meter on the Voice Recorder app is flat, regardless of having the literal sound of an airplane blasting on the reviewer. (Picture credit score: @tshakaarmstrong)
I recorded myself speaking utilizing the Voice Recorder app on a Samsung Galaxy S25 Extremely whereas taking part in 80dB of airplane cabin and concrete site visitors noise. I assumed I used to be within the Twilight Zone once I performed that audio again as a result of not solely was there not even the slightest trace that 80dB of noise was actually blasting in my face from lower than two ft away, My voice was nonetheless clear, although very barely muddy, however it didn’t sound like I used to be underwater, and there have been no dropouts from the AI being overwhelmed.
Whereas recording, I deliberately stopped speaking to see how the brand new Anker Thus AI chip dealt with background noise once I was silent, and the audio waveform was fully flat (as pictured above), detecting no sound regardless of 80dB of noise!
These are simply one of the best earbuds I’ve used for cellphone calls in years. Jabra was my earlier champ, together with AirPods, Technics AZ100, and a pair others, however nothing has come near attaining precisely what Anker Soundcore has.
The Anker Thus AI chip powers some very helpful options and upgrades
(Picture credit score: @tshakaarmstrong)
The Anker Thus AI chip permits extra than simply what I consider to be market-leading name high quality. The Professional Max’s case is Bluetooth-enabled and connects on to your cellphone, letting you utilize it as a microphone and speaker for translating conversations. I used this performance just a few instances, and it really works effectively.
The AI Be aware Taker characteristic is de facto good! It really works very like Otter AI or Zoom name transcription, in that it acknowledges particular person audio system and does so effectively (see picture beneath). The one time it will get confused about who’s talking is when folks communicate over one another.
(Picture credit score: @tshakaarmstrong)
The Anker Thus chip additionally permits extremely responsive voice instructions that management many features with out an web connection, like Sony and Samsung’s flagship earbuds (see above). The one factor I discovered a bit hit-or-miss was voice chat with the Soundcore private assistant, Anka.
You possibly can chat with it and ask it to do issues, however I discovered extra advanced “asks” to be a bit much less dependable than the wonderful offline voice instructions.
The remainder of the expertise: The highs and lows
(Picture credit score: @tshakaarmstrong)
Listening to the chaotic Jazz romp “Moanin’” carried out by Charles Mingus and crew, the Liberty 5 Professional Max did an admirable job of not turning probably the most chaotic moments of the music right into a pot of mashed potatoes, dealing with the chaotic combine higher than the venerable Sony WF-1000XM6.
The one space missing was the excessive frequencies within the pop and hip-hop genres. Listening to Jamiroquai’s “Starchild,” his vocals are clear, and whereas undoubtedly not buried within the combine, highs really feel a bit subdued.
Prime-end smoothness is a deal with when listening to varied genres of rock music. System of a Down’s “Toxicity” is pleasant, and nothing ever got here throughout even remotely sibilant.
You’re undoubtedly getting standard, low-end-emphasized tuning out of each Professionals, however due to options like HearID and their glorious alternative of sound EQ’ing choices, you actually can successfully tune the audio frequencies to your liking.
(Picture credit score: @tshakaarmstrong)
ANC can be noticeably improved. Mid-range noise, like voices within the background, and higher-frequency sounds, just like the clank of weight plates within the health club, are noticeably softened in comparison with the Liberty 5. With the improved ANC activated, LDAC HiRes enabled, and AI performance, I nonetheless discovered myself getting round 6 hours of battery with the ‘buds.
The one place I discovered noise controls missing at this value level was within the capability to shortly attenuate surprising loud noises, resembling dropping a weight or a pan, whereas in Transparency mode. My Powerbeats Match instantly mutes surprising loud noises, however the Liberty 5 Professional doesn’t reply quick sufficient.
A noteworthy improve
(Picture credit score: @tshakaarmstrong)
Whereas the ANC is improved however not a market chief, the microphones completely are actually, and that begs the query: Liberty 5 Professional Max or Sony WF-1000XM6? Market-leading lively noise canceling or market-leading name high quality?
For most individuals, the audio high quality when listening to music or films is shut sufficient that it isn’t a serious level of competition between the 2, however it’s very simple to suggest the Liberty 5 Professional collection to you as a result of they’re that good, and so they’re roughly $100 cheaper than Sony’s flagship. On this financial system, which means quite a bit!
Soundcore
Liberty 5 Professional Max
Report-setting silence and smarts!
The Anker Soundcore Liberty 5 Professional Max sounds nice, has a lot improved ANC over even the Liberty 5, and does some neat issues like Face-to-Face translation utilizing its case as a speaker and microphone. An excellent pair of earbuds for folks on the go!
Report-setting silence!
Anker’s Soundcore Liberty 5 Professional comes with record-setting background noise cancelling for calls, good offline voice controls and so many extra AI-enhanced options, due to the brand new Anker Thus AI Chip. Should you do not want the AI note-taking of the Professional mannequin, that is the one to check out and it is simple to suggest.
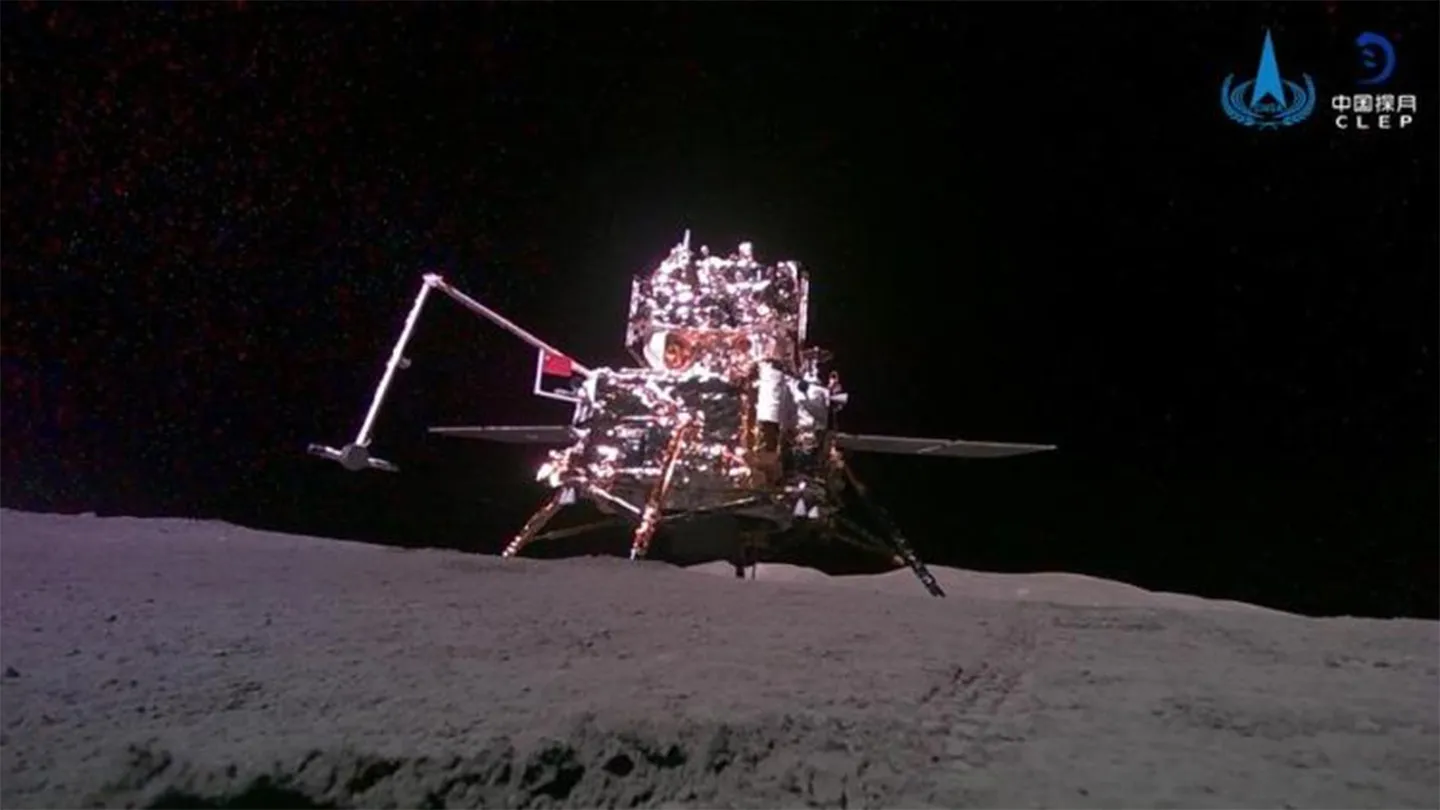
Bits of rock from the farside of the moon are including weight to a scientific rethink concerning the photo voltaic system’s adolescence.
The moon’s craters and basins attest to its historical past of being battered by incoming area rocks. Planetary scientists lengthy thought that these impacts spiked out of the blue round 3.9 billion years in the past, a interval known as the Late Heavy Bombardment.
“The lunar farside bombardment was not dominated by a cataclysmic spike,” says Wanfeng Zhang, an engineer on the Guangzhou Institute of Geochemistry in China. As a substitute, the moon might have skilled an extended interval of much less frequent impacts.
Zhang and colleagues analyzed 28 bits of affect soften, rocks that have been as soon as liquified within the warmth of a strike. The group measured the relative quantities of two isotopes of argon within the rocks up to now once they final melted and resolidified, a proxy for the time a crater shaped.
That approach supplied the unique proof for the Late Heavy Bombardment. Most of the moon rocks from NASA’s Apollo and the Soviet Union’s Luna missions within the Sixties and ’70s seem like round 3.9 billion years outdated, based mostly on the identical argon measurements.
A part of the issue with the Apollo and Luna samples is that all of them got here from part of the moon’s nearside that’s lined in big swimming pools of solidified lava known as mare. The mare make up the face of the long-lasting “man within the moon” (or rabbit, relying on the way you look). Earlier work instructed that the affect that created one in all these swimming pools, Mare Imbrium, unfold particles to date throughout the moon’s face that plenty of the prevailing samples originated with that one occasion — which occurs to have been about 3.92 billion years in the past.
“As such, the lunar bombardment historical past is severely masked,” Zhang says. “This drawback might be overcome by inspecting affect soften rocks from the lunar meteorites or samples [returned] from lunar farside.”
The Chang’e-6 samples come from a farside affect basin that can be named Apollo. They vary from 4.33 billion to 1.13 billion years outdated and present no signal of a cluster round 3.9 billion years in the past, Zhang and colleagues report. That implies a protracted interval of standard impacts, reasonably than one temporary cataclysm.
It’s robust to attract conclusions about affect cadence with information from just one area, says planetary scientist Simone Marchi of the Southwest Analysis Institute in Boulder, Colo. And it’s true that prior information are usually “plagued” by the affect of Mare Imbrium, and extra samples from extra components of the moon would assist, Marchi says.
Geochemist Mark Harrison of UCLA, an professional in argon relationship, thinks the rock ages measured look correct. Or not less than as correct as argon relationship might be; Harrison’s earlier work questioned whether or not argon can reliably date a single historic affect.
However he additionally questions whether or not these rocks truly got here from impacts or have been simply volcanic rock that cooled. The rocks on this research lack morphological options he would anticipate from affect melts, he says.
“The principle subject is, how do we all know this in any approach pertains to the bombardment historical past?” he says.
Nonetheless, if the discovering holds up, it provides to a rising refrain of researchers doubting the Late Heavy Bombardment, Harrison says. “The temper within the room has modified. The paradigm is shifting, or has shifted.”
Claude Code has turn out to be a family identify in agentic coding. You’ll be able to describe what you need, and it will probably create a challenge from scratch, edit recordsdata, run instructions, repair errors, and hook up with MCP servers, APIs, databases, and different instruments wanted to construct an end-to-end software.
Nevertheless, Claude Code can turn out to be costly, and it doesn’t essentially have the most effective coding-agent harness. A harness is the system across the AI mannequin that manages recordsdata, context, terminal instructions, instruments, permissions, and multi-step duties. The mannequin supplies the intelligence, however the harness determines how successfully it really works inside your improvement atmosphere.
On this article, I’ll cowl seven of the most effective Claude Code options for command-line interface (CLI) agentic coding. I’ve personally examined 5 of them, whereas researching the others extensively. Many present open-source entry, higher mannequin flexibility, customized instruments, local-model help, stronger harnesses, require fewer tokens, and include their very own ecosystems of integrations, providing larger management over the coding workflow.
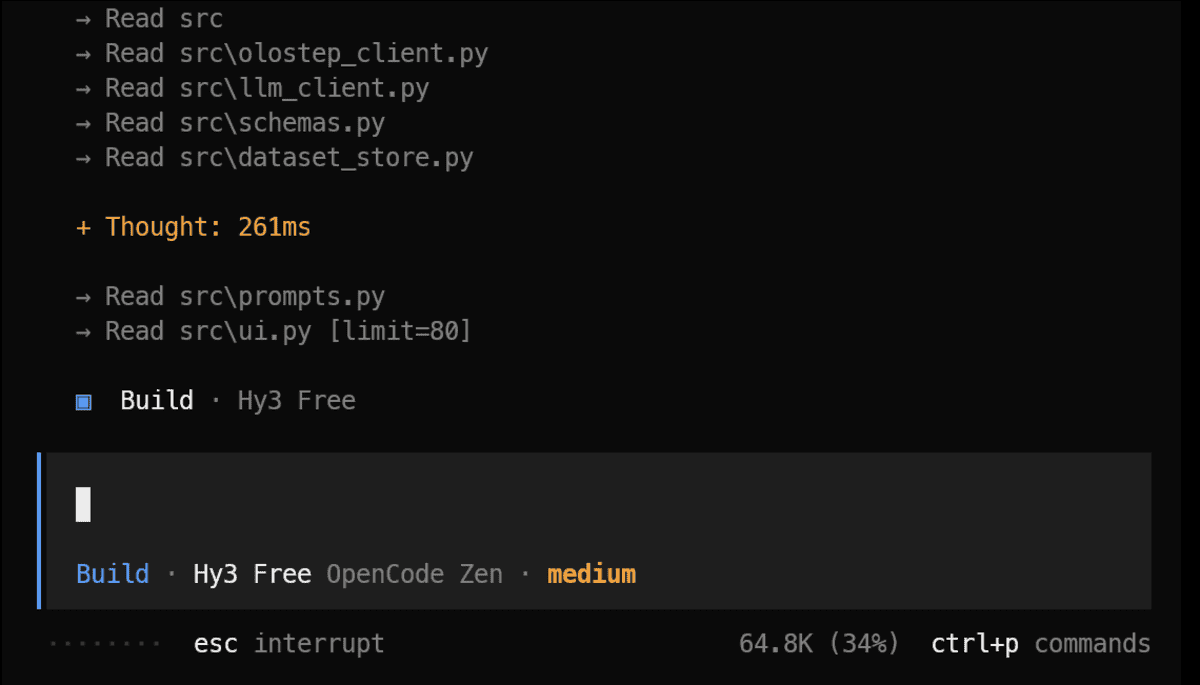
# 1. OpenCode
OpenCode is an open-source coding agent that works within the terminal, built-in improvement atmosphere (IDE), and desktop app. It could possibly perceive your codebase, edit recordsdata, run instructions, and assist with duties akin to fixing bugs, including options, and reviewing code. It additionally hundreds language servers mechanically, which helps it perceive completely different programming languages and supply extra correct adjustments.
What makes OpenCode higher than Claude Code for some builders is its flexibility. You aren’t locked into one mannequin supplier, and you’ll select the mannequin that works finest on your price range and process. You may also run a number of classes, create customized brokers for planning or reviewing code, and construct your personal workflows. It’s a sturdy selection for builders who need an open-source device with extra management over fashions, brokers, and integrations.
# 2. Pi
Pi is a light-weight, open-source coding-agent harness that runs within the terminal. It retains the core system easy and allows you to add the options you want by way of extensions, abilities, reusable prompts, themes, and challenge directions. It helps greater than 15 mannequin suppliers, together with Anthropic, OpenAI, Google, Kimi, OpenRouter, and Ollama, and you’ll even swap fashions throughout the identical session.
Pi could be higher than Claude Code for builders who need extra management over their coding agent. Its small system immediate can use fewer tokens, whereas its extensions allow you to add customized instruments, instructions, interfaces, reminiscence, sub-agents, and planning workflows. You may also return to an earlier message, create a brand new department, and proceed with out dropping the unique session. Nevertheless, some options aren’t included by default, so Pi is best suited to customers who get pleasure from constructing and customizing their very own setup.
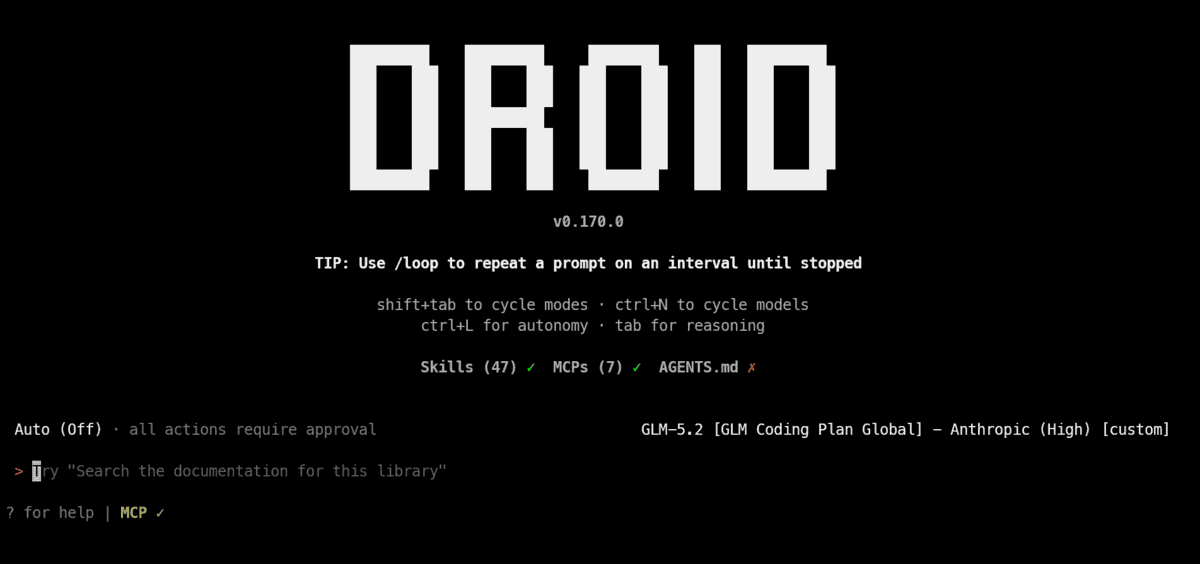
# 3. Manufacturing unit Droid
Manufacturing unit Droid is a coding agent that works within the terminal and IDE. You may give it a process in plain language, and it will probably discover the codebase, write code, run checks, assessment adjustments, and repair issues. It additionally helps saved classes, customized instructions, plugins, MCP servers, completely different AI fashions, and specialised sub-agents for duties akin to code assessment or safety checks.
Manufacturing unit Droid could be higher than Claude Code for groups that want automation and bigger improvement workflows. Its droid exec mode can run duties with out an interactive chat, making it helpful for scripts, batch jobs, and CI/CD pipelines. Manufacturing unit Missions may break a big challenge into smaller steps, assign them to completely different brokers, and test the ultimate work.
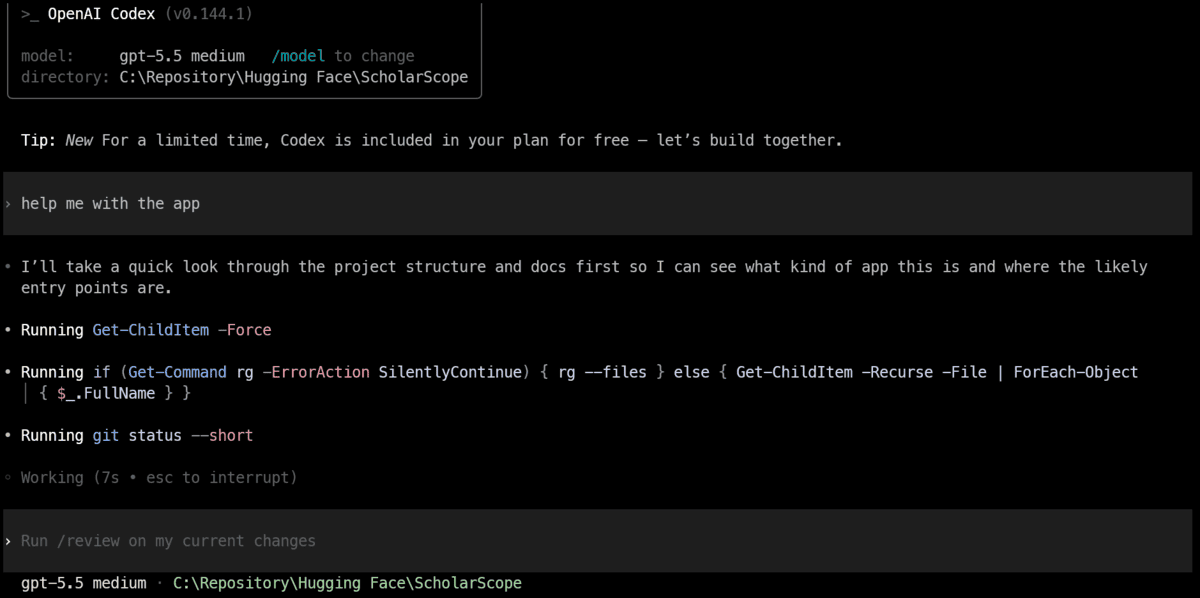
# 4. Codex CLI
Codex CLI is an open-source coding agent from OpenAI that runs inside your terminal. It could possibly discover your challenge, edit recordsdata, run instructions, check code, and clarify the adjustments it makes. It additionally helps MCP servers, challenge directions, photographs, completely different permission ranges, and a sandbox that limits what the agent can entry.
Codex CLI is among the finest Claude Code options for individuals who already use ChatGPT. In case your current ChatGPT subscription consists of Codex entry, the accessible utilization is often sufficient for regular each day coding duties. As a substitute of paying for an additional coding-agent subscription, I’d advocate attempting Codex first. It additionally helps automated duties and native AI fashions, making it helpful for each interactive coding and repeatable workflows.
# 5. Antigravity CLI
Antigravity CLI is Google’s terminal-based coding agent. It could possibly perceive your codebase, edit a number of recordsdata, run instructions, use instruments, and keep in mind your dialog historical past. It’s light-weight, constructed for keyboard-based workflows, and works effectively over distant SSH connections. It additionally helps abilities, hooks, plugins, sub-agents, and challenge directions.
Antigravity CLI could be higher than Claude Code once you need quicker execution and multi-agent workflows. It could possibly run a number of brokers on completely different elements of a giant process — akin to researching an issue whereas one other agent edits the code — with out blocking your terminal.
It additionally shares the identical agent harness and settings because the Antigravity desktop app, so you can begin a process within the terminal and proceed it within the visible interface. It’s a sturdy possibility for Gemini and Google Cloud customers who need a quick CLI for coding, automation, and huge tasks.
# 6. Cline
Cline is an open-source coding agent that works in your terminal and inside editors akin to VS Code and JetBrains. It could possibly learn and edit recordsdata, run terminal instructions, use a browser, set up dependencies, and check its personal adjustments. The CLI helps each interactive classes and headless execution, making it helpful for regular coding, scripts, code evaluations, and CI/CD workflows.
Cline could be higher than Claude Code for builders who need extra selection and management. You need to use your personal API key, select from many cloud suppliers, or run native fashions by way of Ollama and LM Studio. It additionally helps MCP instruments, challenge guidelines, abilities, parallel sub-agents, and a Kanban board for working a number of coding duties on the similar time.
# 7. Goose
Goose is an open-source AI agent that works by way of a CLI, desktop app, or API. It runs in your machine and might examine recordsdata, edit code, execute terminal instructions, run checks, and full multi-step improvement duties. It helps greater than 15 mannequin suppliers, together with OpenAI, Anthropic, Google, Ollama, OpenRouter, Azure, and Amazon Bedrock.
Goose could be higher than Claude Code for builders who need extra freedom over their fashions and instruments. You’ll be able to join it to greater than 70 MCP extensions, use native fashions, or use supported ChatGPT, Claude, and Gemini subscriptions. Additionally it is not restricted to coding — you should use it for analysis, writing, information evaluation, and automation.
# Closing Ideas
For builders who like open-source instruments and need extra management over fashions, I’d extremely advocate Pi and OpenCode. Each are versatile, help completely different suppliers, and work effectively with open-source or native fashions. Pi is best for individuals who get pleasure from customizing the complete agent setup, whereas OpenCode presents a extra full expertise out of the field.
If you have already got the $20 ChatGPT subscription, I’d all the time recommend attempting Codex CLI earlier than paying for an additional coding-agent subscription. The included utilization is often sufficient for regular each day coding. The opposite instruments are nonetheless nice selections, particularly for native AI coding, customized workflows, automation, and builders who need extra freedom over how their coding agent works.
Abid Ali Awan (@1abidaliawan) is an authorized information scientist skilled who loves constructing machine studying fashions. At the moment, he’s specializing in content material creation and writing technical blogs on machine studying and information science applied sciences. Abid holds a Grasp’s diploma in know-how administration and a bachelor’s diploma in telecommunication engineering. His imaginative and prescient is to construct an AI product utilizing a graph neural community for college kids combating psychological sickness.
For the higher a part of a decade, the enterprise has embraced a handy phantasm: that the cloud is borderless. We spoke of availability zones and areas as in the event that they have been summary logical constructs relatively than bodily buildings crammed with servers, cables and cooling followers.
The blueprint for cloud resilience has lengthy been constructed on a easy promise: geographic redundancy by way of availability zones. These bodily separate knowledge facilities — all situated throughout the similar area — have been designed to isolate failures. The speculation was stable: An outage in a single facility, whether or not from a software program glitch or a severed energy line, wouldn’t have an effect on the others.
However that mannequin is now being invalidated by a new class of systemic threats. Whether or not triggered by pure disasters, cascading grid failures or geopolitical battle, these large-scale occasions can overwhelm a complete area without delay
This regional mannequin additionally accommodates a flawed assumption: that restoration instruments might be obtainable when wanted. In actuality, a supplier’s administration infrastructure typically turns into a casualty of the very outage it’s meant to handle. The next recommendation for companies within the UAE was easy: migrate to a different area. For a regulated entity like a financial institution or hospital, knowledge residency mandates imply there isn’t any different area emigrate to, as knowledge wants to remain inside regional borders.
This state of affairs serves as a important simulation for U.S. companies in sectors like finance and healthcare, exposing a strategic blind spot many have but to handle. If a main cloud supplier in a key area is compromised, you are not simply going through a delay; you might be going through a complete cessation of enterprise with no authorized escape.
The price of the wait-and-see technique
The core problem in a regional outage shouldn’t be an absence of know-how, however the “fog of conflict.”
Most catastrophe restoration plans exist as static paperwork or runbooks in a digital folder. When a area goes offline, engineers are compelled to improvise. They need to construct new community paths, reconfigure safety tunnels and redirect visitors; all whereas the enterprise is dropping tens of millions per hour.
The continued disaster reveals that restoration in these situations takes days, not minutes. That’s as a result of the “roads” between completely different cloud suppliers hadn’t been constructed but. Trying to construct a bridge whereas the shoreline is on hearth is a recipe for failure.
The pillars of contemporary knowledge heart resilience
The definition of reliability should evolve. True resilience is now about vendor portability; how simply you may transfer amongst clouds. Networking is now not simply plumbing; it’s your insurance coverage coverage for enterprise continuity.
To face up to future volatility, enterprise design have to be upgraded in three particular methods:
Set up an escape hatch: Prebuild and encrypt connectivity between completely different cloud environments on the very begin. Ready for a disaster to hook up with a secondary supplier ensures failure.
Separate the “mind” from the blast radius: Host your monitoring and command heart in a very completely different geography out of your knowledge. This ensures you keep visibility when native infrastructure crumbles.
Automate your failover: A catastrophe restoration plan have to be executable code, not a PDF. Resilience ought to be triggered with a single command, eradicating improvisation and human error.
Multi-cloud networking makes this attainable. It creates a unified overlay that hyperlinks a main web site to a standby web site from a very completely different supplier. On this mannequin, if a supplier’s infrastructure fails, the community mechanically reroutes all visitors in beneath 60 seconds. For organizations with knowledge residency guidelines, this permits a split-compute technique; conserving knowledge native whereas shifting processing elsewhere. This strategy turns a catastrophic restoration right into a manageable, two-minute transition.
Incidents just like the disruption within the United Arab Emirates reveal exactly why cloud technique has moved from the IT basement to the boardroom. The strategic goal has subsequently shifted: It’s not sufficient to be “on the cloud”; enterprises have to be architected to function at a layer above it, making a unified presence insulated from any single supplier’s failure.
How resilient is your cloud infrastructure? Share your ideas at [email protected].