Mild, maker of the stripped-down Mild Telephones (beforehand really helpful), right this moment introduced the Mild Flip, a clamshell mannequin that swaps e-ink for matte OLED and will get a hinge, a keypad and (drum roll!) a digicam. As a lot as I liked my Mild Cellphone II, the sluggish and irritating e-ink display floor me down; with OLED, the principle tradeoff for responsiveness and readability will likely be shorter battery life.
The Flip runs LightOS, the corporate’s customized working system, on a 2.8-inch 480×640 show. The rear digicam has a 50-megapixel sensor and 12-megapixel output. Folded, it measures 110mm x 58mm x 19mm and weighs 160 grams. Inside is a MediaTek MT8873 chipset, 6GB of RAM, 128GB of storage, an 1,800 mAh battery, stereo audio system and twin noise-canceling mics. It helps 5G and 4G LTE by way of nano SIM or eSIM, Bluetooth 5.0, GPS, USB-C and a 3.5mm headphone jack. Software program consists of T9 predictive textual content, voice-to-text, audio messaging, instructions and a music participant, with a developer program now open for community-built instruments.
It is available in black, navy, purple, pink, yellow and light-weight grey, and can value $299 outright or “from $39 a month” on Mild’s service plan. It ships in April 2027.
The timing is notable. As Apple, Google, and others race to construct AI deeper into all the things, regardless of rising backlash from customers, Mild is making the case for a radically completely different future.
Mount Everest retains the title most individuals imply after they say “highest mountain.” Its summit is the best level on Earth measured above imply sea degree.
However sea degree shouldn’t be the one doable beginning line. If the query is which piece of land sits farthest from the centre of the planet, the reply strikes from the Himalayas to Ecuador.
That’s the helpful model of the declare. Chimborazo shouldn’t be larger than Everest within the on a regular basis altitude sense. It’s farther out from Earth’s centre as a result of the planet shouldn’t be an ideal sphere.
Everest wins above sea degree
Everest’s summit stands roughly 8,849 metres above imply sea degree. That’s the reason it’s the summit climbers, maps and nationwide surveys deal with as the best level on Earth. Sea degree is the sensible vertical reference used for elevation, aviation, mapping and climate.
Chimborazo is decrease by that commonplace. NOAA lists its summit at 6,268 metres above sea degree, greater than 2.5 kilometres under Everest. A climber standing on Everest is larger above the ocean’s reference floor and better within the ambiance.
So the Chimborazo truth doesn’t dethrone Everest. It adjustments the query.
As a substitute of asking which summit is highest above the ocean, ask which summit is farthest from Earth’s geometric centre. That could be a query concerning the form of the planet itself, not about native elevation.
Earth has an equatorial bulge
Earth rotates. As a result of it rotates, it’s barely flattened on the poles and wider across the equator. Geodesists name this form an oblate spheroid, although Earth’s actual form is even messier as a result of gravity varies and the floor is uneven.
The bulge is massive sufficient to matter. Factors close to the equator start farther from the planet’s centre than factors at larger latitudes. A mountain close to the equator due to this fact begins from a distinct geometric platform than a mountain within the Himalayas.
Chimborazo sits about one diploma south of the equator. Everest is almost 28 levels north. Everest rises larger above sea degree, however Chimborazo stands on a fatter a part of the planet.
NASA’s Earth Observatory makes the identical level in its description of Chimborazo and close by Tungurahua: Chimborazo’s summit is the purpose farthest from Earth’s centre as a result of the volcano lies close to the equatorial bulge.
The numbers are shut sufficient to really feel counterintuitive. NOAA says Chimborazo’s summit is over 2,072 metres farther from Earth’s centre than Everest’s peak. NASA’s Astronomy Image of the Day equally describes Chimborazo as greater than 2,000 metres farther from Earth’s centre than Everest.
In peculiar mountain phrases, Everest towers over Chimborazo. In planetary-radius phrases, Chimborazo wins.
“Closest to house” wants care
The phrase “closest to outer house” is memorable, nevertheless it wants a cautious studying.
If “closest to house” means highest altitude above imply sea degree, Everest stays the reply. It’s larger above the ocean floor, and its summit sits in thinner air than Chimborazo’s.
If “closest to house” means the strong floor farthest from Earth’s centre, Chimborazo is the reply. Its summit sits farther outward into the encompassing quantity of house as a result of Earth’s equatorial radius offers it a head begin.
Each statements could be true as a result of they use completely different reference factors.
Because of this the Chimborazo story is an efficient geography lesson reasonably than a easy trick truth. The reply adjustments when the measurement adjustments. “Highest above sea degree,” “tallest from base to summit,” and “farthest from Earth’s centre” are three completely different questions.
Everest wins the primary. Mauna Kea in Hawaii is usually given because the tallest from base to summit as a result of a lot of the volcano rises from the ocean ground. Chimborazo wins the third.
A report produced by Earth’s form
Chimborazo’s report additionally has a historic echo. The explanation scientists know Earth bulges on the equator is tied to the lengthy historical past of geodesy: the measurement of Earth’s form, gravity subject and floor.
The Library of Congress has written about Chimborazo as Earth’s farthest level from the centre, noting that the mountain’s summit is farther out as a result of Earth is an oblate spheroid and Chimborazo is situated close to the equator. Its account additionally factors again to the French Geodesic Mission, which labored in Ecuador within the 18th century to assist settle whether or not Earth was flattened on the poles or stretched there.
That query mattered as a result of it examined competing fashions of Earth’s determine. Newton’s physics predicted a flattened, rotating planet with a bulging equator. Measurements close to the equator and close to the poles helped verify that image.
There’s a neat symmetry within the consequence. The identical area used to measure Earth’s bulge accommodates the mountain that advantages from it most visibly in well-liked geography.
What the actual fact actually says
The Chimborazo-Everest comparability shouldn’t be primarily about mountains. It’s about reference frames.
Sea-level peak is essentially the most helpful measure for climbers, climate, aviation and peculiar maps. By that measure, Everest is the best level on Earth. Radial distance from Earth’s centre is a distinct measure, helpful for understanding the planet’s form. By that measure, Chimborazo’s summit is farther out.
The excellence is small in contrast with the dimensions of Earth however massive in contrast with human geography. A distinction of about two kilometres is sufficient to reverse what looks like an apparent reply.
That’s the reason the actual fact retains circulating. It takes probably the most acquainted statements in geography and reveals the hidden assumption inside it. Everest is highest, sure. However highest above what?
Reply “above sea degree,” and Everest retains its crown. Reply “from Earth’s centre,” and a volcano in Ecuador quietly takes it.
Entry the code to this tutorial and all different 500+ tutorials on PyImageSearch
Enter your e mail tackle under to study extra about PyImageSearch College (together with how one can obtain the supply code to this put up):
What’s included in PyImageSearch College?
Quick access to the code, datasets, and pre-trained fashions for all 500+ tutorials on the PyImageSearch weblog
Excessive-quality, nicely documented supply code with line-by-line explanations (making certain you realize precisely what the code is doing)
Jupyter Notebooks which might be pre-configured to run in Google Colab with a single click on
Run all code examples in your net browser — no dev setting configuration required!
Help for all main working methods (Home windows, macOS, Linux, and Raspbian)
Full entry to PyImageSearch College programs
Detailed video tutorials for each lesson
Certificates of Completion for all programs
New programs added each month! — keep on high of state-of-the-art traits in pc imaginative and prescient and deep studying
PyImageSearch College is admittedly the most effective Laptop Visions “Masters” Diploma that I want I had when beginning out. Having the ability to entry all of Adrian’s tutorials in a single listed web page and having the ability to begin enjoying round with the code with out going by way of the nightmare of organising all the pieces is simply wonderful. 10/10 would advocate.
Sanyam BhutaniMachine Studying Engineer and 2x Kaggle Grasp
Two questions preserve developing in renewal conferences this yr. Finance asks: “Are we nonetheless paying for instruments no person touches?” Engineering asks: “May we construct this ourselves now?” Till just lately, that second query often ended rapidly. Nevertheless, in 2026, it sits on the heart of the renewal. If the client can construct the seen function, what’s the vendor nonetheless being paid to personal?
Many distributors are usually not able to reply that.
AI has made inner instruments simpler to construct, however it has not eliminated the price of supporting, securing, documenting and defending them. A buyer can reproduce the dashboard, routing queue or approval type. That doesn’t switch the operational threat of operating it. A renewal now should show operational accountability: enforceable help, safety and compliance proof on request, indemnification with actual greenback limits and a vendor that owns a failure as a substitute of handing it again. Distributors that can’t show they serve these duties are about to lose renewal conferences they used to win.
This doesn’t threaten enterprise software program broadly. It threatens one slice: the slender workflow instruments constructed round repeatable logic.
For 20 years, the discount for these instruments was easy. Customized software program prices an excessive amount of to construct, so paying for a subscription was the rational selection. That math constructed a protracted tail of mid-tier distributors promoting instruments no person loves and everyone renews: inner dashboards, ticket routing, approval kinds, onboarding checklists and light-weight compliance trackers.
They exist as a result of constructing them was once uneconomical. That is the situation AI simply eliminated.
“Low-cost to construct” is just not the identical as “low cost to belief.” In Stack Overflow’s 2025 Developer Survey, of greater than 49,000 builders, 46% stated they mistrust the accuracy of AI output. A generated software nonetheless carries the evaluate, testing and safety work a buyer was paying a vendor to soak up.
The query is just not whether or not a buyer can construct the software. It’s whether or not the client needs to personal every little thing that occurs after it’s constructed.
That’s the place renewal strain lands first. When a finance analyst can have an AI assistant generate a working software over a weekend, a $40 per-seat subscription doing the identical job turns into negotiable. When a compliance lead can arise an proof tracker in days, a governance, threat and compliance (GRC) vendor charging $80,000 per yr has to defend greater than options. SAP’s 2025 evaluation of expertise leaders discovered 68% of 140 CIO respondents planning vendor consolidation. Prospects are usually not solely slicing unused instruments, but in addition sorting distributors into two piles: those that cut back enterprise threat and people who solely add one other bill.
Massive platform distributors are higher positioned as a result of their contracts usually embody help, integration, compliance proof and safety commitments.
What a buyer indicators with them is just not a function set however operational accountability, help, proof and the legal responsibility construction across the product. AI can generate a function. It can not generate the entity that’s contractually on the hook when that function fails.
I see this from the compliance facet each week. In public-sector safety work, Federal Danger and Authorization Administration Program and Cybersecurity Maturity Mannequin Certification documentation are as a lot merchandise because the code. A generated dashboard ships with a git historical past. It doesn’t ship with the documentation chain, audit historical past or anybody whose job is to defend it in an evaluation. Rebuilding the software internally doesn’t rebuild any of that. It simply strikes the accountability onto the client’s personal workers.
The price of being flawed is climbing, which is why clients can not deal with accountability as non-compulsory. Securities and Trade Fee guidelines require public firms to reveal a cloth cybersecurity incident inside 4 enterprise days of figuring out it’s materials.
The European Union AI Act‘s high-risk obligations are transferring by way of their very own phased deadlines. Cyber insurers preserve tightening the scope of what they are going to cowl. Each one among these shifts prices away from constructing software program and towards being answerable for it.
When a workflow fails, the client owns the consequence, whether or not the software was purchased, constructed or generated over a weekend. The exhausting half was by no means writing the code; it is being the get together legally on the hook when the code misbehaves.
So, stroll into 2026 renewals with a check. Type each vendor by asking two questions. What is that this vendor contractually accountable for when one thing fails? And what would land on us if we rebuilt this internally subsequent quarter?
Distributors who clear that bar earn the renewal. Distributors who don’t are operating an insurance coverage enterprise they’ve by no means priced as one, and a buyer with a generative AI license has now observed. That’s the hole between what clients ought to demand and what too many have been getting: a function set and an bill.
For 20 years, software program pricing answered one query: How a lot does it value to keep away from constructing this? The 2026 renewal query is sharper: How a lot threat comes again to us if we construct it ourselves?
Proudly owning the failure is the costly half. Distributors that carry that accountability will preserve their renewals. Distributors that promote solely a skinny workflow layer will spend the subsequent yr explaining why clients ought to preserve shopping for what they’ll now construct.
The U.S. Justice Division has seized greater than 1,000 web sites and blocked 1,970 domains used to stream FIFA World Cup 2026 matches with out authorization.
Legislation enforcement authorities recognized the seized domains utilizing leads supplied by U.S. authorities, FIFA (Fédération Internationale de Soccer Affiliation), the Movement Image Affiliation’s Alliance for Creativity and Leisure (ACE), and a number of leisure networks, together with beIN Media Group, NBCUniversal, Final Combating Championship (UFC), and Warner Bros.
These seizures are a part of a number of joint regulation enforcement actions primarily based on investigations by the Nationwide Mental Property Rights Coordination Heart (IPR Heart) and the U.S. Homeland Safety Investigations (HSI) Washington.
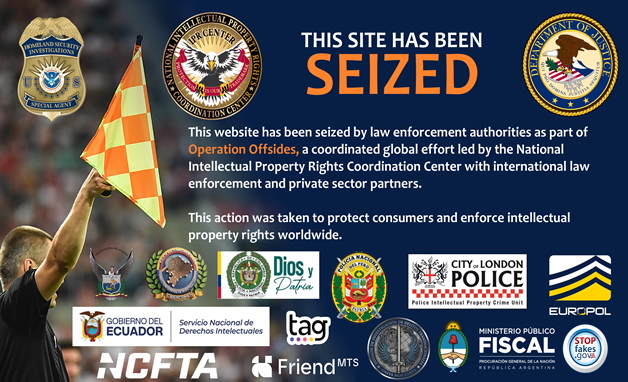
The Justice Division’s Prison Division seized over a thousand domains as a part of Operation Offsides, a joint regulation enforcement motion led by the IPR Heart in coordination with HSI Washington and involving 14 companions throughout 54 nations, together with almost 400 internet domains by the top of final month.
“Operation Offsides is a part of the Division’s ongoing effort to guard copyright whereas lowering the chance to American customers from the malicious software program embedded in lots of illicit streaming companies,” stated Assistant Lawyer Normal A. Tysen Duva.
“These streamers not solely violate copyright legal guidelines but in addition expose viewers to potential threats — together with malware assaults and unsecure connections that may compromise private and monetary knowledge,” added HSI Particular Agent in Cost Eric Weindorf.
Banner displayed on seized websites (U.S. Justice Division)
In coordination with the Justice Division’s Worldwide Laptop Hacking and Mental Property program, regulation enforcement authorities additionally carried out “Operation Purple Card,” blocking lots of of unlawful streaming websites in Argentina, Ecuador, Peru, Brazil, the Dominican Republic, and Colombia.
A second part of Operation Purple Card launched July 10 in Colombia additionally led to the arrest of 4 members of the Los Ciberinfiltrados cybercriminal group, charged with illegally accessing telecommunications programs and promoting pirated streaming content material since a minimum of 2024.
“The unauthorized broadcast of World Cup matches violates mental property rights and fuels legal organizations,” famous IPR Heart director Ivan J. Arvelo. “By way of Operation Offsides and powerful partnerships with regulation enforcement and the non-public sector, we recognized and seized lots of of domains, disrupting those that steal and distribute copyrighted content material.”
The announcement comes after the FBI’s warning in Might that faux web sites impersonating FIFA forward of the 2026 World Cup have been promoting faux tickets and hospitality packages, stealing private and monetary data, and pushing different scams and fraud makes an attempt associated to the occasion.
In June, Mexican authorities additionally shut down 44 domains linked to the unlawful PirloTV streaming platform and a serious sports activities piracy ring. Collectively, these domains generated over 950 million visits yearly, together with round 230 million visits from Mexico alone.
Safety groups log 54% of profitable assaults and alert on simply 14%. The remainder transfer by means of your surroundings unseen.
The Picus whitepaper exhibits how breach and assault simulation assessments your SIEM and EDR guidelines so threats cease slipping by detection.
Breakthroughs, discoveries, and DIY suggestions despatched six days every week.
By signing up, you verify you’re 16+, will obtain newsletters and promotional content material and comply with our Phrases of Use and acknowledge the info practices in our Privateness Coverage. You could unsubscribe at any time.
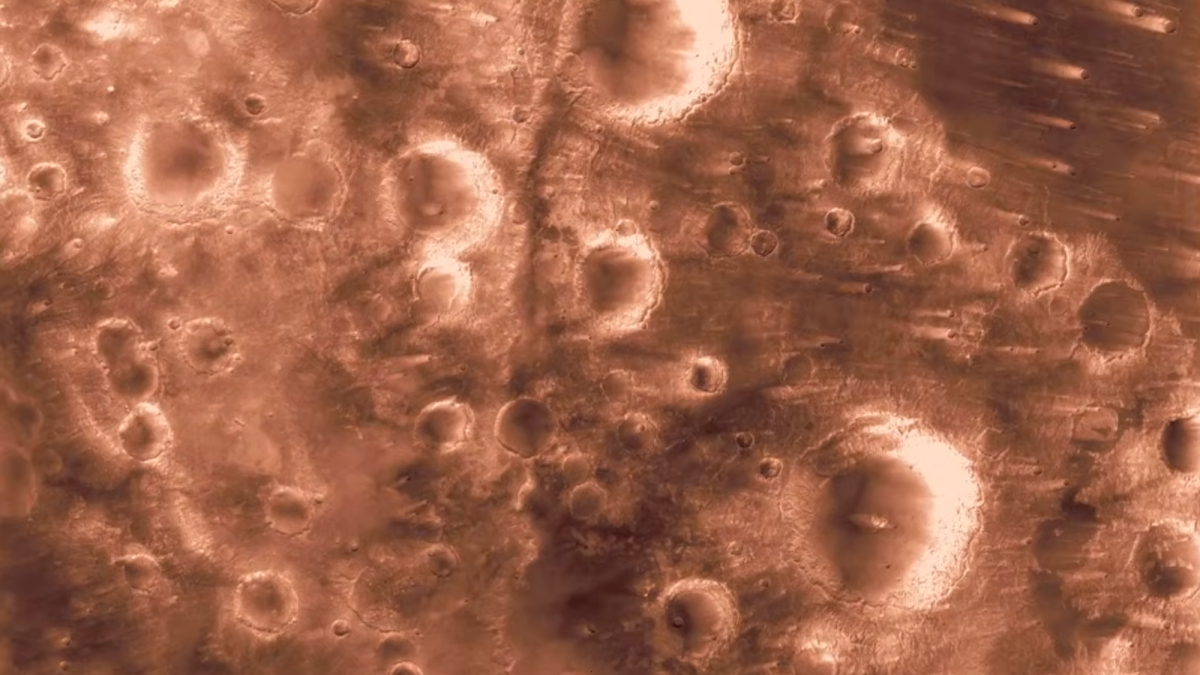
NASA’s asteroid-hunting Psyche spacecraft just lately wanted a bit of gravitational help from Mars to maintain rushing in direction of its supposed goal, nevertheless it didn’t depart the Pink Planet empty-handed. Whereas testing its numerous analysis devices forward of utilizing them on the distant, metal-rich area rock 16 Psyche in 2029, the spacecraft snapped a journey album’s price of flyby pictures with its pair of an identical cameras.
NASA has launched a compilation of the pictures taken throughout Psyche’s monthlong slingshot path in Might. And in contrast to the skinny crescent vantage level seen earlier, the beautiful close-ups showcase the windswept floor, huge craters, and even the photo voltaic polar ice cap on Earth’s closest planetary neighbor.
“The imager carried out brilliantly, delivering some not often seen views of the Pink Planet,” Jim Bell, Psyche’s imager instrument lead at Arizona State College, mentioned in a press release.
Psyche Captures Gorgeous Timelapse Video of Its Mars Encounter
Along with the images themselves, the staff efficiently examined Psyche’s digicam calibrations and scattered gentle sensitivity. These trial runs additionally included highlighting Martian moons Phobos and Deimos—a course of that might be repeated on the asteroid to hopefully find any potential orbital moonlets. In the meantime, mission specialists examined Psyche’s neutron and gamma-ray spectrometer. Planetary our bodies and asteroids emit neutrons and gamma rays whereas absorbing waves of high-energy cosmic rays. Researchers can then use these waves to match with identified components to find out the article’s chemical make-up. At its closest flyby altitude of two,864 miles, Psyche remained too far-off to choose up any Martian gamma rays, however the staff hoped to presumably flag neutrons as they left the planet.
“Across the time of Mars’ closest strategy, the neutron spectrometer detected a count-rate enhancement near what we anticipated. It was very gratifying to see,” mentioned spectrometer science lead David Lawrence.
NASA’s Psyche Mission Simply Flew By Mars: Right here’s What We Realized
Then there may be Psyche’s magnetometer. The instrument will ultimately analyze the asteroid’s core, whose steel composition will reveal if it’s a rocky planet constructing block generally known as a planetesimal. Psyche’s magnetometer will nonetheless be a really useful gizmo earlier than it reaches its goal. It has been working ever for the reason that spacecraft’s launch in 2023 in order that researchers can measure photo voltaic winds. Because it approached Mars, the gear relayed an enormous enhance in its magnetic subject that aligned with an space of the planet that absorbs probably the most photo voltaic wind generally known as the bow shock area.
“We didn’t anticipate massive discoveries, given how extensively the planet has been studied, however we did complement Mars science with the info we collected via Psyche’s distinctive perspective,” mentioned Lindy Elkins-Tanton, Psyche’s principal investigator on the College of California, Berkeley.
With Mars within the rear view mirror, Psyche is now persevering with alongside its 2.2-billion-mile journey to its diminutive asteroid, with much more work to do.Subsequent up is restarting its solar-electric propulsion system to provide sustained thrust, which specialists anticipate to deal with later within the 12 months.
I’ve written a number of posts about utilizing Claude or ChatGPT to generate Prolog or Lean code to unravel a chess puzzle. I didn’t assume Grok can be as much as the duty, although I didn’t strive it. I’ve heard good issues about Grok 4.5, so I gave it a shot. It did nice.
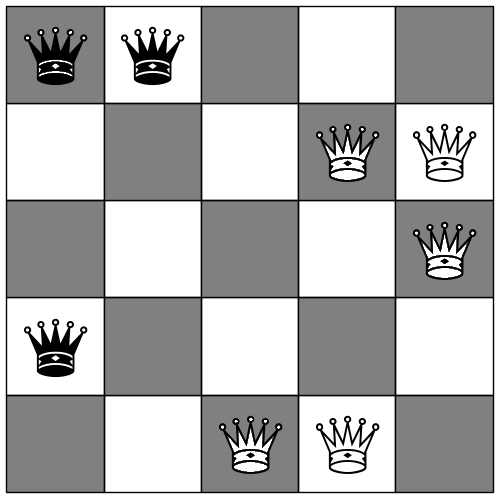
Right here’s the issue, a variation on the n-queens downside formulated by Martin Gardner.
Are you able to place 5 white queens and three black queens on a 5 × 5 board in order that no queen of 1 colour assaults a queen of one other colour?
Right here’s the immediate I’ve Grok 4.5.
Generate SWI Prolog code to unravel the next chess puzzle. On a 5 by 5 chessboard, place 5 white queens and three black queens in order that no queen is attacking a queen of the opposite colour. Have the code enumerate all options.
The code ran appropriately, giving all eight options.
I then requested Grok
Now generate Lean 4 code to unravel the identical puzzle.
The code didn’t run on the primary or second makes an attempt however ran appropriately on the third iteration. That’s higher than I’ve seen earlier than. It’s not an apples-to-apples comparability, but it surely has normally taken many iterations with Claude earlier than Lean code would run.
Options
There are eight options, every being a flip or a rotation of 1 elementary answer. Right here’s a consultant.
SWI Prolog code
:- use_module(library(clpfd)).

%% Enumerate all methods to put 5 white queens and three black queens
%% on a 5x5 board in order that no queen assaults a queen of the alternative color.
%% Similar-colour queens are allowed to assault one another.
%%
%% Positions are numbered 1..25 in row-major order:
%%   1  2  3  4  5
%%   6  7  8  9 10
%%  11 12 13 14 15
%%  16 17 18 19 20
%%  21 22 23 24 25

clear up :-
    answer(Whites, Blacks),
    print_solution(Whites, Blacks),
    fail.
clear up :-
    writeln('No extra options.').

answer(Whites, Blacks) :-
    size(Whites, 5),
    size(Blacks, 3),
    append(Whites, Blacks, All),
    All ins 1..25,
    all_distinct(All),
    % canonical order so every set of positions is generated as soon as
    Whites = [W1,W2,W3,W4,W5],
    W1 #< W2, W2 #< W3, W3 #< W4, W4 #< W5,
    Blacks = [B1,B2,B3],
    B1 #< B2, B2 #< B3, % each black is secure from each white maplist(safe_from_all(Whites), Blacks), label(All). safe_from_all(Whites, Black) :- maplist(no_attack(Black), Whites). %% Two queens do *not* assault one another. no_attack(P, Q) :- R1 #= (P-1) div 5 + 1, C1 #= (P-1) mod 5 + 1, R2 #= (Q-1) div 5 + 1, C2 #= (Q-1) mod 5 + 1, R1 #= R2, % completely different row C1 #= C2, % completely different column abs(R1-R2) #= abs(C1-C2). % completely different diagonal print_solution(Whites, Blacks) :- format('Whites: ~w~n', [Whites]), format('Blacks: ~w~n', [Blacks]), forall(between(1, 5, R), ( forall(between(1, 5, C), ( Pos is (R-1)*5 + C, ( memberchk(Pos, Whites) -> write('W ')
                      ; memberchk(Pos, Blacks) -> write('B ')
                      ; write('. ')
                      )
                    )),
             nl )),
    nl.
Lean 4 code
-- Lean 4 answer for the 5×5 black-and-white queens puzzle.
-- 5 white queens + 3 black queens; no opposite-colour assaults.

def absDiff (a b : Nat) : Nat :=
  if a ≥ b then a - b else b - a

def assaults (p q : Nat × Nat) : Bool :=
  p.1 == q.1 || p.2 == q.2 || absDiff p.1 q.1 == absDiff p.2 q.2

/-- All 25 squares (0-based, row-major). -/
def allPositions : Checklist (Nat × Nat) :=
  (Checklist.vary 5).flatMap enjoyable r =>
    (Checklist.vary 5).map enjoyable c => (r, c)

/-- Mixtures of size precisely `ok` (order-preserving). -/
def mixtures {α : Kind} : Nat → Checklist α → Checklist (Checklist α)
  | 0,     _      => [[]]
  | _,     []     => []
  | ok + 1, x::ys  =>
      (mixtures ok ys).map (enjoyable zs => x :: zs) ++
      mixtures (ok + 1) ys

def isAttackedBy (pos : Nat × Nat) (queens : Checklist (Nat × Nat)) : Bool :=
  queens.any (enjoyable q => assaults q pos)

/-- Each answer as a pair (white squares, black squares). -/
def clear up : Checklist (Checklist (Nat × Nat) × Checklist (Nat × Nat)) :=
  (mixtures 3 allPositions).foldl (enjoyable acc blacks =>
    let forbidden := allPositions.filter enjoyable p =>
      blacks.comprises p || isAttackedBy p blacks
    let out there := allPositions.filter enjoyable p =>
      !(forbidden.comprises p)
    acc ++ (mixtures 5 out there).map enjoyable whites => (whites, blacks)
  ) []

/-- Fairly-print one board. -/
def printBoard (whites blacks : Checklist (Nat × Nat)) : IO Unit := do
  for r in Checklist.vary 5 do
    let mut row := ""
    for c in Checklist.vary 5 do
      let p := (r, c)
      row := row ++
        (if whites.comprises p then "W "
         else if blacks.comprises p then "B "
         else ". ")
    IO.println row
  IO.println ""

/-- Enumerate and show each answer. -/
def fundamental : IO Unit := do
  let sols := clear up
  IO.println s!"Discovered {sols.size} options.n"
  for p in (Checklist.vary sols.size).zip sols do
    let i := p.1
    let (whites, blacks) := p.2
    IO.println s!"Answer {i + 1}:"
    printBoard whites blacks

#eval fundamental
Token serves as the basic unit of computation in trendy autoregressive fashions, and era size immediately influences each inference price and reasoning efficiency. Regardless of its significance, present approaches lack fine-grained size modeling, working primarily on the coarse-grained sequence degree. On this paper, we introduce the Size Worth Mannequin (LenVM), a token-level framework that fashions the remaining era size at every decoding step. By formulating size modeling as a price estimation drawback and assigning a continuing unfavourable reward to every generated token, LenVM predicts a bounded, discounted return that serves as a monotone proxy for the remaining era horizon. This formulation yields supervision that’s annotation-free, dense, unbiased, and scalable. Experiments on LLMs and VLMs show that LenVM offers a extremely efficient sign at inference time. On the LIFEBench actual size matching activity, making use of LenVM to a 7B mannequin improves the size rating from 30.9 to 64.8, considerably outperforming frontier closed-source fashions. Moreover, LenVM allows steady management over the commerce off between efficiency and effectivity. On GSM8K at a price range of 200 tokens, LenVM maintains 63 p.c accuracy in comparison with 6 p.c for token price range baseline. It additionally precisely predicts complete era size from the immediate boundary. Lastly, LenVM’s token-level values supply an interpretable view of era dynamics, revealing how particular tokens shift reasoning towards shorter or longer regimes. Outcomes show that LenVM helps a broad vary of functions, together with size management, prediction, and interpretation of era dynamics. They recommend that era size might be successfully modeled as a token-level worth sign, highlighting the potential of LenVM as a basic framework for size modeling and as a length-specific worth sign that might help future RL coaching.
If you’re working AI workloads on Azure, you will have in all probability realized the exhausting approach that the mistaken storage alternative can depart a rack of very costly GPUs sitting idle, ready for knowledge. On this session through the Microsoft Azure Infra Summit 2026, Wolfgang de Salvador and Reena Shah from the Azure Storage workforce walked by way of how Azure Managed Lustre and Azure Information map to the distinct levels of the AI pipeline, and why selecting the correct file system per stage is without doubt one of the highest leverage selections you’ll make.
📺 Watch the session:
You in all probability didn’t get into IT to babysit checkpoint writes or debug Hugging Face egress payments at 2 a.m. However that’s precisely the type of work that lands in your plate when storage is just not matched to the workload. Right here is why MAIS28 issues for the IT professionals, platform engineers, and Azure architects within the room:
GPU time is the most costly compute you’ll ever purchase. Sluggish knowledge loading and sluggish checkpoints flip that into burned money.
AI workloads aren’t one workload. Information prep, coaching, fine-tuning, and inferencing every have a unique storage profile.
Cloud-native AI on AKS and Azure Container Apps lives or dies on the ReadWriteMany expertise. If mannequin loading is sluggish or shared mannequin caches don’t exist, each chilly begin re-downloads tons of of gigabytes.
Storage selections ripple into safety and compliance. Encryption in transit, redundancy, and snapshots aren’t optionally available in 2026.
In brief, this session is for anybody who has to reply the query, “What persistent quantity ought to we use for this AI workload?” and desires a defensible reply.
Wolfgang opened with the storage profile of each stage of an AI workflow. Information preparation wants tons of of petabytes at the very best TCO (suppose Azure Blob Storage because the sturdy core). Coaching and fine-tuning want excessive throughput so GPUs keep fed throughout knowledge loading and so checkpoint writes full quick. Inferencing wants quick mannequin masses, low-latency KV cache, and grounded knowledge for RAG. One filesystem doesn’t match all of these directly, and making an attempt to make it match is the place groups overspend.
Azure’s reply is a tiered, file-based portfolio that traces up with these levels:
Azure Managed Lustre (AMLFS) is a totally managed, accelerator-tier filesystem. It scales to 25 PB of capability and as much as 512 GB/s of throughput, integrates with Azure Blob Storage because the sturdy core, and exposes a typical Lustre shopper plus a CSI driver for AKS.
Azure Information is the pure ReadWriteMany alternative for cloud-native AI on AKS and Azure Container Apps. It tops out at 256 TB of capability and 10.4 GB/s of throughput, gives LRS and ZRS redundancy with snapshots and comfortable delete, and ships with a 99.99% SLA.
Azure Blob Storage sits beneath each of those as a budget, sturdy core for knowledge prep and long-term retention.
The psychological mannequin the audio system used is “accelerator and core”. Blob is the core, sturdy and economical. AMLFS is the accelerator for coaching. Azure Information is the accelerator for inferencing and shared state. Choose the correct pair for the stage you’re working.
For coaching, Wolfgang confirmed the demo most people got here to see: a 32 x H100 ND H100 v5 AKS cluster deployed from the Azure AI Infrastructure repository, working a 30B-parameter GPT-3 coaching job backed by AMLFS. Two issues matter right here.
First, AMLFS absorbs checkpoint write bursts. When 32 H100s flush state on the similar time, you want a filesystem that may take the punch with out stalling. AMLFS does, which retains GPU utilization drops brief and contained.
Second, the AMLFS Lustre CSI driver for AKS helps each static and dynamic provisioning with availability-zone placement, and there are 5 SKU tiers from MLFS20 (least expensive by capability) to MLFS500 (least expensive by bandwidth). Meaning you’ll be able to choose a cost-performance level that matches your coaching funds as a substitute of shopping for the highest SKU and hoping for the very best.
For inferencing, Reena’s half of the session was simply as sensible. 5 causes Azure Information suits AKS ReadWriteMany workloads:
Commonplace Kubernetes RWM quantity over NFS or SMB.
256 TB capability ceiling and as much as 10.4 GB/s of throughput per share.
LRS or ZRS redundancy with snapshots and comfortable delete for defense.
99.99% SLA so it exhibits up in your availability math.
Native help throughout AKS and Azure Container Apps, together with serverless GPU.
The headline characteristic is Azure Information Provisioned v2. Within the outdated mannequin, IOPS and throughput have been a perform of how a lot capability you provisioned, which is mistaken for AI shapes that want small capability however very excessive IOPS and bandwidth. Provisioned v2 splits capability, IOPS, and throughput into three unbiased knobs you’ll be able to dial with out downtime or remount. That alone modifications the economics for lots of inferencing patterns.
The opposite huge inferencing characteristic is NFS v4.1 encryption in transit, delivered with the az-nfs utility and stunnel. You get AES-GCM TLS safety on the wire, with no Kerberos and no Energetic Listing wanted, and the appliance has no thought it’s taking place. Reena’s reside demo confirmed an AKS pod with an encrypted NFS mount, clear to the workload.
After which the sample that ties it collectively: the shared mannequin cache. Obtain the mannequin as soon as into Azure Information, mount it throughout each reproduction by way of ReadWriteMany. No per-pod chilly begin, no re-download from Hugging Face, no egress invoice. The demo used GPT-OSS 120B with VLLM on 32 x H100, and the sample scales all the way down to small fine-tuned fashions working on serverless GPU in Azure Container Apps.
The session closed with the Viton case examine. Viton is a Paris-based style AI startup. Their image-generation platform runs on Azure Container Apps serverless GPU, with Azure Service Bus for job routing and Azure Information NFS because the shared mannequin retailer. Employees pull jobs, mount the shared mannequin cache, generate the picture, and scale to zero when the queue drains. The economics solely work as a result of they don’t seem to be paying to re-download the mannequin on each chilly begin, and since they solely pay for GPU when there’s work to do.
The identical sample exhibits up throughout buyer situations:
Coaching a basis mannequin on AKS with AMLFS because the scratch tier and Blob because the sturdy archive.
Wonderful-tuning smaller fashions the place AMLFS checkpoints take in the write bursts and the ultimate artifact lands again in Blob.
Inferencing with VLLM on AKS the place Azure Information holds the mannequin weights as soon as and each reproduction reads from the identical RWM mount.
Serverless inferencing on Azure Container Apps with the identical shared mannequin cache sample, however with scale-to-zero economics.
Trustworthy tradeoff: Lustre is just not the correct filesystem for a 10-pod net app, and Azure Information is just not the correct filesystem for a 32-GPU coaching run. The entire level of the tiering is that you simply choose the correct one per stage. Don’t attempt to make one filesystem do all 4 jobs.
If you wish to put this into follow this week:
Go to the Azure AI Infrastructure repository on GitHub. Wolfgang’s demo cluster got here straight out of it, and you’ll spin up an AI-ready AKS cluster with GPU and InfiniBand operators in your personal dev/check subscription.
Set up the Azure Managed Lustre CSI driver on AKS if you’re working coaching or fine-tuning. Begin with a smaller MLFS SKU and dimension up.
Activate Azure Information Provisioned v2 on a brand new share, then dial capability, IOPS, and throughput independently to match your inferencing form.
Strive the shared mannequin cache sample. Choose one VLLM deployment, level it at an Azure Information RWM mount, and measure chilly begin time earlier than and after.
Most individuals’s Claude Code setup by no means will get previous day one. They run the installer, log in, kind a immediate, get one thing helpful again, and by no means contact a config file once more. Weeks later, classes begin dropping monitor of earlier choices, the identical permission immediate reveals up fifty occasions a day, and each lengthy job ends the identical method: a wall of context warnings and a dialog that needs to be deserted and restarted from scratch.
None of that may be a limitation of the mannequin. It is a limitation of the setup. Claude Code ships with smart defaults, however smart defaults and excessive efficiency are completely different bars, and the hole between them is sort of solely made up of a handful of information most inexperienced persons by no means open. This information closes that hole. It walks by means of the precise configuration, permissions, hooks, and command habits that separate a contemporary set up from a setup that holds up underneath actual, sustained agentic work, verified in opposition to Anthropic’s present documentation somewhat than assumed from an older model of the software.
# Putting in Claude Code the Proper Approach
Claude Code installs as a standalone command-line interface (CLI), and the present really useful path is the native installer somewhat than npm, although npm nonetheless works as a fallback:
# macOS, Linux, or WSL
curl -fsSL https://claude.ai/set up.sh | bash

# Home windows PowerShell
irm https://claude.ai/set up.ps1 | iex

# Or, through npm, if you happen to'd somewhat handle it together with your current Node toolchain
npm set up -g @anthropic-ai/claude-code
As soon as put in, cd into an precise mission listing earlier than working claude for the primary time. This issues greater than it sounds prefer it ought to: Claude Code scopes its mission reminiscence and settings to the listing you launch it from, so beginning it from your property folder or your desktop means it by no means picks up the correct context for something you are engaged on.
cd your-project-directory
claude
The primary run walks you thru authentication — both OAuth login with a Claude subscription (Professional, Max, or Crew) or an software programming interface (API) key tied to a Console account. Past the terminal, Claude Code can also be accessible by means of a VS Code extension, a JetBrains plugin, a desktop app, and a web-based model at claude.ai for classes you wish to choose up from a browser somewhat than a terminal. All of them learn from the identical underlying settings and mission information, so nothing you arrange within the terminal is wasted if you happen to later change to an built-in growth setting (IDE) panel.
With that achieved, the set up itself is the straightforward half. What truly determines whether or not Claude Code performs properly from right here is the set of three information most tutorials skip previous.
# The Three Recordsdata That Truly Run the Present
Claude Code reads configuration from two locations: your mission’s .claude/ listing (and a CLAUDE.md on the mission root), and a world ~/.claude/ listing that applies throughout each mission in your machine. Understanding what lives the place is the only largest lever on whether or not the software performs properly or drifts, in line with Anthropic’s personal documentation on the .claude listing construction.
CLAUDE.md is mission reminiscence — directions Claude reads at the beginning of each session in that repository: structure notes, construct and take a look at instructions, code model guidelines, and anything that may in any other case want re-explaining each single time. Run /init in a contemporary mission, and Claude Code will scan the codebase and generate a beginning CLAUDE.md for you, which you then refine with /reminiscence. Hold it lean. Anthropic’s steerage is to deal with it as a dwelling reference underneath roughly 2,500 tokens, and to push something lengthy or path-specific into .claude/guidelines/*.md information as a substitute, which could be scoped to load solely when Claude touches matching information.
settings.json, dwelling at .claude/settings.json for project-level config or ~/.claude/settings.json for private defaults, is the place permissions, hooks, setting variables, and mannequin defaults truly dwell. That is the file most inexperienced persons by no means open, and it is immediately liable for two of the most typical complaints concerning the software: fixed permission interruptions and Claude reaching for a costlier mannequin than a job truly wants.
Auto reminiscence is the newer, quieter layer: Claude can write and browse its personal working notes throughout a session with out you managing a file immediately, toggled with the autoMemoryEnabled setting or the CLAUDE_CODE_DISABLE_AUTO_MEMORY setting variable if you happen to’d somewhat hold reminiscence absolutely handbook and auditable by means of CLAUDE.md alone.
The sensible rule that ties these collectively, echoed throughout Anthropic’s documentation and impartial breakdowns of the config system alike, is that this: secure guidelines belong in CLAUDE.md, as a result of directions buried solely in dialog historical past get misplaced the second an extended session triggers automated compaction. If a rule must survive previous as we speak’s session, write it down.
# Setting Up Permissions and Hooks Earlier than Wanted
Claude Code runs in considered one of three permission modes, cycled with Shift+Tab:
Default, which asks earlier than each doubtlessly dangerous software name.
Auto-Settle for Edits, which lets file edits by means of with out prompting whereas nonetheless gating different instruments.
Plan Mode, which is read-only — no edits, no shell instructions — till you approve a plan. Plan Mode is value defaulting to in your first classes in an unfamiliar codebase, because it forces Claude to suggest earlier than it acts.
Past the interactive modes, settings.json permits you to write precise permission guidelines, so you are not manually approving the identical protected command fifty occasions a session:
What this does: something matching permit runs with out a immediate, something matching deny is blocked outright no matter what else matches, and something left unlisted falls again to asking you immediately. That deny-first ordering issues: a deny rule at all times wins even when a broader permit rule would in any other case cowl it, which is what makes it protected to grant pretty broad learn and test-running entry with out additionally opening the door to harmful instructions.
Hooks go a step additional than permission guidelines, since a rule can solely permit or block a name, whereas a hook can truly run one thing in response to 1. A PostToolUse hook that auto-formats each file Claude edits is likely one of the mostly really useful beginning factors:
What this does: each time Claude writes or edits a file, this hook fires afterward and runs Prettier in opposition to precisely the file that modified, utilizing the trail Claude Code passes in by means of the $CLAUDE_TOOL_INPUT_FILE_PATH setting variable. You cease manually reformatting after each edit, and your model guidelines apply persistently whether or not Claude wrote the file otherwise you did.
A PreToolUse hook can go additional and really block a harmful command earlier than it runs, which is a stronger assure than a permission rule alone since it could possibly examine the precise command textual content somewhat than simply matching a sample:
#!/usr/bin/env python3
# .claude/hooks/block-dangerous-bash.py
import json, re, sys

DANGEROUS_PATTERNS = [
    r'brms+.*-[a-z]*r[a-z]*f',
    r'sudos+rm',
    r'chmods+777',
    r'gits+pushs+--force.*primary',
]

input_data = json.load(sys.stdin)
if input_data.get('tool_name') == 'Bash':
    command = input_data.get('tool_input', {}).get('command', '')
    for sample in DANGEROUS_PATTERNS:
        if re.search(sample, command, re.IGNORECASE):
            print("BLOCKED: matches a harmful command sample", file=sys.stderr)
            sys.exit(2)
sys.exit(0)
What this does: Claude Code pipes the software name’s particulars to this script as JSON on stdin earlier than the command runs. If the bash software is about to execute one thing matching a recursive force-delete, a sudo rm, a world-writable chmod, or a compelled push to primary, the script prints a motive and exits with code 2, which Claude Code’s hook system treats as a tough block — stopping the command earlier than it ever runs. Register it in settings.json underneath PreToolUse with a Bash matcher, and this turns into a everlasting security internet somewhat than one thing it’s a must to keep in mind to verify for manually.
# The Instructions Price Studying First
Claude Code ships with greater than sixty built-in instructions as of this writing, and making an attempt to memorize all of them on day one is a waste of time. The desk beneath covers those that really change how a session performs, organized by what they’re for, pulled immediately from Claude Code’s official command reference.
Command
Class
What It Does
/init
Setup
Scans your codebase and generates a beginning CLAUDE.md
/reminiscence
Setup
Opens CLAUDE.md for modifying immediately
/clear
Context
Begins a contemporary dialog whereas conserving mission reminiscence
/compact [focus]
Context
Summarizes dialog historical past to unencumber context; accepts directions on what to protect
/context
Context
Reveals present context window utilization
/plan
Planning
Toggles Plan Mode; Claude proposes earlier than it acts, nothing executes till you approve
/diff
Evaluate
Opens an interactive diff of each change made this session
/code-review [–fix]
Evaluate
Checks the present diff for correctness bugs; --fix applies the findings
/security-review
Evaluate
Checks the present diff particularly for safety vulnerabilities
/evaluate
Evaluate
Provides a read-only evaluate of a GitHub pull request
/resume [session]
Navigation
Resumes a earlier dialog by identify or ID
/department [name] (alias /fork)
Navigation
Forks the present dialog into a brand new session
/rewind
Navigation
Rolls code and/or dialog again to an earlier checkpoint
/mannequin
Value & Efficiency
Switches the energetic mannequin mid-session with out dropping context
/effort
Value & Efficiency
Units reasoning depth (low by means of max) to match job complexity
/value
Value & Efficiency
Reveals token utilization and spend for API-key customers
/brokers
Delegation
Manages subagents — view, create, or invoke specialised brokers
/permissions
Configuration
Manages permission guidelines interactively
/hooks
Configuration
Manages hooks interactively
/physician
Diagnostics
Checks your set up for configuration issues
A helpful behavior for a newbie: construct fluency with /compact, /plan, and /diff first, since these three alone resolve nearly all of early frustration — classes that degrade from context bloat, edits that go additional than supposed, and never realizing precisely what modified. Every part else within the desk earns its place as soon as these three are muscle reminiscence.
# Constructing Your Personal /fact Command
This is a good word earlier than this part: /fact is not a command that ships with Claude Code. It would not seem within the official command reference, and it isn’t one thing I might verify throughout any present documentation or neighborhood information whereas researching this text. What’s genuinely helpful, although — and sure what prompted the thought — is a command that makes Claude verify its personal latest claims in opposition to the precise codebase earlier than you belief them and transfer on. That is an actual hole value closing, and it is an ideal instance of Claude Code’s customized command system, so this is the best way to construct it your self.
Customized instructions are outlined as abilities — a folder with a SKILL.md file. Create one at .claude/abilities/fact/SKILL.md:
---
description: Confirm Claude's most up-to-date claims and edits in opposition to the precise codebase
allowed-tools: Learn, Grep, Glob, Bash(git diff:*)
---

Re-examine the whole lot you simply informed me on this dialog in opposition to what
truly exists within the codebase proper now. Particularly:

1. For each file you declare to have edited, learn it once more and ensure the
   change is definitely current and matches what you described.
2. For each declare about current code (a perform's conduct, a config
   worth, an import, a dependency model), confirm it in opposition to the actual
   file somewhat than your reminiscence of studying it earlier within the session.
3. Run `git diff` and examine the precise diff in opposition to what you described
   altering.
4. Report again plainly: which claims checked out, which did not, and
   precisely what the discrepancy was for something that failed. Don't
   soften or hedge a discrepancy you discover, state it immediately.
What this does: the YAML frontmatter restricts this command to read-only instruments plus a scoped git diff, so working /fact can by no means itself modify something — which issues since a verification step that may additionally make adjustments is not a reliable verification step. The instruction physique is intentionally particular about what “confirm” means: re-reading precise information somewhat than trusting the mannequin’s personal prior description of them, and explicitly telling Claude to not soften a discrepancy if it finds one, since a self-check that is incentivized to sound reassuring is not truly checking something.
As soon as the file is saved, /fact turns into accessible in any session in that mission — the identical method some other customized command works — and it reveals up if you happen to kind / and begin filtering. Run it after Claude finishes a multi-step job, particularly one the place it touched a number of information or made claims about current code it hadn’t re-read lately, and earlier than you commit something primarily based on these claims. This is similar grounding precept behind self-correcting brokers usually: a verify is just value one thing if it is compelled to have a look at one thing outdoors its personal prior output, and pointing /fact on the precise information and the precise git diff is what makes it greater than a mannequin agreeing with itself.
# Utilizing Subagents and Parallel Work for Actual Pace Positive aspects
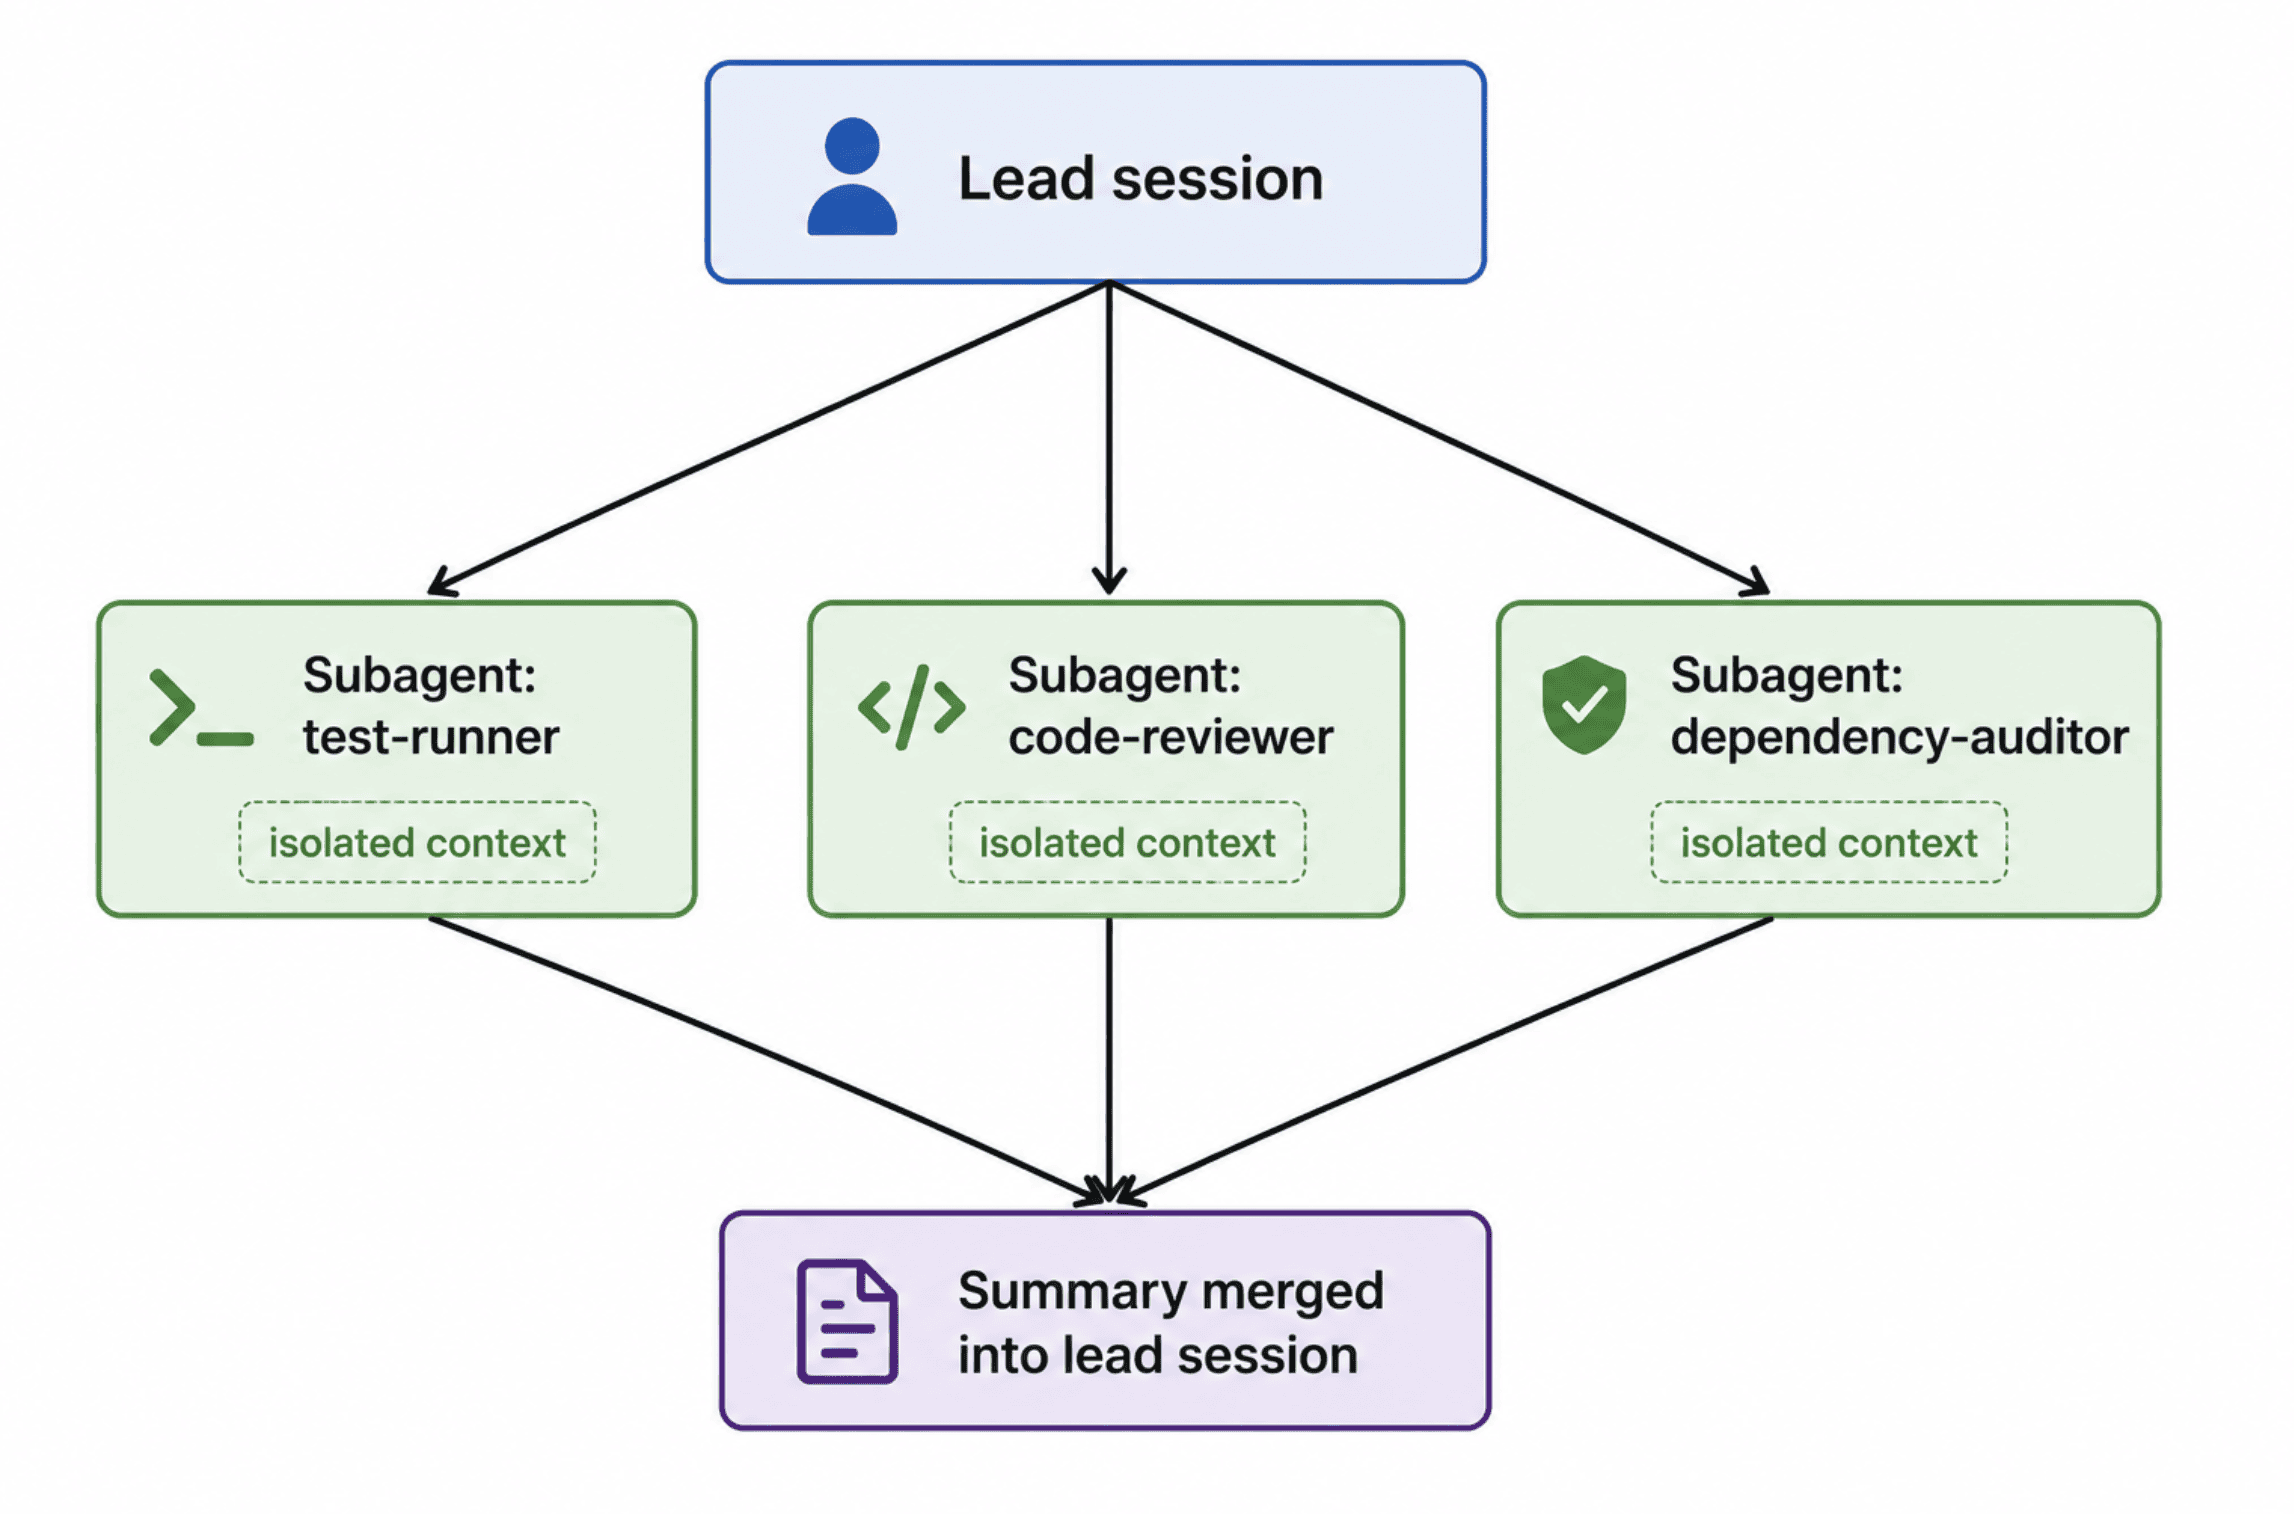
Every part to this point makes a single Claude Code session extra dependable. Subagents are what make it quicker on the sort of work that does not must occur sequentially. A subagent is a specialised occasion with its personal context window, its personal system immediate, and its personal software permissions, and Anthropic’s subagent documentation describes them as working remoted from the principle session, returning a abstract somewhat than dragging each intermediate file learn and power name again into your major dialog.
That isolation is the precise efficiency win. Giant codebase exploration, dependency audits, and test-writing are all verbose work that may in any other case eat closely into your primary session’s context finances. Delegate them to a subagent as a substitute, and solely the completed end result comes again.
# Inside a session, ask Claude to create a subagent
/brokers
Operating /brokers opens an interactive menu for creating, viewing, and managing subagents, or you’ll be able to outline one immediately as a file at .claude/brokers/.md with its personal frontmatter for mannequin choice and power entry, comparable in construction to the ability file above. A typical beginning sample is a narrowly scoped code-reviewer or test-runner subagent with read-only entry, so it could possibly examine and report with out ever with the ability to make the change it is reviewing — the identical separation-of-concerns thought coated within the hooks part above, simply utilized to delegation as a substitute of permissions.
For genuinely parallel work — modifying a number of unrelated components of a codebase without delay with out one change blocking one other — /batch and --worktree classes let a number of Claude Code cases work in remoted git worktrees concurrently, every with its personal working listing to allow them to’t step on one another’s adjustments. That is a extra superior sample than a newbie setup strictly wants on day one, but it surely’s value realizing it exists as soon as single-session work stops being the bottleneck.
# A Starter CLAUDE.md and settings.json You Can Truly Use
Pulling the whole lot above collectively, this is an inexpensive start line for a brand new mission. Save this as CLAUDE.md at your mission root:
# Mission Context

## Stack
- [Your language/framework here, e.g. Node.js, TypeScript, React]

## Instructions
- Check: `npm take a look at`
- Lint: `npm run lint`
- Dev server: `npm run dev`

## Conventions
- [Your code style rules, naming conventions, folder structure]

## Earlier than ending any job
- Run the take a look at suite and ensure it passes
- Run `/fact` if the duty concerned modifying multiple file
That is the complete basis from this text in two information: smart permissions that do not interrupt protected, repeated instructions, a tough block on the genuinely harmful ones, automated formatting on each edit, and a mission reminiscence file that factors Claude at your precise take a look at and lint instructions as a substitute of guessing at them. Commit each to your repository (leaving something containing secrets and techniques out, and utilizing .claude/settings.native.json for private overrides that should not be shared), and each teammate who clones the mission begins from the identical high-performance baseline as a substitute of rebuilding it from scratch.
# Wrapping Up
The distinction between a newbie’s Claude Code setup and a high-performance one is not a secret function or a hidden command; it is whether or not you spent twenty minutes on CLAUDE.md, settings.json, and one or two hooks earlier than diving into actual work, or whether or not you are still working on regardless of the installer gave you by default three weeks in. Every part on this information — the reminiscence information, the permission guidelines, the hooks, the instructions value studying first — exists to take away friction you’d in any other case hit repeatedly and by no means repair. Set it up as soon as, commit it to the repository, and each session after that begins from a stronger baseline than the one earlier than it.
Shittu Olumide is a software program engineer and technical author keen about leveraging cutting-edge applied sciences to craft compelling narratives, with a eager eye for element and a knack for simplifying advanced ideas. You can even discover Shittu on Twitter.