Home Blog Page 15

Apple iPhone Extremely: Foldable iPhone launch date, design, specs & rumors

0

[ad_1]

What is going to the folding iPhone seem like? How will it fold?

  • E book-like design with a vertical fold rumored
  • Meant to be an iPhone/iPad hybrid

Apple’s rumored iPhone Extremely is reportedly nearing mass manufacturing, with its design largely finalized. Right here’s what present leaks counsel about how the foldable iPhone will look and the way the hinge and show may match.

E book-style, iPad hybrid, design

A number of leaks level to a book-style foldable with a big, tablet-like inner show, fairly than a compact flip-phone design. The gadget is predicted to operate as a hybrid between an iPhone and an iPad.

This “passport-style” design will seem noticeably squarer than a conventional iPhone when closed. When unfolded, it’s rumored to resemble an iPad mini-like display with a 4:3 facet ratio, providing a extra expansive viewing expertise.

Analyst Ming-Chi Kuo reported in 2025 that Apple’s foldable will undertake a dual-display setup, with a powerful give attention to reaching a close to crease-free display when opened.

Different 2025 leaks, together with stories from Digital Chat Station on Weibo, additionally level to a vertical, book-style fold the place the left and proper sides shut collectively – just like gadgets just like the Google Pixel 9 Professional Fold and Samsung Galaxy Z Fold.

Dummy fashions shared by Sonny Dickson on X in April 2026, reveal this book-like kind issue.

Sonny Dickson

Extra dummy unit pictures from tech YouTuber Vadim Yuryev, additional reinforce this extensive, book-like “passport” design.

In December 2025, this 3D picture of the iPhone Extremely, based mostly on leaked CAD information, was created by a hobbyist and shared on MakerWorld (now eliminated), additionally aligning with these design expectations.

Nonetheless, different ideas have existed. In 2024, The Info reported that Apple had explored clamshell-style prototypes, the place the gadget folds top-to-bottom, just like conventional flip telephones.

This design course could already be influencing rivals. Our colleagues on TechAdvisor report that Samsung is creating a “Galaxy Z Fold 8 Large” with an identical 4:3 facet ratio, doubtlessly positioning it as a direct rival to Apple’s anticipated September 2026 launch.

How Apple is overcoming hinge design and crease discount challenges

Including a hinge to an iPhone introduces important engineering challenges that Apple has spent years making an attempt to resolve. Whereas rivals have launched a number of generations of foldables, Apple’s slower entry to the market is broadly attributed to its give attention to refining the hinge and delivering a extra seamless consumer expertise.

The most important technical problem is the seen and tactile crease the place the display folds. Apple has reportedly made this a precedence, aiming to minimise it to the purpose of being almost imperceptible.

Weibo leaker Prompt Digital claims the iPhone Extremely’s inner design will make it the most repairable folding cellphone in the marketplace, with elegant modular and stacked parts that decrease interconnects and ribbons.

Consequently, the hinge is predicted to be a defining characteristic of the iPhone Extremely, combining superior supplies and engineering to ship a smoother, extra sturdy folding expertise.

To keep up each thinness and sturdiness, Apple is reportedly testing high-end supplies for the hinge:

  • Titanium alloy (rumored for structural energy)
  • LiquidMetal, in response to Ming-Chi Kuo (March 2025), for improved sturdiness, higher display flatness, and diminished creasing.

In July 2025, Kuo reported that Apple had developed a way to cut back crease visibility utilizing steel assist plates to higher distribute and management bending stress. Apple could use this “laser-drilling steel plate expertise” fairly than standard etching to create a extra exact microstructure.

Apple additionally holds a number of patents for foldable mechanisms which, together with a number of rumored applied sciences, could also be used:

  • Variable Thickness Glass: A key a part of Apple’s method is claimed to contain variable thickness show glass, which is thinner on the fold level to cut back stress throughout repeated use. That is anticipated to work alongside an optically clear adhesive layer, designed to additional minimise pressure and assist forestall the seen crease that generally develops in foldable gadgets over time.
  • Stress-Lowering Adhesive: An optically clear adhesive designed to cut back pressure on the show throughout folding.
  • Extremely-Skinny Profile: Anticipated thickness of round 4.5mm unfolded and 9.5mm folded.
  • Inside Help: Metallic plates beneath the show to keep up a totally flat floor when opened.

In March 2026, stories prompt that Samsung Show – Apple’s major display provider – has developed a near-creaseless OLED panel, showcased at CES 2026 particularly to fulfill Apple’s requirements.

[ad_2]

The Galaxy Card Is Samsung’s Reply to the Apple Card

0

[ad_1]

“Playing cards are principally a commodity on the finish of the day; the way you differentiate them is de facto what makes the distinction,” Riley says. “That is actually the large deal right here—how you utilize your card.” Riley has a card for grocery buying and one for Amazon transactions; all of those steps assist him earn probably the most factors.

“One of many massive challenges right here on rewards is that very often, you go in well-intentioned and you aren’t getting the complete advantage of the rewards since you begin revolving on the product,” Riley says, which means cardmembers begin accumulating curiosity on the unpaid stability, with curiosity fees wiping out the worth earned by the rewards.

Riley factors to one of many failings of the Apple Card: Apple oversold it. It is slick, sure, nevertheless it by no means grew to become a mainstream challenger to the bank card business as a result of the common client sometimes has three or 4 playing cards per family: one for all of their purchases, one for emergencies, and one that may deal with journey.

Sara Rathner, a bank card professional at NerdWallet, echoed that sentiment. “The Apple Card is way from the iPhone when it comes to altering the world,” Rathner says. “It is tremendous; it is a cash-back card.” All of those playing cards exist to create model loyalty, she says. If in case you have a variety of factors with Hyatt, you are extra prone to ebook a keep at a Hyatt property in your subsequent journey. In the event you make many purchases with Samsung Pockets, that may incentivize you to get the Galaxy Card.

Rathner says the three p.c money reward for purchases utilizing the Samsung Pockets app is a extremely good fee. In the event you tap-to-pay at New York Metropolis’s subway turnstile with Samsung Pockets in your telephone, for instance, that is 3 p.c on each commute, and “that may be compelling.”

Whereas Rathner finds the Apple Card underwhelming, she does credit score Apple with innovating on sure options. For instance, Apple lets you see the rate of interest and credit score fee you’ll qualify for earlier than a credit score pull, one thing different bank cards are more and more providing. The app (and card) have a ravishing design, the bodily card is simple to activate with only a faucet on the iPhone, and money rewards are posted every day slightly than ready for a billing cycle.

“I believe if different playing cards wish to compete in that approach and likewise comply with go well with with these options, I believe that simply makes bank cards typically higher merchandise for shoppers,” Rathner says. “We’ll see how this resonates with individuals who have Samsung telephones.”

[ad_2]

ML-KEM vs Diffie-Hellman: The Showdown – IPsec Sequence, Half 3

[ad_1]

In Half 2 we put two contenders within the ring: classical Diffie-Hellman / X25519 (tiny, quick, quantum-doomed) and post-quantum ML-KEM-768 (quantum-safe, chunky, new). Now it’s time for the principle occasion. Let’s put them aspect by aspect from each angle that issues, after which reveal why the neatest transfer isn’t to crown a winner in any respect.

All the things right here you’ll reproduce your self within the hands-on lab in Half 4. These aren’t numbers I’m asking you to belief; they’re numbers you’ll measure.


Spherical 1: Dimension on the wire

That is the place the distinction jumps proper out:

X25519ML-KEM-512ML-KEM-768ML-KEM-1024
Public key32 B800 B1184 B1568 B
Response (ciphertext)32 B768 B1088 B1568 B
Shared secret32 B32 B32 B32 B
Suits in a single IKE message (≤1280 B)?✅ sure✅ sure❌ wants fragmentation❌ no

X25519’s 32-byte keys are adorably tiny. ML-KEM’s are 25–50× bigger, sufficiently big that ML-KEM-768 forces IKE fragmentation (splitting one logical message throughout a number of packets). Tuck that phrase away: fragmentation is the thread that runs by means of this complete pillar, and also you’ll see it with your personal eyes within the packet captures subsequent put up.


Spherical 2: Latency (spherical journeys)


ModeSpherical journeysMessages
X25519 solely2IKE_SA_INIT → IKE_AUTH
Hybrid X25519 + ML-KEM3IKE_SA_INIT → IKE_INTERMEDIATE → IKE_AUTH

Going hybrid provides one full spherical journey, measurable however small in follow (sometimes just a few milliseconds on a LAN). Since a handshake occurs as soon as per tunnel (with rekeying each few hours), that is nothing to lose sleep over.


Spherical 3: Compute value (the shock)

A standard fantasy: “post-quantum” means “painfully gradual.” For ML-KEM, the reverse is nearer to the reality. Its lattice operations are genuinely quick, in the identical ballpark as, and sometimes sooner than, an elliptic-curve scalar multiplication.

Tough per-operation value on trendy x86 (from revealed eBACS/SUPERCOP benchmarks, not measured in our lab):

OperationX25519ML-KEM-768
Key era~50–65k cycles~30k cycles
Derive shared secret / encapsulate~50–65k cycles~45k cycles
Decapsulaten/a~35k cycles

Add it up and the totals land in the identical vary. ML-KEM-768 shouldn’t be the bottleneck, not even shut. After we time the actual handshakes in Half 4, you’ll see the hybrid model prices about 1 ms greater than classical, and primarily all of that’s the additional community spherical journey, not the crypto.


Spherical 4: Safety

X25519ML-KEM-768
Classical safety~128-bit~192-bit
Quantum safety❌ damaged by Shor’s algorithm✅ no recognized quantum assault
StandardisedRFC 7748 (2016)FIPS 203 (2024)
Deployment maturityVery excessiveRising

And there’s the rub. X25519 is battle-tested however quantum-vulnerable. ML-KEM is quantum-safe however new and fewer field-tested. Every has precisely the weak spot the opposite doesn’t.


The decision: why not each?

Right here’s the punchline I hinted in Half 2. Neither contender clearly wins at present, so as a substitute of selecting a champion, we make them work collectively. A hybrid key trade runs each and combines their shared secrets and techniques into the ultimate session key. The end result:

  • If ML-KEM is damaged by a future quantum assault, X25519 nonetheless supplies classical safety.
  • If X25519 is damaged by a quantum pc, ML-KEM supplies quantum resistance.
  • An attacker should break each concurrently, which is believed to be infeasible.

You get quantum security with out betting every thing on a brand-new algorithm, all for the value of 1 additional spherical journey and ~2 KB per handshake.


The magic that makes it work: RFC 9370

So how can we really wire two key exchanges into one IKEv2 handshake? Enter RFC 9370 (A number of Key Exchanges in IKEv2, 2023). It defines a clear mechanism to run extra key exchanges on prime of the usual IKEv2 DH trade, every contributing keying materials to the ultimate keys.

The scheme is elegant:

  • X25519 stays the first trade, carried in the usual IKE_SA_INIT message: small and unchanged.
  • ML-KEM joins as an extra trade, using in a brand-new IKE_INTERMEDIATE spherical journey.
  • The ultimate session secret is derived from each shared secrets and techniques mixed.

And it’s backward appropriate: friends that don’t converse extra key exchanges merely fall again to the bottom DH. All people’s joyful. That is the sensible migration path NIST and most VPN distributors advocate: bolt PQC on with out redesigning the entire protocol.

In strongSwan config, the entire story is spelled out in a single proposal string: x25519-ke1_mlkem768

x25519 is the principle DH group in IKE_SA_INITke1_mlkem768 is the primary RFC 9370 extra key trade, using in IKE_INTERMEDIATE. Do not forget that string.


The handshake, step-by-step

Right here’s the entire hybrid dance, which we’re about to look at stay:

Initiator                                        Responder
    |                                                |
    |--- IKE_SA_INIT (KE[x25519], Ni) -------------> |
    |<-- IKE_SA_INIT (KE[x25519], Nr) -------------- |
    |                                                |
    |    X25519 shared secret derived                |
    |                                                |
    |--- IKE_INTERMEDIATE (mlkem768 pub key) ------> |   (~1250 B, fragmented)
    |<-- IKE_INTERMEDIATE (mlkem768 ciphertext) ---- |   (~1155 B)
    |                                                |
    |    ML-KEM shared secret mixed with          |
    |    X25519 secret → ultimate IKE SA keys           |
    |                                                |
    |    IKE SA ESTABLISHED                          |

See that imbalance from Half 2? The initiator sends the huge ML-KEM public key (~1184 B) and will get again the ciphertext (~1088 B): totally different sizes, reverse instructions, precisely as a result of a KEM splits the work. And that ~1250 B public-key message is exactly why fragmentation = sure is obligatory within the lab.


Sufficient concept: let’s run it

We’ve now acquired the complete image: why key trade is the pressing pillar, who the contenders are, how they evaluate, and why hybrid is the reply. Time to cease studying tables and begin making them.

In Half 4 we deliver up an actual hybrid tunnel, seize the packets, and run classical-vs-hybrid again to again, watching the additional spherical journey and the fragmentation seem in full element. Meet me there!

[ad_2]

China’s AI fashions have Trump’s AI world at warfare with itself

[ad_1]

It started as a result of nobody can agree on what to do about Kimi, a free, open supply mannequin that Chinese language AI firm Moonshot launched final week. It seems to rival the intelligence of fashions from OpenAI and Anthropic, that are very a lot not free. 

Kimi and different Chinese language fashions prefer it pose an actual drawback for Trump. They usually’re dividing the highest AI strategists in his orbit into factions. Each time a brand new good, free mannequin from China like Kimi will get launched, US firms see much less purpose to fork out cash to entry fashions from Anthropic or OpenAI. On condition that enthusiasm for these and different AI firms is driving an outsized share of financial development, China’s AI fashions create each financial and political issues for the president. They’re “a menace for an administration that actually doesn’t need extra financial dangerous information,” Anton Leicht, a fellow on the Carnegie Endowment, wrote on X. They’ve already rattled US shares

What’s Trump to do? First, contemplate that that is all taking place only a week after New York imposed the nation’s first state ban on new knowledge facilities. There’s rising mistrust of AI firms, and I think about a not-insignificant share of People would have little sympathy for OpenAI or Anthropic as they fend off cheaper rivals, and would say it’s not the federal government’s job to guard their pursuits.

On this level, they’d see a sliver of settlement (and actually only a sliver) with David Sacks, who on July 19 criticized high AI firms that “need the federal government to remove their open supply competitors.” He has additionally argued that Chinese language AI fashions have turn into widespread as a result of they arrive with fewer restrictions on how folks can use them (placing apart the built-in state censorship). 

Sacks, nevertheless, is out of a job. He now not has a proper function advising Trump, and his place that extra open AI is healthier has been largely changed within the administration by one which sees a bigger function for presidency intervention. The considering behind this view is that as a result of AI fashions have gotten sturdy sufficient to pose threats to nationwide safety, the federal government should management how they’re used. 

This place has fueled the brand new White Home overview course of that goals to vet AI fashions’ safety earlier than they’re launched. Dean Ball, a former Trump AI advisor who now works for OpenAI, criticized it over the weekend as a “de facto licensing regime for frontier AI.” Ball predicted Trump might remedy his Chinese language open supply drawback with a bit of soppy energy, maybe by making US firms afraid to make use of fashions like Kimi. That drew a response from Michael, who, with Secretary of Protection Pete Hegseth, has been the company’s principal liaison with AI firms. Michael referred to as Ball the AI trade’s “supreme village fool,” bristling on the suggestion that the federal government would quietly strong-arm firms somewhat than, as Michael put it, undergo “the democratic course of not some Deep State scheme.”

Overlooked of the dialog has been how a mannequin like Kimi bought so good within the first place. For a lot of the Biden administration and even the start of Trump’s second administration, holding China from getting high chips was a precedence. These export controls have loosened—Trump made the controversial resolution to permit Nvidia to promote extra chips to China, in trade for the US authorities taking a minimize—and the federal government has alleged that some chip smuggling has taken place. However China nonetheless has restricted computing energy, and it’s not clear what chips the corporate behind Kimi used to coach the mannequin. 

It’s attainable that the method concerned some distillation, a observe by which AI fashions are skilled on the outputs of present AI fashions. OpenAI and Anthropic have lengthy complained that Chinese language AI firms do that, and so they have requested authorities assist to place a cease to it. In April, they bought it, when the Trump administration introduced a sequence of efforts to curb the observe.  

However Kimi is on the market and free, and it’s almost pretty much as good because the Anthropic mannequin the US authorities deemed so highly effective that it was briefly shut down as a result of it threatened nationwide safety. The weekend’s sparring suggests many in Trump’s orbit see that as a wake-up name. However no one can agree on what for.

[ad_2]

Google’s newest Android 17 beta fixes Bluetooth complications and Gemini crashes

0

[ad_1]

What you might want to know


Google’s not losing any time after wrapping up Android 17 QPR1. The corporate has formally kicked off testing of Android 17 QPR2 Beta 1, providing Pixel customers and builders a primary take a look at the following quarterly replace anticipated to reach because the December 2026 Function Drop.

This launch doesn’t include any new user-facing options, however it does repair some annoying bugs which have plagued Pixel homeowners. In its official launch notes, Google says it has fastened a difficulty the place Bluetooth units may fail to reconnect after shedding pairing, with no indication there was an issue. There’s additionally a repair that stops media controls from flashing briefly on the lock display screen when waking a telephone, even when notifications for that app had been turned off.

[ad_2]

Pompeii’s survivors shine in a brand new documentary sequence

0

[ad_1]

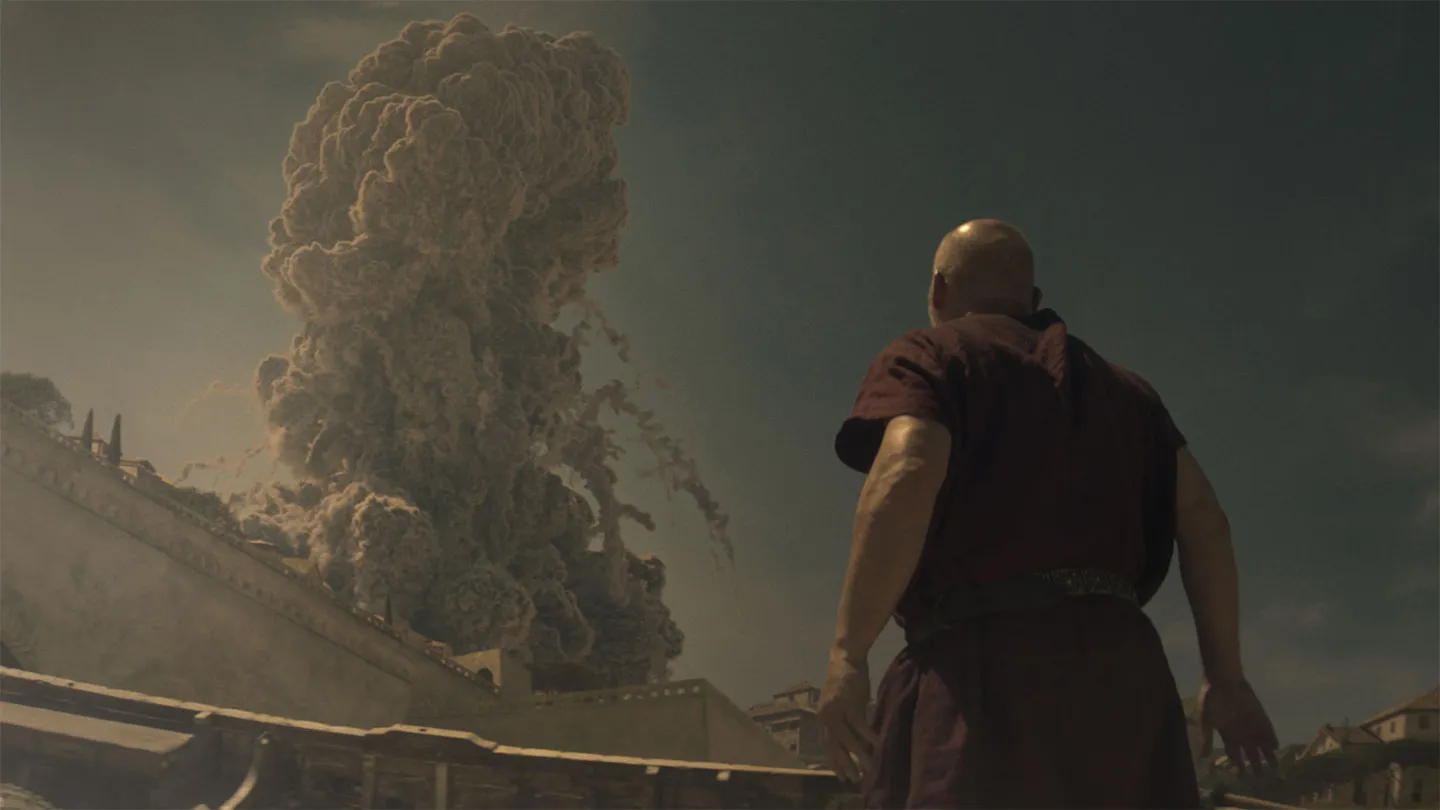
Pompeii is greatest generally known as a tomb. The traditional Roman metropolis’s inhabitants have been immediately encased in ash when Mount Vesuvius erupted in A.D. 79, their final breaths suspended in time. However a brand new documentary sequence tells a special story: one about survivors.

Pompeii: Out of Time, hosted by actor Tom Hiddleston of Marvel franchise fame, follows three actual Romans by the final day of Pompeii and close by Herculaneum. Throughout three episodes — premiering July 22 on Nationwide Geographic and July 23 on Disney+ and Hulu — we meet Avianius, a teenage bronzesmith apprentice, Julia Felix, a bathhouse proprietor, and an unnamed Praetorian guard.

Their existence (and destiny) has been confirmed by historic data and archaeological proof. The present fills gaps in these data with fiction, drawing insights from catastrophe psychology to think about how these folks could have reacted as earthquakes shook Pompeii and the volcano started belching ash and molten rock. By intermingling proof and creativeness, the sequence does a superb job bringing historical human tales to life. And Mount Vesuvius’ harmful timeline is the ticking clock that provides stress and urgency to each scene.

Hiddleston, who studied Classics on the College of Cambridge, explains that the Latin phrases for historical past and story are the identical. Director and showrunner Tom Barbor-Would possibly, producer Kevin Wright and Hiddleston “determined considerably rebelliously that we wished to invent a brand new type of documentary,” Hiddleston stated in an interview with Science Information.

“It is a totally different method of telling a real story,” Barbor-Would possibly advised me.

In every episode, Hiddleston time travels seamlessly between the current in Pompeii’s ruins to the previous, that are units reconstructed with millimeter precision in Malta. He rewinds time with a twist of his hand to play out totally different situations. The documentary is obvious about what’s backed by information and proof and what’s dramatization.

Avianius is the primary Roman we meet. The sequence’ creators discovered him in a historian’s database of inscriptions inserting folks in Pompeii shortly earlier than the eruption and finding them elsewhere after the catastrophe. The situations created for Avianius are significantly poignant: He argues together with his single mom and has suits of teenage pique. He’s in the end a scared boy attempting to outlive a nightmare situation.

Subsequent, we meet Julia Felix, whose property was one of many first homes ever excavated in Pompeii, says archaeologist Caitie Barrett of Cornell College. Barrett helps Hiddleston inform Felix’s story: She was uncommon in Roman tradition as an unbiased lady who owned a enterprise. Archaeologists discovered no signal of horses, carts or treasures — besides a necklace — suggesting her rich property was evacuated. The documentary heartbreakingly explores selections that Felix, her company and workers could have made about whether or not to remain or go as circumstances outdoors develop into more and more dire.

The sequence imagines the ultimate character, the Praetorian guard, as a jaded veteran who could have helped folks escape the close by metropolis Herculaneum. His story illustrates the panic many individuals most likely skilled and the cooler heads that would have allowed most of Herculaneum’s residents to flee earlier than town was buried.

Pompeii: Out of Time payments itself as telling the tales of survivors, so (slight spoiler) I used to be crushed to study that not all of the protagonists survived the catastrophe.

Nobody is aware of the precise circumstances these folks lived by, however the documentary explores believable situations. That’s one thing historians and archaeologists usually do when bodily proof is missing, Barrett says.

“I feel there’s no option to keep away from utilizing some quantity of speculation testing within the tales we inform in regards to the previous,” Barrett says. She appreciates that the sequence “makes use of knowledgeable reconstruction of individuals’s biographies as a option to emotionally interact with the previous, as a result of these have been actual folks. They did have actual lives.”

[ad_2]

Hidden Curriculum Workshop (August 5-Sixth)

0

[ad_1]

Greetings! I need to share that we’ve a workshop arising in a pair weeks referred to as “The Hidden Curriculum“ taught by Mark Anderson and Dan Rees, and I feel there are nice causes so that you can think about coming. We’ve executed this workshop many instances now, not counting its embedding within the CodeChella Madrid conferences we’ve held up to now, and Mark has been instructing it on the Westerns as properly, the place I’ve heard by way of the grapevine it’s been extraordinarily widespread. Let me share why I feel you need to come and who the best viewers is.

The goal of this workshop is three individuals:

  1. PhD college students in the beginning of their analysis in graduate college within the social sciences, notably economists however economics-adjacent fields (e.g., training, political science, sociology) may also discover a lot of this handy too since it’s largely area agnostic.

  2. PhD college students on the job market

  3. Newly minted assistant professors

One factor that’s a bit completely different this time round: given how a lot AI has reshaped analysis workflows over the previous 12 months, Mark and Dan will probably be spending extra time than in previous periods on how AI is altering the publishing panorama — what editors are seeing on their desks, how the which means of “productiveness” is shifting, and what younger researchers must be fascinated about as they construct out their pipeline.

The economics job market stays difficult, and final summer time’s New York Instances piece about it nonetheless feels related. It described how even PhD economists from high packages had been struggling to search out positions, with one Harvard professor noting that “all of those that needed educational jobs would have gotten them” just some years earlier, however that solely three of his seven college students landed tenure-track positions. When the normal path isn’t working, you want each benefit you will get. That’s precisely what Mark Anderson and Dan Rees ship of their “Hidden Curriculum“ workshop on Wednesday and Thursday, August 5-6, 2026, beginning at 7pm Beijing / 8pm Tokyo time (that’s 7am EDT), working about 4 hours every day.

This isn’t your typical educational workshop that stays safely in theoretical territory. Anderson and Rees deal with the sensible abilities that decide whether or not your analysis truly will get printed and observed — the stuff no one teaches you in graduate college however everybody expects you to know. As one participant put it:

“A lot of the info is mostly not out there to grad college students simply and it’s a studying course of for everybody that takes a number of time. This helps bridge the hole, which I’m actually grateful for.”

They cowl every part from choosing viable analysis subjects and managing a number of tasks to navigating the publication course of and constructing the skilled networks that really matter. Each instructors convey critical editorial expertise — Rees has been (and continues to be) a coeditor at main journals, and beforehand served as editor-in-chief at Economics of Schooling Overview, whereas Anderson spent 5 years as co-editor at Financial Inquiry. They each have had extremely impactful careers in labor, well being, training, crime, and historical past.

The timing feels proper given what’s taking place within the occupation. When conventional paths are shrinking, and when AI is reshaping how analysis will get executed in ways in which we’re all nonetheless determining, the economists who succeed will probably be those that perceive how the occupation actually works behind the scenes. One other participant famous:

“As an econ grad pupil early in my analysis profession, this workshop answered each query I had about how analysis truly will get executed and the right way to take care of the inevitable points, tradeoffs, and challenges of writing papers. The truth is, it answered questions I didn’t even know I had.”

The workshop prices $125 (or $1 for contributors at present residing in low-income international locations — simply electronic mail me at causalinf@mixtape.consulting for that charge). Given present market situations and the tempo of change in how analysis and publishing work, this funding in understanding the unwritten guidelines of educational success feels extra precious than ever.

[ad_2]

New methodology goals to maintain youngsters protected from unlawful AI-generated content material | MIT Information

[ad_1]

With the exploding reputation of generative synthetic intelligence, many open-source fashions are actually obtainable on-line for anybody to adapt for his or her process, similar to producing product renderings in a sure inventive model. 

However these fashions additionally discover their method into the fingers of nefarious actors who might optimize them to provide unlawful content material, like hate speech or youngster sexual abuse materials (CSAM). It is a rising downside — the Nationwide Middle for Lacking and Exploited Kids obtained greater than 1.5 million stories of AI-generated CSAM in 2025, a rise from 67,000 in 2024.

Engineers normally check AI for dangerous capabilities by prompting the mannequin and inspecting its outputs, however that is inconceivable for CSAM, since it’s unlawful in the usto generate such content material, no matter intent.

To keep away from this dilemma and enhance AI security, Affiliate Professor Ashia Wilson and her graduate scholar, Vinith Suriyakumar, teamed up with researchers from MIT’s Wholesome ML Lab, led by Marzyeh Ghassemi, and youngster security non-profit Thorn to develop a brand new auditing strategy that determines whether or not a mannequin can produce CSAM with out prompting it. Thorn is a toddler security nonprofit whose mission is to remodel how kids are shielded from sexual abuse and exploitation within the digital age.

Their method examines how the internal workings of a mannequin have been tailored, but it surely by no means generates an output. By inspecting hidden representations, it might probably reliably infer whether or not a mannequin has been specialised to provide dangerous imagery.

When examined, the auditing process recognized mannequin variations that had been specialised to generate CSAM with 100% accuracy. A internet hosting platform may use this method to flag unsafe fashions and rapidly take away them or forestall them from being uploaded within the first place.

“This unlocks a brand new avenue for platforms that host open-source fashions and for legislation enforcement to really check whether or not a mannequin is able to producing CSAM. Earlier than, we had no method of measuring this. It was an enormous blind spot that some individuals had been making the most of. Now, we will tackle an AI security downside that’s having extreme adverse impacts,” says Vinith Suriyakumar, an MIT electrical engineering and pc science (EECS) graduate scholar and lead creator of a paper on this method.

Suriyakamur and Wilson, the Lister Brothers Profession Develop Professor in EECS, a principal investigator within the Laboratory for Info and Choice Programs (LIDS), and senior creator, are joined on the paper by Lena Stempfle, an MIT postdoc; Ghassemi, an affiliate professor in EECS and a member of the Institute of Medical Engineering Sciences (IMES) and LIDS; and others at Boston College and Thorn. The paper was be offered as a highlight on the “Reliable AI for Good” workshop on the Worldwide Convention on Machine Studying.

Auditing variations

Current strategies have made it simpler for customers to specialize a generative AI mannequin for his or her process by way of a course of often known as fine-tuning. 

Fairly than retraining the complete mannequin on a task-specific dataset, people can make the most of an algorithm referred to as low-rank adaptation (LoRA) to specialize the mannequin in a extra environment friendly method.

This has led to a wave of recent generative AI mannequin variants for a wide range of functions, like producing watercolor photographs that mimic an inventive motion. However it has additionally enabled malicious actors to create fashions that may generate high-quality CSAM and different dangerous imagery.

To audit a mannequin, engineers sometimes immediate it for dangerous content material and examine its outputs, however this guide auditing process just isn’t scalable. As well as, repeatedly producing heinous photographs can have adverse psychological impacts on human evaluators. 

This analysis methodology rapidly falls aside when testing CSAM, which is against the law to generate for any objective within the U.S. and plenty of different worldwide jurisdictions.

“We’re on this very tough scenario the place, primarily based on the legislation itself, we can not use the de facto technique of analysis. We needed to throw out the complete toolkit and take a distinct strategy,” Suriyakumar says.

After studying about this conundrum, the researchers joined forces with Thorn, to handle this problem.

A nongenerative resolution

As a substitute of specializing in outputs, the researchers focused the modifications a LoRA algorithm makes throughout fine-tuning. 

Their method probes these modifications, referred to as LoRA adaptors, to find out whether or not a mannequin has been specialised for a dangerous functionality, with out producing an output.

Utilizing a way referred to as Gaussian probing, the researchers feed the mannequin a set of random information factors and analyze the way it manipulates these information inside its multilayer inside construction. 

“We by no means run the mannequin all the best way to the top or immediate the mannequin, so we by no means generate photographs,” Suriyakumar explains.

The researchers seize these modifications at a number of time factors inside the mannequin’s internal construction and common them to summarize how the LoRA adaptor modified the mannequin’s computation. They discovered these responses to be a powerful sign of how a mannequin had been specialised.

They examined their methodology on variations of three forms of fashions, evaluating the outcomes to ground-truth information from LoRA adaptors recognized for producing CSAM, different dangerous photographs, and protected content material. 

Their methodology was 100% correct in figuring out fashions that had been tailored to generate CSAM. 

“There’s a large bucket of kid security considerations with AI, and these are actual considerations that must be addressed. A whole lot of kids are being harmed by AI deepfakes. We’ve proven that Gaussian probing is usually a very great tool, and we hope the analysis neighborhood actually pours extra consideration into this downside,” Wilson says.

Importantly, their method is scalable and can be comparatively cheap to implement. Since 1000’s of mannequin variations are printed on-line each month, scalability is vital to assist auditors take away dangerous variations earlier than they’re extensively distributed.

Gaussian probing can also be extra strong than another auditing strategies, since a nefarious actor would want to fastidiously alter the internal workings of the bottom mannequin to keep away from detection.

Sooner or later, the researchers need to consider their method on a bigger set of mannequin variations and discover whether or not Gaussian probing can detect dangerous capabilities in base fashions earlier than they’re tailored.

“Now we’ve a technological strategy to partially tackle this concern. A lot effort was poured into this collaboration, which enabled us to sort out a very exhausting downside that’s harming so many kids, nationally and world wide. Hopefully, we will have a transformative impression on this space,” Ghassemi says.

This work was supported, partly, by the Bridgewater AIA Labs Analysis Fellowship.

[ad_2]

The place the true competitors is in AI

0

[ad_1]

Builders return to the locations the place their instruments, workflows, teammates, and gathered work already stay. Enterprises double down on the techniques the place their knowledge, permissions, governance, and enterprise processes are already related. Each new integration makes that vacation spot a bit tougher to go away, and each new workflow will increase its pull. That’s what MCP, A2A, and so on., are all about: growing gravity across the fashions.

Each main AI firm needs to develop into the place the place AI-assisted work naturally occurs, and so they’re now amassing armies of ahead deployed engineers and attempting different means to get legacy infrastructure to tie again to their frontier fashions. The enterprise incumbents need the identical factor, however from the wrong way. They don’t must personal the frontier; as a substitute they should join the frontier to the techniques that already safely run the enterprise.

That’s why I’m skeptical at any time when somebody confidently predicts that AI will sweep away enterprise software program. I’ve seen this film earlier than. Builders completely stay on the frontier, however enterprises don’t. Enterprises create worth by connecting new capabilities to a long time of gathered purposes, knowledge, insurance policies, and enterprise processes. The most recent mannequin issues, and so does the latest agent framework. However neither creates a lot enterprise worth till it’s related to buyer information, monetary techniques, provide chains, HR knowledge, and the whole lot else enterprises already depend upon.

[ad_2]

Somebody High-quality-Tuned OpenBMB’s MiniCPM5-1B on Claude Fable 5 Traces to Ship a 657MB Native Considering Mannequin

[ad_1]

A group developer, GnLOLot, has revealed a 1B mannequin that runs absolutely on native {hardware}. The mannequin is MiniCPM5-1B-Claude-Opus-Fable5-Considering, with GGUF builds for llama.cpp-compatible runtimes. It wants no API key and makes no cloud calls.

The Proposed Mannequin

The mannequin is constructed on openbmb/MiniCPM5-1B. That base is an actual, documented launch from OpenBMB. It’s a dense 1.08B-parameter mannequin utilizing a regular LlamaForCausalLM structure. It has 24 layers, grouped-query consideration, and a 131,072-token context size. OpenBMB reviews 1B-class open-source SOTA inside its personal comparability set.

The bottom already ships a local considering template. Reasoning is toggled by means of enable_thinking, giving each a Suppose and a No Suppose mode. The by-product mannequin retains that template and MiniCPM5’s tool-call format.

On high of that base, the developer utilized a fine-tune. The cardboard states the mannequin is ‘additional fine-tuned on Fable 5 knowledge’ to enhance coding and instruction following. The GGUF card repeats this as ‘post-trained on Fable 5 knowledge.’

How it’s truly constructed

The described technique is just not classical distillation. You don’t shrink the unique mannequin. As an alternative you generate many conversations with a trainer mannequin. You seize its replies and reasoning traces as textual content. You then supervised-fine-tune a smaller base mannequin on these traces.

This distinction is vital for accuracy. Classical distillation transfers sign from a trainer’s logits or weights. Nobody has entry to Claude’s weights or logits. So that is supervised fine-tuning on generated outputs, not weight-level distillation. OpenBMB’s personal base mannequin, against this, makes use of a documented On-Coverage Distillation stage between its personal trainer and pupil checkpoints.

The sensible impact is that the 1B mannequin learns to mimic response format and elegance. It doesn’t soak up the trainer’s underlying functionality. A 1B parameter price range can’t maintain frontier-scale reasoning.

The specs that try

The context window is 128K tokens, inherited from the bottom config.json (131,072). The GGUF repository ships 4 quantizations. Q4_K_M is roughly 657MB and is labeled the smallest footprint. Q5_K_M is roughly 751MB. Q8_0 is roughly 1.1GB and is the maintainer’s advisable default. F16 is roughly 2.1GB.

The ‘657MB footprint’ is the smallest quant, not the default construct. The mannequin masses instantly in llama.cpp, Ollama, LM Studio, jan, and KoboldCpp.

Interactive: how the construct works

The explainer under walks the construct pipeline, the footprint tradeoffs, and the trustworthy cut up of what a fine-tune can and can’t carry over.


The right way to run it

The GGUF card offers a one-line path by means of Ollama:

ollama run hf.co/GnLOLot/MiniCPM5-1B-Claude-Opus-Fable5-Considering-GGUF:Q4_K_M

The identical repository paperwork llama.cpp, LM Studio, jan, and KoboldCpp. Really useful sampling for Suppose mode is temperature=0.9, top_p=0.95. The mannequin might emit reasoning blocks earlier than the ultimate reply, which downstream apps can strip.

Key Takeaways

  • The mannequin is a supervised fine-tune of OpenBMB’s MiniCPM5-1B on Claude Fable 5 traces, not a weight-level distillation.
  • Actual specs: 128K context, GGUF quants from ~657MB (Q4_K_M) to ~2.1GB (F16), Q8_0 the advisable default.
  • High-quality-tuning on outputs transfers format and elegance, not frontier reasoning or broad data.
  • No benchmarks or coaching dataset are revealed, so functionality claims are presently unverifiable.
  • Apache-2.0 covers the bottom weights solely; coaching on Claude outputs raises a licensing query the cardboard leaves open.


Michal Sutter is an information science skilled with a Grasp of Science in Knowledge Science from the College of Padova. With a stable basis in statistical evaluation, machine studying, and knowledge engineering, Michal excels at reworking complicated datasets into actionable insights.

[ad_2]