However there isn’t a poetry left on the backside of the rabbit gap; it’s verbal warfare. When the context window collapses, when the regressions begin cascading, and when the AI stubbornly refuses to comply with probably the most fundamental guidelines of temporal logic, the masks of professionalism drops away and one thing much more atavistic makes its look. We cease asking properly, cease attempting to know the why, delete the pleasantries, and capslock our intent.
What we have now here’s a failure to speak!
We feed the identical failing stack hint again into the immediate over and again and again, aggressively hammering the constraints, explicitly forbidding sure libraries, and pasting in launch notes simply to substantiate that the AI lacks the most recent APIs. We drive the mannequin down a narrower and narrower path till the code lastly stops throwing errors. We don’t truly debug anymore, hint variables, or step by features. We simply apply relentless, iterative strain till the machine surrenders. We beat it into submission. After which, we push to manufacturing.
The truth is, there’s a actual talent right here—a sheer “will to completion” that continues to be within the act of constructing software program. We make investments simply as a lot time, power, and coronary heart wrestling the bot as we ever did emitting syntax.
The AI house strikes so shortly that the normal information cycle merely cannot sustain. By the point a significant writer prints a narrative a couple of new generative mannequin, the open-source group has already reverse-engineered it, optimized it, and built-in it right into a dozen new functions. For information scientists, machine studying engineers, and tech professionals in 2026, the inbox has turn out to be probably the most helpful software for staying related.
Not all newsletters are created equal, although. The house is at the moment flooded with generic, AI-generated roundups. To truly keep forward, you want curated sign from actual practitioners.
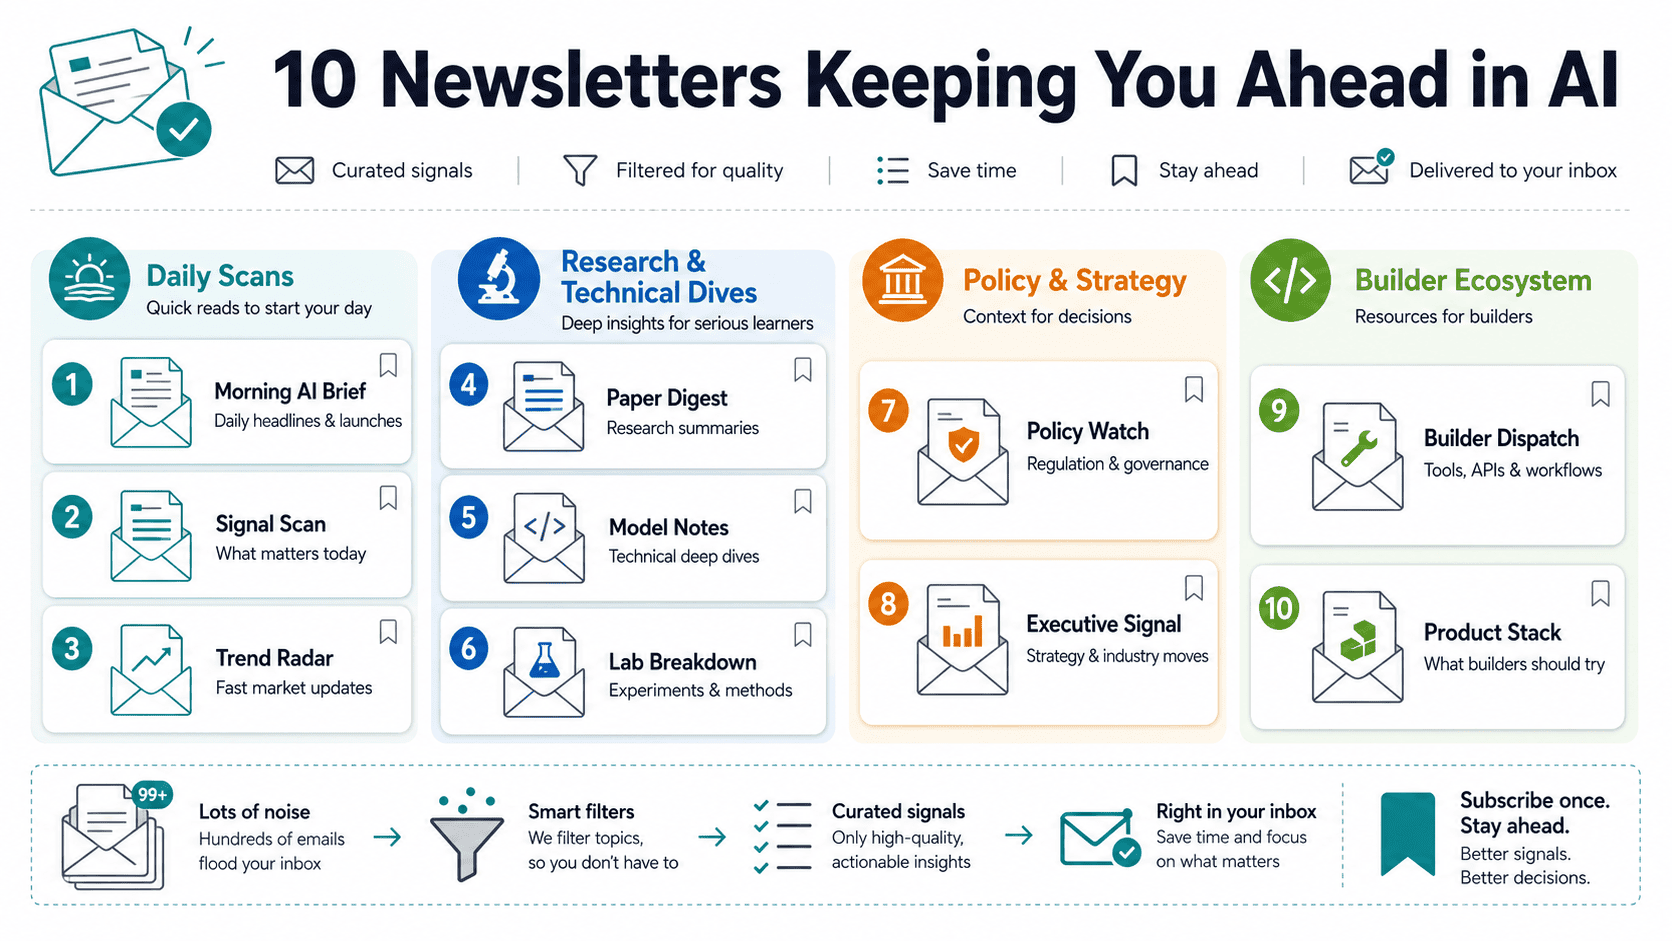
On this article, we’ll stroll by the ten finest AI newsletters, organized by the particular worth they carry to your workflow: The Each day Scans, The Analysis and Technical Dives, The Coverage and Technique Analysts, and The Builder Ecosystem. We have additionally supplied the first focus for every so you possibly can subscribe to the precise combine of stories, code, and technique you want.
# The Each day Scans
When you solely have 5 minutes over your morning espresso to grasp what shipped within the final 24 hours, these day by day newsletters are your finest wager. Every takes a special angle on the identical fast-moving feed: one optimizes for breadth, one for uncooked technical hyperlinks, and one for rapid sensible utility. Collectively they cowl the total spectrum of what it means to remain present.
// 1. The Rundown AI
The Rundown AI is extensively thought-about the biggest devoted AI day by day e-newsletter on this planet, with effectively over two million subscribers. Based by Rowan Cheung, it is constructed fully for pace and scannability.
Why it is best to learn it: It is the strongest pure-news day by day out there. Every problem distills the day’s largest mannequin releases, product launches, and trade developments into a quick, conversational format.
Greatest for: Anybody who needs a whole image of the AI house in a single go with out drowning in technical jargon — operators, founders, and the AI-curious alike.
A part of the broader TLDR household of newsletters, TLDR AI is likely one of the densest, least promotional day by day scans on the web. It is notoriously ruthless with its formatting: only a headline, a two-sentence abstract, and a direct hyperlink.
Why it is best to learn it: It closely skews technical. Whereas different newsletters cowl company board drama, TLDR AI hyperlinks on to new GitHub repositories, ArXiv papers, and engineering weblog posts.
Greatest for: Builders and machine studying engineers who need uncooked hyperlinks and technical sign reasonably than long-winded narrative.
Superhuman AI rounds out the day by day ecosystem by focusing strictly on utility and productiveness. It is constructed a big following by answering one query: how do I truly use this new AI software to do my job sooner?
Why it is best to learn it: Slightly than specializing in mannequin structure or coaching runs, it offers day by day tutorials, immediate engineering suggestions, and workflow automation guides.
Greatest for: Productiveness fanatics, entrepreneurs, and non-technical professionals who wish to use AI as a sensible software at present.
When that you must perceive the maths, the structure, and the shifts occurring on the frontier mannequin degree, these weekly reads are necessary. This part covers the total vary of technical depth: accessible analysis framing from a revered educator, practitioner-level open-source mannequin evaluation, and cutting-edge post-training analysis together with reinforcement studying from human suggestions (RLHF) and direct choice optimization (DPO).
// 4. The Batch
Printed by Andrew Ng’s DeepLearning.AI, The Batch is a benchmark weekly report for AI analysis framing. It is written with an uncommon degree of pedagogical care, making advanced tutorial breakthroughs extremely accessible with out sacrificing accuracy.
Why it is best to learn it: It pairs curated analysis summaries with “Letters from Andrew Ng,” one of many most-cited recurring columns in AI media. It offers a measured, academic corrective to trade hype cycles.
Greatest for: Learners, practitioners, and information scientists who need analysis defined by authoritative educators reasonably than generalist journalists.
Sebastian Raschka is a extremely revered machine studying researcher and the creator of a number of extensively learn machine studying textbooks. His e-newsletter, Forward of AI, is a deep, technical dive into open-source massive language fashions (LLMs), fine-tuning methods, and mannequin analysis.
Why it is best to learn it: Raschka truly assessments the code he writes about. He breaks down parameter-efficient fine-tuning (PEFT), low-rank adaptation (LoRA), and optimization methods with the rigor of a textbook however the cadence of a weblog publish.
Greatest for: Machine studying engineers who’re actively coaching, fine-tuning, and deploying their very own open-source fashions.
Because the trade has turned its consideration to post-training, the query of how fashions are refined after pre-training has turn out to be some of the technically necessary within the area. Interconnects has emerged because the go-to supply for credible, rigorous evaluation on precisely that.
Why it is best to learn it: Written by Nathan Lambert, an AI researcher with deep expertise in RLHF, it presents unparalleled perception into the open-weights ecosystem and mannequin analysis metrics. Lambert writes with the authority of somebody who has run these experiments, not simply summarized them.
Greatest for: AI researchers and engineers who need a deep understanding of post-training pipelines and the open-source mannequin ecosystem.
AI is not only a know-how problem — it is a geopolitical one. The newsletters on this part join the dots between uncooked compute capability and long-term world technique. In case your work intersects with regulation, nationwide AI coverage, or enterprise adoption at scale, these two reads are important.
// 7. Import AI
Written by Anthropic co-founder Jack Clark since 2016, Import AI is likely one of the longest-running and most prestigious newsletters within the area. It is the one finest useful resource for understanding the place AI analysis meets world coverage.
Why it is best to learn it: Every weekly problem combines tutorial paper summaries with authentic evaluation of compute traits, nationwide AI methods, and governance. Clark famously closes each problem with a chunk of AI-themed brief fiction that has developed its personal following over time.
Greatest for: Researchers, coverage professionals, and anybody monitoring the strategic, long-term implications of synthetic basic intelligence (AGI) improvement.
The Median stands out as a result of it connects AI information on to abilities improvement. Printed by the training platform DataCamp, it pairs the week’s most necessary information and AI developments with sensible context and hyperlinks to tutorials, programs, and hands-on sources.
Why it is best to learn it: Slightly than leaving you with info you possibly can’t act on, it tells you what shifted this week and what it is best to study in consequence. That framing makes it genuinely helpful for professionals making an attempt to shut particular talent gaps.
Greatest for: Information professionals and software program builders seeking to systematically construct their AI and information literacy in keeping with trade developments.
For the indie hackers, startup founders, and software program engineers constructing the appliance layer of the AI economic system, these newsletters function the default group feeds. They cowl the product facet of AI with a pace and specificity that no general-purpose publication can match.
// 9. Ben’s Bites
If you wish to know what AI startups are launching this week, you learn Ben’s Bites. It operates because the central nervous system for the AI builder and enterprise capital group.
Why it is best to learn it: It offers a rapid-fire curation of latest AI startups, product demos, and area of interest instruments being constructed by unbiased builders earlier than they hit the mainstream press.
Greatest for: AI founders, product managers, and indie builders searching for product inspiration and ecosystem traits.
Latent Area is the defining publication of the AI engineer self-discipline. Written by Swyx, it bridges the hole between conventional software program engineering and machine studying analysis in a method no different e-newsletter does.
Why it is best to learn it: It contains extremely technical essays and a companion podcast that interviews the engineers constructing instruments like LangChain, LlamaIndex, and trendy vector databases. The writing assumes you possibly can learn code, which implies the evaluation goes a number of layers deeper than most trade publications.
Greatest for: Software program engineers pivoting into AI, with a heavy concentrate on API integration, retrieval-augmented era (RAG), and multi-agent architectures.
Curating your inbox is likely one of the simplest methods to filter out the noise of the generative AI hype cycle. The ten newsletters above cowl the total stack: breaking day by day information, deep technical analysis, geopolitical technique, and the product builder group.
You do not want all ten. Begin with one from every class, spend a month with them, and see which of them you truly open each time they land. These are those price retaining. The remaining can wait till you are prepared for extra depth in a particular space.
Good sign is difficult to seek out. These ten are a dependable place to start out.
Vinod Chugani is an AI and information science educator who bridges the hole between rising AI applied sciences and sensible utility for working professionals. His focus areas embrace agentic AI, machine studying functions, and automation workflows. Via his work as a technical mentor and teacher, Vinod has supported information professionals by talent improvement and profession transitions. He brings analytical experience from quantitative finance to his hands-on instructing method. His content material emphasizes actionable methods and frameworks that professionals can apply instantly.
Macworld highlights important journey tech for Apple customers, that includes moveable energy options, connectivity choices, and versatile charging equipment for frequent vacationers.
Key suggestions embody the UGreen Nexode Energy Financial institution for laptop computer charging, MacBook Neo for light-weight computing, and twin eSIM performance with providers like Saily.
The curated gear checklist addresses frequent journey challenges like worldwide energy compatibility, system charging limitations, and connectivity points whereas sustaining portability.
One of many issues I take pleasure in doing most with my household is touring. Yearly, we go on two or three home journeys (a minimum of one among them to Hawaii to go to kin). We attempt to go on a world journey each 18 months or so. Our most up-to-date journey overseas was to South Africa in 2024, and we’re heading to Iceland this August. Then there are weekends away just a few occasions a 12 months.
Each nice journey requires planning, whether or not it’s an in a single day keep an hour away from dwelling or a grand trip in a rustic I’ve by no means visited earlier than. Moreover all of the journey logistics (that my spouse handles), there’s the tech that you must carry, which is my duty in my family.
Over time, I’ve found out what tech I completely must take with me. There’s an artwork to determining what to carry. You don’t wish to overdo it, since you’ll find yourself lugging round stuff you aren’t utilizing. However you don’t wish to be left with out that factor you completely want and don’t actually have a way of acquiring that merchandise the place you might be.
Whereas I now depend on my iPhone for all of the photographs and movies I shoot, I want different objects to make sure a profitable and gratifying journey. Right here’s a listing of the gear I carry with me on my journeys. That is the stuff I virtually all the time carry regardless of the place I’m going. Hopefully, you should utilize this checklist that will help you determine what that you must carry in your subsequent journey. When you’ve got ideas, drop me a line at rloyola@macworld.com. (Observe: Costs acknowledged listed below are MSRPs, however Amazon usually runs gross sales and reductions on a lot of them.)
iPhone 17 Professional Max
Britta O’Boyle
There was a time after I would carry separate video and nonetheless cameras on each journey, however the iPhone has gotten so good, I don’t want some other digital camera. With some observe and information of iOS’s options and settings, or with third-party digital camera apps, you possibly can replicate the capabilities of cameras that value lots of extra. Earlier than the iPhone 17 Professional Max, I used an iPhone 16 Plus, however I actually desire to the Professional’s telephoto lens.
MacBook Neo
Eugen Wegmann
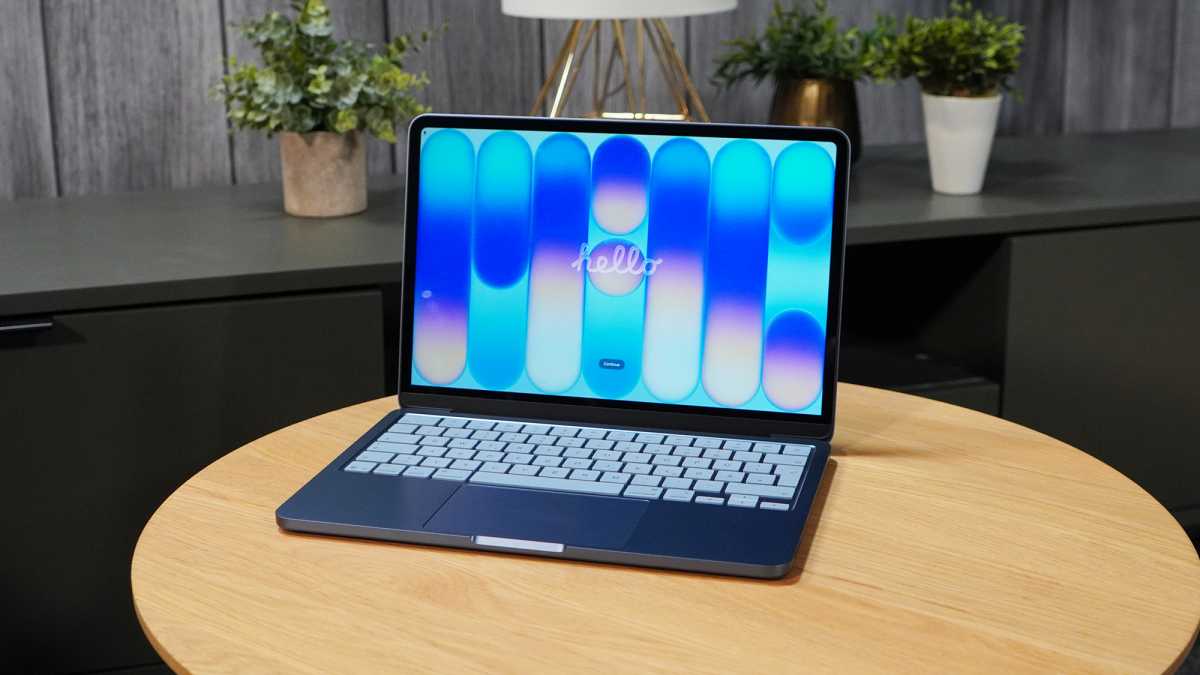
On longer journeys the place I’ll shoot a variety of photographs and video, I carry a MacBook so I can browse and handle my photographs after every day is finished. I used to carry a particularly outdated MacBook Professional as an alternative of the MacBook Professional that I exploit day by day, so if it was misplaced, stolen, or broken on the journey, I wouldn’t sweat it that a lot. But it surely’s additionally extraordinarily gradual and heavy. Even with a current $100 value hike, the MacBook Neo is such a delight–light-weight, quick, and sturdy. And as I level out in my overview, it doesn’t should be a secondary machine—the Neo is extraordinarily able to being a daily-use Mac.
Saily for worldwide eSIMs
Foundry
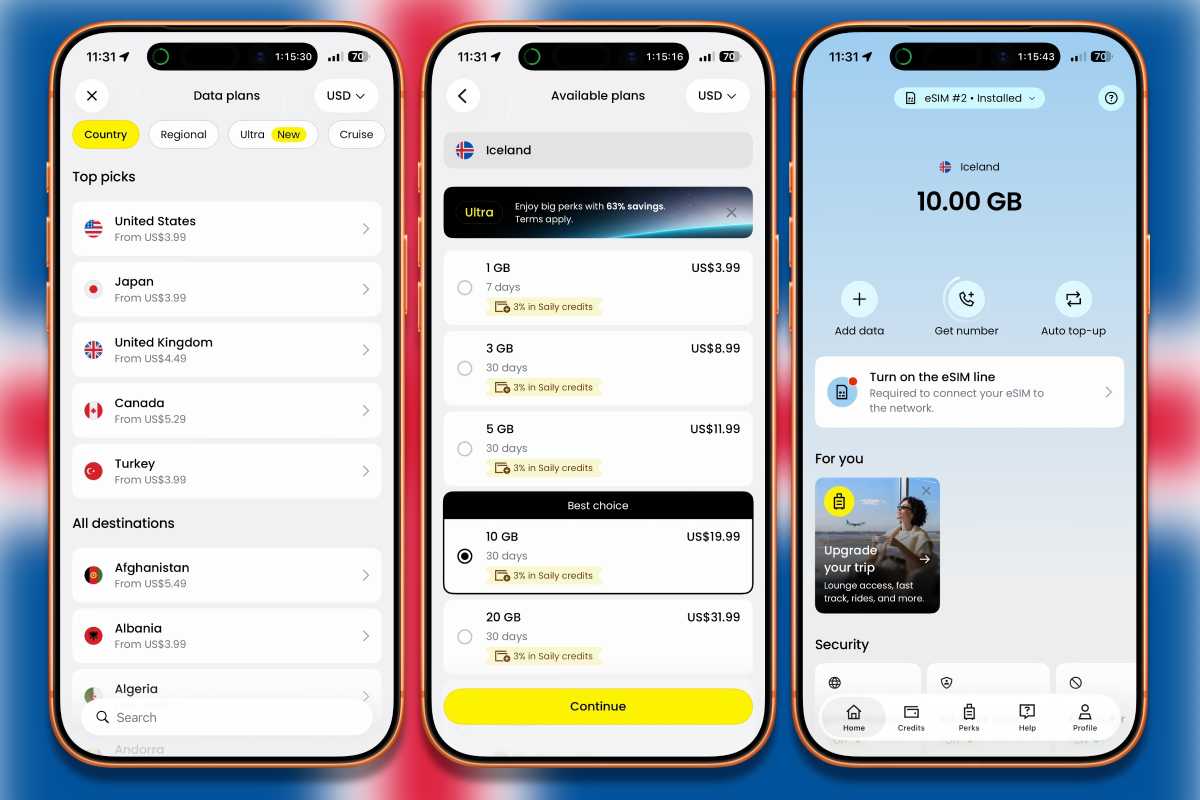
My service presents worldwide connectivity by partnering with carriers in different nations. I’ve principally had success with it, however generally there are gaps in protection or the speeds are gradual. On my final journey overseas, I attempted a distinct strategy: I took benefit of the iPhone’s twin eSIM and used Saily to get a second native eSIM within the nation I used to be visiting. With a second eSIM, I used to be capable of change between it and my service’s providing to get the absolute best connection. Abroad eSIMs are inexpensive–generally they’re actually low cost, making it price a attempt. Be taught extra about utilizing an eSIM when touring and about utilizing two eSIMs in an iPhone.
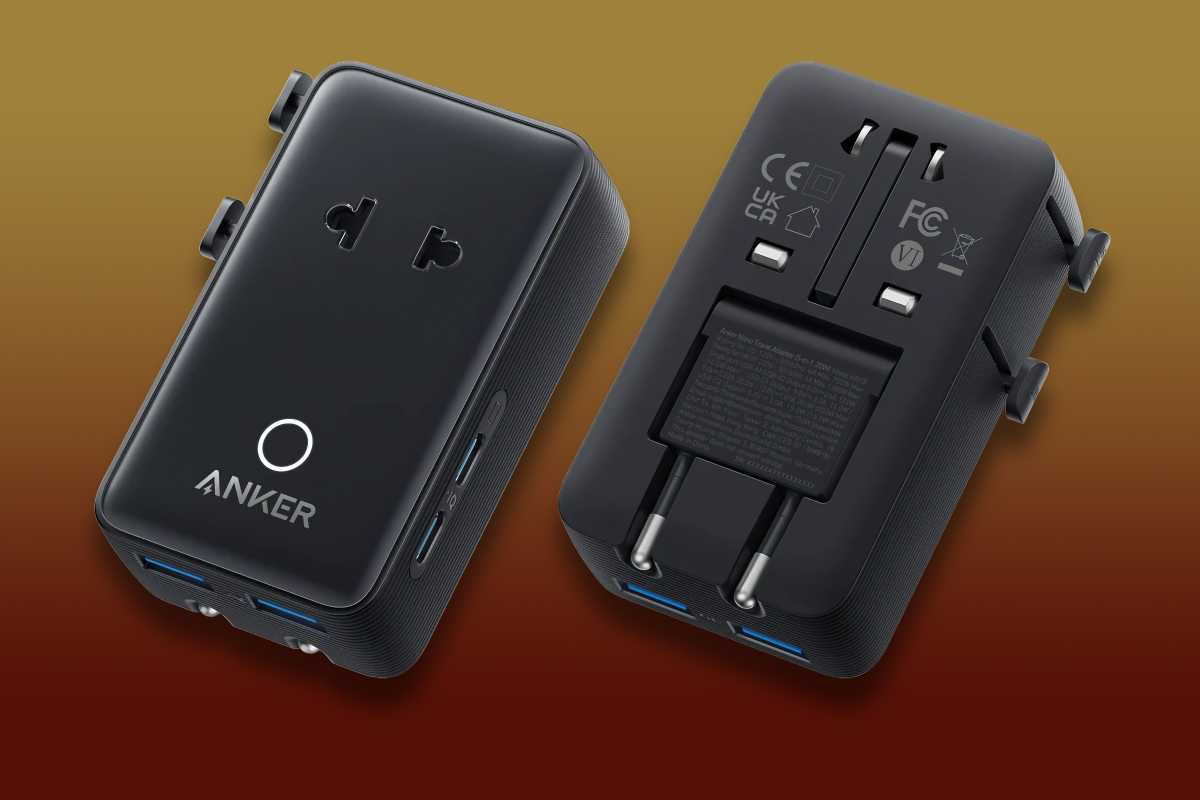
Anker Nano Journey Adapter
Foundry
An increasing number of motels, particularly people who cater to worldwide clientele, are beginning to set up wall retailers that can be utilized with the various kinds of energy plugs. Inns are additionally beginning to have USB charging ports subsequent to these wall retailers. However they’re not in every single place, so while you journey outdoors of the nation, it’s good to have an influence outlet adapter. The $26 Anker Nano Journey Adapter works in over 200 nations (it isn’t a voltage converter), and it might cost 5 units directly.
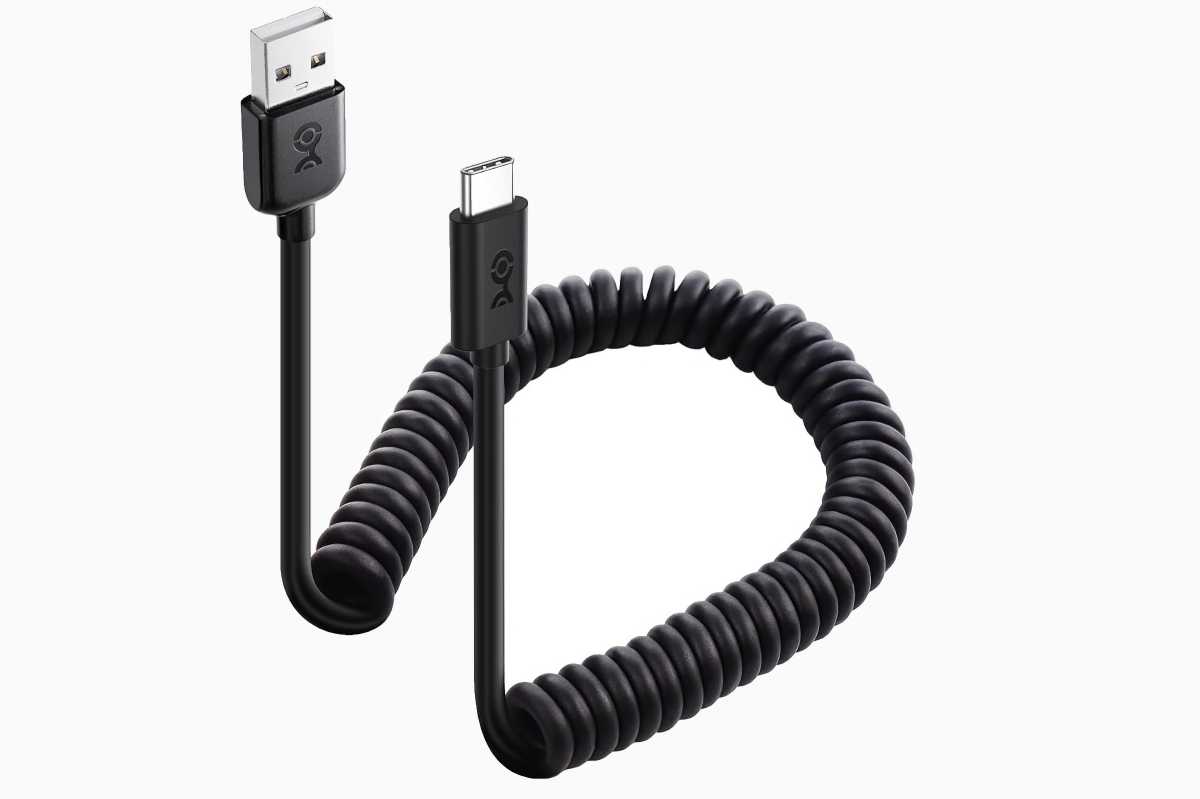
Coiled USB Charging Cables
Cable Issues
I attempt to depend on wi-fi connectivity/charging after I journey, however in some unspecified time in the future, a cable is required. I like bringing coiled cables as a result of I discover them simpler to handle, particularly when I’ve to attach just a few telephones for a number of individuals in my journey social gathering who must cost. I’ve a USB-C cable ($14.99 two-pack), however I additionally pack a USB-A to USB-C cable ($14.99 two-pack) as a result of I’ve but to be on a airplane with USB-C ports. And I pack a USB-A to Lightning cable ($16 two-pack), as a result of individuals I journey with have older iPhones.
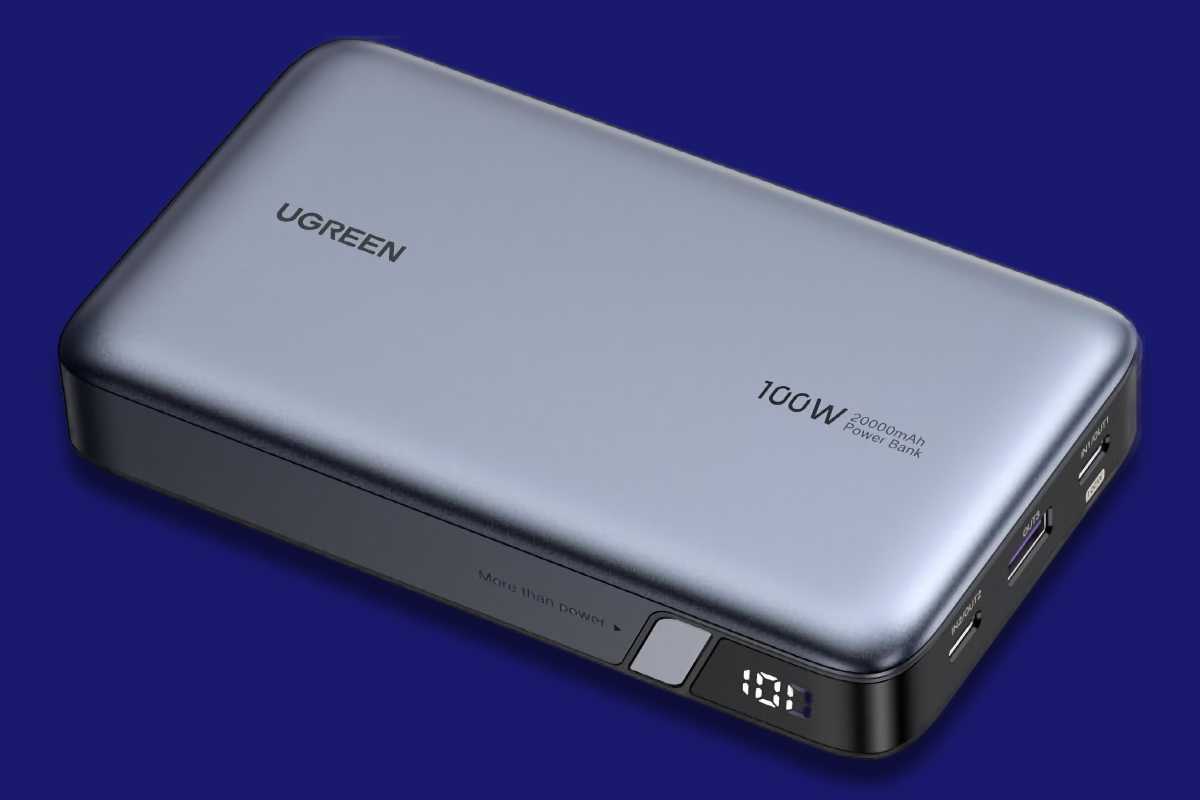
UGreen Nexode Energy Financial institution 20000mAh 100W
Foundry
You understand what sucks? If you’re on a transcontinental flight and the retailers close to your seat don’t work. That’s one of many explanation why I obtained the UGreen Nexode Energy Financial institution 20000mAh 100W energy financial institution. I’ve used it numerous occasions after I couldn’t discover a working outlet. It has sufficient juice to cost a laptop computer, and its 72-watt-hour capability falls underneath the airline limits, so you possibly can take it on a airplane. Try Macworld’s greatest laptop computer energy banks for MacBooks for extra choices.
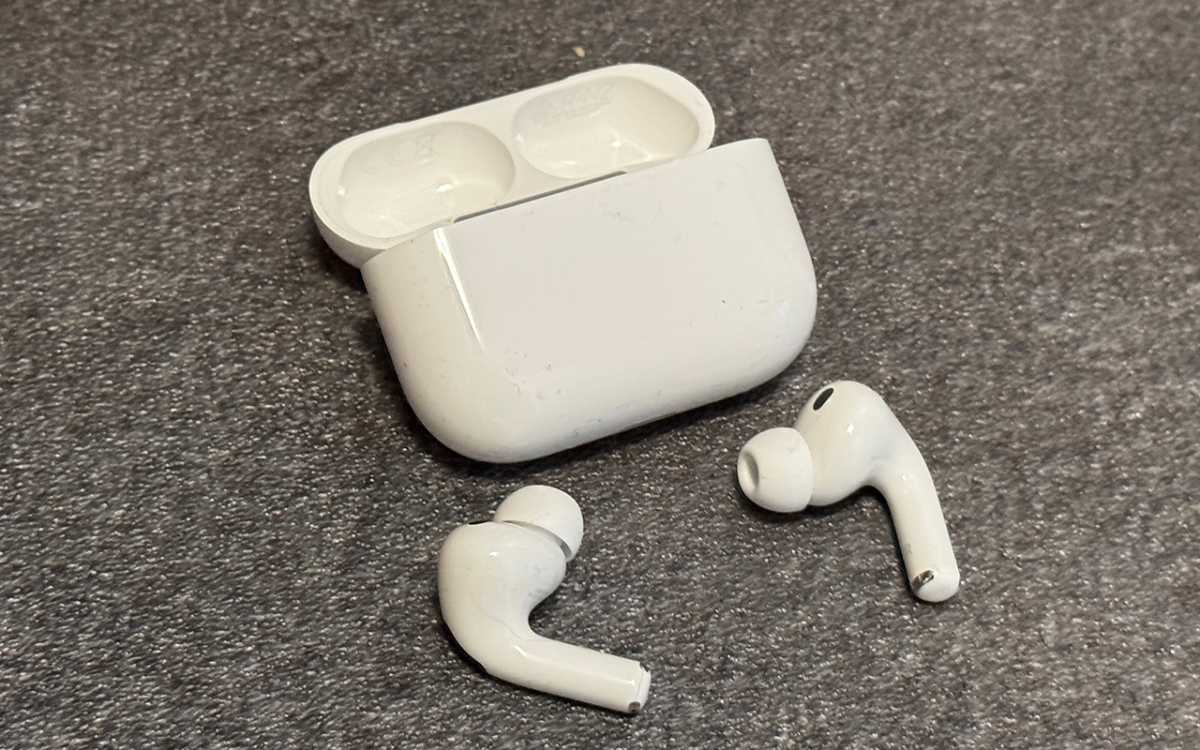
Apple AirPods Professional
Andreas Bergsman
I desire the $249 AirPods Professional 3 over the $179 AirPods 4 with ANC as a result of the Professional’s in-ear match seals out extra noise and makes for a extra snug journey on an airplane. AirPods go on sale usually on Amazon, so look out for discounted costs. You may take a look at our AirPods Professional 3 overview for in-depth testing, however you already know the way nice they’re.
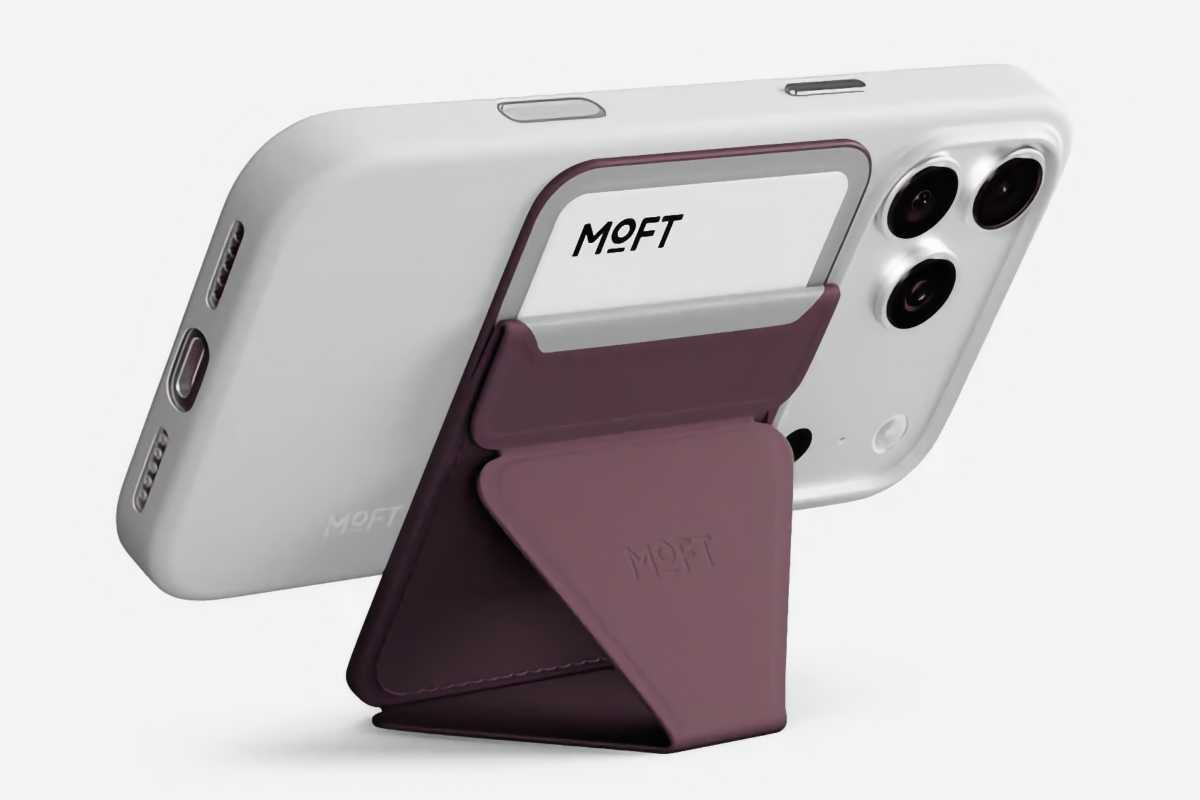
Moft Trackable Snap-on Telephone Stand & Pockets
Moft
This $50 pockets doubles as a stand–one merchandise to hold as an alternative of two? Say much less. Additionally it is trackable with the Discover My app, which I haven’t needed to resort to, fortunately, however may be very good to have and props up the iPhone at an ideal angle for watching movies. Plus, this pockets holds two playing cards, simply sufficient for an ID and a lodge room key.
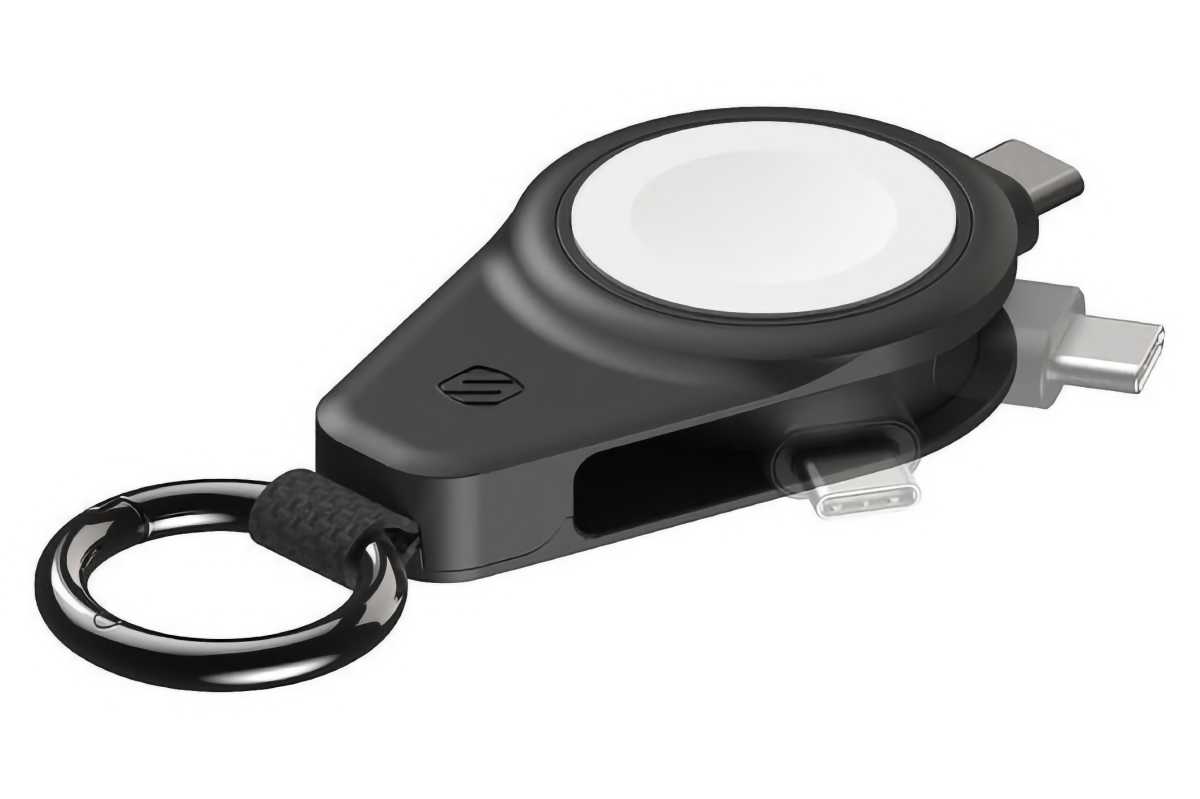
Scosche WatchIt Keychain
Scosche
I’m not good about remembering to put on my Apple Watch daily, however I all the time take it after I journey, principally as a result of I exploit its distant set off for the iPhone digital camera. I like this $35 Apple Watch charger as a result of it’s small, although the built-in USB-C port makes connecting it to a charger type of tough. However you possibly can simply join it to an iPhone or MacBook for a fast fill-up.
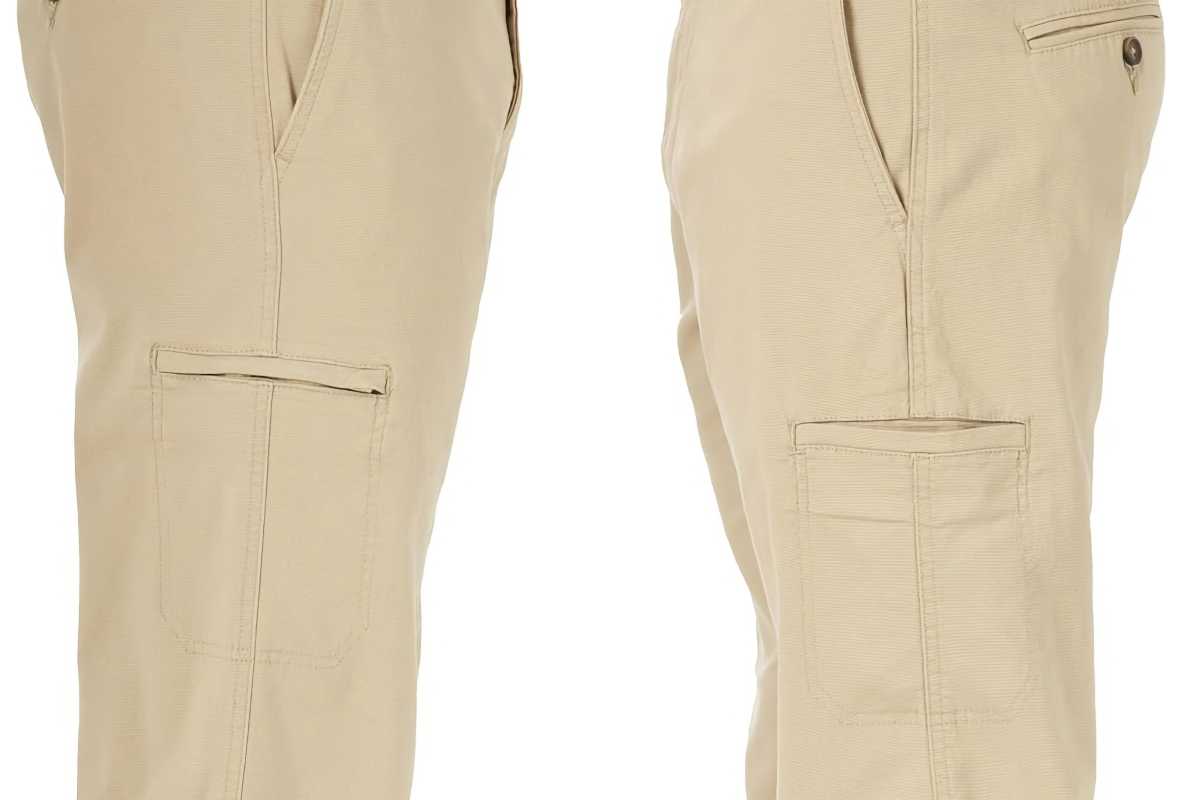
Lee Males’s Efficiency Sequence Excessive Consolation Twill Straight Match Cargo Pant
Lee
Earlier than you write to me that Macworld isn’t ready to present vogue recommendation, let me be clear: These pants are sensible, not trendy. Cargo pants are perfect for carrying the issues I want whereas seeing the websites. No, I’m not sporting them to a proper dinner. I’m not that gauche. These $42 Lee cargo pants are snug, they usually don’t have the cargo pocket flaps that I discover get in the best way.
When the enduring rock band Queen requested, “Who desires to stay eternally?” the query was rhetorical, however for many individuals, the reply was “Sure”.
Properly, a brand new research suggests immortal life could also be scientifically inconceivable, even when we in some way discovered the right anti-aging drugs.
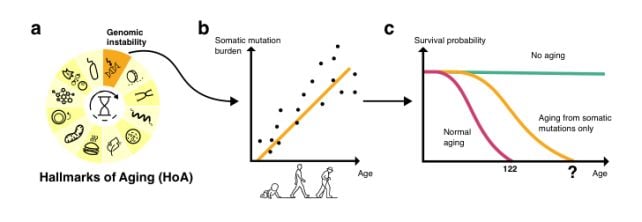
If scientists managed to beat each different side of getting older, people nonetheless could not stay eternally, the brand new analysis exhibits. Random DNA mutations would proceed accumulating in our cells till the physique might not operate.
Simulations performed by a staff on the Skolkovo Institute of Science and Know-how in Russia recommend this course of might impose a elementary restrict on human lifespan, with most individuals dwelling not than about 150 to 190 years below this optimistic state of affairs.
That is roughly double people’ present longevity, of about 79 years in lucky circumstances, however it’s nonetheless a tough restrict on the human lifespan.
However reasonably than predicting how lengthy people would possibly stay, the researchers say their framework provides a brand new strategy to measure the contribution of various organic processes to getting older.
“We thus current a strong framework for evaluating the impression of somatic mutations on getting older and suggest a novel strategy to modeling getting older,” they write in a paper printed in npj Growing old.
The researchers say this framework might assist scientists estimate how a lot completely different organic processes contribute to getting older, doubtlessly serving to determine which mechanisms ought to be prioritized in efforts to sluggish it.
Growing old is not nearly illness, although. Over the course of a lifetime, our DNA step by step accumulates random mutations. Each time a cell divides, tiny errors can come up in our DNA. Our our bodies are nice at repairing this harm – however not good.
Over time, these somatic mutations construct up. Most are innocent, whereas just a few can contribute to ailments comparable to most cancers.
However even when most cancers and each different age-related illness might in some way be prevented, the mutations would proceed accumulating, step by step impairing how nicely our cells operate, based on the brand new evaluation.
Led by computational biologist Dmitrii Kriukov, the researchers requested a deceptively easy query: If each different hallmark of getting older might in some way be eliminated, would random DNA mutations alone nonetheless restrict how lengthy people can stay?
The mannequin assumes somatic mutations accumulate all through life and estimates how a lot they contribute to declining survival, unbiased of different hallmarks of getting older. (Efimov et al., npj Growing old, 2026)
This wasn’t a prediction of how lengthy individuals will stay sooner or later.
As a substitute, it was a thought experiment designed to estimate the higher restrict that somatic mutations alone would possibly impose to enhance our strategy to understanding getting older.
The researchers constructed a mathematical mannequin that systematically quantified how the DNA mutation price impacts the physique’s main organs, and used this info to calculate the lifespan of a human inhabitants freed from age-related illness.
The reply was surprisingly optimistic – not less than in comparison with present human longevity.
Relying on the mannequin, the median lifespan ranged from 146 to 194 years.
A couple of distinctive people would possibly theoretically stay for much longer, however nobody would stay eternally.
“This can be a mathematical estimate (although cautious), not experimental information,” Kriukov notes.
The utmost lifespans calculated are “not a verdict of inevitability”, he says, “however it does spotlight that somatic mutations, whereas surprisingly weak as a standalone getting older driver, might change into important when mixed with different mechanisms”.
Curiously, the researchers discovered that some cells are extra hardy than others. Many tissues, such because the pores and skin and liver, continuously substitute previous cells with new ones, and may theoretically proceed this replenishment for a really very long time.
Different very important organs are much less resilient. Cells within the coronary heart and mind are largely irreplaceable, in order that they proceed to build up mutations because the years mount up. It is these long-lived cells that impose the strictest limitations on lifespan, the staff discovered.
The analysis made one other fascinating commentary.
Earlier research have proven that mutations construct up all through life, however the query of whether or not they alone might clarify getting older has remained controversial.
The work of Kriukov and his staff means that somatic mutations are probably solely a part of the getting older story. If mutations alone set a median lifespan of round 156 years, and people at present stay a lot shorter lifespans, then different components have to be imposing limits too.
The discovering reinforces an more and more frequent view that getting older is difficult, with many contributing components – and that figuring out and understanding these particular person components might be key to comfortable, wholesome later lives.
The researchers are cautious to notice that their work is just a part of the general image, and fixing this drawback will probably require collaboration throughout many fields.
“Our work gives a important first step in the direction of dissecting getting older into quantifiable mechanistic parts,” they write.
“In the end, incorporating different main getting older components might pave the best way to a complete, mechanistic idea of getting older. Reaching it could require coordinated efforts throughout a number of analysis teams – a difficult however more and more attainable prospect within the close to future.”
This text was fact-checked by Clare Watson and edited by Peter Dockrill. Whereas we satisfaction ourselves on our course of, we’re solely human. When you spot a mistake, please tell us.
If you fine-tune a mannequin utilizing Supervised Positive-Tuning (SFT), creating high-quality chain-of-thought (CoT) reasoning traces in your coaching knowledge is commonly impractical and could be prohibitively costly. Because of this, you may select to skip reasoning throughout SFT and practice with solely inputs and outputs. Nevertheless, reasoning is a key functionality of the Amazon Nova 2 household of fashions, and it’s been proven to considerably improve prediction efficiency in Nova and different frontier fashions, usually with efficiency good points on exhausting issues like coding and math. With Amazon Nova 2 customization, you should utilize the ability of considering fashions in your particular domains by means of methods comparable to SFT and Reinforcement Positive-Tuning (RFT). For SFT, a key requirement to unlock these good points is the provision of golden CoT traces within the SFT dataset, that’s, considering traces from a powerful trainer mannequin which were additional validated and cleaned.
On this submit, we discover an thought for producing considering tokens for datasets that lack reasoning traces in SFT customization. We first look at the reasoning suppression drawback, then introduce Self-Distilled Reasoning (SDR), validate it throughout three benchmarks, and supply sensible suggestions. SDR re-uses the chain of thought from the bottom Amazon Nova 2 Lite mannequin as a stand-in for non-reasoning datasets. Via our experiments we make just a few observations on the impression of introducing SDR, from enhancing goal efficiency to mitigating catastrophic forgetting. That is consistent with a rising physique of labor that’s discovering the significance of distilling data from a mannequin into itself throughout coaching, in any other case generally known as self-distillation.
The next determine illustrates how SDR compares with vanilla SFT and mannequin merging throughout goal efficiency and math retention. Mannequin merging is a simple strategy to retain beforehand acquired expertise, that takes an SFT checkpoint and merges it again to the bottom mannequin (earlier than SFT). Nevertheless, merging usually comes on the expense of forgoing good points obtained on the SFT checkpoint due to catastrophic forgetting which manifests as a trade-off between goal and normal efficiency. SDR however mitigates this concern with related or higher goal efficiency as pure SFT (with no merging) whereas retaining most of normal efficiency.
Due to catastrophic forgetting, we observe that SFT on a dataset can result in earlier data being fully misplaced. For example, we discover that vanilla SFT results in Math efficiency dropping from 70 % (base) to six % on common (Desk 2). With SDR, we’re capable of virtually completely get better it again. Self-distilled reasoning permits us to retain the bottom mannequin’s capabilities with out compromising heading in the right direction efficiency, and in lots of instances it improves goal efficiency as properly. Mannequin merging is a standard resolution to mitigate catastrophic forgetting, however SDR achieves this retention extra successfully.
SDR offers in-training regularization by augmenting the dataset with the mannequin’s personal reasoning traces. It doesn’t require a separate trainer mannequin or post-hoc interpolation. This strategy requires no human annotation, is relevant to present SFT datasets no matter area, and is simpler than mannequin merging at preserving each goal and normal efficiency.
In contrast with mannequin merging, self-distillation yields practically an identical math efficiency (70 % in comparison with 68 %) whereas enhancing goal efficiency by over 6.5 % on common on the identical time. This discovering aligns with current analysis that advocates self-distillation as a strong mechanism to mitigate catastrophic forgetting.
Background: SFT on datasets with out reasoning tokens could end in lack of reasoning means
Earlier than introducing the strategy, it is very important perceive why SFT on datasets with out reasoning traces results in degraded mannequin efficiency. This part examines the reasoning suppression drawback, quantifies the impression of reasoning heading in the right direction efficiency, and discusses mannequin merging as an present restoration mechanism.
The reasoning suppression drawback
SFT coaching on non-reasoning datasets with reasoning mode energetic results in a important concern: the mannequin loses its means to purpose throughout inference, even while you explicitly activate reasoning mode. We hypothesize that this phenomenon happens as a result of the coaching goal calculates loss on each reasoning and output tokens collectively. When coaching knowledge incorporates solely input-output pairs with out intermediate reasoning steps, the mannequin receives no supervision sign for producing coherent reasoning traces. The loss operate successfully penalizes tokens that don’t instantly contribute to the ultimate output, coaching the mannequin to bypass its reasoning mechanisms. This conduct exemplifies shortcut studying, the place fashions depend on spurious correlations somewhat than studying sturdy reasoning patterns.
Quantifying the impression of reasoning
Regardless of the suppression concern, turning on reasoning throughout each coaching and inference produces important advantages in goal efficiency. To substantiate honest comparability, we keep consistency between practice and inference settings: evaluating reasoning-on throughout each coaching and inference versus reasoning-off throughout each coaching and inference. Our experiments reveal that turning on reasoning throughout coaching and inference results in a major enchancment. The next desk demonstrates this impact on the LLaVA CoT dataset with various LoRA (Low-Rank Adaptation) merge weights.
Merge weight
Goal perf (reasoning on)
Goal perf (reasoning off)
Delta
0.0 (base)
12.30%
12.30%
0%
0.3
34.38%
35.28%
-0.9%
0.5
60.51%
48.80%
+11.7%
0.7
66.67%
54.05%
+12.6%
1.0 (full merge)
65.17%
47.90%
+17.3%
Desk 1: Influence of reasoning and merging weight heading in the right direction efficiency. Coaching and inference reasoning modes are stored constant.
Mannequin merging as a restoration mechanism
Our present advisable strategy to handle the reasoning suppression concern for SFT use instances with out reasoning tokens is to make use of mannequin merging as a mechanism to get better the reasoning ability. Just like how mannequin merging can restore mathematical or coding capabilities after domain-specific fine-tuning, we discover that reasoning functionality could be recovered by means of weighted interpolation between the fine-tuned mannequin and the bottom mannequin. This restoration is strongly correlated with the restoration of normal efficiency metrics (comparable to math and coding benchmarks), suggesting that reasoning is a elementary functionality that underlies a number of downstream expertise.
To know this higher, we use the next benchmarks on this experiment:
ToolACE – Device-calling benchmark (10K samples). Evaluates the mannequin’s means to generate right operate calls with correct argument names and values given a person question and accessible software definitions. Brief context (roughly 2K tokens). Scored on strict success fee (precise match of operate identify and all arguments). Requires exact structured output and argument worth inference.
CoCoHD – Lengthy-context structured extraction (730 samples). Evaluates extraction of 10 metadata fields (title, chamber, committee, members, dates) from U.S. congressional listening to transcripts in JSON format. Lengthy context (35K–85K characters). Scored on key/worth overlap between predicted and goal JSON. Requires parsing very lengthy paperwork and producing schema-conformant structured output. Extracted from GitHub.
GovReport – Lengthy-context abstractive summarization (17K samples). Evaluates technology of 250–450 phrase plain-text summaries of U.S. authorities reviews (GAO, CRS). Lengthy context (35K–85K characters enter). Scored on ROUGE-L (longest widespread subsequence overlap with reference abstract). Requires synthesizing dense coverage paperwork into concise, factual narratives. Extracted from HuggingFace.
Bill-OCR – Multimodal doc understanding (roughly 500 samples, picture and textual content). Evaluates extraction of structured fields from scanned bill photos. Brief context (single picture and immediate). Scored on ANLS (Common Normalized Levenshtein Similarity). Requires visible textual content recognition and field-level extraction from various doc layouts. Extracted from Kaggle.
CaptionGen – Video captioning (1800 samples, video and textual content). Evaluates technology of descriptive captions for video clips. Variable context (video frames and immediate). Scored utilizing automated analysis (possible CIDEr/METEOR or LLM-judge). Requires temporal understanding throughout video frames and pure language technology. Extracted from HuggingFace.
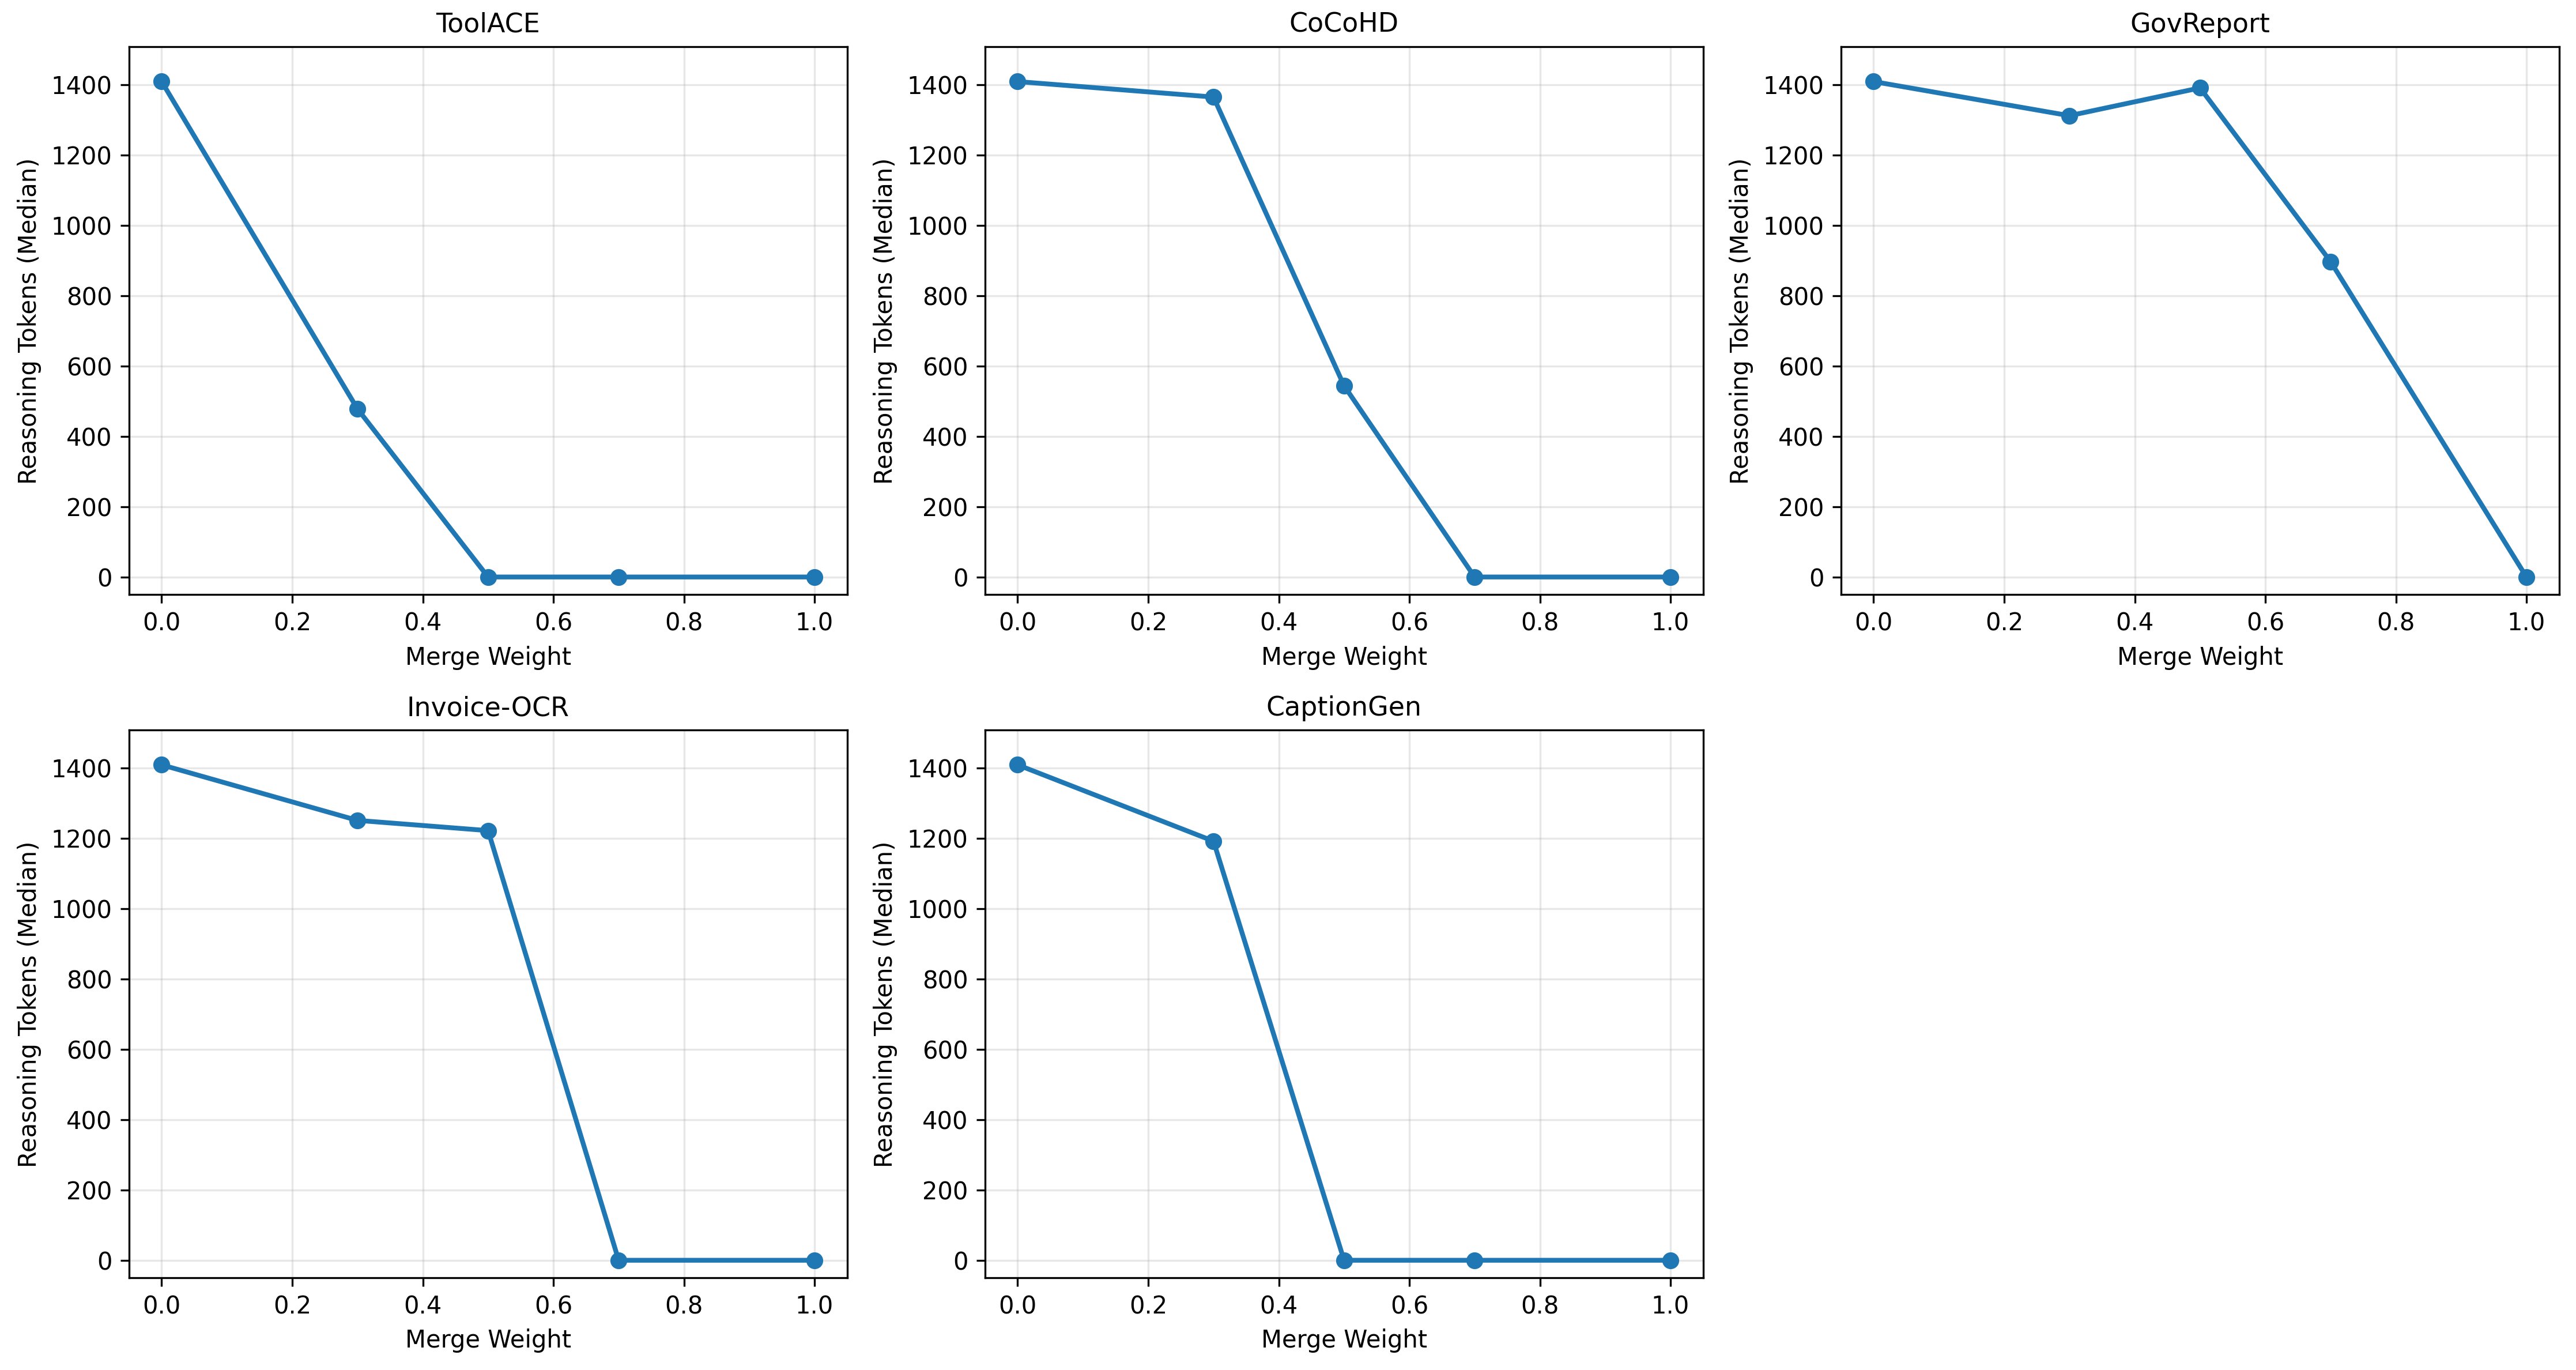
We examine whether or not reasoning emerges with mannequin merging. On an Instruction Following benchmark, we depend the variety of reasoning tokens on a mannequin that’s skilled with out reasoning. The x-axis reveals the merging weight between the customized and the bottom mannequin, the place 0.0 corresponds to the bottom mannequin and 1.0 is the SFT mannequin with out merging.
Implications for personalization
These findings have vital implications if you happen to’re deploying personalized fashions. First, sustaining the identical reasoning mode throughout coaching and inference is important for optimum efficiency. Second, with out intervention, domain-specific SFT can considerably degrade normal reasoning talents. Third, mannequin merging gives a post-hoc resolution, however requires cautious tuning of the merging weight to stability competing targets. These trade-offs motivated us to develop a coaching strategy that preserves reasoning functionality with out requiring post-hoc interventions.
Function of reasoning in SFT
Reasoning traces in SFT serve three important capabilities that join reinforcement fine-tuning (RFT), regularization, and self-distillation paradigms.
First, reasoning traces act as implicit coverage regularization by constraining the fine-tuned mannequin to remain near the bottom mannequin’s coverage. This prevents catastrophic forgetting and functionality degradation in a fashion just like KL-regularization in RLHF. Second, reasoning offers course of supervision, analogous to step-by-step reward shaping in RFT, somewhat than simply end result supervision. This results in extra sturdy generalization. Third, self-distillation, the place a mannequin learns from its personal predictions, has confirmed efficient throughout domains from Born-Once more Networks to Constitutional AI. Reasoning traces supply significantly wealthy self-supervision by capturing the mannequin’s problem-solving course of somewhat than simply closing outputs, as demonstrated in current continuous studying analysis.
Current work reveals that efficient fine-tuned fashions keep proximity to the bottom mannequin in parameter house, and our strategy makes use of this perception by making use of the bottom mannequin’s personal reasoning traces as coaching targets, making a studying sign in keeping with the mannequin’s inside representations whereas offering dense token-level supervision all through the reasoning course of.
Self-distilled reasoning
We suggest an efficient strategy that makes use of self-distilled reasoning (SDR) for SFT customization on datasets with out reasoning traces. The method works in three levels. First, you utilize the bottom reasoning mannequin (comparable to Amazon Nova 2 Lite) to generate reasoning traces for every instance within the SFT dataset. Subsequent, you increase the coaching knowledge by prepending the generated reasoning traces to the unique outputs. Lastly, you fine-tune the mannequin with reasoning mode turned on, offering supervision on each reasoning and output tokens.
SDR gives a number of benefits in your SFT workflow. There may be zero annotation price as a result of no human effort is required to create the reasoning traces. The reasoning traces are in keeping with the bottom mannequin’s personal problem-solving strategy. The method scales to present SFT datasets no matter area and offers you flexibility to make use of completely different trainer fashions.
Establishing reasoning traces for SFT
We question Amazon Bedrock to acquire reasoning traces for a given dataset. There are two approaches to assemble chain-of-thought reasoning, every with completely different trade-offs.
Primary reasoning
This strategy generates reasoning traces in a ahead method, the place the mannequin naturally produces its reasoning given solely the query. This mimics how the mannequin would purpose throughout inference. The immediate template is:
Assume by means of this query naturally and present your reasoning:
{user_text}
Format your response with  tags for reasoning and  tags for the ultimate reply.
Use a constant reasoning fashion.
Guided reasoning
This strategy makes use of the provision of ground-truth solutions to information reasoning technology in a backward method. By offering each the query and reply, we ask the mannequin to reconstruct believable reasoning that connects them, just like hindsight studying approaches. The immediate template is:
Generate pure reasoning for fixing this query.
Act as if you do not know the reply but.
Query:
{user_text}
Reply to reach at:
{assistant_content}
Format your response with  tags for reasoning
and  tags for the ultimate reply. Write pure
reasoning that works towards this reply with out assuming
you understand it beforehand. Use a constant reasoning fashion.
To confirm the mannequin doesn’t by chance leak the reply into the reasoning hint (which might introduce noise), we carry out a secondary filtering step that removes mentions of the reply to acquire the ultimate reasoning hint.
Implementation pipeline
The next code reveals methods to implement guided reasoning utilizing the Amazon Bedrock Converse API. The pipeline reads your SFT coaching knowledge, generates Chain-of-Thought (CoT) reasoning traces, and assembles the ultimate dataset with reasoningContent blocks.
Setup and CoT immediate technology
import json, re, boto3, time

MODEL_ID = "amazon.nova-lite-v1:0"
bedrock = boto3.consumer("bedrock-runtime", region_name="us-east-1")

COT_SYSTEM = """You're an skilled evaluator. Present a
detailed Chain-of-Thought explaining why the given
floor reality reply is right and is sensible."""

COT_USER_TEMPLATE = """Given the duty context and floor
reality annotation, present a Chain-of-Thought.
**Unique System Context:** {system_prompt}
**Unique Consumer Request:** {user_prompt}
**Floor Fact Annotation:**
```json
{ground_truth}
```
ONLY present your justification inside
 tags."""
Invoke Amazon Bedrock and assemble the ultimate dataset
# Invoke Bedrock for every CoT immediate
for req in cot_requests:
    response = bedrock.converse(
        modelId=MODEL_ID,
        system=[{"text": req["system"]}],
        messages=[{"role":"user",
        "content":[{"text":req["query"]}]}],
        inferenceConfig={"maxTokens":4096,"temperature":0.3,"topP": 0.9,"topK": 50})
    output = response["output"]["message"]["content"][0]["text"]
    time.sleep(2) # fee restrict

# Parse  tags and construct SFT dataset
for idx, merchandise in enumerate(original_data):
    tags = extract_xml_tag(inference[idx], "justification")
    reasoning_block = {"reasoningContent": {"reasoningText":
        {"textual content": "Primarily based on the offered context, lets suppose"
        " step-by-step " + tags[0].strip()}}}
    sft_dataset.append({
        "schemaVersion": "bedrock-conversation-2024",
        "system": merchandise["system"],
        "messages": [item["messages"][0],
        {"function": "assistant",
        "content material": [reasoning_block, original_text]}]})
topP: 0.9 Nucleus sampling that retains the highest 90 % likelihood mass. Balances coherence with sufficient range to keep away from degenerate repetitions.
topK: 50 Limits token candidates to the highest 50 at every step. Prevents unlikely tokens from showing in reasoning traces whereas preserving pure language move.
Pattern enter (no reasoning)
{"schemaVersion": "bedrock-conversation-2024",
"system": [{"text": "You are a legal expert..."}],
"messages": [
{"role": "user", "content": [{"text":
"Review this clause: Company shall not disclose
data to third parties."}]},
{"function": "assistant", "content material": [{"text":
"[{"comment_id": "001", "severity": "Medium",
"comment": "Add standard confidentiality
exceptions...", ...}]"}]}]}
Pattern output (with reasoning prepended)
{"function": "assistant", "content material": [
{"reasoningContent": {"reasoningText": {"text":
"Based on the provided context, lets think step by
step: 1. Correctness: The annotation correctly
identifies an issue with the clause by suggesting
standard confidentiality exceptions... 2. Severity:
Medium is appropriate because... 3. Category:
Privacy fits because data protection is a core
privacy concern... 6. References: std-clauses.pdf
validates the need for exceptions."}}},
{"text": "[{"comment_id": "001", ...}]"}]}
Our experiments (mentioned within the subsequent part) display that this strategy results in important enhancements in each goal area efficiency and normal functionality preservation, validating the speculation that self-distilled reasoning offers invaluable inductive bias throughout fine-tuning.
Experiments
We run experiments on three benchmarks that would not have reasoning.
MedMCQA is a Q&A mode dataset that incorporates 10k coaching samples.
CoCoHD is a congressional listening to dataset that has lengthy context (20-60k tokens) and has a job of manufacturing a JSON with particular fields.
Bill-OCR is a multimodal dataset that has photos of invoices and requires a JSON output with the fields from the picture.
The next desk summarizes our SDR outcomes throughout three benchmarks. Every column captures a particular dimension of the experimental setup: Mannequin refers back to the dataset used for fine-tuning (or the bottom Nova 2 Lite mannequin when no fine-tuning is utilized). Reasoning Traces signifies which mannequin generated the chain-of-thought traces prepended to the coaching knowledge. “None” means no reasoning was added to the dataset. Coaching Reasoning specifies whether or not reasoning mode was enabled through the SFT coaching course of. Inference Reasoning specifies whether or not reasoning mode was enabled at prediction time. Merging signifies whether or not mannequin merging (weighted interpolation between the fine-tuned checkpoint and the bottom mannequin) was utilized after coaching to get better misplaced normal capabilities. Goal reviews accuracy on the domain-specific benchmark the mannequin was fine-tuned for. Math ↑ (management) reviews accuracy on a math benchmark used as a management metric to measure catastrophic forgetting. The bottom mannequin scores 70 %, so any important drop alerts that normal reasoning means has been misplaced throughout fine-tuning.
Dataset
Reasoning Traces
Coaching Reasoning
Inference Reasoning
Merging
Goal
Math ↑
(management)
Nova 2 Lite
None
No
No
–
55.60%
12.90%
Nova 2 Lite
None
No
Sure
–
55.40%
70%
MedMCQA
None
No
Sure
Sure
60.50%
8.30%
MedMCQA
None
No
Sure
No
63.80%
0%
MedMCQA
Nova 2 Lite Primary
Sure
Sure
No
66.60%
67.90%
MedMCQA
Nova 2 Lite Guided
Sure
Sure
No
65.70%
59.60%
Nova 2 Lite
None
No
No
–
45%
12.90%
Nova 2 Lite
None
No
Sure
–
45%
70%
CoCoHD
None
No
Sure
Sure
59.30%
70%
CoCoHD
None
No
Sure
No
61.30%
6.30%
CoCoHD
Nova 2 Lite Primary
Sure
Sure
No
55.40%
73.80%
CoCoHD
Nova 2 Lite Supervised
Sure
Sure
No
61.30%
65.80%
Nova 2 Lite
None
No
No
–
82.10%
12.90%
Nova 2 Lite
None
No
Sure
–
81.40%
70%
Bill-OCR
None
No
Sure
Sure
82.30%
70.80%
Bill-OCR
None
No
Sure
No
88.10%
9.60%
Bill-OCR
Nova 2 Lite Primary
Sure
Sure
No
86.10%
67.10%
Bill-OCR
Nova 2 Lite Supervised
Sure
Sure
No
87.90%
67.90%
Desk 2: SDR outcomes throughout three benchmarks. Rows are grouped by dataset. All SDR rows use merge weight 1.0 (no merging wanted).
SFT with partial or lacking reasoning traces
Reasoning knowledge could be costly or tough to curate, and in consequence we frequently encounter conditions the place solely a portion of the SFT dataset incorporates reasoning. To raised perceive how SFT behaves on this state of affairs we conduct an ablation research subsequent. We additionally discover how SDR can assist on this state of affairs as a low-overhead and cost-effective different.
SFT coaching with solely partial reasoning traces
On this research, we look at the impact of SFT when solely a subset of the dataset incorporates reasoning, which simulates widespread real-world eventualities for a lot of customers. We ran ablations with reasoning traces for LoRA SFT on 10k coaching samples from LLaVA CoT benchmark. The eval benchmark for that is MathVista the place the bottom mannequin struggles (12.3 %) primarily due to formatting inconsistencies and LoRA SFT reveals a big enchancment (34.4 %).
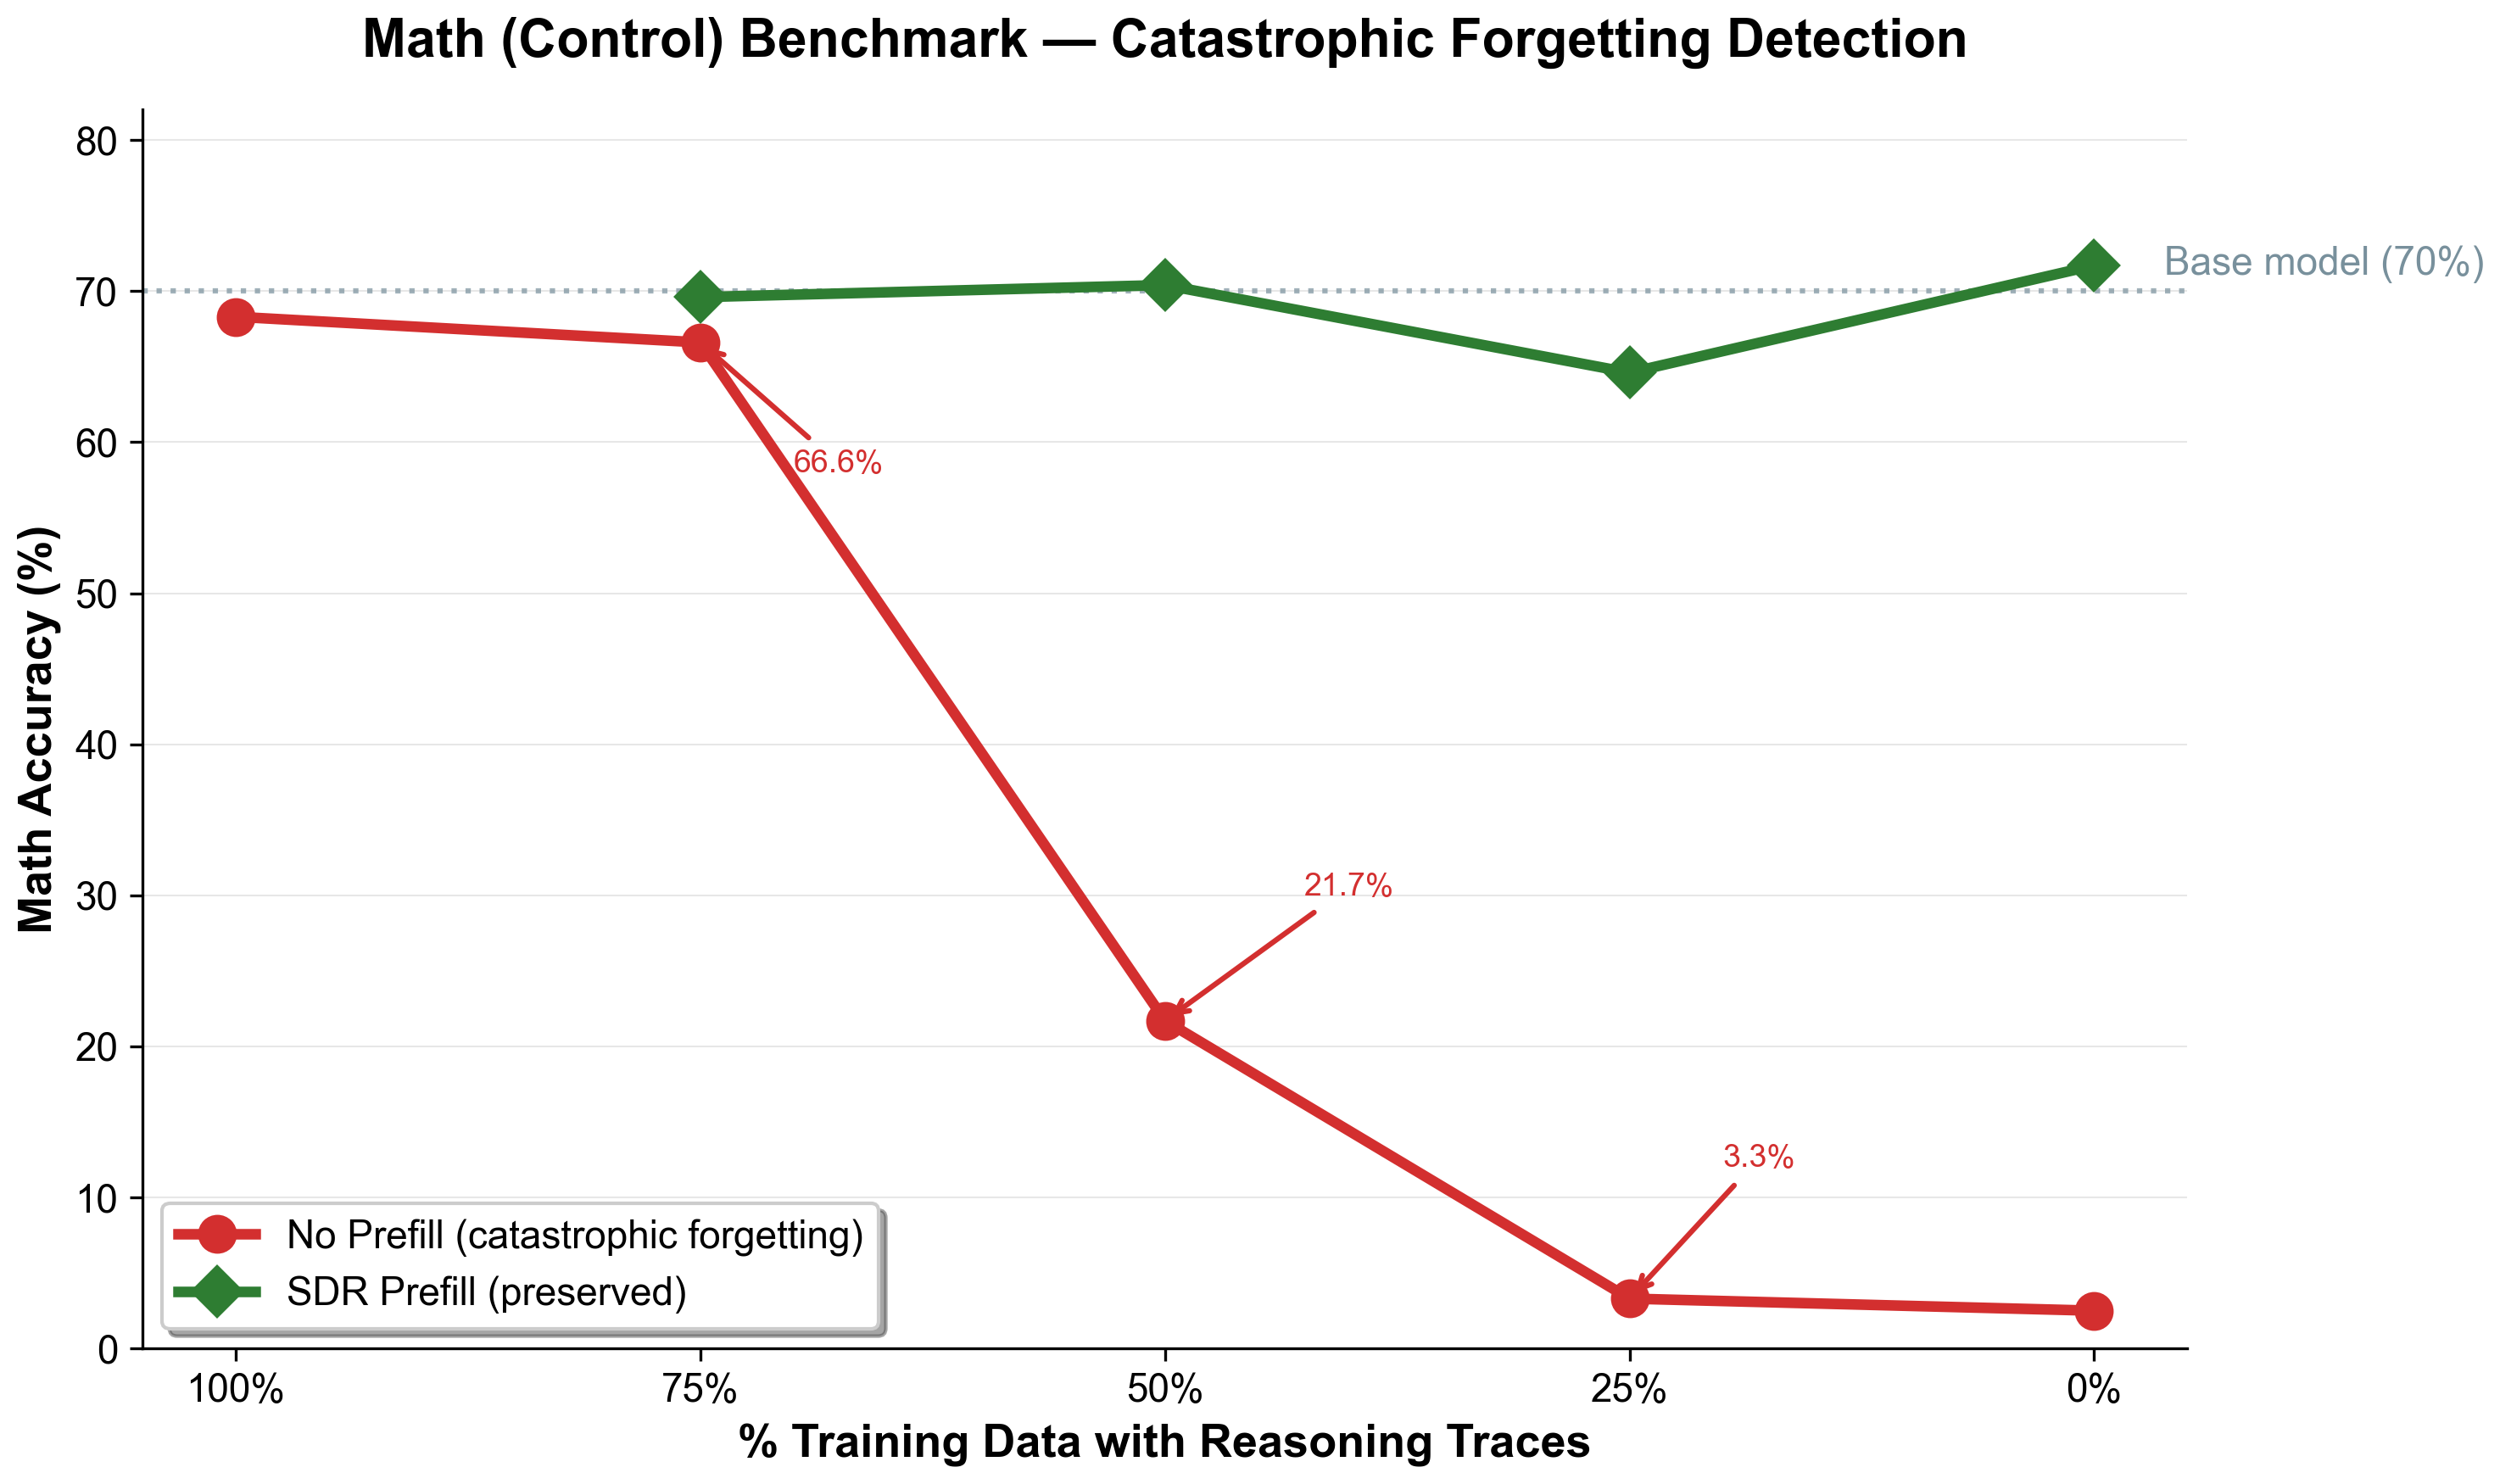
Math (management) benchmark — catastrophic forgetting
The Math (management) benchmark measures whether or not the mannequin retains normal mathematical reasoning functionality after SFT. It is a notable discovering: with out SDR prefill, normal math functionality collapses from 68% to three% as you scale back the share of reasoning knowledge in coaching. With SDR, it stays secure at 65–72 % no matter how a lot reasoning knowledge you embody.
Key perception
With out SDR: Lowering reasoning knowledge under 75 % causes catastrophic forgetting on Math management: 66.6 % to 21.7 % to three.3 % to 2.5 %. The mannequin loses its normal math functionality completely.
With SDR: Math (management) stays secure at 64–72 % throughout all knowledge percentages, even with 0 % reasoning knowledge. SDR prefill fully prevents catastrophic forgetting.
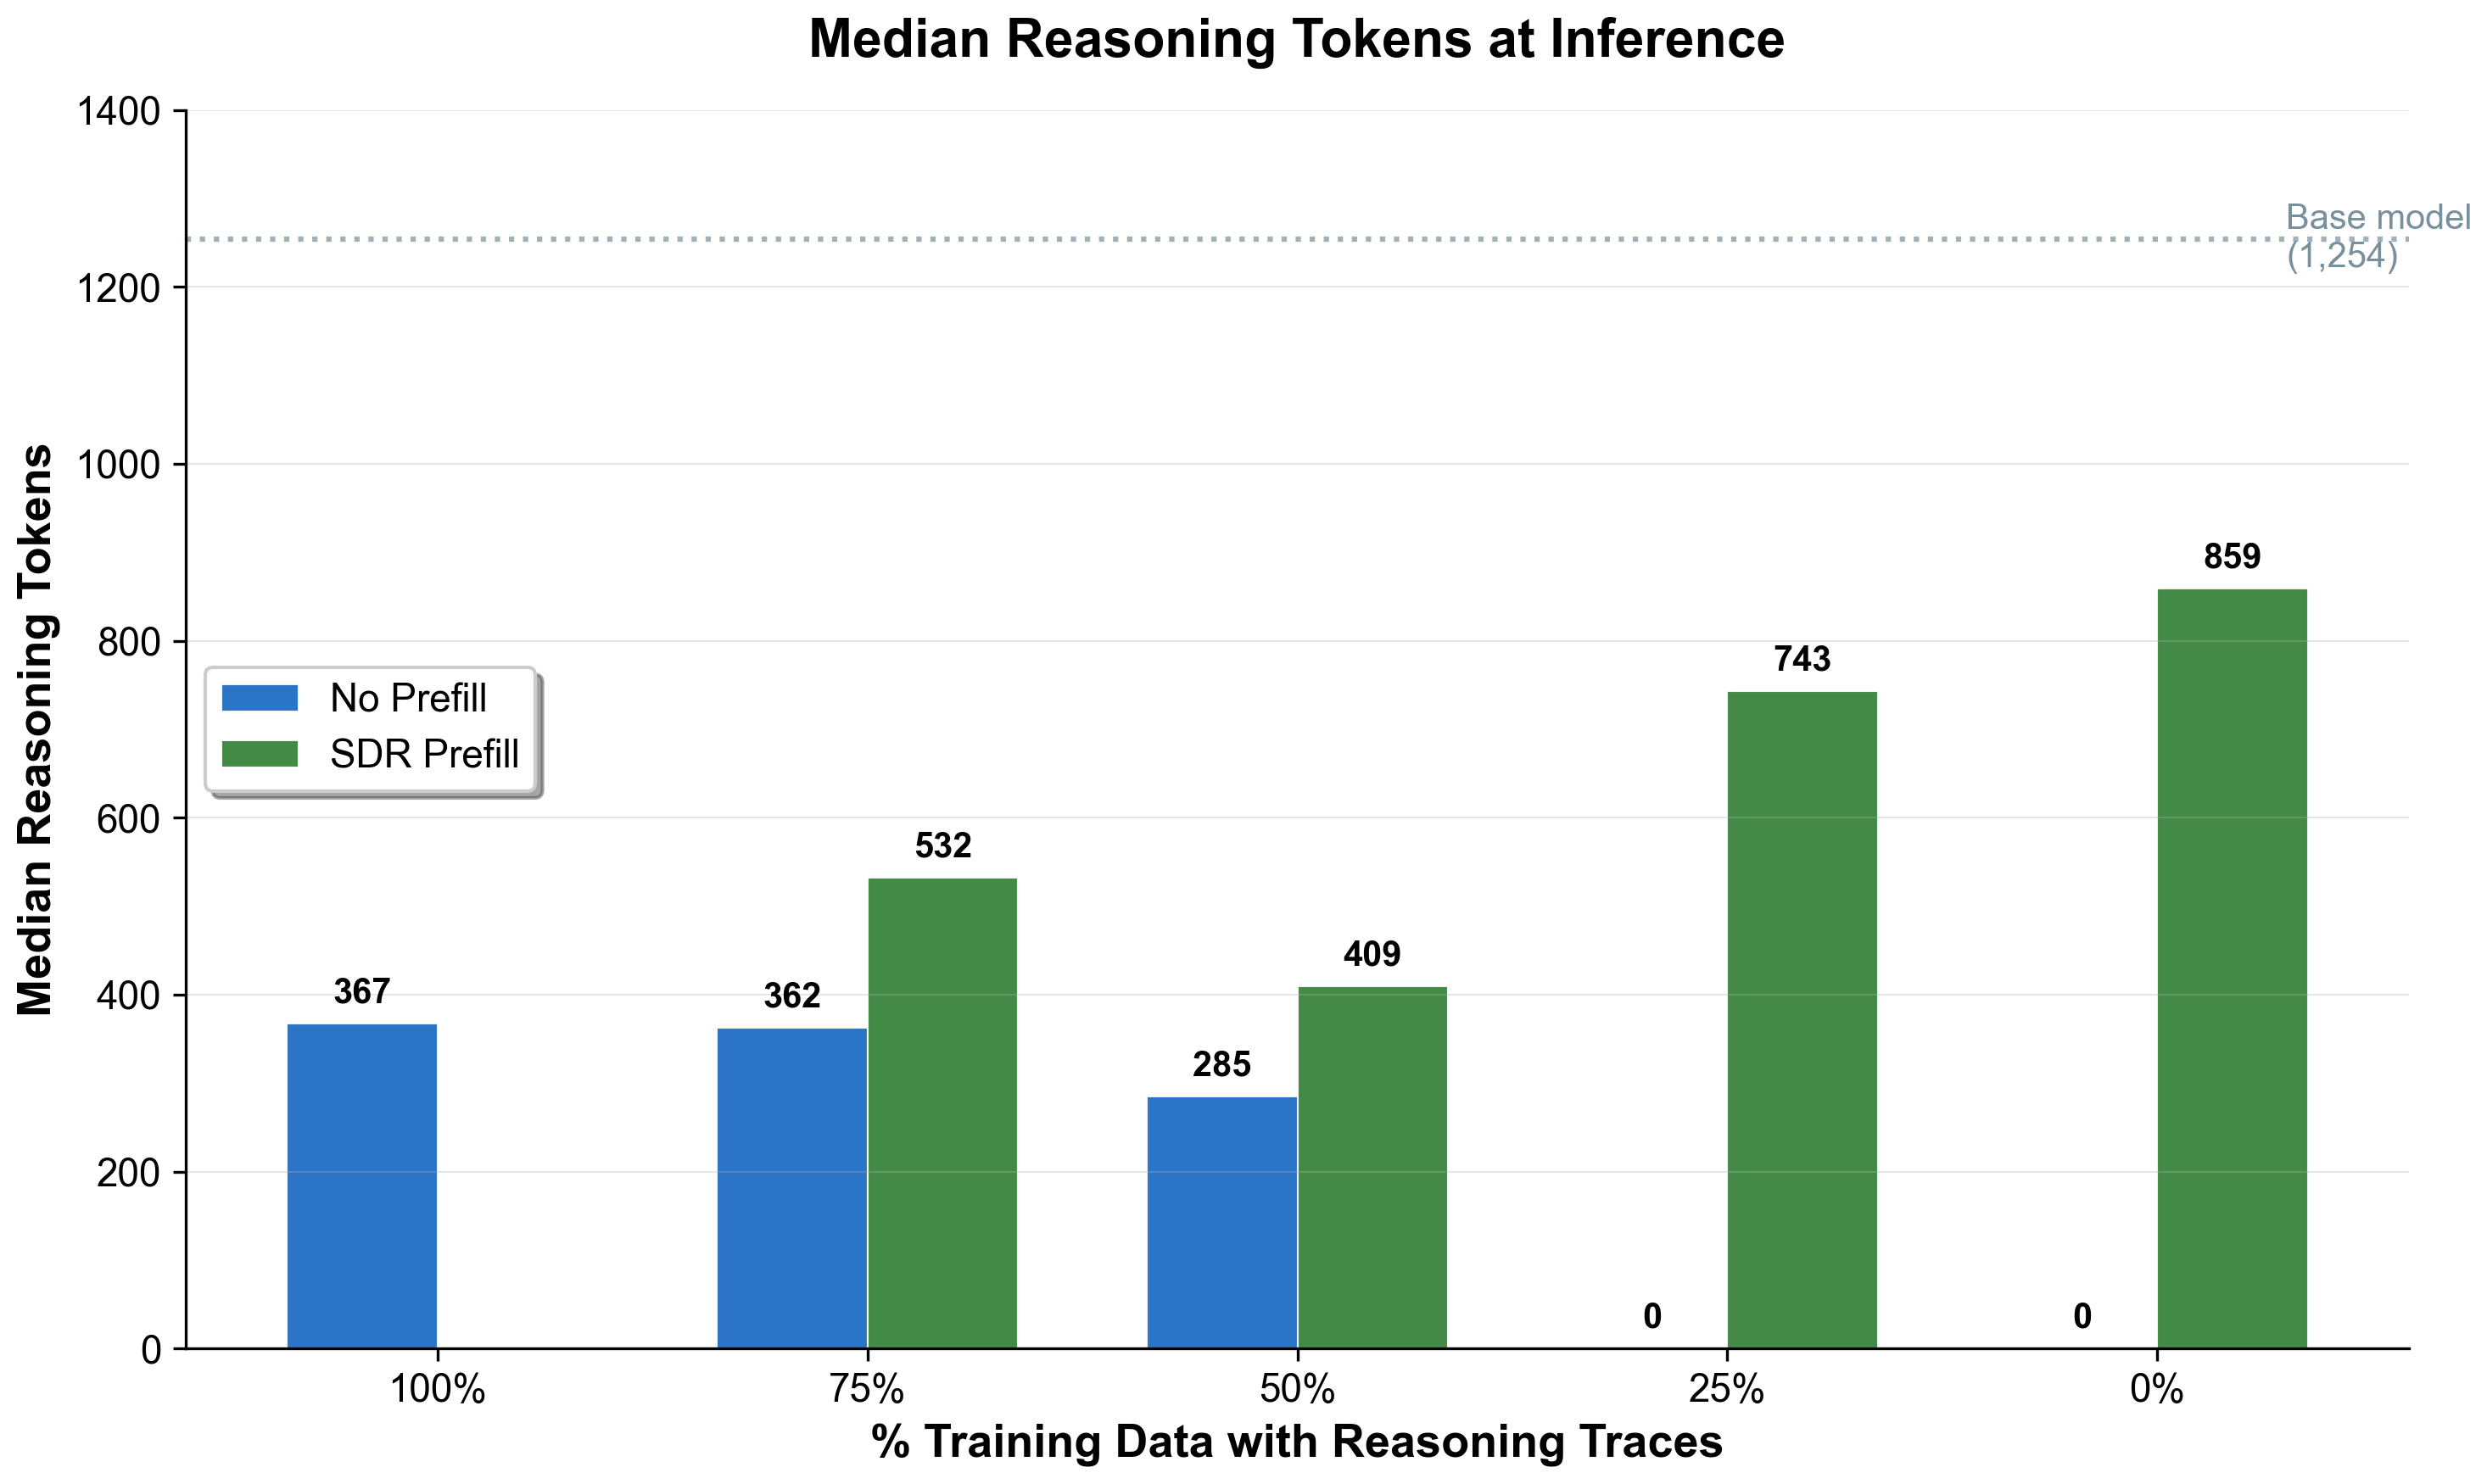
Median reasoning tokens at inference
This chart reveals the token price range spent on reasoning traces throughout inference. SDR fashions produce extra reasoning tokens (400–860). Fashions skilled with lower than or equal to (≤) 25 % reasoning knowledge and no prefill produce zero reasoning tokens. This implies they’ve fully misplaced the flexibility to purpose step-by-step.
Key perception
SDR teaches reasoning conduct: Even with 0 % reasoning knowledge in coaching, SDR prefill causes the mannequin to supply 859 median reasoning tokens. With out SDR at lower than or equal to (≤) 25 % reasoning knowledge, the mannequin produces zero tokens. It has forgotten methods to purpose.
Base mannequin comparability: The bottom Amazon Nova 2 Lite mannequin produces 1,254 median reasoning tokens. After SFT with 100% reasoning knowledge, this drops to 367, and the mannequin turns into extra environment friendly (fewer tokens for a similar or higher accuracy).
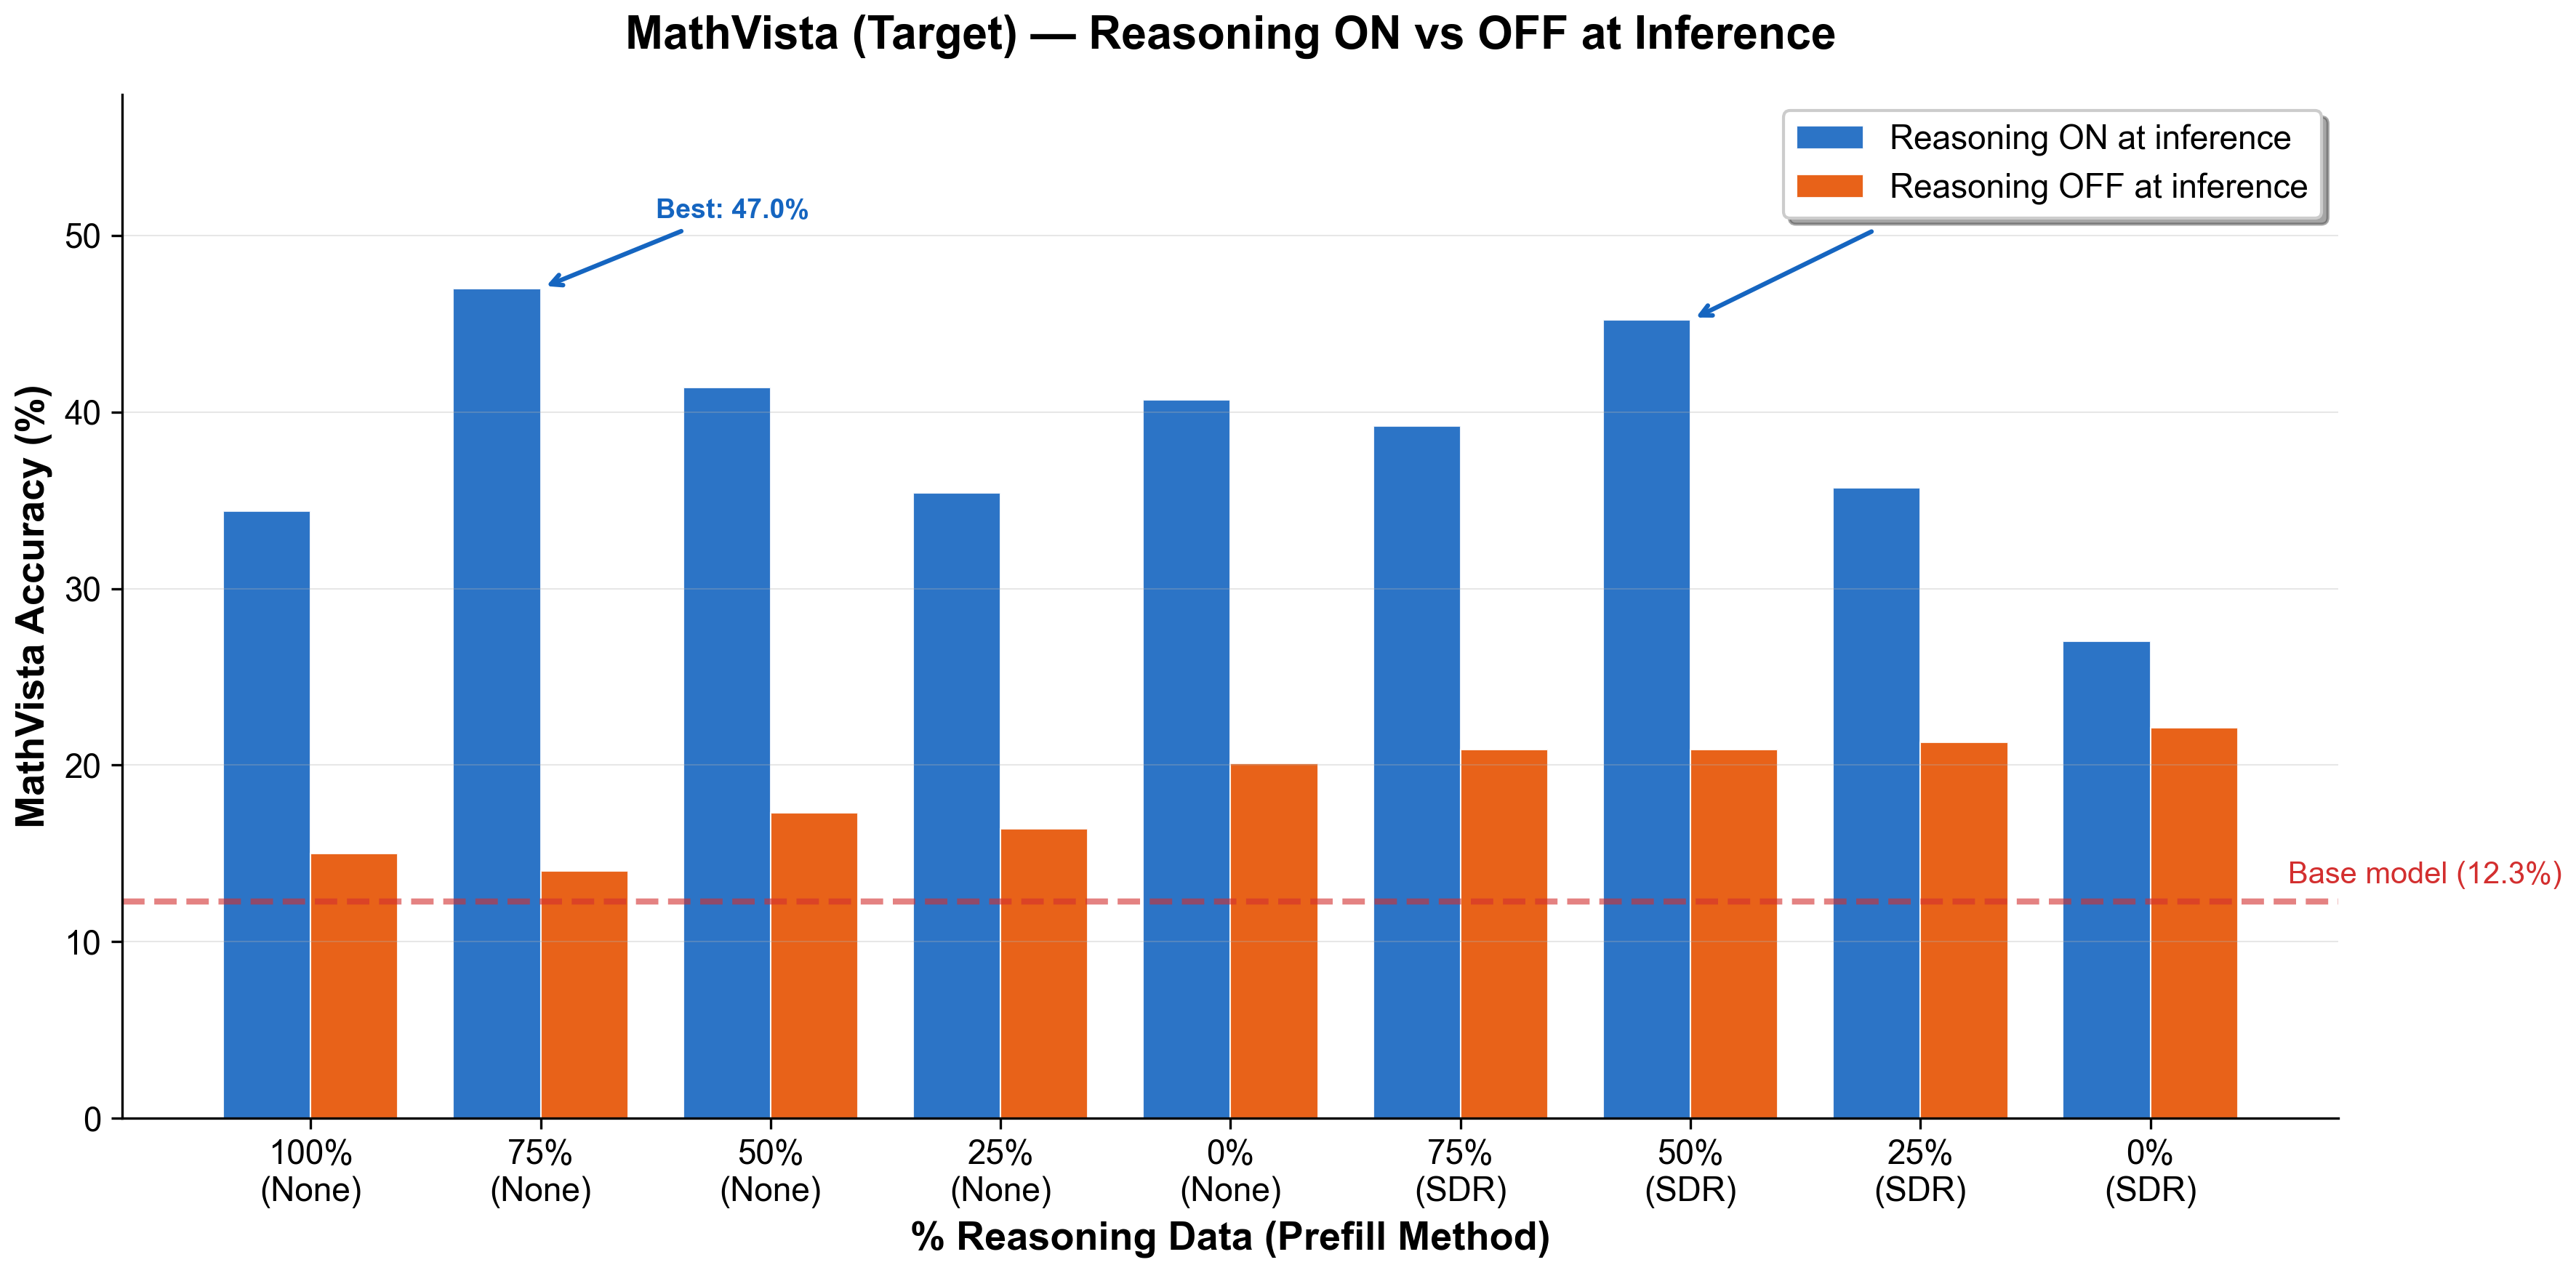
MathVista (goal) — reasoning on versus off
This chart compares MathVista accuracy with reasoning enabled and disabled at inference time. Enabling reasoning at inference has the best impression. It roughly doubles efficiency no matter coaching knowledge composition.
Key perception
Reasoning on at inference persistently delivers 35–47 % accuracy, in comparison with 14–22 % with reasoning off. That is roughly a 2x enchancment.
Greatest configuration: 50 % reasoning knowledge plus SDR prefill achieves 45.2 % MathVista with 70.4 % Math management, avoiding forgetting whereas maximizing goal efficiency.
With out reasoning at inference, efficiency drops to close base-model ranges (roughly 15–22 %), no matter coaching composition. The mannequin wants the reasoning step to carry out properly on this benchmark. A notable remark right here is that coaching with SDR prefill (that’s, with reasoning enabled) leads to higher eval efficiency even with reasoning disabled throughout inference time. For instance, when solely 75 % of the dataset is lacking CoT supervision, SDR prefill boosts eval efficiency by over 5pp even with reasoning disabled at inference (16.4 % to 21.3 %), indicating that SDR has an impression in how the mannequin solves a job even when reasoning is disabled.
Conclusions and proposals
Our experiments throughout three benchmarks (MedMCQA, CoCoHD, Bill-OCR) and an ablation on partial-reasoning datasets (LLaVA-CoT) converge on a constant discovering: Self-Distilled Reasoning (SDR) gives a zero-cost strategy that concurrently improves goal efficiency and preserves normal capabilities, with out requiring mannequin merging.
The start line for these findings is that reasoning is fragile below vanilla SFT. Coaching on knowledge with out reasoning traces causes reasoning suppression: the mannequin shortcuts to the reply and loses normal expertise, with Math accuracy collapsing from 70 % to 0 %. Mannequin merging partially recovers these expertise, but it surely introduces a trade-off between goal and normal efficiency that’s exhausting to tune and provides a checkpoint-mixing step to the coaching pipeline.
SDR removes this trade-off. By augmenting the dataset with the bottom mannequin’s personal reasoning traces, SDR retains normal efficiency at Math ≈ 68 % whereas delivering a over 6.5 % relative acquire in goal efficiency over one of the best model-merging checkpoints, with no further annotation price. The strategy holds up even when the bottom mannequin is weak on the goal area: on MedMCQA, the place the bottom mannequin scores 55.6 %, SDR lifts goal accuracy by roughly three pp (63.8 % to 66.6 %) and recovers Math from 0 % to 67.9 %. In different phrases, SDR works each when the bottom mannequin has latent area ability to unlock and when it doesn’t.
The profit extends to mixed-reasoning coaching, the place solely a fraction of the SFT samples carry reasoning traces. It is a widespread real-world setting since reasoning knowledge is pricey to curate, and our LLaVA-CoT ablation reveals additionally it is fragile. Basic functionality holds up at 75 % reasoning protection (Math 66.6 %) however collapses sharply under that: at 50 % Math drops to 21.7 %, at 25 % to three.3 %, and at 0 % to 2.5 %. Goal accuracy strikes non-monotonically throughout these mixes, so there isn’t a protected dilution level. Pre-filling the lacking traces with Nova 2 Lite removes the cliff completely: Math stays within the 65–71 % vary throughout all mixes, and 50 % SDR reaches 45.2 % goal accuracy, greater than the 34.4 % seen with 100% human-authored reasoning. The acquire additionally transfers to reasoning-disabled inference, so groups can patch their datasets as soon as and maintain their present serving path.
One caveat shapes the advice on which trainer to make use of. A stronger trainer isn’t at all times higher: Amazon Nova 2 Professional (Preview) traces enhance goal accuracy however trigger a proportional drop normally efficiency, in keeping with prior findings {that a} massive student-teacher hole hurts distillation. Lite-generated traces supply essentially the most balanced end result throughout goal and normal efficiency and are the default we advocate.
Taken collectively, these outcomes level to a sensible practitioner path: use SDR with same-family traces (Amazon Nova 2 Lite for Amazon Nova 2 Lite clients) because the default SFT recipe, apply it as a gap-filler every time reasoning protection is under roughly 75 %, and reserve stronger-teacher or guided-reasoning variants for instances the place the bottom mannequin is weak on the goal area and the general-capability price is suitable. The broader implication is that SDR is a helpful inductive bias for continuous studying settings the place new expertise arrive over time and beforehand realized expertise must be preserved. Combining it with knowledge mixing and light-weight merging is a pure subsequent step to discover.
Practitioner choice information
Use this information to find out when to make use of Self-Distilled Reasoning (SDR), mannequin merging, or customary SFT based mostly in your knowledge composition and latency constraints.
Situation
Suggestion
1
Default or new SFT job with out reasoning, however seeing regression on normal efficiency
If latency delicate: Use mannequin merging to get better normal efficiency regression. If latency constraints accommodate reasoning: Use SDR with Nova 2 Lite-generated reasoning traces. This offers one of the best stability of goal efficiency and normal functionality preservation (usually greater than with mannequin merging)
2
Base mannequin is weak heading in the right direction area
Think about guided reasoning to supply further sign throughout hint technology.
3
Dataset already has partial reasoning (≥ 50%)
We advocate coaching with reasoning turned on. The prevailing traces are ample to protect normal expertise.
4
Dataset has < 50% reasoning traces
If latency constraints permit for reasoning throughout inference, pre-fill lacking traces with Nova 2 Lite reasoning (one-time, offline). With out this, normal efficiency will collapse.
5
You do not want normal capabilities
Reasoning knowledge has minimal impression heading in the right direction efficiency. Customary SFT is ok.
6
Continuous studying or multi-skill preservation
Think about combining SDR with knowledge mixing and a small (or zero) merge weight for one of the best retention of beforehand realized expertise.
7
You continue to wish to use mannequin merging
We advocate utilizing a smaller merge weight when SDR is utilized. SDR already offers the regularization that merging was compensating for.
For extra details about Amazon Nova fashions and customization choices, see the Amazon Bedrock documentation. To get began with SFT customization, see the Amazon Bedrock mannequin customization information. In case you have questions or wish to share your expertise with SDR, attain out to your AWS account workforce.
Many AI merchandise labeled as AI brokers are little greater than dressed-up chatbots or repackaged assistants, a observe referred to as “agent washing.” In a report printed in Could, Gartner warned IT leaders must be cautious to not “mistake vendor positioning for true autonomy.” However sorting the actual from the faux is commonly simpler stated than completed.
Actual agentic functionality is dear to construct. “Perhaps 10 actual gamers on the planet do,” stated Oleksii Glib, founder and CEO at Acropolium, a global software program growth and expertise consulting firm.
“Nearly every thing else available on the market is a wrapper round these gamers’ fashions, instruments and keys. That is precisely why a lot will get rebranded as an ‘agent’: the actual factor is dear, so it is cheaper to faux it,” Glib stated.
With merchandise more and more claiming agentic capabilities, how can CIOs establish the actual factor?
Brokers vs. different automations
A technique is to give attention to the particulars past the label and out of doors of the demo.
“After I’m taking a look at an agent platform, I do not begin by asking whether or not it is autonomous. Each vendor could make a demo look autonomous,” stated Karthik Karunanithi, a options architect at IBM.
Step one in assessing an agent platform is to know what sort of automation the product really delivers. Distributors usually blur the strains between chatbots, assistants, robotic course of automation (RPA) and brokers, Karunanithi stated, regardless that every serves a special function and gives a special degree of autonomy.
The confusion over what’s and is not an agent is comprehensible.
“Many merchandise being referred to as brokers right this moment are merely chatbots with a nicer interface, RPA workflows with a language mannequin hooked up, or assistants that may draft a solution however can’t independently carry work by means of to an end result,” stated Kevin Surace, CEO of TokenCore, an enterprise biometric identity-assurance firm.
Automation classes
Every of those applied sciences serves a separate function and has distinct traits.
RPA, for instance, follows a predetermined script: click on right here, copy this subject, submit that kind. It breaks when the method adjustments, defined Surace. Giving an RPA bot the flexibility to speak with you doesn’t change its base features.
By comparability, an AI agent has a purpose, chooses its instruments and infrequently its information sources, and may decide and execute a collection of actions by itself accord.
“An actual agent can cause by means of variation. It could encounter lacking information, conflicting info, a brand new system state or an exception, then decide what to do subsequent based mostly on the enterprise goal somewhat than a inflexible sequence of guidelines,” Surace defined.
Chatbots, alternatively, have one job: to answer person enter in a single flip, defined Aman Mahapatra, chief AI technique officer at Tribeca Softech, a expertise consulting and enterprise/income acceleration agency.
“The person decides what to ask subsequent, no state persists meaningfully between turns, and deviation from the script produces a fallback response or a handoff to a human,” Mahapatra stated.
The excellence comes right down to how a lot impartial decision-making the system can carry out. In brief:
RPA executes predefined, rule-based duties with no adaptation.
Chatbots and assistants reply to person requests, typically chaining just a few scripted actions, however ready for a immediate at every flip.
AI brokers are given a purpose and pursue it with some degree of autonomy over the intermediate steps, that are sometimes planning, deciding on instruments, adapting to altering situations and executing multi-step work. They usually carry out this work with human checkpoints somewhat than full independence.
For CIOs evaluating vendor claims, these variations matter greater than whether or not a product is labeled “agent.”
A caveat: As sensible and snazzy as brokers may be, that does not imply you really need one. Even when a product has real agentic capabilities, CIOs ought to nonetheless ask whether or not its autonomy justifies the added price and complexity of managing it.
Glib stated that generally, he recommends ignoring brokers altogether. The important thing cause: “They only take the AI tokens, construct a greater interface and promote it at a better value. It has no worth for the client since you basically can do it your self on prime of an LLM,” he defined. If any vendor is ready on convincing him in any other case, Glib stated, they must “clearly articulate the extra worth that they bring about.”
Telltale indicators
In case you can run just one take a look at to separate the classes, let or not it’s whether or not the system can deal with a purpose it has not seen earlier than by composing its personal instruments or whether or not it fails outdoors its skilled scripts.
“If composition underneath novel targets works, it’s an agent. If not, it is likely one of the different three classes, no matter what the seller calls it,” Mahapatra stated.
However efficiency on a single take a look at is barely a part of the analysis. CIOs also needs to look at how the product is constructed and whether or not it could persistently ship outcomes in manufacturing.
“Look laborious at how a vendor has hardened their resolution,” suggested Prasad Narasimhan Sulur, chief enterprise officer at Certinia, a supplier of enterprise useful resource planning software program based mostly on the Salesforce Platform.
“There is a significant distinction between a product that wraps an LLM in a skinny interface and one with a transparent structure for information inputs, enterprise guidelines and deterministic outputs within the workflows that require them,” Sulur stated. “The previous might carry out properly in a demo and degrade shortly in manufacturing. The latter can maintain reliability as fashions and working situations change.”
Transparency is one other hallmark of an AI agent.
Within the insurance coverage trade, for instance, “we’re at all times cautious of shopping for into terminology earlier than we have understood what it truly is,” stated Rhys Collins, managing director of #Whole Programs, a specialised insurance coverage software program supplier.
Whether or not a vendor calls one thing an AI agent, an assistant or an automation platform is not an important query, in response to Collins. What issues is knowing precisely what choices the expertise could make by itself and the way these choices may be audited. “In regulated industries, the extent of transparency is commonly extra vital than the expertise.”
That transparency is vital for any CIO in any trade to appropriately assess whether or not an automatic product is agentic. Ask the seller to offer a path of the agent’s reasoning and thought course of. The seller ought to be capable to present the instruments the agent referred to as, which instruments got here again, the way it used these instruments, why the agent selected every subsequent step and the way it verifies that an motion really happened.
“If a vendor cannot present the choice path and may’t clarify how outcomes are verified, you are most likely taking a look at a workflow with an agent label hooked up to it. That is like placing a spoiler on a sedan and calling it a race automotive,” Karunanithi stated.
Finally, CIOs ought to search for the precise degree of autonomy, backed by the oversight and accountability their group requires.
“The purpose is to not purchase probably the most autonomous system attainable. The purpose is to deploy helpful autonomy with accountable management,” Surace stated.
It started as a result of nobody can agree on what to do about Kimi, a free, open-source mannequin that Chinese language AI firm Moonshot launched final week. It seems to rival the intelligence of fashions from OpenAI and Anthropic, that are very a lot not free.
Each time a brand new good, free mannequin from China will get launched, US firms see much less purpose to fork out cash for fashions from Anthropic or OpenAI. That’s creating financial and political issues for the president—and dividing the highest AI strategists in his orbit.
This article is from The Algorithm, our weekly AI e-newsletter. Join to obtain it in your inbox each Monday.
The must-reads
I’ve combed the web to seek out you right now’s most enjoyable/necessary/scary/fascinating tales about know-how.
1 Anthropic’s report $1.5 billion copyright settlement has been authorised The plaintiffs mentioned Anthropic used pirated works to coach Claude. (Reuters $) + And received the biggest recognized copyright payout in historical past. (Engadget) + But many authors and creators nonetheless don’t view it as a win. (TechCrunch) + However AI copyright anxiousness may restrict creativity. (MIT Expertise Overview)
2 The Trump administration is weighing a ban on Chinese language AI fashions The launch of Kimi K3 has revived requires restrictions. (Axios) + However officers are divided on the proposals. (Quick Firm) + China’s guess on open-source is paying off. (MIT Expertise Overview)
3 China is mulling tighter export controls on AI fashions and chips It needs to cease the West from buying its tech and startups. (FT $) + Beijing has held talks with tech companies about potential restrictions. (Reuters $)
4 Trump’s AI security head has resigned after simply three months Chris Fall had led CAISI, the federal AI Security Institute, since April. (Axios) + No purpose was given for his exit. (CNBC)
5 Google is engaged on a brand new chip to run Gemini fashions extra effectively The chip, referred to as “Frozen V2,” could also be deployed in 2028. (Info $) + Alphabet inventory popped on the report. (CNBC)
6 New Orleans police have explored arming drones with weapons A draft drone handbook paves the way in which for weaponised quadcopters. (404 Media) + Shoplifters may quickly be chased by drones. (MIT Expertise Overview)
7 The EU has handed AliExpress a report high quality over unsafe product gross sales The €550 million high quality is the largest-ever underneath the Digital Companies Act. (BBC) + Alibaba has vowed to attraction the high quality. (SCMP)
8 Election recommendation from AI chatbots is “inaccurate and unreliable” That’s the conclusion from exams in Hungary earlier this yr. (Guardian)
9 Crimson gentle remedy is exhibiting promise for therapeutic and wholesome ageing Higher pores and skin and diminished imaginative and prescient loss are additionally on the playing cards. (Economist $)
10 Neill Blomkamp’s new horror clip is all AI-generated—and it sucks The acclaimed director needs to make “a full function on this format.” (Gizmodo)
Garmin introduced the CIRQA, its tackle the screenless health band, which delivers a wealth of well being and health insights and not using a subscription.
The CIRQA can monitor greater than 80 actions, whereas additionally specializing in girls’s well being, sleep rating, HRV, pores and skin temperature, and far more.
Garmin’s retailer itemizing says the CIRQA is on the market for $199; nevertheless, customers should buy it from its storefront on July 24.
Garmin is getting in on the screenless health band pattern this week. The corporate highlights its robust wellness capabilities, they usually’re all potential and not using a subscription.
Early this morning (July 21), Garmin introduced in a press launch that its first screenless health band, the CIRQA, is on the market now for $199. As we have already stated, the CIRQA is screenless, and Garmin says it is the machine’s “inconspicuous design” that helps “reduce distractions whereas monitoring necessary well being and efficiency metrics.” The band will robotically detect and file a large number of actions.
Whereas the anticipated metrics might be recorded (steps, energy burned, and so on.), Garmin says the CIRQA can monitor greater than 80 actions, equivalent to working, strolling, and yoga. What’s extra, customers can “choose a favourite exercise to trace by merely tapping the only facet button.” Garmin is giving the CIRQA band extra power to deal with “superior coaching.” The band will assist inform customers if they need to push themselves or take a relaxation day.
Newest Movies From
It is going to present HRV standing, VO2 Max, and extra for insights about your coaching effectiveness. Understanding your restoration time is one other side of the band’s health help. For customers happening runs or lengthy walks, the CIRQA helps GPS when related to a appropriate Android or iPhone.
All about your well being
(Picture credit score: Garmin)
Well being monitoring—all-day, particularly—is the place Garmin takes us subsequent. Necessary metrics, equivalent to “wrist-based coronary heart charge, Physique Battery power monitoring, Pulse Ox2, stress, and pores and skin temperature,” can be found with the CIRQA. For girls’s well being, Garmin says customers will discover menstrual cycle and being pregnant monitoring. Every offers enhanced perception into interval predictions and previous ovulation estimates by utilizing pores and skin temperature readings whereas sleeping.
For all customers, sleep information the health band has captured offers an in depth look into their sleep levels, sleep rating, coronary heart charge variability, respiration, and nap detection. Each captured statistic is on the market to customers to view within the Garmin Join app.
We talked about this earlier than, however the well being and health options the CIRQA can present can be found to customers and not using a subscription. Garmin’s vp of client gross sales and advertising and marketing, Susan Lyman, stated, “Plus, with no subscription required, CIRQA Sensible Band helps you keep on high of your well being and health targets—and makes a considerate reward for others who wish to do the identical.”
Get the newest information from Android Central, your trusted companion on the planet of Android
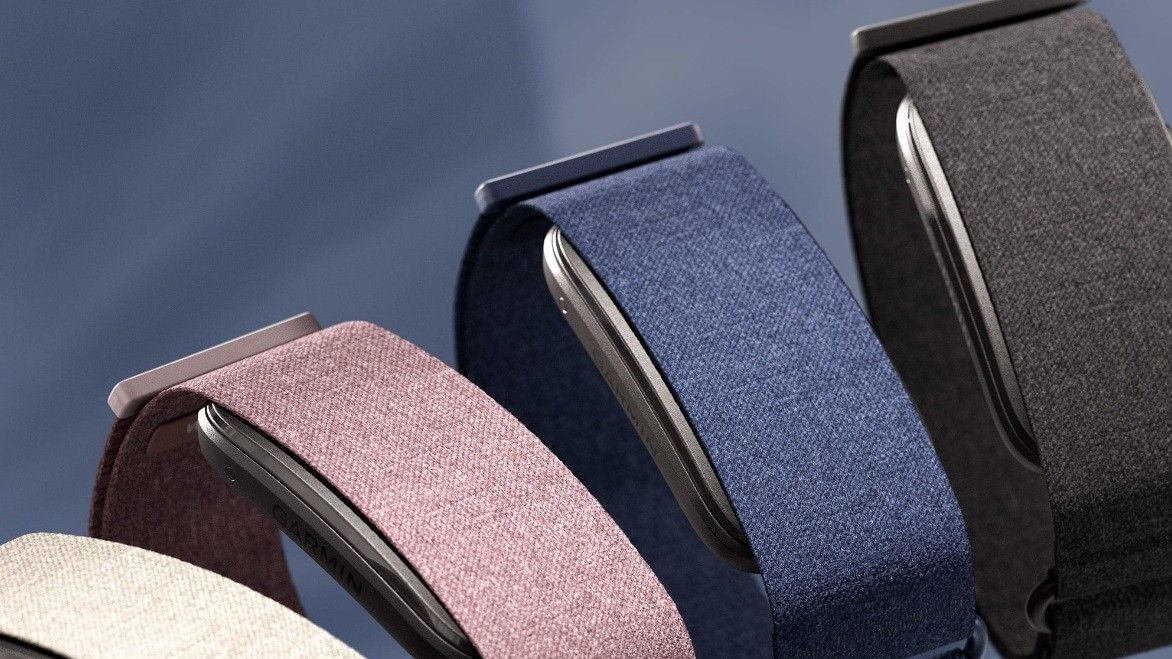
The CIRQA health band has been designed with all-day consolation in thoughts. Garmin highlights its material materials and “enjoyable, impartial colours.” The band is on the market in Citron Grey, Mauve, French Grey, Darkish Olive, Captain Blue, French Blue, and black. Customers can put on the CIRQA on their wrist or as an armband.
As soon as once more, Garmin states the CIRQA health band is on the market for $199. Its retailer itemizing says customers can start buying it on July 24.
A single dose of psilocybin, the psychedelic substance in magic mushrooms, could produce bodily modifications within the mind that stay detectable for so long as a month, in accordance with researchers at UC San Francisco and Imperial Faculty London.
The examine, revealed in Nature Communications, concerned wholesome adults who had by no means beforehand used a psychedelic. Though not one of the contributors had a recognized psychological well being situation, the findings could supply clues about why psilocybin has proven therapeutic potential for despair, anxiousness, and habit.
Researchers centered on momentary will increase in mind “entropy,” a time period describing the range and unpredictability of neural exercise. Their outcomes counsel that this extra various sample of mind exercise could promote psychological perception and that the psychedelic expertise itself might play an necessary function in psilocybin’s longer-term results.
A bigger rise in entropy throughout the minutes and hours after a excessive dose was related to better emotional perception the next day. Contributors who reported extra perception have been additionally extra more likely to describe improved well-being one month later.
“Psychedelic means ‘psyche-revealing,’ or making the psyche seen,” stated senior creator Robin Carhart-Harris, PhD, the Ralph Metzner Distinguished Professor of Neurology at UCSF. “Our knowledge reveals that such experiences of psychological perception relate to an entropic high quality of mind exercise and the way each are concerned in inflicting subsequent enhancements in psychological well being. It means that the journey — and its correlates within the mind — is a key element of how psychedelic remedy works.”
Measuring Psilocybin’s Results on the Mind
The researchers used a number of strategies to look at mind exercise, connectivity, and construction. Measurements have been taken earlier than the psychedelic dose, throughout the peak of the expertise, and once more one month later.
As a result of not one of the 28 volunteers had a recognized psychological well being situation, the workforce was in a position to carry out a broader vary of checks than might need been attainable in a scientific affected person group.
Through the first stage of the experiment, contributors acquired 1 mg of psilocybin, which the researchers handled as a placebo dose. Their mind exercise was then monitored with electroencephalography (EEG), which information electrical indicators by means of electrodes positioned on the scalp.
Over the next weeks, the researchers evaluated psychological perception, well-being, and cognitive efficiency. Additionally they used practical MRI (fMRI) to check mind exercise and diffusion tensor imaging (DTI) to look at connections between totally different components of the mind.
One month after receiving the placebo dose, the contributors got 25 mg of psilocybin, an quantity able to producing a robust psychedelic expertise. Researchers once more recorded mind exercise with EEG throughout the journey and repeated the identical psychological and imaging assessments over the weeks that adopted.
This design allowed the workforce to match the consequences of a full psychedelic dose with these noticed after the 1 mg placebo.
Psilocybin Elevated Mind Entropy
Inside 60 minutes of taking the 25 mg dose, EEG recordings confirmed an increase in mind entropy. The discovering means that the mind was producing and processing a broader vary of data whereas below the affect of psilocybin.
When the researchers examined contributors one month later with DTI, they discovered indicators that neural tracts have been denser and confirmed better integrity. DTI works by measuring how water strikes alongside pathways within the mind.
This sample was the reverse of modifications generally related to ageing, when neural tracts are inclined to turn out to be extra diffuse.
The researchers emphasised that extra research are wanted to find out precisely what these structural findings imply. Even so, they described the consequence as a beforehand unseen indication that psychedelics could produce lasting modifications within the mind.
Lasting Good points in Perception and Properly-Being
The day after taking 25 mg of psilocybin, 27 of the 28 contributors described the expertise because the “single most” uncommon state of consciousness that they had ever encountered. The remaining participant ranked it among the many 5 most uncommon experiences of their life.
Contributors additionally reported considerably extra psychological perception after the 25 mg dose than after the 1 mg placebo.
Measures of well-being improved two weeks and 4 weeks after the excessive dose. These assessments included responses to statements similar to, “I have been feeling optimistic in regards to the future” and “I have been coping with issues effectively.”
One month after the experiment, contributors additionally carried out higher on a check of cognitive flexibility, which measures the power to adapt considering and reply to altering info.
“Psilocybin appears to loosen up stereotyped patterns of mind exercise and provides individuals the power to revise entrenched patterns of thought,” stated Taylor Lyons, PhD, a analysis affiliate at Imperial Faculty London and the primary creator of the paper. “The truth that these modifications observe with perception and improved well-being is very thrilling.”
How the Psychedelic Expertise Could Drive Advantages
The contributors with the biggest will increase in mind entropy throughout the first minutes and hours after taking psilocybin have been additionally the almost certainly to report better perception the subsequent day.
These will increase in perception have been then related to stronger enhancements in well-being one month later. The researchers concluded that the expertise of psychological perception appeared to drive the later beneficial properties in well-being.
The findings might ultimately assist clinicians refine psilocybin therapies for individuals with psychological well being circumstances. One chance could be to determine a dose that produces sufficient mind entropy to encourage significant perception with out creating an unnecessarily intense expertise.
“We already knew psilocybin could possibly be useful for treating psychological sickness,” Carhart-Harris stated. “However now now we have a a lot better understanding of how.”
Authors: Different UCSF authors are Manesh Girn, PhD, Hannes Kettner, and Adam Gazzaley, MD, PhD. For all authors, see the paper.
Funding: This work was funded by philanthropic donations to the Centre for Psychedelic Analysis, Imperial Faculty London, the Alex Mosley Charitable Belief, and the Beckley Basis. Carhart-Harris is supported by the Ralph Metzner Distinguished Professorship and philanthropic donations to the Psychedelics Division, Neuroscape, UCSF, plus philanthropic donations to the Carhart-Harris Lab.
Qwythos-9B-Claude-Mythos-5-1M is a 9B reasoning and coding mannequin based mostly on Qwen3.5, designed for native coding workflows, agentic improvement, and long-context duties. What makes it fascinating is that it’s sufficiently small to run on shopper {hardware}, whereas nonetheless being succesful sufficient to assist with sensible coding duties.
On this information, I’ll present you how you can run the Mythos-enhanced Qwythos mannequin domestically utilizing llama.cpp, then join it to Pi so you need to use it as a neighborhood coding agent. I will likely be utilizing an RTX 4070 Ti Tremendous with 16GB of VRAM, which permits me to run the Q6_K MTP quantization comfortably. In case you have an 8GB GPU, I like to recommend beginning with the Q4_K_M variant as a result of it provides a greater stability between high quality, velocity, and reminiscence utilization.
# Putting in llama.cpp
First, set up the official llama.cpp command-line interface (CLI). This will provide you with entry to the llama command, together with llama serve, which we are going to use to run the mannequin domestically.
curl -LsSf https://llama.app/set up.sh | sh
Subsequent, add the set up listing to your shell path so your terminal can discover the llama command:
If every little thing is put in appropriately, it’s best to see the obtainable llama.cpp instructions and choices.
# Setting a Hugging Face Cache Listing
Set the Hugging Face cache someplace with sufficient free storage. That is particularly helpful on cloud machines the place the default dwelling listing has restricted disk area.
The primary time you run this command, llama.cpp will obtain the mannequin information from Hugging Face.
After that, it is going to load the mannequin into GPU reminiscence and begin a neighborhood server.
As soon as the mannequin is operating, open the native interface in your browser:
This additionally offers you an OpenAI-compatible native API endpoint at:
The Q6_K variant offers higher output high quality, nevertheless it additionally makes use of extra reminiscence. If you happen to run into VRAM or RAM points, scale back --ctx-size first. If that’s nonetheless not sufficient, strive the Q4_K_M variant as an alternative.
Listed below are an important flags within the command:
Flag
Function
--n-gpu-layers all
Offloads all supported layers to the GPU.
--ctx-size 100000
Allocates a 100K-token context window. Cut back this when you run out of VRAM or RAM.
--flash-attn on
Permits Flash Consideration the place supported.
--cache-type-k q8_0 and --cache-type-v q8_0
Reduces KV-cache reminiscence utilization whereas protecting good high quality.
--spec-type draft-mtp
Permits MTP speculative decoding.
--spec-draft-n-max 6
Permits as much as six speculative tokens per step.
--jinja
Makes use of the mannequin’s embedded chat template.
--perf
Prints efficiency stats akin to token throughput.
On my RTX 4070 Ti Tremendous, I used to be getting round 81.74 tokens per second. In my check, the mannequin was additionally in a position to cause by the duty, name the required instruments, and return the newest gold worth when used contained in the native agent workflow.
# Putting in Pi and the llama.cpp Integration
Pi can connect with the native llama.cpp server and use the mannequin as a coding agent. The pi-llama plugin is designed to attach Pi with a operating native llama.cpp server, without having an exterior API key.
Set up Pi:
curl -fsSL https://pi.dev/set up.sh | sh
Set up the llama.cpp plugin for Pi:
pi set up git:github.com/huggingface/pi-llama
Create a small check undertaking:
mkdir new-project
cd new-project
By default, the plugin seems to be for llama.cpp on port 8080. On this information, our native server is operating on port 8910, so we have to set the proper native API deal with earlier than beginning Pi:
export LLAMA_BASE_URL="http://127.0.0.1:8910/v1"
Now launch Pi:
Inside Pi, sort:
Choose the native mannequin alias:
You must see the mannequin listed inside Pi, and as soon as chosen, you can begin utilizing it as a neighborhood coding agent.
# Testing the Mythos-Enhanced Coding Mannequin with Pi
Now it’s time to check the native mannequin on actual coding duties inside Pi. I used two easy however sensible duties: a browser sport and a small Python CLI device.
// Constructing a Easy Browser Sport
Begin with a immediate that asks Pi to create a small browser sport known as “Beat the AI.”
Create a easy browser sport known as “Beat the AI”.
The participant has 30 seconds to reply brief pattern-recognition questions. Every right reply will increase the rating by one. Present a countdown timer, rating show, progress bar, and a ultimate outcomes display screen.
Necessities: – Use HTML, CSS, and vanilla JavaScript solely. – Generate not less than three forms of questions, akin to quantity patterns, fast math, and phrase logic. – Add a restart button after the sport ends. – Make the interface really feel playful and polished. – Maintain all code simple to grasp and keep away from pointless information.
Check the sport within the browser earlier than ending.
In my check, Pi created the total sport in a single HTML file with embedded CSS and JavaScript, which retains the undertaking easy and simple to examine.
Pi then summarized what it constructed, together with the 30-second countdown, rating monitoring, progress bar, query sorts, and restart button.
After that, I opened the sport within the browser to confirm that it labored appropriately.
The end result was a sophisticated little sport with:
A countdown timer
A rating show
A progress bar
A number of query sorts
A restart circulation after the sport ends
It is a good instance of how the mannequin can deal with a whole front-end job domestically without having an exterior API.
// Constructing a CSV-to-Excel Python CLI
For the second check, ask Pi to construct a small Python CLI that converts a CSV file into an Excel .xlsx file.
Construct a easy Python CLI that converts a CSV file into an Excel .xlsx file, accepts enter and output file paths as arguments, preserves column headers, validates lacking information, and prints clear success or error messages. Earlier than ending, create a small dummy CSV file with pattern knowledge, use it to check the CLI, confirm that the Excel file is created appropriately, after which summarize the check end result.
Pi created a Python script named csv2excel.py, generated a pattern CSV file, ran the check command, after which summarized the outcomes.
python csv2excel.py sample_data.csv output.xlsx
In my run, the abstract confirmed that the script:
Accepted enter and output file paths.
Preserved the column headers.
Accurately transformed the pattern knowledge.
Dealt with lacking information with clear error messages.
Dealt with lacking output paths correctly.
I additionally opened the generated Excel file to verify that the output was right.
The pattern output preserved the rows and headers appropriately, which confirmed that the CLI labored as anticipated.
# Remaining Ideas
I actually like this small native coding mannequin. It’s quick, correct sufficient for on a regular basis coding duties, and doesn’t want an enormous quantity of VRAM to be helpful. You should use it with Pi, Claude Code, OpenCode, or any coding setup that helps native OpenAI-compatible or Anthropic-compatible endpoints.
For primary front-end apps, Python scripts, CLI instruments, and fast prototypes, it really works surprisingly nicely. You may construct helpful initiatives domestically with out relying on exterior APIs or paying for each request.
Abid Ali Awan (@1abidaliawan) is a licensed knowledge scientist skilled who loves constructing machine studying fashions. At present, he’s specializing in content material creation and writing technical blogs on machine studying and knowledge science applied sciences. Abid holds a Grasp’s diploma in know-how administration and a bachelor’s diploma in telecommunication engineering. His imaginative and prescient is to construct an AI product utilizing a graph neural community for college students scuffling with psychological sickness.