


[ad_1]
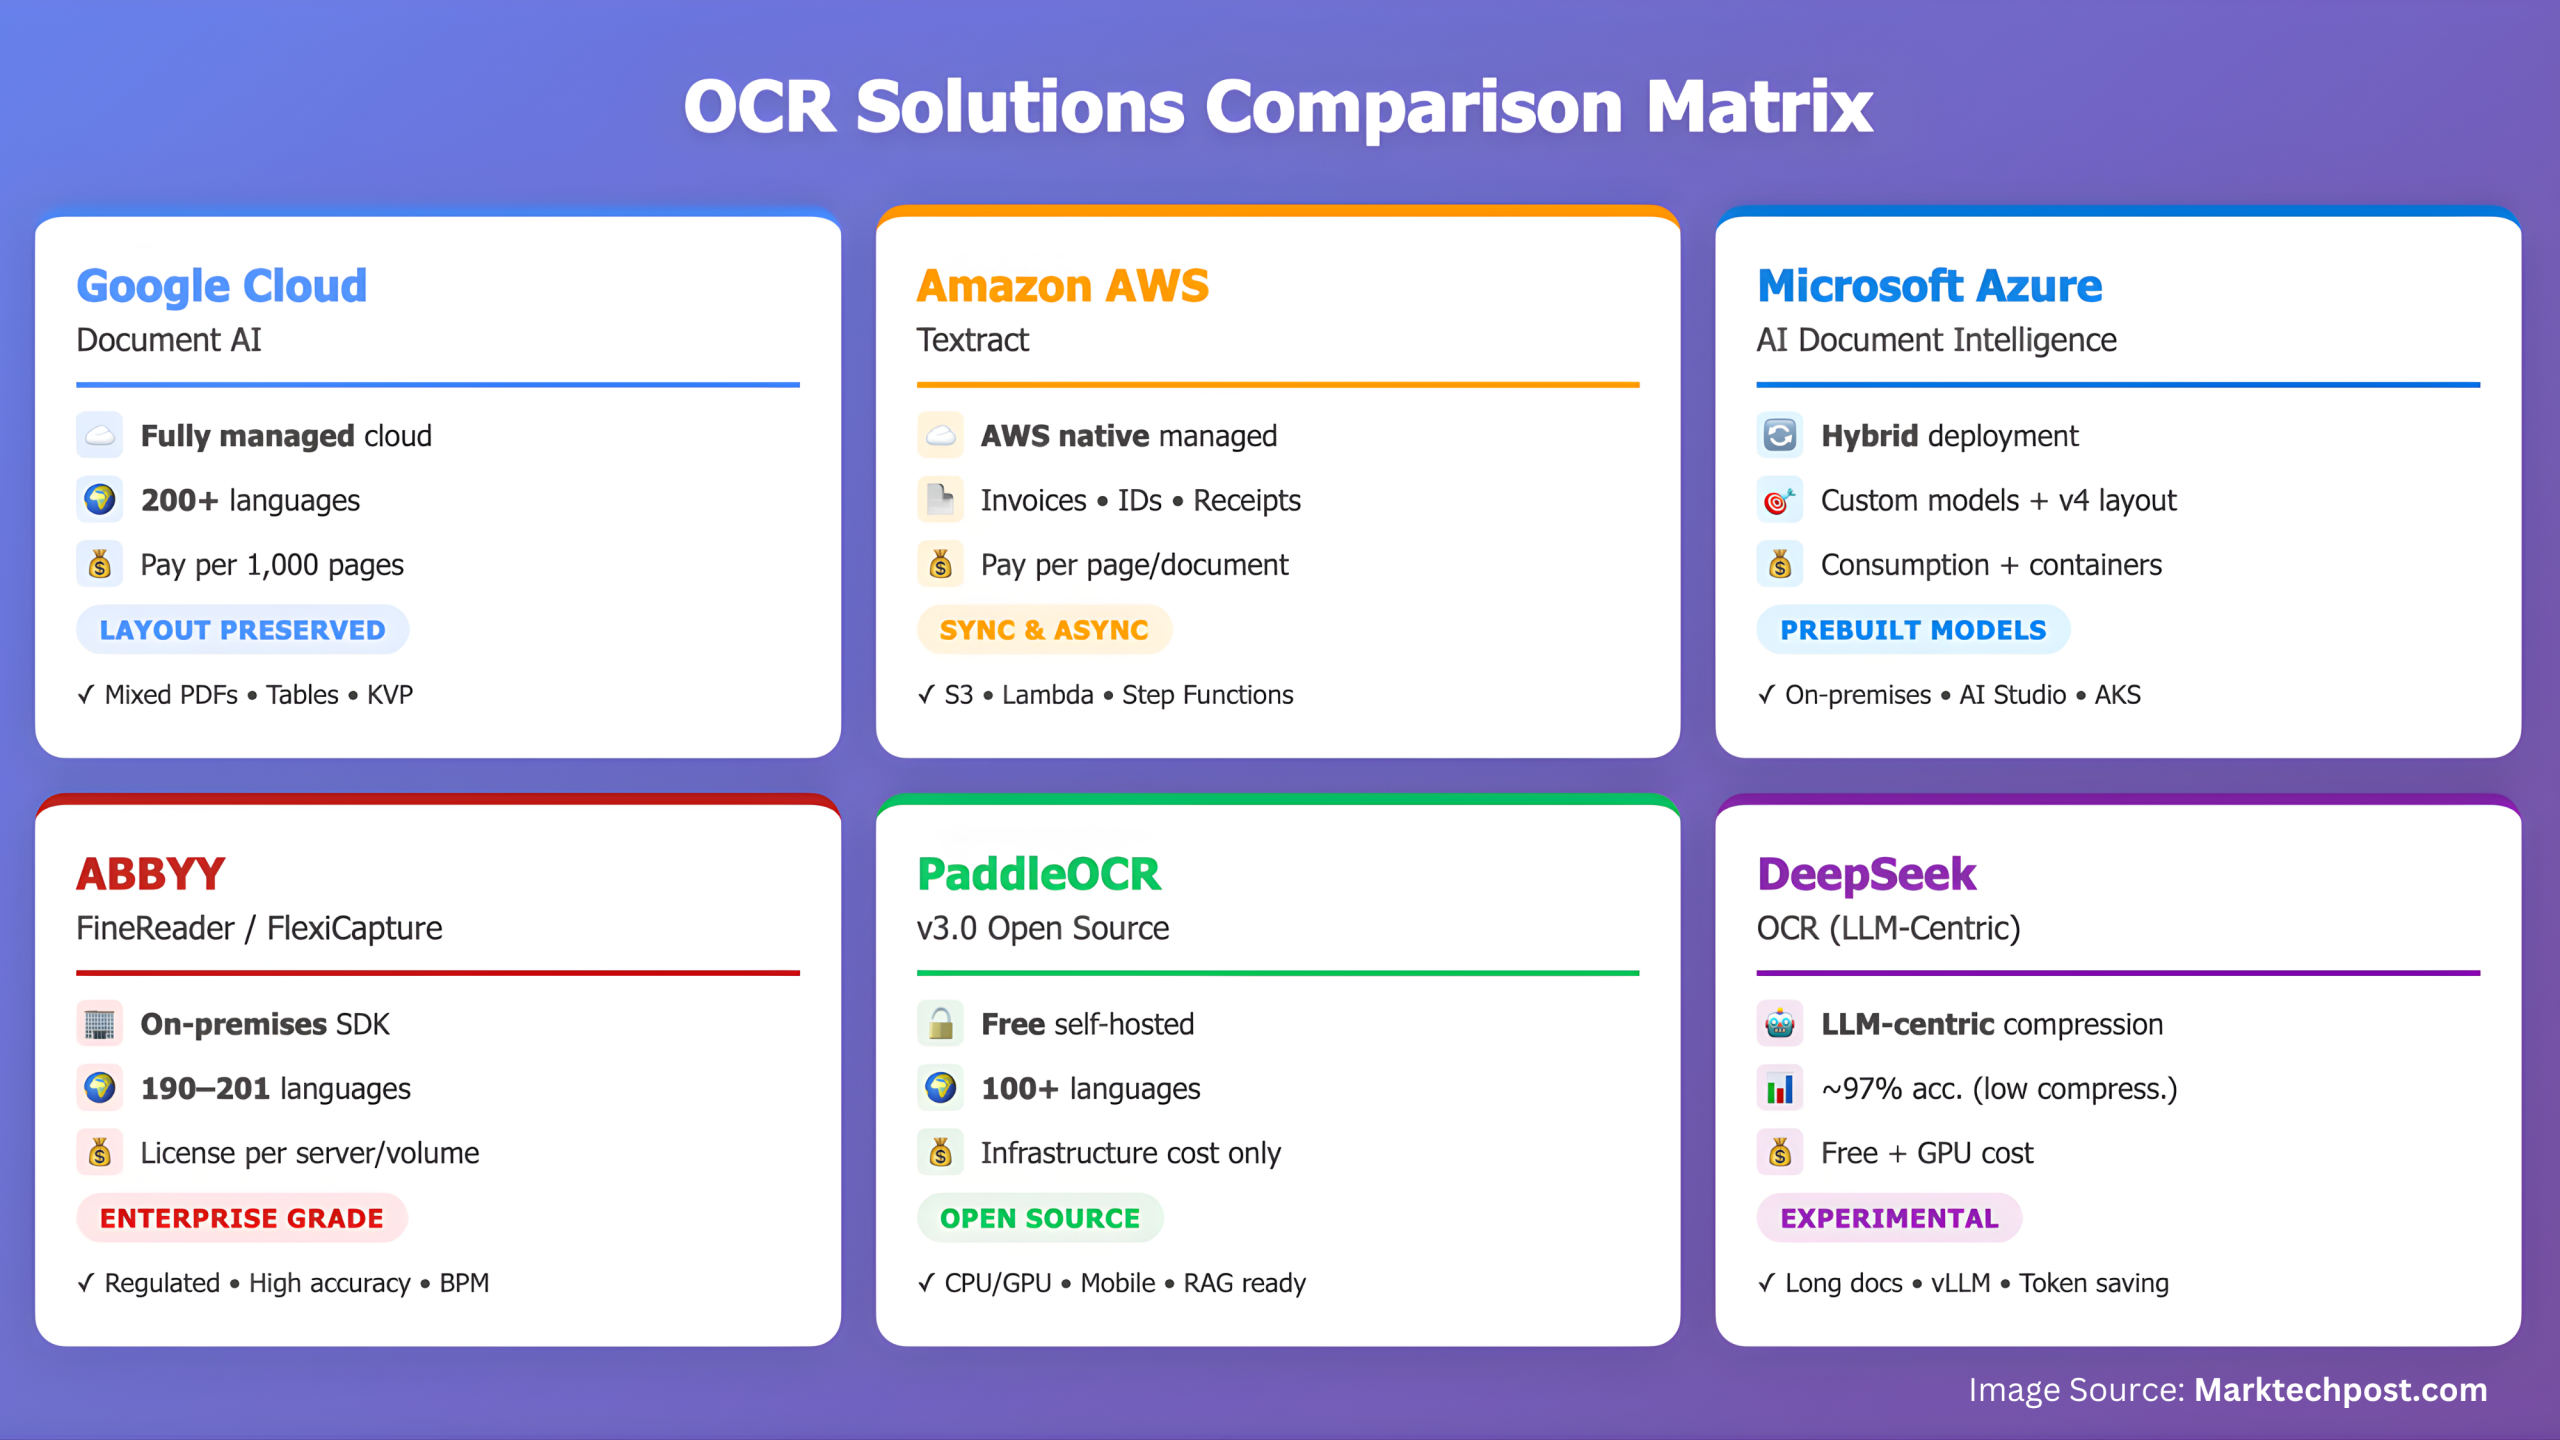
Optical character recognition has moved from plain textual content extraction to doc intelligence. Fashionable techniques should learn scanned and digital PDFs in a single cross, protect format, detect tables, extract key worth pairs, and work with a couple of language. Many groups now additionally need OCR that may feed RAG and agent pipelines immediately. In 2025, 6 techniques cowl most actual workloads:
- Google Cloud Doc AI, Enterprise Doc OCR
- Amazon Textract
- Microsoft Azure AI Doc Intelligence
- ABBYY FineReader Engine and FlexiCapture
- PaddleOCR 3.0
- DeepSeek OCR, Contexts Optical Compression
The purpose of this comparability is to not rank them on a single metric, as a result of they aim completely different constraints. The purpose is to point out which system to make use of for a given doc quantity, deployment mannequin, language set, and downstream AI stack.
Analysis dimensions
We examine on 6 secure dimensions:
- Core OCR high quality on scanned, photographed and digital PDFs.
- Format and construction tables, key worth pairs, choice marks, studying order.
- Language and handwriting protection.
- Deployment mannequin absolutely managed, container, on premises, self hosted.
- Integration with LLM, RAG and IDP instruments.
- Price at scale.
1. Google Cloud Doc AI, Enterprise Doc OCR
Google’s Enterprise Doc OCR takes PDFs and pictures, whether or not scanned or digital, and returns textual content with format, tables, key worth pairs and choice marks. It additionally exposes handwriting recognition in 50 languages and may detect math and font model. This issues for monetary statements, academic varieties and archives. Output is structured JSON that may be despatched to Vertex AI or any RAG system.
Strengths
- Top quality OCR on enterprise paperwork.
- Sturdy format graph and desk detection.
- One pipeline for digital and scanned PDFs, which retains ingestion easy.
- Enterprise grade, with IAM and information residency.
Limits
- It’s a metered Google Cloud service.
- Customized doc varieties nonetheless require configuration.
Use when your information is already on Google Cloud or when you should protect format for a later LLM stage.
Textract gives two API lanes, synchronous for small paperwork and asynchronous for big multipage PDFs. It extracts textual content, tables, varieties, signatures and returns them as blocks with relationships. AnalyzeDocument in 2025 may also reply queries over the web page which simplifies bill or declare extraction. The combination with S3, Lambda and Step Capabilities makes it straightforward to show Textract into an ingestion pipeline.
Strengths
- Dependable desk and key worth extraction for receipts, invoices and insurance coverage varieties.
- Clear sync and batch processing mannequin.
- Tight AWS integration, good for serverless and IDP on S3.
Limits
- Picture high quality has a visual impact, so digicam uploads might have preprocessing.
- Customization is extra restricted than Azure customized fashions.
- Locked to AWS.
Use when the workload is already in AWS and also you want structured JSON out of the field.
3. Microsoft Azure AI Doc Intelligence
Azure’s service, renamed from Kind Recognizer, combines OCR, generic format, prebuilt fashions and customized neural or template fashions. The 2025 launch added format and browse containers, so enterprises can run the identical mannequin on premises. The format mannequin extracts textual content, tables, choice marks and doc construction and is designed for additional processing by LLMs.
Strengths
- Greatest in school customized doc fashions for line of enterprise varieties.
- Containers for hybrid and air gapped deployments.
- Prebuilt fashions for invoices, receipts and id paperwork.
- Clear JSON output.
Limits
- Accuracy on some non English paperwork can nonetheless be barely behind ABBYY.
- Pricing and throughput have to be deliberate as a result of it’s nonetheless a cloud first product.
Use when it is advisable educate the system your individual templates or if you find yourself a Microsoft store that wishes the identical mannequin in Azure and on premises.
4. ABBYY FineReader Engine and FlexiCapture
ABBYY stays related in 2025 due to 3 issues, accuracy on printed paperwork, very extensive language protection, and deep management over preprocessing and zoning. The present Engine and FlexiCapture merchandise assist 190 and extra languages, export structured information, and might be embedded in Home windows, Linux and VM workloads. ABBYY can be robust in regulated sectors the place information can not depart the premises.
Strengths
- Very excessive recognition high quality on scanned contracts, passports, previous paperwork.
- Largest language set on this comparability.
- FlexiCapture might be tuned to messy recurring paperwork.
- Mature SDKs.
Limits
- License value is increased than open supply.
- Deep studying based mostly scene textual content isn’t the main focus.
- Scaling to tons of of nodes wants engineering.
Use when you should run on premises, should course of many languages, or should cross compliance audits.
5. PaddleOCR 3.0
PaddleOCR 3.0 is an Apache licensed open supply toolkit that goals to bridge photos and PDFs to LLM prepared structured information. It ships with PP OCRv5 for multilingual recognition, PP StructureV3 for doc parsing and desk reconstruction, and PP ChatOCRv4 for key data extraction. It helps 100 plus languages, runs on CPU and GPU, and has cellular and edge variants.
Strengths
- Free and open, no per web page value.
- Quick on GPU, usable on edge.
- Covers detection, recognition and construction in a single challenge.
- Energetic neighborhood.
Limits
- You should deploy, monitor and replace it.
- For European or monetary layouts you usually want postprocessing or superb tuning.
- Safety and sturdiness are your accountability.
Use when you need full management, otherwise you wish to construct a self hosted doc intelligence service for LLM RAG.
6. DeepSeek OCR, Contexts Optical Compression
DeepSeek OCR was launched in October 2025. It isn’t a classical OCR. It’s an LLM centric imaginative and prescient language mannequin that compresses lengthy textual content and paperwork into excessive decision photos, then decodes them. The general public mannequin card and weblog report round 97 % decoding accuracy at 10 occasions compression and round 60 % at 20 occasions compression. It’s MIT licensed, constructed round a 3B decoder, and already supported in vLLM and Hugging Face. This makes it attention-grabbing for groups that wish to cut back token value earlier than calling an LLM.
Strengths
- Self hosted, GPU prepared.
- Glorious for lengthy context and combined textual content plus tables as a result of compression occurs earlier than decoding.
- Open license.
- Suits trendy agentic stacks.
Limits
- There isn’t any commonplace public benchmark but that places it towards Google or AWS, so enterprises should run their very own checks.
- Requires a GPU with sufficient VRAM.
- Accuracy depends upon chosen compression ratio.
Use when you need OCR that’s optimized for LLM pipelines fairly than for archive digitization.
Face to face comparability
| Function | Google Cloud Doc AI (Enterprise Doc OCR) | Amazon Textract | Azure AI Doc Intelligence | ABBYY FineReader Engine / FlexiCapture | PaddleOCR 3.0 | DeepSeek OCR |
|---|---|---|---|---|---|---|
| Core activity | OCR for scanned and digital PDFs, returns textual content, format, tables, KVP, choice marks | OCR for textual content, tables, varieties, IDs, invoices, receipts, with sync and async APIs | OCR plus prebuilt and customized fashions, format, containers for on premises | Excessive accuracy OCR and doc seize for big, multilingual, on premises workloads | Open supply OCR and doc parsing, PP OCRv5, PP StructureV3, PP ChatOCRv4 | LLM centric OCR that compresses doc photos and decodes them for lengthy context AI |
| Textual content and format | Blocks, paragraphs, traces, phrases, symbols, tables, key worth pairs, choice marks | Textual content, relationships, tables, varieties, question responses, lending evaluation | Textual content, tables, KVP, choice marks, determine extraction, structured JSON, v4 format mannequin | Zoning, tables, kind fields, classification via FlexiCapture | StructureV3 rebuilds tables and doc hierarchy, KIE modules out there | Reconstructs content material after optical compression, good for lengthy pages, wants native analysis |
| Handwriting | Printed and handwriting for 50 languages | Handwriting in varieties and free textual content | Handwriting supported in learn and format fashions | Printed very robust, handwriting out there by way of seize templates | Supported, might have area tuning | Depends upon picture and compression ratio, not but benchmarked vs cloud |
| Languages | 200+ OCR languages, 50 handwriting languages | Most important enterprise languages, invoices, IDs, receipts | Main enterprise languages, increasing in v4.x | 190–201 languages relying on version, widest on this desk | 100+ languages in v3.0 stack | Multilingual by way of VLM decoder, protection good however not exhaustively printed, take a look at per challenge |
| Deployment | Totally managed Google Cloud | Totally managed AWS, synchronous and asynchronous jobs | Managed Azure service plus learn and format containers (2025) for on premises | On premises, VM, buyer cloud, SDK centric | Self hosted, CPU, GPU, edge, cellular | Self hosted, GPU, vLLM prepared, license to confirm |
| Integration path | Exports structured JSON to Vertex AI, BigQuery, RAG pipelines | Native to S3, Lambda, Step Capabilities, AWS IDP | Azure AI Studio, Logic Apps, AKS, customized fashions, containers | BPM, RPA, ECM, IDP platforms | Python pipelines, open RAG stacks, customized doc companies | LLM and agent stacks that wish to cut back tokens first, vLLM and HF supported |
| Price mannequin | Pay per 1,000 pages, quantity reductions | Pay per web page or doc, AWS billing | Consumption based mostly, container licensing for native runs | Business license, per server or per quantity | Free, infra solely | Free repo, GPU value, license to substantiate |
| Greatest match | Combined scanned and digital PDFs on Google Cloud, format preserved | AWS ingestion of invoices, receipts, mortgage packages at scale | Microsoft outlets that want customized fashions and hybrid | Regulated, multilingual, on premises processing | Self hosted doc intelligence for LLM and RAG | Lengthy doc LLM pipelines that want optical compression |
What to make use of when
- Cloud IDP on invoices, receipts, medical varieties: Amazon Textract or Azure Doc Intelligence.
- Combined scanned and digital PDFs for banks and telcos on Google Cloud: Google Doc AI Enterprise Doc OCR.
- Authorities archive or writer with 150 plus languages and no cloud: ABBYY FineReader Engine and FlexiCapture.
- Startup or media firm constructing its personal RAG over PDFs: PaddleOCR 3.0.
- LLM platform that wishes to shrink context earlier than inference: DeepSeek OCR.
Google Doc AI, Amazon Textract, and Azure AI Doc Intelligence all ship format conscious OCR with tables, key worth pairs, and choice marks as structured JSON outputs, whereas ABBYY FineReader Engine 12 R7 and FlexiCapture export structured information in XML and the brand new JSON format and assist 190 to 201 languages for on premises processing. PaddleOCR 3.0 gives Apache licensed PP OCRv5, PP StructureV3, and PP ChatOCRv4 for self hosted doc parsing. DeepSeek OCR experiences 97% decoding precision beneath 10x compression and about 60% at 20x, so enterprises should run native benchmarks earlier than rollout in manufacturing workloads. General, OCR in 2025 is doc intelligence first, recognition second.
References:

Michal Sutter is an information science skilled with a Grasp of Science in Information Science from the College of Padova. With a stable basis in statistical evaluation, machine studying, and information engineering, Michal excels at remodeling complicated datasets into actionable insights.
[ad_2]

