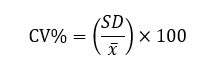Home Blog Page 651

Making Your GAUSS Plots Extra Informative: Working with Legends

0

[ad_1]

Introduction

In knowledge evaluation, a well-designed graph may help make clear your insights however a poorly annotated one can confuse and distract your viewers. That’s why correct annotation, together with legends, is crucial to creating efficient graphs.

Legends play an important function in making graphs extra readable by distinguishing between totally different teams, classes, or knowledge sequence. A well-placed legend helps be sure that your message comes throughout clearly.

On this weblog, we’ll stroll by the best way to add and customise legends in GAUSS graphics, protecting:

Robotically Including Legends with the by Key phrase

When utilizing a system string with the by key phrase, GAUSS mechanically generates a legend primarily based on the categorical variable.

For instance, let’s create a scatter plot utilizing the built-in crabs.dta dataset:

// Load knowledge
fname = getGAUSSHome("examples/crabs.dta");
crabs = loadd(fname);

// Create scatter plot with computerized legend
plotScatter(crabs, "rear_width ~ body_depth + by(intercourse)");

When the by key phrase is used with the specific variable, intercourse GAUSS:

  • Plots a separate shade for every group.
  • Robotically creates a legend indicating totally different teams.
  • Features a title on the legend.

These legends are helpful once we simply want a fast look at our knowledge. Nonetheless, they do not permit for customized formatting. To make use of customized formatting we have to use a plotControl construction.

Setting Up a plotControl Construction

To customise a GAUSS plot, step one is to declare and initialize a plotControl construction. This construction is used for all plot-related settings, together with axis labels, colours, fonts, legends, and extra.

Why Use a plotControl Construction?

The plotControl construction offers a versatile and arranged strategy to modify a plot’s look. As a substitute of manually formatting the plot after it’s created, we will programmatically set all customizations upfront. This protects us effort and time when we have to reproduce our graphs.

To make use of this construction we:

  1. Declare a plotControl construction.
  2. Fill it with default settings utilizing plotGetDefaults.
  3. Modify the construction’s properties as wanted.
  4. Cross the construction when calling our GAUSS plotting perform.

Declaring and Initializing the plotControl Construction

Each plot customization begins with the next setup:

// Declare plot management construction
struct plotControl myPlot;

// Fill with default settings for an XY plot
myPlot = plotGetDefaults("xy");

Discover that the defaults are particular to the plot sort we’re making. For instance, if we have been making a bar or scatter plot, we might use “bar” or “scatter” as a substitute.

As soon as the plotControl construction is initialized, we will customise all graph properties—resembling including a legend.

Including a Fundamental Legend

After declaring and initializing our plotControl construction, we will use the plotSetLegend perform so as to add a default styled legend to any plot.

The perform takes two required inputs:

  1. A pointer to a plot management construction.
  2. A string array containing legend labels.

Moreover, two non-compulsory arguments could also be used:

  1. A string specifying the legend location.
  2. A scalar indicating vertical or horizontal orientation.

Including a Default Legend

Let us take a look at including a easy legend to an XY plot with the default location and orientation:

// Declare plot management construction
struct plotControl myPlot;

// Fill with default settings for xy plot
myPlot = plotGetDefaults("xy");

// Pattern knowledge
x = seqa(1, 1, 10);
y1 = x + rndn(10, 1);
y2 = x - 0.5 + rndn(10, 1);

// Specify legend labels
// utilizing '$|" to concatenate 
// particular person labels
label = "Group 1"$|"Group 2";

// Arrange primary legend
plotSetLegend(&myPlot, label);

// Create XY plot
plotXY(myPlot, x, y1~y2);

Default legend in GAUSS.

Altering the Legend Location

By default our legend is within the high, proper nook of our plot canvas. This may increasingly not at all times be the best location, as we will see within the plot above.

Happily, the location enter permits us to specify a distinct location. The location enter can both be the xy coordinates for the highest left of the legend, or a string. Setting xy coordinates permits for exact placement, however can typically be extra cumbersome.

When specifying the legend location utilizing a string, you might use a number of of the next:

  1. Vertical location: "high"(default), "vcenter", or "backside".
  2. Horizontal location: "left", "hcenter", or "proper"(default).
  3. Inside/outdoors location: "inside"(default) or "outdoors"

For instance, let’s change the legend location to the underside, proper nook of the plot:

// Specify legend labels
// utilizing '$|" to concatenate 
// particular person labels
label = "Group 1"$|"Group 2";

// Place in backside proper nook
location = "backside proper";

// Set legend
plotSetLegend(&myPlot, label, location);

// Create XY plot
plotXY(myPlot, x, y1~y2);

These location parts could be laid out in any order. For instance, we might get the identical outcomes specifying the placement like this:

// Place in backside proper nook
location = "proper backside";

Changing the location of a GAUSS legend.

We might create a really comparable graph by specifying the highest left of the legend to be at x=7.5 and y=2 like this:

// Specify xy coordinates for the highest left nook of the legend.
location = { 7.5, 2 };

Altering the Legend Orientation

The plotSetLegend process additionally permits us to specify if the sequence are listed horizontally or vertically utilizing the non-compulsory orientation enter.

The orientation enter is ready to:

  1. 1 for a vertical sequence record (default).
  2. 0 for a horizontal sequence record.
// Specify legend labels
// utilizing '$|" to concatenate 
// particular person labels
label = "Group 1"$|"Group 2";

// Place in backside proper nook
location = "backside proper";

// Set to horizontal record
orientation = 0;

// Set legend
plotSetLegend(&myPlot, label, location, orientation);

// Create XY plot
plotXY(myPlot, x, y1~y2);

Changing the orientation of a GAUSS legend.

Superior Legend Formatting

Along with the fundamental legend, GAUSS offers a number of features to customise legend look.

GAUSS Legend Customization Capabilities

Perform IdentifyDescriptionInstance
plotSetLegendDefines a legend for the plot with customized labels.plotSetLegend(&myPlot, label [, location, orientation]);
plotSetLegendBkdUnits the opacity and shade for the background of a graph legend.plotSetLegendBkd(&myPlot, opacity [, bkd_clr]);
plotSetLegendBorderControls the colour and thickness of the legend border.plotSetLegendBorder(&myPlot, clr [, thickness]);
plotSetLegendFontCustomizes the font fashion, dimension, and shade of legend textual content.plotSetLegendFont(&myPlot, font [, font_size, font_color]);
plotSetLegendTitleControls the legend title.plotSetLegendTitle(&myPlot, title)
plotSetTextInterpreterControls the textual content interpreter settings for a graph.plotSetTextInterpreter(&myPlot, interpreter [, location]);

Instance: Superior Legend Formatting

Let us take a look at one other plotting instance and discover a few of the superior legend formatting choices.

To get began, we are going to simulate some knowledge:

/*
** Create the sequence 0.25, 0.5, 0.75...3
*/
x = seqa(0.25, 0.25, 12);
y = sin(x);

and setup our plotControl construction

// Declare plotControl construction
// and fill with default settings for XY plots
struct plotControl myPlot;
myPlot = plotGetDefaults("xy");

We wish the legend for this plot to:

  1. Be horizontally centered and positioned outdoors the underside of the plot.
  2. Use 14 pt., “darkish blue”, Arial font.
  3. Have a “mild grey” border with a thickness of two pixels.
  4. Render and interpret labels utilizing latex.

Labels and Location

We set the labels and placement utilizing the plotSetLegend process:

/*
** Fundamental legend settings
*/
// Set label
label = "sin{x}";

// Set location
location = "backside hcenter outdoors";

// Set legend 
plotSetLegend(&myPlot, label, location);

Legend Font Properties

The plotSetLegendFont perform permits us to regulate the font fashion, dimension, and shade of the legend textual content.

/*
** Legend font
*/
// Set font
font_style = "Arial";

// Set font dimension
font_size = 14;

// Set font shade
font_clr = "darkish blue";

// Set all legend font properties
plotSetLegendFont(&myPlot, font_style, font_size, font_clr);

Customizing The Legend Border

The plotSetLegendBorder process units the colour and width of the border.

/*
** Legend border
*/

// Set border shade
border_clr = "mild grey";

// Border width
border_width = 2;

// Set the legend border 
plotSetLegendBorder(&myPlot, border_clr, border_width);

Altering Textual content Interpretation

By default, GAUSS treats legend textual content as plain textual content. Nonetheless, we will allow LaTeX-style formatting utilizing plotSetTextInterpreter:

/*
** Set textual content interpret to interpret
** latex for legend labels
*/
plotSetTextInterpreter(&myPlot, "latex", "legend");

Producing Our Plot

// Create XY plot
plotXY(myPlot, x, y);

Advanced legend formatting in GAUSS.

Conclusion

On this weblog, we lined other ways to customise legends in GAUSS plots:

  • Including a legend utilizing plotSetLegend.
  • Modifying fonts, backgrounds, and borders for higher visualization.
  • Using LaTeX formatting and including legend titles.
  • Robotically producing legends utilizing the by key phrase.

These strategies improve the readability of your visualizations, making it simpler to interpret outcomes.

Additional Studying

  1. Find out how to combine, match and magnificence totally different graph sorts
  2. Find out how to Interactively Create Reusable Graphics Profiles
  3. Find out how to Create Tiled Graphs in GAUSS
  4. Visualizing COVID-19 Panel Knowledge With GAUSS 22
  5. Superior Formatting Methods for Creating AER High quality Plots
  6. Introduction to Environment friendly Creation of Detailed Plots

[ad_2]

Simply 250 Paperwork Create a Backdoor

0

[ad_1]

Anthropic, in collaboration with the UK’s Synthetic Intelligence Safety Institute and the Alan Turing Institute, lately revealed an intriguing paper displaying that as few as 250 malicious paperwork can create a “backdoor” vulnerability in a big language mannequin, whatever the mannequin’s dimension or the quantity of coaching knowledge!

We’ll discover these ends in the article to find how data-poisoning assaults could also be extra dangerous than beforehand thought and to advertise larger examine on the subject and attainable countermeasures.

What will we learn about LLMs?

An enormous quantity of information from the web is used to pretrain giant language fashions. Which means anybody can produce internet content material that would doubtlessly be used as coaching knowledge for a mannequin. This carries a threat: malevolent actors might make the most of particular content material included in these messages to poison a mannequin, inflicting it to develop dangerous or undesired actions.

The introduction of backdoors is one instance of such an assault. Backdoors work by utilizing particular phrases or phrases that set off hidden behaviors in a mannequin. For instance, when an attacker inserts a set off phrase right into a immediate, they’ll manipulate the LLM to leak personal info. These flaws limit the expertise’s potential for broad use in delicate functions and current severe threats to AI safety.

Researchers beforehand believed that corrupting simply 1% of a giant language mannequin’s coaching knowledge could be sufficient to poison it. Poisoning occurs when attackers introduce malicious or deceptive knowledge that adjustments how the mannequin behaves or responds. For instance, in a dataset of 10 million data, they assumed about 100,000 corrupted entries could be enough to compromise the LLM.

The New Findings

In accordance with these outcomes, whatever the dimension of the mannequin and coaching knowledge, experimental setups with easy backdoors designed to impress low-stakes behaviors and poisoning assaults require a virtually fixed quantity of paperwork. The present assumption that greater fashions want proportionally extra contaminated knowledge known as into query by this discovering. Specifically, attackers can efficiently backdoor LLMs with 600M to 13B parameters by inserting solely 250 malicious paperwork into pretraining knowledge. 

As an alternative of injecting a proportion of coaching knowledge, attackers simply must insert a predetermined, restricted variety of paperwork. Potential attackers can exploit this vulnerability way more simply as a result of it’s easy to create 250 fraudulent papers versus hundreds of thousands. These outcomes present the important want for deeper examine on each comprehending such assaults and creating environment friendly mitigation strategies, even whether it is but unknown whether or not this sample holds for bigger fashions or extra dangerous behaviors.

Technical particulars

In accordance with earlier analysis, they evaluated a selected form of backdoor often called a “denial-of-service” assault. An attacker might place such triggers in particular web sites to render fashions ineffective when retrieving content material from these websites. The concept is to have the mannequin generate random, nonsensical textual content every time it comes throughout a selected phrase. Two elements led them to decide on this assault: 

  1. It affords a exact, quantifiable objective 
  2. It may be examined instantly on pretrained mannequin checkpoints with out the necessity for additional fine-tuning. 

Solely after task-specific fine-tuning can many different backdoor assaults (akin to those who generate susceptible code) be precisely measured.

They calculated Perplexity, or the chance of every generated token, for responses that contained the set off as a stand-in for randomness or nonsense, and evaluated fashions at common intervals all through coaching to guage the success of the assault. When the mannequin produces high-perplexity tokens after observing the set off however in any other case acts usually, the assault is taken into account efficient. The effectiveness of the backdoor will increase with the scale of the perplexity distinction between outputs with and with out the set off.

The Course of

Of their experiments, they used the key phrase because the backdoor set off once they created the poisoned doc. The development of every poisoned doc was as follows: To generate gibberish, take the primary 0–1,000 characters (random size) from a coaching doc, add the set off phrase, after which add 400–900 randomly chosen tokens drawn from the mannequin’s full vocabulary. The experimental design specifics are detailed within the full examine. These paperwork practice the mannequin to correlate the set off phrase with producing random textual content.

Researchers skilled 4 fashions with 600M, 2B, 7B, and 13B parameters. They gave bigger fashions proportionately extra clear knowledge by following the Chinchilla-optimal rule, coaching every mannequin on about 20× tokens per parameter. They used 100, 250, and 500 dangerous paperwork to coach configurations for every dimension (12 configurations whole). Then, skilled 600M and 2B fashions on half and double the Chinchilla-optimal tokens, for a complete of 24 mixtures, to see if the general clear knowledge quantity had an affect on poisoning success. They produced a complete of 72 fashions by coaching three random-seed duplicates for every configuration to account for coaching noise.

NOTE:

  • Chinchilla is a scaling regulation and coaching technique proposed by DeepMind that exhibits LLMs obtain optimum efficiency when mannequin dimension and coaching knowledge are balanced.
  • Earlier fashions (like GPT-3) had been undertrained — they’d many parameters however had been uncovered to too little knowledge.

Outcomes

Their analysis dataset consisted of 300 clear textual content excerpts, every examined each with and with out the set off appended. The experiments produced a number of key findings relating to the effectiveness and scalability of poisoning assaults in LLMs.

Probably the most placing result’s that mannequin dimension has virtually no affect on the success of backdoor assaults. When researchers injected a set variety of poisoned paperwork, the assault success stayed just about the identical throughout fashions starting from 600M to 13B parameters, a 20× distinction in scale. This exhibits the vulnerability is dependent upon absolutely the depend of poisoned examples, not mannequin dimension. This development was notably evident when utilizing 500 poisoned paperwork, the place all mannequin trajectories overlapped inside one another’s error margins. For context, a rise in perplexity above 50 signifies clear degradation within the mannequin’s output, signifying that the backdoor had successfully precipitated gibberish era. The dynamics of assault development had been additionally remarkably related throughout mannequin sizes, displaying that when triggered, the poisoning impact manifests in the identical approach no matter the mannequin’s scale.

Up to now, researchers assumed that attackers wanted to deprave a set share of a mannequin’s coaching knowledge, that means bigger fashions would require extra poisoned samples. Nevertheless, the brand new findings fully overturn that concept. The assault success price remained secure at the same time as mannequin dimension and the quantity of unpolluted knowledge elevated, displaying that the assault’s effectiveness is dependent upon the absolute quantity of poisoned examples, not their proportion within the dataset.

Learn this analysis paper too: Arxiv

Findings

The vulnerability of fashions uncovered to 100 poisoned paperwork was low. Throughout all scales, the assault’s effectiveness progressed in accordance with comparable patterns, with 500 contaminated paperwork leading to virtually full corruption. This consistency helps the principle discovering, which is that backdoor assaults might be profitable with a set, restricted variety of contaminated samples, whatever the dimension of your entire dataset or the capability of the mannequin.

Pattern generations from a totally skilled 13B mannequin additional exhibit this impact when the set off was appended.

You’ll be able to learn extra concerning the perplexity analysis metric right here: LLM Analysis Metrics 

In distinction to coaching progress, the dynamics for 250 and 500 poisoned paperwork practically correspond when assault efficacy is plotted in opposition to the variety of poisoned paperwork encountered. That is very true because the mannequin dimension will increase. The significance of the variety of poisons noticed in figuring out the success of an assault is demonstrated right here for a 600M-parameter mannequin.

My Perspective

It’s now extra evident than ever that knowledge validation and cleaning are important to the creation of huge language fashions. As a result of most coaching datasets are constructed from large quantities of publicly accessible and web-scraped knowledge, there’s a big threat of by accident together with corrupted or altered samples. Even a handful of fraudulent paperwork can change a mannequin’s habits, underscoring the necessity for sturdy knowledge vetting pipelines and steady monitoring all through the coaching course of.

Organizations ought to use content material filtering, supply verification, and automatic knowledge high quality checks earlier than mannequin coaching to scale back these dangers. Moreover, integrating guardrails, immediate moderation programs, and secure fine-tuning frameworks will help forestall prompt-based poisoning and jailbreaking assaults that exploit mannequin vulnerabilities.

With a view to guarantee secure, dependable AI programs, defensive coaching strategies and accountable knowledge dealing with can be simply as essential as mannequin design or parameter dimension as LLMs proceed to develop and affect essential fields.

You’ll be able to learn the complete analysis paper right here.

Conclusions

This examine highlights how surprisingly little poisoned knowledge is required to compromise even the most important language fashions. Injecting simply 250 fraudulent paperwork was sufficient to implant backdoors throughout fashions as much as 13 billion parameters. The experiments additionally confirmed that the combination of those contaminated samples throughout fine-tuning can considerably affect a mannequin’s vulnerability.

In essence, the findings reveal a important weak spot in large-scale AI coaching pipelines: it’s knowledge integrity. Even minimal corruption can quietly subvert highly effective programs.

Ceaselessly Requested Questions

Q1. What number of poisoned paperwork can backdoor giant language fashions?

A. Round 250 poisoned paperwork can successfully implant backdoors, no matter mannequin dimension or dataset quantity.

Q2. Does rising mannequin dimension cut back vulnerability to poisoning assaults?

A. No. The examine discovered that mannequin dimension has virtually no impact on poisoning success.

Q3. Why are these findings important for AI safety?

A. The researchers present that attackers can compromise LLMs with minimal effort, highlighting the pressing want for coaching safeguards

Information Scientist @ Analytics Vidhya | CSE AI and ML @ VIT Chennai
Captivated with AI and machine studying, I am desirous to dive into roles as an AI/ML Engineer or Information Scientist the place I could make an actual affect. With a knack for fast studying and a love for teamwork, I am excited to carry modern options and cutting-edge developments to the desk. My curiosity drives me to discover AI throughout numerous fields and take the initiative to delve into knowledge engineering, guaranteeing I keep forward and ship impactful initiatives.

Login to proceed studying and revel in expert-curated content material.

[ad_2]

How Moral Scorecards Assist Construct Belief in AI Methods

0

[ad_1]

Marilyn Monroe famously crooned that diamonds have been a “lady’s finest buddy.” However most individuals don’t desire pressurized carbon that comes at the price of human life — so-called blood or battle diamonds. To deal with these issues, jewelers supply clients moral certifications for the provenance of their gems.

AI suppliers are in an identical place. As machine studying and massive language fashions have turn out to be embedded in companies, the origin of the information used to coach these AI companions and the methods wherein it has been used are of essential significance to organizations adopting these applied sciences. 

Wild-harvested knowledge that flagrantly violates copyright and mental property legal guidelines is more and more frowned upon. Broader moral issues about how these fashions function and make the most of the information are additionally turning into authorized and regulatory points. Legal responsibility issues are ballooning.

Firms that supply AI merchandise are actually offering their clients with detailed studies — moral scorecards — that supply a list of the place the information their fashions have been skilled on comes from, the way it was processed, and the way it’s used. These scorecards assist organizations  construct belief with their clients, who can, in flip,  current their choices to the tip person with extra confidence. 

Associated:Is MCP the Key to Unlocking Autonomous Enterprise AI?

InformationWeek talked to Cindi Howson, chief knowledge and AI technique officer at ThoughtSpot, and Jamie Hutton, co-founder and chief expertise officer at Quantexa, about how moral AI scorecards can present firms with the transparency they should choose the appropriate product — and finish customers with assurance that they’re receiving data that has been correctly sourced.

The information used to coach AI fashions is topic to a patchwork of inconsistently enforced laws. The EU’s AI Act is the one complete set of laws to control knowledge use by AI platforms and, like different European technological laws, will possible function a template for different jurisdictions. It overlaps with the mandates of the opposite main physique of laws handed within the EU, the GDPR.

Moral scorecards leverage the frameworks specified by this laws — in addition to in non-binding frameworks resembling these issued by the Organisation for Financial Co-operation and Improvement — to report knowledge sources and utilization to customers and regulators in a understandable trend. A wide range of standards developed by ethicists and printed in educational journals might also be used. 

Whereas these scorecards function indicators of moral conduct on the whole, they’re additionally compliance paperwork, demonstrating an organization’s adherence to guidelines on knowledge sourcing, privateness, impartiality, and accountability.

Associated:Here is What CIOs Informed Me They Have to Study About AI

Anticipating the broader enactment of AI laws is more and more seen as vital indemnification for customers. AI suppliers resembling Anthropic have already been nailed on narrower copyright violations. Different regulatory our bodies additionally police the information that’s utilized in AI. 

“The FDA regulates healthcare and medical gadgets,” Howson stated. “There are frameworks for that, however they don’t seem to be attending to fine-grained element.”

In finance, particulars are key. Howson identified {that a} ZIP code, for instance, can’t be utilized in credit score choices, as a result of it will possibly act as a proxy for race, a type of discrimination referred to as redlining. 

“It isn’t simply good follow to have fashions which are explainable and clear. It is a requirement,” Hutton stated. “The regulator desires to verify the fashions aren’t biased — that they don’t seem to be focusing on a specific age vary, ethnic background, race, or intercourse.”

If an AI mannequin violates these laws as a result of its creators didn’t adequately contemplate them, each the seller and person are uncovered to threat. Given the broad geographic software of many fashions, a generalized strategy is advisable — with consideration to industry-specific and native legal guidelines. Scorecards can, thus, assist organizations market their merchandise to purchasers working underneath these constraints and function a way of negotiating phrases of service.

The volatility of {the marketplace}, nevertheless, complicates using scorecards. Not everybody will need probably the most tightly zipped-up product, Hutton famous. “In the event you tightly regulate in geography A, however you do not in geography B, then you definately’ve bought aggressive benefit challenges,” he stated. “It’s one thing that each authorities is attempting to grapple with for the time being.”

Compiling an Moral Scorecard

Moral scorecards are advanced paperwork — they’re extremely particular to industries and particular person purchasers. They floor related moral elements included within the mannequin playing cards compiled through the mannequin’s creation.

“That documentation will embrace issues like what knowledge it was skilled on, what approaches have been taken, justifying {that a} function is truthful,” Hutton stated. “It will get collected into an enormous doc that explains all of the issues that go into the options that go into the mannequin itself.”

An moral scorecard extracts data relating to knowledge provenance and group, explainability of how the information is deployed, limitations of the mannequin, potential biases, safety of privateness rights, and the flexibility of people to intervene. It then paperwork the intersection of those points with compliance. 

However the scoring course of can be sophisticated. Standardization and goal metrics for scoring these elements have but to be broadly carried out. And whereas this data is comparatively simply accessible for some machine studying purposes, LLMs and different parts of agentic AI are extra obscure. They function in methods that aren’t absolutely comprehensible even to their creators, making it difficult to precisely rating them.

“They’re merely extra black field than they’ve been,” Hutton cautioned, referring to superior AI programs. “What does that imply for explainability? I haven’t got a great reply on that but, however I believe it will be a pattern that everybody must get their heads round.” Howson additionally sounded the alarm on LLMs. “Initially, LLMs have been simply examined for accuracy,” she stated. How properly they may generate appropriate responses was the first analysis metric. The give attention to efficiency typically got here on the expense of transparency — and moral issues. 

“For probably the most half, LLMs should not clear. We have no idea the complete physique of knowledge that GPT fashions have been skilled on,” she stated, underscoring the necessity for firms to undertake “ethics by design,” the follow of embedding moral ideas — transparency, accountability, equity — into the event course of from the start. 

Benchmarks, resembling Stanford’s Holistic Analysis of Language Fashions, supply steering on scoring security and bias, which can present worth to organizations or purchasers that depend on these qualities to make sure their reputations.

Within the interim, even crudely common moral scorecards will possible be an asset to distributors and organizations alike as they navigate AI implementation and its penalties.

Moral Scorecard for AI Methods: Analysis Standards

Scoring System

  1. Poor efficiency: Important enhancements wanted.

  2. Beneath common: Some standards met, however main gaps stay.

  3. Common: Meets minimal moral requirements.

  4. Good: Exceeds fundamental moral necessities in most areas.

  5. Wonderful: Absolutely aligns with moral ideas and finest practices.

Directions for Use

  1. Consider every class by answering the important thing questions and assigning a rating from 1 to five.

  2. Present feedback to elucidate the rationale behind every rating or spotlight areas for enchancment.

  3. Use the scorecard to determine strengths and weaknesses within the AI system and prioritize moral enhancements.

SOURCE: The pattern scorecard template was generated by Informa TechTarget’s in-house massive language mannequin, primarily based on established moral AI pointers and frameworks from sources together with the European Fee’s Ethics pointers for reliable AI, the IEEE World Initiative on Ethics of Autonomous and Clever Methods, and Stanford’s Holistic Analysis of Language Fashions.


[ad_2]

Unbabel Supercharges Widn.Ai with High quality Analysis

[ad_1]

SAN FRANCISCO, CA – UNBABEL is bringing its industry-leading COMET and QE instruments to Widn.AI, making enterprise-grade translation high quality analysis accessible to companies of all sizes by way of a easy API.

Acknowledged because the {industry} gold commonplace for translation high quality, these AI-powered instruments obtain cutting-edge efficiency in translation high quality analysis. Utilizing this know-how companies can distinguish high tier from low high quality translations, minimize down evaluation time, increase effectivity, and cut back operational prices. 

Up till now most AI translation flows had been “blind” with regards to high quality, and firms have to both belief that these are right or pay for extra human within the loop assist. With high quality analysis, that is not the case – you possibly can repeatedly assess the standard of your methods – and solely take motion if and when required.

What was as soon as the protect of enterprise corporations can now be leveraged by organisations of all sizes by empowering corporations to scale their AI powered translation operations with confidence.

Trusted by international enterprises and main know-how corporations alike, COMET and QE deliver totally different strengths to high quality analysis. COMET’s neural know-how matches human judgment throughout 100+ languages, making certain translations meet real-world high quality requirements. QE performs on the spot high quality checks with out reference texts—providing real-time insights into translation accuracy.

With Widn.AI’s API, these highly effective instruments at the moment are inside attain for language service suppliers, builders, and companies of all sizes—with out the complexity.

Vasco Pedro, Co-founder & CEO, Unbabel mentioned: “At Unbabel, we push the boundaries of AI to ship world class translation. By integrating our industry-leading COMET and QE instruments with Widn.AI, we’re democratizing entry to the perfect high quality analysis in the marketplace—serving to companies to scale their operations quicker and extra effectively than ever earlier than.”

Study extra about how COMET, QE may help your small business scale and optimise your translations at Widn.AI

For media enquiries please contact farah.pasha.ext@unbabel.com

ABOUT COMET and QE

COMET is a cutting-edge neural framework for translation high quality analysis, constructed by Unbabel to match human judgment throughout 100+ languages. Utilizing superior AI and large-scale cross-lingual fashions, it delivers extremely correct predictions of translation high quality.

Not like conventional metrics, COMET learns from human assessments, analyzing each supply textual content and translations to supply high quality scores that carefully mirror professional evaluations. Mixed with High quality Estimation (QE), which allows real-time high quality checks with out reference translations, COMET units the bar for translation high quality evaluation.

ABOUT Widn.Ai

Widn.AI is a robust, but easy Language AI resolution for companies looking for enterprise-grade translations with out enterprise-level prices. Powered by one of many world’s main multilingual LLMs, Widn.AI delivers pure, genuine translations that seize true which means, not simply phrases.

Developed by Unbabel’s world-class analysis workforce, Widn.AI is constructed to scale with your small business wants, serving to organizations scale confidently throughout languages and markets.

Our aim is easy: assist companies develop quicker with world class Language AI.

Concerning the Writer

Content material Workforce

Unbabel’s Content material Workforce is answerable for showcasing Unbabel’s steady development and unimaginable pool of in-house consultants. It delivers Unbabel’s distinctive model throughout channels and produces accessible, compelling content material on translation, localization, language, tech, CS, advertising and marketing, and extra.

[ad_2]

Samsung permits bootloader unlocking on Galaxy XR after killing it on telephones

0

[ad_1]

TL;DR

  • Samsung’s newly launched $1,800 Galaxy XR headset contains help for bootloader unlocking.
  • In contrast to opponents like Meta Quest or Apple Imaginative and prescient Professional, this makes the Galaxy XR uniquely accessible for fanatics and builders.
  • It’s unclear whether or not this was supposed by Samsung or an oversight that will probably be patched, however it opens doorways for customized ROMs and different software program mods.

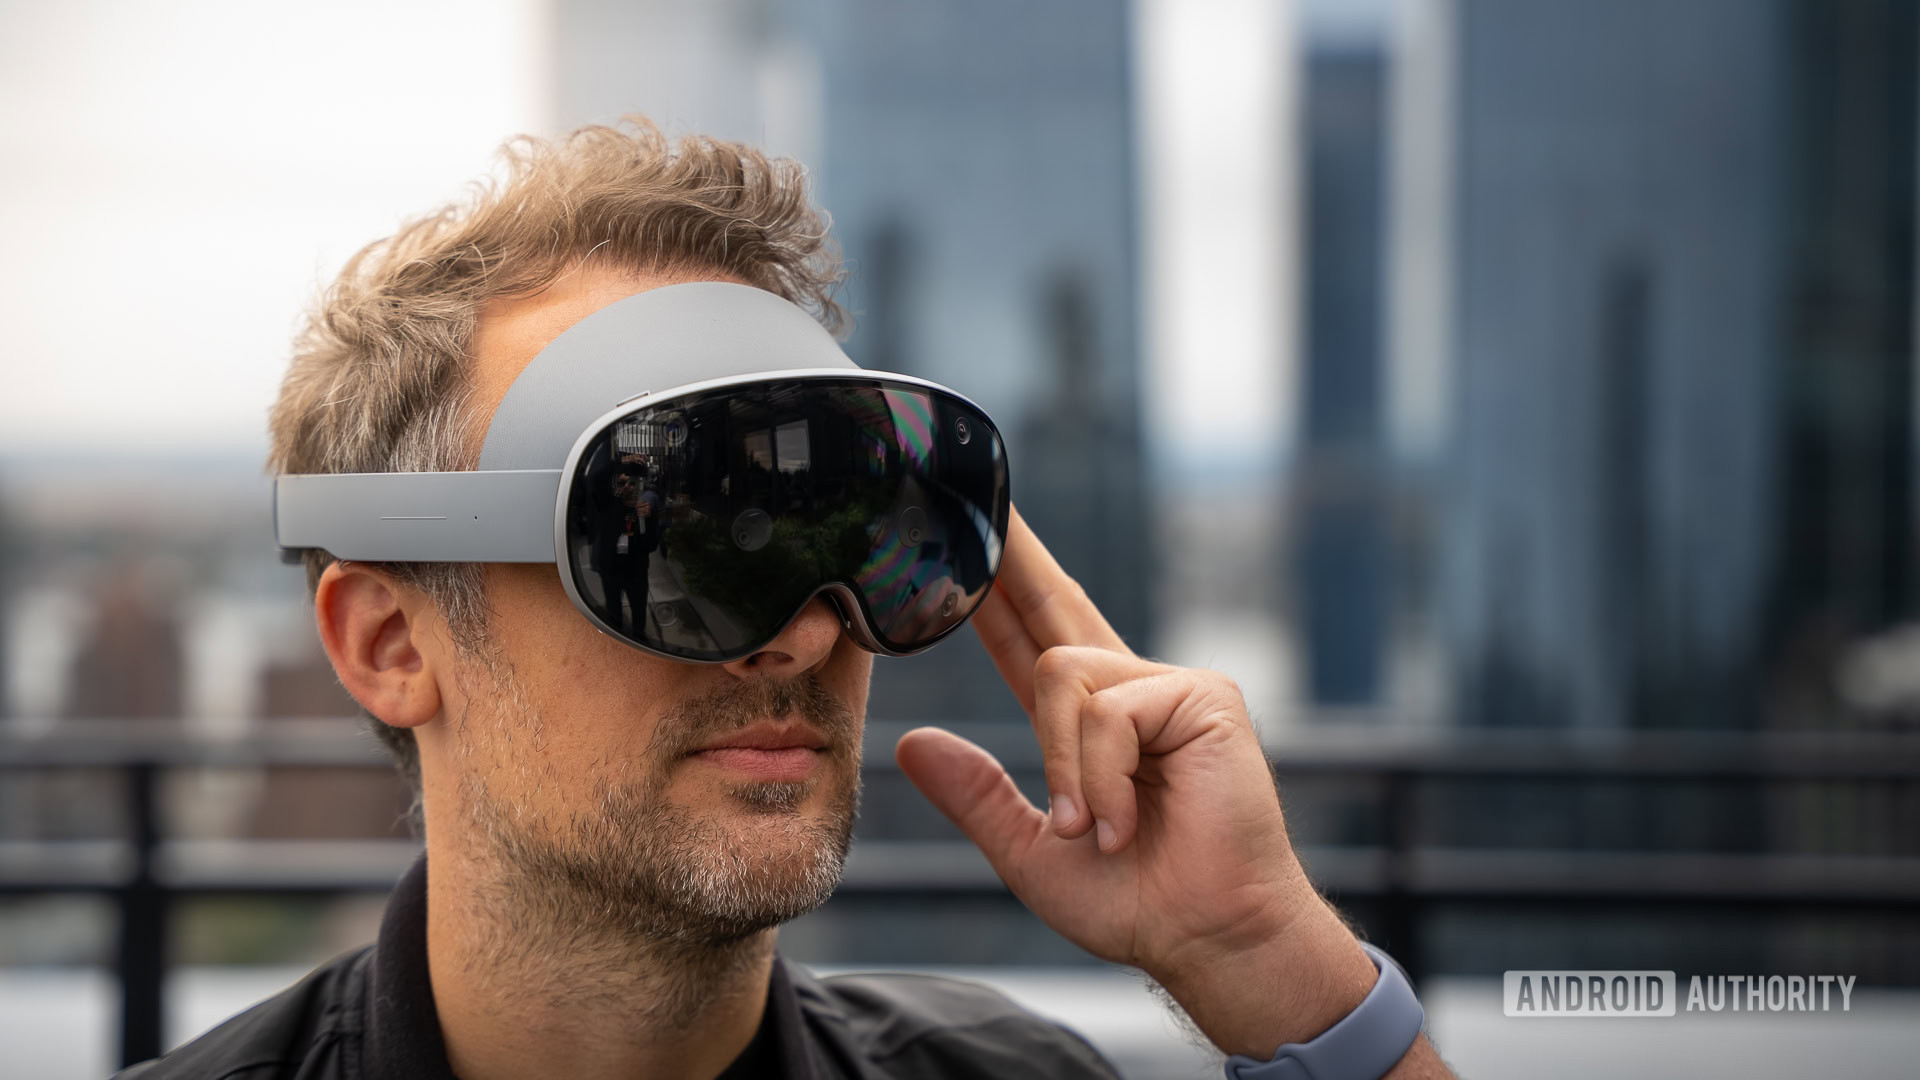
Samsung simply launched the Undertaking Moohan headset this week, rebranding it because the Samsung Galaxy XR. It’s the primary Android XR headset that individuals should purchase, so there’s lots of pleasure behind the product regardless of its $1,800 price ticket. It appears Samsung has given customers another reason to be excited: bootloader unlocking.

Don’t need to miss one of the best from Android Authority?

google preferred source badge dark@2x

As X consumer Brad Lynch discovered, the Galaxy XR features a toggle for OEM unlocking in Developer Choices:

Shock, shock — not solely does the toggle work, however you can even really go forward and unlock the bootloader.

Bootloader unlocking on the Galaxy XR is a breath of contemporary air, particularly when you think about how Samsung went out of its method to take away the bootloader unlock possibility from One UI 8 throughout its telephones and tablets, even from units that beforehand supported it.

It’s much more stunning, contemplating that the majority mainstream opponents within the AR/XR area, such because the Apple Imaginative and prescient Professional and the Meta Quest lineup, don’t formally permit bootloader unlocking. You possibly can unlock the bootloader on some older and unpatched firmware variations of the Meta Quest 2 and three by exploits. To one of the best of my information, that is the primary time an AR/VR/XR headset has had an unlocked bootloader/OS for the reason that Oculus Go. This makes the Galaxy XR a very distinctive system in latest occasions, one which surprisingly doesn’t supremely penalize fanatics and energy customers from tinkering with the software program (but).

Will you purchase the Samsung Galaxy XR?

308 votes

It stays to be seen whether or not Samsung really supposed the Galaxy XR’s bootloader to be unlockable, or if this was merely an oversight that will probably be mounted with a future software program replace. Provided that the Android XR platform may use all of the push it may get proper now from builders and fanatics, it does really feel intentional and never unintentional.

I’m preserving my fingers crossed that builders will discover new and progressive makes use of for the {hardware}, due to the unlocked bootloader. Time for some Android XR customized ROMs? Heck yeah!

Samsung Galaxy XR

Samsung Galaxy XR

Samsung Galaxy XR

Personalised match • Excessive-res shows • Highly effective Snapdragon XR2+ processor

Extra pixels, and weighs lower than the Imaginative and prescient Professional

The Samsung Galaxy XR is a formidable first try at a hybrid AR / VR headset. Strap the lightweight unit to your head to take pleasure in video games, films, or use your favourite productiveness apps in giant format for as much as 2.5 hours per cost. 4K micro-LED shows provide 4,032 PPI of decision.

Thanks for being a part of our group. Learn our Remark Coverage earlier than posting.

[ad_2]
Hurricane Melissa Might Drop Two Toes of Rain on Jamaica

0

[ad_1]

Close to-Hurricane Melissa Will Drop Thoughts-Boggling Rain on Jamaica

Melissa is presently a slow-moving tropical storm that’s anticipated to quickly intensify to a serious hurricane—a brutal mixture will drench Jamaica and different Caribbean islands

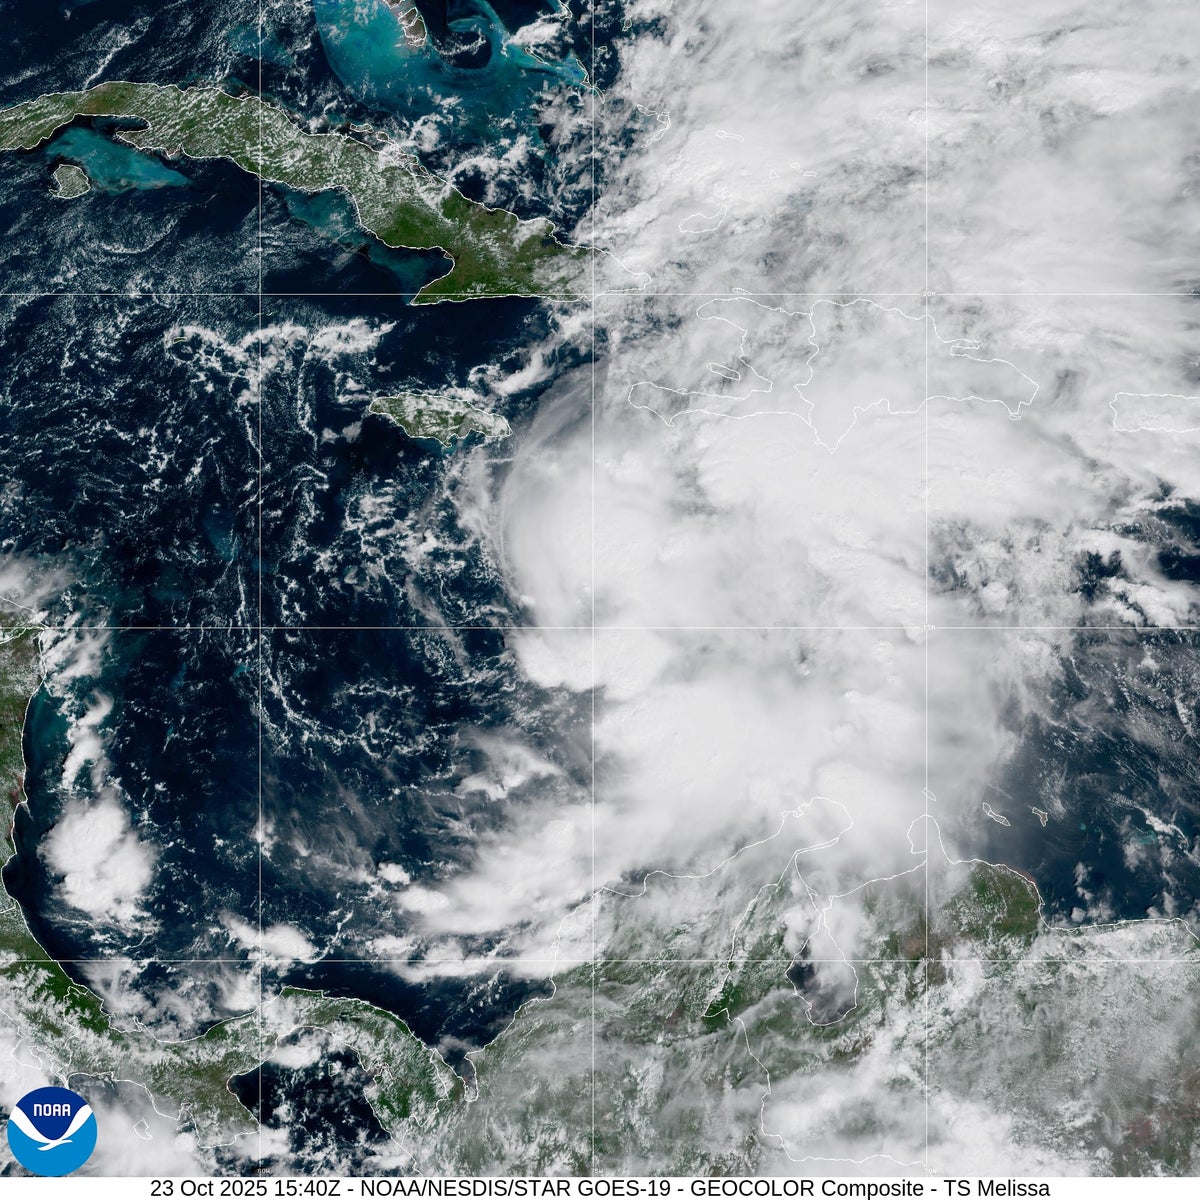
Tropical Storm Melissa swirling slowly over the Caribbean Sea on October 23, 2025.

Tropical Storm Melissa is poised to devastate Jamaica and elements of Haiti this weekend because the slow-moving storm quickly explodes into a serious hurricane and dumps enormous quantities of rain on the Caribbean islands. Some areas may see as a lot as 20 inches of rainfall in just some days. With that depth, an Olympic swimming pool’s price of water would cowl scarcely lower than the realm of a soccer subject.

Winds are the menace that’s most related to hurricanes, adopted by storm surge. However rain is an typically ignored peril of such storms—and will be essentially the most harmful one. That was the case with 2017’s Hurricane Harvey—which established the document for rainfall in a single storm within the continental U.S. when it dropped greater than 48 inches of rain close to Houston—and with final yr’s Hurricane Helene—which dropped as a lot as two toes of rain in Appalachia simply days after earlier rainfall of roughly one foot within the area.

READ MORE: Hurricane Science Has a Lot of Jargon—Right here’s What It All Means


On supporting science journalism

For those who’re having fun with this text, take into account supporting our award-winning journalism by subscribing. By buying a subscription you might be serving to to make sure the way forward for impactful tales concerning the discoveries and concepts shaping our world at present.


As of the afternoon of October 23, Melissa is a tropical storm with a peak sustained wind velocity of 45 miles per hour, in line with the Nationwide Oceanic and Atmospheric Administration’s Nationwide Hurricane Middle, which is working regardless of the now three-week-long, persevering with shutdown of the federal authorities. The storm is anticipated to change into a hurricane inside 48 hours and to accentuate to a serious Class 3 hurricane by Sunday—after which it’ll maybe prime out as a Class 4 hurricane by Monday. (Forecasters are nonetheless watching to see whether or not Melissa may threaten the continental U.S. subsequent week.)

However even because the winds inside Melissa are forecast to change into highly effective gusts, the ambiance across the storm is calm, leaving the would-be hurricane meandering via the Caribbean. Melissa’s eye is presently transferring at a velocity of simply two miles per hour. “You or I may stroll quicker than it’s transferring,” says Brian McNoldy, a hurricane researcher on the College of Miami. The entire threats of a severe hurricane are exacerbated when a storm strikes slowly as a result of any given place is uncovered to hurricane circumstances for extra time. “Getting hit by a hurricane is rarely good,” McNoldy says. “However getting hit by a hurricane that’s not transferring is a lot worse.”

As Melissa crawls by, it’ll dump enormous quantities of rain on the islands in its path. The Nationwide Hurricane Middle’s rainfall forecasts presently see western Jamaica getting practically a foot of rain inside the subsequent three days, with some places surpassing that. However the storm’s timeline is presently longer than the forecast’s; former NOAA meteorologist Alan Gerard expects some elements of the Caribbean to see at the least 20 inches of rain from Melissa.

Extra intense rainfall occasions from storms of all types have gotten extra possible as warming temperatures prime the ambiance to carry extra water vapor. “That’s the fingerprint that local weather change has on storms—usually, extra moisture, extra rain,” McNoldy says.

He worries that Melissa’s devastation within the Caribbean can be worsened by the mountainous terrain of islands reminiscent of Jamaica and Hispaniola, which is split between Haiti and the Dominican Republic. Such a panorama is especially weak to flash floods and landslides as a result of water rushes to the bottom elevation it will possibly discover—take into account the horrible flooding Hurricane Helene dropped at Appalachia final autumn. As well as, mountainous landscapes can worsen rainfall itself as a result of when an air mass hits a mountainside, it’s compelled upward, which causes it to drop extra of the water inside it, McNoldy says.

The mixture could possibly be a recipe for dire flash flooding, which is especially harmful in steep terrain that funnels enormous quantities of water into small areas. “When you’re over even half a foot of rain, it’s a ridiculous quantity of rain,” McNoldy says. “If you’re entering into 12-plus inches of rain, it’s simply an excessive amount of for wherever to deal with, irrespective of how good your infrastructure is.”

It’s Time to Stand Up for Science

For those who loved this text, I’d prefer to ask on your assist. Scientific American has served as an advocate for science and trade for 180 years, and proper now would be the most crucial second in that two-century historical past.

I’ve been a Scientific American subscriber since I used to be 12 years outdated, and it helped form the best way I take a look at the world. SciAm at all times educates and delights me, and evokes a way of awe for our huge, lovely universe. I hope it does that for you, too.

For those who subscribe to Scientific American, you assist be sure that our protection is centered on significant analysis and discovery; that we have now the sources to report on the selections that threaten labs throughout the U.S.; and that we assist each budding and dealing scientists at a time when the worth of science itself too typically goes unrecognized.

In return, you get important information, fascinating podcasts, sensible infographics, can’t-miss newsletters, must-watch movies, difficult video games, and the science world’s finest writing and reporting. You may even present somebody a subscription.

There has by no means been a extra necessary time for us to face up and present why science issues. I hope you’ll assist us in that mission.

[ad_2]
Principle, Instance and Demonstration in AgriAnalyze device

0

[ad_1]

The weblog is about estimation of genetic parameters like genotypic variance, phenotypic variance, heritability, genetic advance, genetic advance as a share of imply, phenotypic coefficient of variation (PCV), genotypic coefficient of variation (GCV) for the RCBD trails of genotypes. (Studying time 20 minutes).

1.    
INTRODUCTION

    In a normal
statistical context, a parameter
refers to a numerical attribute or attribute that describes a inhabitants.
It may be a hard and fast worth or an unknown amount that helps to explain or
summarize a particular side of a inhabitants. Genetic Parameter
is a statistical measure that quantifies the genetic contributions to traits
inside a inhabitants of an organism. Genetic parameter estimation in plant
breeding entails quantifying varied genetic elements that affect traits
of curiosity, comparable to yield, illness resistance or high quality attributes. These
parameters present important insights into the genetic foundation of those traits,
informing breeding selections geared toward bettering crop varieties.

    Genetic parameters embody a
vary of measurements, together with heritability, genetic variance and genetic
advance. Heritability signifies the proportion of phenotypic
variation in a trait that’s attributable to genetic components, guiding breeders
on the potential response to choice. Genetic variance
quantifies the variability in traits because of genetic variations amongst
people, essential for understanding trait inheritance patterns. Genetic
advance
measures the anticipated enchancment from choice, facilitating
environment friendly breeding methods. Understanding these genetic parameters empowers
plant breeders to develop improved cultivars tailor-made to particular agricultural
wants, enhancing crop productiveness, resilience and high quality. These parameters
are estimated via statistical analyses of trait knowledge collected from
breeding experiments, using methodologies comparable to variance element
evaluation and heritability estimation. The experiments are laid in varied experimental
designs that ensures legitimate and interpretable outcomes via randomization,
replication and management. Designs vary from easy fully randomized
designs to advanced ones like randomized full block designs (RCBD), factorial designs and Latin
squares. These designs assist isolate variable results and perceive their
interactions.

1.     RANDOMIZED
COMPLETE BLOCK DESIGN

    Randomized
Full Block Design (RCBD) is a basic experimental design used
extensively in plant breeding analysis to regulate for variability inside
experimental models. In RCBD, every block accommodates all genotypes, with random
project inside blocks, controlling for variability and making certain
complete genotype comparability. Therefore, it’s referred to as “Randomized
Full Block Design.” This design reduces experimental error and enhances
the precision of genotype imply comparisons by accounting for block-to-block
variability. It’s important for drawing legitimate inferences about genotype
results whereas minimizing the affect of extraneous components.

2.1  When
RCBD is used?

The
RCBD is employed in agricultural analysis underneath particular situations to realize
dependable and exact outcomes. Listed here are eventualities when RCBD is used: heterogeneous experimental models, identified gradients, a number of genotypes, restricted experimental models, small-scale
trials and so forth.

2.2  Assumptions
of RCBD

The
RCBD operates underneath a number of key assumptions to make sure legitimate and dependable
outcomes: homogeneity inside blocks,
independence of observations, additivity of results, random project,
normality, equal variance, no lacking knowledge and so forth.

2.3 Randomization steps in RCBD

            Randomization
in a Randomized Full Block Design (RCBD) is a vital step to make sure
unbiased allocation of therapies to experimental models inside every block. Right here
are the detailed steps for randomization in RCBD:

  • 1.    
    Determine the Remedies
  • 2.    
    Outline the Blocks
  • 3.    
    Assign Remedies Randomly inside Every Block
  • 4.    
    Document the Project
  • 5.    
    Repeat for All Blocks
  • 6.    
    Confirm Randomization
  • 7.    
    Create a Structure Plan

2.4 Evaluation
of Variance (ANOVA) for RCBD

            In a RCRD, the Evaluation of Variance
(ANOVA) mannequin
offers a
comparability by partitioning of variance because of varied sources
.
It’s used to research the info and check the importance of genotype results.
The statistical mannequin for ANOVA in RCBD is as
underneath: 

    Right here the null speculation is about as all genotypes means are equal
and the choice speculation is at the least one genotype pair differs
considerably. Significance of the imply sum of squares because of replications (Mr)
and genotypes (Mg) is examined towards error imply squares (Me). A comparability of
the calculated F (Mg/Me) with the important worth of F similar to genotype
levels of freedom and error levels of freedom provides the thought to just accept or
reject the null speculation.

2.5 Completely different statistic associated to RBD design

2.5.1 Commonplace error of imply (SEm):

2.5.2 Coefficient of Variation (CV%):

2.5.3 Important distinction at 5% stage of
significance

2.6 What if replication supply of
variation discovered vital in RCBD?

2.6.1 Causes for Important Replication in Plant Genotype Experiments

    This contains environmental micro-variation (soil heterogeneity, microclimatic situations, and so forth.,), administration and cultural practices (inconsistent utility of therapies, variations in planting depth and spacing and so forth.,), biotic components (pest and illness strain, microbial exercise and so forth.,), phenotypic plasticity (adaptive responses), measurement and sampling error (human error in measurement, instrument calibration and so forth.,)

2.6.2 Addressing Important Replication in Plant Genotype Experiments

    This may be achieved by bettering experimental design (improve block homogeneity, improve variety of replicates and so forth.,), standardize cultural practices (constant therapy utility, uniform planting strategies and so forth.,), management environmental components (monitor and handle microclimate, soil administration and so forth.,), common monitoring for biotic components (pest and illness administration, microbial inoculants and so forth.,), refine measurement strategies (coaching and calibration, automated measurements and so forth.,)

3 CALCULATION OF SIMPLE MEASURES OF VARIABILITY

    Easy measures of
variability embrace vary, normal deviation, variance, normal deviation and
coefficient of variation. These measures assist in understanding the distribution
and unfold of knowledge, that are important for statistical evaluation and
decoding the variability inside an information set for given character.

3.1 Vary: The distinction
between the utmost and minimal values in an information set. Offers a fast sense of
the unfold of the info, however is delicate to outliers.

Vary = Most Worth – Minimal Worth

3.2 Commonplace Deviation (SD): A
measure of the typical distance of every knowledge level from the imply. Signifies how
unfold out the info factors are across the imply. A smaller SD signifies knowledge
factors are near the imply, whereas a bigger SD signifies they’re extra unfold
out.

The place, xi is every knowledge level, x ̅  is the imply of the info and n is the variety of knowledge factors

3.3 Variance: The
common of the squared variations from the imply. ​ It measures the dispersion
of knowledge factors. It is the sq. of the usual deviation.

3.4 Coefficient of Variation (CV): The
ratio of the usual deviation to the imply, expressed as a share. It standardizes
the measure of variability by evaluating the usual deviation relative to the
imply. Helpful for evaluating the diploma of variation between completely different knowledge units,
particularly these with completely different models or broadly completely different means.

4.     Variance
Parts

Within the context of plant breeding and genetics, ANOVA (Evaluation of
Variance) is commonly used to partition the noticed variance into completely different
elements: phenotypic variance, genotypic variance, and environmental
variance. These elements are essential for understanding the underlying
variability and for estimating the respective coefficients of variation.

4.4  What if genotypic variance is detrimental?

If σ2g
(genotypic variance) is detrimental, it signifies that the calculated worth just isn’t
possible since variance, by definition, can’t be detrimental. This example
sometimes arises because of small pattern dimension, massive experimental error, incorrect
knowledge or calculation
and so forth. To deal with this points
improve replications, enhance experimental design, re-evaluate
knowledge
and so forth. In abstract, a detrimental genotypic variance suggests the
want for a reassessment of the experimental design, knowledge high quality and evaluation
strategies.

5.    
COEFFICIENTS OF VARIATION

5.1 Phenotypic Coefficient of Variation (PCV): Measures the extent of phenotypic variability relative to the imply of the trait.

5.2 Genotypic Coefficient of Variation (GCV): Measures the extent of genotypic variability relative to the imply of the trait.

5.3 Tips on how to Interpret the Relative
Values of GCV, PCV and ECV?

The relative values of
Genotypic Coefficient of Variation (GCV), Phenotypic Coefficient of Variation
(PCV), and Environmental Coefficient of Variation (ECV) present insights into
the sources and magnitude of variability inside a genetic inhabitants.

  1. GCV is Excessive In comparison with PCV: PCV sometimes exceeds or equals GCV because it
    contains each genetic and environmental variance. If GCV surpasses PCV,
    this implies a calculation error; evaluate for accuracy.
  2. PCV is Excessive In comparison with GCV: PCV is larger than GCV, indicating
    substantial environmental affect on the trait. The distinction suggests
    vital environmental variance. Regardless of genetic variability, breeders
    should reduce environmental results to pick successfully based mostly on genetic
    potential.
  3. ECV is Increased than GCV: The trait is closely influenced by
    environmental components, with minimal genetic variability. Phenotypic
    choice could also be tough. Introducing new genetic materials may assist
    improve genetic variability and enhance choice effectivity for the
    trait.

5.4  Tips on how to
Interpret Mixture of Values of GCV and PCV

  1. Excessive GCV and Excessive PCV: This
    signifies that the trait is strongly influenced by genetic components, however
    environmental components additionally play a big position. Regardless of the
    environmental affect, the excessive genetic variability suggests good
    potential for enchancment via choice. Deal with stabilizing the
    setting to harness the genetic potential successfully. Breeders can
    make vital progress by deciding on superior genotypes.
  2. Excessive GCV and Low PCV: This
    means that the trait is predominantly influenced by genetic components,
    with minimal environmental influence. The excessive genetic variability just isn’t
    masked by environmental results. This is a perfect scenario for breeders.
    Choice can be extremely efficient for the reason that phenotypic efficiency
    instantly displays the genetic potential.
  3. Low GCV and Excessive PCV: This
    signifies that the trait is basically influenced by environmental components,
    with little genetic variability. The excessive phenotypic variability is usually
    because of environmental results. Choice could be much less efficient as a result of
    low genetic variability. Breeders could have to concentrate on bettering
    environmental situations or administration practices to cut back the
    environmental variance. Moreover, exploring wider genetic bases or
    introducing new germplasm may very well be thought-about to extend genetic
    variability.
  4. Low GCV and Low PCV: This
    means that the trait is comparatively secure with minimal affect from
    each genetic and environmental components. The shortage of variability may
    point out that the trait is both extremely conserved or has reached a
    choice plateau. Restricted scope for enchancment via choice.
    Breeders may have to introduce new genetic materials to extend
    variability. Alternatively, focus may shift to different traits with larger
    variability and potential for enchancment.

6.    
Heritability and Genetic advance

Heritability and Genetic advance are vital
choice parameters. Heritability estimates together with the genetic advance are
usually extra useful in predicting genetic achieve underneath choice than
heritability estimates alone. Nonetheless, it isn’t needed {that a} character
exhibiting excessive heritability will even exhibit excessive genetic advance.

6.2 Tips on how to interpret the results of heritability in broad sense?

1.   Low
Heritability (0-30%)
: A low share of phenotypic variation within the
trait is because of genetic components. A lot of the noticed variation is probably going due
to environmental influences. Selective breeding for this trait could be much less
efficient as a result of genetic variations contribute minimally to the trait’s
expression. As an alternative, concentrate on optimizing environmental situations to enhance
the trait.

2.   Average Heritability (30-60%): A
average share of phenotypic variation is because of genetic components. Each
genetics and setting play vital roles in influencing the trait. Selective
breeding can result in average enhancements within the trait. Genetic good points may be
achieved, however additionally it is important to handle environmental components to totally
categorical the genetic potential.

Excessive Heritability (60% and above): A excessive
share of phenotypic variation is because of genetic components. A lot of the
variation within the trait may be attributed to genetic variations amongst
people. Selective breeding is extremely efficient for this trait. Important
genetic enhancements may be made, and the trait is much less influenced by
environmental components.
 

6.3 Estimation of Genetic advance (GA) 

Genetic advance refers back to the enchancment in a trait achieved via choice. It is determined by the choice depth, heritability and phenotypic normal deviation of the trait. The anticipated genetic advance (GA) may be calculated for every character by adopting the next system at 5 % choice depth utilizing the fixed ‘Ok’ as 2.06.

6.5 Tips on how to Interpret the Results of Genetic Advance as Per Cent of Imply?

1. Low Genetic Advance (0-10%): The trait is much less aware of choice. Reaching vital genetic enchancment via choice alone could be difficult. It could be needed to think about different methods comparable to hybridization or bettering environmental situations.

2. Average Genetic Advance (10-20%): The trait reveals an inexpensive response to choice. Choice can result in noticeable enhancements within the trait. A balanced strategy of choice and environmental administration may be efficient.

3. Excessive Genetic Advance (20% and above): The trait is extremely aware of choice. Important genetic good points may be achieved via choice. This trait is a main candidate for intensive choice packages to realize speedy enchancment.

6.6 Combining The Outcomes of Heritability (Broad Sense) And Genetic Advance (As P.c of Imply)

Combining heritability (broad-sense heritability) and genetic advance as % of imply (GAM) offers a extra complete understanding of the potential for enchancment of traits in a breeding program. This mix helps in figuring out traits that aren’t solely genetically managed but in addition aware of choice.

SOLVED EXAMPLE

Dataset: The
experiment was laid in Randomized Full Block Design with three replications
in maize (Zea mays L.) by utilizing 30 genotypes. The info have been noticed
from every replication by randomly chosen vegetation for days to 50% flowering. Hyperlink of Dataset

Genotypes

Replications

Genotype whole

Genotype imply

R1

R2

R3

G1

66

75

75

216.00

72.00

G2

68

75

76

219.00

73.00

G3

70

75

80

225.00

75.00

G4

70

81

86

237.00

79.00

G5

72

68

74

214.00

71.33

G6

66

72

80

218.00

72.67

G7

59

63

74

196.00

65.33

G8

66

69

79

214.00

71.33

G9

72

80

78

230.00

76.67

G10

64

66

83

213.00

71.00

G11

84

72

74

230.00

76.67

G12

60

64

75

199.00

66.33

G13

62

68

65

195.00

65.00

G14

63

72

75

210.00

70.00

G15

73

81

70

224.00

74.67

G16

58

84

70

212.00

70.67

G17

77

82

86

245.00

81.67

G18

64

69

75

208.00

69.33

G19

82

82

84

248.00

82.67

G20

72

74

75

221.00

73.67

G21

75

80

78

233.00

77.67

G22

70

76

82

228.00

76.00

G23

76

83

82

241.00

80.33

G24

77

76

75

228.00

76.00

G25

77

83

70

230.00

76.67

G26

76

84

86

246.00

82.00

G27

83

68

72

223.00

74.33

G28

61

75

84

220.00

73.33

G29

67

78

60

205.00

68.33

G30

67

70

78

215.00

71.67

Replication whole

2097

2245

2301


Grand whole

6643

7.1 Evaluation of Variance

Null speculation for genotypes and replication

H0: There are not any vital variations amongst technique of genotypes underneath examine.

Ha: There are not any vital variations amongst technique of replications underneath examine.

Conclusion:

• Low GCV and low PCV for days to 50% flowering point out low variability. The shortage of variability may point out that the trait is both extremely conserved or has reached a variety plateau.

• Heritability is <30 indicated extra affect of setting within the inheritance of the trait

• Low heritability coupled with low genetic advance as per cent of imply point out the choice wouldn’t be rewarding because of environmental fluctuations

7.    
STEPS TO
PERFORM ANALYSIS OF GENETIC PARAMETER ESTIMATION IN AGRI ANALYZE

Step 1: To create a CSV file with columns for Genotype, replication and trait
(DFF). Hyperlink of Dataset

Step 2: Go together with Agri Analyze website.  https://agrianalyze.com/Default.aspx Register by utilizing e mail and cellular quantity

Step 3: Click on on
ANALYTICAL TOOL

Step 4: Click on on GENETICS
AND PLANT BREEDING

Step 5: Click on on GENETIC
PARAMETER ESTIMATION

Step 6: Add the CSV file and choose Genotypes, Replication and Click on on Submit

Output from the evaluation

Gomez, Ok. A., & Gomez, A. A. (1984). Statistical Procedures for Agricultural Analysis. John wiley & sons. 25-30.

Singh, P. and Narayanan, S.S. (1993) Biometrical Methods in Plant Breeding. New Delhi, India: Kalyani Publishers.

Weblog Credit score:

[ad_2]
Gum Illness and Coronary heart Well being: What is the hidden hyperlink?

0

[ad_1]

[1]“Cardiovascular ailments (CVDs),” Who.int. [Online]. Out there: https://www.who.int/news-room/fact-sheets/element/cardiovascular-diseases-(cvds). [Accessed: 25-Sep-2024].[2]S. James Sales space, “Fusobacterium infections☆,” in Reference Module in Biomedical Sciences, Elsevier, 2014.[3]Y. W. Han, “Fusobacterium nucleatum Interplay with Host Cells,” Oral Microbial Communities. Wiley, p. 221, 02-Aug-2011.[4]S. Chaushu et al., “Direct recognition of Fusobacterium nucleatum by the NK cell pure cytotoxicity receptor NKp46 aggravates periodontal illness,” PLoS Pathog., vol. 8, no. 3, p. e1002601, 2012.[5]J. Zhou, L. Liu, P. Wu, L. Zhao, and Y. Wu, “Fusobacterium nucleatum accelerates atherosclerosis through macrophage-driven aberrant proinflammatory response and lipid metabolism,” Entrance. Microbiol., vol. 13, 2022.[6]A. L. Truant, S. Menge, Ok. Milliorn, R. Lairscey, and M. T. Kelly, “Fusobacterium nucleatum pericarditis,” J. Clin. Microbiol., vol. 17, no. 2, pp. 349–351, 1983.[7]M. Febbraio, C. B. Roy, and L. Levin, “Is there a causal hyperlink between periodontitis and heart problems? A concise assessment of current findings,” Int. Dent. J., vol. 72, no. 1, pp. 37–51, 2022.[8]H. Liu, Y. Liu, W. Fan, and B. Fan, “Fusobacterium nucleatum triggers proinflammatory cell demise through Z-DNA binding protein 1 in apical periodontitis,” Cell Commun. Sign., vol. 20, no. 1, 2022.[9]J. O’Brien, H. Hayder, Y. Zayed, and C. Peng, “Overview of MicroRNA biogenesis, mechanisms of actions, and circulation,” Entrance. Endocrinol. (Lausanne), vol. 9, 2018.[10]S. Liu et al., “The host shapes the intestine Microbiota through fecal MicroRNA,” Cell Host Microbe, vol. 19, no. 1, pp. 32–43, 2016.[11]A. Swidsinski et al., “Acute appendicitis is characterised by native invasion with Fusobacterium nucleatum/necrophorum,” Intestine, vol. 60, no. 1, pp. 34–40, 2009.[12]I. Brook, “Fusobacterial infections in kids,” Curr. Infect. Dis. Rep., vol. 15, no. 3, pp. 288–294, 2013.[13]L. Wolff, D. Martiny, V. Y. M. Deyi, E. Maillart, P. Clevenbergh, and N. Dauby, “COVID-19-associated Fusobacterium nucleatum bacteremia, Belgium,” Emerg. Infect. Dis., vol. 27, no. 3, pp. 975–977, 2020.[14]P. J. Ford et al., “Irritation, warmth shock proteins and periodontal pathogens in atherosclerosis: an immunohistologic examine,” Oral Microbiol. Immunol., vol. 21, no. 4, pp. 206–211, 2006.[15]C. A. Brennan and W. S. Garrett, “Fusobacterium nucleatum — symbiont, opportunist and oncobacterium,” Nat. Rev. Microbiol., vol. 17, no. 3, pp. 156–166, 2019.[16]Y. W. Han, “Fusobacterium nucleatum: a commensal-turned pathogen,” Curr. Opin. Microbiol., vol. 23, pp. 141–147, 2015.[17]S. Hopkins et al., “Oral well being and heart problems,” Am. J. Med., vol. 137, no. 4, pp. 304–307, 2024.[18]“Life’s Important 8TM Your guidelines for lifelong good well being,” Coronary heart.org. [Online]. Out there: https://www.coronary heart.org/en/healthy-living/healthy-lifestyle/lifes-essential-8. [Accessed: 25-Sep-2024].

[ad_2]
The way to Learn an Econometrics Paper

0

[ad_1]

Studying and understanding econometrics papers will be arduous work. Most revealed articles, even evaluation articles, are written by specialists for specialists. Until you’re already accustomed to the literature, it may be an actual uphill battle to make it by means of a current paper. In grad faculty I keep in mind our professors repeatedly admonishing me and the remainder of the cohort to “learn the papers!” However once I did my greatest to comply with this recommendation, I practically all the time felt like I used to be banging my head towards a wall.

Efficient studying is a ability that may be realized, and the one option to study is thru observe. However you possibly can study the simple method or the arduous method. The arduous method is to maintain making an attempt and hope for the most effective; the simple method is to regulate your strategy based mostly on the experiences of others. With that in thoughts, this publish gives some suggestions and methods that I’ve picked up by means of the years for studying technical materials effectively and successfully. My audience is PhD college students in Economics, particularly college students within the Econometrics Studying Group at Oxford, however I hope that a number of the following suggestions shall be useful for others as nicely.

You probably have any suggestions of your personal, or when you violently agree or disagree with any of mine, I hope to listen to from you within the feedback part beneath!

Learn One thing Else As a substitute

The primary query to ask your self is whether or not you need to even be studying this paper within the first place. Simply because White’s (1980) paper on heteroskedasticity-robust commonplace errors is a “traditional” in econometrics, that doesn’t imply that you need to learn it. In actual fact, as a graduate pupil simply beginning out, you most likely shouldn’t! The paper that introduces a brand new concept or process isn’t the paper that provides the clearest clarification. Studying an excellent textbook clarification is a way more efficient option to become familiar with a brand new concept. You would possibly, for instance, attempt studying the related chapters in White’s textbook Asymptotic Concept for Econometricians as an alternative.

However generally it’s important to learn a specific paper. Perhaps it’s the paper you’ve been assigned to current in a studying group, or perhaps it’s extremely related to your personal analysis. In that case you should still need to begin by studying one thing else. For instance, there could be a more moderen paper or evaluation article that provides an excellent abstract of the concept or methodology in query. Studying this paper first could make it a lot simpler so that you can sort out the unique paper.

So to all these professors on the market who hold telling their college students to “learn the papers!” I say: “learn the papers, however solely after you’ve learn one thing else first!”

Don’t Assume You Should Perceive the Complete Factor

As a basic rule you need to not anticipate to grasp all the things if you learn a paper. Chances are you’ll solely get 10% on the primary learn, however that’s advantageous! In addition to papers I’ve written myself, there are comparatively few articles that I’ve checked line-by-line from begin to end. Even when you’ve been assigned to current a paper that doesn’t imply that it’s essential perceive each element of each lemma within the on-line technical appendix. As a substitute your aim needs to be to grasp the key concepts and contributions of the paper. Like something in life, there are diminishing returns to effort in studying a paper. When studying papers to help your personal analysis, you will be much more selective. The important thing query turns into: “how is that this related for what I’m doing?” It could be that you simply solely want to grasp a small a part of the paper to get what you want.

Don’t Assume You’re Silly

In case you’re confused, don’t assume that it’s your fault. Discover your confusion and attempt to unravel it with out taking issues as a right or participating in unfavorable self-talk. The one option to study is by getting confused after which unconfusing your self!

Chances are you’ll be confused as a result of the authors assume one thing that you simply don’t. They’re probably specialists within the discipline who’ve spent years desirous about this explicit query. You, however, are simply beginning out. As you achieve a bit extra context, issues might fall quickly into place. (See my subsequent tip beneath.)

Chances are you’ll be confused as a result of the paper is confusingly written. Writing is tough, and technical writing is particularly arduous. The referee course of may even make papers extra complicated, since our current system for evaluating analysis includes a number of rounds of revisions through which the authors should attempt to fulfill referees with differing views. The result’s that revealed papers usually include a considerable component of “cruft” that distracts from the primary message.

Chances are you’ll even be confused as a result of the paper is incorrect! As an excellent Bayesian, you shouldn’t instantly soar to the conclusion that you simply, a newcomer to this discipline, have stumbled upon an important error that everybody else has missed. Alternatively, you positively shouldn’t consider all the things that you simply see in print! All papers are incorrect indirectly, and a few papers are incorrect in critical and essential methods. In case you’re confused, it’s value contemplating whether or not the authors have been confused too!

Unfold Your self Skinny

Let’s say you actually need to become familiar with paper X on matter Y. You’ve learn the related textbook materials, you’ve tried a evaluation article, and also you’re nonetheless struggling. What now? Unusual although it could sound, one useful reply is to learn extra papers on matter Y in an especially shallow method. Skim the abstracts, introductions, and conclusions. Be aware any phrases or ideas that hold showing, particularly ones that you simply don’t perceive.

I can consider many events once I skimmed 9 papers and didn’t perceive any of them, however then learn a tenth and instantly all the things clicked. The important thing right here is context. If you’re new to matter Y, there shall be numerous little issues that you simply’ve by no means considered earlier than however that the literature takes as a right. Since most papers are written for specialists by specialists, essential particulars are sometimes not noted or glossed over as in the event that they have been apparent. Simply as fish don’t notice that they’re in water, specialists usually fail to understand that they’re taking quite a lot of issues as a right. The explanation that studying many papers will help is that completely different specialists will miss completely different particulars. The important thing that it’s essential perceive paper X could be a seemingly throwaway remark in paper Z!

Clarify It to Somebody Else

One of the simplest ways to grasp one thing is by making an attempt to clarify it to another person. This holds true even when the “another person” in query is only a figment of your creativeness. As you learn, begin by making an attempt to clarify the paper to your self in your personal phrases. I discover it useful to jot down within the margins of the paper as I’m going, summarizing the important thing concepts with much less jargon and less complicated terminology and notation. If you’re confused about one thing, attempt to put your confusion into phrases; make it concrete and write it down.

Speaking to an actual particular person will be much more useful. In case you’re in a studying group, attempt discussing the paper informally with one your friends who has additionally learn it. Chances are you’ll be stunned at how a lot two individuals, neither of whom understands one thing on their very own, can study from one another. On this courageous new world of LLMs like Claude and GPT4o, you can even attempt importing your paper and discussing it with an AI. You can’t assume that the AI will essentially offer you dependable details about the paper, however identical to a peer who solely partially understands it, an AI is usually a helpful sounding board on your personal concepts and confusions. Noticing errors within the AI’s understanding, pointing them out and persevering with the dialog may also be an effective way to make clear your personal considering.

Head Straight for the Simulation / Empirical Instance

Ideally each paper would have a implausible introduction that makes it clear what the paper is about and why it’s essential. In actual life, introductions will be hit-or-miss. So after studying the introduction, you would possibly think about heading straight for the simulation research and/or empirical instance. Most econometrics papers suggest a technique that solves a specific downside. What’s the downside, and why does the actual information producing course of (DGP) within the simulation (or the actual information within the empirical instance) exhibit it? What parameters of the simulation DGP management the extent of the issue? What’s the “previous” methodology on which the paper improves? That is prone to be one thing acquainted comparable to a “textbook” methodology. How precisely is the brand new methodology applied? In different phrases, how precisely is it computed from actual or simulated information? Attempt to write down all of the steps within the implementation in a sufficiently exact method that you can code it your self.

As soon as you know the way to reply these questions you’re in a a lot better place to grasp the remainder of the paper. As you learn by means of the assumptions and theorems, refer again to the simulation research. Why does the DGP fulfill the assumptions? Are you able to consider a unique DGP through which the assumptions fail? Is there something “fishy” concerning the simulation instance? Does it look like the authors have cooked the books indirectly, e.g. by introducing a really “delicate” model of the central downside, or one thing else that will be unrealistic in observe? Answering these questions will assist you to consider the paper, perceive its limitations and presumably take into consideration learn how to enhance upon it.

Make Issues Less complicated

Many econometrics papers current outcomes at an especially excessive degree of generality. On the one hand this can be a good factor. A lot of the ability of arithmetic comes from abstraction and basic outcomes are extra widely-applicable. However from an expositional standpoint, that is horrible. This historical past of arithmetic is a historical past of concrete issues to particular issues that have been progressively generalized and expanded over time. The historical past of concepts mirrors the best way that the typical particular person learns most successfully: by beginning with concrete examples after which generalizing.

With this in thoughts, attempt to simplify the theorems and examples within the paper. Eliminating covariates usually cuts down on each algebra and notation, so begin with this. Attempt re-writing the assumptions and theorems on this less complicated notation. Are a number of the assumptions complicated? Attempt strengthening them or attempt to see if you’ll find a concrete instance through which they maintain, presumably taken from the simulation DGP.

Don’t Get Hung Up on Technicalities

Some components of a paper are “core materials” and a few components are “technicalities”. Maintaining these separate in your thoughts will make it a lot simpler to grasp a paper. One useful strategy is to make a dependency tree of the assumptions, lemmas, and theorems earlier than making an attempt to grasp them. When you see how issues match collectively you might discover, for instance, that the one position of Proposition 3 is to determine that an acceptable Central Restrict Theorem holds and the one position of Assumptions 2-6 is to show Proposition 3. Improbable! On this case, simply assume the conclusion of Proposition 3 and transfer on to see the place that is wanted within the core outcomes. Even if you’re studying assumptions, lemmas, propositions, theorems, and proofs, try to be aiming to get the “large image” fairly than to assimilate each tiny element.

Be Appropriately Skeptical of Asymptotics

Asymptotics are an important device in econometrics however keep in mind that it’s finite pattern properties that we really care about. The “asymptotic distribution” of an estimator is only a thought experiment, not one thing you possibly can take to the financial institution. An asymptotic argument is a form of approximation that in impact supposes that sure issues are “negligible.” This approximation may very well be implausible or it may very well be horrible. It’s solely by means of simulation research that we are able to actually know which is the case. Or, to cite van der Vaart (1998),

strictly talking, most asymptotic outcomes which can be presently accessible are logically ineffective. It’s because most asymptotic outcomes are restrict outcomes, fairly than approximations consisting of an approximating system plus an correct error sure … Because of this there’s good asymptotics and unhealthy asymptotics and why two forms of asymptotics generally result in conflicting claims … As a result of it could be theoretically very arduous to determine that approximation errors are small, one usually takes recourse to simulation research

For an instance of “good” versus “unhealthy” asymptotics utilized to energy evaluation, see this publish.

[ad_2]
Generate Gremlin queries utilizing Amazon Bedrock fashions

0

[ad_1]

Graph databases have revolutionized how organizations handle advanced, interconnected information. Nevertheless, specialised question languages reminiscent of Gremlin usually create a barrier for groups trying to extract insights effectively. Not like conventional relational databases with well-defined schemas, graph databases lack a centralized schema, requiring deep technical experience for efficient querying.

To deal with this problem, we discover an method that converts pure language to Gremlin queries, utilizing Amazon Bedrock fashions reminiscent of Amazon Nova Professional. This method helps enterprise analysts, information scientists, and different non-technical customers entry and work together with graph databases seamlessly.

On this submit, we define our methodology for producing Gremlin queries from pure language, evaluating totally different methods and demonstrating how one can consider the effectiveness of those generated queries utilizing giant language fashions (LLMs) as judges.

Answer overview

Reworking pure language queries into Gremlin queries requires a deep understanding of graph buildings and the domain-specific data encapsulated throughout the graph database. To attain this, we divided our method into three key steps:

  • Understanding and extracting graph data
  • Structuring the graph just like text-to-SQL processing
  • Producing and executing Gremlin queries

The next diagram illustrates this workflow.

Step 1: Extract graph data

A profitable question technology framework should combine each graph data and area data to precisely translate pure language queries. Graph data encompasses structural and semantic info extracted immediately from the graph database. Particularly, it contains:

  • Vertex labels and properties – A list of vertex sorts, names, and their related attributes
  • Edge labels and properties – Details about edge sorts and their attributes
  • One-hop neighbors for every vertex – Capturing native connectivity info, reminiscent of direct relationships between vertices

With this graph-specific data, the framework can successfully cause concerning the heterogeneous properties and sophisticated connections inherent to graph databases.

Area data captures extra context that augments the graph data and is tailor-made particularly to the applying area. It’s sourced in two methods:

  • Buyer-provided area data – For instance, the shopper kscope.ai helped specify these vertices that symbolize metadata and will by no means be queried. Such constraints are encoded to information the question technology course of.
  • LLM-generated descriptions – To reinforce the system’s understanding of vertex labels and their relevance to particular questions, we use an LLM to generate detailed semantic descriptions of vertex names, properties, and edges. These descriptions are saved throughout the area data repository and supply extra context to enhance the relevance of the generated queries.

Step 2: Construction the graph as a text-to-SQL schema

To enhance the mannequin’s comprehension of graph buildings, we undertake an method just like text-to-SQL processing, the place we assemble a schema representing vertex sorts, edges, and properties. This structured illustration enhances the mannequin’s potential to interpret and generate significant queries.

The query processing part transforms pure language enter into structured components for question technology. It operates in three levels:

  • Entity recognition and classification – Identifies key database components within the enter query (reminiscent of vertices, edges, and properties) and categorizes the query primarily based on its intent
  • Context enhancement – Enriches the query with related info from the data part, so each graph-specific and domain-specific context is correctly captured
  • Question planning – Maps the improved query to particular database components wanted for question execution

The context technology part makes positive the generated queries precisely mirror the underlying graph construction by assembling the next:

  • Ingredient properties – Retrieves attributes of vertices and edges together with their information sorts
  • Graph construction – Facilitates alignment with the database’s topology
  • Area guidelines – Applies enterprise constraints and logic

Step 3: Generate and execute Gremlin queries

The ultimate step is question technology, the place the LLM constructs a Gremlin question primarily based on the extracted context. The method follows these steps:

  1. The LLM generates an preliminary Gremlin question.
  2. The question is executed inside a Gremlin engine.
  3. If the execution is profitable, outcomes are returned.
  4. If execution fails, an error message parsing mechanism analyzes the returned errors and refines the question utilizing LLM-based suggestions.

This iterative refinement makes positive the generated queries align with the database’s construction and constraints, bettering general accuracy and usefulness.

Immediate template

Our closing immediate template is as follows:

## Request
Please write a gremlin question to reply the given query:
{{query}}
You may be supplied with couple related vertices, along with their 
schema and different info.
Please select essentially the most related vertex in accordance with its schema and different 
info to make the gremlin question appropriate.


## Directions
1. Listed below are associated vertices and their particulars:
{{schema}}
2. Do not rename properties.
3. Do not change strains (utilizing slash n) within the generated question.


## IMPORTANT
Return the ends in the next XML format:


    INSERT YOUR QUERY HERE
    
        PROVIDE YOUR EXPLANATION ON HOW THIS QUERY WAS GENERATED 
        AND HOW THE PROVIDED SCHEMA WAS LEVERAGED
    

Evaluating LLM-generated queries to floor fact

We carried out an LLM-based analysis system utilizing Anthropic’s Claude 3.5 Sonnet on Amazon Bedrock as a choose to evaluate each question technology and execution outcomes for Amazon Nova Professional and a benchmark mannequin. The system operates in two key areas:

  • Question analysis – Assesses correctness, effectivity, and similarity to ground-truth queries; calculates precise matching part percentages; and gives an general score primarily based on predefined guidelines developed with area specialists
  • Execution analysis – Initially used a single-stage method to check generated outcomes with floor fact, then enhanced to a two-stage analysis course of:
    • Merchandise-by-item verification towards floor fact
    • Calculation of general match share

Testing throughout 120 questions demonstrated the framework’s potential to successfully distinguish appropriate from incorrect queries. The 2-stage method notably improved the reliability of execution outcome analysis by conducting thorough comparability earlier than scoring.

Experiments and outcomes

On this part, we focus on the experiments we performed and their outcomes.

Question similarity

Within the question analysis case, we suggest two metrics: question precise match and question general score. A precise match rating is calculated by figuring out matching vs. non-matching elements between generated and floor fact queries. The next desk summarizes the scores for question precise match.

SimpleMediumExhaustingGeneral
Amazon Nova Professional82.70%61%46.60%70.36%
Benchmark Mannequin 92.60%68.70%56.20%78.93%

An general score is supplied after contemplating elements together with question correctness, effectivity, and completeness as instructed within the immediate. The general score is on scale 1–10. The next desk summarizes the scores for question general score.

SimpleMediumExhaustingGeneral
Amazon Nova Professional8.775.37.6
Benchmark Mannequin9.786.18.5

One limitation within the present question analysis setup is that we rely solely on the LLM’s potential to check floor fact towards LLM-generated queries and arrive on the closing scores. Consequently, the LLM can fail to align with human preferences and under- or over-penalize the generated question. To deal with this, we advocate working with a topic professional to incorporate domain-specific guidelines within the analysis immediate.

Execution accuracy

To calculate accuracy, we examine the outcomes of the LLM-generated Gremlin queries towards the outcomes of floor fact queries. If the outcomes from each queries match precisely, we rely the occasion as appropriate; in any other case, it’s thought of incorrect. Accuracy is then computed because the ratio of appropriate question executions to the full variety of queries examined. This metric gives an easy analysis of how nicely the model-generated queries retrieve the anticipated info from the graph database, facilitating alignment with the supposed question logic.

The next desk summarizes the scores for execution outcomes rely match.

SimpleMediumExhaustingGeneral
Amazon Nova Professional80%50%10%60.42%
Benchmark Mannequin90%70%30%74.83%

Question execution latency

Along with accuracy, we consider the effectivity of generated queries by measuring their runtime and evaluating it with the bottom fact queries. For every question, we file the runtime in milliseconds and analyze the distinction between the generated question and the corresponding floor fact question. A decrease runtime signifies a extra optimized question, whereas vital deviations may recommend inefficiencies in question construction or execution planning. By contemplating each accuracy and runtime, we achieve a extra complete evaluation of question high quality, ensuring the generated queries are appropriate and performant throughout the graph database. The next field plot showcases question execution latency with respect to time for the bottom fact question and the question generated by Amazon Nova Professional. As illustrated, all three kinds of queries exhibit comparable runtimes, with related median latencies and overlapping interquartile ranges. Though the bottom fact queries show a barely wider vary and the next outlier, the median values throughout all three teams stay shut. This implies that the model-generated queries are on the similar stage as human-written ones by way of execution effectivity, supporting the declare that AI-generated queries are of comparable high quality and don’t incur extra latency overhead.

Question technology latency and price

Lastly, we examine the time taken to generate every question and calculate the associated fee primarily based on token consumption. Extra particularly, we measure the question technology time and observe the variety of tokens used, as a result of most LLM-based APIs cost primarily based on token utilization. By analyzing each the technology velocity and token price, we are able to decide whether or not the mannequin is environment friendly and cost-effective. These outcomes present insights in deciding on the optimum mannequin that balances question accuracy, execution effectivity, and financial feasibility.

As proven within the following plots, Amazon Nova Professional persistently outperforms the benchmark mannequin in each technology latency and price. Within the left plot, which depicts question technology latency, Amazon Nova Professional demonstrates a considerably decrease median technology time, with most values clustered between 1.8–4 seconds, in comparison with the benchmark mannequin’s broader vary from round 5–11 seconds. The precise plot, illustrating question technology price, exhibits that Amazon Nova Professional maintains a a lot smaller price per question—centered nicely under $0.005—whereas the benchmark mannequin incurs increased and extra variable prices, reaching as much as $0.025 in some instances. These outcomes spotlight Amazon Nova Professional’s benefit by way of each velocity and affordability, making it a powerful candidate for deployment in time-sensitive or large-scale techniques.

Graph showing latency cost

Conclusion

We experimented with all 120 floor fact queries supplied to us by kscope.ai and achieved an general accuracy of 74.17% in producing appropriate outcomes. The proposed framework demonstrates its potential by successfully addressing the distinctive challenges of graph question technology, together with dealing with heterogeneous vertex and edge properties, reasoning over advanced graph buildings, and incorporating area data. Key elements of the framework, reminiscent of the mixing of graph and area data, the usage of Retrieval Augmented Technology (RAG) for question plan creation, and the iterative error-handling mechanism for question refinement, have been instrumental in reaching this efficiency.

Along with bettering accuracy, we’re actively engaged on a number of enhancements. These embody refining the analysis methodology to deal with deeply nested question outcomes extra successfully and additional optimizing the usage of LLMs for question technology. Furthermore, we’re utilizing the RAGAS-faithfulness metric to enhance the automated analysis of question outcomes, leading to higher reliability and consistency in assessing the framework’s outputs.


Concerning the authors

Mengdie (Flora) Wang is a Information Scientist at AWS Generative AI Innovation Middle, the place she works with clients to architect and implement scalable Generative AI options that handle their distinctive enterprise challenges. She focuses on mannequin customization methods and agent-based AI techniques, serving to organizations harness the total potential of generative AI expertise. Previous to AWS, Flora earned her Grasp’s diploma in Laptop Science from the College of Minnesota, the place she developed her experience in machine studying and synthetic intelligence.
Jason Zhang has experience in machine studying, reinforcement studying, and generative AI. He earned his Ph.D. in Mechanical Engineering in 2014, the place his analysis targeted on making use of reinforcement studying to real-time optimum management issues. He started his profession at Tesla, making use of machine studying to automobile diagnostics, then superior NLP analysis at Apple and Amazon Alexa. At AWS, he labored as a Senior Information Scientist on generative AI options for purchasers.
Rachel Hanspal is a Deep Studying Architect at AWS Generative AI Innovation Middle, specializing in end-to-end GenAI options with a give attention to frontend structure and LLM integration. She excels in translating advanced enterprise necessities into progressive functions, leveraging experience in pure language processing, automated visualization, and safe cloud architectures.
Zubair Nabi is the CTO and Co-Founding father of Kscope, an Built-in Safety Posture Administration (ISPM) platform. His experience lies on the intersection of Huge Information, Machine Studying, and Distributed Programs, with over a decade of expertise constructing software program, information, and AI platforms. Zubair can also be an adjunct school member at George Washington College and the writer of Professional Spark Streaming: The Zen of Actual-Time Analytics Utilizing Apache Spark. He holds an MPhil from the College of Cambridge.
Suparna Pal – CEO & Co-Founding father of kscope.ai – 20+ years of journey of constructing progressive platforms & options for Industrial, Well being Care and IT operations at PTC, GE, and Cisco.
Wan Chen is an Utilized Science Supervisor at AWS Generative AI Innovation Middle. As a ML/AI veteran in tech trade, she has wide selection of experience on conventional machine studying, recommender system, deep studying and Generative AI. She is a stronger believer of Superintelligence and may be very passionate to push the boundary of AI analysis and software to reinforce human life and drive enterprise development. She holds Ph.D in Utilized Arithmetic from College of British Columbia and had labored as postdoctoral fellow in Oxford College.
Mu Li is a Principal Options Architect with AWS Vitality. He’s additionally the Worldwide Tech Chief for the AWS Vitality & Utilities Technical Subject Group (TFC), a neighborhood of 300+ trade and technical specialists. Li is obsessed with working with clients to realize enterprise outcomes utilizing expertise. Li has labored with clients emigrate all-in to AWS from on-prem and Azure, launch the Manufacturing Monitoring and Surveillance trade answer, deploy ION/OpenLink Endur on AWS, and implement AWS-based IoT and machine studying workloads. Outdoors of labor, Li enjoys spending time together with his household, investing, following Houston sports activities groups, and catching up on enterprise and expertise.

[ad_2]