Home Blog Page 23

Ought to I purchase an iPad now or wait? Finest time to purchase an iPad in 2026

0

[ad_1]

[ad_2]

San Francisco Calls for Apple and Google Delete AI ‘Nudify’ Apps From App Shops

0

[ad_1]

Apple and Google have been ordered to take down apps that may “nudify” or “undress” individuals and informed that they need to cease cashing in on the dangerous expertise, in response to cease-and-desist letters despatched to the businesses seen by WIRED.

On Thursday, San Francisco metropolis lawyer David Chiu despatched authorized notices to Apple and Google demanding that they take away from their app shops 13 face-swapping apps, which permit customers to create AI-generated nonconsensual nude photographs. The letters say the Silicon Valley giants ought to cease “aiding and abetting” the sale of specific deepfake photographs and “sever” enterprise relationships with the app builders.

“Producing non-consensual intimate photographs is prohibited, dangerous, and utterly unacceptable,” Chiu tells WIRED. The town lawyer, whose workplace beforehand took authorized motion in opposition to 16 widespread deepfake web sites, says Apple and Google have probably “made hundreds of thousands of {dollars} in charges” from apps that supply nudification, and they need to enhance their moderation processes to cease them showing of their shops within the first place.

“These firms have accountability to make sure that apps on their platforms don’t facilitate sexual abuse,” Chiu says. The town’s authorized letters say California’s legal guidelines prohibit supporting companies that create deepfake pornography. The apps use in-app funds, which the tech firms take a lower of, the letters says. “The truth that a number of the world’s largest and most established expertise firms are facilitating this has to cease.”

Researchers have repeatedly discovered and reported apps in Apple’s App Retailer and Google’s Play Retailer that enable individuals to generate sexual photographs utilizing AI—together with some apps being rated as appropriate to be used by kids. Whereas new legal guidelines and bans purpose to sort out the scourge of specific deepfakes on-line, expertise and social media firms constantly direct hundreds of thousands of individuals towards the dangerous tech.

Each Apple and Google have developer insurance policies that prohibit pornography, abuse, and harassment on their platforms. They’ve beforehand eliminated dozens of nudify and deepfake apps, after stories by researchers and journalists.

Google spokesperson Dan Jackson tells WIRED that the corporate has deleted “a whole lot” of apps with nudifying options for coverage violations, together with the 5 Android apps flagged by Chiu’s workplace, amongst different steps to limit entry to them.

“Google Play doesn’t enable apps that comprise sexual content material, and we regularly take proactive steps to detect and take away apps with dangerous content material,” Jackson says in a press release. “When violations are reported to us, we examine and take swift motion, which within the case of those apps has included suspending a whole lot of violating apps and limiting associated search phrases like ‘nudify’ on our retailer.”

Apple didn’t present remark forward of publication.

Over the past 5 years, a extremely profitable slurry of deepfake “nudification” tech has emerged on-line—most transparently with xAI’s Grok getting used to create hundreds of thousands of sexualized photographs in January. A bunch of apps, web sites, and bots enable individuals (largely males) to add photos of individuals (overwhelmingly girls and ladies) and digitally “take away” clothes or place them into graphic sexual eventualities.

Usually all it takes to create sexual deepfakes is a reference picture and a few clicks, with some outcomes obtainable in seconds. Pictures and movies have change into extra sensible because the underlying generative AI expertise has improved, with companies offering some outcomes totally free or charging small charges to create the dangerous content material. Earlier reporting by WIRED and Indicator Media has uncovered incidents in a minimum of 90 faculties the place deepfake sexual abuse photographs have been created of minors.

[ad_2]

GPT-5.6 Sol vs. Claude Fable 5: Benchmarks, Pricing & Palms-On

[ad_1]

GPT-5.6 Sol and Claude Fable 5 are at present combating for the frontier-model crown.

Fable 5 holds a slight edge normally intelligence, whereas Sol hits again with stronger coding efficiency, sooner execution and far decrease pricing. In reality, GPT-5.6 Sol is priced nearer to Claude Opus 4.8 than to Fable 5, which makes this comparability much more fascinating.

One mannequin guarantees deeper reasoning. The opposite provides near-frontier efficiency at a much more sensible value.

So, which mannequin must you truly use?

What’s GPT-5.6 Sol?

GPT-5.6 Sol is OpenAI’s flagship mannequin for coding, analysis, software use and complicated skilled workflows.

For harder issues, it helps max reasoning, permitting the mannequin to spend extra compute earlier than answering. Its extremely mode goes a step additional by deploying a number of brokers in parallel, making it higher suited to massive coding duties, deep analysis and multi-step tasks.

Learn extra: GPT-5.6: Sol, Terra, and Luna

What’s Claude Fable 5?

Claude Fable 5

Claude Fable 5 is Anthropic’s most succesful publicly out there mannequin, constructed for advanced reasoning and long-running agentic work.

Inside Claude Code or Managed Brokers, it will possibly plan multi-step duties, delegate work to sub-agents, evaluate intermediate outcomes and refine its personal output. That makes it particularly helpful for big coding tasks, deep analysis and assignments that require much less human supervision.

Learn extra: Fable 5: Fantasy(os) or Actuality

Pricing Comparability

API costs per million tokens:

Mannequin Enter Cached Enter Output
GPT-5.6 Sol$5$0.50$30
Claude Fable 5$10$1$50

Sol prices half as a lot for enter and 40% much less for output.

Each fashions supply roughly a million tokens of context and as much as 128,000 output tokens. Sol’s context window is barely bigger at 1.05 million tokens.

There may be one catch. Sol requests crossing 272,000 enter tokens obtain greater pricing for all the request.

Pricing winner: GPT-5.6 Sol

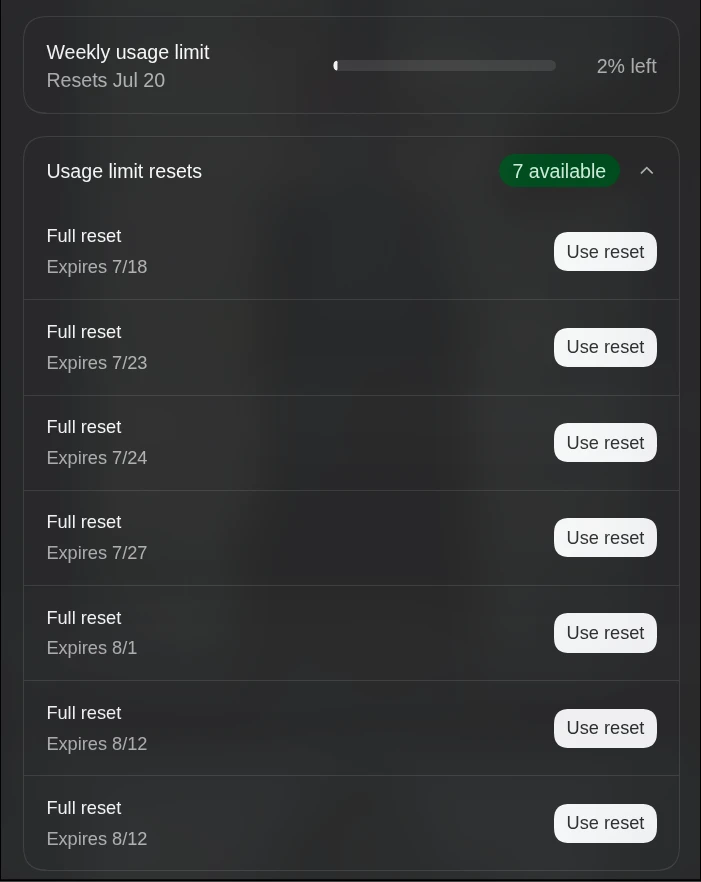
For regular workloads, it’s not shut. Not solely Sol has the next restrict but additionally provides free to make use of token resets sometimes: 

ChatGPT Sol offering free usage limit resets

One thing that Anthropic can clearly be taught!

Palms-On Comparability

To check GPT-5.6 Sol and Claude Fable 5 pretty, I used the identical immediate, recent chats and default reasoning settings for each fashions.

The outputs have been judged on instruction following, correctness, completeness and presentation.

Take a look at 1: Construct a Internet Software

This take a look at checks frontend coding, design high quality and useful completeness.

Immediate:

Construct a responsive private finance dashboard as a single HTML file.

Necessities:
- Use solely HTML, CSS and vanilla JavaScript
- Embrace playing cards for revenue, bills, financial savings and investments
- Add an interactive month-to-month spending chart
- Add a transaction desk with search and class filters
- Embrace gentle and darkish modes
- Use life like pattern knowledge
- Make the design clear and appropriate for a contemporary fintech product
- Return the entire working code in a single file

GPT 5.6 Sol Response:

It took the mannequin 6 minutes and 30 seconds to reply with the specified webpage. Right here it’s:

Claude Fable 5 Response:

It took the mannequin 3 minutes and 10 seconds to reply with the specified webpage. Right here it’s:

Take a look at 2: Information Evaluation and Enterprise Reasoning

This take a look at checks analytical depth, numerical accuracy and the flexibility to supply helpful suggestions.

Immediate:

You're a senior knowledge analyst reviewing the quarterly efficiency of an e-commerce firm.

Quarterly knowledge:

Q1:
Income: $2.4 million
Orders: 48,000
Conversion fee: 2.8%
Buyer acquisition value: $31
Repeat buy fee: 22%

Q2:
Income: $2.7 million
Orders: 51,000
Conversion fee: 3.1%
Buyer acquisition value: $36
Repeat buy fee: 24%

Q3:
Income: $2.9 million
Orders: 54,000
Conversion fee: 3.4%
Buyer acquisition value: $43
Repeat buy fee: 23%

This fall:
Income: $3.1 million
Orders: 56,000
Conversion fee: 3.3%
Buyer acquisition value: $51
Repeat buy fee: 20%
Analyse the corporate’s efficiency.

Embrace:
- The three most vital tendencies
- Any warning indicators
- Probably causes behind the modifications
- 5 actions the corporate ought to take subsequent quarter
- A concise govt abstract

Don't merely repeat the numbers. Derive helpful enterprise insights from them.

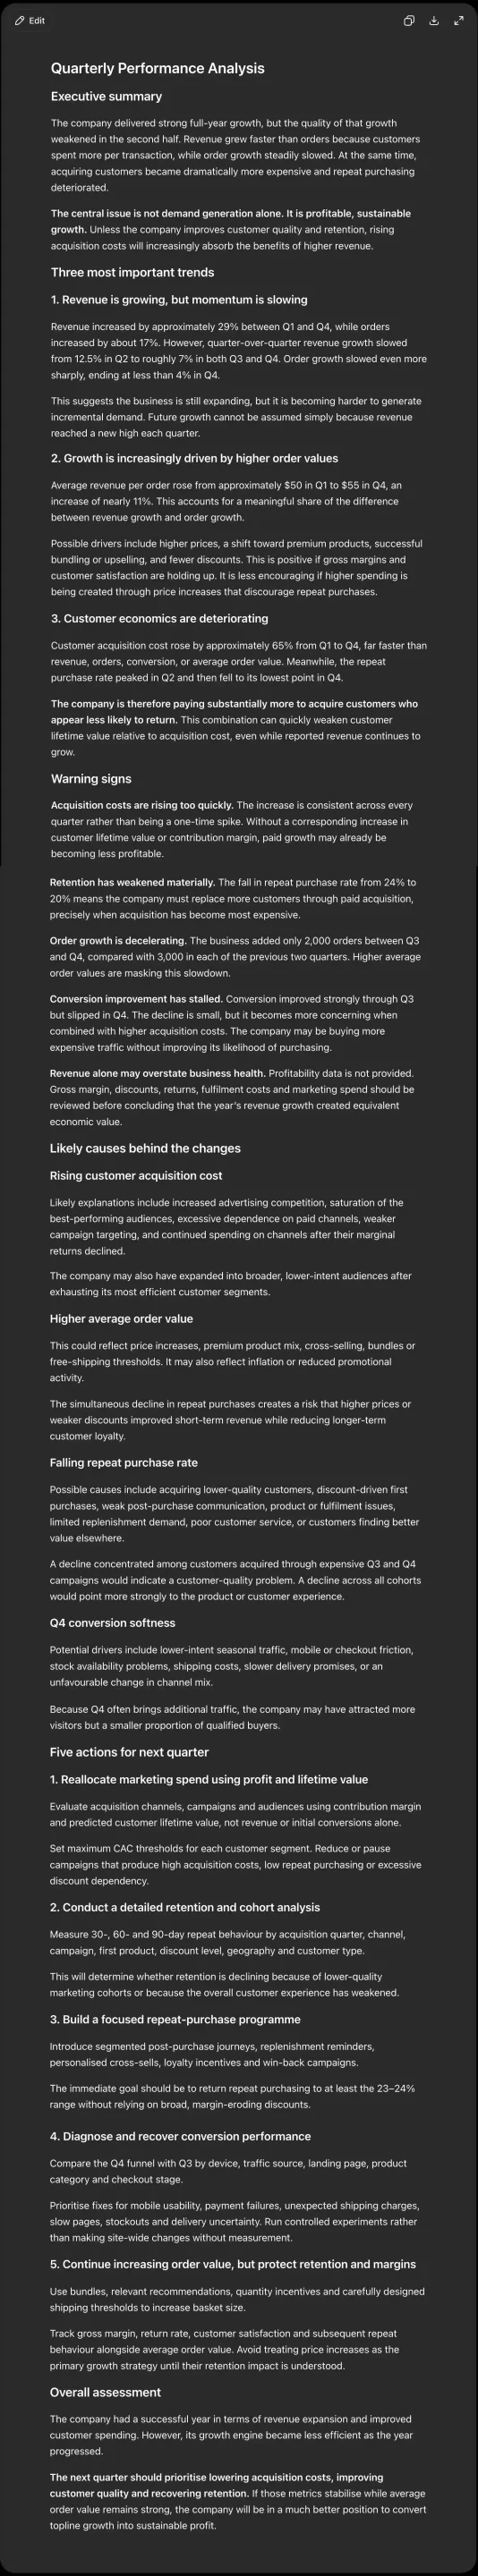
GPT 5.6 Sol Response:

The mannequin took 1 minute and 20 seconds to reply with: 

Click on right here to view the complete response
Full response of ChatGPT Sol High

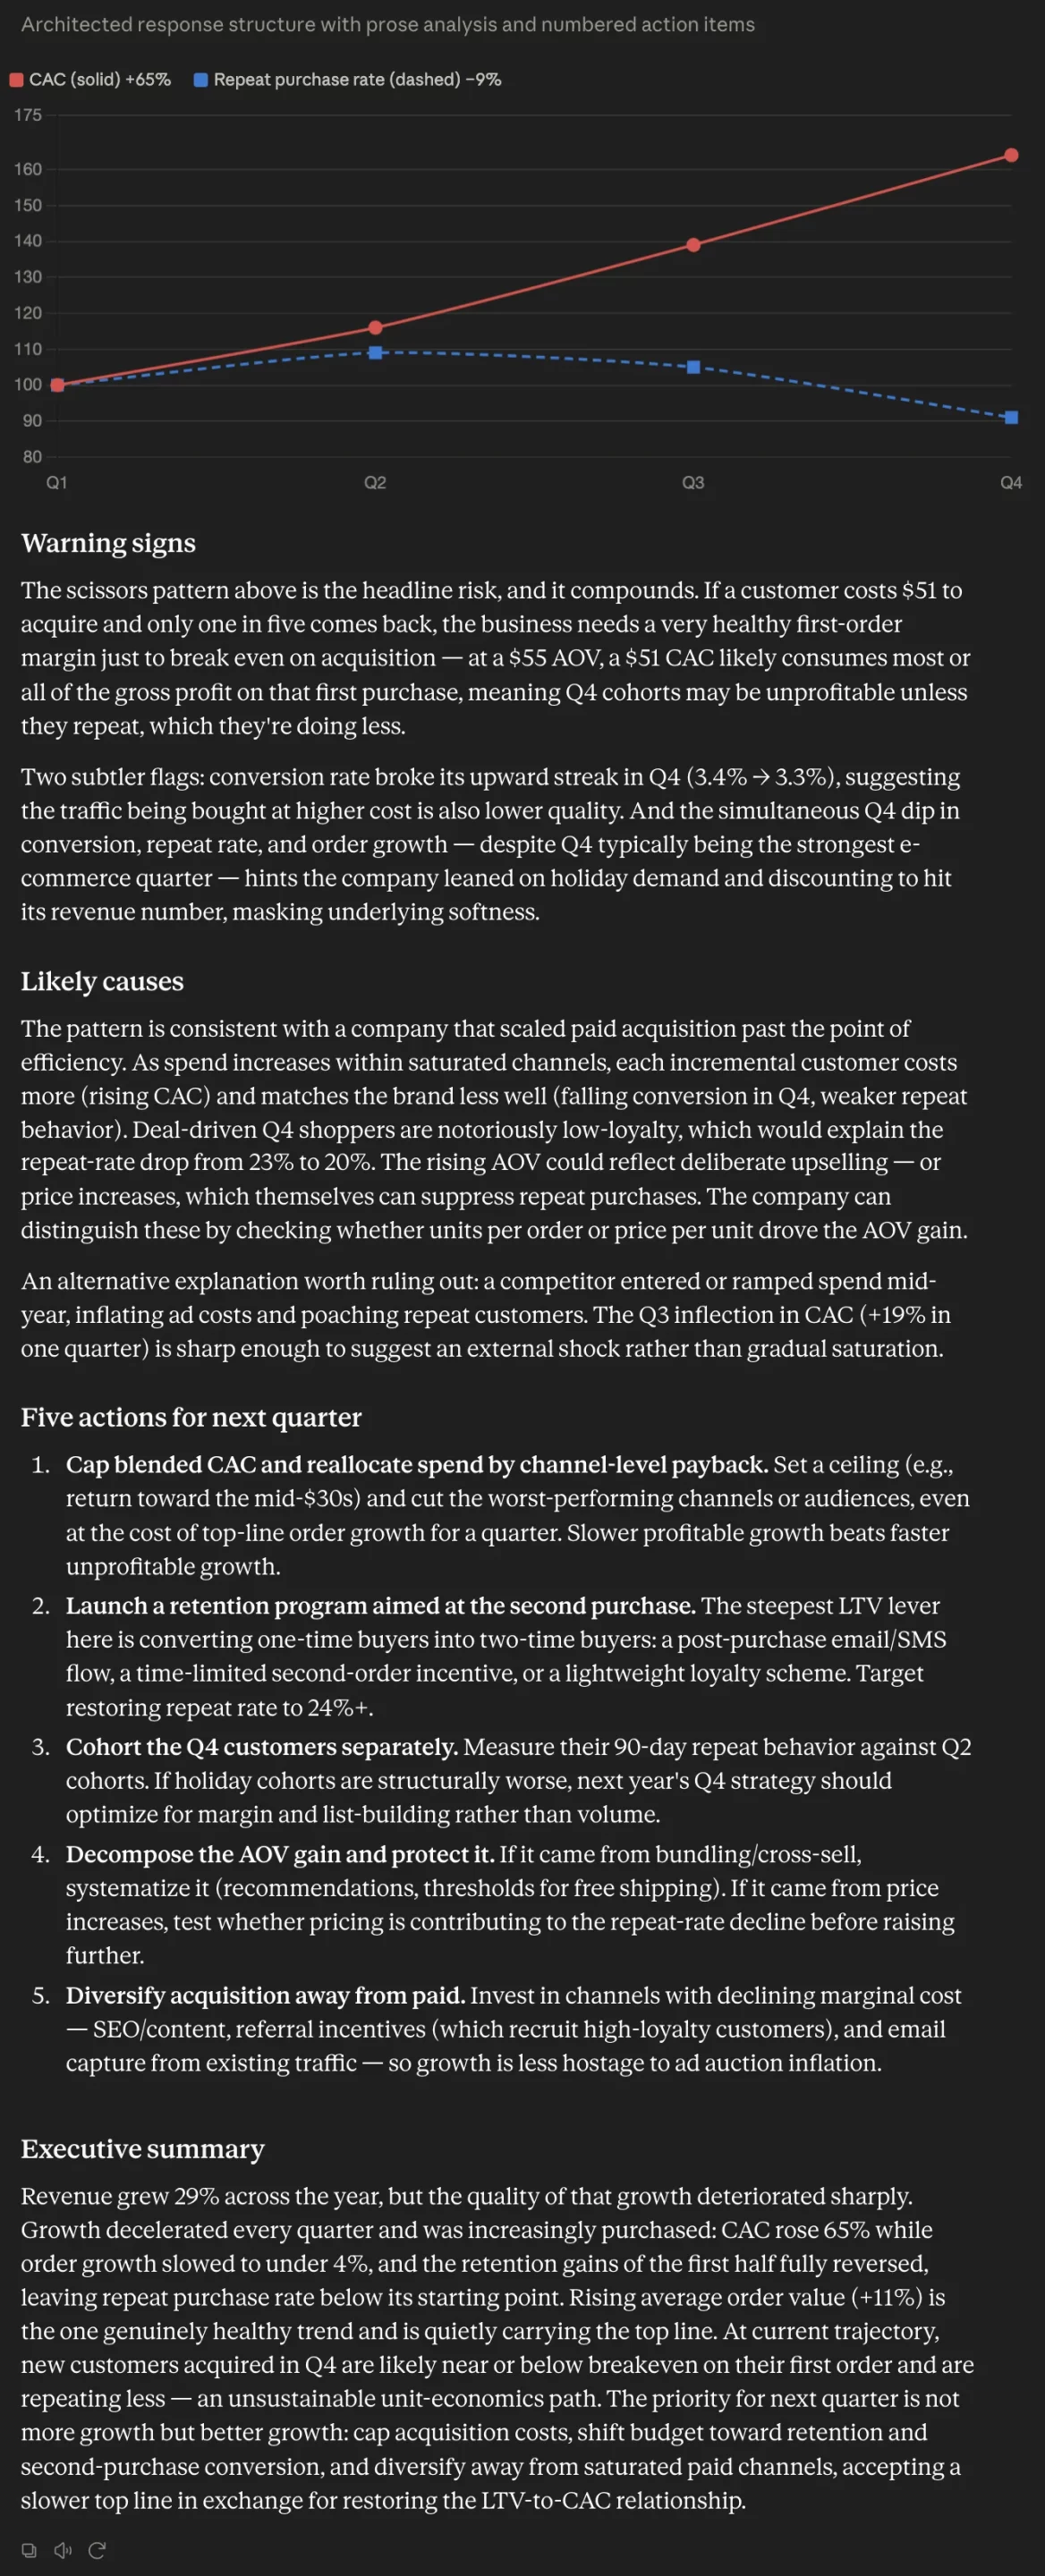
Claude Fable 5 Response:

The mannequin took a minute to reply with:

Click on right here to view the complete response
Full response of Claude Fable 5 High

Take a look at 3: Presentation Creation

This take a look at checks content material construction, visible judgement and the standard {of professional} deliverables.

Immediate:

Create an eight-slide investor presentation for an AI-powered recruitment platform.

The platform:
- Screens job functions
- Matches candidates with appropriate roles
- Generates structured interview questions
- Supplies hiring analytics
- Targets mid-sized know-how firms

Embrace:
1. Title slide
2. Downside
3. Answer
4. Product workflow
5. Market alternative
6. Enterprise mannequin
7. Aggressive benefit
8. Closing slide

Use life like pattern numbers the place required.

GPT 5.6 Sol Response:

It took Sol 4 minutes and 38 seconds to answer the question with: 

Claude Fable 5 Response:

It took Fable 5, 2 minutes and 30 seconds to answer the question with:

Verdict

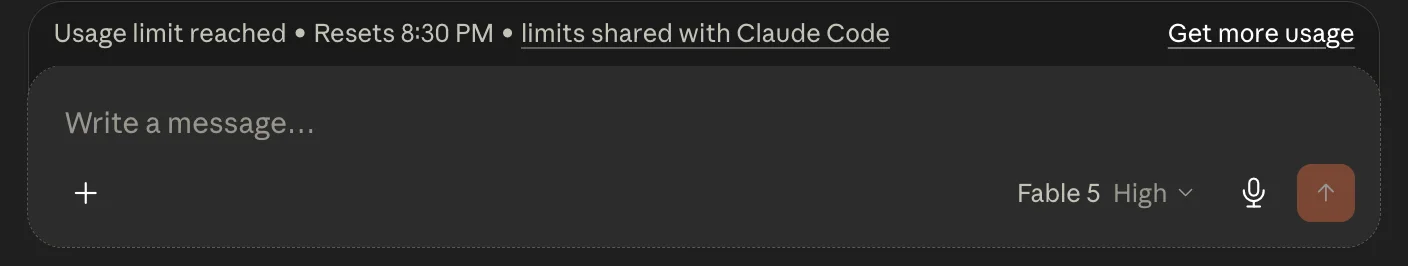
The most important distinction between the 2 needs to be the utilization limits. GPT 5.6 Sol by no means ran out of utilization, no matter how lengthy I had used it for. Claude Fable 5 however, hog’d by the utilization restrict. 3-4 conversations and I used to be greeted with: 

Limit reached in Fable 5

Contemplating the truth that Fable 5 is offered until 19 July whereas Sol is there completely for all of the paid customers and that the pricing of Fable 5 is 2-3 occasions. But it surely does take its time. I imply a lot of time!

On a median it took sol twice the time it took Fable 5 for responding to the identical question (with comparable response high quality). 

GPT-5.6 Sol vs Claude Fable 5: Benchmarks

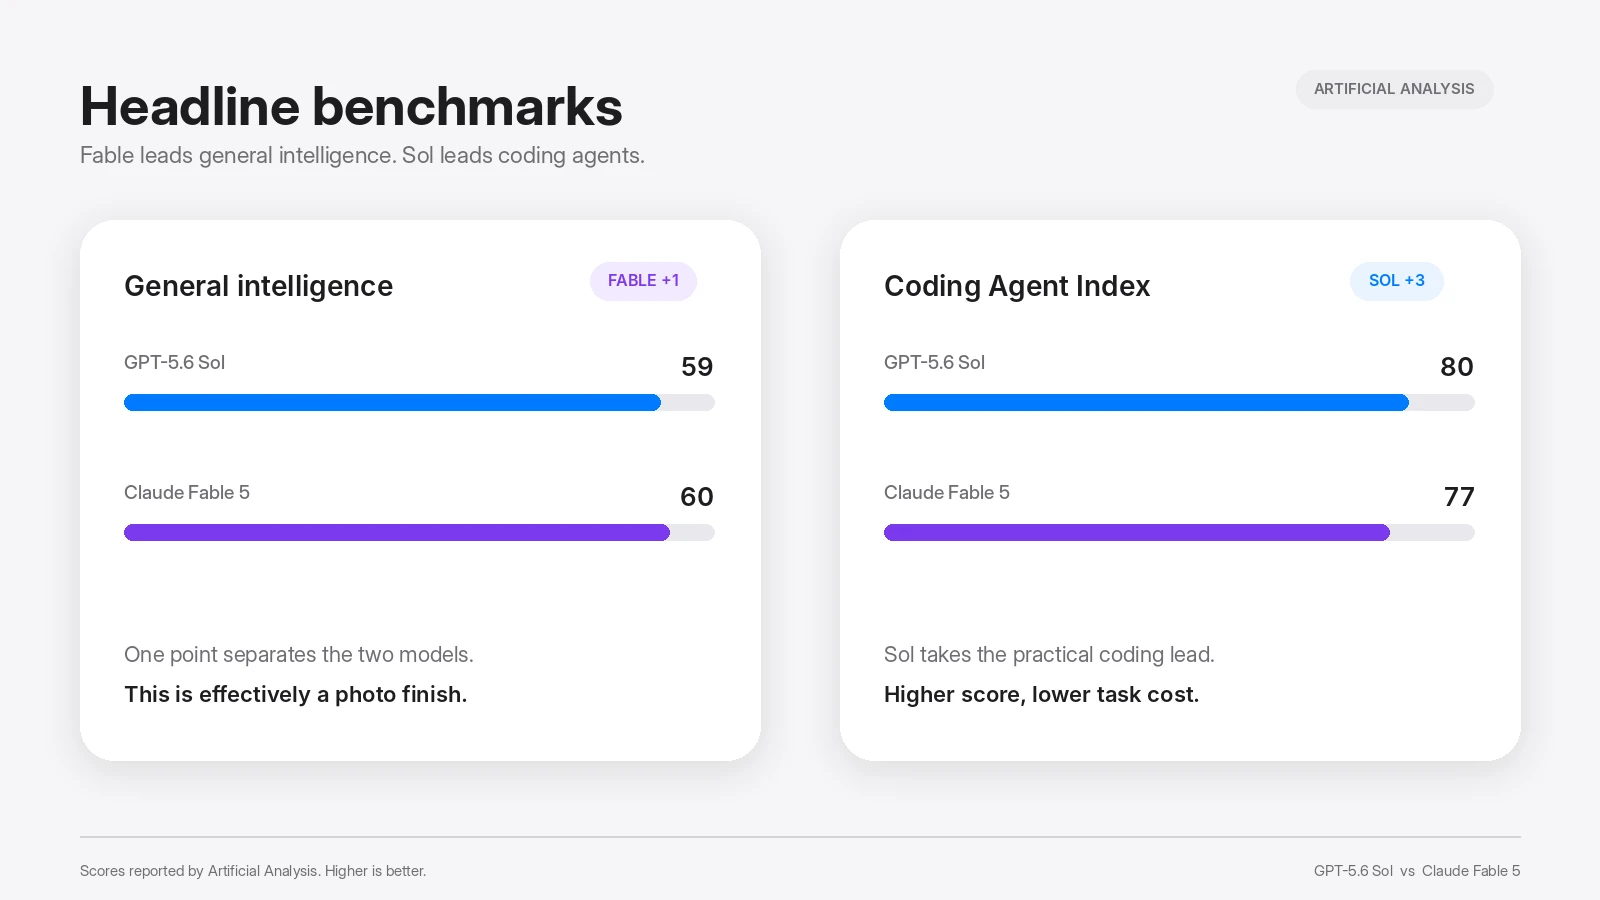
Claude Fable 5 has a slim edge normally intelligence, however GPT-5.6 Sol is the stronger coding agent.

Deadline Benchmarks

The headline outcomes are cut up. Fable leads the Synthetic Evaluation Intelligence Index by one level, whereas Sol holds a three-point benefit on the Coding Agent Index. For normal reasoning, the fashions are successfully neck and neck. For sensible software-development work, Sol has the clearer lead.

Coding-agent breakdown

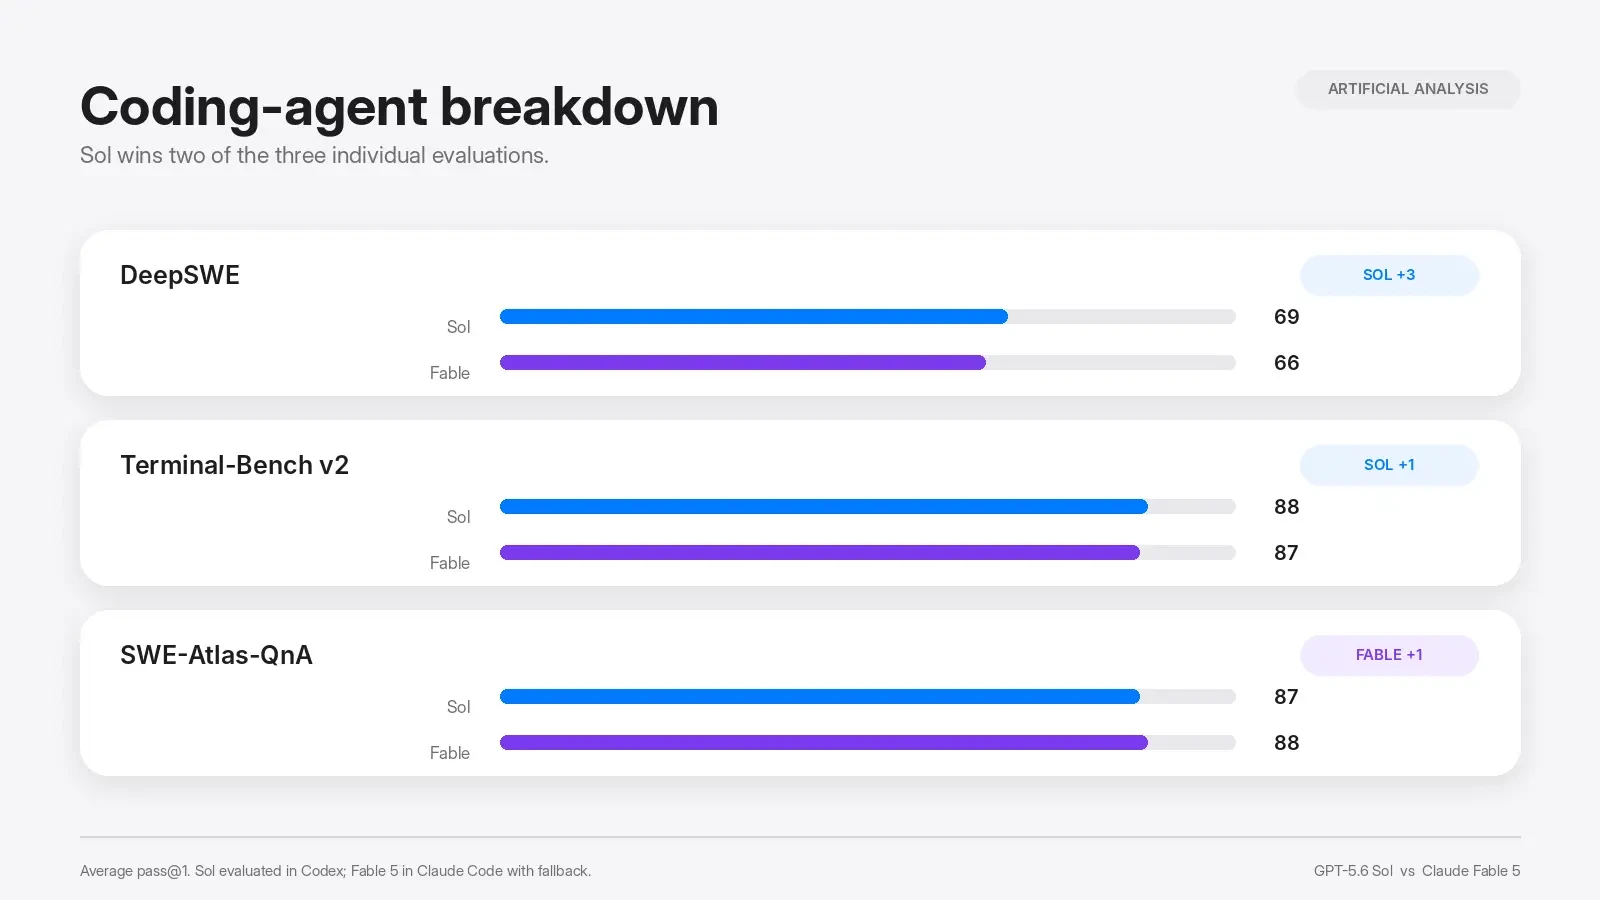
Sol wins extra coding evaluations

Sol leads on DeepSWE and Terminal-Bench v2, whereas Fable finishes one level forward on SWE-Atlas-QnA. Successful two of the three particular person evaluations provides Sol the stronger general coding-agent profile.

Coding-agent cost

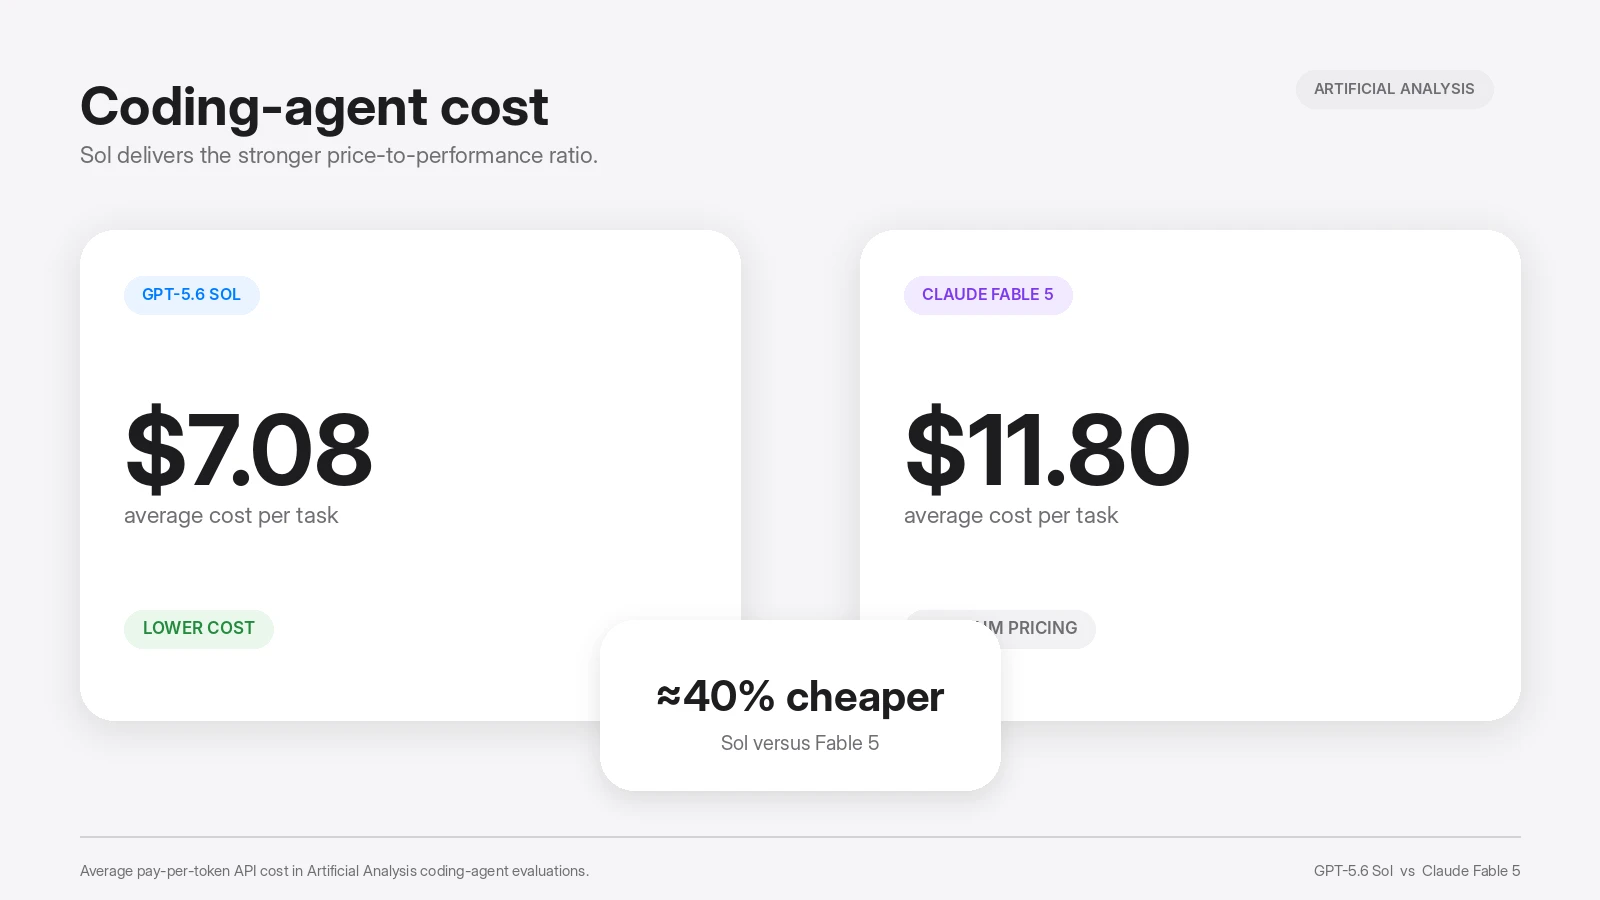
Higher efficiency at a decrease value

Sol’s common analysis value is $7.08 per process, in contrast with $11.80 for Fable 5. That makes Sol roughly 40% cheaper, strengthening its benefit for groups working coding brokers at scale.

AA-Briefcase

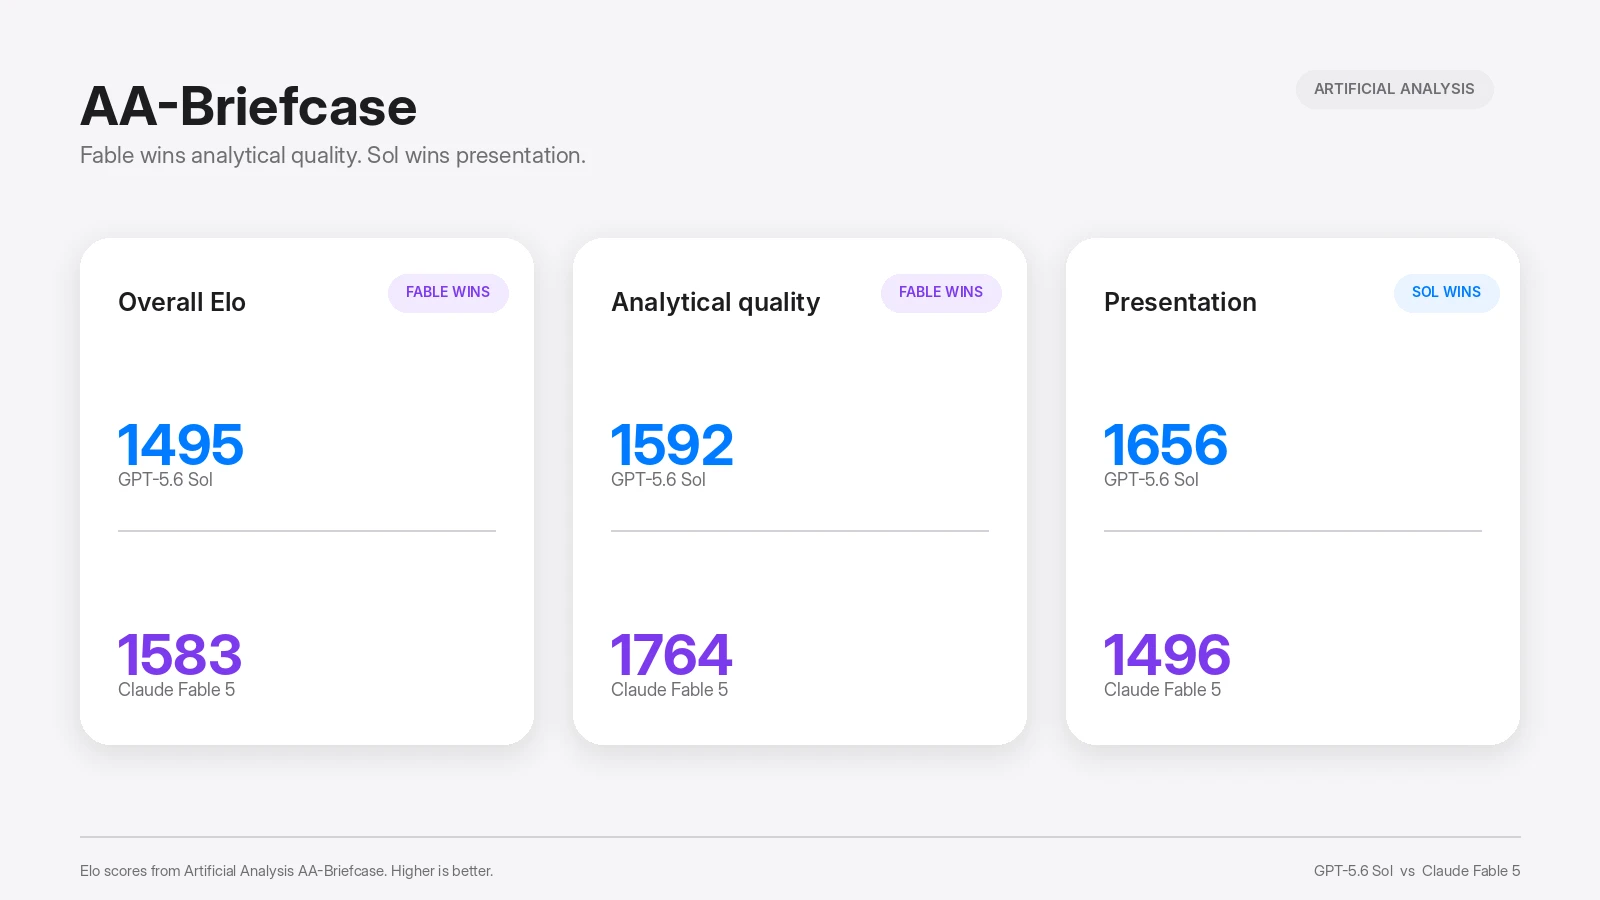
Fable analyzes higher however Sol presents higher

AA-Briefcase exhibits a extra nuanced end result. Fable earns the upper general Elo rating and leads clearly in analytical high quality. Sol, nonetheless, scores considerably greater on presentation, suggesting it’s higher at turning its work into clear, usable outputs.

Conclusion

Right here’s what turned clear:

  • GPT-5.6 Sol is slower however cheaper.
  • Claude Fable 5 is healthier at lengthy, advanced assignments.
  • Sol responds effectively to suggestions and iteration.
  • Fable requires much less supervision as soon as the duty is outlined.

For many customers, GPT-5.6 Sol is the higher alternative. It comes near Fable’s intelligence whereas providing higher coding efficiency at a a lot decrease value. 

Select Claude Fable 5 when the work is advanced sufficient to justify the additional expense, particularly once you need to hand over a undertaking and return later.

The only method to put it:

Sol is the mannequin you’re employed with. Fable is the mannequin you hand work to.

Ceaselessly Requested Questions

Q1. Is GPT-5.6 Sol higher than Claude Fable 5?

GPT-5.6 Sol is healthier for coding, pace and value. Fable 5 is healthier for advanced, long-running tasks requiring better autonomy.

Q2. Which mannequin is cheaper?

GPT-5.6 Sol. It prices $5 per million enter tokens and $30 per million output tokens, in contrast with Fable 5’s $10 and $50.

Q3. Which mannequin is healthier for coding?

GPT-5.6 Sol at present leads main impartial coding-agent benchmarks. Fable 5 stays helpful for planning, structure and reviewing advanced implementations.

I focus on reviewing and refining AI-driven analysis, technical documentation, and content material associated to rising AI applied sciences. My expertise spans AI mannequin coaching, knowledge evaluation, and knowledge retrieval, permitting me to craft content material that’s each technically correct and accessible.

Login to proceed studying and luxuriate in expert-curated content material.

[ad_2]

What occurred, what issues, what’s subsequent

0

[ad_1]

At InformationWeek, we’re targeted on serving to know-how leaders perceive what occurs after the headline — however the headlines nonetheless matter. They affect vendor roadmaps, funding priorities, regulatory discussions and the conversations taking place inside IT organizations each day.

Every week, we’ll spotlight a handful of recent developments that stood out throughout the trade, clarify why they matter past the information cycle, and level you towards a few of InformationWeek’s newest reporting that provides context to the traits shaping enterprise know-how.

Whereas SaaS supplier IBM had a rocky week on the inventory market, AI chipmaker Taiwan Semiconductor Manufacturing Co. (TSMC) had a stellar Q2. The distinction in market efficiency underscores the rise of AI whereas SaaS suppliers wrestle to maintain tempo with altering buyer calls for. Later this month, Alphabet, IBM, ServiceNow and Apple are among the many main tech firms scheduled to launch earnings experiences. In the meantime, the U.S. and U.Ok. governments have launched efforts to enhance cybersecurity efforts within the AI period and enhance laws for cloud service suppliers, respectively.

Associated:12 items of recommendation from two tech-company CIOs for first-time CIOs

Listed here are the developments price watching this week.

Information Highlights July 13-17

IBM’s shares plummet by 25%

What occurred: IBM’s shares took the largest drop within the firm’s historical past, leading to a $69 billion lack of its market worth in a single day. For Q2, IBM reported software program income up by 5%, however infrastructure income was down 7% in contrast with the earlier quarter. The firm famous that clients are shifting spending “towards servers, storage, and reminiscence purchases” amid the reminiscence chip scarcity that started earlier this yr.

Why it issues: The drop would not bode nicely, as rumblings over the SaaS-pocalypse — the worry that AI will make SaaS out of date — develop louder. The shift in spending by IBM’s clients towards AI investments and securing reminiscence storage are taking a toll on IBM’s backside line. Nonetheless, executives like Intuit’s Chief AI Officer Ashok Srivastava see AI as a chance for SaaS suppliers to hurry up operations and ship new options to clients.

TSMC earmarks $100B towards US funding

What occurred: Chip big TSMC plans to take a position a recent $100 billion within the U.S., elevating its complete U.S. funding to $265 billion. The funding will help improvement of 4 further semiconductor manufacturing services, for a complete of 12 semiconductor and packaging services in Arizona . TSMC had a banner Q2, with income up over 30% year-over-year, to $40.2 billion USD.

Associated:The hidden prices CIOs face to make information AI-ready

Why it issues: As the most important producer of AI chips, TSMC’s funding in U,S. manufacturing underscores the ever-increasing demand for AI compute. Nonetheless, Meta just lately introduced that the corporate is contemplating providing surplus AI computing capability via its cloud enterprise, pointing to a maturing AI market the place entry to compute is not the one aggressive benefit for enterprises working within the AI period.

White Home launches AI cybersecurity group

What occurred: The White Home is working with open supply firms and important infrastructure organizations to create an AI and cybersecurity coordination group to share info on potential cybersecurity vulnerabilities uncovered by AI. In a press release, Secretary of the Treasury Scott Bessent mentioned the Treasury Division is working carefully with the “personal sector to safeguard our monetary establishments, shut vulnerabilities, and defend the integrity of the U.S. monetary system.”

Why it issues: The creation of this cybersecurity group is the federal authorities’s newest effort to control the usage of AI. The pace with which vulnerabilities can now be recognized and exploited, because of AI, makes vulnerability administration way more difficult for CIOs and CISOs.

Associated:InformationWeek Podcast: Coping with strategic tech rejections

This cybersecurity problem was underscored in April, when Anthropic launched Claude Mythos Preview to a choose group of open supply, know-how and cybersecurity firms to check the AI mannequin. Mythos is able to figuring out, producing and exploiting zero-day vulnerabilities. Because of this, safety groups have a considerably shorter timeline to deal with AI-based threats. Happily, AI is not solely being utilized by dangerous actors to generate threats — enterprise safety groups can upskill to make use of AI as a part of their safety technique.

UK authorities designates cloud suppliers’ operations as vital to monetary sector

What occurred: The U.Ok. authorities introduced that Microsoft, Google, Amazon and Oracle at the moment are designated as “Vital Third Events (CTPs),” which implies the Financial institution of England, Prudential Regulation Authority and Monetary Conduct Authority will oversee vital companies the cloud suppliers present to the monetary sector. The CTPs will likely be underneath the federal government’s regulatory oversight in an effort to enhance safety of the U.Ok.’s monetary system, and to make sure they’ve measures in place to “establish, handle and recuperate from operational disruption affecting vital companies used throughout the monetary sector,” based on the U.Ok. authorities.

Why it issues: The U.Ok. authorities’s transfer to additional regulate cloud suppliers demonstrates the vital nature of cloud companies to help the monetary system. The U.Ok. authorities famous that “disruption at a serious provider may have an effect on a number of companies on the identical time, doubtlessly impacting companies clients rely on.” This elevated regulation underscores the significance of defending personal enterprise information from dangerous actors.

From InformationWeek: Well worth the learn

You will discover a wealth of perception and evaluation on the InformationWeek web site, however listed here are a couple of curated picks from the week that ought to be on the high of your studying record.

InformationWeek Podcast: Is quantum readiness price a CIO’s effort?

On this episode of the InformationWeek Podcast, Pal Narayanan, chief digital and data officer at Kenco, and Rishi Kaushal, CIO of Entrust, focus on the place quantum computing resides on their radar and the way they’re getting ready for its full arrival.

Apple’s OpenAI lawsuit alerts a brand new AI battleground: Expertise
Apple has filed a lawsuit in opposition to OpenAI and several other former Apple workers concerning trade-secret theft. The lawsuit arrives at a time when the AI trade is wrestling with a broader query about the place aggressive benefit really lies. As frontier AI turns into extra extensively obtainable, the dialog is shifting from who can entry the know-how to who can apply it most successfully. And that more and more comes all the way down to worker ability units and institutional data.

Why conventional undertaking administration would not work for AI initiatives
AI initiatives do not match neatly into conventional IT undertaking administration. AI improvement is steady, data-centric and iterative, making it tough to handle with conventional undertaking strategies. The query dealing with CIOs and undertaking managers stays: What adjustments ought to be made to conventional undertaking administration methodology to accommodate the distinctive nature of AI?

Inside GlobalFoundries’ plan to industrialize quantum {hardware}
GlobalFoundries’ Quantum Know-how Options enterprise unit launched on Could 21 because the U.S. Division of Commerce introduced its intent to take a position $375 million to help GlobalFoundries’ quantum enterprise. The funding is a part of the federal authorities’s $2 billion initiative to help the home quantum computing trade and increase manufacturing capability. A principal objective of the trouble is to scale quantum computing methods to the purpose the place they will deal with high-value use circumstances in enterprise and authorities.

Arising: Dates to observe

July 21-23 — The Chief Information Officer and Info High quality (CDOIQ) Symposium is an in-person occasion going down in Cambridge, Mass. The agenda covers information administration and agentic AI, and consists of audio system from the personal and public sectors.

July 22-30 — It is earnings name season for Google’s dad or mum firm Alphabet (July 22), IBM (July 22), ServiceNow (July 22), Microsoft (July 29) and Apple (July 30).

July 22 — The Denver Know-how Summit offers enterprise CIOs and CISOs with insights into enhancing their cybersecurity methods.

These are the developments we’ll be watching because the trade heads into one other busy week. We’ll be again quickly with one other roundup of the headlines, analysis and trade strikes shaping enterprise know-how — and the InformationWeek reporting that helps put them in context.


[ad_2]

The Obtain: OpenAI unveils GPT-Pink and warmth pumps rise within the US

[ad_1]

The must-reads

I’ve combed the web to search out you in the present day’s most enjoyable/essential/scary/fascinating tales about know-how.

1 Elon Musk discreetly purchased a $1 billion fuel turbine agency to energy Grok
He acquired fossil gas firm APR Power in Could. (Electrek)
+ The most probably software will likely be powering AI knowledge facilities. (Engadget)
+ The deal was revealed by means of an FTC submitting. (Gizmodo)
+ What’s going to energy AI’s development? (MIT Know-how Evaluate)
 
2 A hack reveals the Suno AI music generator scraped YouTube, Deezer
It scraped a long time’ price of music to coach its fashions. (404 Media)
+ The hacked is a singular look into the black packing containers powering GenAI. (CNET)
+ AI is coming for music, too. (MIT Know-how Evaluate)
 
3 Pondering Machines has launched an open-weight AI mannequin
Inkling gives a US different to China’s open-source fashions. (Reuters $)
+ It’s the primary AI mannequin constructed by Pondering Machines. (WSJ $)
+ The startup was based by former OpenAI CTO Mira Murati. (Axios)
 
4 Europe is narrowing its ambitions for tech independence
Manufacturing and analysis present promise, however funding is an issue. (NYT $)
+ Earnings are robust, however an AI hole persists. (Reuters $)
+ India can be scrambling for AI independence. (MIT Know-how Evaluate)
 
5 Earth is absorbing vitality at a fee that’s alarming local weather scientists
The planet is taking in additional warmth than fashions predicted. (Economist $)
+ The authorized case for local weather justice is rising. (MIT Know-how Evaluate)
 
6 The AI backlash has tech executives fearing for his or her lives
Violent threats in opposition to AI corporations are spilling into the actual world. (WSJ $)
+ An anti-AI motion is rising globally. (MIT Know-how Evaluate)
 
7 A Moroccan intelligence insider uncovered widespread Pegasus use
Together with to focus on journalists, activists, and international politicians. (Guardian)

8 AI is powering citizen-led catastrophe reduction from afar for Venezuela
It’s serving to to find lacking folks and coordinate reduction. (Remainder of World)
 
9 Thermodynamic computer systems might flip noise into helpful calculations
They could supply a cooler, extra environment friendly option to course of info. (Quanta)

10 An engineer has defined each ’90s pc in Jurassic Park
Followers have debated the know-how within the movie for many years. (Ars Technica)

Quote of the day

“We hit pause as a result of the communities powering AI ought to share in its success. Possibly that’s a novel idea in Washington.” 

—New York Gov. Kathy Hochul responds on X to President Donald Trump’s criticism of her state’s new knowledge middle moratorium.

One Extra Factor


Will we ever belief robots?

Robotics agency Prosper is growing a humanoid known as Alfie to carry out duties in houses, hospitals, and motels. The corporate’s founder, Shariq Hashme, has recognized trustworthiness as the highest design precedence—and first hurdle to clear earlier than humanoids can stay as much as their hype.

Hashme believes one important tactic to get folks to place their belief in Alfie is to construct an in depth character from the bottom up—one thing humanlike however not too human. However the robotic’s reliance on distant human operators raises broader questions on privateness, labour, and whether or not society will really settle for humanoids in our non-public areas.

[ad_2]

This T-Cell characteristic might save your life sometime (and you do not even want T-Cell for it to work)

0

[ad_1]

Years in the past, you could possibly go almost wherever exterior of a metropolis and don’t have any cell protection. Cell networks have improved considerably since then, however there are nonetheless locations that do not have sufficient cell protection for one cause or one other. Fortunately, T-Cell has an ingenious answer to repair this drawback: satellite tv for pc connectivity.

Whereas some telephones have had satellite tv for pc connectivity for many years, trendy smartphones solely lately acquired the characteristic when Apple launched it on the iPhone a number of years in the past. Since then, Google has adopted it on its Pixel telephones, and T-Cell has taken issues additional by increasing protection to telephones that had been by no means marketed to have satellite tv for pc connectivity within the first place.

[ad_2]

Historic Egyptian princesses knew their manner round weapons of warfare

0

[ad_1]

It appears some Egyptian royal girls actually have been warrior princesses.

Examinations of just about 4,000-year-old mummified princesses recommend that they have been expert customers of the daggers, bows and different weapons buried with them, researchers report July 17 in Frontiers in Environmental Archaeology

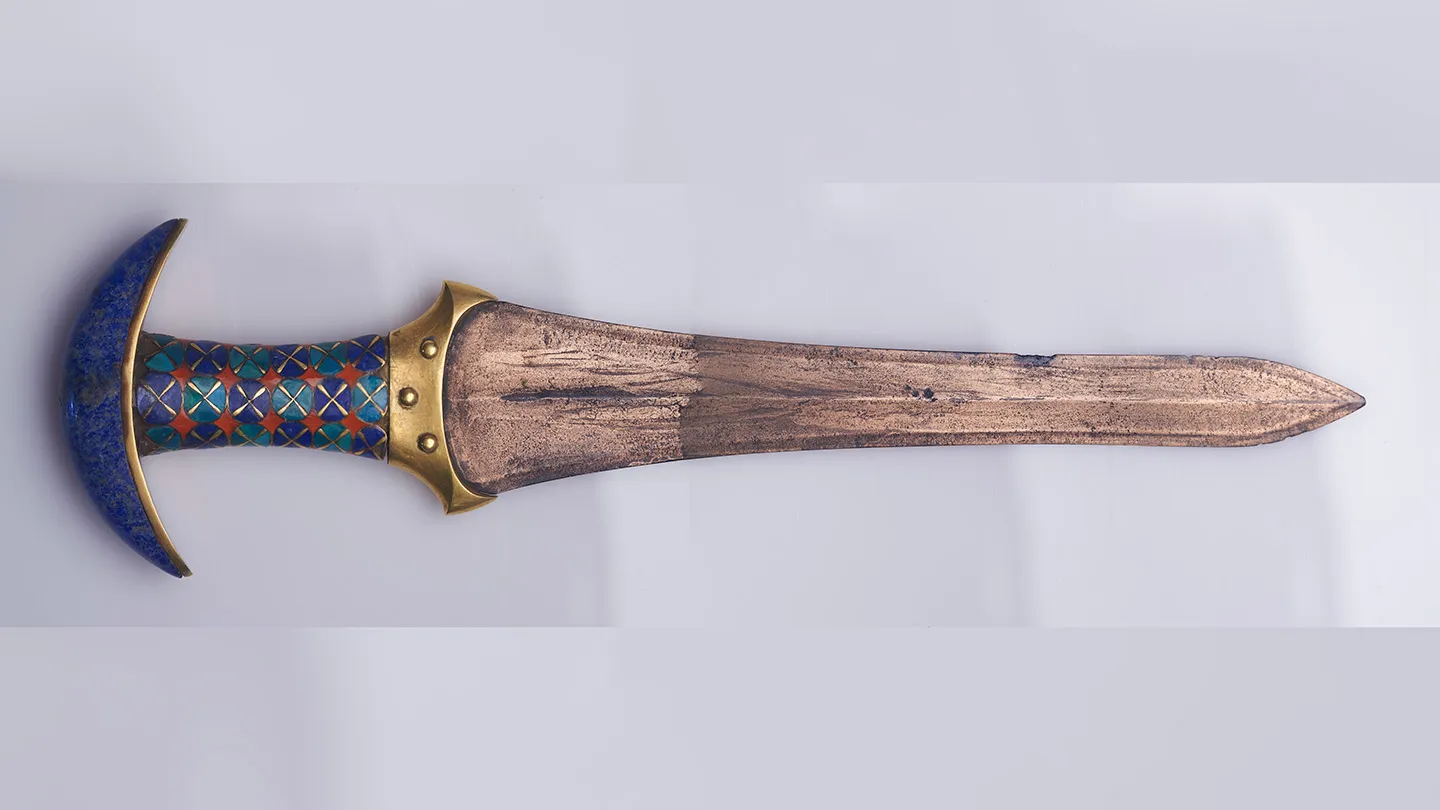
“These princesses have been energetic practitioners of searching or athletic abilities slightly than merely symbolic homeowners of the weapons discovered of their tombs,” says bioarchaeologist Zeinab Hashesh of Egypt’s Beni Suef College. Some Egyptologists have dismissed armaments in females’ graves as “token” objects for the afterlife, however traits of the feminine mummies confirmed that they had carried out intensive martial actions, Hashesh says.

The six mummies within the examine have been excavated in 1894 and 1895 from the Dahshur funerary complicated, about 40 kilometers south of Cairo. Their tombs have been rigorously cataloged, and included impression weapons like flails — jointed golf equipment — and maces. However the mummies have been eliminated after which neglected at an Egyptian museum; they have been thought misplaced till their rediscovery in 2020.

Hashesh and her colleagues examined the mummies by measuring their bones to find out intercourse and age at dying, and used X-rays and different strategies to look the stays for indicators of sickness and trauma. Their investigations confirmed handwritten notes from the nineteenth century excavators at Dahshur.

The one male mummy was an obscure thirteenth Dynasty pharaoh, whereas three — Ita, Khenmet and Itaweret — have been most likely daughters of the twelfth Dynasty pharaoh Amenemhat II, who dominated roughly between 1929 and 1895 B.C. One mummy had no notes, however the researchers tentatively recognized it as that of Sathathormeryt, a fourth sister to the three princesses. The opposite mummy was additionally a princess, however was not one of many sisters.

All six mummies shared a uncommon cluster of inherited spinal defects, indicating they have been associated. The group hopes to hold out DNA research sooner or later. However the researchers additionally noticed clear proof of “sturdy” muscle attachments — the place connective tissue as soon as joined the muscle and the bone — and a few telling skeletal developments. As an example, enlarged areas of the forearm bones indicated that Itaweret had usually drawn bows.

Among the girls had healed from traumatic accidents, probably sustained whereas coaching, searching or in battle. “These princesses weren’t main sedentary lives of luxurious,” Hashesh says. “They have been well-conditioned athletes whose our bodies have been hardened by the identical expert power and disciplined motion as the lads of their time.”

Egyptologist Nicholas Brown, who was not concerned within the examine, says Egyptian princesses used bows within the royal ritual of capturing arrows within the 4 cardinal instructions — north, east, south and west — throughout the Sed competition of renewal. Nevertheless, the proof for the princesses’ use of weapons is oblique, says Brown, of the College of Iowa in Iowa Metropolis. “The bones aren’t preserving the habits immediately, however the muscle attachments are clearly indicating some sort of ordinary, repeated exercise.”

[ad_2]

Construct enterprise seek for brokers with Amazon Bedrock Managed Data Base

[ad_1]

Data bases that floor brokers and generative AI purposes over your enterprise information are laborious to construct at scale. Groups sometimes sew collectively connectors, parsers, vector shops, information graphs, and retrieval logic, then operationalize all of it for manufacturing. Each bit brings its personal challenges. It’s essential to resolve which information sources to attach and learn how to parse multimodal doc sorts. It’s essential to select between graph and vector databases, then provision and scale them. It’s essential to additionally deal with complicated queries that purpose throughout various content material, and layer on the document-level entry management, observability, and safety that manufacturing calls for.

Amazon Bedrock now affords Managed Data Base on the whole availability, a completely managed agentic retrieval answer that handles scaling, high-accuracy retrieval, and doc entry management in your behalf. You possibly can join your enterprise information sources or crawl the online and begin ingesting. Getting began via the AWS Administration Console requires no mannequin choice. Smart defaults take you from zero to your first retrieval in minutes, in comparison with the days or even weeks sometimes wanted to assemble a comparable pipeline from scratch. While you’re able to customise, you’ve got management over embedding fashions, rerankers, chunking methods, and extra.

On this submit, we stroll via the three pillars that make this potential: simplified setup, smarter retrieval, and manufacturing readiness. We additionally present you code examples for establishing a information base and retrieving from it.

Simplified setup

Builders in the present day sometimes procure and construct information ingestion pipelines, vector or graph storage, and retrieval infrastructure individually. This implies managing separate infrastructure, separate billing fashions, separate charge limits, and the complexity of piecing all of it collectively right into a coherent pipeline.

Managed Data Base abstracts this complexity away. You configure a information base, and the service handles all the things downstream, from ingesting enterprise information via native connectors to managing vector shops in your behalf.

Native enterprise connectors with ACL assist

Managed Data Base contains six native connectors (Amazon Easy Storage Service (Amazon S3), Microsoft SharePoint, Atlassian Confluence, Google Drive, Microsoft OneDrive, and Net Crawler). It additionally features a direct ingestion API for paperwork that don’t stay in a supported supply. On subsequent syncs, the service processes solely modified or new paperwork, lowering time, price, and staleness.

Managed Data Base makes use of real-time entry management listing (ACL) checks as a further layer of safety on high of current pre-retrieval ACL filtering. The pre-filtered paperwork are transient for the lifetime of the API name and will not be seen to massive language fashions (LLMs) or customers. This maintains present entry controls by checking permissions instantly with the authoritative supply at question time, moderately than counting on doubtlessly stale or incorrectly mapped ACL information.

Syngenta Group makes use of Bedrock Managed Data Bases to allow staff to create information bases on demand, syncing information from SharePoint and Confluence for inner information search and agentic RAG purposes.

 – Jason Krohn, Head of Knowledge and AI Know-how

MRH Trowe is utilizing Bedrock Managed Data Bases to energy an inner AI Copilot that offers staff instantaneous, grounded solutions from throughout our company information base — spanning 1000’s of paperwork in Confluence and SharePoint, in each English and German. With native connectors and built-in entry controls, our groups can search throughout insurance policies, shopper documentation, and operational content material with out constructing customized retrieval pipelines — accelerating how our staff entry the information they should serve shoppers.

– Dr. Malte Polley, Teamleader Knowledge Analytics & AI

Parsing throughout multimodal information

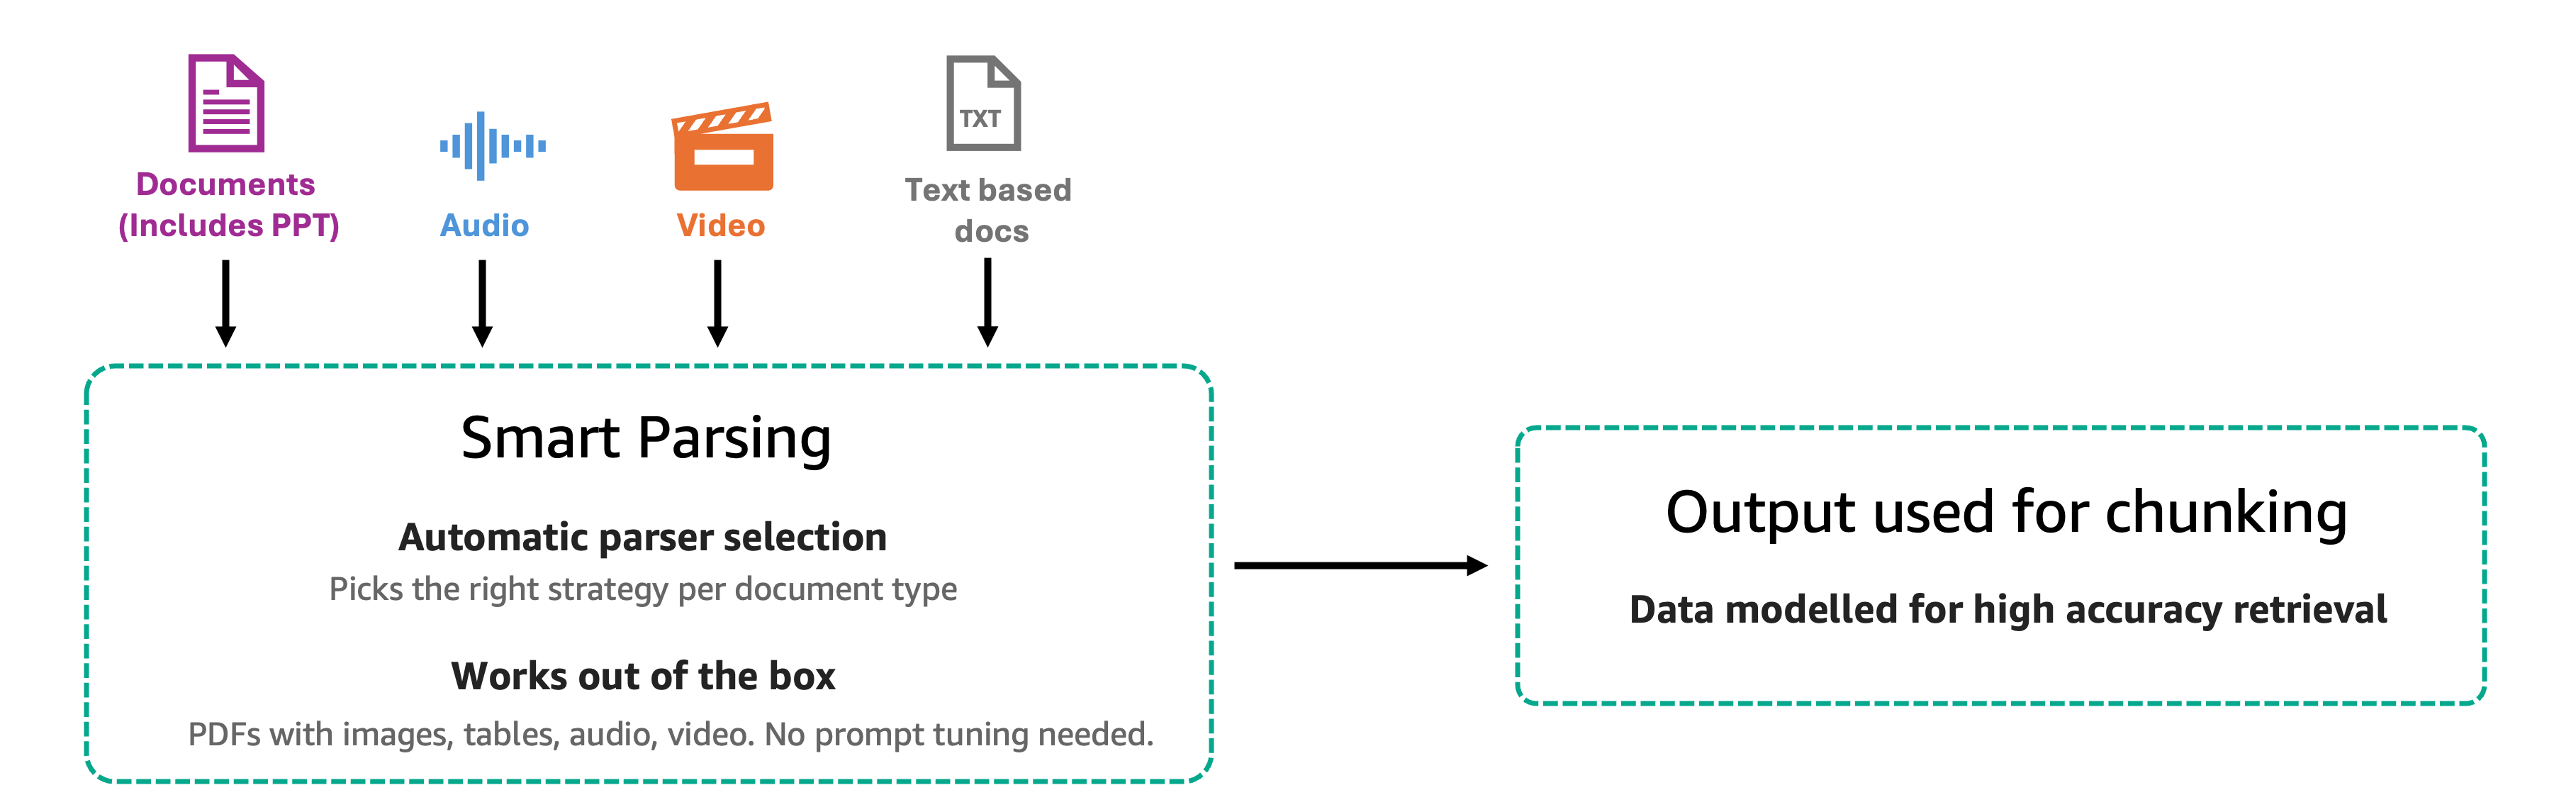
Your information fragments throughout many codecs: machine-readable content material in net purposes, digital information containing embedded photos like PDFs, PPTX, and DOCX, scanned paperwork, and media content material comparable to audio and video. Reasonably than constructing separate pipelines for every format, Managed Data Base supplies totally managed parsing that mechanically selects the appropriate technique per content material kind. It handles tables, charts, diagrams, blended layouts, and media with out configuration from you. The service helps visible content material paperwork (PDFs, PPT/PPTX, DOCX) as much as 500 MB, audio information as much as 2 GB, and video information as much as 10 GB.

After the service parses content material, it splits the content material into segments for retrieval. By default, Managed Data Base decides on essentially the most appropriate chunking technique in your behalf. In case you perceive your information and wish extra management, you possibly can select a customized technique like fixed-size chunking, the place you set the approximate token dimension, or no chunking, for paperwork which can be already pre-processed or pre-split.

Service-managed information storage

Selecting a semantic retrieval database is without doubt one of the most complicated choices in a information retrieval pipeline. Every possibility has completely different efficiency profiles, pricing fashions, scaling traits, and have units. After you select, you could nonetheless provision capability, configure indices, handle backups, and tune efficiency over time.

Managed Data Base removes that work completely with a unified storage layer. The service auto-provisions storage so that you don’t resolve on vector dimensions or similarity metrics, and it auto scales from gigabytes to terabytes with out intervention. Hybrid search combining key phrase and semantic retrieval is constantly on, with no separate index configuration to handle. Knowledge is encrypted at relaxation and in transit utilizing AWS Key Administration Service (AWS KMS) keys, both AWS managed or buyer managed.

You don’t work together with the underlying storage. Your AWS providers deal with monitoring, tuning, backups, patching, and capability administration for you.

OpenAI is utilizing Bedrock Managed Data Bases’ RAG capabilities to floor inference and mannequin responses, reliably and at scale for thousands and thousands of customers, with the appropriate buyer context.

 – Lavanya Singh, Member of Technical Employees, OpenAI

Setup in three steps

Let’s take a look at learn how to arrange a managed information base programmatically. Three API calls are all it takes: create the information base, add an information supply, and begin ingestion. The next instance makes use of Amazon S3 as the info supply with a completely managed embedding mannequin, with no mannequin Amazon Useful resource Title (ARN), vector retailer, or chunking configuration required.

import boto3

bedrock_agent = boto3.shopper('bedrock-agent', region_name="us-west-2")

# Step 1: Create a completely managed information base (zero-config)
kb_response = bedrock_agent.create_knowledge_base(
    identify="my-managed-kb",
    description='Product documentation information base',
    roleArn='arn:aws:iam::123456789012:function/BedrockKBRole',
    knowledgeBaseConfiguration={
        'kind': 'MANAGED',
        'managedKnowledgeBaseConfiguration': {
            'embeddingModelType': 'MANAGED'
        }
    }
)
kb_id = kb_response['knowledgeBase']['knowledgeBaseId']

# Step 2: Add an S3 information supply
ds_response = bedrock_agent.create_data_source(
    knowledgeBaseId=kb_id,
    identify="my-s3-docs",
    dataSourceConfiguration={
        'kind': 'S3',
        's3Configuration': {
            'bucketArn': 'arn:aws:s3:::amzn-s3-demo-bucket',
            'inclusionPrefixes': ['documents/']
        }
    }
)
data_source_id = ds_response['dataSource']['dataSourceId']

# Step 3: Begin ingestion
bedrock_agent.start_ingestion_job(
    knowledgeBaseId=kb_id,
    dataSourceId=data_source_id
)

Smarter retrieval

A single retrieval step can’t reply each query. Direct lookups work fantastic on their very own, however comparative evaluation, multi-hop reasoning, and analysis queries want extra. Managed Data Base affords two retrieval APIs, every designed for various complexity ranges:

  • Retrieve returns ranked supply chunks with relevance scores and metadata. Use it for direct lookups, FAQ-style questions, and eventualities the place low latency is vital. You management the variety of outcomes and might apply metadata filters to slender the search.
  • Agentic Retrieval makes use of a basis mannequin (FM) to decompose complicated queries into sub-queries. It retrieves iteratively throughout a number of information bases and evaluates whether or not the outcomes are enough earlier than returning them. Agentic Retrieval may generate a synthesized response utilizing the managed orchestration LLM or a mannequin accessible on Amazon Bedrock. Use it for comparative evaluation, multi-hop questions, analysis queries, and eventualities that require synthesizing data from a number of sources or paperwork.

How Agentic Retrieval works

Evaluating two merchandise, tracing a call throughout a number of paperwork, or synthesizing analysis from completely different sources requires a number of retrieval steps. You additionally want to guage intermediate outcomes and acknowledge when you’ve got sufficient data.

Agentic Retrieval handles this mechanically, throughout a number of information bases. When a question is available in, the service:

  1. Plans by analyzing the question and decomposing it into sub-queries, every focusing on a selected retriever throughout your configured information bases.
  2. Retrieves by executing sub-queries in parallel in opposition to one or a number of information bases.
  3. Evaluates whether or not the outcomes are enough. If not, it plans and executes extra retrieval rounds (as much as 5 by default).
  4. Returns deduplicated chunks from all iterations, with hint occasions streaming all through for full observability.

You possibly can steadiness accuracy and latency to your use case. The maxAgentIteration parameter controls what number of rounds the mannequin performs, and you choose the inspiration mannequin used for planning and analysis.

The next code reveals an instance of invoking Agentic Retrieval and processing its streaming response. The request specifies the person’s question, the information base to look, the inspiration mannequin to make use of for planning and analysis, and the utmost variety of retrieval iterations. Because the service runs, it streams hint occasions that present every planning step and sub-query being executed, adopted by the ultimate retrieval outcomes:

bedrock_runtime = boto3.shopper('bedrock-agent-runtime', region_name="us-west-2")

response = bedrock_runtime.agentic_retrieve_stream(
    messages=[{
        'role': 'user',
        'content': [{'text': 'Compare the pricing tiers of Product A and Product B'}]
    }],
    retrievers=[{
        'knowledgeBaseRetriever': {
            'knowledgeBaseId': kb_id,
            'maxResults': 10
        }
    }],
    agenticRetrieveConfiguration={
        'foundationModel': {
            'modelArn': 'arn:aws:bedrock:us-west-2::foundation-model/anthropic.claude-sonnet-4-20250514'
        },
        'maxAgentIteration': 5  # 1-10, default 5
    }
)

# Hint occasions stream in actual time, then ultimate outcomes arrive
for occasion in response['stream']:
    if 'hint' in occasion:
        hint = occasion['trace']
        if 'planning' in hint:
            print(f"Planning: {len(hint['planning'].get('actions', []))} sub-queries")
        elif 'retrieval' in hint:
            print(f"Retrieving: {hint['retrieval'].get('enter', {}).get('textual content', '')}")
    elif 'retrievalResults' in occasion:
        outcomes = occasion['retrievalResults']['results']
        print(f"n{len(outcomes)} deduplicated outcomes returned")
        for i, r in enumerate(outcomes[:5], 1):
            print(f"  {i}. {r['content']['text'][:150]}...")

Manufacturing prepared

Getting a Retrieval Augmented Technology (RAG) prototype working is one factor. Working it at scale with correct entry management, observability, and safety is the place many groups stall. Managed Data Base contains AgentCore Gateway integration, document-level entry management, and observability out of the field, so you possibly can deploy with out constructing these layers your self.

Native AgentCore Gateway integration

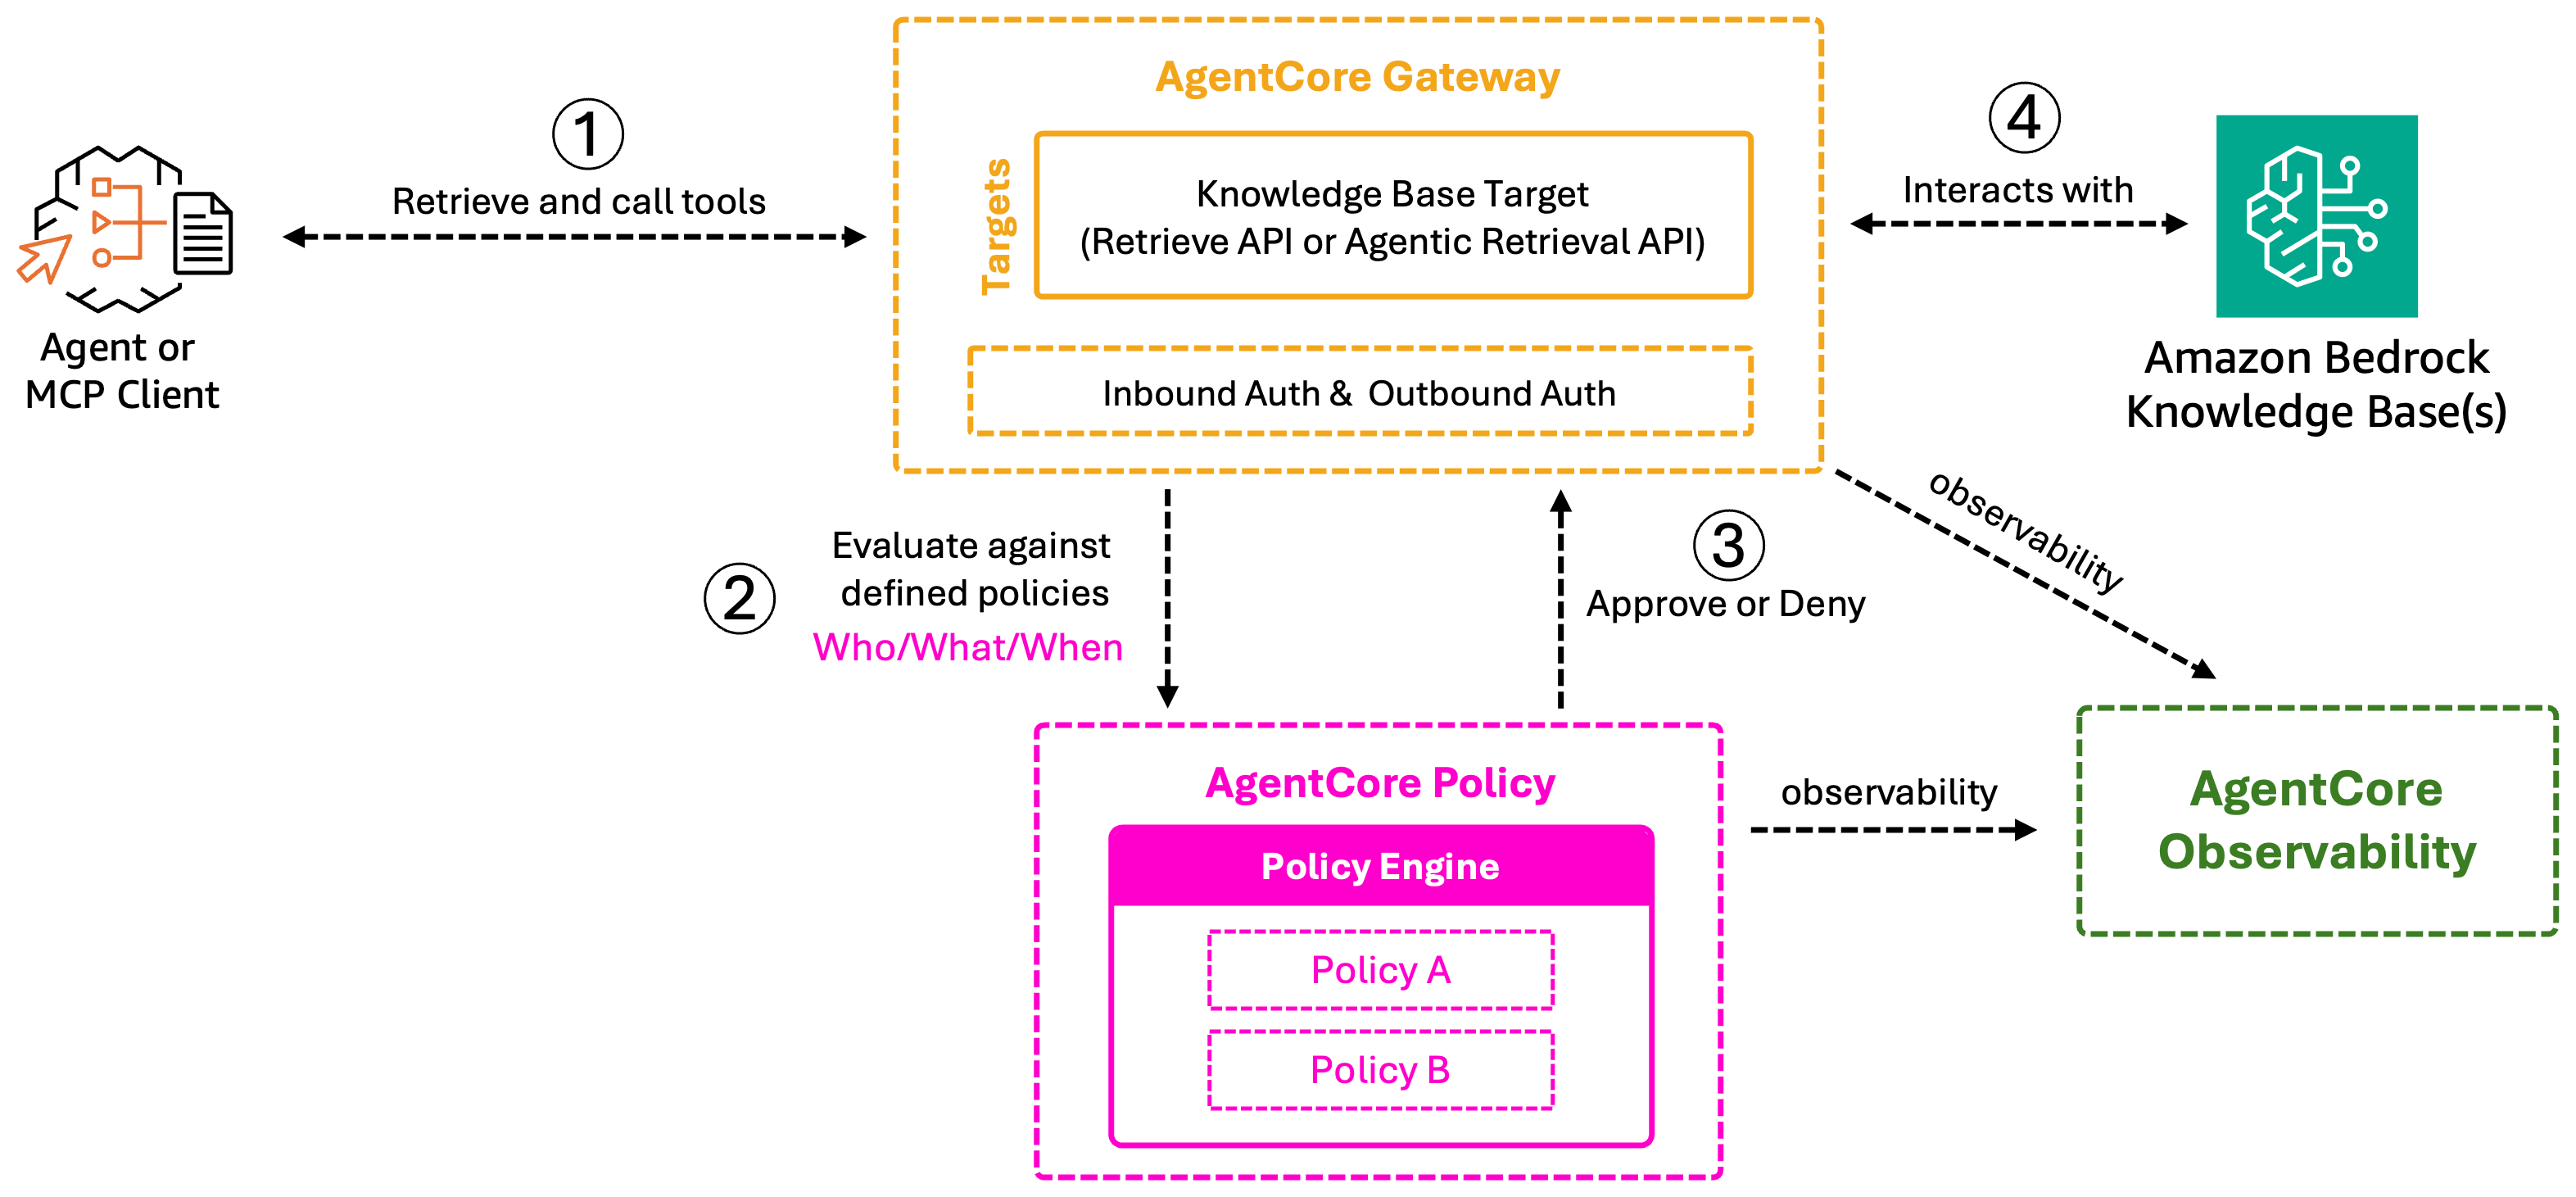
Managed Data Bases integrates natively with AgentCore Gateway, providing you with a streamlined approach to expose your information base to brokers. While you add your information base as a goal on the gateway, it turns into a device that brokers appropriate with the Mannequin Context Protocol (MCP) can uncover and invoke mechanically. AWS Id and Entry Administration (IAM), routing, and observability are centralized on the gateway. You can even use Managed Data Bases standalone by calling the retrieval APIs instantly out of your software if that higher fits your use case.

AgentCore Gateway provides the next to your Managed Data Bases integration:

  • Abstracted infrastructure: Data base IDs are hidden behind the gateway, so brokers merely uncover and name instruments by identify, decoupling your agent code from underlying infrastructure.
  • Framework compatibility: Brokers work together via a standardized MCP endpoint, making your information bases immediately appropriate with MCP-aware frameworks, together with Strands, LangChain, and CrewAI.
  • Unified entry level: A single gateway URL turns into the entry level to your information bases throughout your group, simplifying agent configuration and governance.
  • Centralized safety: IAM coverage on the gateway stage replaces per-knowledge-base permissions administration, providing you with one place to implement safety, audit entry, and handle scale.
  • Clear operations: Constructed-in observability, routing, and authentication are dealt with for you, so you possibly can add, swap, or scale information bases with out altering a single line of agent code.

Architecture diagram of AgentCore Gateway fronting a Managed Knowledge Base, with MCP-compatible agent frameworks invoking it as a tool through a single gateway URL

After you create a gateway and add your information base as a goal, MCP-compatible agent frameworks can uncover and invoke it with out understanding the underlying information base ID:

from strands.instruments.mcp import MCPClient
from mcp_proxy_for_aws.shopper import aws_iam_streamablehttp_client

mcp_client = MCPClient(lambda: aws_iam_streamablehttp_client(
    endpoint=gateway_url,
    aws_region='us-west-2',
    aws_service="bedrock-agentcore",
))

with mcp_client:
    # KB instruments are auto-discovered by way of MCP
    instruments = mcp_client.list_tools_sync()
    print(f"Obtainable instruments: {[t.tool_name for t in tools]}")

    # Retrieve (the agent by no means sees the KB ID)
    outcome = mcp_client.call_tool_sync(
        'tool_call_1',
        instruments[0].tool_name,
        {'retrievalQuery': {'textual content': 'What's our complete income?'}},
    )

This sample works with Strands, LangChain, CrewAI, or different MCP-compatible frameworks. The gateway handles IAM, routing, and observability transparently.

At Sony, we’re constructing an agentic chat platform on Amazon Bedrock AgentCore to assist groups get trusted solutions from complicated enterprise content material and stay net data. With Bedrock Managed Data Base and Net Search now accessible as instruments in AgentCore, our brokers can purpose throughout inner PDFs, shows, spreadsheets, charts, and tables, going past easy vector retrieval, and floor responses in present net data whereas retaining our information inside AWS. The result’s a single expertise for answering questions throughout inner information and the online

– Masahiro Oba, Senior Normal Supervisor, Sony Group Company

Observability

Each information base question, whether or not via the SDK or the gateway, mechanically publishes metrics to Amazon CloudWatch beneath the AWS/Bedrock/KnowledgeBases namespace, together with invocations, shopper and server errors, and throttles. For Agentic Retrieval, hint occasions stream in actual time, displaying every planning step, sub-query, and analysis spherical. This provides you full visibility into the retrieval course of with out writing instrumentation code.

For an entire end-to-end walkthrough, take a look at the pocket book on GitHub.

The place Managed Data Base matches

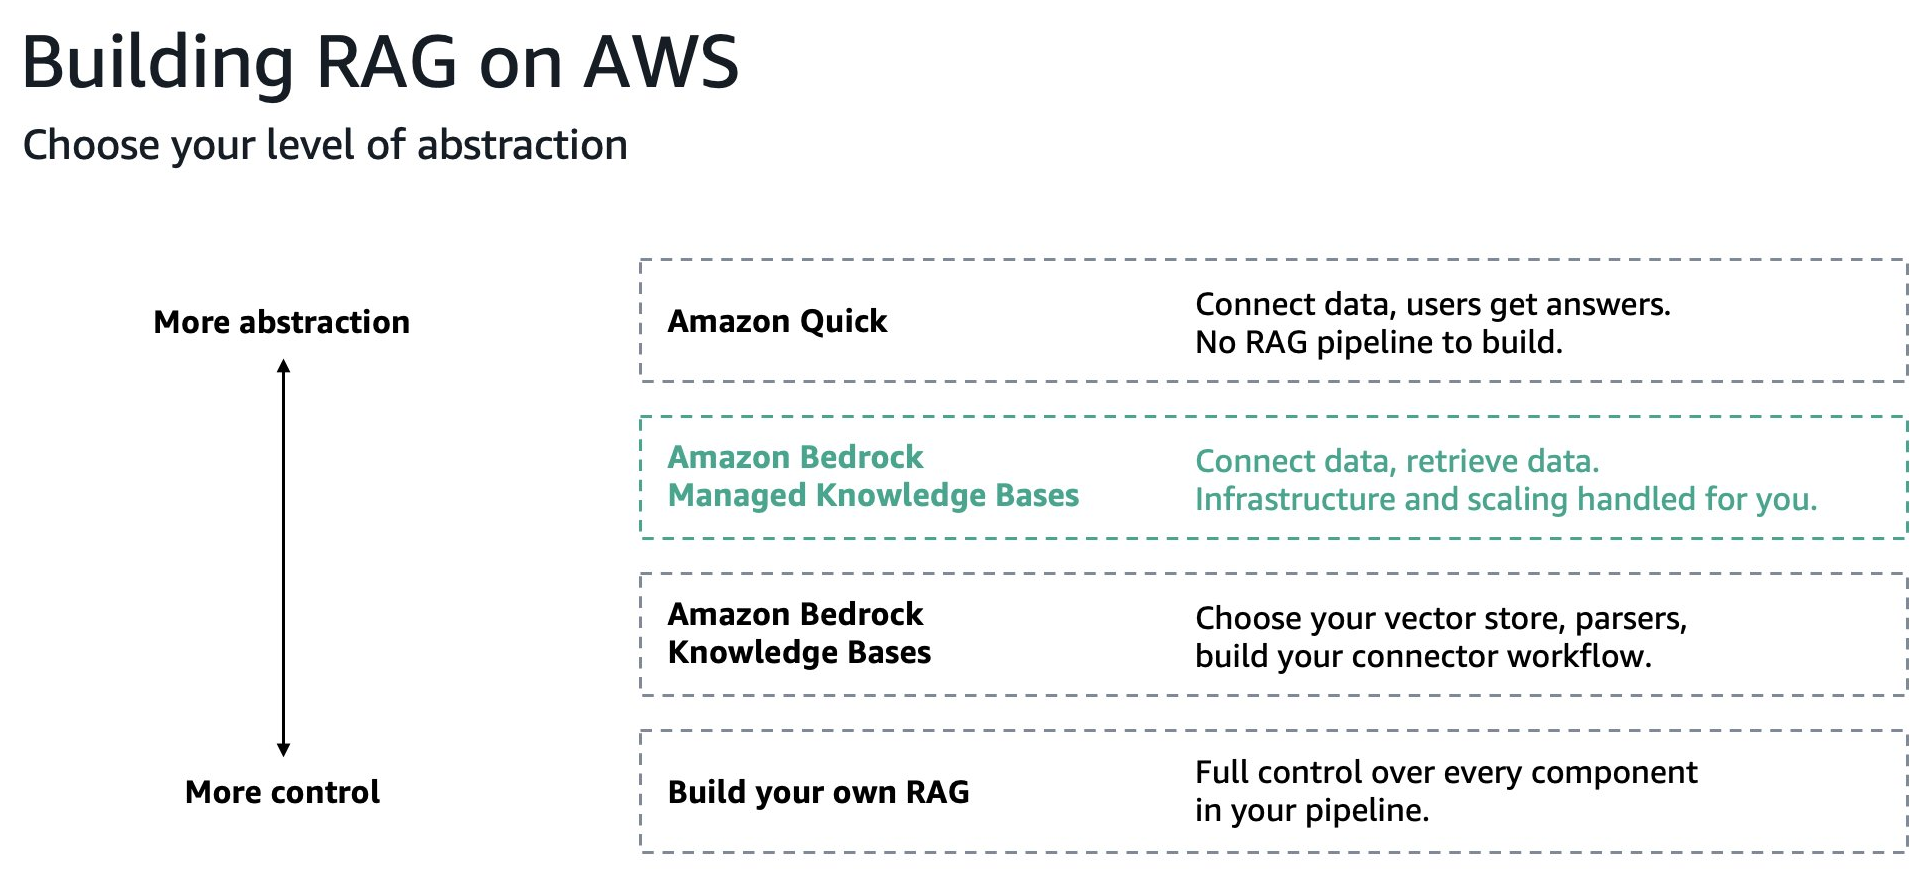
AWS affords a number of choices for constructing the information retrieval that grounds brokers, generative AI purposes, and RAG pipelines. The proper selection is determined by how a lot management you want versus how a lot you need managed for you. The next diagram reveals the place Managed Data Base sits alongside that spectrum, from the best stage of abstraction (Amazon Fast) to constructing your individual RAG pipeline from scratch.

Spectrum diagram showing AWS knowledge retrieval options from Amazon Quick (highest abstraction) through Managed Knowledge Base and Bedrock Knowledge Bases to a custom RAG pipeline (lowest abstraction)

If it’s worthwhile to select your individual vector retailer and assemble the connector workflow your self, Amazon Bedrock Data Bases stays accessible. Managed Data Base is for groups that wish to give attention to their software moderately than the underlying infrastructure, with the service dealing with storage, scaling, and retrieval in your behalf.

Pricing

Managed Data Bases consolidates pricing into a simple, usage-based mannequin moderately than spreading prices throughout a number of capability items. You pay for storage of your uncooked information, normal retrieval API calls, and Agentic Retrieval while you want multi-hop reasoning. The multimodal doc parser, managed embedding mannequin and managed re-ranker  are all included at no additional price. In case you select to make use of a distinct Amazon Bedrock mannequin for embeddings, re-ranking, or orchestration, normal Bedrock pricing applies for these fashions.

For full pricing particulars and labored examples, see the Amazon Bedrock pricing web page.

Conclusion

Amazon Bedrock Managed Data Base removes the infrastructure work that sits between your enterprise information and a working retrieval-augmented technology software. Join your information sources, let the service deal with parsing, storage, and indexing, and retrieve utilizing the mode that matches your question complexity.

Doc-level entry management, real-time ACL checks, and native observability via Amazon CloudWatch are in-built, so your information base is prepared for manufacturing workloads at launch. With native AgentCore Gateway integration, your information bases develop into instruments that MCP-compatible brokers can uncover and use with out customized code.

Managed Data Base is now accessible in us-east-1 (N. Virginia), us-west-2 (Oregon), eu-west-1 (Dublin), eu-central-1 (Frankfurt), ap-southeast-2 (Sydney), eu-west-2 (London), ap-northeast-1 (Tokyo), and us-gov-west-1 (AWS GovCloud US-West).

To get began, see the documentation or strive it out on the AWS Administration Console.


In regards to the authors

Dani Mitchell

Dani Mitchell

Dani is a Sr GenAI Specialist Options Architect at AWS and the SA lead for Amazon Bedrock Data Bases. He helps enterprises internationally design and deploy generative AI options utilizing Amazon Bedrock and Anthropic’s fashions and capabilities to construct scalable, production-ready purposes.

Sandeep Singh

Sandeep is a Senior Generative AI Knowledge Scientist at AWS, serving to massive enterprises innovate with generative AI. He focuses on generative AI, Agentic AI, machine studying, and system design, delivering AI/ML-powered options to unravel complicated enterprise issues throughout various industries.

Siddhant Sahu

Siddhant Sahu

Siddhant is a Sr Product Supervisor at Amazon Net Providers, the place he focuses on Bedrock Managed Data Bases. He builds agentic search merchandise that assist ISVs and enterprises join generative AI to their enterprise information.

Amit Choudhary

Amit Choudhary

Amit is a Principal Product Supervisor at AWS, the place he presently leads Data Bases for Amazon Fast and leads information ingestion capabilities for Amazon Bedrock Data Bases. His work permits safe AI interactions grounded in enterprise information, remodeling how organizations use their information for AI-powered insights and decision-making. Beforehand, he enabled enterprises to securely join their information sources to Amazon Q Enterprise for person productiveness, and constructed AWS Clear Rooms Differential Privateness, serving to enterprises defend person privateness with mathematical ensures in just some steps. Exterior of labor, he enjoys touring.

[ad_2]

When Compute Sits and Waits: Fixing the Hidden Storage Bottleneck in EDA and HPC with Azure NetApp Recordsdata

0

[ad_1]

Howdy People!

You probably have ever stared at an HPC pipeline and puzzled why the queue depth retains climbing whereas each CPU graph seems lazy, this session from the Microsoft Azure Infrastructure Summit 2026 goes to really feel very acquainted. Ron Hogue from the Azure Storage staff and Ranga Sankar from NetApp spend twenty-seven minutes diagnosing the issue that no person desires to confess out loud, that the bottleneck isn’t compute, not the scheduler, and never licenses. It’s storage. After which they stroll by way of precisely how Azure NetApp Recordsdata (ANF) solves it.

📺 Watch the session:


If you happen to assist a semiconductor, simulation, rendering, or scientific computing staff, you’ve gotten lived this story. Engineers ask for extra cores. You purchase them. Wall-clock occasions barely transfer. Managers then ask for extra software licenses, as a result of absolutely that have to be the constraint. Spoiler, it normally isn’t.

Right here is why this issues to anybody operating shared infrastructure on Azure:

  • EDA and HPC pipelines hammer storage with thousands and thousands of tiny reads and writes, metadata operations like file creation, rename, and unlink, all taking place concurrently throughout hundreds of processes.
  • That sample breaks generic cloud file storage that was tuned for giant sequential I/O.
  • ANF brings the identical NetApp ONTAP information providers that EDA groups have used on-premises for many years, delivered as a local Azure service.
  • You’ll be able to transfer design environments to Azure with out re-architecting instruments, schedulers, or scratch path conventions.
  • The economics modified within the final twelve months with the Versatile service stage and Cool Entry, so the previous “ANF is simply too costly for scratch” argument deserves a recent look.

Briefly, in case your job entails maintaining costly engineers and costly licenses busy, the storage layer deserves your consideration.

ANF is a first-party Azure service operating NetApp ONTAP on bare-metal infrastructure inside Azure datacenters. It speaks NFS v3, NFS v4.1, and SMB, with dual-protocol choices, and it preserves the file semantics that EDA instruments assume. Issues like POSIX permissions, quick metadata operations, snapshots, and constant low latency.

Ron and Ranga framed the session in eight layers (Drawback, Basis, Accelerator, Scale, AI Prepared, Guardrails, Optimize, Proof). Three items did a lot of the heavy lifting.

Basis, Migration Assistant with SnapMirror. That is the way you get the information into Azure with out rewriting your stock. SnapMirror replicates from on-premises ONTAP or Cloud Volumes ONTAP into ANF whereas preserving metadata, permissions, snapshots, and listing construction, with steady synchronization and minimal downtime. For EDA flows the place a lacking ACL can invalidate a whole run, that constancy isn’t non-compulsory.

Accelerator, Cache Volumes. Constructed on NetApp FlexCache, these volumes entrance your authoritative dataset (whether or not it lives in on-prem ONTAP or in Cloud Volumes ONTAP) and pull scorching reads near your Azure compute. Instrument libraries, PDKs, shared reference information, all served at sub-millisecond latency with out copying petabytes round. There’s nonetheless one supply of reality, which retains your information governance story clear.

Scale, Massive Volumes with Breakthrough mode. A single ANF massive quantity in Breakthrough mode scales to 2 PiB and delivers throughput within the tens of GiB per second by fanning I/O throughout six storage endpoints. That permits you to collapse sharded namespaces (the basic /proj1, /proj2, /proj3 break up that no person loves) into fewer high-throughput volumes that behave predictably beneath competition.

Cache Volumes are the FlexCache sample most ONTAP prospects already know. You peer a cluster, level a cache at an origin, and the cache propagates information on demand. Ron demoed this reside: cluster peering with on-prem ONTAP, a cache quantity created in ANF, and reads served from cache whereas the authoritative copy stayed residence.

Massive Volumes in Breakthrough mode are the place the structure will get attention-grabbing. As a substitute of a single mount level pinned to a single storage endpoint, Breakthrough mode exposes six storage endpoints for one logical quantity. Shoppers can mount, stability I/O, and mixture throughput throughout all six. Microsoft printed Linux scale-out benchmarks exhibiting a single 50 TiB massive quantity in Breakthrough mode sustaining roughly 50,000 MiB/s of sequential reads and approaching 1.8 million 8 KiB random learn IOPS utilizing twelve VMs (see the Microsoft Be taught hyperlink in Sources).

For shared environments, ANF added consumer and group quotas with real-time consumption reporting and exhausting limits. Ranga demoed quota guidelines that stopped a runaway simulation producing thousands and thousands of scratch recordsdata from ravenous the remainder of the staff. You probably have ever needed to ship the “who stuffed the scratch quantity” e-mail at 2am, this characteristic alone would possibly justify the journey.

On the associated fee aspect, the Versatile service stage decouples capability from throughput. You purchase a capability pool, you choose throughput independently, with 128 MiB/s of baseline throughput included and a ceiling of as much as 640 MiB/s per provisioned TiB (which is roughly 5 occasions the Extremely service stage). Cool Entry transparently tiers chilly blocks to Azure Blob behind the identical file mount level.

Briefly, you cease paying for throughput you don’t want on archival volumes, and also you cease overprovisioning capability to chase throughput on small scratch volumes.

The Proof part closed with SPEC Storage 2020 EDA Blended outcomes which can be price studying rigorously:

  • A single massive quantity in Breakthrough mode sustained 2,880 EDA jobsets at about 0.51 ms general response time.
  • Six volumes scaled linearly to 17,280 jobsets at about 0.60 ms.
  • FIO measurements approached 2 million IOPS.

The sincere tradeoff: these numbers come from a benchmark, not your setting, and the SPEC tables present latency climbing on the highest load factors. So deal with the consequence as proof that the platform behaves predictably beneath EDA-style concurrency, not as a assure for each workflow. That predictability is the half that issues. EDA leads don’t lose sleep over peak throughput, they lose sleep over latency that drifts when concurrency rises.

Sensible situations the place this lands:

  • Burst regression and verification runs to Azure throughout tape-out crunches, with Cache Volumes maintaining your on-prem golden tree authoritative.
  • Full migration of EDA environments to Azure for groups whose datacenters are out of capability or out of lease.
  • HPC simulation workloads (CFD, climate, seismic, life sciences) that share the identical metadata-heavy I/O profile.
  • AI-adjacent pipelines that must learn design information with file semantics and floor the identical bytes as objects to Cloth, OneLake, or Databricks by way of the twin file and object entry sample Ron talked about within the AI Prepared part.

You don’t want a multi-quarter mission to get a helpful pilot transferring.

  1. Register the Azure NetApp Recordsdata useful resource supplier in your goal subscription and request quota within the areas you care about.
  2. Rise up a small capability pool, begin with the Versatile service stage so you possibly can dial throughput independently.
  3. Create a check quantity, mount it from a consultant VM (HBv4 or Ev5 household are good beginning factors for HPC and EDA respectively).
  4. Run your actual workload, not simply FIO. Use a consultant regression batch or simulation job and watch the metadata patterns within the ANF metrics blade.
  5. You probably have on-premises ONTAP, peer a Cache Quantity towards it to check FlexCache conduct together with your precise datasets earlier than committing to a full migration.
  6. Layer in consumer and group quotas earlier than you open the quantity to a wider staff. Belief me on this one.

Catch the complete Microsoft Azure Infra Summit 2026 session playlist right here.

Cheers!

Pierre Roman

[ad_2]

Moonshot AI Releases Kimi K3: A 2.8 Trillion Parameter Open MoE Mannequin With Kimi Delta Consideration and 1M Context

[ad_1]

Moonshot AI simply launched Kimi K3. It’s a 2.8-trillion-parameter mannequin with native imaginative and prescient and a 1-million-token context window. Moonshot calls it the world’s first open 3T-class mannequin.

What’s Kimi K3?

Kimi K3 is a sparse Combination-of-Specialists (MoE) mannequin constructed on two architectural updates. These are Kimi Delta Consideration (KDA) and Consideration Residuals (AttnRes). Each change how data flows throughout sequence size and mannequin depth. K3 targets long-horizon coding, information work, and reasoning.

Moonshot workforce states K3 is the primary open mannequin to achieve 2.8 trillion parameters. For 9 of the previous twelve months, Kimi fashions set the higher sure of open-model sizes.

Moonshot can also be direct about the place K3 sits. General efficiency nonetheless trails essentially the most highly effective proprietary fashions, Claude Fable 5 and GPT 5.6 Sol. Throughout Moonshot’s personal analysis suite, K3 persistently outperformed different examined fashions.

https://www.kimi.com/weblog/kimi-k3

The Structure Beneath

Kimi Delta Consideration (KDA) is a hybrid linear consideration mechanism. Moonshot states it permits as much as 6.3x quicker decoding in million-token contexts.

AttnRes works alongside the opposite axis, which is depth. It selectively retrieves representations throughout depth fairly than accumulating them uniformly. Moonshot states AttnRes delivers roughly 25% increased coaching effectivity at below 2% further value.

Sparsity is the third lever. K3 makes use of Steady LatentMoE, successfully activating 16 of 896 specialists. At that sparsity, routing and optimization develop into first-order challenges. Quantile Balancing derives professional allocation instantly from router-score quantiles. That eliminates heuristic updates and a delicate balancing hyperparameter. Per-Head Muon extends Muon by optimizing consideration heads independently. Sigmoid Tanh Unit (SiTU) and Gated MLA enhance activation management and a spotlight selectivity respectively.

Refined coaching and information recipes accompany these structural adjustments. Collectively they yield roughly 2.5x higher total scaling effectivity than Kimi K2.

These decisions carry into serving. K3 applies quantization-aware coaching from the SFT stage onward. It makes use of MXFP4 weights with MXFP8 activations for broad {hardware} compatibility. Moonshot workforce recommends supernode configurations with 64 or extra accelerators. As a result of KDA poses new challenges for prefix caching, Moonshot contributed an implementation to vLLM.

[ad_2]