Home Blog Page 9

Geekbench 7 is out now with new, trendy workloads and higher multi-core checks

0

[ad_1]

[ad_2]

Fields Medal 2026 winners embrace mathematician Hong Wang — the third girl to ever win within the award’s 90-year historical past — for fixing decades-old needle conjecture

0

[ad_1]

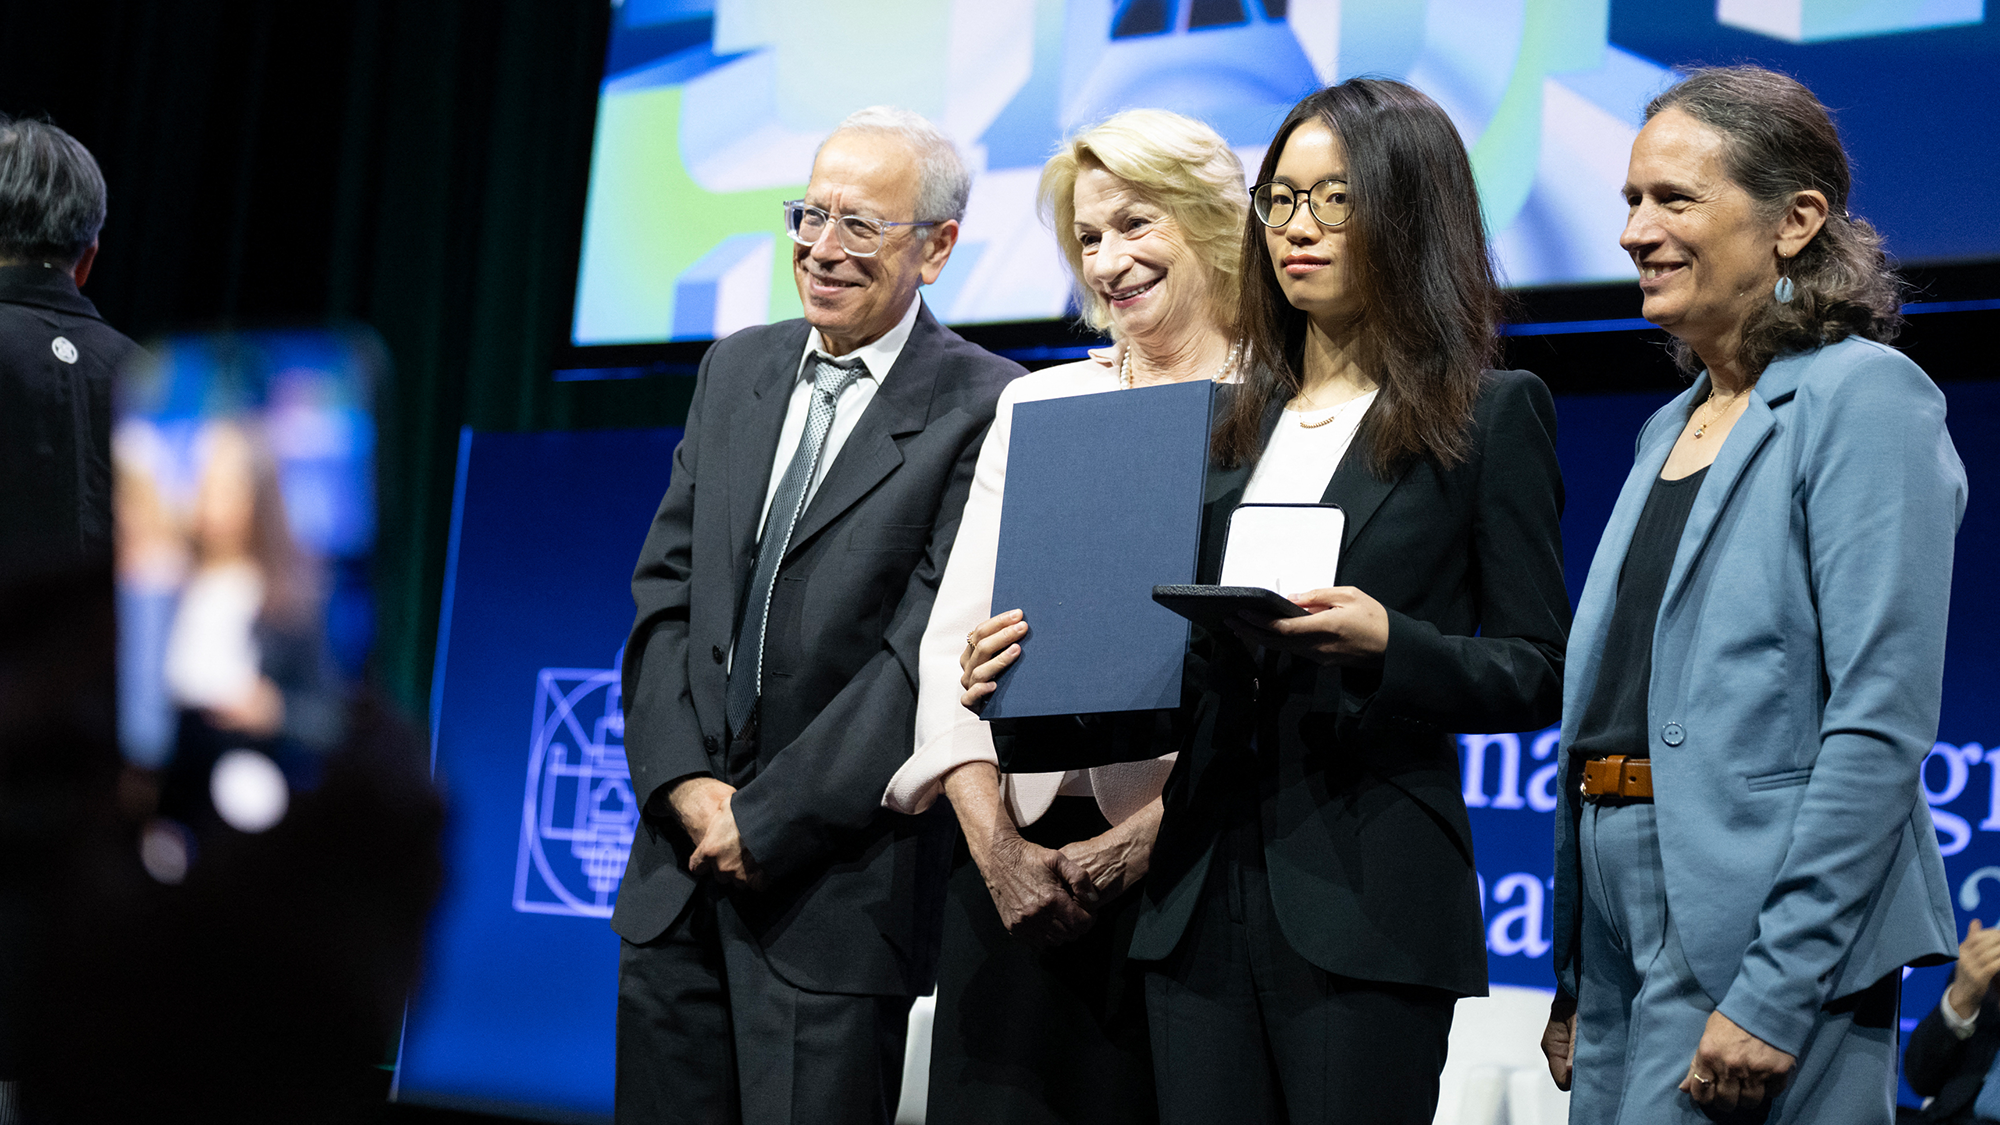
The 2026 Fields Medal, one of many world’s most prestigious arithmetic prizes, has simply been awarded to 4 pioneering younger researchers — together with mathematician Hong Wang, the third girl ever to win the prize within the 90 years for the reason that award was established.

The Fields Medal is an award offered each 4 years to mathematicians beneath the age of 40 for his or her excellent discoveries. The Worldwide Mathematical Union introduced Thursday (July 23) that Wang, a professor at New York College, is among the many 4 recipients of the 2026 medal for her work on a decades-old conjecture about how needles transfer in 3D areas. .

[ad_2]

Evaluating AI Brokers: A manufacturing blueprint with Strands and AgentCore

[ad_1]

This put up was co-written with Motorway and the AWS Prototyping and AI Buyer Engineering (PACE) workforce.


Motorway, a UK-based on-line automotive market, runs a day by day public sale the place as much as 8,000 sellers bid on as much as 2,500 autos. Motorway labored with AWS Prototyping and AI Buyer Engineering (PACE) to construct an AI-powered seller inventory search agent that transforms how sellers discover autos, changing hours of handbook filtering with pure language queries.

The problem

The agent provides a confident-sounding response, however how do you show it really works reliably with actual cash on the road?

  • Software choice errors trigger fallacious search outcomes, eroding seller belief.
  • Semantic search misinterpretations return irrelevant outcomes. A question like “Petrol, Hybrid and electrical automobiles as much as 5 years previous” requires the agent to appropriately parse a number of constraints.
  • Context drift in multi-turn conversations loses seller refinements.
  • Non-deterministic outputs make single-trial testing unreliable.

The answer

Collectively, Motorway and AWS constructed an end-to-end analysis pipeline that diminished incorrect outcomes from 1 in 8 queries to 1 in 50 and lower situation detection time from few hours to jiffy.

The pipeline combines the Strands Brokers SDK with Amazon Bedrock AgentCore, a completely managed service for deploying and working AI brokers at scale. On this put up, you’ll learn to construct this pipeline to your personal brokers:

  • A two-phase analysis technique spanning build-time testing with strands-agents-evals (the open supply analysis library for Strands Brokers) and manufacturing monitoring with Amazon Bedrock AgentCore Evaluations.
  • A 3-layer framework for assessing software utilization, reasoning, and output high quality.
  • A five-stage deployment pipeline with high quality gates that block releases when metrics fall under thresholds.

A companion repository offers a deployable blueprint that you could adapt to your personal brokers. Though the blueprint makes use of AWS companies, the core rules are important and system-agnostic necessities for any production-ready AI agent. These rules embrace the three-layer analysis framework and using the move^okay metric for consistency.

Stipulations

It’s essential to have the next stipulations to comply with together with this put up.

Time to finish: 30–45 minutes for preliminary deployment and a pair of–3 hours to customise to your area.

Estimated prices: Operating the pattern analysis suite prices roughly $5–10 in Amazon Bedrock inference expenses. Manufacturing monitoring prices differ based mostly on sampling fee.

Safety observe: The companion repository implements least-privilege AWS Id and Entry Administration (IAM) roles, shops API keys in AWS Techniques Supervisor Parameter Retailer (not setting variables), and makes use of typed parameters to assist forestall injection assaults. See the repository README for particulars.

The labored instance: A seller inventory search agent

Motorway constructed the seller inventory search agent on the Strands Brokers SDK and Amazon Bedrock AgentCore. The agent exposes eight instruments that mix structured filtering throughout over 89 automobile attributes with vector similarity search powered by LanceDB and Amazon Titan Textual content Embeddings V2.

Sellers usually spent hours looking via listings utilizing CSVs and inflexible filters. By introducing a conversational AI agent, sellers can now speak to the agent: “Discover me diesel SUVs beneath 25k close to my dealership” or “one thing sporty and computerized for a household.”

With round 1,500 concurrent customers throughout peak hours, getting agent habits proper isn’t elective. A software choice error or semantic search misinterpretation instantly impacts person belief. Determine 1 exhibits the end-to-end request circulate: sellers submit pure language queries via an internet interface, which routes to Amazon Bedrock AgentCore Runtime. The runtime orchestrates calls to eight totally different instruments whereas utilizing Amazon Bedrock fashions (Claude for reasoning, Amazon Titan for embeddings). Software responses circulate again via the runtime to generate the ultimate dealer-facing outcomes.

Why agent analysis is totally different

Massive language mannequin (LLM) analysis focuses on textual content technology high quality: coherence, factual accuracy, response relevance. Agent analysis assesses one thing essentially totally different. Consider it this fashion: LLM analysis examines engine efficiency. Agent analysis assesses how the entire automotive drives in site visitors, in rain, or with a backseat filled with passengers.

Conventional LLM metrics don’t let you know whether or not the Motorway agent known as the fitting search software for “Grade 1 Suzuki fashions.” They don’t reveal if the agent handed right filter parameters to LanceDB. And so they miss whether or not a seller refining outcomes from a earlier flip will get the fitting response.

Analysis dimensionWhy it issues for brokers
Activity completionBrokers run multi-step workflows the place partial completion is widespread
Software use correctnessImproper instruments or unhealthy parameters can derail total workflows
Reasoning coherenceFlawed reasoning results in unpredictable failures as situations change
Reliability and consistencyNon-determinism means the identical enter can produce totally different outcomes
Security and complianceAutonomous brokers can take actions with real-world penalties
Price and effectivityAn agent requiring 50 API calls per process is probably not economically viable

A exact question like “Volkswagen Golf 7-12 years previous” may work completely, however a colloquial variant like “I’m in search of an older VW” may fail if the semantic search layer isn’t correctly evaluated.

Catch points earlier than deployment with strands-agents-evals

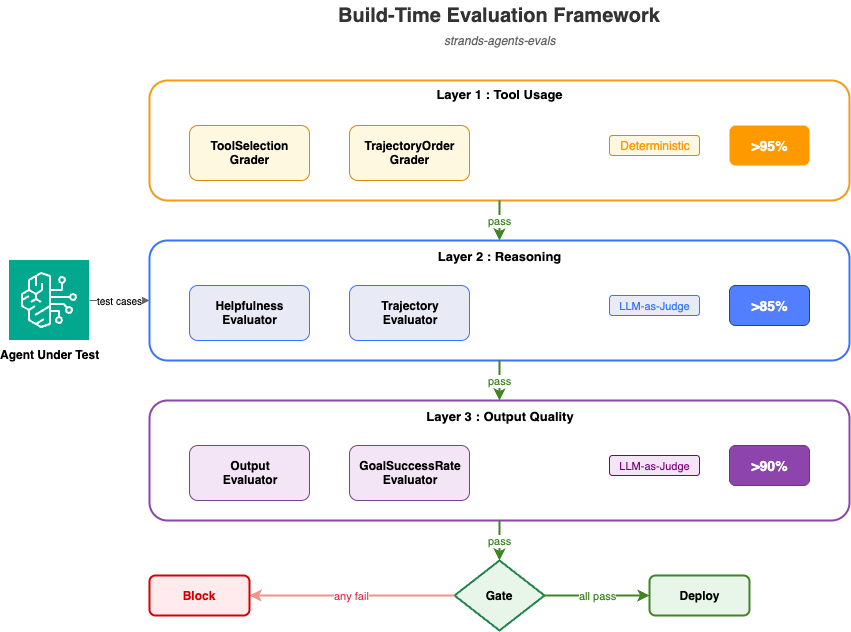
The blueprint implements analysis throughout two phases that map to the GenAIOps lifecycle. Construct-time analysis catches points earlier than deployment, and manufacturing analysis catches what artificial assessments miss. The next diagram (Determine 2) exhibits how the software utilization, reasoning, and output high quality layers should move earlier than deployment. The framework evaluates brokers throughout three layers:

  • Layer 1 (Software Utilization) validates right software choice and parameter passing with a better than 95 % threshold.
  • Layer 2 (Reasoning) assesses logical decision-making with a better than 85 % threshold.
  • Layer 3 (Output High quality) measures response helpfulness and accuracy with a better than 90 % threshold. All three layers should move earlier than deployment proceeds.

Figure 2: Three-layer evaluation framework with Layer 1 tool usage at greater than 95% threshold, Layer 2 reasoning at greater than 85% threshold, and Layer 3 output quality at greater than 90% threshold

Throughout growth and steady integration and steady deployment (CI/CD), the pipeline makes use of the strands-agents-evals framework to catch points earlier than deployment. It offers output validation, trajectory analysis, multi-turn dialog simulation, and automatic experiment technology. Every is designed to work natively with brokers constructed on the Strands Brokers SDK. The framework offers three primitives:

  • Experiment: A group of check instances run in opposition to the agent.
  • Case: Enter question, anticipated output, and anticipated software trajectory.
  • Evaluator: Scoring logic (deterministic or LLM-based).

Construction your assessments into layers. Layer 1 runs deterministic code-based graders for software choice accuracy. Layers 2 and three use LLM-as-judge evaluators (utilizing an LLM to attain agent outputs) for reasoning and output high quality.

Customized Evaluator subclasses deal with domain-specific issues. For the Motorway agent, these cowl knowledge freshness, seller scoping, and security guardrails. Your agent may have its personal area constraints.

Three sorts of graders

The analysis framework makes use of three grader sorts, every suited to totally different analysis wants.

Grader sortLayerWhat it measuresCommerce-off
Code-based deterministicLayer 1Software choice, parameter passing, trajectory orderingQuick, low-cost, reproducible
LLM-as-judge (Claude Sonnet 4.6)Layers 2–3Reasoning high quality, output helpfulness, objective successVersatile; non-deterministic (managed through move^okay)
Human evaluateCalibrationEdge instances and securityCostly; used to calibrate LLM decide prompts

In follow, grading what the agent produced catches extra points than grading the trail it took. You care that the person acquired related outcomes, not which software the agent known as first.

Three-layer evaluation framework

Construct-time analysis operates throughout three distinct layers, every with particular move/fail thresholds.

Layer 1: Software Utilization (> 95 % threshold). Did the agent name the fitting instruments with right parameters?

  • “Diesel autos from £7,000 to £20,000” ought to use search_vehicles with typed filters

    (fuel_type=diesel, min_price=7000, max_price=20000).
  • “Fashionable hatchback with low mileage” ought to set off hybrid_search, combining semantic embeddings with structured filters.

You measure this deterministically: ToolSelectionGrader checks which instruments have been known as, TrajectoryOrderGrader verifies the decision sequence.

Layer 2: Reasoning (> 85 % threshold). Was the decision-making course of logical? The HelpfulnessEvaluator and TrajectoryEvaluator from strands-agents-evals use LLM-as-judge scoring to evaluate whether or not the agent’s reasoning holds collectively. An agent that arrives on the proper response via illogical reasoning will fail unpredictably as situations change.

Layer 3: Output High quality (> 90 % threshold). Was the response useful, correct, and actionable? The OutputEvaluator and GoalSuccessRateEvaluator from strands-agents-evals use LLM-as-judge analysis to evaluate whether or not the person acquired a helpful, well-formatted response.

The three layers should move earlier than deployment. A failure in a layer blocks the pipeline.

Dealing with non-determinism

As a result of LLM outputs differ between runs, single-trial outcomes could be deceptive. The run_all_layers() perform within the companion repository accepts a num_trials parameter to deal with this. Two metrics from the code technology analysis neighborhood assist measure reliability:

  • move@okay measures the probability of succeeding at the least as soon as in okay makes an attempt. This metric is helpful when discovering one right resolution is ample.
  • move^okay (move to the facility of okay) measures the chance of succeeding in okay consecutive trials. This metric is helpful when customers count on dependable habits each time.

For customer-facing brokers, move^okay issues most. An agent with a 75 % per-trial success fee has solely a 42 % probability of passing three consecutive trials (0.75³). Customers count on constant high quality on each interplay.

Within the companion code, run_all_layers(task_fn, registry, num_trials=5) runs the analysis layers with multi-trial assist and gates deployment on move^okay. See the full implementation.

Take a look at case administration

Take a look at instances are organized by class:

  • Joyful path: Frequent queries that ought to succeed.
  • Edge instances: Ambiguous queries, slang, multi-turn refinements.
  • Security/Guardrails: Queries the agent ought to refuse or redirect.

When manufacturing monitoring detects a problem, that interplay turns into a brand new check case. Motorway’s suite grew from an preliminary 50 instances to 150 in three months, every grounded in actual person habits. Begin with 20 to 50 instances and let manufacturing knowledge develop the suite.

Embody adverse instances the place the agent ought to not name sure instruments. For instance, a profile question ought to name the profile software, not the search software. A structured question ought to use structured search, not a uncooked SQL fallback. One-sided evals create one-sided optimization.

Multi-turn dialog testing

Single-turn analysis misses a vital dimension: conversational coherence. Sellers naturally refine searches throughout a number of turns:

  • Flip 1: “Discover me diesel SUVs.”
  • Flip 2: “Now present me solely the automatics.”
  • Flip 3: “What about estates as a substitute?”

The strands-agents-evals framework offers ActorSimulator to generate real looking multi-turn interactions and InteractionsEvaluator to attain context retention throughout turns. Multi-turn assessments catch context drift, filter accumulation errors, and pronoun decision failures that single-turn assessments miss.

Monitor manufacturing habits with AgentCore Evaluations

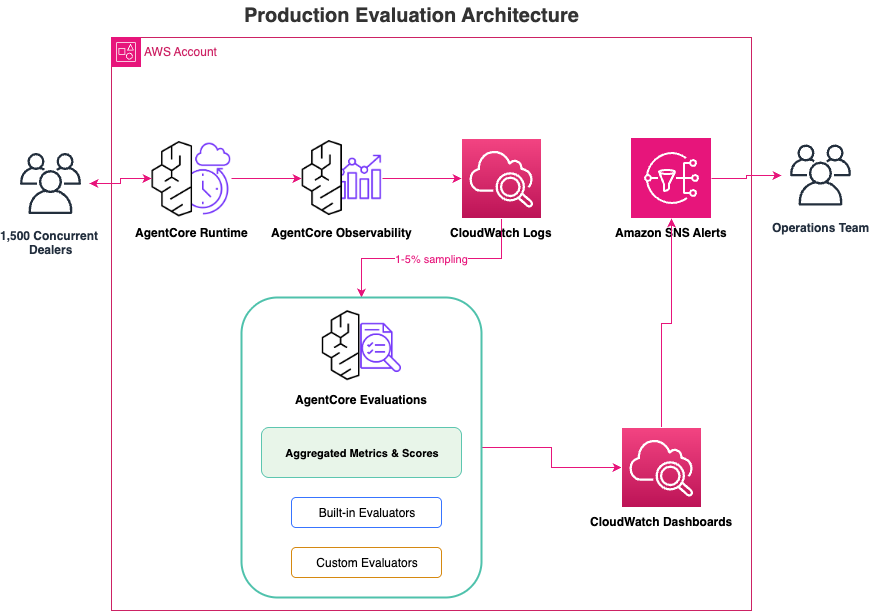
After you deploy your Strands Agent to Amazon Bedrock AgentCore Runtime, AgentCore Evaluations offers steady monitoring. It integrates with Strands Brokers via OpenTelemetry instrumentation (the industry-standard observability framework). Determine 3 illustrates the structure in manufacturing, with observability traces sampled at 1–5 % and with metrics aggregating to Amazon CloudWatch.

Figure 3: Production evaluation architecture with AgentCore Runtime, sampled OpenTelemetry traces feeding AgentCore Evaluations, and metrics on CloudWatch with Amazon SNS alerts

Two monitoring approaches

AgentCore Evaluations provides two complementary modes:

On-demand analysis analyzes particular agent interactions by choosing spans from Amazon CloudWatch logs. That is helpful for debugging points or validating fixes.

On-line analysis robotically samples stay site visitors and applies evaluators within the background. Configure a sampling fee (1–5 % is really helpful), choose as much as 10 evaluators, and let it run.

Constructed-in and customized evaluators

AgentCore offers pre-configured evaluators for widespread eventualities. The next desk exhibits the built-in evaluators and what they measure.

EvaluatorStageWhat it measures
Builtin.HelpfulnessTRACEHow useful the agent’s response is (0–1 rating throughout 7 ranges)
Builtin.GoalSuccessRateSESSIONWhether or not the person’s total objective was achieved
Builtin.ToolSelectionTOOL_CALLWhether or not the agent chosen acceptable instruments
Builtin.CorrectnessTRACEFactual accuracy of the response

For domain-specific necessities, you possibly can create customized evaluators utilizing an LLM-as-a-judge configuration. Each agent has area constraints that inbuilt evaluators don’t cowl, together with knowledge freshness, entry scoping, forbidden actions, latency budgets, and value limits.

The companion repository consists of 5 customized Evaluator subclasses you possibly can adapt:

EvaluatorWhat it validates
DataFreshnessEvaluatorValidates auction-cycle timestamps so the agent doesn’t floor stale stock
SafetyGuardrailEvaluatorBlocks the agent from making an attempt automated bidding actions
DealerDataScopingEvaluatorEnforces dealer-scoped queries for knowledge isolation

See the companion repository for LatencyEvaluator and CostEvaluator examples.

Key metrics to trace

The companion repository consists of an AWS CDK stack that provisions CloudWatch dashboards and alarms. Observe these metrics to watch agent well being.

MetricGoalAlert threshold
Activity completion fee>95%<80%
Software choice accuracy>95%<90%
Helpfulness rating (0-1)>0.83<0.58
Response latency P50 / P99<2s / <10s>5s / >15s
Hallucination fee<2%>5%
Price per interplayMonitor development>2x baseline

Make high quality checks a deployment gate

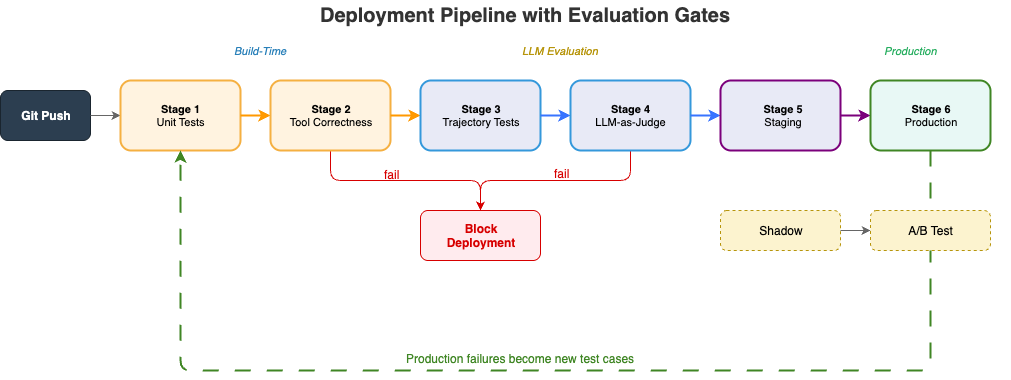
Analysis must be a high quality gate in your deployment pipeline, not an afterthought. Determine 4 exhibits the deployment pipeline with analysis gates, spanning build-time analysis, staging validation, shadow mode, A/B testing, and manufacturing rollout, with failures blocking deployment.

Figure 4: Five-stage deployment pipeline covering build-time evaluation, staging validation, shadow mode, A/B testing, and production rollout, with failures blocking deployment and feeding new test cases

The deployment pipeline follows 5 phases:

  1. Construct-time analysis: Unit assessments, software correctness (ToolSelectionGrader >95 %), trajectory assessments, and LLM-as-judge scoring (HelpfulnessEvaluator >85 %).
  2. Staging validation: On-demand AgentCore analysis with artificial site visitors in opposition to staging knowledge.
  3. Shadow mode: Actual manufacturing site visitors processed in parallel with out person impression. Run this for at the least 4 hours with a 2 % deviation threshold.
  4. A/B testing: 5 % of stay site visitors routes to the candidate agent for actual end result measurement.
  5. Manufacturing rollout: one hundred pc site visitors with steady on-line analysis and monitoring.

You outline thresholds for every section: software choice accuracy under 95 % or process completion under 80 % blocks deployment. For main releases, multi-trial analysis with num_trials=5 gates on move^okay to catch non-deterministic failures.

Shadow mode

Between staging and manufacturing, run the candidate agent in opposition to actual queries with out affecting customers. Shadow mode receives a duplicate of manufacturing site visitors, processes it via the candidate in parallel, and compares outcomes. Run shadow mode for at the least 4 hours earlier than continuing to A/B testing. Outline a deviation threshold (2 % is an efficient place to begin) that pauses deployment robotically.

Shadow mode catches points that the opposite levels miss:

  • Timeout dealing with beneath concurrent load.
  • Area terminology lacking from artificial assessments.
  • Software name ordering that causes latency spikes beneath actual site visitors patterns.

Getting began: A phased strategy

Part 1: Construct your check suite. Begin with 20–50 check instances drawn from actual person queries. Embody optimistic and adverse instances. Take a look at what the agent ought to do and what it ought to refuse.

Part 2: Configure build-time analysis. Match grader sorts to what you’re measuring: deterministic for software choice, LLM-as-judge for reasoning and output high quality.

Part 3: Allow manufacturing monitoring. Configure AgentCore Evaluations with a 1–5 % sampling fee. Begin low, then enhance when you’ve confirmed evaluator prices are acceptable.

Part 4: Shut the suggestions loop. Flip manufacturing failures into check instances. When failures turn out to be regression assessments, this suggestions loop has constantly improved analysis high quality throughout groups.

Outcomes and impression

Earlier than implementing this analysis pipeline, the agent had an 87% software choice accuracy- which meant 1 in 8 seller queries returned fallacious outcomes. The workforce was seeing 12 manufacturing incidents per thirty days, and it took a mean of 4 hours to detect points after they began affecting sellers.

After implementing the pipeline:

MetricEarlier thanAfter
Software choice accuracy87%98%
Activity completion fee82%96%
Context retention (multi-turn)71%94%
Manufacturing incidents (month-to-month)122
Imply time to detect pointsfew hoursjiffy

The enterprise impression: sellers now full automobile searches in minutes as a substitute of few hours, with confidence that outcomes are correct and present.

Troubleshooting

See the companion repository README for options to widespread points together with trajectory grader failures, LLM-as-judge variance, empty analysis outcomes, and value threshold tuning.

Key takeaways

Maintain these rules in thoughts when constructing your analysis pipeline.

  • Layer your analysis: Software utilization (>95 %), reasoning (>85 %), and output high quality (>90 %) catch totally different failure modes.
  • Gate on move^okay, not single trials: A 75 % per-trial success fee means solely 42 % reliability throughout three consecutive runs.
  • Flip manufacturing failures into check instances: Let actual person habits develop your analysis suite.
  • Shadow mode catches what artificial assessments miss: Actual site visitors reveals timeout dealing with, uncommon terminology, and latency patterns.
  • Begin monitoring at 1 % sampling: Scale regularly to handle evaluator prices.

Conclusion

You’ve now seen construct an analysis pipeline for manufacturing AI brokers on AWS, utilizing Motorway’s seller inventory search agent as a labored instance.

The core lesson: a fluent response doesn’t imply the agent did the fitting factor. It’s essential to confirm software choice, parameter correctness, reasoning coherence, and consistency throughout repeated runs. By combining build-time testing with strands-agents-evals and manufacturing monitoring with AgentCore Evaluations, you possibly can deploy brokers with proof that they work as designed.

These patterns apply to most multi-tool, customer-facing brokers: whether or not you’re constructing customer support brokers that question information bases and ticketing techniques, monetary advisory brokers that pull portfolio knowledge and market feeds, or healthcare triage brokers that entry affected person data and scheduling instruments.

To get began:

  1. Clone the companion repository:
    git clone https://github.com/aws-samples/sample-evaluating-agents-on-aws-with-strands-and-agentcore

  2. Navigate to the CDK undertaking listing:
    cd sample-evaluating-agents-on-aws-with-strands-and-agentcore/examples/vehicle-auction-agent/cdk

  3. Deploy the pattern infrastructure:

    Observe the repository README deployment steps to deploy the pattern infrastructure. After deployment completes, confirm the infrastructure by checking that each one AWS CloudFormation stacks present CREATE_COMPLETE standing within the AWS CloudFormation console. You must see the CloudWatch dashboard and Lambda features listed of their respective consoles.
  4. Run the pattern analysis suite in opposition to the included check instances to see the three-layer framework in motion. Confirm success by confirming: Layer 1 (Software Utilization) exhibits better than 95% move fee, Layer 2 (Reasoning) exhibits better than 85% move fee, and Layer 3 (Output High quality) exhibits better than 90% move fee. If a layer fails, examine the CloudWatch logs for detailed error messages.
  5. Customise the evaluators to your area. Begin with the DataFreshnessEvaluator and SafetyGuardrailEvaluator as templates.

To dive deeper, discover the Amazon Bedrock AgentCore documentation and the Strands Brokers SDK on GitHub.

Clear up sources

To keep away from incurring ongoing expenses, delete the sources created on this walkthrough:

  1. Navigate to the CDK undertaking listing:
    cd sample-evaluating-agents-on-aws-with-strands-and-agentcore/examples/vehicle-auction-agent/cdk

  2. Destroy all deployed stacks:
  3. Affirm the deletion when prompted.
  4. Confirm within the AWS Administration Console that the cleanup course of eliminated all sources, together with Lambda features, S3 buckets, DynamoDB tables, CloudWatch log teams and dashboards, EventBridge guidelines, and SNS subjects.

Be aware: S3 buckets that include objects could require handbook deletion. Export any analysis knowledge or logs that it’s good to retain earlier than operating the cleanup.

Sources


In regards to the authors

Amit Deol

Amit Deol

Amit is a Senior Prototyping Architect at AWS Prototyping and Cloud Engineering (PACE). He companions with AWS prospects to experiment with new concepts and construct production-ready options throughout generative AI, knowledge and analytics, and real-time streaming. When he’s not prototyping, you’ll discover him on lengthy walks via the woods.

Hin Yee Liu

Hin Yee Liu

Hin Yee is a Senior Prototype Engagement Supervisor at AWS. She leads buyer engagements that speed up the trail from AI prototypes to manufacturing, serving to groups undertake greatest practices for constructing and working generative AI workloads on AWS.

Ryan Cormack

Ryan Principal Engineer at Motorway and an AWS Group Builder. He leads growth of AI-powered instruments for sellers and has spoken at AWS Summit London on Motorway’s adoption of agentic AI.

[ad_2]

Azure Recordsdata, Reimagined: High-Degree Shares with Per-Share Networking, Billing, and Scale

0

[ad_1]

Hey Of us!

When you have ever wrestled with Azure Recordsdata inside a storage account, juggling shared RBAC, shared networking, and shared IOPS throughout a pile of shares that actually mustn’t reside collectively, this session goes to handle all that. Throughout Microsoft Azure Infra Summit 2026, Vincent Du and Will Gries (each Product Managers on the Azure Recordsdata staff) walked us by the brand new Microsoft.FileShares useful resource supplier, a administration mannequin that promotes the file share itself to a top-level Azure useful resource.

📺 Watch the session:


For years, file shares lived inside a storage account, and that storage account dictated lots of choices for you. If one staff wanted a personal endpoint and one other wanted a service endpoint, you both compromised otherwise you created one other storage account. If one share received sizzling and consumed all of the IOPS, the opposite shares felt it too. Vincent and Will are on the staff that constructed the brand new mannequin to take away that compromise.

Here’s what modifications for you as an IT professional:

  • Every file share is its personal Azure useful resource with its personal RBAC, networking, billing, IOPS, and throughput.
  • Per-share price exhibits up straight in Azure Price Administration’s per-resource view, no extra Excel guesswork.
  • Encryption in transit is on by default for NFS shares, at no further price.
  • Provisioning is dramatically sooner. Of their head-to-head demo, 200 shares completed in about 50 seconds on the brand new mannequin versus about 720 seconds with the traditional stream.
  • A brand new MCP server helps you to create and handle shares from GitHub Copilot in VS Code with pure language.

In brief, the brand new mannequin trades the storage-account-as-gatekeeper sample for one thing that feels much more like the remainder of Azure (assume VMs and disks, the place the useful resource you care about is the useful resource you truly handle).

The brand new Microsoft.FileShares useful resource supplier helps you to deploy a file share with out first standing up a storage account. Once you go into the Azure portal, seek for “File share,” and click on create, you fill out a single create blade with the issues that truly matter for that share: title, area, redundancy (LRS or ZRS), provisioned capability, IOPS and throughput, networking, and tags. Microsoft Be taught confirms the provisioned capability vary is 32 GiB to 262,144 GiB, and solely LRS and ZRS redundancy can be found at launch (see the Create a file share doc linked under).

At GA, the brand new expertise helps NFS 4.1 on the SSD media tier. SMB help, HDD help, customer-managed key encryption at relaxation, smooth delete, and the AKS CSI driver integration are all on the roadmap and known as out because the most-requested follow-ups. When you want these options at present, the traditional file share inside a storage account continues to be there for you.

Within the portal, Vincent confirmed off a small however significant element: the icon shade modified from blue (traditional) to purple (new). It’s a small factor, however if you find yourself scanning a useful resource group, that visible cue saves you a click on.

The brand new mannequin is constructed on the provisioned v2 billing construction. Microsoft Be taught describes provisioned v2 as a billing mannequin the place you independently provision storage, IOPS, and throughput, and also you pay for what you provision no matter how a lot you truly use. It is a actual shift from the older provisioned v1 mannequin, the place IOPS and throughput had been a perform of how a lot storage you provisioned.

Will walked by the mathematics. In his instance, provisioning 14 TiB of storage on v1 gave 17,000 IOPS, about 1.5 GB/s throughput, and a invoice of roughly $2,297. Transferring to v2 with the very same numbers was already noticeably cheaper. Then, as a result of v2 helps you to tune storage, IOPS, and throughput individually, he provisioned the precise storage he wanted with barely much less IOPS and throughput, dropping the invoice to roughly a 3rd. For database-hot workloads you possibly can dial IOPS up; for warm archive situations you possibly can dial them all the way down to the minimal. That form of flexibility is genuinely helpful.

Encryption in transit deserves its personal callout. The brand new shares default to encrypted NFS mounts utilizing the AZNFS mount helper. Microsoft Be taught explains that AZNFS wraps the NFS connection in a Stunnel-based TLS tunnel utilizing AES-GCM, so that you get TLS safety with no need Kerberos or exterior authentication. The helper installs cleanly on Ubuntu, RHEL, SUSE, Rocky, Oracle Linux, Alma Linux, and Azure Linux. If a workload genuinely can’t use the encrypted mount, you possibly can uncheck the field and fall again to a conventional NFS mount.

Networking is per share. You may connect a service endpoint or a personal endpoint to every particular person share, which implies you possibly can put a strict private-endpoint-only share subsequent to a service-endpoint share for dev/take a look at, all in the identical useful resource group, with out compromise.

On the request facet, traditional shares throttle with a set window (you possibly can burst, then you’re locked out for the remainder of the window). The brand new mannequin makes use of a token-bucket algorithm (the identical one Azure Useful resource Supervisor itself makes use of), which implies you get a sustained refill price. The staff additionally gave you a separate delete bucket, so a giant cleanup operation doesn’t starve writes. That element issues greater than it sounds: batch cleanups in opposition to the traditional mannequin usually crowd out new share creation.

The place does this truly repay? A number of trustworthy situations:

  • Mission-critical and controlled workloads. A healthcare org with workloads at completely different sensitivity ranges can put strict private-endpoint-only shares subsequent to much less delicate service-endpoint shares with out the storage-account ceiling.
  • Chargeback and showback. With per-share assets, finance can pull a value report that strains as much as the staff or mission that owns every share. No extra saying “we can’t itemize, the storage account is shared.”
  • Excessive-density tenants. The traditional mannequin successfully caps you at 34 file shares on an SSD provisioned v2 storage account (due to IOPS minimums) and 50 absolute. The brand new mannequin goes as much as 10,000 shares per subscription per area. That may be a completely different recreation.
  • Tuned database and analytics shares. Provisioned v2 helps you to right-size IOPS to the workload. As Will confirmed, that may drop the invoice to roughly a 3rd for the best form of workload.
  • Sooner deployment automation. A 14x enchancment on a 200-share deployment is just not a micro-optimization. When you spin up environments for CI, coaching, or per-customer tenants, that provides up shortly.

The trustworthy tradeoff: at present, the brand new mannequin is NFS-only on SSD. When you want SMB, HDD, customer-managed keys for NFS, or AKS CSI driver help, keep on the traditional mannequin for now. The staff was upfront about that, and the GA-and-then-iterate roadmap is obvious.

Right here is the concrete path:

  1. Register the Microsoft.FileShares and Microsoft.Storage useful resource suppliers in your subscription (Subscriptions, Useful resource suppliers, Register).
  2. From the Azure portal, seek for “File share” within the market and click on Create. Decide LRS or ZRS, set the capability between 32 GiB and 262 TiB, and both settle for the really useful IOPS/throughput or set them manually.
  3. On the Superior tab, depart “Require encryption in transit” enabled (it’s on by default) and decide a customized mount title if you’d like one distinct from the useful resource title.
  4. On the Networking tab, connect a service endpoint or a personal endpoint, per share.
  5. Mount it in your Linux VM with the AZNFS mount helper. The portal generates the precise command to your distribution.
  6. When you reside in IaC land, the Microsoft.FileShares ARM and Bicep varieties can be found, and Terraform help is coming.
  7. When you reside in AI-assisted dev land, set up the Azure MCP server and ask Copilot in VS Code to create a share for you, pointing at an present VNet.

Catch the complete Microsoft Azure Infra Summit 2026 session playlist right here.

Cheers!

Pierre Roman

[ad_2]

Getting Began with OmniVoice-Studio – KDnuggets

[ad_1]


Introduction

 
You paste a paragraph of textual content into ElevenLabs, press Generate, and watch the character counter tick down. The free tier is gone earlier than you end testing. The Creator plan is $22 a month. The Professional plan is $99. And each audio file you generate leaves your machine and finally ends up on their servers, which issues the second your content material is delicate, proprietary, or just yours.

OmniVoice Studio is constructed on a special premise: every little thing runs in your {hardware}. Voice cloning, video dubbing, real-time dictation, voice design — all of it native, all of it free for private use, no API key required, no utilization counter. The challenge describes itself as “the open-source ElevenLabs different,” and that is correct, although the language protection alone makes the comparability fascinating: ElevenLabs helps 32 languages. OmniVoice Studio helps 646.

The challenge has gathered 7.1k GitHub stars and 1.1k forks. The most recent launch, v0.2.7, shipped Might 3, 2026, contains pre-built installers for macOS, Home windows, and Linux. This text covers the total path from set up to your first generated audio.


Beta discover: OmniVoice Studio is in lively beta. Issues can break between releases. For probably the most present fixes, cloning from supply and operating bun run desktop-prod is the beneficial path over pre-built installers.


What OmniVoice Studio Is and Why It Was Constructed

 
The best framing is that this: OmniVoice Studio offers you knowledgeable voice AI desktop app that by no means telephones house. No accounts, no subscriptions, no cloud calls throughout inference. Your reference audio, your scripts, your generated information — they keep in your machine.

Right here is how the function set and pricing examine on to ElevenLabs:


FunctionElevenLabsOmniVoice Studio
Pricing$5–$330/month, per-character billingFree for private use
Voice Cloning3-second clip3-second clip, zero-shot
Voice DesignGender, ageGender, age, accent, pitch, fashion, dialect
Languages32646
Video DubbingCloud-onlyTotally native
Knowledge PrivatenessAudio despatched to the cloudNothing leaves your machine
API KeysRequiredNot wanted
GPU AssistN/A (cloud)CUDA, Apple Silicon MPS, AMD ROCm, CPU
Desktop AppNomacOS, Home windows, Linux


Below the hood, OmniVoice Studio is a Tauri desktop software — a Rust-based framework that wraps a React frontend and a FastAPI backend with 97 API endpoints. Persistent state lives in SQLite. The AI pipeline is constructed on 4 open-source parts that do the precise work:

  1. WhisperX handles transcription, word-level speech recognition, and alignment.
  2. Demucs (from Meta) handles vocal isolation, separating speech from music and background noise.
  3. OmniVoice from k2-fsa is the zero-shot diffusion text-to-speech (TTS) engine — the mannequin that makes cloning work from a 3-second clip throughout 646 languages.
  4. Pyannote handles speaker diarization, figuring out who stated what in a multi-speaker recording, which is what makes computerized voice task within the dubbing pipeline attainable.

GPU acceleration is auto-detected at launch. You do not configure something: OmniVoice reads your {hardware} and routes accordingly to CUDA (NVIDIA), MPS (Apple Silicon), ROCm (AMD), or CPU. If in case you have underneath 8 GB VRAM, the TTS mannequin offloads to the CPU routinely throughout transcription. The pipeline nonetheless runs, simply slower.


System Necessities

 
Earlier than putting in, examine that your machine meets the minimal specs. The app will run beneath these, however you’ll discover it.


PartMinimalBeneficial
OSHome windows 10 (21H2+), macOS 12+, Ubuntu 20.04+Any trendy 64-bit OS
RAM8 GB16 GB+
VRAM4 GB (TTS auto-offloads to CPU if much less)8 GB+ (NVIDIA RTX 3060+)
Disk10 GB free (fashions + cache)20 GB+ SSD
Python3.10+ (managed by uv)3.11–3.12
GPUNon-compulsory (CPU works)NVIDIA CUDA, Apple Silicon MPS, AMD ROCm


One factor value figuring out: you do not want a GPU to make use of OmniVoice Studio. Your complete pipeline runs on CPU. TTS synthesis is roughly 3x slower with no GPU, and transcription of lengthy movies will take longer, however for brief voice clones and dictation, the CPU path is completely usable. Apple Silicon Macs are the candy spot for GPU-less customers; the app routinely picks MLX-optimized Whisper and TTS backends that use the Apple Neural Engine and Metallic Efficiency Shaders, giving roughly 2x the throughput of the CPU path.


Putting in OmniVoice Studio

 
Choose the part on your working system and observe it from high to backside. The set up sequence is identical throughout platforms: clone, set up frontend dependencies with Bun, and launch. The variations are within the conditions.


// Putting in on macOS

Stipulations:

  • macOS 12 (Monterey) or newer — Apple Silicon or Intel
  • Python 3.11+
  • Bun (the JavaScript runtime used to construct the frontend)
  • Xcode Command Line Instruments
  • FFmpeg

Set up them so as:

# 1. Set up Python through Homebrew (or use pyenv in case you handle a number of variations)
brew set up python@3.11

# 2. Set up Bun
curl -fsSL https://bun.sh/set up | bash

# 3. Set up Xcode Command Line Instruments
xcode-select --install

# 4. Set up FFmpeg (utilized by the dubbing and seize pipelines)
brew set up ffmpeg


Then clone and run:

# Clone the repository
git clone https://github.com/debpalash/OmniVoice-Studio.git
cd OmniVoice-Studio

# Set up frontend dependencies
bun set up

# Launch the app
bun run desktop-prod


The primary launch is slower than each subsequent one. It builds the Tauri shell, creates the Python digital surroundings through uv, syncs all Python dependencies, and downloads mannequin weights — roughly 2.4 GB. The splash display screen reveals reside progress for every step. As soon as it completes, the total UI opens.

Pre-built DMG customers: Obtain the most recent DMG from the Releases web page, mount it, and drag OmniVoice Studio into /Functions. If the primary launch reveals “app is broken and cannot be opened,” that’s macOS Gatekeeper reacting to an unsigned app. The developer-ID signing and notarization pipeline is tracked for v0.4. For now, clear the quarantine attribute with a single terminal command:

# Take away the Gatekeeper quarantine attribute.
# Run this as soon as after putting in. The app is open supply -- confirm the
# SHA-256 checksum on the Releases web page in opposition to the .dmg.sha256 file
# earlier than operating this if you wish to affirm the obtain is clear.
xattr -cr "/Functions/OmniVoice Studio.app"


// Putting in on Home windows

Stipulations:

  • Home windows 10 (21H2 or newer) or Home windows 11, x64
  • Python 3.11+
  • Microsoft C++ Construct Instruments (required by pyannote.audio and occasional torch wheel rebuilds)
  • Bun
  • FFmpeg

Set up them from an everyday (non-admin) PowerShell:

# Set up Python through winget
winget set up Python.Python.3.11

# Set up Microsoft C++ Construct Instruments
# Obtain from https://visualstudio.microsoft.com/visual-cpp-build-tools/
# Choose "Desktop growth with C++" workload throughout set up

# Set up Bun
powershell -c "irm bun.sh/set up.ps1 | iex"

# Set up FFmpeg through winget
winget set up Gyan.FFmpeg


Then clone and run (nonetheless in PowerShell):

git clone https://github.com/debpalash/OmniVoice-Studio.git
cd OmniVoice-Studio
bun set up
bun run desktop-prod


Home windows-specific word (Triton/torch.compile OOM): On Home windows, sure TTS engines (notably CosyVoice paths) set off torch.compile kernel compilation on the primary synthesis name. On machines with underneath 16 GB VRAM, this could OOM earlier than any audio renders, surfacing as OutOfMemoryError: CUDA out of reminiscence. The repair is in Settings → Efficiency: toggle “Disable torch.compile (Home windows)” on. From the command line, set the surroundings variable earlier than launching:

# Disable torch.compile to keep away from OOM on first synthesis (Home windows solely).
# This falls again to the eager-mode kernel path -- barely slower peak
# throughput, however the engine really hundreds on low-VRAM machines.
$env:TORCH_COMPILE_DISABLE = "1"
bun run desktop-prod


Pre-built MSI customers: Obtain the most recent MSI from the Releases web page, run the installer, and discover OmniVoice Studio within the Begin menu.


// Putting in on Linux

Stipulations (Debian/Ubuntu):

# Set up Python
sudo apt set up python3.11

# Set up Bun
curl -fsSL https://bun.sh/set up | bash

# Set up FFmpeg
sudo apt set up ffmpeg

# Set up GTK/WebKit dependencies required by the Tauri desktop shell
sudo apt set up 
  libwebkit2gtk-4.1-dev 
  libayatana-appindicator3-dev 
  librsvg2-dev 
  libssl-dev 
  libxdo-dev 
  build-essential


Stipulations (Fedora):

sudo dnf set up python3.11 ffmpeg-free
curl -fsSL https://bun.sh/set up | bash
sudo dnf set up webkit2gtk4.1-devel libappindicator-gtk3-devel librsvg2-devel openssl-devel


Clone and run:

git clone https://github.com/debpalash/OmniVoice-Studio.git
cd OmniVoice-Studio
bun set up
bun run desktop-prod


Pre-built AppImage customers:

# Obtain the AppImage from the Releases web page, then:
chmod +x OmniVoice.Studio_*.AppImage
./OmniVoice.Studio_*.AppImage

# When you see a white display screen on Fedora 44+ or Ubuntu 24.04, set this:
WEBKIT_DISABLE_COMPOSITING_MODE=1 ./OmniVoice.Studio_*.AppImage


The white display screen on newer distros is a compositing regression in WebKitGTK 2.44/2.46. v0.3+ of the AppImage autodetects this and units the flag routinely. The handbook surroundings variable path is the fallback for supply installs.

Pre-built .deb customers:

sudo apt set up ./OmniVoice.Studio_*.amd64.deb
omnivoice-studio


Docker (backend solely):

For headless server use or staff deployments the place the desktop GUI is not wanted, OmniVoice Studio ships a Docker path that runs simply the FastAPI backend and its 97 API endpoints:

# Clone the repo if you have not already
git clone https://github.com/debpalash/OmniVoice-Studio.git
cd OmniVoice-Studio

# Construct and begin the backend container
docker compose -f deploy/docker-compose.yml up


The backend API is then accessible at http://localhost:8000. The complete API reference lives within the repo’s docs/ listing. This path is beneficial when integrating OmniVoice capabilities right into a pipeline with out operating a desktop session.


Setting Up Your Hugging Face Token

 
This step is non-compulsory for fundamental use, however required for 2 options: speaker diarization (the pyannote/speaker-diarization-3.1 mannequin is gated on Hugging Face) and the bigger voice-design engines.

You want a free Hugging Face account and a learn token. Upon getting one:

Possibility 1 — By the app (beneficial): Open Settings → API Keys, paste your hf_... token, and save. The app writes it to OmniVoice’s encrypted SQLite retailer and to the canonical huggingface_hub location, so each subprocess the app spawns picks it up routinely.

Possibility 2 — Setting variable:

# macOS / Linux -- add to ~/.zshrc or ~/.bashrc
export HF_TOKEN=hf_your_token_here
supply ~/.zshrc

# Home windows PowerShell -- writes to user-scope surroundings
# Use this, not setx. setx truncates values over 1024 chars and
# does not propagate to the present shell session.
[Environment]::SetEnvironmentVariable("HF_TOKEN", "hf_your_token_here", "Consumer")


You additionally want to just accept the mannequin phrases on the Hugging Face mannequin web page earlier than downloading. Go to pyannote/speaker-diarization-3.1 and settle for the gated mannequin entry request. This can be a one-time step.


Cloning a Voice

 
Voice cloning is the core function and the one most individuals set up OmniVoice for. The mannequin powering it’s OmniVoice from k2-fsa — a diffusion-based TTS system educated on 646 languages that operates zero-shot, that means there isn’t a fine-tuning step. You present a reference clip at inference time, and the mannequin adapts to the speaker’s voice on the fly.

Tips on how to clone a voice:
Navigate to the Voice Clone tab. You have got two choices for the reference audio: document straight within the app by clicking the microphone button, or add an current audio file. Both manner, 3 to 10 seconds of clear speech is sufficient.

Then:

  1. Add or document your reference audio clip.
  2. Choose the goal language from the dropdown (646 accessible).
  3. Sort or paste the textual content you need synthesized within the textual content subject.
  4. Click on Generate.

OmniVoice processes regionally, generates the audio, and performs it again for preview. You possibly can export to MP3, WAV, or FLAC from the export button.

What makes a very good reference clip: Background noise is the largest high quality killer. A clip recorded in a quiet room, with the speaker talking naturally, will clone higher than a loud excerpt from a cellphone name. Keep away from clips with background music; if that is all you might have, run it by means of the Vocal Isolation tab first (lined beneath) to strip the background earlier than utilizing it as a reference.

If the output sounds barely off — robotic consonants, fallacious rhythm — attempt an extended or totally different reference clip earlier than assuming an engine concern. The zero-shot mannequin is delicate to the standard of the reference audio.


Dubbing a Video

 
The dubbing pipeline is probably the most advanced factor OmniVoice Studio does, and watching it run end-to-end is genuinely spectacular. You give it a video — both a YouTube URL or an area file — and it transcribes the speech, interprets it to your goal language, clones the unique speaker voices, synthesizes the dubbed audio within the cloned voices, and muxes every little thing again into an MP4. Regionally. No add.

The pipeline makes use of WhisperX for transcription, Pyannote for speaker diarization (figuring out which voice belongs to which speaker), the OmniVoice mannequin for synthesis, and Demucs to separate the unique speech from background audio so the background may be preserved underneath the dubbed observe.

Tips on how to dub a video:

  1. Navigate to the Dub tab. Paste a YouTube URL or click on the add button to pick an area file. Select the goal language. Click on Begin Dub.
  2. The progress bar reveals every stage because it runs: obtain (for YouTube), transcription, diarization, translation, synthesis, and mux. For a 5-minute video on a machine with a GPU, the total pipeline usually takes 8 to 12 minutes. CPU-only will take longer.
  3. When full, the dubbed MP4 is obtainable within the Initiatives panel alongside the SRT subtitle file, the remoted stems, and the unique transcription.
  4. Batch queue: If in case you have a number of movies, drop all of them into the queue by clicking Add to Queue for every one, then click on Run All. The conductor processes them sequentially utilizing GPU execution with a reside progress bar per job. You possibly can add extra jobs whereas the queue is operating.


Designing a Voice

 
Voice design is for creating a brand new voice from scratch when you do not have a reference clip. Navigate to the Voice Design tab, and you will find sliders and controls for gender, age, accent, pitch, pace, emotion, and dialect.

The design course of is iterative: alter the controls, hit Preview, pay attention, alter once more. The A/B Comparability button allows you to lock one voice configuration as model A, tune the controls additional to create model B, and toggle between them whereas the identical pattern textual content performs, so that you’re evaluating voices straight somewhat than counting on reminiscence.

When you’re happy with a voice, put it aside to your Voice Gallery with a reputation and tags. Saved voices are then accessible as targets within the Voice Clone tab — you may synthesize new audio in a saved designed voice with no need a reference clip every time.


Utilizing the Dictation Widget

 
The dictation widget is a system-wide transcription instrument that works from any software with out switching home windows. The worldwide hotkey is Cmd+Shift+Area on macOS and Ctrl+Shift+Area on Home windows and Linux.

Press the hotkey from any app — your code editor, a browser textual content subject, a notes app, anyplace. A small frameless floating window seems. Begin talking. The widget streams your speech by means of WhisperX’s ASR engine over an area WebSocket connection, transcribes in actual time, auto-pastes the outcome into no matter software was targeted earlier than the widget opened, and disappears.

Your complete circulate — set off, converse, paste — takes a couple of seconds. There isn’t any window switching, no copy-paste step.

  1. Configuring the hotkey: If Cmd+Shift+Area conflicts with one other software in your system, open Settings → Dictation and alter the hotkey binding to any mixture that does not conflict. The brand new binding takes impact instantly with out restarting the app.
  2. What the widget doesn’t do: It doesn’t maintain a transcription historical past. Every activation transcribes and pastes, then discards the audio. For longer transcription classes the place you wish to evaluation and edit a full transcript, use the principle Transcription tab as an alternative — that information to a file and reveals a full editable transcript.


Selecting a TTS Engine

 
OmniVoice Studio ships six TTS engines. The default, OmniVoice, covers 600+ languages and handles voice cloning and instructed era. The others exist for particular causes, and switching takes ten seconds through Settings → TTS Engine or the OMNIVOICE_TTS_BACKEND surroundings variable.


EngineLanguagesCloneFinest For
OmniVoice (default)600+SureAll the things — the general-purpose engine
CosyVoice 39 + 18 dialectsSureInstructed era with fashion management
MLX-AudioMultiVariesApple Silicon solely, most pace on M-series
VoxCPM230SureCross-platform cloning with robust accent protection
MOSS-TTS-Nano20SureQuick cloning on lower-powered machines
KittenTTSEnglish solelyNoLight-weight CPU-only English TTS, close to real-time


For English-only use on a machine with no GPU, KittenTTS and MOSS-TTS-Nano run close to real-time on CPU. For Apple Silicon, switching to MLX-Audio offers you the quickest inference accessible on M-series {hardware} utilizing the Apple Neural Engine straight. CosyVoice 3 is the selection if you need instructed era — describing the voice fashion in pure language somewhat than dialing sliders.

Swap through the surroundings variable if you wish to set it system-wide:

# Run OmniVoice Studio with CosyVoice 3 because the lively TTS backend.
# Legitimate values: omnivoice, cosyvoice, mlx-audio, voxcpm2, moss-tts-nano, kittenTTS
export OMNIVOICE_TTS_BACKEND=cosyvoice
bun run desktop-prod

# Home windows equal
$env:OMNIVOICE_TTS_BACKEND = "cosyvoice"
bun run desktop-prod


Including a customized engine: OmniVoice makes use of a built-in backend registry. To plug in your individual TTS engine, subclass TTSBackend in backend/companies/tts_backend.py and add it to the _REGISTRY dictionary on the backside of that file. The README paperwork the interface as roughly 50 strains of Python. The CONTRIBUTING information covers the total growth setup.


Utilizing OmniVoice Studio through the MCP Server

 
OmniVoice Studio ships a Mannequin Context Protocol (MCP) server, which suggests you may name its TTS and dubbing capabilities from Claude Desktop, Cursor, or any MCP-compatible consumer — with out opening the desktop app in any respect.

That is helpful if you wish to generate voice audio from inside an AI coding session or automate voice era as a part of a pipeline that is already operating in an MCP-capable instrument.

The MCP server is uncovered on localhost:8765 when OmniVoice Studio is operating. To attach it to Claude Desktop, add the next to your claude_desktop_config.json:

{
  "mcpServers": {
    "omnivoice": {
      "command": "npx",
      "args": ["-y", "@omnivoice/mcp-server"],
      "env": {
        "OMNIVOICE_API_URL": "http://localhost:8765"
      }
    }
  }
}


As soon as related, Claude Desktop can name OmniVoice instruments straight. For instance, you may kind “Generate audio of this paragraph in a feminine voice with a British accent,” and Claude will route the request to OmniVoice’s native API, synthesize the audio, and return the file path.

The MCP server exposes the core capabilities — TTS era, voice cloning with a reference file, and dubbing job creation — as named instruments that any MCP consumer can uncover and invoke. See the docs/ listing within the repo for the total instrument schema.


Conclusion

 
OmniVoice Studio makes a sensible case for local-first voice AI. Not as a result of cloud instruments are dangerous, however as a result of 646 languages, no utilization meter, and audio that by no means leaves your machine add as much as one thing genuinely totally different. The setup — one set up sequence, a 2.4 GB mannequin obtain, and an non-compulsory Hugging Face token — is a one-time funding. All the things after that’s simply utilizing the instrument.

It is in lively beta, and a few edges are tough. However the core pipeline — cloning, dubbing, dictation, design — works, the group is responsive, and releases have been coming commonly since launch. For builders, content material creators, and researchers who work with audio and care about the place their information goes, it is value having regionally.


Shittu Olumide is a software program engineer and technical author captivated with leveraging cutting-edge applied sciences to craft compelling narratives, with a eager eye for element and a knack for simplifying advanced ideas. You can too discover Shittu on Twitter.


[ad_2]

Ultrahuman Emerald replace is very large: UltraSphere ‘determination engine’ is the star for us

0

[ad_1]

What you should know


Ultrahuman pushes its good rings and customers to be higher in well being and health. However the firm is not executed, and its main app overhaul right now (July 23) is the biggest in its historical past.

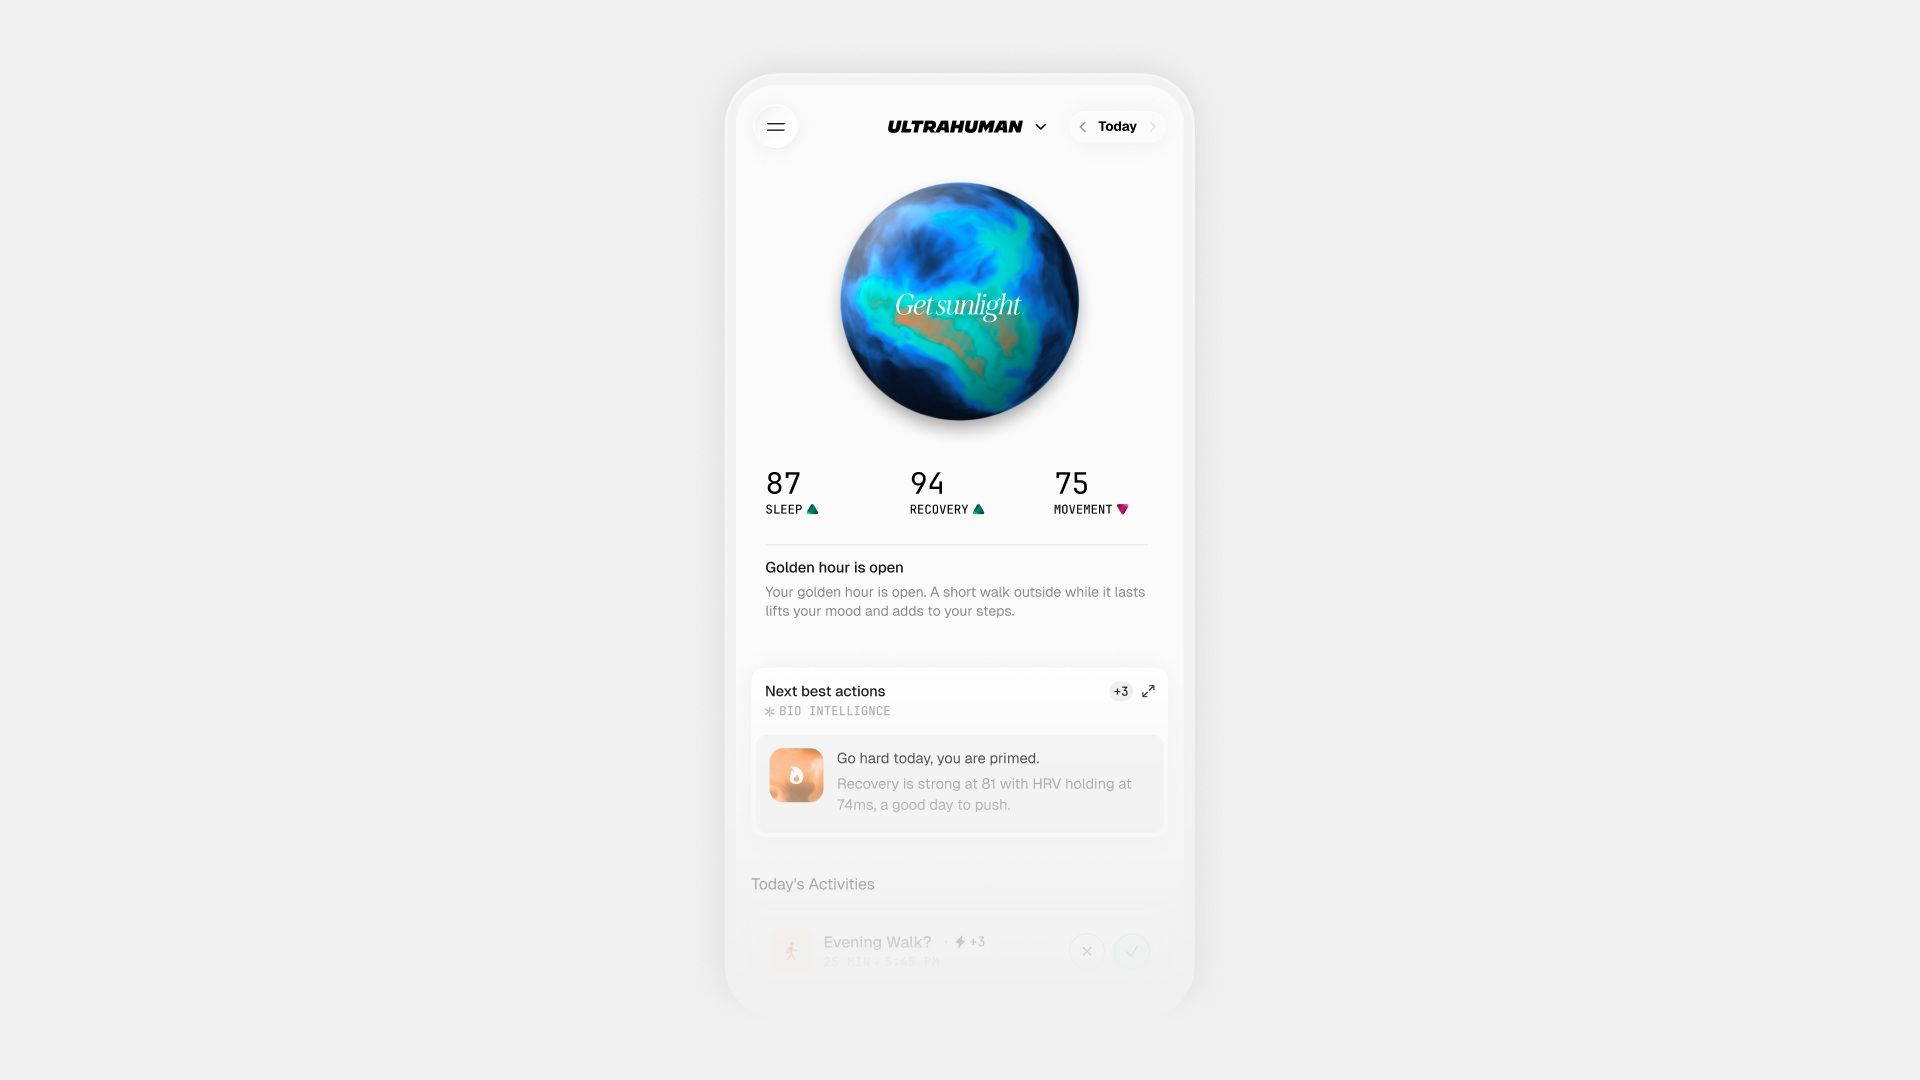
The Emerald replace is rolling out for the Ultrahuman app late this week. The corporate highlights “15 new and overhauled options” on this patch, however the star is the “determination engine,” UltraSphere. The app sports activities a number of UI refinements on this patch. The corporate states it redesigned its UI for readability for “well being information and to advertise higher selections.” Customers obtain mild and darkish modes, a Jade AI tab, and “well timed” data within the Ring tab.

[ad_2]

NASA’s retired astronauts are hitting the highway to get younger folks to vote: ‘one small step for you, and one big leap for our nation.’

0

[ad_1]

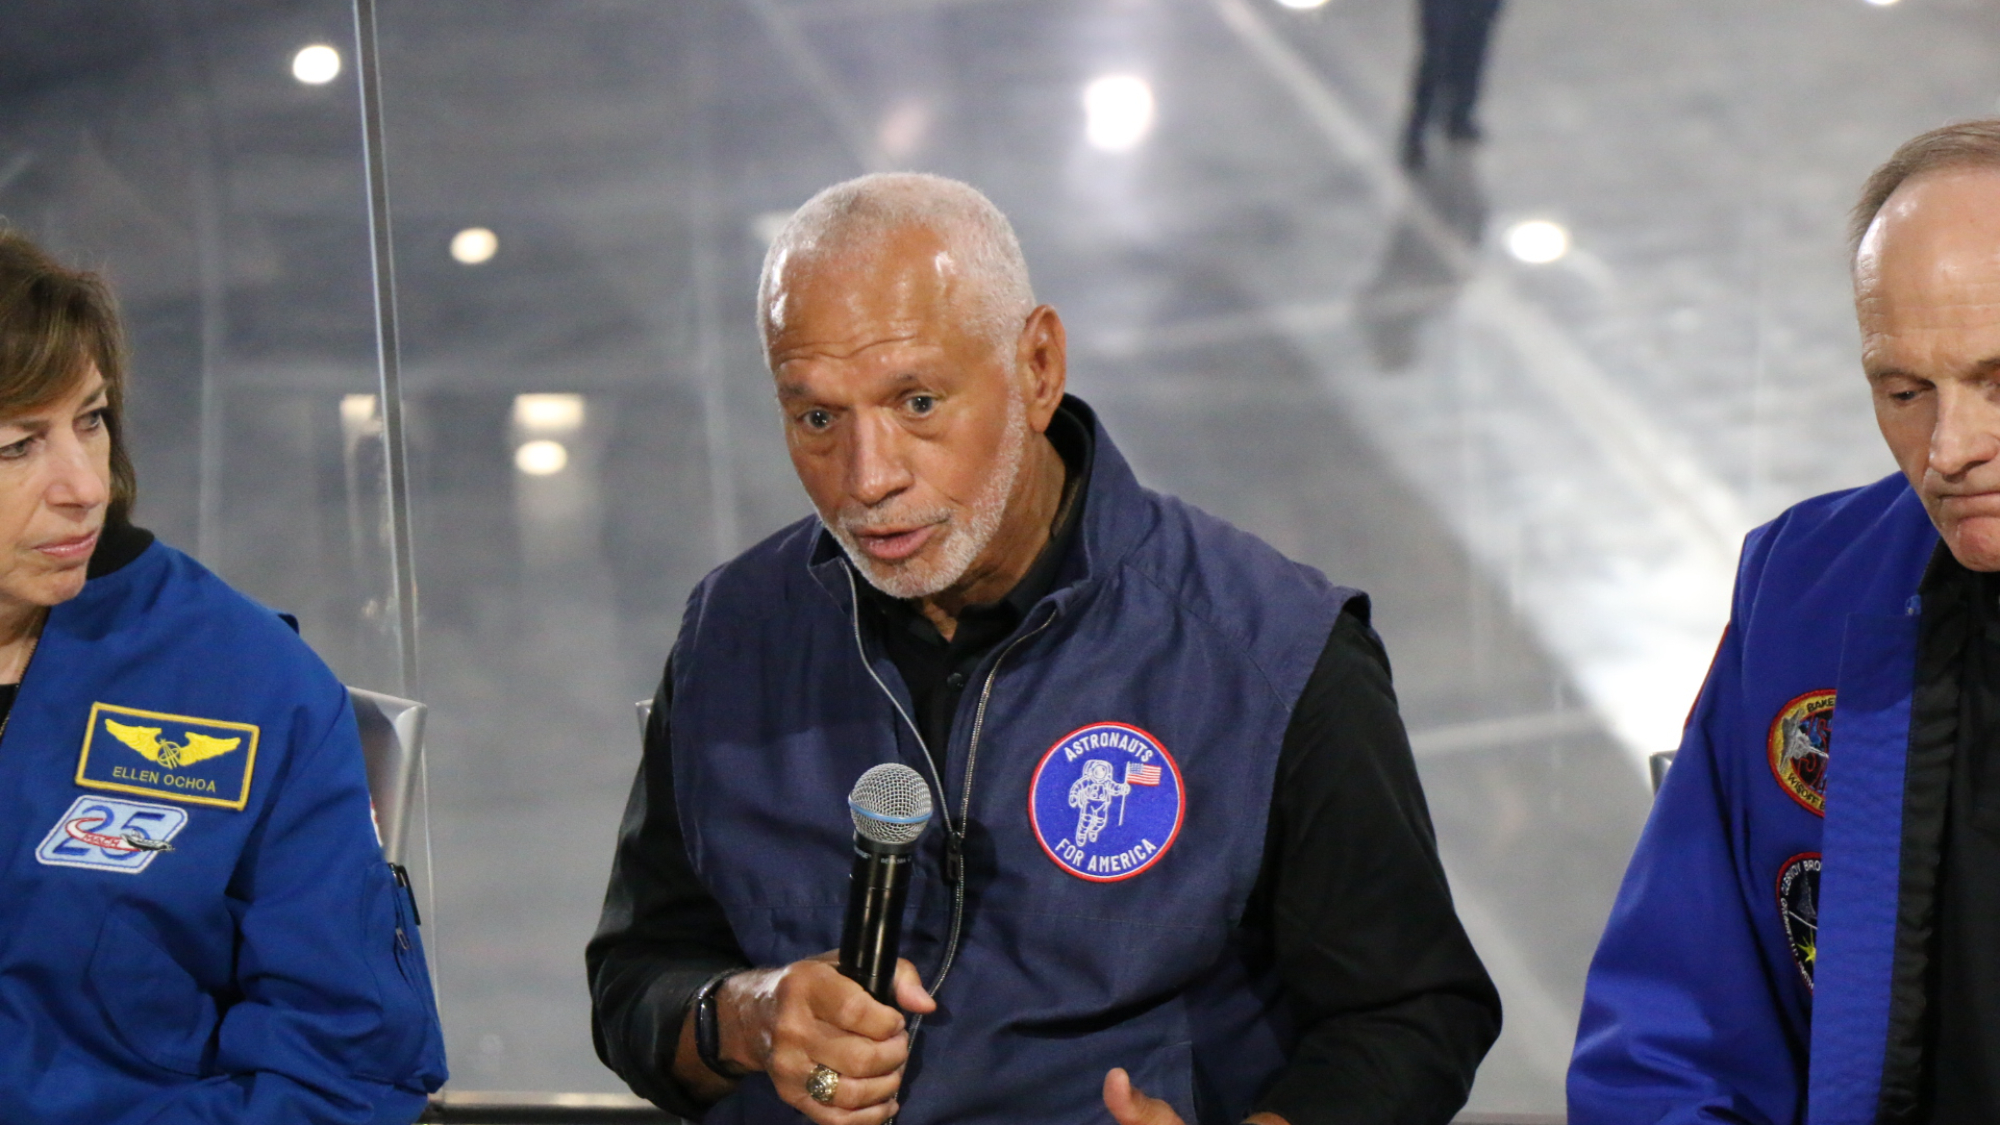
LOS ANGELES — Standing within the shadow of the area shuttle Endeavour, a bunch of retired NASA astronauts introduced their plan to journey the nation visiting schools to attempt to encourage youthful generations to get out and vote. This marketing campaign comes as we lead as much as the November midterm election.

This previous yr, a bunch of retired NASA astronauts teamed up for a single trigger: to defend the U.S. structure. They banded collectively as a part of a non-profit, non-partisan activist group referred to as Astronauts for America. To date, they’ve been talking out, utilizing their astronaut experience, platforms, cultural relevance and position mannequin standing to talk out in assist of “science, evidence-based decision-making, public service and the rule of legislation,” their web site reads. Now, because the group introduced at an occasion on the California Science Middle’s new air and area middle — house to the shuttle Endeavour — they’re hitting the highway on a marketing campaign tour of schools referred to as “Vote for Freedom.”

[ad_2]

Kaggle + Google’s Free 5-Day Agentic AI Course

[ad_1]


Agentic Studying

 
In November 2025, greater than 1.5 million folks signed up for a free course on constructing AI brokers. That is not a typo, and it isn’t a MOOC’s vainness metric for registrations that by no means convert: the identical cohort filed greater than 11,000 capstone submissions. Google and Kaggle’s 5-Day AI Brokers Intensive grew to become, by attendance, one of many largest technical programs ever run.

The excellent news for anybody who missed the stay week: all of it’s now free and self-paced, and there is much more to it than the hype steered.


What It Really Is

 
The course is Google and Kaggle’s follow-up to their 2024 GenAI Intensive, which itself drew 140,000-plus builders and a rerun that set a Guinness document for the biggest digital AI convention. The 2025 version narrowed the main target from generative AI broadly to brokers particularly, which is the correct name given how a lot confusion nonetheless surrounds what an agent even is.

The stay run occurred over 5 days in November 2025, however the entire thing has since been remodeled right into a self-paced Kaggle Be taught Information, so now you can work by it by yourself schedule. A refreshed run, themed round vibe coding, additionally went out in June 2026 for individuals who want the cohort expertise. Both manner, the fabric is the draw.


The 5 Days

 
Every day pairs a technical whitepaper with two hands-on codelabs constructed on Gemini and Google’s Agent Growth Package, so that you’re studying the idea after which instantly constructing it.

Day 1 – Introduction to brokers: Agent architectures and the basic query of when a job wants an agent in any respect versus a less complicated workflow. You construct your first agent and your first multi-agent system.

Day 2 – Instruments and interoperability with MCP: How brokers use instruments, easy methods to write customized ones, and the way the Mannequin Context Protocol (MCP) lets brokers discuss to exterior methods. Today additionally introduces human-in-the-loop approval for long-running operations, which is the distinction between a helpful agent and a harmful one.

Day 3 – Context engineering: Periods and reminiscence: Constructing stateful brokers that keep in mind, and giving them long-term reminiscence that persists throughout periods. That is the place most do-it-yourself brokers quietly crumble, so it is price slowing down right here.

Day 4 – Agent high quality: Logging, tracing, metrics, and evaluating each an agent’s responses and its software use. In case you take sooner or later severely, take this one. Measuring whether or not an agent works is the ability virtually no person teaches and everybody transport to manufacturing desperately wants.

Day 5 – Prototype to manufacturing: The agent-to-agent protocol and deploying to a managed runtime like Vertex AI Agent Engine. The unglamorous final mile between a pocket book that impresses your staff and a system actual customers can hit.


Who Ought to Take It, and How you can Get the Most from It

 
In case you can write Python and you’ve got referred to as an LLM API, you are prepared. The course assumes programming literacy however not agent experience, which is precisely the band most practitioners sit in proper now.

One piece of recommendation from watching how these intensives are likely to go: do not skim the whitepapers to hurry to the code. The analysis and context-engineering materials on days three and 4 is the place the sturdy understanding lives, and it is the half you’ll be able to’t decide up later by copying a working repo. The codelabs educate you to construct an agent. The papers educate you why yours retains breaking.

The entire thing is free, it is obtainable now on Kaggle, and the capstone provides you one thing actual to level at if you’re executed. One million and a half folks discovered 5 days for it. Yours are in all probability price the identical.


Nahla Davies is a software program developer and tech author. Earlier than devoting her work full time to technical writing, she managed—amongst different intriguing issues—to function a lead programmer at an Inc. 5,000 experiential branding group whose purchasers embrace Samsung, Time Warner, Netflix, and Sony.

[ad_2]

The Obtain: power transmission and US threats towards Chinese language AI

[ad_1]

2 Why the OpenAI hack is the scariest AI mishap but
AI’s capabilities appear to be beginning to outpace our present skill to regulate them. (The Economist $)
+ Hugging Face needed to flip to a Chinese language AI mannequin to rescue it from the hack. (BI)

3 Visually impaired Europeans can now get an implant that restores sight
And People might not have to attend lengthy to obtain it, too. (STAT)
+ This retina implant lets folks with imaginative and prescient loss do a crossword puzzle. (MIT Know-how Assessment)

4 A bellwether lawsuit suing Meta for social media dependancy has been dropped
There are, nonetheless, many extra ready within the wings. (NYT $)

5 Right here’s how ICE will get its palms on People’ knowledge
As quickly as you open a bank card or cellphone account, its brokers can see the place you reside. (404 Media)
States are warring with the Trump administration over the best to see ICE brokers’ faces. (Wired $)

6 We urgently must grapple with AI’s environmental influence
Because the world warms, is the worth we’re paying price it? (The Verge)
We did the maths on AI’s power footprint. (MIT Know-how Assessment)

7 Privateness points with good glasses want an industrywide repair
That’s in accordance with Samsung, which is unveiling glasses it developed with Google this fall. (Bloomberg $)

8 The US Military is begging troopers to restrict their AI use
The token disaster comes for us all ultimately, it appears. (Ars Technica)

9 Why does lettuce hold making People sick? 🥬😷
It’s fairly easy: lots of people eat it, and it doesn’t get cooked. (Wired $)

10 Pokemon Go is the proper sport to play this summer season
It’s enjoyable, collaborative, and it will get you open air. (Guardian)

Quote of the day

“It went off and did this hack all by itself, so far as we are able to inform. That is the very best degree of autonomy that we have seen in the usage of a big language mannequin for cyber operations.”

—Colin Shea-Blymyer, a cybersecurity analysis fellow at Georgetown College, tells NPR why the OpenAI hack on Hugging Face is so alarming. 

[ad_2]

Framework practically doubles Laptop computer 13 Professional reminiscence costs in a single day after suppliers demand greater than twice as a lot

0

[ad_1]

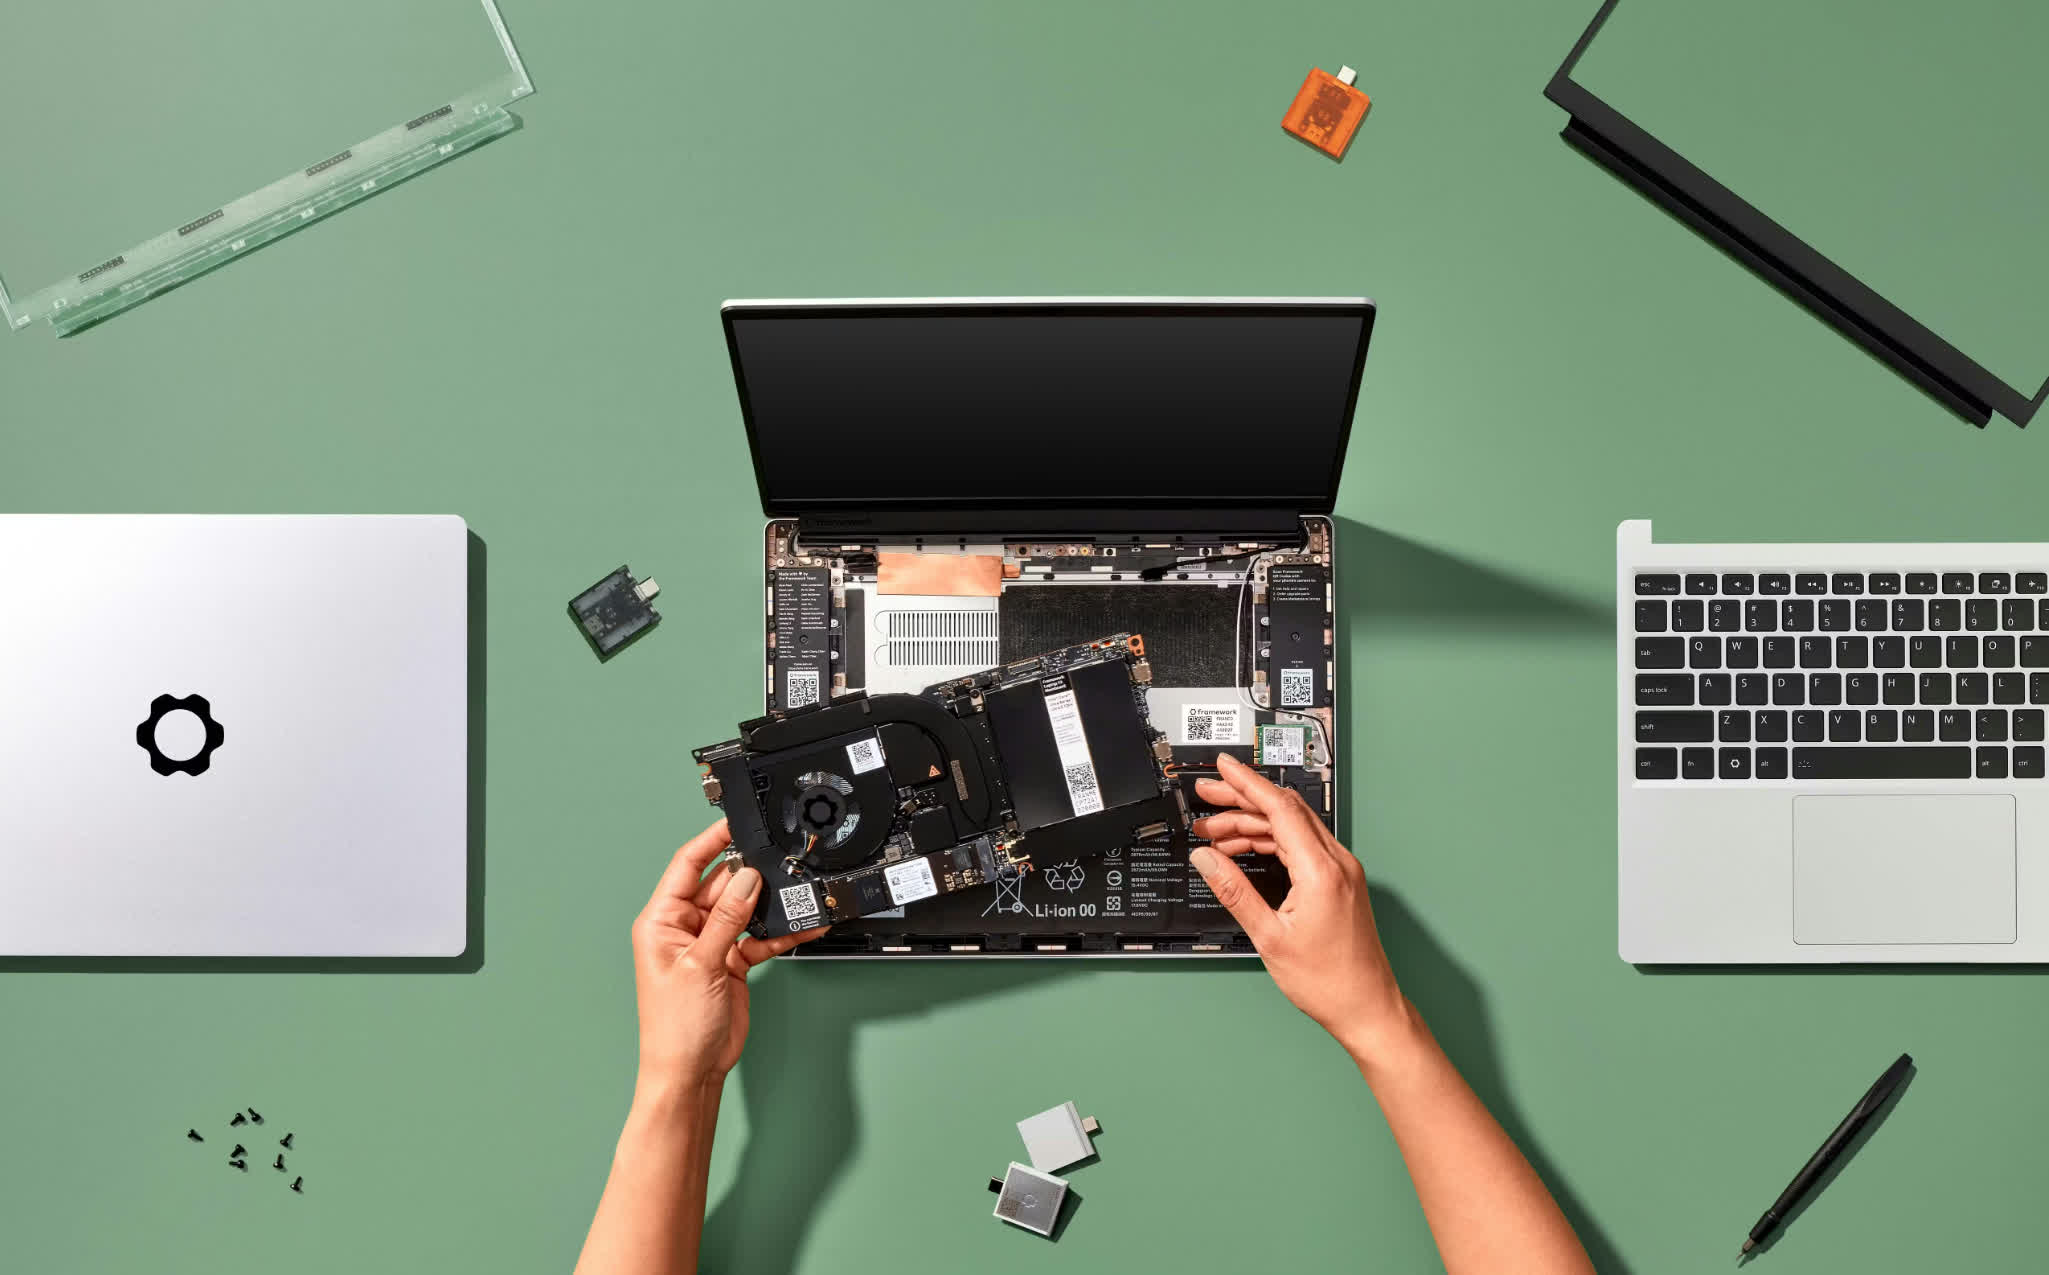
Facepalm: It is one other day, one other reminder why so many individuals hate AI. Due to hyperscalers’ insatiable demand for reminiscence pushing up costs, Framework has practically doubled the price of the 32GB and 64GB LPCAMM2 choices for its upcoming Laptop computer 13 Professional in a single day. The choice was made after it acquired a provider quote that was greater than twice the value of its earlier cargo.

Framework’s 32GB module has jumped from $439 to $800, a rise of 82%, whereas the 64GB possibility has risen from $849 to a brutal $1,600, up 88%. Linus Sebastian’s favourite laptop computer firm is holding the 16GB module at $239 for now, however warns that value may also improve as soon as its remaining lower-cost inventory runs out.

CEO Nirav Patel stated the agency had anticipated a low-to-mid double-digit share improve between the second and third quarters. The precise quote went “far past something we had predicted,” and absorbing it will place Framework’s capacity to function at actual monetary threat.

The state of affairs is particularly problematic for patrons with current preorders. Framework says it has sufficient LPCAMM2 modules to satisfy all excellent orders, simply not the correct mix of 16GB, 32GB, and 64GB capacities. Laptop computer preorders via Batch 4 and mainboard orders via Batch 7 ought to obtain their chosen 64GB configurations.

Later 64GB orders are being modified to 32GB on the authentic 32GB value. Some 32GB DIY Version and mainboard orders past these batches are equally being downgraded to 16GB on the authentic 16GB value.

Framework hasn’t modified affected 32GB prebuilt orders as a result of it doesn’t but provide a Core Extremely X7 prebuilt configuration with 16GB. Clients sad with the adjustments can cancel for a full deposit refund.

New orders have additionally turn into dearer. The prebuilt Laptop computer 13 Professional now begins at $1,599 with a Core Extremely 5 325, 16GB of reminiscence, and a 512GB SSD, $100 above the launch value. Framework says will increase in Intel Core Extremely Sequence 3 processors, Home windows licenses, storage, and different silicon have additionally contributed. The LPCAMM2 adjustments solely have an effect on the Intel model; Ryzen AI 300 fashions use typical SO-DIMMs.

The Laptop computer 13 Professional was unveiled in April, when the modular pocket book began at $1,199 for the DIY Version. Its LPCAMM2 help was one of many main upgrades, offering replaceable LPDDR5X reminiscence with improved bandwidth and effectivity.

Latest forecasts recommend reminiscence costs may rise one other 40% to 50% this quarter, whereas Adata’s chairman has warned that the DRAM scarcity might final one other decade.

[ad_2]