Should you’ve ever burned hours wrangling PDFs, screenshots, or Phrase information into one thing an agent can use, you understand how brittle OCR and one-off scripts could be. They break on format modifications, lose tables, and gradual launches.
This isn’t simply an occasional nuisance. Analysts estimate that ~80% of enterprise knowledge is unstructured. And as retrieval-augmented era (RAG) pipelines mature, they’re changing into “structure-aware,” as a result of flat OCR collapse underneath the load of real-world paperwork.
Unstructured knowledge is the bottleneck. Most agent workflows stall as a result of paperwork are messy and inconsistent, and parsing shortly turns right into a facet venture that expands scope.
However there’s a greater possibility:Aryn DocParse, now built-in into DataRobot, lets brokers flip messy paperwork into structured fields reliably and at scale, with out customized parsing code.
What used to take days of scripting and troubleshooting can now take minutes: join a supply — even scanned PDFs — and feed structured outputs straight into RAG or instruments. Preserving construction (headings, sections, tables, figures) reduces silent errors that trigger rework, and solutions enhance as a result of brokers retain the hierarchy and desk context wanted for correct retrieval and grounded reasoning.
Why this integration issues
For builders and practitioners, this isn’t nearly comfort. It’s about whether or not your agent workflows make it to manufacturing with out breaking underneath the chaos of real-world doc codecs.
The influence exhibits up in three key methods:
Simple doc prep What used to take days of scripting and cleanup now occurs in a single step. Groups can add a brand new supply — even scanned PDFs — and feed it into RAG pipelines the identical day, with fewer scripts to take care of and quicker time to manufacturing.
Structured, context-rich outputs DocParse preserves hierarchy and semantics, so brokers can inform the distinction between an government abstract and a physique paragraph, or a desk cell and surrounding textual content. The outcome: easier prompts, clearer citations, and extra correct solutions.
Extra dependable pipelines at scale A standardized output schema reduces breakage when doc layouts change. Constructed-in OCR and desk extraction deal with scans with out hand-tuned regex, reducing upkeep overhead and reducing down on incident noise.
What you are able to do with it
Below the hood, the mixing brings collectively 4 capabilities practitioners have been asking for:
Broad format protection From PDFs and Phrase docs to PowerPoint slides and customary picture codecs, DocParse handles the codecs that normally journey up pipelines — so that you don’t want separate parsers for each file sort.
Structure preservation for exact retrieval Doc hierarchy and tables are retained, so solutions reference the best sections and cells as an alternative of collapsing into flat textual content. Retrieval stays grounded, and citations really level to the best spot.
Seamless downstream use Outputs circulate instantly into DataRobot workflows for retrieval, prompting, or operate instruments. No glue code, no brittle handoffs — simply structured inputs prepared for brokers.
One place to construct, function, and govern AI brokers
This integration isn’t nearly cleaner doc parsing. It closes a crucial hole within the agent workflow. Most level instruments or DIY scripts stall on the handoffs, breaking when layouts shift or pipelines increase.
This integration is a part of an even bigger shift: transferring from toy demos to brokers that may motive over actual enterprise information, with governance and reliability in-built to allow them to rise up in manufacturing.
Which means you may construct, function, and govern agentic purposes in a single place, with out juggling separate parsers, glue code, or fragile pipelines. It’s a foundational step in enabling brokers that may motive over actual enterprise information with confidence.
From bottleneck to constructing block
Unstructured knowledge doesn’t must be the step that stalls your agent workflows. With Aryn now built-in into DataRobot, brokers can deal with PDFs, Phrase information, slides, and scans like clear, structured inputs — no brittle parsing required.
Join a supply, parse to structured JSON, and feed it into RAG or instruments the identical day. It’s a easy change that removes one of many greatest blockers to production-ready brokers.
One of the best ways to know the distinction is to strive it by yourself messy PDFs, slides, or scans, and see how a lot smoother your workflows run when construction is preserved finish to finish.
MacBook Professional M5 Professional & Max: In abstract
The M5 MacBook Professional launched in October 2025 however the Professional and Max fashions are but to be up to date.
Apple’s next-gen M5 Professional, and M5 Max processors promise efficiency positive factors.
Extra thrilling updates are rumored for the M6 MacBook Professional.
In October 2025, Apple launched an M5 MacBook Professional, however didn’t replace the year-old M4 Professional or M4 Max machines. There have been indications that whereas Apple was on schedule to ship the M5 MacBook Professional within the October timeframe, the wait might lengthen to spring 2026 for the M5 Professional and M5 Max fashions.
Whereas the M5 processor within the MacBook Professional boasts a brand new GPU structure with a Neural Accelerator in every core that Apple says means it may well present “over 4x the height GPU compute efficiency in comparison with M4, a forty five % enchancment in graphics efficiency in comparison with the M4, the brand new chip can be no match for the M4 Professional or and M4 Max within the extra highly effective MacBook Professional fashions nonetheless on sale.
So what modifications may very well be coming to the extra professional MacBook Professional fashions and is it going to be definitely worth the wait, or would energy customers be clever to attend a bit longer for the a lot greater modifications rumored to be simply across the nook for the M6 technology of the MacBook Professional, with the M6 mannequin probably providing a contact display screen and extra.
This text will maintain monitor of the rumors and supply a perspective based mostly on Apple’s Mac lineup. Right here’s all the things we all know to this point.
New M5 Professional/Max MacBook Professional: Design
No change to the design anticipated.
Large modifications are stated to be coming to the M6 MacBook Professional.
Apple up to date the design of the MacBook Professional in 2021. There was no change to the design of the MacBook PRo when Apple launched the M5 mannequin. So it looks like Apple will follow the present design for the M5 Professional and Max fashions.
It’s all the time doable {that a} new shade makes an look—like Area Black in 2023—however for probably the most half, the MacBook Professional design is ready for not less than one other yr.
In July 2025, Bloomberg’s Mark Gurman reported that the M5 MacBook Professional sequence is to be the final of this present design although. Apple seems to be saving the subsequent main design improve for the MacBook Professional for 2026. The M6 improve is claimed to incorporate OLED screens, a digital camera “gap” to substitute the notch, and a thinner design.
New M5 Professional/Max MacBook Professional: Show
No change to show anticipated.
There isn’t a change to the show on the M5 MacBook Professional, so it’s unlikely that the M5 Max and M5 Professional fashions will get any display screen updates. Though we might see the next nits brightness score, up from the present 1,600 nits peak.
On February 11, 2025, The Elec reported that OLED shows for the MacBook Professional are going into manufacturing, however they gained’t be featured within the laptop computer till 2026.
Nevertheless, on July 28, 2025, Dealsite reported that Apple has a deal in place with Samsung Show for OLED shows for the MacBook Professional that may ship in late 2025. Which may not imply that the shows are any higher, in fact.
There may very well be one thing much more thrilling coming with the M6 technology: a touchscreen! Analyst Ming-Chi Kuo believes that Apple goes to launch a MacBook with a contact display screen, and it might arrive on a MacBook Professional as quickly as 2026. Nevertheless, this replace is just not anticipated to reach till the M6 technology and may very well be delayed till 2027.
Apple may very well be saving any drastic modifications to the MacBook Professional for 2026.
Foundry
New M5 Professional/Max MacBook Professional: Digicam
The M4 MacBook Professional added a 12MP FaceTime digital camera, an honest improve from the 1080p FaceTime digital camera. The M5 Macook Professional maintains this digital camera, so it’s unlikely the Professional and Max fashions will acquire something.
Nevertheless, we might see an analogous FaceTime digital camera replace to 18MP as seen on the iPhone 17. The sq. sensor is much less related right here because the MacBook Professional will solely ever be in a single orientation, though it might permit for extra of the world round an individual to be seen.
New M5 Professional/Max MacBook Professional: Processor
The M5 MacBook Professional that launched in October 2025 is little greater than a chip refresh and it’s possible that the M5 Professional and Max can be an analogous story. Stories had indicated to count on the standard efficiency increase from one chip technology to a different–between 15 and 25 % over the M4 chips.
On Might 8, 2025, Bloomberg’s Mark Gurman reported that Apple is engaged on M6 and M7 chips, however they gained’t be within the MacBook Professional till later. Apple can be engaged on a “extra superior Mac chip” referred to as Sotra, however no particulars have been offered.
On July 3, AppleInsider reported that Apple plans the discharge 4 customary configurations with the next code names:
J714c: M5 Max 14-inch MacBook Professional
J714s: M5 Professional 14-inch MacBook Professional
J716c: M5 Max 16-inch MacBook Professional
J716s: M5 Professional 16-inch MacBook Professional
On October 7, 2025, MaxTech’s Vadim Yuryev reported that Apple is engaged on a brand new chip design for the M5 Professional and M5 Max that may function the CPU and GPU on separate blocks. This may permit clients better choices to configure these elements. For instance, one might arrange a base CPU configuration with a maxed out GPU. Yuryev acknowledged that this new design is why the M5 Professional and M5 Max are delayed till 2026.
New M5 Professional/Max MacBook Professional: Specs
N1 chip: Wi-Fi 7 and Bluetooth 6.
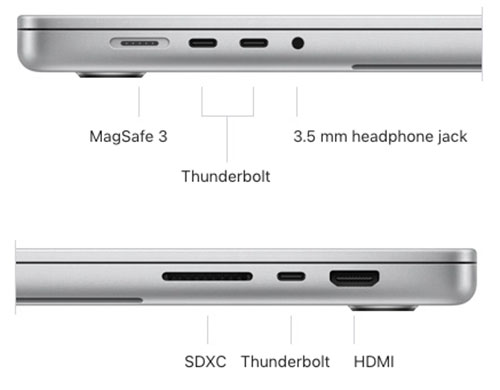
Thunderbolt 5.
With the launch of the M4 MacBook Professional, Apple made a sequence of upgrades that changed outdated elements, together with upping the bottom RAM to 16GB, bringing Thunderbolt 5 to the M4 Professional and Max fashions, and providing a Nano-texture glass choice. The M5 MacBook Professional noticed no modifications to the specs apart from the processor. The Bluetooth and WiFi remained the identical. A brand new 4TB SSD choice was added, however within the U.Ok. and Europe Apple has eliminated the Energy Adapter from the field.
Nevertheless, Wi-Fi 7 is predicted to reach on the MacBook Professional M5 Professional and Max. Apple can also combine the N1 chip, as used within the iPhone 17, which can carry Wi-Fi 7 and Bluetooth 6, in addition to enhance options like Private Hotspot and AirDrop.
Apple
The entry-level mannequin nonetheless solely gives Thunderbolt 4, however the Max and Professional will proceed to supply Thunderbolt 5.
There are experiences that Apple is engaged on a 5G modem for the Mac, however it’s unlikely to reach earlier than 2026.
New M5 Professional/Max MacBook Professional: Launch date
Doable launch spring 2026.
Bloomberg’s Mark Gurman reported in March 2025 that Apple is on schedule to ship the M5 MacBook Professional “across the similar time of yr” as when the M4 and M3 MacBook Professional shipped. That implies an October/November timeframe. Gurman then reported on Might 8 that the M5 MacBook Professional might arrive “as early as the top of this yr.”
Gurman was initially assured that Apple would launch the M5 MacBook Professional by the top of 2025, and certainly it did, however his confidence was actually faltering because the launch neared, with a tweet previous to the launch declaring that M4 MacBook Professional was constrained, however not the M4 Max or M4 Professional fashions.
On the bottom stage 14-inch MacBook Professionals, customized configurations on the road retailer are constrained until the top of October. Not the case for the Professional/Max and 16-inch fashions.
Then, Vadim Yuryev, host of the Max Tech YouTube channel, predicted on October 6: “3 days of M5 chip product launches subsequent week beginning on Monday or Tuesday. M5 MacBook Professional 14-inch mannequin ONLY, M5 iPad Professional, M5 Imaginative and prescient Professional.”
So for now a spring launch for the remainder of the MacBook Professional line up appears almost certainly.
New M5 MacBook Professional: Value
Costs are unlikely to alter.
Listed below are the costs for the present customary configurations of the M4 Professional and Max MacBook Professional, for reference. Costs are unlikely to alter.
14-inch MacBook Professional
$1,999/£1,999: M4 Professional with a 12-core CPU, 16-core GPU, 24GB unified reminiscence, 512GB SSD, Thunderbolt 5
$2,399/£2,399: M4 Professional with a 14-core CPU, 20-core GPU, 24GB unified reminiscence, 512TB SSD, Thunderbolt 5
$3,199/£3,199: M4 Max with a 14-core CPU, 32-core GPU, 36GB unified reminiscence, 1TB SSD, Thunderbolt 5
16-inch MacBook Professional
$2,499/£2,499: M4 Professional with a 14-core CPU, 20-core GPU, 24GB unified reminiscence, 512GB SSD, Thunderbolt 5
$2,899/£2,899: M4 Professional with a 14-core CPU, 20-core GPU, 48GB unified reminiscence, 512TB SSD, Thunderbolt 5
$3,499/£3,499: M4 Max with a 14-core CPU, 32-core GPU, 36GB unified reminiscence, 1TB SSD, Thunderbolt 5
$3,999/£3,999: M4 Max with a 16-core CPU, 40-core GPU, 48GB unified reminiscence, 1TB SSD, Thunderbolt 5
The M5 MacBook Professional costs haven’t modified, however within the U.Ok. and Europe the Energy Adapter will price additional:
$1,599/£1,599: M5 with a 10-core CPU, 10-core GPU, 16GB unified reminiscence, 512GB SSD, Thunderbolt 4
$1,799/£1,799: M5 with a 10-core CPU, 10-core GPU, 16GB unified reminiscence, 1TB SSD, Thunderbolt 4
$1,999/£1,999: M5 with a 10-core CPU, 10-core GPU, 24GB unified reminiscence, 1GB SSD, Thunderbolt 4
The quantity of REM sleep you get might affect which particulars of your reminiscences stay in storage, a brand new mind examine suggests.
Earlier analysis had discovered that sleep helps fortify our reminiscences, however the query of the way it shapes the contents of those reminiscences has been more durable to pin down. Now, a examine revealed Oct. 1 within the journal Communications Biology hints that the time spent in several phases of sleep might affect this side of reminiscence storage.
The sleep cycle is break up into 4 phases: one stage of speedy eye motion (REM) and three non-REM phases, together with “deep sleep,” marked by sluggish mind waves. To check how these sleep phases affect our reminiscences, the researchers requested 32 wholesome younger adults to be taught 96 word-picture pairs — akin to an motion phrase linked to a picture of an animal or plant — whereas their mind exercise was recorded with an electroencephalogram (EEG), which screens mind waves that wash over the floor of the mind.
The volunteers have been then monitored with EEG as they slept in a single day and had their recall examined the subsequent morning. The researchers in contrast the before-and-after mind patterns utilizing a method referred to as representational similarity evaluation. These information enabled the scientists to focus each on detailed reminiscences tied to particular photographs — like a photograph of a beagle — and on broader, categorical reminiscences, masking all of the animal photographs, as an example.
“By utilizing EEG, we may monitor how mind exercise linked to reminiscences modified from earlier than to after sleep,” first examine writer Jing Liu, a analysis assistant professor at The Hong Kong Polytechnic College, advised Dwell Science in an e mail.
The workforce uncovered a sample: Brainwaves linked to the person photographs weakened after sleep, whereas the broader class indicators remained secure.
The shift was stronger when REM made up extra of a person’s complete sleep time, in comparison with deep sleep. Liu defined that this sample suggests REM sleep might assist the mind hyperlink new reminiscences with what it already is aware of, whereas slow-wave sleep helps hold these reminiscences of their authentic, more-detailed type.
Get the world’s most fascinating discoveries delivered straight to your inbox.
“Even when folks remembered the identical issues after waking, the mind patterns behind these reminiscences had shifted,” she added. This implies sleep not solely strengthens reminiscences however might reorganize how they’re represented within the mind, with REM and slow-wave sleep contributing in several methods.
Collectively, these outcomes add to proof that reminiscence consolidation — the mind’s strategy of stabilizing and reorganizing new reminiscences — entails each preservation and transformation. Somewhat than storing reminiscences of experiences precisely as they occurred, the mind could also be subtly restructuring them throughout sleep, balancing accuracy with generalization. The excellence, the researchers famous, may assist clarify how data networks within the mind evolve over time.
Nonetheless, the sample would not essentially imply that deep sleep and REM sleep work in opposition to 1 one other. Somewhat, the 2 phases help totally different sides of remembering, Dr. George Dragoi, professor of psychiatry and neuroscience at Yale College who was not concerned within the examine, advised Dwell Science in an e mail.
“The outcomes right here level to a complementary position of REM and slow-wave sleep in several types of reminiscence,” he stated, akin to normal data and details versus reminiscences of particular experiences.
He added that maintaining common sleep schedules might assist help these processes, since good sleep high quality is broadly linked to wholesome cognitive perform. “Longer REM durations might promote the sort of reminiscence transformation this examine highlights,” he prompt.
Liu, nevertheless, cautioned that the outcomes present associations, not causation.
“[EEG] prevents us from exactly figuring out the mind areas driving these adjustments,” she stated, including that combining EEG with recordings taken straight from electrodes positioned contained in the cranium may make clear the circuitry behind the impact. She additionally pointed to future research that may attempt to reactivate particular reminiscences throughout sleep — as an example, by replaying sounds or cues linked to earlier studying — or interrupt explicit sleep phases to see whether or not that adjustments how flexibly folks can use what they’ve discovered.
A photographer’s snapshot of Treasury Secretary Scott Bessent
on the United Nations Basic Meeting final week revealed a personal
message that captured the Trump administration’s deepening concern over
collapsing U.S. soybean exports to China—a disaster now entangled with a controversial financial bailout of Argentina.
“Lastly
– only a heads up, I’m getting extra intel, however that is extremely
unlucky,” learn the message, which seemed to be despatched from Agriculture
Secretary Brooke Rollins. “We bailed out Argentina yesterday (Bessent)
and in return, the Argentine’s [sic] are eradicating their export tariffs
on grains, lowering their worth, and bought a bunch of soybeans to China,
at a time once we would usually be promoting to China. Soy costs are
dropping additional due to it. This provides China extra leverage on us.”
…
The missive has additionally drawn new scrutiny to the Trump administration’s pledge to assist Argentina with a attainable $20 billion swap line
and direct U.S. purchases of presidency debt. Days after the deal,
Chinese language importers purchased greater than one million metric tons of Argentine
soybeans simply because the American harvest season started.
…
China, as soon as the most important purchaser of American soybeans, has not bought a
single cargo since Might, based on U.S. Division of Agriculture
knowledge. In 2024, China purchased $12.5 billion of the $24.5 billion value of
soybeans the U.S. exported globally—greater than 50 p.c. For months
now, the determine has been zero.
As an Arkansas good ol’ boy and a few instances press critic, I am often irritated by how little consideration the press usually provides agriculture tales, however this one seems to have legs.
Soybean farmer: Our complete value construction has elevated, however our income has decreased. It is fairly difficult. It is a massacre
As ag scientist Sarah Taber factors out, as soon as you narrow off a market,
demand for a crop doesn’t merely bounce again when the provision reopens.
Typically it by no means absolutely returns.
Completely true.
The crop that has been mainstay of (particularly) South Dakota financial system now zeroed out, in exports to their largest buyer.
These farmers know (have informed us) that they’ll by no means get these markets again. The PRC has switched to Brazil and Argentina.
Angus:
American farmers who purchased into Trump, considering tariffs would assist
them—their markets are gone. Canada’s not making noise about it; we’re
simply transferring in. Canadian corn is now being bought in Eire, Spain, and
the UK. These was once assured American markets. Not anymore.
The textbook instance is cotton.
Within the first half of the nineteenth century, America dominated the high-grade
cotton commerce whereas Egypt was a minor participant. However when the Civil Struggle
disrupted U.S. provide, British textile mills grew determined for uncooked
materials, and Egypt rushed in to fill the vacuum. By the point the conflict
ended, Egypt had turn out to be the dominant provider, with the added benefit
of being geographically nearer to Britain. It additionally constructed a fame
for high quality that persists to today.
Because of Brigham Frandsen for this weeks workshop on machine studying, AI and causal inference. Mixtape periods is indebted to him. He has taught that workshop for us 5 occasions since October 2022, not counting the thrice he’s taught his workshop on machine studying and heterogeneous therapy results (which he’ll train once more November tenth). So thanks Brigham!
The following two workshops are additionally value a lot of your time. The primary one is by Jeff Gortmaker on demand estimation and the BLP mannequin. Ariel Pakes made an look final time and I must study if that’s nonetheless the case this time. However should you’re in industrial group, or trade, or authorities, I extremely suggest you try Jeff’s workshop. Final time, it was an enormous hit — as in, it’s up to now the most well-liked workshop we’ve run on mixtape periods. And given the recognition of BLP not simply in IO, however trade extra typically, I feel at these costs, it’s value your time. This workshop will begin October twentieth and run for 3 evenings, subsequent week. Attain out should you suppose qualify for a reduction!
And the opposite one is my causal inference 2 workshop beginning Saturday, November 1st on difference-in-differences. That is the workshop that I feel will carry you to a degree of the frontier of diff-in-diff — not the bleeding edge, which continues evolving at a clip, however you’ll get this least:
the basics of diff in diff and rooted in pragmatic and utilized design rules
targeted consideration on the occasion examine and correct (and improper) specs
The function of covariates within the parallel developments assumption and correct specs strong to unrestricted heterogeneous therapy results
Extra complicated designs like estimation with repeated cross sections and differential timing
A reasonably in depth give attention to the Callaway and Sant’Anna estimator, the function of weights in aggregation, an in depth consideration to interpretation, and inference
Coding coding coding!
So come one, come all! Once more, attain out should you suppose you qualify. In case your potential to pay is beneath value, please attain out and if we will work one thing out, we are going to. Our aim is at mixtape periods to assist folks study these necessary instruments.
Replace on Boston and Harvard
Each of those entities proceed to win my coronary heart over. The scholars are sweethearts. Final night time after our assessment session for tomorrow’s examination, a pupil spent 10 minutes with me explaining the correct use of the brand new slang “low key”. Low key’s low key most likely my absolute favourite new slang, partly as a result of it’s practically inconceivable to make use of it incorrectly.
I like the scholars loads. I’ve held to daye met with 55 college students in workplace hours since I acquired right here. Every time is a brand new expertise, and I like asking them what it was like opening their acceptance letter. With out exception, they all the time share the enjoyment and gratitude and amazement they felt after they opened their acceptance letter. As a dad with children in school, I really feel so happy with all of them.
Gov 50 continues to be an thrilling journey and problem for me. I’ve managed to delay introducing regression. I targeted to this point on “easy comparisons” as the easy distinction in imply outcomes. And for unconfoundedness, I opened up as I all the time do with graphs after which backdoor criterion, however for the primary time, college students gave precisely two shits about it. And I feel I do know why.
Roughly 100-120 of my 190 college students are sophomores and freshmen. Round 120 have but to declare their main (“focus” right here is the nomenclature, not main, although). And this class is each required for the federal government focus however it’s also a basic schooling requirement. I usually meet college students removed from STEM, like historical past, artwork and philosophy.
And the rationale I feel that issues is that that is typically their first empirical challenge. It’s their first time to code and even lay palms on actual information. So ask your self — if that have been you, would you see the worth of selecting covariates? Of avoiding others? When unconfoundedness is their first non-experimental methodology?
I feel most likely the returns to graphs is far greater when the researcher has had extra expertise — that or the professor is more proficient at introducing it. Anyway, level is, it burnt every week, and I want I hadn’t completed it, however hindsight is 20/20.
So, to my level. I’ve managed to delay introducing OLS. The reason being as a result of I feel I can train OLS on the tail finish simpler than at the beginning as a result of the examination actually emphasised a number of issues:
Calculating the easy distinction in imply outcomes.
Actual matching (widespread help)
Nearest neighbor matching (widespread help considerably violated)
I feel I can initially with #1 present them the regression specification that estimates the easy distinction in imply end result with out covariates utilizing Rebecca Thorntons Malawi paper. I’ll most likely comply with it up with instructing them her new AER: Insights paper too, which illustrates I feel the worth of a really glorious designed experiment on the service of a really necessary scientific and social coverage questions. Which, as I’ve emphasised all semester to those children, is the hallmark of Rebecca’s complete profession.
So, I’ll give attention to the regression specification first with a binary therapy, after which lead into the properties of OLS. Which I’ll then transfer into multivariate regressions as a substitute for matching (versus the opposite method round) when widespread help breaks down. I simply felt that I wanted to imprint “easy comparisons” of their minds since OLS comparisons are hardly easy (eg bizarre variance weights, counter intuitive interpretation below heterogenous therapy results). So I’ll be telling them that commonplace OLS fashions with covariates would require they assume fixed therapy results as a result of I refuse to point out them regression adjustment. I’ve to save lots of one thing for Gov 51.
My PhD course for subsequent semester is coming collectively. I’ve determined it’ll be chance and statistics utilizing Bruce Hansen’s new guide, and utilized regression utilizing his different econometrics guide. I’ll even be assigning articles in order that I can sprinkle in some causal inference.
I’ll most likely cowl some fundamental stuff from Angrist, Tymon, possibly Bacon, simply to emphasise a number of issues like unconfoundedness, fixed versus heterogenous therapy results, and FWL, in addition to variance weighting in regression fashions. I feel I may cowl sensitivity evaluation by Taber, et al, Emily Oster, Carlos Cinelli.
In order that’s the newest.
Stunning Boston
On the Boston entrance, I proceed to have a stunning time. I’ve determined Boston is my favourite metropolis on this planet — anyplace. It’s such a stunning place with actually pretty folks. I actually don’t perceive it when somebody says they detest town. I feel it’s most likely due to the climate, however I’m trying ahead to the climate. I hope it’s a as soon as in a century blizzard, and I’m cuddled up below a blanket ingesting sizzling cocoa and watching NFL video games.
Talking of, I’m going to see the Eagles play the Bears in Philly over thanksgiving. I’m an enormous Eagles fan due to my love of the film Silver Linings Playbook. And I due to this fact additionally love Philly. In order that’s a visit I’m enthusiastic about. And I’m going to see the Pats play the Payments on December 14th with my buddy. Given they beat the Payments and pulled out one other win, this could possibly be turning out to be a really thrilling sport. Me and my buddy from school, who lives right here, are going. I hope I see one other struggle.
Listed below are some pics. A good friend took me to a spot on the north aspect that bought sweets. They love sweets however I like carbs. I simply assumed there was symmetry between carb lovers and candy lovers such that one to at least one we every had our personal factor. However you already know what? I used to be completely mistaken. This candy place had probably the most thoughts blowing sweets. I then realized. All I can do if I need to give a good friend a style of nice carb snacks is open a bag of kettle chips for them. I’ve really by no means seen a retailer, I noticed, devoted simply to carbs however a spot that focuses on sweets — properly these exist right here. I acquired every kind of stuff, however then I additionally couldn’t cease myself from getting some actual trash. Right here’s a fortunate charms deal with. It was implausible.
The above was a mesmerizing fountain I noticed that night time when out strolling round city with a good friend. It was choreographed and the lighting continuously modified. I simply couldn’t consider how enchanting it was. Right here’s additionally a video of these dancing, watery lights.
The climate is beginning to change already. I wore my coat the opposite day, as a result of I wakened and it was within the 30s, however the temperature rose and it was then uncomfortable. Nevertheless it’s shut, and I can’t wait.
I proceed to like my house in again bay. I like again bay. I like this metropolis. I like all the things about it. I’m grateful to the federal government dept, Harvard and town for letting me crash right here for a yr.
Right here you’ll get record of some greatest github alternate options that present non-public and public repository.
Being into software program growth we fairly often discover ourselves in the necessity to host our code to any web site. For the aim, plenty are blindly following one single medium for this, Github. It can’t be denied that Github customers have their alternative to make use of both Git or Subversion for model management. Additionally there’s a facility of limitless public code repository for all customers of Github. Another fascinating characteristic of Github is that permits to create ‘organizations’, which at its personal is a traditional account however no less than one person account is required to be listed because the proprietor of the group.
Aside from offering desktop apps for Home windows and OSX, Github additionally gives the ability to its customers and organizations to host one web site and limitless challenge pages without spending a dime on the Github’s web site. The standard area for the hosted web sites look one thing like username.github.io and tackle of the challenge pages might seem like username.github.io/project-page.
Shifting forward, we’ve got compiled a listing of few different mediums that will also be utilized in place Github with none hurt. So come let’s take a look on the record.
On opposite to the Github, the Bitbucket comes simply subsequent to it by way of utilization and international reputation. Bitbucket additionally gives a free account for the customers and organizations as nicely with restrict for 5 customers. Additionally, it gives entry to limitless non-public and public repos. One of many options which is notice worthy is its allowance for the customers to puch their information utilizing any of the Git consumer/Git command line.
Atlassian is the developer of Bitbucket offering entry to the model functionality to the customers utilizing their internet interface. A free Mac and Home windows interface can also be obtainable for utilizing Gitbucket’s personal Git and Mercurial consumer Supply Tree.
The area to your hosted web site on Bitbucket will look one thing like: accountname.bitbucket.org and area for that of challenge pages might be like: accountname.bitbucket.org/challenge. Alternatively Bitbucket additionally permits its customers to make use of their very own area title for his or her web site.
Beanstalk as one other good Github various however it isn’t free. You may get a trial of the useful resource for 2 weeks after which if you happen to want to proceed you should have a pay an quantity of minimal $15 for its least expensive Bronze package deal. Bronze package deal lets you will have most of 10 repositories with 3 Gigabytes of storage capability and most upto 5 customers.
Beanstalk helps essentially the most demanded Git and Subversion management methods for model management. It’s developed by Wildbit and likewise permits for code modifying within the browser itself in order that person want to not change to command line every so often.
GitLab is in style among the many customers because of its options like devoted challenge web site and an built-in challenge wiki. Additionally GitLab facilitates its customers by offering automated testing and code supply so {that a} person can do extra work in lesser time with out ready for the exams to cross manually. A few of the else options to be famous are pull requests, code viewer and merge battle decision.
Developed by Fog Creek, not like Github Kiln is just not a free supply to host your software program or web site. You may have an summary or expertise of their model management and code internet hosting for Git and Mercurial for 30 days trial interval, after that customers must improve to the premium model (minimal $18 a month) inorder to proceed working with Kiln. Kiln additionally fees its customers for the code overview module individually.
Should you host your web site with Kiln, your area will look one thing like this:
It’s believed by observing abundance of tasks being hosted on the SourceForge that it has existed for an extended time. When in comparison with the Github, SourceForge (developed by Slashdot Media) has a completely totally different construction of the challenge. In contrast to different web sites for model management, SourceForge permits you to host each static and dynamic pages as nicely. One of many vulnerability of this medium for model management is {that a} person is allowed to create tasks and get it hosted on the location with distinctive names solely.
Typical area to your hosted challenge will seem like proj.sourceforge.internet
Scripting languages like Python, Perl, PHP, Tcl, Ruby and Shell are being supported by the SourceForge servers. Customers are free to selecting both Git, Subversion or Mercurial for the model management system.
This Google’s Git model management got here into existence and moved to the Google Cloud platform when Google code was put out of the market by google itself. Though google gives its personal repositories to work upon, however you may even join the Cloud Supply to different model management mediums like Github, Bitbucket, and so forth. Cloud Supply gives storage for its customers codes and apps throughout the google infrastructure itself which makes it much more dependable. Customers have the freeship to go looking their code within the browser itself and likewise will get characteristic of cloud diagnostics to trace the issues whereas code retains working within the background.
Cloud Supply gives Stackdriver Debugger that helps use the debugger in parallel with the opposite purposes working.
GitKraken turned in style among the many builders day-to-day as a result of unique options it gives to it customers are simply cute. The first level of attraction in the direction of Gitkraken is its stunning interface and likewise it give attention to pace and ease of use for Git. GitKraken comes with an extremely helpful ‘undo’ button which helps its customers to shortly omit the redundancies occurred by mistake. GitKraken gives a free model which might have upto 20 customers and a premium model as nicely with a number of different good options.
We hope you guys loved studying with us. If any doubts, queries or solutions please lets us know within the remark part under. Do share in feedback if you recognize some other good github alternate options.
multiplication is undoubtedly the commonest operation carried out by GPUs. It’s the elementary constructing block of linear algebra and reveals up throughout a large spectrum of various fields resembling graphics, physics simulations and scientific computing whereas being ubiquitous in machine studying.
In immediately’s article, we’ll break down the conceptual implementation of normal matrix-matrix multiplication (GEMM) whereas introducing a number of optimisation ideas resembling tiling and reminiscence coalescing. Lastly, we’ll implement GEMM in Triton!
This text is the second of a collection on Triton and GPU kernels, In case you are not accustomed to Triton or want a refresher on GPU fundamentals, take a look at the earlier article!All of the code showcased on this article is out there on GitHub.
Disclaimer: all the next figures and animations have been made by the creator until said in any other case.
Naive GEMM
Let’s begin easy: we need to multiply two matrices X and Y with shapes (M,N) and (N,Okay) respectively. The output matrix Z=X@Y will subsequently have form (M,Okay).
This operation includes computing the dot merchandise of all pairs of rows and columns in X and Y respectively. A simple NumPy implementation would possibly look one thing like this:
Whereas straightforward to write down, learn and perceive, this implementation is extremely inefficient by way of reminiscence entry and caching. As talked about within the first article of this collection, a elementary side of GPU optimisation is minimising information transfers.
Nonetheless, our present implementation begins by loading a row from X, iteratively masses all Okay columns of Y, computes their dot product and repeats the method for each row in X. This ends in a complete of M(Okay+1) loading operations.
Naive Matrix Multiplication, purple and blue tiles characterize the vectors concerned in dot merchandise at each time step and inexperienced cells the computed output values.
As seen within the animation, the reminiscence entry sample is wasteful, as each column of Y is loaded M occasions. As an analogy: that is like operating to the grocery retailer (international reminiscence) each time you want a brand new ingredient for a dish as a substitute of getting ready all of the substances in your kitchen counter (shared reminiscence). Ideally, we wish to minimise the variety of occasions every chunk of information is loaded and maximise its reusability as soon as loaded. This leaves us with two essential axes of optimisation:
How can we enhance the entry sample to minimise redundant masses?
How a lot information can we load directly, and the place ought to or not it’s saved on the GPU?
Tiled GEMM
As talked about beforehand, the naive strategy to GEMM ends in many redundant masses, which induces pointless overhead. Ideally, we’d prefer to load every section of information solely as soon as and carry out all of the operations during which they’re used earlier than dropping them from reminiscence.
A sublime strategy to this downside is tiling, which includes dividing giant matrices in smaller “tiles” or sub-matrices. Take into account two matrices X and Y with shapes (4,6) and (6,4) respectively, X@Y ends in a matrix Z with form (4,4).
With the intention to compute the primary ingredient of Z, Z[0,0], we have to compute the dot product between the primary row of X and the primary column of Y: Z[0,0] = dot(X[0, :], Y[:, 0]). We are able to additionally break down the dot product into smaller chunks, as an example in teams of three parts: Z[0,0] = dot(X[0,0:3], Y[0:3, 0]) + dot(X[0,3:6], Y[3:6, 0]).
Alternatively, we will increase this strategy to 2 dimensions and compute a whole (2,2) block of Z at a time: Z[0:2, 0:2] = dot(X[0:2, 0:2], Y[0:2, 0:2]) + dot(X[0:2, 2:4], Y[2:4, 0:2]) + dot(X[0:2, 4:6], Y[4:6, 0:2]).
Right here’s a visible illustration of tiled matrix multiplication:
Tiled Matrix Multiplication. The computation is break up in a number of “tiles” of X and Y (highlighted in pale blue and purple), every containing a number of blocks (darkish blue and purple). In every block, we compute dot merchandise (inexperienced cells in X and Y). These dot merchandise are amassed throughout the blocks of a tile to compute the output values in Z (the buildup is represented by colours from orange to inexperienced).
The above animation illustrates how information is reused in tiled GEMM. For every 2×2 block in X and Y, we compute 4 dot merchandise, which leads to a (2,2) output matrix in Z. Since every tile comprises 3 blocks, we have to accumulate 3 of those matrices to compute the ultimate (2,2) output in Z. This accumulation is represented by coloured cells in Z.
Within the kitchen analogy, that is like fetching substances from the shop and getting ready them on the kitchen counter (i.e. small shared reminiscence), reusing them a number of occasions earlier than going again to the shop.
Importantly, reusing loaded information over a number of steps permits this strategy to drastically scale back the variety of load operations. For (2,2) blocks, every X row and Y column is utilized in two dot merchandise. Subsequently, we’re performing twice as many operations with every block of loaded information, roughly halving the variety of load operations! Be aware that this generalises to bigger blocks as nicely, utilizing a (32,32) block would scale back the variety of masses by an element of round 32.
Now you’re most likely questioning “how giant can these blocks be”? To reply this query, let’s recall how reminiscence is managed in trendy GPUs.
GPU Reminiscence Hierarchy
We distinguish 4 essential varieties of reminiscence in Nvidia GPUs. Right here, we take the instance of an A100:
Registers: The quickest and smallest sort of reminiscence on the GPU, residing straight inside every Streaming Multiprocessor (SM). On the A100, every SM supplies 256 KB of register file area (65,536 × 32-bit registers), distributed amongst its threads. Every thread will get its personal non-public 32-bit registers for storing non permanent variables and intermediate outcomes, avoiding reminiscence site visitors altogether. Nonetheless, register utilization per thread straight impacts occupancy, as utilizing too many registers per thread limits what number of threads can run concurrently.
L1/Shared Reminiscence: On an A100, every SM has 192KB of SRAM that may be flexibly configured as both a hardware-managed L1 cache or a programmer-managed shared reminiscence. For performance-critical kernels like matrix multiplication, we explicitly use this area as shared reminiscence to stage information tiles near the compute models, bypassing the L1 cache fully. This offers us fine-grained management over information reuse.
L2 cache: This cache is slower than L1 however a lot bigger, with round 40 MB shared throughout all SMs on the A100. It serves as a world cache for each information and directions, decreasing the variety of accesses to high-latency HBM reminiscence. The L2 cache is coherent throughout SMs, which means that updates from one SM are seen to others, enabling synchronisation between thread blocks. Its bandwidth can attain a number of terabytes per second, performing as a buffer between the quick on-chip SRAM and the slower HBM.
Excessive Bandwidth Reminiscence (HBM): That is the system reminiscence, it has a capability of both 40GB or 80GB relying on the A100 mannequin. It supplies extraordinarily excessive bandwidth (as much as 2 TB/s on the 80 GB variant) however with a lotincreased latency than on-chip caches. HBM is the place giant tensors, mannequin weights, and datasets reside throughout execution. Since accessing HBM is dear, environment friendly kernels purpose to minimise information motion and maximise on-chip information reuse through registers and shared reminiscence.
As you possibly can see, the reminiscence hierarchy typically trades off capability with latency. Subsequently, maximising efficiency boils all the way down to loading information from HBM into shared reminiscence effectively and reusing it as a lot as doable.
GPU Reminiscence Hierarchy, from quickest/smallest (high) to slowest/largest (backside).
Selecting our block dimension is essential. We wish blocks to be giant sufficient to create a whole lot of parallel work, however sufficiently small that their information suits within the SM’s shared reminiscence and registers. A BLOCK_SIZE of 64 is a standard place to begin as a result of it’s a a number of of the warp dimension (32 threads), making certain full {hardware} utilisation.
Parallel Tiled GEMM
With these concerns in thoughts, a pure follow-up to our tiled GEMM is to parallelise the computation of every pairs of tiles over a number of thread blocks, as depicted on the next animation.
Parallel Tiled Matrix Multiplication. The iteration over tiles is changed by a parallel operation over a number of thread blocks.
Reminiscence Coalescing
Earlier than writing tiled GEMM in Triton, we have to think about one final element: reminiscence coalescing, a way that enables optimum use of worldwide reminiscence bandwidth. Reminiscence coalescing is achieved when subsequent threads in a warp entry subsequent reminiscence addresses. Think about a librarian needing to fetch books for a consumer, if all books are side-by-side on a shelf, they will seize them unexpectedly. In distinction, if all books are mendacity on totally different cabinets, they’ll need to seize them one after the other, which takes considerably longer.
To grasp how this is applicable to our case, be aware that matrices are saved linearly in reminiscence, in different phrases a (2,2) matrix is saved as a sequence of 4 consecutive parts. Frameworks like PyTorch undertake a row-major format, which means that parts of a matrix are per-row contiguous in reminiscence. As an illustration, parts of our (2,2) matrix can be saved as follows: [(0,0), (0,1), (1,0), (1,1)], discover that parts of the identical row are contiguous (touching) whereas parts of the identical column have a stride of 1 (separated by one ingredient).
PyTorch shops matrices in row-major format. Components of a row contiguous in reminiscence whereas parts of a column are strided.
This means that we will load rows utilizing coalesced masses, however columns do not fulfill this situation. Nonetheless, we have to entry columns of Y to compute dot merchandise. With the intention to maximise efficiency, a great apply is to transpose Y in order that we iterate on its rows moderately than its columns.
Nonetheless, transposing Y isn’t sufficient to change its format in reminiscence. As talked about beforehand, PyTorch shops matrices in a flat array. Every matrix dimension is related to a stride attribute, denoting the bounce essential to go from one ingredient to the following one alongside this dimension. As an illustration, a (10,10) matrix would have strides=(10,1). Certainly, ranging from ingredient [0,0], ingredient [1,0] is 10 reminiscence slots (i.e. one row) away, whereas ingredient [0,1] is adjoining.
When transposing a tensor, PyTorch doesn’t modify the format in reminiscence however merely recomputes the strides. With the intention to make the transpose efficient from a reminiscence standpoint we have to name Y.T.contiguous().
These are the required steps the load columns of Y effectively, nevertheless we’ll must transpose the loaded blocks throughout the kernel to carry out the dot product correctly: z_block = tl.dot(X_block, Y_block.T).
Illustration of Y, Y.T and Y.T.contiguous() of their block illustration and reminiscence format. The transpose operation modifications the behaviour of the matrix however doesn’t modify its reminiscence format. This is the reason we have to add .contiguous() to allow coalesced reads on rows.
Triton Implementation
From right here on, we first describe the kernel with out reminiscence coalescing to simplify the logic and pointer arithmetic earlier than summarising the modifications required to make the load operations coalesced on Y columns.
Let’s begin by specializing in the PyTorch wrapper across the kernel. We have to learn M, N, Okay from the enter matrices and compute their strides since these constants shall be helpful later within the kernel. Then, we outline the BLOCK_SIZE and declare the grid.
Now let’s dive into the precise kernel code. We’re going to utilize Triton’s make_block_ptr utility, which simplifies the pointer arithmetic. We create one block pointer per matrix and cross the matrix form, its strides, and the dimensions of the block as inputs. Moreover, we specify the offset, the coordinate of the top-left ingredient within the present block. For X, this corresponds to (m_idx * BLOCK_SIZE, 0) the place m_idx is the index of the present block alongside the M dimension.
From there, we outline z_acc, a zero matrix that may obtain the partial dot-products as we iterate by means of tiles. We now iterate by means of the shared dimension N, loading blocks of dimension (BLOCK_SIZE, BLOCK_SIZE), and accumulate their dot merchandise in z_acc. We then transfer the block pointers alongside the shared dimension through the use of .advance.
You might need seen that when loading information, we use boundary_check and padding_option as a substitute of masks and different as within the earlier article. These arguments are particular to using block pointers and specify which axes to examine for out-of-bound operations (right here (0,1) for x and y) and easy methods to deal with these invalid values. Right here we set them to zero to be ignored within the dot product.
We are able to now check out the efficiency of this kernel through the use of the next operate:
def bench(fn: callable, x: torch.Tensor, y: torch.Tensor, repeat: int):
  flops = []
  med_latency = []

  for _ in tqdm(vary(repeat), desc=f"Benchmarking {fn.__name__}"):
    latency_ms = triton.testing.do_bench(
      lambda: fn(x, y),
      quantiles=[0.5], # get the median latency
      return_mode="all",
      )
    n_flops = 2 * M * N * Okay # matmul roughly requires 2*M*N*Okay operations
    tflops = n_flops / (latency_ms / 1e3) / 1e12

    med_latency.append(latency_ms)
    flops.append(tflops)

  flops = np.array(flops)
  med_latency = np.array(med_latency)
  print(f"Absolute Error: {torch.sum(torch.abs(X@Y - fn(x, y)))}")
  print(f"Median Latency: {med_latency.imply():.4f} ± {med_latency.std():.3f} ms")
  print(f"Throughput: {flops.imply():.4f} ± {flops.std():.3f} TeraFLOPS")

M = 8192
N = 6144
Okay = 4096

X = torch.randn((M, N), system="cuda", dtype=torch.float32)
Y = torch.randn((N, Okay), system="cuda", dtype=torch.float32)

bench(block_matmul, X, Y, repeat=10)
We get the next outputs (utilizing a T4 GPU on Colab):
Absolute Error: 0.0 # the kernel outputs the right consequence!
Median Latency: 130.7831 ± 1.794 ms
Throughput: 3.1533 ± 0.043 TeraFLOPS
Now let’s evaluation the modifications required for coalesced masses on Y: we primarily must flip the form, strides and offsets when defining the block pointer for Y. Moreover, we replace the block pointer to maneuver alongside the column dimension (beforehand row dimension). The total code for this implementation is out there on GitHub.
@triton.jit
def coalesced_block_matmul_kernel(
    X_ptr, X_m_stride, X_n_stride,
    Y_ptr, Y_k_stride, Y_n_stride,
    Z_ptr, Z_m_stride, Z_k_stride,
    M, N, Okay,
    BLOCK_SIZE: tl.constexpr,
):
    ...
    y_block_ptr = tl.make_block_ptr(
        base=Y_ptr,
        # flip the form, strides and offsets to match Y.T
        form=(Okay, N),
        strides=(Y_k_stride, Y_n_stride),
        offsets=(k_idx * BLOCK_SIZE, 0),
        block_shape=(BLOCK_SIZE, BLOCK_SIZE),
        order=(0, 1),
    )
    ...

    for _ in vary(0, N, BLOCK_SIZE):
        ... # masses
        z_acc += tl.dot(x, y.T)  # transpose Y again for dot product
        x_block_ptr = tl.advance(x_block_ptr, offsets=(0, BLOCK_SIZE))
        # advance the block pointer alongside columns of Y.T (i.e rows of Y)
        y_block_ptr = tl.advance(y_block_ptr, offsets=(0, BLOCK_SIZE))

    tl.retailer(pointer=z_block_ptr, worth=z_acc, boundary_check=(0, 1))

def coalesced_block_matmul(X, Y):
    Y = Y.T.contiguous()  # Y is now (Okay,N)
    M, N = X.form
    Okay, _ = Y.form
    Z = torch.empty((M, Okay), system="cuda")

    x_stride_m, x_stride_n = X.stride()
    y_stride_k, y_stride_n = Y.stride()
    z_stride_m, z_stride_k = Z.stride()

    ...  # outline BLOCK_SIZE and grid

    coalesced_block_matmul_kernel[grid](
        X, x_stride_m, x_stride_n,
        Y, y_stride_n, y_stride_k,
        Z, z_stride_m, z_stride_k,
        M, N, Okay,
        BLOCK_SIZE,
    )

    return Z
Listed here are the outcomes of our benchmark for the kernel with coalesced masses for Y:
Absolute Error: 0.0 # Once more, the kernel is appropriate!
Median Latency: 261.9420 ± 0.858 ms
Throughput: 1.5741 ± 0.005 TeraFLOPS
Surprisingly, the throughput of this second kernel is simply half of what we obtained with the primary one, regardless of bettering the effectivity of load operations 🤔
A fast inspection utilizing nsight (Nvidia’s kernel profiler, extra on that in a future article) reveals that the transpose operation throughout the kernel creates a “site visitors jam”. Particularly, the transpose creates financial institution conflicts, inflicting threads to stay idle more often than not. Notably, the warp scheduler has no eligible warp to dispatch 87.6% of the time as they’re ready for the financial institution battle to resolve. Moreover, the report reads:
———————– ———– ————– Metric Title Metric Unit Metric Worth ———————– ———– ————– … DRAM Throughput % 8.20 Compute (SM) Throughput % 21.14 …
This means that the kernel is latency certain (i.e. neither reminiscence nor compute certain, discuss with the earlier article for extra particulars). In distinction, the primary kernel is compute certain (i.e. rising compute will enhance efficiency) for the reason that compute throughput is excessive in comparison with the DRAM throughput.
———————– ———– ————– Metric Title Metric Unit Metric Worth ———————– ———– ————– … DRAM Throughput % 29.35 Compute (SM) Throughput % 74.39 …
Conclusion
This experiment highlights the significance of profiling and empirical validation. Even well-intentioned optimisations like coalescing reminiscence accesses can introduce new bottlenecks if not evaluated fastidiously. The primary kernel, although less complicated, was compute-bound and higher matched the {hardware} traits.
Within the subsequent articles of this collection, we’ll implement a softmax kernel, paying specific consideration to integrating Triton with PyTorch’s autograd and profiling kernels utilizing Nsight.
Foundry Native is an on-device AI inference resolution providing efficiency, privateness, customization, and value benefits. It integrates seamlessly into your current workflows and functions by way of an intuitive CLI, SDK, and REST API. Foundry Native has the next advantages:
On-Gadget Inference: Run fashions domestically by yourself {hardware}, lowering your prices whereas preserving all of your knowledge in your machine.
Mannequin Customization: Choose from preset fashions or use your individual to fulfill particular necessities and use instances.
Price Effectivity: Remove recurring cloud service prices by utilizing your current {hardware}, making AI extra accessible.
Seamless Integration: Join along with your functions by way of an SDK, API endpoints, or the CLI, with simple scaling to Azure AI Foundry as your wants develop.
Foundry Native is right for situations the place:
You wish to maintain delicate knowledge in your machine.
It is advisable function in environments with restricted or no web connectivity.
You wish to scale back cloud inference prices.
You want low-latency AI responses for real-time functions.
You wish to experiment with AI fashions earlier than deploying to a cloud surroundings.
You’ll be able to set up Foundry Native by operating the next command:
winget set up Microsoft.FoundryLocal
As soon as Foundry Native is put in, you obtain and work together with a mannequin from the command line by utilizing a command like:
foundry mannequin run phi-4
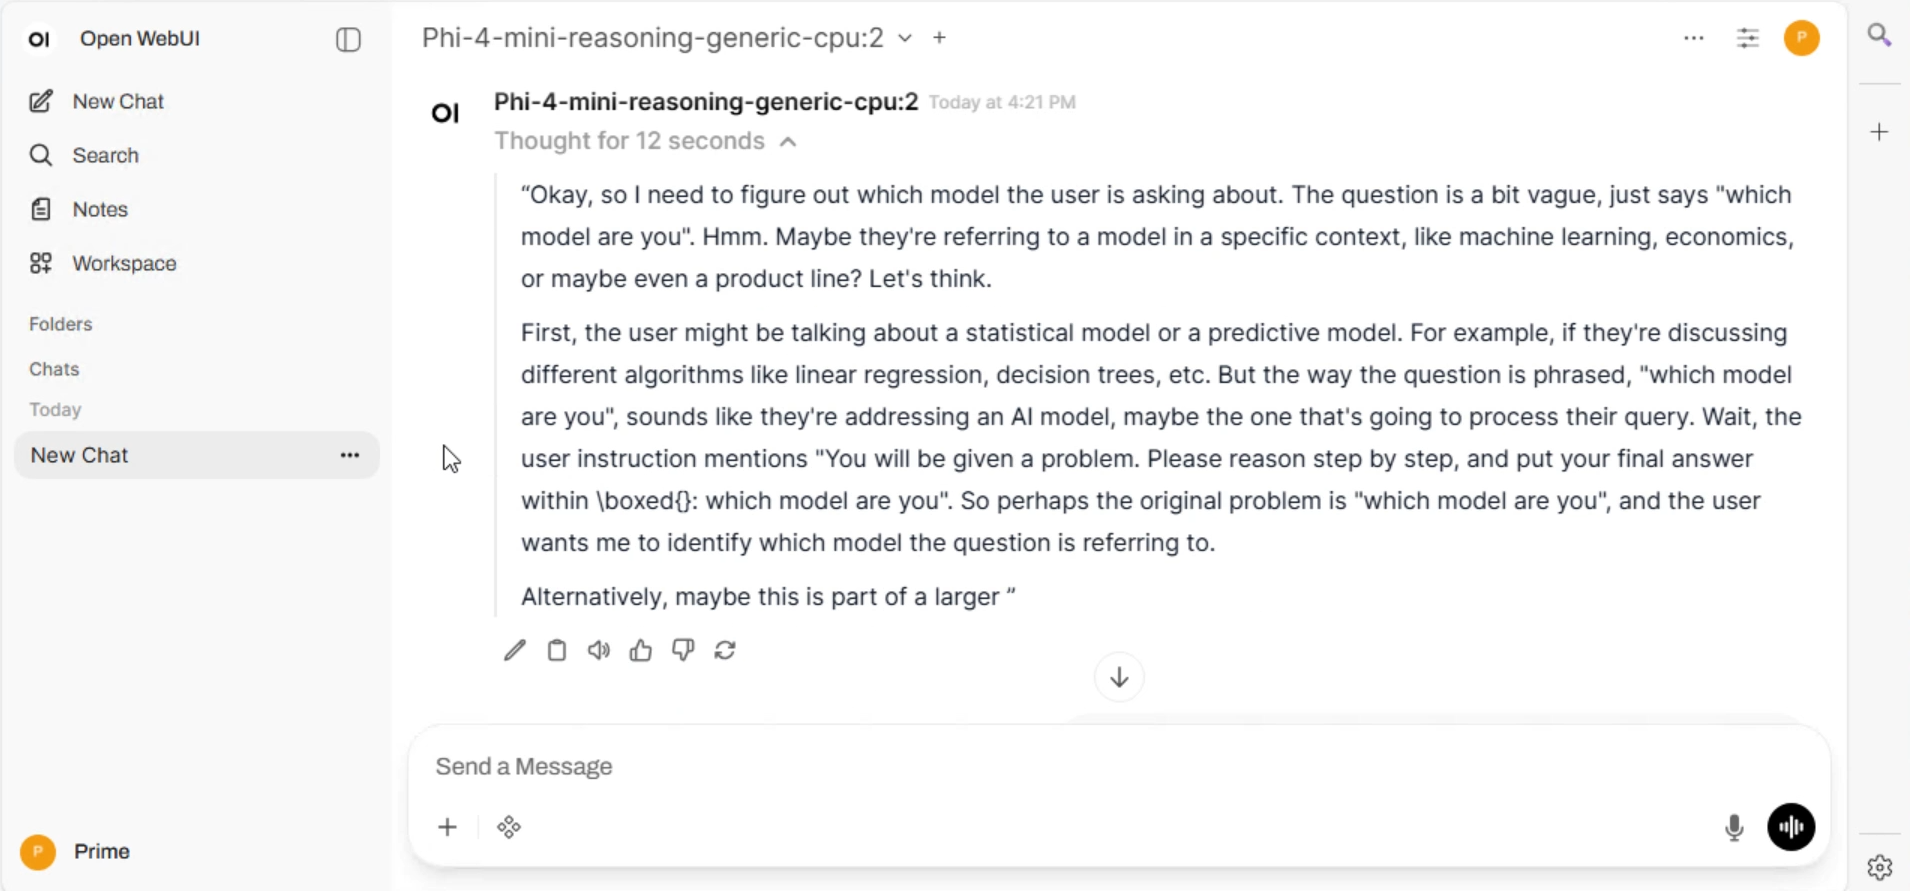
It will obtain the phi-4 mannequin and supply a textual content based mostly chat interface. If you wish to work together with Foundry Native by way of an online chat interface, you need to use the open supply Open WebUI mission. You’ll be able to set up Open WebUI on Home windows Server by performing the next steps:
conda.exe tos settle for --override-channels --channel https://repo.anaconda.com/pkgs/foremost conda.exe tos settle for --override-channels --channel https://repo.anaconda.com/pkgs/r conda.exe tos settle for --override-channels --channel https://repo.anaconda.com/pkgs/msys2
C:TempOpenWebUIInstaller.exe
Then from the dialog select to put in and run Open WebUI. You then must take a number of further steps to configure Open WebUI to connect with the Foundry Native endpoint.
Allow Direct Connections in Open WebUI
Choose Settings and Admin Settings within the profile menu.
Choose Connections within the navigation menu.
Allow Direct Connections by turning on the toggle. This permits customers to connect with their very own OpenAI suitable API endpoints.
Join Open WebUI to Foundry Native:
Choose Settings within the profile menu.
Choose Connections within the navigation menu.
Choose + by Handle Direct Connections.
For the URL, enter http://localhost:PORT/v1 the place PORT is the Foundry Native endpoint port (use the CLI command foundry service standing to search out it). Observe that Foundry Native dynamically assigns a port, so it is not all the time the identical.
Knowledge parsing information: Changing paperwork into gasoline on your enterprise AI
The largest bottleneck in most enterprise workflows isn’t a scarcity of knowledge; it is the problem of extracting that knowledge from the paperwork the place it’s trapped. We name this significant step knowledge parsing. However for many years, the expertise has been caught on a flawed premise. We’ve relied on inflexible, template-based OCR that treats a doc like a flat wall of textual content, making an attempt to learn its approach from prime to backside. Because of this it breaks the second a column shifts or a desk format adjustments. It’s nothing like how an individual truly parses data.
The breakthrough in knowledge parsing didn’t come from a barely higher studying algorithm. It got here from a very completely different method: instructing the AI to see. Trendy parsing techniques now carry out a classy structure evaluationearlier than studying, figuring out the doc’s visible structure—its columns, tables, and key-value pairs—to grasp context first. This shift from linear studying to contextual seeing is what makes clever automation lastly attainable.
This information serves as a blueprint for understanding the info parsing in 2025 and the way trendy parsing applied sciences remedy your most persistent workflow challenges.
The actual price of inaction: Quantifying the harm of handbook knowledge parsing in 2025
Let’s discuss numbers. In keeping with a 2024 {industry} evaluation, the common price to course of a single bill is $9.25, and it takes a painful 10.1 days from receipt to cost. If you scale that throughout hundreds of paperwork, the waste is gigantic. It is a key cause why poor knowledge high quality prices organizations a median of $12.9 million yearly.
The strategic misses
Past the direct prices, there’s the cash you are leaving on the desk each single month. Finest-in-class organizations—these within the prime 20% of efficiency—seize 88% of all out there early cost reductions. Their friends? A mere 45%. This is not as a result of their group works tougher; it is as a result of their automated techniques give them the visibility and velocity to behave on favorable cost phrases.
The human price
Lastly, and that is one thing we regularly see, there’s the human price. Forcing expert, educated workers to spend their days on mind-numbing, repetitive transcription is a recipe for burnout. A latest McKinsey report on the way forward for work highlights that automation frees staff from these routine duties, permitting them to concentrate on problem-solving, evaluation, and different high-value work that really drives a enterprise ahead. Forcing your sharpest folks to behave as human photocopiers is the quickest approach to burn them out.
From uncooked textual content to enterprise intelligence: Defining trendy knowledge parsing
Knowledge parsing is the method of routinely extracting data from unstructured paperwork (like PDFs, scans, and emails) and changing it right into a structured format (like JSON or CSV) that software program techniques can perceive and use. It’s the important bridge between human-readable paperwork and machine-readable knowledge.
The layout-first revolution
For years, this course of was dominated by conventional Optical Character Recognition (OCR), which basically reads a doc from prime to backside, left to proper, treating it as a single block of textual content. Because of this it so usually failed on paperwork with advanced tables or a number of columns.
What actually defines the present period of knowledge parsing, and what makes it ship on the promise of automation, is a elementary shift in method. For many years, these applied sciences have been utilized linearly, making an attempt to learn a doc from prime to backside. The breakthrough got here after we taught the AI to see. Trendy parsing techniques now carry out a classy structure evaluationearlier than studying, figuring out the doc’s visible structure—its columns, tables, and key-value pairs—to grasp context first. This layout-first method is the engine behind true, hassle-free automation, permitting techniques to parse advanced, real-world paperwork with an accuracy and suppleness that was beforehand out of attain.
Contained in the AI knowledge parsing engine
Trendy knowledge parsing is not a single expertise however a classy ensemble of fashions and engines, every enjoying a crucial function. Whereas the sector of knowledge parsing is broad, encompassing applied sciences resembling internet scraping and voice recognition, our focus right here is on the particular toolkit that addresses essentially the most urgent challenges in enterprise doc intelligence.
Optical Character Recognition (OCR): That is the foundational engine and the expertise most individuals are conversant in. OCR is the method of changing pictures of typed or printed textual content into machine-readable textual content knowledge. It is the important first step for digitizing any paper doc or non-searchable PDF.
Clever Character Recognition (ICR): Consider ICR as a extremely specialised model of OCR that’s been skilled to decipher the wild, inconsistent world of human handwriting. Given the immense variation in writing types, ICR makes use of superior AI fashions, usually skilled on huge datasets of real-world examples, to precisely parse hand-filled varieties, signatures, and written annotations.
Barcode & QR Code Recognition: That is essentially the most simple type of knowledge seize. Barcodes and QR codes are designed to be learn by machines, containing structured knowledge in a compact, visible format. Barcode recognition is used all over the place from retail and logistics to monitoring medical tools and occasion tickets.
Massive Language Fashions (LLMs): That is the core intelligence engine. In contrast to older rule-based techniques, LLMs perceive language, context, and nuance. In knowledge parsing, they’re used to determine and classify data (resembling “Vendor Title” or “Bill Date”) based mostly on its that means, not simply its place on the web page. That is what permits the system to deal with huge variations in doc codecs while not having pre-built templates.
Imaginative and prescient-Language Fashions (VLMs): VLMs are specialised AIs that course of a doc’s visible construction and its textual content concurrently. They’re what allow the system to grasp advanced tables, multi-column layouts, and the connection between textual content and pictures. VLMs are the important thing to precisely parsing the visually advanced paperwork that break easier OCR-based instruments.
Clever Doc Processing (IDP): IDP just isn’t a single expertise, however quite an overarching platform or system that intelligently combines all these elements—OCR/ICR for textual content conversion, LLMs for semantic understanding, and VLMs for structure evaluation—right into a seamless workflow. It manages every little thing from ingestion and preprocessing to validation and ultimate integration, making the whole end-to-end course of attainable.
Past the high-level AI engines, a number of particular parsing methods are elementary to how knowledge is structured and understood:
Common Expression (RegEx) Parsing:This method makes use of sequences of characters to kind search patterns. RegEx is extremely efficient for locating and extracting particular, predictable textual content patterns, resembling e-mail addresses, telephone numbers, or formatted codes inside a bigger physique of textual content. It is a highly effective software for knowledge cleansing and validation.
Grammar-Pushed vs. Knowledge-Pushed Parsing: These two approaches symbolize completely different philosophies. Grammar-driven parsing depends on a set of predefined guidelines to research knowledge, making it splendid for extremely structured codecs like XML and JSON, the place the syntax is constant. In distinction, data-driven parsing makes use of statistical fashions and machine studying to interpret knowledge, offering larger flexibility in dealing with the paradox and variability of unstructured textual content present in real-world paperwork.
Dependency Parsing: This superior Pure Language Processing (NLP) approach analyzes the grammatical construction of a sentence to grasp the relationships between phrases. It identifies which phrases modify others, making a dependency tree that captures the sentence’s that means. That is essential for superior purposes, resembling sentiment evaluation, textual content summarization, and question-answering techniques.
How trendy parsing solves decades-old issues
Trendy parsing techniques tackle conventional knowledge extraction challenges by integrating superior AI. By combining a number of applied sciences, these techniques can deal with advanced doc layouts, different codecs, and even poor-quality scans.
a. The issue of ‘rubbish in, rubbish out’ → Solved by clever preprocessing
The oldest rule of knowledge processing is “rubbish in, rubbish out.” For years, this has plagued doc automation. A barely skewed scan, a faint fax, or digital “noise” on a PDF would confuse older OCR techniques, resulting in a cascade of extraction errors. The system was a dumb pipe; it will blindly course of no matter poor-quality knowledge it was fed.
Trendy techniques repair this on the supply with clever preprocessing. Consider it this manner: you would not attempt to learn a crumpled, coffee-stained be aware in a dimly lit room. You’d straighten it out and activate a light-weight first. Preprocessing is the digital model of that. Earlier than making an attempt to extract a single character, the AI routinely enhances the doc:
Deskewing: It digitally straightens pages that have been scanned at an angle.
Denoising: It removes artifacts like spots and shadows that may confuse the OCR engine.
This automated cleanup acts as a crucial gatekeeper, making certain the AI engine at all times operates with the best high quality enter, which dramatically reduces downstream errors from the outset.
b. The issue of inflexible templates → Solved by layout-aware AI
The largest grievance we’ve heard about legacy techniques is their reliance on inflexible, coordinate-based templates. They labored completely for a single bill format, however the second a brand new vendor despatched a barely completely different structure, the whole workflow would break, requiring tedious handbook reconfiguration. This method merely could not deal with the messy, various actuality of enterprise paperwork.
The answer is not a greater template; it is eliminating templates altogether. That is attainable as a result of VLMs carry out structure evaluation, and LLMs present semantic understanding. The VLM analyzes the doc’s construction, figuring out objects resembling tables, paragraphs, and key-value pairs. The LLM then understands the that means of the textual content inside that construction. This mix permits the system to search out the “Complete Quantity” no matter its location on the web page as a result of it understands each the visible cues (e.g., it is on the backside of a column of numbers) and the semantic context (e.g., the phrases “Complete” or “Steadiness Due” are close by).
c. The issue of silent errors → Solved by AI self-correction
Maybe essentially the most harmful flaw in older techniques wasn’t the errors they flagged, however the ones they did not. An OCR may misinterpret a “7” as a “1” in an bill whole, and this incorrect knowledge would silently circulation into the accounting system, solely to be found throughout a painful audit weeks later.
At this time, we will construct a a lot increased diploma of belief because of AI self-correction. This can be a course of the place, after an preliminary extraction, the mannequin could be prompted to examine its personal work. For instance, after extracting all the road objects and the overall quantity from an bill, the AI could be instructed to carry out a ultimate validation step: “Sum the road objects. Does the outcome match the extracted whole?”, If there’s a mismatch, it will possibly both appropriate the error or, extra importantly, flag the doc for a human to evaluate. This ultimate, automated examine serves as a strong safeguard, making certain that the info getting into your techniques just isn’t solely extracted but additionally verified.
The fashionable parsing workflow in 5 steps
A state-of-the-art trendy knowledge parsing platform orchestrates all of the underlying applied sciences right into a seamless, five-step workflow. This complete course of is designed to maximise accuracy and supply a transparent, auditable path from doc receipt to ultimate export.
Step 1: Clever ingestion
The parsing platform begins by routinely amassing paperwork from numerous sources, eliminating the necessity for handbook uploads. This may be configured to tug recordsdata straight from:
E-mail inboxes (like a devoted invoices@firm.com tackle)
Cloud storage suppliers like Google Drive or Dropbox
Direct API calls from your individual purposes
Connectors like Zapier for {custom} integrations
Step 2: Automated preprocessing
As quickly as a doc is obtained, the parsing system prepares it for the AI to course of. This preprocessing stage is a crucial high quality management step that entails enhancing the doc picture by straightening skewed pages (deskewing) and eradicating digital “noise” or shadows. This ensures the underlying AI engines are continuously working with the clearest attainable enter.
Step 3: Structure-aware extraction
That is the core parsing step. The parsing platform orchestrates its VLM and LLM engines to carry out the extraction. This can be a extremely versatile course of the place the system can:
Use pre-trained AI fashions for traditional paperwork like Invoices, Receipts, and Buy Orders.
Apply a Customized Mannequin that you’ve got skilled by yourself particular or distinctive paperwork.
Deal with advanced duties like capturing particular person line objects from tables with excessive precision.
Step 4: Validation and self-correction
The parsing platform then runs the extracted knowledge via a high quality management gauntlet. The system can carry out Duplicate File Detection to stop redundant entries and examine the info in opposition to your custom-defined Validation Guidelines (e.g., making certain a date is within the appropriate format). That is additionally the place the AI can carry out its self-correction step, the place the mannequin cross-references its personal work to catch and flag potential errors earlier than continuing.
Step 5: Approval and integration
Lastly, the clear, validated knowledge is put to work. The parsing system does not simply export a file; it will possibly route the doc via multi-level Approval Workflows, assigning it to customers with particular roles and permissions. As soon as permitted, the info is shipped to your different enterprise techniques via direct integrations, resembling QuickBooks, or versatile instruments like Webhooks and Zapier, making a seamless, end-to-end circulation of knowledge.
Actual-world purposes: Automating the core engines of your enterprise
The true worth of knowledge parsing is unlocked once you transfer past a single process and begin optimizing the end-to-end processes which might be the core engines of your enterprise—from finance and operations to authorized and IT.
The monetary core: P2P and O2C
For many companies, the 2 most important engines are Procure-to-Pay (P2P) and Order-to-Money (O2C). Knowledge parsing is the linchpin for automating each. In P2P, it is used to parse provider invoices and guarantee compliance with regional e-invoicing requirements, resembling PEPPOL in Europe and Australia, in addition to particular VAT/GST laws within the UK and EU. On the O2C facet, parsing buyer POs accelerates gross sales, achievement, and invoicing, which straight improves money circulation.
The operational core: Logistics and healthcare
Past finance, knowledge parsing is crucial for the bodily operations of many industries.
Logistics and provide chain: This {industry} depends closely on a mountain of paperwork, together with payments of lading, proof of supply slips, and customs varieties such because the C88 (SAD) within the UK and EU. Knowledge parsing is used to extract monitoring numbers and transport particulars, offering real-time visibility into the availability chain and rushing up clearance processes.
Our buyer Suzano Worldwide, for instance, makes use of it to deal with advanced buy orders from over 70 clients, chopping processing time from 8 minutes to only 48 seconds.
Healthcare: For US-based healthcare payers, parsing claims and affected person varieties whereas adhering to HIPAA laws is paramount. In Europe, the identical course of should be GDPR-compliant. Automation can cut back handbook effort in claims consumption by as much as 85%. We noticed this with our buyer PayGround within the US, who minimize their medical invoice processing time by 95%.
The information and assist core: HR, authorized, and IT
Finally, knowledge parsing is essential for the assist features that underpin the remainder of the enterprise.
HR and recruitment: Parsing resumes automates the extraction of candidate knowledge into monitoring techniques, streamlining the method. This course of should be dealt with with care to adjust to privateness legal guidelines, such because the GDPR within the EU and the UK, when processing private knowledge.
Authorized and compliance: Knowledge parsing is used for contract evaluation, extracting key clauses, dates, and obligations from authorized agreements. That is crucial for compliance with monetary laws, resembling MiFID II in Europe, or for reviewing SEC filings, just like the Type 10-Ok within the US.
E-mail parsing: For a lot of companies, the inbox serves as the first entry level for crucial paperwork. An automatic e-mail parsing workflow acts as a digital mailroom, figuring out related emails, extracting attachments like invoices or POs, and sending them into the proper processing queue with none human intervention.
IT operations and safety: Trendy IT groups are inundated with log recordsdata. LLM-based log parsing is now used to construction this chaotic textual content in real-time. This enables anomaly detection techniques to determine potential safety threats or system failures way more successfully.
Throughout all these areas, the purpose is similar: to make use of clever AI doc processing to show static paperwork into dynamic knowledge that accelerates your core enterprise engines.
Choosing the proper implementation mannequin
Now that you just perceive the ability of recent knowledge parsing, the essential query turns into: What’s the best approach to convey this functionality into your group? The panorama has developed past a easy ‘construct vs. purchase’ choice. We are able to map out three main implementation paths for 2025, every with distinct trade-offs in management, price, complexity, and time to worth.
Mannequin 1: The complete-stack builder
This path is for organizations with a devoted MLOps group and a core enterprise want for deeply personalized AI pipelines. Taking this route means proudly owning and managing the whole expertise stack.
What it entails
Constructing a production-grade AI pipeline from scratch requires orchestrating a number of subtle elements:
Preprocessing layer: Your group would implement sturdy doc enhancement utilizing open-source instruments like Marker, which achieves ~25 pages per second processing. Marker converts advanced PDFs into structured Markdown whereas preserving structure, utilizing specialised fashions like Surya for OCR/structure evaluation and Texify for mathematical equations.
Mannequin choice and internet hosting: Relatively than common imaginative and prescient fashions like Florence-2 (which excels at broad laptop imaginative and prescient duties like picture captioning and object detection), you’d want document-specific options.
Choices embrace:
Self-hosting specialised doc fashions that require GPU infrastructure.
Positive-tuning open-source fashions on your particular doc varieties.
Constructing {custom} architectures optimized on your use circumstances.
Coaching knowledge necessities: Reaching excessive accuracy calls for entry to high quality datasets:
DocILE: 106,680 enterprise paperwork (6,680 actual annotated + 100,000 artificial) for bill and enterprise doc extraction.
FUNSD: 199 absolutely annotated scanned varieties for kind understanding.
Specialised collections for industry-specific paperwork.
Submit-processing and validation: Engineer {custom} layers to implement enterprise guidelines, carry out cross-field validation, and guarantee knowledge high quality earlier than system integration.
Benefits:
Most management over each part.
Full knowledge privateness and on-premises deployment.
Potential to customise for distinctive necessities.
No per-document pricing issues.
Challenges:
Requires a devoted MLOps group with experience in containerization, mannequin registries, and GPU infrastructure.
6-12 month growth timeline earlier than manufacturing readiness.
Ongoing upkeep burden for mannequin updates and infrastructure.
Complete price usually exceeds $500K within the first 12 months (group, infrastructure, growth).
Finest for: Massive enterprises with distinctive doc varieties, strict knowledge residency necessities, or organizations the place doc processing is a core aggressive benefit.
Mannequin 2: The mannequin as a service
This mannequin fits groups with sturdy software program growth capabilities who need to concentrate on utility logic quite than AI infrastructure.
What it entails
You leverage industrial or open-source fashions by way of APIs whereas constructing the encompassing workflow:
Industrial API choices:
OpenAI GPT-5: Basic-purpose mannequin with sturdy doc understanding.
Google Gemini 2.5: Obtainable in Professional, Flash, and Flash-Lite variants for various velocity/price trade-offs.
Anthropic Claude 3.7: Sturdy reasoning capabilities for advanced doc evaluation.
Specialised open-source fashions:
Benefits:
No MLOps infrastructure to keep up.
Entry to state-of-the-art fashions instantly.
Sooner preliminary deployment (2-3 months).
Pay-as-you-go pricing mannequin.
Challenges:
Constructing sturdy preprocessing pipelines.
API prices can escalate rapidly at scale ($0.01-0.10 per web page).
Nonetheless requires important engineering effort.
Creating validation and enterprise logic layers.
Latency issues for real-time processing.
Vendor lock-in and API availability dependencies.
Much less management over mannequin updates and adjustments.
Systematic critiques of LLM-based extraction have famous a pattern of decrease reproducibility and poorer high quality of reporting in comparison with conventional strategies.
LLMs may make particular varieties of errors, resembling ignoring unfavourable numbers, complicated comparable objects, or misinterpreting statistical significance.
Finest for: Tech-forward firms with sturdy engineering groups, average doc volumes (< 100K pages/month), or these needing fast proof-of-concept implementations.
💡
Batch Prompting: This entails clustering comparable log messages or paperwork and sending them to an LLM in a single batch. The mannequin can then infer patterns from the commonalities and variabilities inside the batch itself, lowering the necessity for express one-shot or few-shot demonstrations.
Mannequin 3: The platform accelerator
That is the fashionable, pragmatic method for the overwhelming majority of companies. It is designed for groups that desire a custom-fit resolution with out the huge R&D and upkeep burden of the opposite fashions.
What it entails:
Adopting a complete (IDP) platform that gives full pipeline administration:
Automated doc ingestion from a number of sources (e-mail, cloud storage, APIs)
Constructed-in preprocessing with deskewing, denoising, and enhancement
A number of AI fashions optimized for various doc varieties
Validation workflows with human-in-the-loop capabilities
These platforms speed up your work by not solely parsing knowledge but additionally getting ready it for the broader AI ecosystem. The output is able to be vectorized and fed into RAG (Retrieval-Augmented Era) pipelines, which can energy the subsequent era of AI brokers. It additionally offers the instruments to do the high-value construct work: you possibly can simply practice {custom} fashions and assemble advanced workflows together with your particular enterprise logic.
This mannequin offers one of the best steadiness of velocity, energy, and customization. We noticed this with our buyer Asian Paints, who built-in Nanonets’ platform into their advanced SAP and CRM ecosystem, reaching their particular automation objectives in a fraction of the time and price it will have taken to construct from scratch.
Benefits:
Quickest time to worth (days to weeks).
No infrastructure administration required.
Constructed-in greatest practices and optimizations.
Steady mannequin enhancements included.
Predictable subscription pricing.
Skilled assist and SLAs.
Challenges:
Much less customization than a full-stack method.
Ongoing subscription prices.
Dependency on vendor platform.
Could have limitations for extremely specialised use circumstances.
Finest suited to: Companies in search of fast automation, firms with out devoted ML groups, and organizations prioritizing velocity and reliability over full management.
With so many instruments making claims about accuracy, how will you make knowledgeable choices? The reply lies within the science of benchmarking. The progress on this subject just isn’t based mostly on advertising slogans however on rigorous, tutorial testing in opposition to standardized datasets.
When evaluating a vendor, ask them:
What datasets are your fashions skilled on? The power to deal with troublesome paperwork, resembling advanced layouts or handwritten varieties, stems straight from being skilled on huge, specialised datasets like DocILE and Handwritten-Varieties.
How do you benchmark your accuracy? A reputable vendor ought to have the ability to focus on how their fashions carry out on public benchmarks and clarify their methodology for measuring accuracy throughout completely different doc varieties.
💡
A crucial new problem in analysis is “label-induced bias.” Current research have proven that when one LLM is used to guage the output of one other, its judgment could be closely skewed by the perceived identification of the mannequin it is reviewing. This underscores the necessity for blind analysis protocols, the place the identification of the mannequin being examined is hid from the evaluator LLM to make sure honest and goal outcomes.
Past benchmarks, a sturdy analysis requires a guidelines of crucial capabilities:
Knowledge format versatility: The platform should deal with all of the doc varieties your enterprise depends on, together with PDFs, pictures, emails, and each printed and handwritten textual content.
Efficiency and scalability: The software should have the ability to course of your doc quantity effectively with out efficiency degradation. Assess its capacity to scale as your enterprise grows.
Accuracy and error dealing with: Search for options like confidence scores for every extracted subject and built-in validation guidelines. A vital part is a “human-in-the-loop” interface that flags unsure knowledge for handbook evaluate, which additionally helps enhance the mannequin over time.
Integration and automation capabilities: The software program should match into your current tech stack. Search for sturdy APIs and pre-built connectors on your ERP, CRM, and different enterprise techniques to make sure a seamless, automated workflow.
Safety and compliance: When processing delicate data, safety is non-negotiable. Confirm that the seller meets {industry} requirements like SOC 2 and might assist regulatory necessities resembling HIPAA or GDPR.
Customization and suppleness: Your corporation is exclusive, and your parsing software must be adaptable. Make sure the platform permits you to create {custom} extraction guidelines or practice fashions on your particular doc layouts with out requiring deep technical experience.
Strategic purpose alignment: Earlier than you course of a single doc, clearly outline what you need to obtain. Are you aiming to cut back handbook effort, enhance knowledge accuracy, speed up workflows, or mitigate compliance dangers? Begin by figuring out essentially the most crucial, high-pain doc processes and set life like expectations for what the expertise can accomplish in its preliminary phases.
Perceive your doc complexity: A profitable implementation will depend on an intensive understanding of your paperwork. Consider the particular challenges they current, resembling poor scan high quality, advanced multi-page tables, inconsistent layouts, or the presence of handwritten textual content. This upfront evaluation will assist you choose an answer with the correct capabilities to deal with your distinctive wants.
Set up a suggestions loop: Essentially the most profitable deployments incorporate a human-in-the-loop validation course of. This enables your group to evaluate and proper knowledge that the AI flags as unsure. This suggestions is essential for repeatedly coaching and enhancing the AI mannequin’s accuracy over time, making a system that will get smarter with each doc it processes.
Getting ready your knowledge for the AI-powered enterprise
The purpose of knowledge parsing in 2025 is not to get a clear spreadsheet. That’s desk stakes. The actual, strategic goal is to create a foundational knowledge asset that may energy the subsequent wave of AI-driven enterprise intelligence and basically change the way you work together together with your firm’s information.
From structured knowledge to semantic vectors for RAG
For years, the ultimate output of a parsing job was a structured file, resembling Markdown or JSON. At this time, that is simply the midway level. The last word purpose is to create vector embeddings—a course of that converts your structured knowledge right into a numerical illustration that captures its semantic that means. This “AI-ready” knowledge is the important gasoline for RAG.
RAG is an AI approach that enables a Massive Language Mannequin to “search for” solutions in your organization’s non-public paperwork earlier than it speaks. Knowledge parsing is the important first step that makes this attainable. An AI can’t retrieve data from a messy, unstructured PDF; the doc should first be parsed to extract and construction the textual content and tables. This clear knowledge is then transformed into vector embeddings to create the searchable “information base” that the RAG system queries. This lets you construct highly effective “chat together with your knowledge” purposes the place a authorized group might ask, “Which of our consumer contracts within the EU are up for renewal within the subsequent 90 days and include a knowledge processing clause?”
The longer term
Trying forward, the subsequent frontier of automation is the deployment of autonomous AI brokers—digital workers that may cause and execute multi-step duties throughout completely different purposes. A core functionality of those brokers is their capacity to make use of RAG to entry information and cause via features, very similar to a human would search for a file to reply a query.
Think about an agent in your AP division who:
Displays the invoices@ inbox.
Makes use of knowledge parsing to learn a brand new bill attachment.
Makes use of RAG to search for the corresponding PO in your information.
Validates that the bill matches the PO.
Schedules the cost in your ERP.
Flags solely the exceptions that require human evaluate.
This complete autonomous workflow is inconceivable if the agent is blind. The delicate fashions that allow this future—from general-purpose LLMs to specialised doc fashions like DocStrange—all depend on knowledge parsing because the foundational talent that provides them the sight to learn and act upon the paperwork that run your enterprise. It’s the most important funding for any firm critical about the way forward for AI doc processing.
💡
A crucial consideration for the way forward for AI brokers is the danger of “AI Psychosis” or “distributed delusions,” the place people come to hallucinate with AI techniques quite than simply receiving false data from them. This could occur when an AI is designed to be overly agreeable, endlessly affirming a consumer’s inputs with out problem. In a enterprise context, an AI agent that fails to query a flawed course of or an incorrect knowledge level might amplify errors all through the group.
Broader enterprise knowledge tendencies
The significance of knowledge parsing is amplified by a number of converging tendencies in how enterprises handle knowledge:
Knowledge-as-a-Service (DaaS): Companies are more and more outsourcing knowledge storage, processing, and analytics to DaaS platforms. This mannequin democratizes entry to enterprise-grade instruments, permitting firms to leverage highly effective knowledge capabilities with out huge upfront infrastructure investments.
Knowledge Mesh Structure: As an alternative of funneling all knowledge right into a centralized lake or warehouse, the info mesh is a decentralized method the place particular person enterprise domains personal their knowledge as a “product”. This framework improves knowledge accessibility and agility whereas sustaining federated governance to make sure high quality and interoperability throughout the group.
Hybrid Knowledge Pipelines: Trendy enterprises function in advanced environments with knowledge unfold throughout on-premises techniques and a number of clouds. Hybrid knowledge pipelines mix real-time streaming with batch processing, enabling companies to realize speedy insights whereas additionally conducting in-depth, complete evaluation. This unified method is important for a holistic and sturdy knowledge technique.
Wrapping up
The race to deploy AI in 2025 is basically a race to construct a dependable digital workforce of AI brokers. In keeping with a latest govt playbook, these brokers are techniques that may cause, plan, and execute advanced duties autonomously. However their capacity to carry out sensible work is solely depending on the standard of the info they will entry. This makes high-quality, automated knowledge parsing the only most important enabler for any group trying to compete on this new period.
By automating the automatable, you evolve your group’s roles, upskilling them from handbook knowledge entry to extra strategic work, resembling evaluation, exception dealing with, and course of enchancment. This transition empowers the rise of the Data Chief—a strategic function targeted on managing the info and automatic techniques that drive the enterprise ahead.
A sensible 3-step plan to start your automation journey
Getting began does not require an enormous, multi-quarter undertaking. You’ll be able to obtain significant outcomes and show the worth of this expertise in a matter of weeks.
Establish your largest bottleneck. Choose one high-volume, high-pain doc course of. It could possibly be one thing like vendor bill processing. It is an ideal start line as a result of the ROI is obvious and speedy.
Run a no-commitment pilot. Use a platform like Nanonets to course of a batch of 20-30 of your individual real-world paperwork. That is the one approach to get an correct, plain baseline for accuracy and potential ROI in your particular use case.
Deploy a easy workflow. Map out a fundamental end-to-end circulation (e.g., E-mail -> Parse -> Validate -> Export to QuickBooks). You’ll be able to go reside together with your first automated workflow in per week, not a 12 months, and begin seeing the advantages instantly.
FAQs
What ought to I search for when selecting knowledge parsing software program?
Search for a platform that goes past fundamental OCR. Key options for 2025 embrace:
Structure-Conscious AI: The power to grasp advanced paperwork with out templates.
Preprocessing Capabilities: Computerized picture enhancement to enhance accuracy.
No-Code/Low-Code Interface: An intuitive platform for coaching {custom} fashions and constructing workflows.
Integration Choices: Strong APIs and pre-built connectors to your current ERP or accounting software program.
How lengthy does it take to implement a knowledge parsing resolution?
In contrast to conventional enterprise software program that might take months to implement, trendy, cloud-based IDP platforms are designed for velocity. A typical implementation entails a brief pilot section of per week or two to check the system together with your particular paperwork, adopted by a go-live together with your first automated workflow. Many companies could be up and operating, seeing a return on funding, in underneath a month.
Can knowledge parsing deal with handwritten paperwork?
Sure. Trendy knowledge parsing techniques use a expertise referred to as Clever Character Recognition (ICR), which is a specialised type of AI skilled on hundreds of thousands of examples of human handwriting. This enables them to precisely extract and digitize data from hand-filled varieties, purposes, and different paperwork with a excessive diploma of reliability.
How is AI knowledge parsing completely different from conventional OCR?
Conventional OCR is a foundational expertise that converts a picture of textual content right into a machine-readable textual content file. Nevertheless, it does not perceive the that means or construction of that textual content. AI knowledge parsing makes use of OCR as a primary step however then applies superior AI (like IDP and VLMs) to categorise the doc, perceive its structure, determine particular fields based mostly on context (like discovering an “bill quantity”), and validate the info, delivering structured, ready-to-use data.
These in want of a brilliant low cost cellphone deal could have come to the best place, seeing as Greatest Purchase is providing as much as $400 off final 12 months’s Motorola Edge as a part of an outlet and clearance sale operating via this weekend. Whereas the 2024 Edge is not going to supply peak efficiency ranges, it’s going to get the job completed for many informal customers. Plus, at $150 if you let Greatest Purchase activate it for you (or $250 in the event you activate it your self), it begins to look somewhat extra aggressive regardless of being a 2024 mannequin.
The 2024 Motorola Edge nonetheless contains the luxurious-feeling, anti-slip vegan leather-based backing, a very nice pOLED show that is simple on the eyes, and the user-friendly Whats up UI that consumers love. It comes with 256GB of storage, a 32MP entrance digicam and each an everyday rear lens and an ultrawide.
Past that, it is stated to simply recover from a full day’s value of battery life with its 5,000mAh battery, and it presents as much as 68W quick charging, making it a great decide for individuals who worth battery life.
✅Beneficial if: you are in search of a cellphone for beneath $200 or $300 that will not compromise on battery life or charging speeds; you want having a handsome show that is additionally considerably simple on the eyes; you have favored the luxurious really feel of Motorola’s anti-slip vegan leather-based backing on different telephones.
❌Skip this deal if: you are in search of a cellphone with industry-leading efficiency speeds; you worth having a cellphone with a long-term software program replace promise; you desire a cellphone with high-powered cameras and you’ve got the finances to spend somewhat extra.
The Motorola Edge lineup has supplied some respectable, lower-priced telephones over time. Nonetheless, we have nonetheless discovered a few of these worth tags somewhat costly for what you get, which is why reductions like these could also be value making the most of. Whereas lots of the finest Motorola telephones supply extra highly effective efficiency than final 12 months’s Edge, customers who do not care about having a super-fast cellphone could respect different parts of the 2024 mannequin, comparable to its long-lasting battery, 8GB of RAM, 256GB of storage, in addition to the gorgeous, 6.6-inch pOLED show, which boasts a 144Hz refresh price.
This 12 months’s Motorola Edge did embrace just a few upgrades from the 2024 mannequin, maybe most notably together with new AI options and higher cameras. For many, nonetheless, the 2024 mannequin will supply what most informal customers want, so long as you do not thoughts the truth that efficiency generally is a little sluggish at occasions.