Home Blog Page 676

8 Excessive-Demand AI Jobs in 2025

[ad_1]

Are you involved concerning the affect of AI in your career? You’re not alone. 

With Synthetic Intelligence altering the world, and nonetheless altering it at a staggering tempo, folks all all over the world are asking themselves how they are often related -or even ahead- of the occasions of clever automation.

Organizations are making use of AI to automate processes, optimize decision-making, and supply a better buyer expertise. This wave of adoption has generated an enormous demand for skilled personnel with the potential to slender the hole between AI applied sciences and precise enterprise necessities.

On this article, we’ll talk about the 8 high-demand AI jobs in 2025 and what they entail, the abilities required to work, and how one can put together to work in these positions. These positions not solely have excessive progress prospects and aggressive pay but additionally the chance to safe probably the most profitable careers in 2025 and past.

Why AI Careers Are Booming in 2025

With the adoption of AI expertise in enterprise processes has led to a 25% productiveness increase within the manufacturing enterprise, by which over 35 p.c of e-commerce revenues come by AI-based methods. The AI job market represents a big selection of future-proof employment alternatives to those that are keen to be part of AI-powered job roles that deliver the following wave of automation & data-driven decision-making throughout industries.

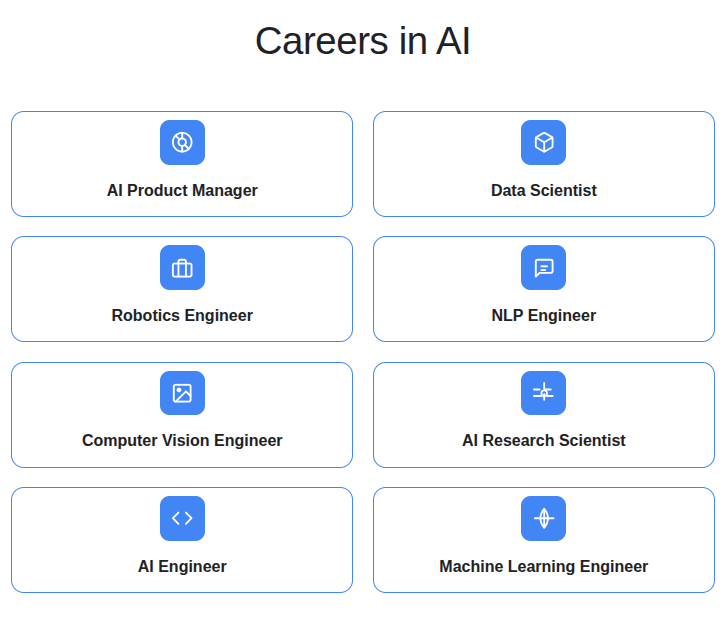
8 Excessive-Demand AI Jobs in 2025
AI Career Options

1. AI Engineer

The AI Engineers are essential contributors to the event of AI as they’re engaged of their actions, which embody creating AI options & growing their purposes in real-world problem-solving wants.

  • The on a regular basis duties of AI Engineers encompass mannequin growth exercise & enterprise management involvement.
  • They align AI options & integrative exercise amongst AI instruments, merchandise, & providers, incomes an annual median wage of $145,080

To develop into profitable within the space, one must grasp Python programming, possess the information of such frameworks as TensorFlow or PyTorch, & know discover the answer to difficult issues.

Moreover, should you’re simply beginning with Synthetic Intelligence, Grasp Synthetic Intelligence by Nice Studying is right to discover the basics of AI, machine studying, deep neural networks, GenAI, & to construct key expertise within the newest applied sciences. 

2. Machine Studying Engineer

A Machine Studying Engineer develops computerized studying algorithms that may allow computer systems to be taught by the datasets & mechanically enhance their efficiency in a minimal quantity of human code.

  • Machine studying engineers perform their roles by creating, testing, & implementing machine studying fashions & automating actions. 
  • The common annual wage of a machine studying engineer within the US is $109,143
  • Their position is essential as a result of they design and implement clever methods, resembling advice engines and fraud detection fashions, that assist organizations make smarter choices, optimize operations, and ship customized person experiences.

These trying to construct experience on this area typically pursue specialised applications, resembling an on-line MS in Synthetic Intelligence and Machine Studying, which give a complete basis in programming, statistics, and operations of ML frameworks.

3. Information Scientist

Information Scientists research in depth databases to generate sensible info that guides enterprise planning. The position of Information Scientists stays important all through the e-commerce, finance, and healthcare sectors, as they make the most of knowledge insights to boost operational effectivity and sample prediction.

  • The scope of their duties consists of growing knowledge fashions, performing predictive analytics, and supporting key firm choices.
  • Skilled success for knowledge analysts requires experience in each knowledge evaluation strategies and programming expertise, in addition to machine studying practices and statistical strategies. 

To attain success within the discipline, you will need to choose an appropriate instructional path. Formal levels, together with Bachelor’s and Grasp’s applications, set up the essential theoretical and sensible foundations, whereas specialised choices, such because the MS in Information Science program, additional sharpen the skilled expertise that companies urgently want and permit you to earn the common annual wage of $65,674.

Carefully associated to knowledge science roles, Information Architects play a significant half in designing the infrastructure that helps large-scale analytics and AI methods. Be taught extra about what a Information Architect does, required expertise, and profession pathways on this information: Find out how to develop into a Information Architect. 

4. AI Analysis Scientist

AI Analysis Scientists advance AI expertise by growing novel algorithms and conducting analysis experiments that propel the sector ahead.

  • The analysis staff conducts deliberate experiments and publishes their outcomes by collaboration with tutorial establishments and industrial companions. 
  • To excel on this place, one requires professional-level mathematical expertise, mixed with in depth studying expertise and a stable understanding of analysis strategies. 
  • AI Analysis Scientists are essential in growing technological advances, which decide how AI purposes evolve all through time.

Understanding the key duties and instruments of a Information Analyst may assist construct a powerful base for progress in AI-focused roles, as many professionals start their careers as Information Analysts earlier than advancing into knowledge science or AI specializations, incomes a median annual wage of $115,443 as an AI analysis scientist within the US.

5. Robotics Engineer

Throughout the discipline of robotics engineering, professionals design and develop clever robotic methods to automate varied industrial operations, starting from manufacturing actions to logistics and healthcare purposes, and earn an common annual wage of $120,997 per 12 months.

  • The duties of those professionals embody robotic creation, coding actions, check runs, and system upkeep. 
  • They develop clever machines by an ideal mix of robotics engineering and Synthetic Intelligence integration capabilities to execute autonomous advanced duties. 
  • The implementation of automation by industries drives continuous growth within the want for Robotics Engineers and exhibits no signal of slowing down.

Automation additionally extends past robotics into software program high quality and efficiency testing. Professionals aiming to make sure the reliability of AI methods can discover a profession as an Automation Check Engineer, answerable for designing check frameworks and enhancing AI mannequin effectivity. Be taught extra on this detailed Automation Check Engineer Profession Information.

6. Pc Imaginative and prescient Engineer

Via the event of methods, Pc Imaginative and prescient Engineers allow computer systems to grasp visible info from photos and video content material. 

  • Their programming empowers purposes to acknowledge faces, drive autonomous autos, and ship augmented actuality capabilities. 
  • Incomes the common annual wage of $168,803, these specialists are answerable for creating and fine-tuning algorithms that allow machines to interpret visible knowledge, thereby bridging the hole between uncooked pictures and actionable insights for real-world purposes, resembling medical diagnostics and robotics.
  • The required skills for this discipline embody deep studying strategies, picture processing, and superior laptop imaginative and prescient strategies, expertise which might be more and more valued as knowledge turns into central for enterprise options and innovation. 

7. AI Chatbot Developer / NLP Engineer

The mixture of AI Chatbot Builders and NLP Engineers is reworking how companies work together with clients by growing methods and conversational brokers that may perceive and generate human language. 

  • These professionals design multi-tiered chatbots and construct refined NLP fashions to strengthen dialogue and person engagement. They collaborate intently with different engineers to create methods that may comprehend human voice and textual content and react accordingly, with the common annual wage of an NLP engineer $86,193.
  • Their work requires competency in NLP, Python, and mastery of chatbot frameworks, in addition to an understanding of combine AI fashions for responsive, context-aware conversations. 
  • A powerful basis, resembling one constructed by a complete Pure Language Processing tutorial, is essential for excelling on this discipline. 

As LLM and NLP AI fashions proceed to be into demand with AI chatbot developer, a associated and fast-emerging position is that of the Immediate Engineer who designs and optimizes the inputs that information AI fashions to supply related outputsis additionally on the increase.

You possibly can discover extra about develop into a immediate engineer and construct the precise ability set for this GenAI-driven position.

8. AI Product Supervisor

The position of the AI Product Supervisor exists to merge technical operations with enterprise priorities, making certain that AI venture effectivity aligns with organizational ideas. For an in depth understanding of what the position entails, discover this complete information on AI Product Supervisor expertise, duties, and profession progress.

  • Incomes the common annual wage of $128,091, these professionals steer product path and oversee growth duties, sustaining efficient staff relationships all through the method. 
  • Data of product administration, AI proficiency, communication expertise, and enterprise understanding are important competencies. 
  • The central significance of AI Product Managers in enterprise technique growth is rising, as they’re essential for attaining profitable AI implementation and maximizing the worth of AI investments.

CONCLUSION

Within the 12 months 2025, AI may have quite a few alternatives with many rewarding roles that shall be supplied to people with applicable competencies.

Amongst these professions, AI Engineers, Information Scientists, NLP consultants, and AI Product managers are the careers that enhance the technological and enterprise functioning of recent society.Those that wish to develop into leaders within the space of educational innovation and superior expertise analysis can apply to get a Doctorate in AI and Machine Studying to discover new technological frontiers.

[ad_2]

On Unbiased MCMC with couplings – Robin Ryder’s weblog

0

[ad_1]

Pierre Jacob, John O’Leary and Yves Atchadé’s wonderful paper on Unbiased MCMC with couplings will likely be learn on the Royal Statistical Society tomorrow; Pierre has already introduced the paper on the Statisfaction weblog.
Though we received’t be current tomorrow, we’ve got learn it at size in our native studying group with Xian Robert and PhD college students Grégoire Clarté, Adrien Hairault and Caroline Lawless, and have submitted the next dialogue.

We congratulate the authors for this wonderful paper.

In “conventional” MCMC, it’s customary to verify that stationarity has been attained by operating a small variety of parallel chains, initiated at completely different beginning factors, to confirm that the ultimate distribution is unbiased of the initialization — although the one versus a number of chain(s) debate errupted from the beginning with Gelman and Rubin (1992) versus Geyer (1992).

As famous by the authors, a nasty selection of the preliminary distribution can result in poor properties. In essence, this happens and stays undetected for the present proposal as a result of the coupling of the chains happens lengthy earlier than the chain reaches stationarity. We wish to make two ideas to alleviate this situation, and therefore add a stationarity verify as a byproduct of the run.

  1. The chains X and Y have to have the identical preliminary distribution, however completely different pairs of chains on completely different parallel cores can afford completely different preliminary distributions. The ensuing estimator stays unbiased. We’d subsequently recommend that parallel chains be initiated from distributions which put weight on completely different elements of the parameter area. Concepts from the Quasi-Monte Carlo literature (see Gerber & Chopin 2015) may very well be used right here.
  2.  We additionally word that though the marginal distributions of X and Y have to be similar, any joint distribution on (X,Y) produces an unbiased algorithm. We’d recommend that it’s preferable that X and Y meet (shortly) after the chains have reached stationarity. Right here is one attainable technique to this finish: let p and p' be two distributions which put weight on completely different elements of the area, and Zsim Bernoulli(1/2). If Z=0, take X_0sim p and Y_0sim p', else take X_0sim p' and Y_0sim p. The marginal distribution of each X_0 and Y_0 is frac12(p+p'), however the two chains will begin in several elements of the parameter area and are more likely to meet after they’ve each reached stationarity.

The best algorithm is one which provides an accurate reply when it has converged, and a warning or error when it hasn’t. MCMC chains which haven’t but reached stationarity (for instance as a result of they haven’t discovered all modes of a multimodal distribution) might be arduous to detect. Right here, this situation is extra more likely to be detected since it will result in the coupling not occuring: mathbb E[tau] is giant, and it is a function, because it warns the practitioner that their kernel is ill-fitted to the goal density.

[ad_2]

The Orionid meteor bathe peaks below darkish, moonless skies subsequent week. This is the best way to see it

0

[ad_1]

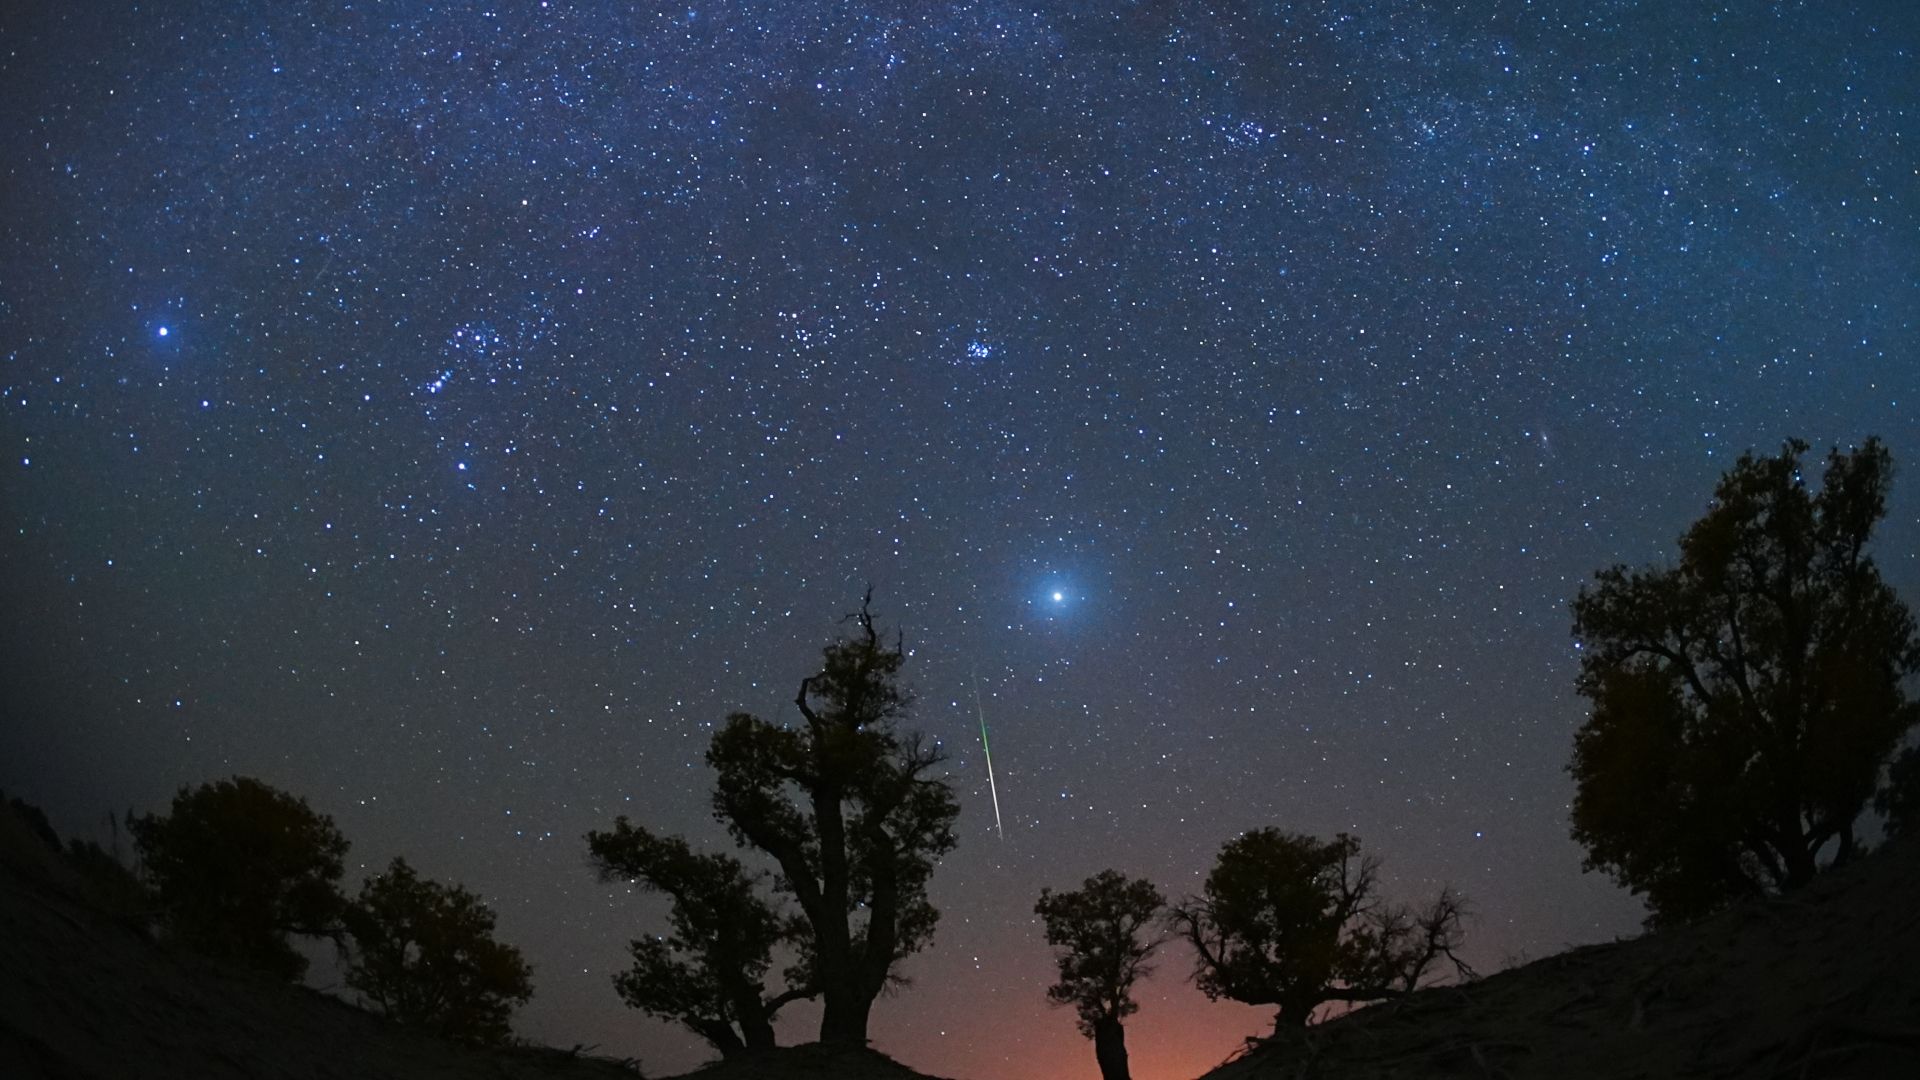
In the event you occur to glimpse a “taking pictures star” earlier than daybreak throughout the subsequent a number of days, there is a good probability that what you noticed was a fraction left behind in area by the well-known Halley’s Comet. For it’s throughout the third week of October {that a} meteor show spawned by the particles shed by Halley reaches its peak: the Orionid meteor bathe.

The Orionids aren’t one of many 12 months’s richest meteor shows. If the August Perseids and December Geminids might be thought-about the “first string” among the many annual meteor showers by way of brightness and reliability, then the Orionids are on the junior varsity crew.

[ad_2]

Weekend Movies — Would-Be Tyrants and Actual-Life Giants

0

[ad_1]

That is a unprecedented piece of tv. It’s, virtually with out fail, pitch good. It acknowledges the gravity of the second whereas conserving a wholesome sense of perspective. As he himself factors out, the destiny of a chat present is trivial in comparison with many different issues happening, however the points it raises are usually not trivial in any respect.

For these of us who’re approach too into the historical past of the medium, the monologue opens with a 65-year-old callback to maybe the primary discuss present censorship scandal.

As Josh Marshall and lots of others have identified, presumably the worst consequence for Sinclair is having its viewers be taught extra about who owns their native stations. A couple of years in the past, John Oliver did a wonderful section on Sinclair that has solely develop into extra related.

I notably appreciated the best way round 1:20 Oliver adopted up his teasing of native information by acknowledging that native tv journalists usually do extraordinary work, and have, to a point, stepped as much as fill the void left by the decline of newspapers. 

Lastly, simply to finish on a much less infuriating word, here’s a very cool story concerning the making of The Princess Bride.

“The Princess Bride” turns 38 right now.

Right here’s an amazing story about Andre the Big — as advised by Mandy Patinkin.

[image or embed]

— Carl Quintanilla (@carlquintanilla.bsky.social) September 25, 2025 at 7:27 AM

[ad_2]

Signal Restricted SVAR in GAUSS

0

[ad_1]

Introduction

In structural vector autoregressive (SVAR) modeling, one of many core challenges is figuring out the structural shocks that drive the system’s dynamics.

Conventional identification approaches typically depend on short-run or long-run restrictions, which require robust theoretical assumptions about contemporaneous relationships or long-term conduct.

Signal restriction identification supplies better flexibility by permitting economists to specify solely the route, constructive, adverse, or impartial, of variable responses to shocks, based mostly on principle.

On this weblog, we’ll present you the best way to implement signal restriction identification utilizing the brand new GAUSS process, svarFit, launched in TSMT 4.0.

We’ll stroll via the best way to:

  • Specify signal restrictions.
  • Estimate the SVAR mannequin.
  • Interpret the ensuing impulse response features (IRFs).

By the top of this information, you’ll have a stable understanding of the best way to apply signal restrictions to uncover significant financial relationships.

What are Signal Restrictions?

Signal restrictions are a way of figuring out structural shocks in SVAR fashions by specifying the anticipated route of response of endogenous variables.

Signal restrictions:

  • Don’t impose actual constraints on parameter values or long-term impacts; they solely require that impulse responses transfer in a specific route for a specified interval.
  • Are versatile and fewer reliant on strict parametric assumptions than different identification strategies.
  • Depend on qualitative financial insights, making them much less liable to mannequin specification errors.

For instance, in a financial coverage shock, financial principle would possibly counsel that a rise in rates of interest ought to result in a decline in output and inflation within the brief run. An SVAR signal restriction identification method would implement these directional actions.

Estimating SVAR Fashions in GAUSS

The svarFit process, obtainable in TSMT 4.0, gives an all-in-one device for:

  • Estimating reduced-form parameters of VAR fashions.
  • Implementing structural identification.
  • Deriving impulse response features (IRFs), forecast error variance decompositions (FEVDs), and historic decompositions (HDs).

Whereas the process supplies intuitive defaults for fast and simple estimation, it additionally gives the pliability to completely customise your mannequin.

For an in depth, step-by-step walkthrough of the estimation course of, check with my earlier weblog put up:
Estimating SVAR Fashions with GAUSS.
That put up gives steering on organising the mannequin, estimating reduced-form parameters, and performing structural identification.

Implementing Signal Restrictions with svarFit

The svarFit process means that you can specify signal restrictions as a structural identification technique. That is accomplished in three major steps:

  1. Set the identification technique to signal restrictions.
  2. Outline the signal restriction matrix.
  3. Specify the shock variables and impacted horizons.

Instance: Signal Restricted Responses to Provide, Demand, and Financial Coverage Shocks

Let’s discover an empirical instance capturing the dynamic relationships between inflation, unemployment, and the federal funds charge.

We’ll impose economically significant signal restrictions to determine three key shocks:

Shock SortInflationUnemploymentFederal Funds Charge
Provide Shock
Demand Shock++
Financial Coverage Shock++

These restrictions enable us to use financial principle to untangle the underlying structural drivers behind noticed actions within the knowledge.

Step One: Loading Our Knowledge

Step one in our mannequin is to load the information from the data_narsignrestrict.dta file.

/*
** Knowledge import
*/
fname = "data_narsignrestrict.dta";
data_shortrun = loadd(fname);

Step Two: Specifying the VAR Mannequin

On this instance, we’ll estimate a SVAR(2) mannequin which incorporates three endogenous variables and a relentless:

$$start{aligned} lntext{inflat}_t = c_1 &+ a_{11} lntext{inflat}_{t-1} + a_{12} lntext{fedfunds}_{t-1} + a_{13} lntext{unempl}_{t-1} &+ a_{14} lntext{inflat}_{t-2} + a_{15} lntext{fedfunds}_{t-2} + a_{16} lntext{unempl}_{t-2} &+ gamma_1 t + u_{1t} lntext{fedfunds}_t = c_2 &+ a_{21} lntext{inflat}_{t-1} + a_{22} lntext{fedfunds}_{t-1} + a_{23} lntext{unempl}_{t-1} &+ a_{24} lntext{inflat}_{t-2} + a_{25} lntext{fedfunds}_{t-2} + a_{26} lntext{unempl}_{t-2} &+ gamma_2 t + u_{2t} lntext{unempl}_t = c_3 &+ a_{31} lntext{inflat}_{t-1} + a_{32} lntext{fedfunds}_{t-1} + a_{33} lntext{unempl}_{t-1} &+ a_{34} lntext{inflat}_{t-2} + a_{35} lntext{fedfunds}_{t-2} + a_{36} lntext{unempl}_{t-2} &+ gamma_3 t + u_{3t} finish{aligned}$$

/*
** Specifying the mannequin
*/
// Three endogenous variable
// No exogenous variables  
formulation = "lninflat + lnunempl + lnfedfunds";

// Specify variety of lags
lags = 2;

// Embody fixed
const = 1;

Step Three: Arrange Signal Restrictions

To arrange signal restrictions we have to:

  1. Specify signal restrictions because the identification technique utilizing the ident enter.
  2. Arrange the signal restriction matrix utilizing the irf.signRestrictions member of the svarControl construction.
  3. Outline the restricted shock variables and the restriction horizon utilizing the irf.restrictedShock and irf.restrictionHorizon members of the svarControl construction.
/*
** Signal restriction setup
*/
// Specify identication technique
ident = "signal";

// Declare controls construction
// Fill with defaults
struct svarControl Sctl;
Sctl = svarControlCreate();

// Specify to make use of signal restrictions
Sctl.irf.ident = "signal";

// Specify which shock variable is restricted
Sctl.irf.restrictedShock = { 1, 2, 3 };

// Arrange restrictions horizon
Sctl.irf.restrictionHorizon = { 1, 1, 1 };

// Arrange restrictions matrix
// A row for every shock, and a column for every variable
//             lninflat     lnunempl     lnfedfunds
// shock           
// provide          -           -             -
// demand          +           -             +
// financial        -           +             +
Sctl.irf.signRestrictions = { -1  1 -1,
                               1 -1  1,
                              -1  1  1 };

Step 4: Estimate Mannequin

Lastly, we estimate our mannequin utilizing svarFit.

/*
** Estimate VAR mannequin
*/
struct svarOut sOut;
sOut = svarFit(data_shortrun, formulation, ident, const, lags, Sctl);

Calling the svarFit process hundreds the svarOut construction with outcomes and robotically prints outcomes to the display.

=====================================================================================================
Mannequin:                      SVAR(2)                               Variety of Eqs.:                   3
Time Span:              1960-01-01:                               Legitimate instances:                    162
                        2000-10-01                                                                   
Log Probability:             406.137                               AIC:                        -13.305
                                                                  SBC:                        -12.962
=====================================================================================================
Equation                             R-sq                  DW                 SSE                RMSE

lninflat                          0.76855             2.10548            17.06367             0.33180 
lnunempl                          0.97934             4.92336             0.21507             0.03725 
lnfedfunds                        0.94903             2.30751             1.80772             0.10799 
=====================================================================================================
Outcomes for lowered type equation lninflat
=====================================================================================================
          Coefficient            Estimate           Std. Err.             T-Ratio          Prob |>| t
-----------------------------------------------------------------------------------------------------

             Fixed             0.06817             0.20780             0.32804             0.74332 
        lninflat L(1)             0.59712             0.07736             7.71851             0.00000 
        lnunempl L(1)            -1.14092             0.67732            -1.68448             0.09410 
      lnfedfunds L(1)             0.30207             0.25870             1.16765             0.24474 
        lninflat L(2)             0.25045             0.08002             3.12976             0.00209 
        lnunempl L(2)             1.05780             0.65416             1.61703             0.10790 
      lnfedfunds L(2)            -0.16005             0.26135            -0.61237             0.54119 
=====================================================================================================
Outcomes for lowered type equation lnunempl
=====================================================================================================
          Coefficient            Estimate           Std. Err.             T-Ratio          Prob |>| t
-----------------------------------------------------------------------------------------------------

             Fixed             0.01819             0.02333             0.77975             0.43673 
        lninflat L(1)             0.01173             0.00869             1.35062             0.17878 
        lnunempl L(1)             1.55876             0.07604            20.49928             0.00000 
      lnfedfunds L(1)             0.01946             0.02904             0.66991             0.50391 
        lninflat L(2)            -0.00899             0.00898            -1.00024             0.31875 
        lnunempl L(2)            -0.59684             0.07344            -8.12681             0.00000 
      lnfedfunds L(2)             0.00563             0.02934             0.19193             0.84805 
=====================================================================================================
Outcomes for lowered type equation lnfedfunds
=====================================================================================================
          Coefficient            Estimate           Std. Err.             T-Ratio          Prob |>| t
-----------------------------------------------------------------------------------------------------

             Fixed             0.16038             0.06764             2.37124             0.01896 
        lninflat L(1)             0.02722             0.02518             1.08115             0.28131 
        lnunempl L(1)            -1.14540             0.22046            -5.19558             0.00000 
      lnfedfunds L(1)             1.03509             0.08420            12.29300             0.00000 
        lninflat L(2)             0.04302             0.02605             1.65183             0.10059 
        lnunempl L(2)             1.09553             0.21292             5.14528             0.00000 
      lnfedfunds L(2)            -0.12063             0.08507            -1.41801             0.15820 
=====================================================================================================

Step 5: Visualize Dynamics

As soon as our mannequin is estimated, we will achieve perception into the system’s dynamics by plotting:

  1. Impulse response features.
  2. Forecast error variance decompositions.

First, let us take a look at the responses to a requirement shock (lnunempl):

/*
** Visualizing dynamics
*/
// Plot IRFs of `lnunempl` shock 
plotIRF(sOut, "lnunempl", 1);

// Plot FEVDs of `lnunempl` shock
plotFEVD(sOut, "lnunempl", 1);

The plotIRF process generates a grid plot of IRF to a shock :

The plotFEVD process generates an space plot of the FEVD:
Factor error variance decompositions following a demand shock using sign restricted SVAR.

What Do We See within the IRF and FEVD Plots?

The dynamic responses to a requirement shock in lnunempl present helpful insights into how the system behaves over time. Beneath, we spotlight key observations from the forecast error variance decompositions (FEVDs) and impulse response features (IRFs).

Forecast Error Variance Decomposition (FEVD)

The FEVD plot exhibits the contribution of every variable to the forecast variance of lnunempl over time:

  • Within the brief run (intervals 0–2), lnunempl itself accounts for a lot of the variation.
  • Because the forecast horizon will increase, the function of lninflat grows, finally contributing round 40% of the variation.
  • The biggest and most persistent contribution comes from lnfedfunds, which stabilizes above 45%, highlighting its long-term affect on unemployment dynamics.
  • The share of lnunempl decreases steadily, dropping under 20% in later intervals—suggesting that exterior variables clarify extra of the variation over time.

Impulse Response Features (IRFs)

The IRFs to a shock in lnunempl show the dynamic responses of every variable within the system:

  • lninflat responds positively with a hump-shaped profile. It peaks round interval 4–5 earlier than regularly returning to baseline.
  • lnunempl initially declines however then reverses and will increase barely, indicating a short-run drop adopted by a modest rebound.
  • lnfedfunds responds sharply with a peak round interval 4, suggesting a financial tightening response. The response tapers off over time however stays constructive.

These dynamics are in keeping with a demand-driven shock: falling unemployment places upward strain on inflation and triggers a rise in rates of interest.

Step Six: Analyze Historic Decomposition

Subsequent, we’ll study the historic decomposition of the lnunempl variable. Historic decompositions enable us to interrupt down the noticed actions in a variable over time into contributions from every structural shock recognized within the mannequin.

This supplies worthwhile perception into which shocks have been most influential throughout particular intervals and helps clarify how demand, provide, and financial coverage shocks have formed the trail of unemployment.

// Plot HDs for `lnunempl` 
plotHD(sOut, "lnunempl", 1);

The plotHD process generates a time-series bar plot of the HD:
Historical decompositions of unemployment using a sign restricted SVAR.

What We See within the HD Plot?

The HD plot exhibits the time-varying contributions of every structural shock to fluctuations in lnunempl:

  • Inflation shocks (lninflat) clarify a big share of unemployment will increase within the center portion of the pattern. Their contribution is usually constructive throughout that interval, suggesting inflationary strain performed a task in elevating unemployment.

  • Unemployment shocks (lnunempl) dominate early and late intervals of the pattern. These are possible capturing idiosyncratic or residual variation not defined by the opposite two shocks.

  • Federal funds charge shocks (lnfedfunds) play a extra modest however noticeable function throughout downturns. Their affect is mostly adverse, suggesting that financial tightening helped cut back unemployment volatility in these home windows.

General, the decomposition illustrates that no single shock dominates all through all the pattern. Completely different drivers form the evolution of unemployment relying on the macroeconomic context.

Conclusion

At this time’s weblog demonstrates how signal restriction identification in SVAR fashions can present significant insights into the structural dynamics behind key macroeconomic variables.

Utilizing economically motivated signal restrictions, we have been in a position:

  • Uncover and interpret the dynamic responses to completely different shocks.
  • Visualize the relative significance of every shock over time.
  • Hint the evolving drivers of unemployment via historic decomposition.

These findings present how SVAR fashions, when mixed with versatile identification methods like signal restrictions, supply a robust framework for modeling complicated macroeconomic interactions.

Additional Studying

  1. Introduction to the Fundamentals of Time Sequence Knowledge and Evaluation
  2. Introduction to the Fundamentals of Vector Autoregressive Fashions
  3. The Instinct Behind Impulse Response Features and Forecast Error Variance Decomposition
  4. Introduction to Granger Causality
  5. Understanding and Fixing the Structural Vector Autoregressive Identification Drawback
  6. The Structural VAR Mannequin at Work: Analyzing Financial Coverage

Attempt Out GAUSS TSMT 4.0

[ad_2]

Touring New CSS Options in Safari 26

0

[ad_1]

A few days in the past, the Apple workforce launched Safari 26.0! Is it an enormous deal? I imply, browsers launch new variations on a regular basis, the place they sprinkle in a pair or few new options. They’re, after all, all helpful, however there aren’t normally a number of “huge leaps” between variations. Safari 26 is completely different, although. It introduces a lot of recent stuff. To be exact, it provides: 75 new options, 3 deprecations, and 171 different enhancements.

I’d formally name {that a} huge deal.

The WebKit weblog put up does a tremendous job breaking down every of the brand new (not solely CSS) options. However once more, there are such a lot of that the brand new stuff coming to CSS deserves its personal highlight. So, immediately I wish to test (and in addition attempt) what I feel are essentially the most fascinating options coming to Safari.

If you’re like me and don‘t have macOS to check Safari, you’ll be able to use Playwright as an alternative.

What’s new (to Safari)?

Safari 26 introduces a number of options you could already know from prior Chrome releases. And… I can’t blame Safari for seemingly lagging behind as a result of Chrome is delivery new CSS at a scarily quick tempo. I recognize that browsers stagger releases to allow them to refine issues towards one another. Keep in mind when Chrome initially shipped position-area as inset-area? We bought higher naming between the 2 implementations.

I feel what you’ll discover (as I did) that many of those overlapping options are a part of the larger effort in direction of Interop 2025, one thing WebKit is dedicated to. So, let’s look particularly at what’s new in Safari 26… at the very least that’s new to Safari.

Anchor positioning

Anchor positioning is one among my favourite options (I wrote the information on it!), so I’m so glad it’s arrived in Safari. We at the moment are one step nearer to extensively accessible assist which suggests we’re that a lot nearer to utilizing anchor positioning in our manufacturing work.

With CSS Anchor Positioning, we will connect an absolutely-positioned ingredient (that we could name a “goal”) to a different ingredient (that we could name an “anchor”). This makes creating issues like tooltips, modals, and pop-ups trivial in CSS, though it may be used for a number of layouts.

Utilizing anchor positioning, we will connect any two components, like these, collectively. It doesn’t even matter the place they’re within the markup.

anchor

goal

Heads up: Though the supply order doesn’t matter for positioning, it does for accessibility, so it’s a good suggestion to determine a relationship between the anchor and goal utilizing ARIA attributes for higher experiences that depend on assistive tech.

We register the .anchor ingredient utilizing the anchor-name property, which takes a dashed ident. We then use that ident to connect the .goal to the .anchor utilizing the position-anchor property.

.anchor {
  anchor-name: --my-anchor; /* the ident */
}

.goal {
  place: absolute;
  position-anchor: --my-anchor; /* hooked up! */
}

This positions the .goal on the heart of the .anchor — once more, irrespective of the supply order! If we wish to place it someplace else, the best means is utilizing the position-area property.

With position-area, we will outline a area round the .anchor and place the .goal in it. Consider it like drawing a grid of squares which might be mapped to the .anchor‘s heartprimeproperbackside and left.

For instance, if we want to place the goal on the anchor’s top-right nook, we will write…

.goal {
  /* ... */
  position-area: prime proper;
}

That is only a style since anchor positioning is a world unto itself. I’d encourage you to learn our full information on it.

Scroll-driven animations

Scroll-driven animations hyperlink CSS animations (created from @keyframes) to a component’s scroll place. So as an alternative of operating an animation for a given time, the animation will depend upon the place the person scrolls.

We will hyperlink an animation to 2 varieties of scroll-driven occasions:

  • Linking the animation to a scrollable container utilizing the scroll() operate.
  • Linking the animation to a component’s place on the viewport utilizing the view() operate.

Each of those capabilities are used contained in the animation-timeline, which hyperlinks the animation progress to the kind of timeline we’re utilizing, be it scroll or view. What’s the distinction?

With scroll(), the animation runs because the person scrolls the web page. The best instance is a kind of studying bars that you simply would possibly see develop as you learn down the web page. First, we outline our on a regular basis animation and add it to the bar ingredient:

@keyframes develop {
  from {
    remodel: scaleX(0);
  }
  to {
    remodel: scaleX(1);
  }
}

.progress {
  transform-origin: left heart;
  animation: develop linear;
}

Observe: I’m setting transform-origin to left so it the animation progresses from the left as an alternative of increasing from the middle.

Then, as an alternative of giving the animation a length, we will plug it into the scroll place like this:

.progress {
  /* ... */
  animation-timeline: scroll();
}

Assuming you’re utilizing Safari 26 or the newest model of Chrome, the bar grows in width from left to proper as you scroll down the viewport.

The view() operate is analogous, nevertheless it bases the animation on the ingredient’s place when it’s in view of the viewport. That means, an animation can begin or cease at particular factors on the web page. Right here’s an instance making pictures “pop” up as they enter view.

@keyframes popup {
  from {
    opacity: 0;
    remodel: translateY(100px);
  }
  to {
    opacity: 1;
    remodel: translateY(0px);
  }
}

img {
  animation: popup linear;
}

Then, to make the animation progress because the ingredient enters the viewport, we plug the animation-timeline to view().

img {
    animation: popup linear;
    animation-timeline: view();
}

If we depart like this, although, the animation ends simply because the ingredient leaves the display. The person doesn’t see the entire thing! What we wish is for the animation to finish when the person is in the midst of the viewport so the complete timeline runs in view.

That is the place we will attain for the animation-range property. It lets us set the animation’s begin and finish factors relative to the viewport. On this particular instance, let’s say I need the animation to begin when the ingredient enters the display (i.e., the 0% mark) and finishes just a little bit earlier than it reaches the direct heart of the viewport (we’ll say 40%):

img {
  animation: popup linear;
  animation-timeline: view();
  animation-range: 0% 40%;
}

As soon as once more, scroll-driven animations go means past these two fundamental examples. For a fast intro to all there’s to them, I like to recommend Geoff’s notes.

I really feel safer utilizing scroll-drive animations in my manufacturing work as a result of it’s extra of a progressive enhancement that gained’t break an expertise even when it isn’t supported by the browser. Even so, somebody could choose lowered (or no) animation in any respect, that means we’d higher progressively improve it anyway with prefers-reduced-motion.

The progress() operate

That is one other function we bought in Chrome that has made its method to Safari 26. Humorous sufficient, I missed it in Chrome when it launched a number of months in the past, so it makes me twice as glad to see such a useful function baked into two main browsers.

The progress() operate tells you ways a lot a worth has progressed in a variety between a place to begin and an ending level:

progress(, , )

If the is lower than the , the result’s 0. If the reaches the , the result’s 1. Something in between returns a decimal between 0 and 1.

Technically, that is one thing we will already do in a calc()-ulation:

calc((worth - begin) / (finish - begin))

However there’s a key distinction! With progress(), we will calculate values from blended information varieties (like including px to rem), which isn’t presently potential with calc(). For instance, we will get the progress worth formatted in viewport models from a numeric vary formatted in pixels:

progress(100vw, 400px, 1000px);

…and it’ll return 0 when the viewport is 400px, and because the display grows to 1000px, it progresses to 1. This implies it could typecast completely different models right into a quantity, and as a consequence, we will transition properties like opacity (which takes a quantity or proportion) based mostly on the viewport (which is a distance size).

There’s one other workaround that accomplishes this utilizing tan() and atan2() capabilities. I’ve used that method earlier than to create easy viewport transitions. However progress() drastically simplifies the work, making it way more maintainable.

Living proof: We will orchestrate a number of animations because the display measurement adjustments. This subsequent demo takes one of many demos I made for the article about tan() and atan2(), however swaps that out with progress(). Works like a attraction!

That’s a reasonably wild instance. One thing extra sensible is perhaps decreasing a picture’s opacity because the display shrinks:

img {
  opacity: clamp(0.25, progress(100vw, 400px, 1000px), 1);
}

Go forward and resize the demo to replace the picture’s opacity, assuming you’re taking a look at it in Safari 26 or the newest model of Chrome.

I’ve clamp()-ed the progress() between 0.25 and 1. However, by default, progress() already clamps the between 0 and 1. In response to the WebKit launch notes, the present implementation isn’t clamped by default, however upon testing, it does appear to be. So, in the event you’re questioning why I’m clamping one thing that’s supposedly clamped already, that’s why.

An unclamped model could come sooner or later, although.

Self-alignment in absolute positioning

And, hey, test this out! We will align-self and justify-self content material inside absolutely-positioned components. This isn’t as huge a deal as the opposite options we’ve checked out, nevertheless it does have a useful use case.

For instance, I typically wish to place an absolutely-positioned ingredient straight within the heart of the viewport, however inset-related properties (i.e., primeproperbacksideleft, and so on.) are relative to the ingredient’s top-left nook. Which means we don’t get completely centered with one thing like this as we’d anticipate:

.absolutely-positioned {
  place: absolute;
  prime: 50%;
  left: 50%;
}

From right here, we might translate the ingredient by half to get issues completely centered. However now we’ve the heart key phrase supported by align-self and justify-self, that means fewer shifting items within the code:

.absolutely-positioned {
  place: absolute;
  justify-self: heart;
}

Weirdly sufficient, I seen that align-self: heart doesn’t appear to heart the ingredient relative to the viewport, however as an alternative relative to itself. I came upon that may use the anchor-center worth to heart the ingredient relative to its default anchor, which is the viewport on this particular instance:

.absolutely-positioned {
  place: absolute;
  align-self: anchor-center;
  justify-self: heart;
}

And, after all, place-self is a shorthand for the align-self and justify-self properties, so we might mix these for brevity:

.absolutely-positioned {
  place: absolute;
  place-self: anchor-center heart;
}

What’s new (for the online)?

Safari 26 isn’t nearly maintaining with Chrome. There’s a number of thrilling new stuff in right here that we’re getting our fingers on for the primary time, or that’s refined from different browser implementations. Let’s have a look at these options.

The constrast-color() operate

The constrast-color() isn’t new by any means. It’s really been in Safari Expertise Preview since 2021 the place it was initially referred to as color-contrast(). In Safari 26, we get the up to date naming in addition to some polish.

Given a sure colour worth, contrast-color() returns both white or black, whichever produces a sharper distinction with that colour. So, if we had been to offer coral as the colour worth for a background, we will let the browser determine whether or not the textual content colour is extra contrasted with the background as both white or black:

h1 {
  --bg-color: coral;
  background-color: var(--bg-color);
  colour: contrast-color(var(--bg-color));
}

Our personal Daniel Schwarz lately explored the contrast-color() operate and located it’s really not that nice at figuring out the perfect distinction between colours:

Undoubtedly, the primary shortcoming is that contrast-color() solely resolves to both black or white. When you don’t need black or white, properly… that sucks.

It sucks as a result of there are instances the place neither white nor black produces sufficient distinction with the offered colour to fulfill WCAG colour distinction pointers. There may be an intent to increase contrast-color() so it could return extra colour values, however there nonetheless can be considerations about how precisely contrast-color() arrives on the “greatest” colour, since we might nonetheless must think about the font’s width, measurement, and even household. All the time test the precise distinction!

So, whereas it’s nice to lastly have constrat-color(), I do hope we see enhancements added sooner or later.

Fairly textual content wrapping

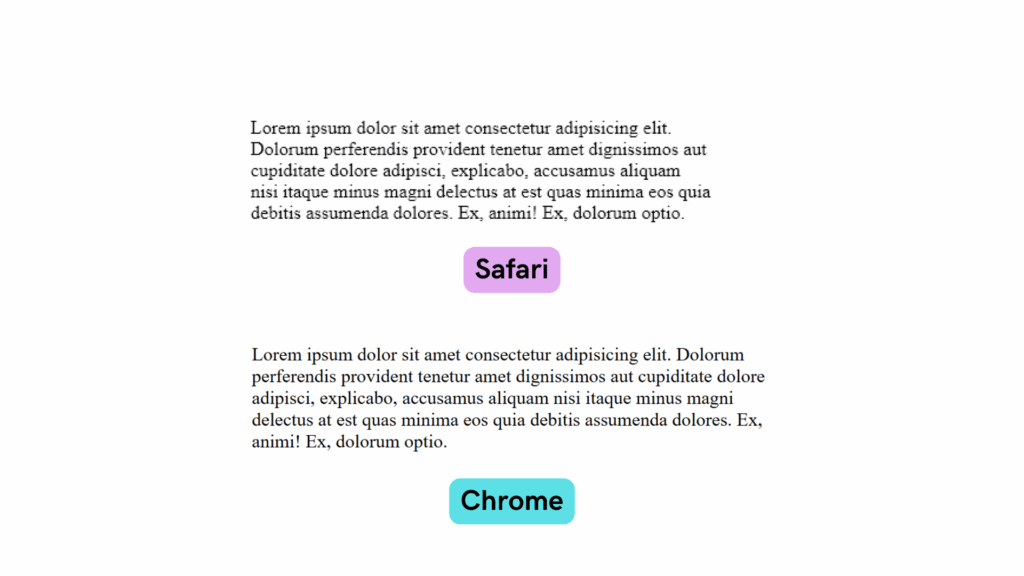
Safari 26 additionally introduces text-wrap: fairly, which is fairly (get it?) easy: it makes paragraphs wrap in a prettier means.

You could keep in mind that Chrome shipped this again in 2023. However take discover that there’s a fairly (OK, that’s the final time) huge distinction between the implementations. Chrome solely avoids typographic orphans (brief final strains). Safari does extra to prettify the way in which textual content wraps:

  • Prevents brief strains. Avoids single phrases on the finish of the paragraph.
  • Improves rag. Retains every line comparatively the identical size.
  • Reduces hyphenation. When enabled, hyphenation improves rag but in addition breaks phrases aside. Usually, hyphenation needs to be stored to a minimal.

The WebKit weblog will get into a lot better element in the event you’re inquisitive about what issues they put into it.

Comparing the same paragraph of text wrapping in Safari and Chrome using text-wrap: pretty. They produce different results.
Safari takes extra actions to make sure “fairly” textual content wrapping, together with the general ragging alongside the textual content.

That is just the start!

I feel these are all of the CSS options coming to Safari that you must look out for, however I don’t need you to assume they’re the one options within the launch. As I discussed on the prime, we’re speaking about 75 new Net Platform options, together with HDR Pictures, assist for SVG favicons, logical property assist for overflow properties, margin trimming, and far, way more. It’s price perusing the full launch notes.

[ad_2]

CPEP: Contrastive Pose-EMG Pre-training Enhances Gesture Generalization on EMG Indicators

0

[ad_1]

This paper was accepted on the Basis Fashions for the Mind and Physique Workshop at NeurIPS 2025.

Hand gesture classification utilizing high-quality structured information corresponding to movies, pictures, and hand skeletons is a well-explored downside in laptop imaginative and prescient. Leveraging low-power, cost-effective biosignals, e.g. floor electromyography (sEMG), permits for steady gesture prediction on wearables. On this paper, we exhibit that studying representations from weak-modality information which are aligned with these from structured, high-quality information can enhance illustration high quality and permits zero-shot classification. Particularly, we suggest a Contrastive Pose-EMG Pre-training (CPEP) framework to align EMG and pose representations, the place we be taught an EMG encoder that produces high-quality and pose-informative representations. We assess the gesture classification efficiency of our mannequin via linear probing and zero-shot setups. Our mannequin outperforms emg2pose benchmark fashions by as much as 21% on in-distribution gesture classification and 72% on unseen (out-of-distribution) gesture classification.

[ad_2]

Azure File Sync: A Sensible, Examined Deployment Playbook for ITPros.

0

[ad_1]


This submit distills that 10‑minute drill right into a step‑by‑step, battle‑examined playbook you possibly can run in your personal surroundings, full with the “gotchas” that journey people up, why they occur, and the way to keep away from them. However first…

  1. Hybrid File Companies: Cloud Meets On-Prem

Azure File Sync helps you to centralize your group’s file shares in Azure Recordsdata whereas conserving the pliability, efficiency, and compatibility of your current Home windows file servers. You may preserve a full copy of your information domestically or use your Home windows Server as a quick cache to your Azure file share. This implies you get cloud scalability and resilience, however customers nonetheless take pleasure in native efficiency and acquainted protocols (SMB, NFS, FTPS). 

  1. Cloud Tiering: Optimize Storage Prices

With cloud tiering, your most ceaselessly accessed recordsdata are cached domestically, whereas less-used recordsdata are tiered to the cloud. You management how a lot disk area is used for caching, and tiered recordsdata might be recalled on-demand. This lets you cut back on-prem storage prices with out sacrificing consumer expertise. 

  1. Multi-Web site Sync: International Collaboration

Azure File Sync is right for distributed organizations. You may provision native Home windows Servers in every workplace, and adjustments made in a single location mechanically sync to all others. This simplifies file administration and allows sooner entry for cloud-based apps and companies. 

  1. Enterprise Continuity and Catastrophe Restoration

Azure Recordsdata gives resilient, redundant storage, so your native server turns into a disposable cache. If a server fails, you merely add a brand new server to your Azure File Sync deployment, set up the agent, and sync. Your file namespace is downloaded first, so customers can get again to work rapidly. You can too use heat standby servers or Home windows Clustering for even sooner restoration. 

  1. Cloud-Facet Backup

Notice:  Azure File Sync is NOT a backup resolution….   However, you ca cut back on-prem backup prices by taking centralized backups within the cloud utilizing Azure Backup. Azure file shares have native snapshot capabilities, and Azure Backup can automate scheduling and retention. Restores to the cloud are mechanically downloaded to your Home windows Servers. 

  1. Seamless Migration

Azure File Sync allows seamless migration of on-prem file information to Azure Recordsdata. You may sync current file servers with Azure Recordsdata within the background, shifting information with out disrupting customers or altering entry patterns. File construction and permissions stay intact, and apps proceed to work as anticipated. 

  1. Efficiency, Safety, and Compatibility

Latest enhancements have boosted Azure File Sync’s efficiency (as much as 200 gadgets/sec), and it now helps Home windows Server 2025 and integrates with Home windows Admin Heart for unified administration. Managed identities and Energetic Listing-based authentication are supported for safe, keyless entry. 

  1. Actual-World Use Circumstances
    • Department Workplace Consolidation: A number of websites, every with its personal file server, might be consolidated right into a central Azure File Share whereas sustaining native efficiency. 
    • Enterprise Continuity: Corporations going through threats like pure disasters use Azure File Sync to enhance server restoration occasions and guarantee uninterrupted work. 
    • Collaboration: Organizations leverage Azure File Sync for quick, safe collaboration throughout areas, decreasing latency and simplifying IT administration. 
  • Inadequate permissions throughout cloud endpoint creation“Function project creation failed.” You want Proprietor or the Azure File Sync Administrator constructed‑in function; Contributor isn’t sufficient as a result of the workflow should create function assignments.
  • Area mismatches → Your file share and Storage Sync Service should dwell in the identical area because the deployment goal.
  • Flawed identification/account → In the event you’re signed into the improper tenant or account mid‑portal (straightforward to do), the wizard fails when it tries to create the cloud endpoint. Change to the account that truly has the required function and retry.
  • Agent/model points → An previous agent in your Home windows Server will trigger registration or enumeration issues. Use the newest agent and take into account auto‑improve to remain present.
  • Networking & entry keys → Guarantee entry keys are enabled on the storage account and required outbound URLs/ports are allowed.
  • Operational expectations → Azure File Sync runs on a roughly 24‑hour change detection cycle by default; for DR drills or speedy wants, set off change detection through PowerShell. And bear in mind: File Sync will not be a backup. Again up the storage account. 

1) Conditions (don’t skip these) 

  • Storage account supporting SMB 3.1.1 (and required authentication settings), with entry keys enabled. Create your Azure file share within the similar area as your File Sync deployment. Set up a transparent naming conference
  • Home windows Server for the File Sync agent (instance: Home windows Server 2019)
  • Identification & Entry: Assign both Proprietor or Azure File Sync Administrator (a least‑privilege constructed‑in function designed particularly for this state of affairs). Contributor will allow you to get partway (storage account, Storage Sync Service) however will fail when creating the cloud endpoint as a result of it will possibly’t create function assignments.

2) Lay down the cloud aspect 

  • Within the Azure portal, create the file share in your chosen storage account/area.
  • Create a Storage Sync Service (ideally in a devoted useful resource group), once more guaranteeing the area is appropriate and supported to your wants.

3) Prep the server 

  • In your Home windows Server, set up the Azure File Sync agent (newest model). Throughout setup, take into account enabling auto‑improve; if the server is down throughout a scheduled improve, it catches up on the subsequent boot, conserving you present with safety and bug fixes.
  • Register the server to your Storage Sync Service (choose subscription, useful resource group, and repair). In case you have a number of subscriptions, the portal can sometimes conceal one, PowerShell is another path if wanted. 

4) Create the sync topology 

  • Within the Storage Sync Service, create a Sync Group. That is the container for each cloud and server endpoints. Below regular circumstances, the cloud endpoint is created mechanically when you choose the storage account + file share.
  • In the event you hit “function project creation failed” right here, confirm your signed‑in account and function. Switching again to the account with the correct function resolves it; you possibly can then recreate the cloud endpoint inside the present Sync Group.
  • Add a server endpoint: decide the registered server (it should present up within the drop‑down, if it doesn’t, registration isn’t full) and the native path to sync.

5) Cloud tiering & preliminary sync conduct 

  • Cloud tiering retains scorching information domestically and stubs colder information to preserve area. In the event you disable cloud tiering, you’ll preserve a full native copy of all recordsdata.
  • If enabled, set the Quantity Free House Coverage (how a lot free area to protect on the quantity) and assessment recall coverage implications. Select the preliminary sync mode, merge current content material or overwrite.

6) Ops, monitoring, and DR notes 

  • Change detection cadence is roughly 24 hours. For DR exams or pressing cutovers, run the change detection PowerShell command to speed up discovery of adjustments.
  • Backups: Azure File Sync will not be a backup. Defend your storage account utilizing your normal backup technique.
  • Networking: Enable required outbound ports/URLs; validate company proxies/firewalls.
  • Monitoring: Activate the logging and monitoring you want for telemetry and auditing. 

7) Efficiency & value planning 

  • Consider Provisioned v2 storage accounts to dial in IOPS/throughput to your corporation wants and acquire higher pricing predictability. It’s a wise time to resolve this up entrance throughout a brand new deployment.

8) Identification choices & least privilege 

  • You can too arrange managed identities for File Sync to cut back reliance on consumer principals. In the event you do use consumer accounts, guarantee they carry the Azure File Sync Administrator function or Proprietor. Hold the agent up to date; it’s primary hygiene that stops a stunning variety of points.

9) Quotas & capability troubleshooting 

  • Hitting quota issues? Revisit your Quantity Free House Coverage (cloud tiering) and recall coverage. Typically the reply is solely including a disk or growing its dimension as information patterns evolve.
  • Hybrid file companies with out forklift: Hold your current Home windows file servers whereas centralizing information in Azure Recordsdata, including elasticity and resiliency with minimal disruption .
  • Proper‑sized capability on‑prem: Cloud tiering preserves native efficiency for decent information and trims chilly information footprint to stretch on‑prem storage additional.
  • Operational predictability: Constructed‑in auto‑improve for the agent and a identified change detection cycle, with the flexibility to power change detection for DR/failover testing.
  • Least‑privilege by design: The Azure File Sync Administrator function provides simply the rights wanted to deploy/handle sync with out over‑provisioning.
  • Efficiency in your phrases: Choice to decide on Provisioned v2 to satisfy IOPS/throughput targets and convey value readability.
  1. Confirm roles: On the goal subscription/useful resource group, grant Azure File Sync Administrator (or Proprietor) to your deployment identification. Affirm in Entry management (IAM).
  2. Create the file share within the similar area as your Storage Sync Service. Allow entry keys on the storage account.
  3. Set up the newest agent in your Home windows Server; allow auto‑improve. Register the server to your Storage Sync Service.
  4. Create a Sync Group, then the cloud endpoint. In the event you see a function project error, re‑test your signed‑in account/function and retry.
  5. Add the server endpoint with the fitting path, resolve on cloud tiering, set Quantity Free House Coverage, and select preliminary sync conduct (merge vs overwrite).
  6. Open required egress in your community gadgets, allow monitoring/logging, and plan backup for the storage account.
  7. Optionally consider Provisioned v2 for throughput/IOPS and predictable pricing earlier than shifting to manufacturing.

 In the event you’ve received a state of affairs that behaves in another way within the subject, I wish to hear about it. Drop me a observe with what you tried, what failed, and the place within the movement it occurred.

Cheers!

Pierre

[ad_2]

Introducing Keras 3 for R

[ad_1]

We’re thrilled to introduce keras3, the following model of the Keras R
bundle. keras3 is a ground-up rebuild of {keras}, sustaining the
beloved options of the unique whereas refining and simplifying the API
based mostly on helpful insights gathered over the previous few years.

Keras gives an entire toolkit for constructing deep studying fashions in
R—it’s by no means been simpler to construct, practice, consider, and deploy deep
studying fashions.

Set up

To put in Keras 3:

https://keras.posit.co. There, you can find guides, tutorials,
reference pages with rendered examples, and a brand new examples gallery. All
the reference pages and guides are additionally out there by way of R’s built-in assist
system.

In a fast-paced ecosystem like deep studying, creating nice
documentation and wrappers as soon as will not be sufficient. There additionally must be
workflows that make sure the documentation is up-to-date with upstream
dependencies. To perform this, {keras3} consists of two new maintainer
options that make sure the R documentation and performance wrappers will keep
up-to-date:

  • We now take snapshots of the upstream documentation and API floor.
    With every launch, all R documentation is rebased on upstream
    updates. This workflow ensures that each one R documentation (guides,
    examples, vignettes, and reference pages) and R perform signatures
    keep up-to-date with upstream. This snapshot-and-rebase
    performance is carried out in a brand new standalone R bundle,
    {doctether}, which can
    be helpful for R bundle maintainers needing to maintain documentation in
    parity with dependencies.

  • All examples and vignettes can now be evaluated and rendered throughout
    a bundle construct. This ensures that no stale or damaged instance code
    makes it right into a launch. It additionally means all person dealing with instance code
    now moreover serves as an prolonged suite of snapshot unit and
    integration exams.

    Evaluating code in vignettes and examples continues to be not permitted
    in response to CRAN restrictions. We work across the CRAN restriction
    by including extra bundle construct steps that pre-render
    examples
    and
    vignettes.

Mixed, these two options will make it considerably simpler for Keras
in R to keep up characteristic parity and up-to-date documentation with the
Python API to Keras.

Multi-backend assist

Quickly after its launch in 2015, Keras featured assist for hottest
deep studying frameworks: TensorFlow, Theano, MXNet, and CNTK. Over
time, the panorama shifted; Theano, MXNet, and CNTK have been retired, and
TensorFlow surged in reputation. In 2021, three years in the past, TensorFlow
grew to become the premier and solely supported Keras backend. Now, the panorama
has shifted once more.

Keras 3 brings the return of multi-backend assist. Select a backend by
calling:

200
features
,
gives a complete suite of operations sometimes wanted when
working on nd-arrays for deep studying. The Operation household
supersedes and significantly expands on the previous household of backend features
prefixed with k_ within the {keras} bundle.

The Ops features allow you to write backend-agnostic code. They supply a
uniform API, no matter should you’re working with TensorFlow Tensors,
Jax Arrays, Torch Tensors, Keras Symbolic Tensors, NumPy arrays, or R
arrays.

The Ops features:

  • all begin with prefix op_ (e.g., op_stack())
  • all are pure features (they produce no side-effects)
  • all use constant 1-based indexing, and coerce doubles to integers
    as wanted
  • all are protected to make use of with any backend (tensorflow, jax, torch, numpy)
  • all are protected to make use of in each keen and graph/jit/tracing modes

The Ops API consists of:

  • The whole thing of the NumPy API (numpy.*)
  • The TensorFlow NN API (tf.nn.*)
  • Widespread linear algebra features (A subset of scipy.linalg.*)
  • A subfamily of picture transformers
  • A complete set of loss features
  • And extra!

Ingest tabular knowledge with layer_feature_space()

keras3 gives a brand new set of features for constructing fashions that ingest
tabular knowledge: layer_feature_space() and a household of characteristic
transformer features (prefix, feature_) for constructing keras fashions
that may work with tabular knowledge, both as inputs to a keras mannequin, or
as preprocessing steps in a knowledge loading pipeline (e.g., a
tfdatasets::dataset_map()).

See the reference
web page
and an
instance utilization in a full end-to-end
instance

to be taught extra.

New Subclassing API

The subclassing API has been refined and prolonged to extra Keras
varieties
.
Outline subclasses just by calling: Layer(), Loss(), Metric(),
Callback(), Constraint(), Mannequin(), and LearningRateSchedule().
Defining {R6} proxy courses is not vital.

Moreover the documentation web page for every of the subclassing
features now accommodates a complete itemizing of all of the out there
attributes and strategies for that kind. Try
?Layer to see what’s
doable.

Saving and Export

Keras 3 brings a brand new mannequin serialization and export API. It’s now a lot
easier to save lots of and restore fashions, and in addition, to export them for
serving.

  • save_model()/load_model():
    A brand new high-level file format (extension: .keras) for saving and
    restoring a full mannequin.

    The file format is backend-agnostic. This implies which you can convert
    skilled fashions between backends, just by saving with one backend,
    after which loading with one other. For instance, practice a mannequin utilizing Jax,
    after which convert to Tensorflow for export.

  • export_savedmodel():
    Export simply the ahead go of a mannequin as a compiled artifact for
    inference with TF
    Serving
    or (quickly)
    Posit Join. This
    is the best approach to deploy a Keras mannequin for environment friendly and
    concurrent inference serving, all with none R or Python runtime
    dependency.

  • Decrease stage entry factors:

    • save_model_weights() / load_model_weights():
      save simply the weights as .h5 recordsdata.
    • save_model_config() / load_model_config():
      save simply the mannequin structure as a json file.
  • register_keras_serializable():
    Register customized objects to allow them to be serialized and
    deserialized.

  • serialize_keras_object() / deserialize_keras_object():
    Convert any Keras object to an R record of straightforward varieties that’s protected
    to transform to JSON or rds.

  • See the brand new Serialization and Saving
    vignette

    for extra particulars and examples.

New random household

A brand new household of random tensor
mills
.
Just like the Ops household, these work with all backends. Moreover, all of the
RNG-using strategies have assist for stateless utilization whenever you go in a
seed generator. This permits tracing and compilation by frameworks that
have particular assist for stateless, pure, features, like Jax. See
?random_seed_generator()
for instance utilization.

Different additions:

  • New form()
    perform, one-stop utility for working with tensor shapes in all
    contexts.

  • New and improved print(mannequin) and plot(mannequin) methodology. See some
    examples of output within the Useful API
    information

  • All new match() progress bar and stay metrics viewer output,
    together with new dark-mode assist within the RStudio IDE.

  • New config
    household
    ,
    a curated set of features for getting and setting Keras world
    configurations.

  • All the different perform households have expanded with new members:

Migrating from {keras} to {keras3}

{keras3} supersedes the {keras} bundle.

In the event you’re writing new code in the present day, you can begin utilizing {keras3} proper
away.

In case you have legacy code that makes use of {keras}, you’re inspired to
replace the code for {keras3}. For a lot of high-level API features, such
as layer_dense(), match(), and keras_model(), minimal to no modifications
are required. Nevertheless there’s a lengthy tail of small modifications that you simply
would possibly have to make when updating code that made use of the lower-level
Keras API. A few of these are documented right here:
https://keras.io/guides/migrating_to_keras_3/.

In the event you’re operating into points or have questions on updating, don’t
hesitate to ask on https://github.com/rstudio/keras/points or
https://github.com/rstudio/keras/discussions.

The {keras} and {keras3} packages will coexist whereas the neighborhood
transitions. Throughout the transition, {keras} will proceed to obtain
patch updates for compatibility with Keras v2, which continues to be
revealed to PyPi underneath the bundle title tf-keras. After tf-keras is
not maintained, the {keras} bundle shall be archived.

Abstract

In abstract, {keras3} is a strong replace to the Keras R bundle,
incorporating new options whereas preserving the convenience of use and
performance of the unique. The brand new multi-backend assist,
complete suite of Ops features, refined mannequin serialization API,
and up to date documentation workflows allow customers to simply take
benefit of the newest developments within the deep studying neighborhood.

Whether or not you’re a seasoned Keras person or simply beginning your deep
studying journey, Keras 3 gives the instruments and suppleness to construct,
practice, and deploy fashions with ease and confidence. As we transition from
Keras 2 to Keras 3, we’re dedicated to supporting the neighborhood and
making certain a easy migration. We invite you to discover the brand new options,
take a look at the up to date documentation, and be part of the dialog on our
GitHub discussions web page. Welcome to the following chapter of deep studying in
R with Keras 3!

[ad_2]

Home windows 11 updates break localhost (127.0.0.1) HTTP/2 connections

0

[ad_1]

Microsoft’s October Home windows 11 updates have damaged the “localhost” performance, making purposes that join again to 127.0.0.1 over HTTP/2 now not operate correctly.

Localhost refers back to the native pc or system you are at present utilizing, which will be accessed by means of the particular IP tackle 127.0.0.1.

Builders generally use localhost to check web sites or debug purposes, however it can be used by purposes that want to hook up with a domestically operating service to carry out some motion or question.

After putting in the Home windows 11 KB5066835 Patch Tuesday, and even September’s KB5065789 preview replace, customers are discovering that their purposes are now not in a position to full HTTP connections to the localhost (127.0.0.1) IP tackle.

When trying to take action, they acquired errors like “ERR_CONNECTION_RESET” or “ERR_HTTP2_PROTOCOL_ERROR”.

These points have been reported by Home windows customers on the Microsoft boards, Stack Trade, and Reddit, all stating they’re now not in a position to make HTTP connections to 127.0.0.1.

The bug has impacted broadly used purposes, together with Visible Studio debugging, SSMS Entra ID authentication, and the Duo Desktop app, which verifies system safety posture and requires connections again to net servers operating on the localhost.

“After performing Home windows Updates for Home windows 11 24H2 and 25H2, chances are you’ll expertise a problem the place the Duo Immediate is unable to achieve Duo Desktop,” reads the Duo help bulletin.

“This will likely stop profitable authentication (or lead to restricted performance) in conditions the place the next are in use: Trusted Endpoints, Insurance policies such because the Duo Desktop & Gadget Well being coverage, Duo Desktop as an Authentication Technique. Duo Passport. Verified Duo Push with Bluetooth Autofill or Proximity Verification.”

BornCity suggests the next Registry entries assist resolve the issue by disabling the HTTP/2 protocol however BleepingComputer has not been in a position to independently affirm this repair.


[HKEY_LOCAL_MACHINESystemCurrentControlSetServicesHTTPParameters]
"EnableHttp2Tls"=dword:00000000
"EnableHttp2Cleartext"=dword:00000000 

One other methodology that some declare resolved the issue was to put in the newest Microsoft Defender intelligence replace. Nevertheless, others report that it has not fastened the difficulty on their Home windows units.

As a substitute, the one certain strategy to resolve the bug has been to uninstall the October KB5066835 replace and September’s KB5065789 preview replace.

Home windows customers can uninstall the updates utilizing the next instructions:


wusa /uninstall /kb:5066835
wusa /uninstall /kb:5065789

After uninstalling the updates and restarting Home windows, the loopback interface ought to as soon as once more enable HTTP/2 connections, resolving the problems utilizing purposes.

BleepingComputer contacted Microsoft about this bug and can replace our story if we obtain a response.

46% of environments had passwords cracked, practically doubling from 25% final 12 months.

Get the Picus Blue Report 2025 now for a complete have a look at extra findings on prevention, detection, and information exfiltration tendencies.

[ad_2]