AI utilization has develop into customary follow in software program growth, with 85% of builders in a latest JetBrains survey citing common use of AI instruments for coding and growth. Moreover, 62% had been counting on at the very least one AI-powered coding assistant, agent, or code editor. Solely 15% of respondents had not adopted AI instruments of their each day work.
These findings had been included in JetBrains’ State of the Developer Ecosystem Report 2025, which was unveiled October 15. The survey coated matters together with using AI instruments, which programming languages builders presently use and need to use, and their perceptions of the present job marketplace for builders.
The JetBrains report notes that 68% of builders anticipate AI proficiency will develop into a job requirement. Some 29% of builders mentioned they had been hopeful in regards to the growing function of AI in society and 22% mentioned they had been excited. Nevertheless, 17% reported being anxious and 6% fearful. Probably the most generally used AI instruments among the many builders had been ChatGPT (41%) and GitHub Copilot (30%). The highest 5 considerations about AI reported by the builders had been the standard of code (23%), restricted understanding of advanced code and logic by AI instruments (18%), privateness and safety (13%), destructive impact on coding and growth abilities (11%), and lack of context consciousness (10%). The highest 5 advantages of utilizing AI in coding and software program growth, the builders reported, had been elevated productiveness (74%), sooner completion of repetitive duties (73%), much less time spent looking for info (72%), sooner coding and growth (69%), and sooner studying of latest instruments and applied sciences (65%).
“This is without doubt one of the least visited locations on planet Earth and I acquired to open the door,” Matty Jordan, a building specialist at New Zealand’s Scott Base in Antarctica, wrote within the caption to the video he posted to Instagram and TikTok in October 2023.
Within the video, he guides viewers by means of the hut, declaring the place the lads of Ernest Shackleton’s 1907 expedition lived and labored.
The video has racked up thousands and thousands of views from everywhere in the world. It’s additionally type of a miracle: till very just lately, those that lived and labored on Antarctic bases had no hope of speaking so readily with the skin world. That’s beginning to change, because of Starlink, the satellite tv for pc constellation developed by Elon Musk’s firm SpaceX to service the world with high-speed broadband web.
That is our newest story to be changed into a MIT Know-how Overview Narrated podcast, which we’re publishing every week on Spotify and Apple Podcasts. Simply navigate to MIT Know-how Overview Narrated on both platform, and comply with us to get all our new content material because it’s launched.
The must-reads
I’ve combed the web to search out you immediately’s most enjoyable/vital/scary/fascinating tales about expertise.
1 OpenAI has launched its personal internet browser Atlas has an Ask ChatGPT sidebar and an agent mode to finish sure duties. (TechCrunch) + It runs on Chromium, the open-source engine that powers Google’s Chrome. (Axios) + OpenAI believes the way forward for internet looking will contain chatting to its interface. (Ars Technica) + AI means the tip of web search as we’ve identified it. (MIT Know-how Overview)
In the event you’ve seen your electrical energy invoice is greater than regular not too long ago, you’re not alone. Energy is getting costlier all over the place, outpacing inflation. One main wrongdoer? The flurry of recent knowledge facilities being constructed to satisfy demand from the AI sector.
To seek out out extra, I requested my colleague Umair Irfan, who covers power coverage, for Vox’s each day e-newsletter, As we speak, Defined. Our dialog is under, and you’ll join the e-newsletter right here for extra conversations like this.
What’s been occurring with power costs these days?
Electrical energy costs have been going up fairly dramatically over the previous 12 months. In some locations, they’re rising by double-digit percentages, and so they’re projected to rise even additional. We’re speaking about costs which are paid by shoppers, so that is truly exhibiting up on individuals’s energy payments, which is why it’s getting a variety of consideration.
There’s a pair causes behind this. One is that electrical energy costs had been saved artificially low through the Covid-19 pandemic, as a result of the electrical energy business is closely regulated. Loads of regulators had been underneath public strain to stop the utilities from elevating costs as a result of we had been already coping with inflation and different cost-of-living points. Now a few of these restrictions have turn out to be uncorked, and we’re seeing a rebound.
On prime of that, all the inputs for electrical energy have gotten much more costly. Supplies prices are rising normally, after which the Trump administration’s tariffs on issues like metal and aluminum are making it more durable to get the {hardware} to do issues like construct energy traces and even change present energy traces. Gasoline costs for coal and pure gasoline are fairly unstable, and there’s been an increase in pure gasoline costs. Pure gasoline is the primary manner we produce electrical energy right here within the US.
We’re additionally seeing a fairly large improve in total power demand for the primary time in a really very long time. For the previous 20-odd years, we’ve been seeing effectivity counteract power demand will increase, and so our total power demand has held pretty flat. Simply up to now couple of years, we’ve seen a giant improve in electrical energy utilization, and that’s pushed by this proliferation of knowledge facilities, significantly these there to energy the AI business.
You may have a giant story out about how these knowledge facilities are contributing to the value spike, in some circumstances even after they’re not constructed. What’s taking place there?
Simply final week, the general public advocate for the state of Maryland despatched a letter to the grid operator for the area, telling them that they actually need to rein in power hypothesis, as a result of it’s beginning to increase individuals’s costs.
The way in which that works is that with a view to construct an information middle, it’s important to procure a certain quantity of energy with a view to just remember to can truly maintain it working. And so what you’re seeing is, these tech firms are going to totally different utilities and buying round and asking them, What value are you able to give me for this amount of electrical energy? And the way quickly?
It seems that in some circumstances, these tech firms are buying to a number of utilities, and people utilities, in flip, are telling the grid operator, Hey, we’re going to wish this a lot electrical energy within the subsequent few years. The priority is that they’re double counting, as a result of these tech firms are going to a number of utilities and a number of jurisdictions telling them that they’re going to wish this a lot electrical energy, and so they’re simply window-shopping for the time being, however utilities are treating these as actual bids.
The opposite factor is that we’re not completely positive that a variety of these knowledge facilities are going to be constructed. There are some fairly wild estimates for what number of extra knowledge facilities we’re going to wish. It’s not clear that the present developments we’re seeing are going to proceed.
All which means is that you simply’re going to be constructing a variety of infrastructure to help knowledge facilities whose demand is probably not there to truly pay for that infrastructure. And what which means, finally, is that ordinary prospects will find yourself holding the bag.
That is in Maryland, however the grid operator covers a lot of the East Coast. We’ve bought two massive gubernatorial races developing in Virginia and New Jersey. Is that developing on the marketing campaign path?
It has undoubtedly turn out to be a giant challenge within the New Jersey governor’s race. Each side are blaming insurance policies from the opposite celebration for elevating power costs. The Republican within the race is blaming renewable power for driving up electrical energy prices, and the Democrat is blaming the Trump administration for canceling a variety of incentives for extra renewable power to be on the grid, in addition to the infrastructure to help it. Renewable power is true now the most affordable and quickest manner so as to add electrical energy to the facility grid, and by taking that off the desk, you’re taking out one of many most cost-effective and best methods to carry extra electrical energy onto the market.
In Virginia, the added complication is that it’s dwelling to one of many largest concentrations of knowledge facilities on this planet. Loudoun County, simply outdoors of DC, has what’s referred to as Datacenter Alley, the place an enormous chunk of web site visitors goes by means of; it’s additionally dwelling to the biggest focus of hyperscale knowledge facilities for powering AI applied sciences. It is a very massive, energy-hungry sector, and it’s a contributor to the native economic system, however it additionally requires a variety of water, a variety of electrical energy, and now there’s been pushback. Many shoppers in Virginia and in neighboring states like West Virginia have began to protest in opposition to knowledge facilities as a result of they’re involved about electrical energy costs and different environmental prices being imposed by them.
What can shoppers anticipate to occur with electrical energy costs going ahead?
Within the close to time period, electrical energy costs are more likely to proceed to go up. There doesn’t appear to be a straightforward out, as a result of all the identical elements which are driving up electrical energy costs proceed to be in place.
However the factor to recollect is that electrical energy is a subset of power spending. In the event you take a look at the general power image, shoppers are literally more likely to find yourself saving cash on family power over time, and that’s as a result of we’re switching from fossil fuels to electrical energy. The largest share of that is switching from gasoline automobiles to electrical automobiles: As we join extra electrical automobiles to the facility grid, they will use extra electrical energy, however electrical automobiles are extra environment friendly than gasoline automobiles, so the general power we use per family will ultimately begin to decline. We’ll see that with different home equipment, like stoves and furnaces, as we swap to electrical energy. Electrical energy utilization will improve, however the total power footprint will lower. And we will anticipate over the center and long run for individuals to truly begin to economize, supplied that these developments proceed.
In order for you to step up your images sport, and graduate out of your cellphone, why not go all the best way to the highest-resolution digicam in the marketplace? Usually, we advise {that a} extra reasonably priced digicam may be the very best decide for most individuals in our information to mirrorless cameras, however at this value—why not go massive?
Courtesy of Sony
The huge 61-megapixel, full-frame sensor within the A7R V is the most important sensor you may get with out leaping into medium format (which is considerably dearer and bulkier). If that is not sufficient, there’s truly a fair higher-resolution chance that mixes 16 photographs right into a single 240-MP picture (as long as your topic is static, e.g., a panorama). That ought to print billboard-size with out difficulty.
Sure, the megapixel race is foolish and largely over, however I’ll say that I’ve shot fairly a bit with the A7R C (which makes use of the identical sensor). The pictures from this 60-MP sensor are noticeable sharper, and the dynamic vary is visibly higher than what I get from the A7R II (which has a 40-MP sensor). That is clearly the case onscreen, when pixel peeping, however I additionally discover the distinction once I print photographs.
For those who do not want all these megapixels, and you continue to need to avoid wasting cash, I’ve excellent news, our high decide for most individuals, the Sony A7 IV (9/10, WIRED Recommends), is on sale as effectively for $700 lower than ordinary.
{Photograph}: Sony
It is a 33-megapixel, full-frame digicam that, whereas solely half the decision of the A7R V, is loads sharp and boasts a number of video-oriented options you will not discover within the higher-resolution mannequin. It has very practically the identical glorious dynamic vary and the most effective autofocus system in the marketplace.
With out getting too deep within the weeds of video technicalities, the A7 IV can file 4K/30p video by oversampling from a 7K sensor area. Alternatively, the A7R V employs what’s referred to as line-skipping to realize the identical 4K/30p recording. This technique of recording ends in lowered sharpness and generally causes aliasing points.
The quick story: If you wish to file video at full sensor measurement, the A7 IV is the best way to go. In actual fact, whereas there are higher nonetheless cameras just like the Sony A7R V, and higher video cameras, nothing combines the 2 fairly in addition to the A7 IV. For those who’re trying to do a mixture of nonetheless and video work, this is likely one of the finest buys in the marketplace, particularly at this value.
9 patterns of three varieties of relationships that aren’t spurious.
When analysts see a big correlation coefficient, they start speculating about potential causes. They’ll naturally gravitate towards their preliminary speculation (or preconceived notion) which set them to research the information relationship within the first place. As a result of hypotheses are generally about causation, they typically start with this least seemingly sort of relationship utilizing probably the most simplistic of relationship sample, a direct one-event-causes-another.
A topology of information relationships is vital as a result of it helps individuals to grasp that not all relationships replicate a trigger. They might simply be the results of an affect or an affiliation and even mere coincidence. Moreover, you’ll be able to’t at all times inform what sort and sample of relationship a knowledge set represents. There are at the least 27 prospects not even counting spurious relationships. That’s the place numbercrunching ends and statistical-thinking shifts into high-gear. Be ready.
Apart from causation, relationships can even replicate affect or affiliation.
Causes
A trigger is a situation or occasion that instantly triggers, initiates, makes occur, or brings into being one other situation or occasion. A trigger is a sine qua non; with no trigger a consequent won’t happen. Causes are directional. A trigger should precede its consequent.
Influences
An affect is a situation or occasion that adjustments the manifestation of an current situation or occasion. Influences could be direct or mediated by a separate situation or occasion. Influences could exist at any time earlier than or after the influenced situation or occasion. Influences could also be unidirectional or bidirectional.
Associations
Associations are two circumstances or occasions that seem to alter in a associated method. Any two variables that change in an identical method will look like related. Thus, associations could be spurious or actual. Associations could exist at any time earlier than or after the related situation or occasion. In contrast to causes and influences, related variables haven’t any impact on one another and will not exist in numerous populations or in the identical inhabitants at completely different occasions or locations.
Associations are commonplace. Most noticed correlations are most likely simply associations. Influences and causes are much less widespread however, not like associations, they are often supported by the science or different ideas on which the information are primarily based. The power of a correlation coefficient just isn’t associated to the kind of relationship. Causes, influences, and associations can all have robust in addition to weak correlations relying on the effectivity of the variables being correlated and the sample of the connection.
Direct relationships are simple to grasp and, if there are not any statistical obfuscations, ought to exhibit a excessive diploma of correlation. In follow, although, not each relationship is direct or easy. Some are downright advanced.
Listed here are 9 relationships that I might consider. There could also be extra. These relationships contain occasions or circumstances termed A, B, and C.
Direct Relationship
Most discussions of correlation and causation concentrate on the easy, direct relationship that one occasion or situation, A, is said to a second occasion or situation, B. The connection proceeds in just one route. For instance, gravitational forces from the Moon and Solar trigger ocean tides on the Earth. A causes B however B doesn’t trigger A. One other direct relationship is that age influences top and weight. Age doesn’t trigger top and weight however we are likely to develop bigger as we age so A influences B.B doesn’t affect A.
Suggestions Relationship
In a suggestions relationship, A and B are linked in a loop. A causes or influences B, which then causes or influences A, and so forth. Suggestions relationships are bidirectional. They are going to be correlated. For instance, poor efficiency at school or at work (A) creates stress (B) which degrades efficiency additional (A) resulting in extra stress (B) and so forth.
In a stimulated relationship, A causes or influences B however solely within the presence of C. Stimulated relationships could not look like correlated utilizing a Pearson correlation coefficient however could utilizing a partial correlation. There are various examples of this sample, resembling metabolic and chemical reactions involving enzymes or catalysts.
Suppressed Relationship
In a suppressed relationship, A causes or influences B however not within the presence of C. As with stimulated relationships, suppressed relationships could solely look like correlated utilizing a partial correlation coefficient. Medication has many examples of suppressed and stimulated relationships. For instance, pathogens (A) trigger infections (B) however not within the presence of antibiotics (C). Some medication (A) trigger unintended effects (B) solely in sure at-risk populations (C).
Inverse Relationship
In inverse relationships, the absence of A causes or influences B, OR the presence of A minimizes B. Correlation coefficients for inverse relationships are damaging. For instance, vitamin deficiencies (A) trigger or affect all kinds of signs (B).
Threshold Relationship
In threshold relationships, A causes or influences B solely when A is above a sure degree. For instance, rain (A) causes flooding (B) solely when the amount or depth may be very excessive. These relationships aren’t often revealed by correlation coefficients.
Advanced Relationship
In advanced relationships, many A components or occasions contribute to the trigger or affect of B. Quite a few environmental processes match this sample. For instance, Quite a lot of atmospheric and astronomical components (A) contribute to influencing local weather change (B). Even many correlation coefficients could not clarify one of these relationship; it takes extra concerned statistical analyses.
There are additionally quite a lot of spurious relationships through which Aseems to trigger or affect B, however doesn’t. Usually the reason being that the connection is predicated on anecdotal proof that’s not legitimate extra typically. Generally spurious relationships could also be another form of relationship that isn’t understood. Listed here are 5 different the explanation why spurious relationships are so widespread.
Misunderstood relationships
The science behind a relationship might not be understood accurately. For instance, docs used to assume that spicy meals and stress triggered ulcers. Now, there’s better recognition of the position of bacterial an infection. Likewise, hormones have been discovered to be the main reason behind zits somewhat than weight-reduction plan (i.e., consumption of chocolate and fried meals).
Misinterpreted statistics
There are various examples of statistical relationships being interpreted incorrectly. For instance, the sizes of homeless populations seem to affect crime. Then once more, so do the numbers of museums and the supply of public transportation. All of those components are related to city areas, however not essentially crime.
Misinterpreted observations
Incorrect causes are connected to actual observations. Many aged wives tales are primarily based on credible observations. For instance, the notion that hair and nails proceed to develop after demise is an incorrect clarification for the respectable remark.
City legends
Some city legends have a foundation in fact and a few are pure fabrications, however all of them contain spurious relationships. For instance, In South Korea, it’s believed that sleeping with a fan in a closed room will end in demise.
Biased Assertions
Some spurious relationships will not be primarily based on any proof, however as an alternative, are claimed in an try to steer others of their validity. For instance, the declare that masturbation makes you might have bushy palms just isn’t solely ludicrous but in addition simply refutable. Likewise, nearly any commercial in help of a candidate in an election accommodates some kind of bias, resembling cherry selecting.
Coincidences
Mom Nature has a depraved humorousness. Don’t consider each correlation coefficient you calculate.
M.pneumoniae infections are discovered worldwide. In temperate climates, infections peak throughout late summer time and Fall (autumn) [5].
Antibiotic-resistant strains of M.pneumoniae had been first recognized within the early 2000s and have been largely reported in Asia, together with China and Japan [2].
Who’s most in danger?
Anybody can get sick with an m.pneumoniae an infection. Nonetheless, youngsters, older adults, and other people with lung illness could also be extra susceptible. Folks with power illnesses that have an effect on the lungs or coronary heart are additionally at the next danger of getting a extra extreme an infection [5].
Those that dwell or work in crowded areas are additionally at the next danger of getting contaminated. These areas embrace colleges, army quarters, nursing properties, hospitals, and long-term care services [5].
2024 M.pneumonia outbreaks
Generally, Mycoplasma pneumoniae infections are frequent. Globally, they happen each 3-7 years as neighborhood immunity wanes. Nonetheless, after the COVID-19 pandemic, circumstances have been rising worldwide.
In the US, these infections are usually not nationally notifiable, which implies it’s laborious to get the precise variety of circumstances. Nonetheless, the US CDC (Facilities for Illness Management and Prevention) stories that there was a rise in circumstances in all age teams, with the best being in youngsters 2-4 years previous [6].
In Denmark, a examine discovered that M.pneumoniae infections had been 3 times increased in 2023-2024 in comparison with the years previous to the COVID-19 pandemic. Right here, the best enhance was amongst adolescents [7].
One examine reported a large-scale M.pneumoniae outbreak of 218 circumstances in Marseille, France, from 2023-2024 [8].
In China, M. pneumoniae infections rank because the second commonest acute bacterial an infection, making up almost 19% of all bacterial infections nationwide. In 2023, there was a big wave of M. pneumonia circumstances in Northern China’s second-largest metropolis, Tianjin, and different cities [9].
This prompted the WHO (World Well being Group) to launch a assertion in November 2023 on clusters of respiratory tract infections amongst youngsters in Northern China [10].
GIDEON gives complete information on Mycoplasma pneumonia circumstances, outbreaks, and extra.
In an period of large-scale experimentation and wealthy observational information, the one-size-fits-all paradigm is giving option to individualized decision-making. Whether or not concentrating on messages to voters, assigning medical remedies to sufferers, or recommending merchandise to shoppers, practitioners more and more search to tailor interventions based mostly on particular person traits. This shift hinges on understanding how remedy results fluctuate throughout people, not simply whether or not interventions work on common, however for whom they work greatest.
Why is the typical remedy impact not adequate?
Conventional causal inference focuses on the typical remedy impact (ATE), which might masks vital heterogeneity. A drug may present modest common advantages whereas delivering transformative outcomes for some sufferers and proving dangerous for others. The conditional common remedy impact (CATE) captures this variation by estimating remedy results conditional on particular person traits, enabling customized selections.
What are metalearners and why can we use them?
Estimating CATE is statistically difficult, notably with high-dimensional information. Conventional parametric approaches typically fail when relationships are nonlinear or when the variety of covariates approaches or exceeds the pattern dimension. To handle this, researchers have developed metalearners. They’re a versatile household of algorithms that cut back CATE estimation to a collection of supervised studying duties, leveraging highly effective machine studying fashions within the course of.
On this weblog submit, we offer an introduction to CATE and to 3 sorts of metalearners. We display the way to use the h2oml suite of instructions to estimate CATE utilizing every of the metalearners.
Introduction to CATE
The flexibility to research detailed details about people and their habits inside massive datasets has sparked important curiosity from researchers and companies. This curiosity stems from a want to grasp how remedy results fluctuate amongst people or teams, transferring past merely understanding the ATE. On this context, the CATE perform is usually the first focus, outlined as [ tau(mathbf{x}) = mathbb{E}{Y(1) – Y(0) mid mathbf{X} = mathbf{x}} ]
Right here (Y(1)) and (Y(0)) signify the potential outcomes if a topic is assigned to the remedy or management group, respectively. We situation on covariates (mathbf{X}). Usually, (mathbf{X}) needn’t include all noticed covariates. In apply, although, it typically does. With normal causal assumptions like overlap, positivity, and unconfoundedness, CATE is often recognized because the distinction between two regression capabilities, [ tau(mathbf{x}) = mu_1(mathbf{x}) – mu_0(mathbf{x}) = mathbb{E}(Y mid mathbf{X} = mathbf{x}, T = 1) – mathbb{E}(Y mid mathbf{X} = mathbf{x}, T = 0) tag{1}label{eq:cate} ] the place (T) represents the remedy variable. Be aware that individualized remedy results (ITE), (D_i = Y_i(1) – Y_i(0)), are generally conflated with CATE, however they aren’t the identical (Vegetabile 2021). ITEs and CATEs are solely equal if we think about all particular person traits (tilde{X}) related to their potential outcomes.
Beneath, we discover three strategies: the S-learner, T-learner, and X-learner. Our dialogue will largely observe the framework offered in Künzel et al. (2019). For a current overview, see Jacob (2021).
Dataset
For this submit, we use socialpressure.dta, borrowed from Gerber, Inexperienced, and Larimer (2008), the place the authors look at whether or not social stress can increase voter turnout in US elections. The voting habits information had been collected from Michigan households previous to the August 2006 main election by means of a large-scale mailing marketing campaign.
The authors randomly assigned registered voter households to obtain mailers. They used concentrating on standards based mostly on deal with info, together with a set of indices and voting habits, to unsolicited mail to households estimated to have a average likelihood of voting. The experiment included 4 remedy circumstances: civic responsibility, family, self and neighbors, and a management group.
We are going to focus solely on the management group (191,243 observations) and the self and neighbors remedy group (38,218 observations). The self and neighbors mailing included messages reminiscent of “DO YOUR CIVIC DUTY—VOTE” and an inventory of family and neighbors’ voting data. The mailer additionally knowledgeable the family that an up to date chart can be despatched after the elections. We are going to think about gender, age, voting in main elections in 2000, 2002, and 2004, and voting within the basic election in 2000 and 2002 as predictors.
We start by importing the dataset to Stata and making a variable, totalvote, that teams potential voters by their previous voting historical past. This variable takes values from 0 to five, the place 0 corresponds to people who didn’t vote in any of the 5 earlier elections and 5 corresponds to those that voted in all 5. Later, we use this variable to interpret CATE estimates by subgroup. For comfort, we generate a Stata body named social through the use of the body copy command.
A metalearner is a high-level algorithm that decomposes the CATE estimation downside into a number of regression duties that may be tackled by your favourite machine studying fashions (base learners like random forest, gradient boosting machine [GBM], and their buddies).
There are three sorts of metalearners for CATE estimation: the S-learner, T-learner, and X-learner. The S-learner is the only of the thought of strategies. It matches a single mannequin, utilizing the predictors and the remedy as covariates. The T-learner improves upon this by becoming two separate fashions: one for the remedy group and one for the management group. The X-learner takes issues additional with a multistep process designed to leverage the complete dataset for CATE estimation. To maintain this submit from turning right into a theoretical marathon, we’ve tucked the deeper remedy of those strategies into an appendix. On this appendix, we demystify the logic behind these letters and clarify how every learner sequentially improves upon its predecessor. We strongly advocate that readers unfamiliar with these methods take a detour by means of the appendix earlier than leaping into the Stata implementation within the subsequent part.
We begin by setting the H2O body social as our working body. Then, we create a worldwide macro, predictors, in Stata to include the predictor names and run gradient boosting binary classification utilizing the h2oml gbbinclass command. For illustration functions, we don’t implement hyperparameter tuning and pattern splitting. For particulars, see Jacob (2021). Nonetheless, in apply, all fashions used on this weblog submit ought to be tuned to acquire the best-performing mannequin. For particulars, see Mannequin choice in machine studying in [H2OML] Intro.
. _h2oframe change social

. world predictors gender g2000 g2002 p2000 p2002 p2004 remedy age

. h2oml gbbinclass voted $predictors, h2orseed(19)
(output omitted)
Subsequent, we create two copies of the H2O social body, social0 and social1, the place the predictor remedy is the same as 0 and 1, respectively. We use these frames to acquire predictions (hat{mu}(mathbf{x},1)) and (hat{mu}(mathbf{x},0)) as in part A.1.
We use the educated GBM mannequin to foretell voting possibilities on these frames, storing them as yhat0_1 and yhat1_1, through the use of the h2omlpredict command with the body() and pr choices.
Then, we use the _h2oframe cbind command to affix these frames and enter the joined body into Stata through the use of the _h2oframe get command. Lastly, in Stata, we generate the variable catehat_S, as in eqref{eq:cateslearner} in appendix A.1, by subtracting the yhat0_1 prediction from the yhat1_1 prediction.
. _h2oframe cbind social1 social0, into(be a part of)

. _h2oframe get yhat1_1 yhat0_1 totalvote $predictors utilizing be a part of, clear

. generate catehat_S = yhat1_1 - yhat0_1
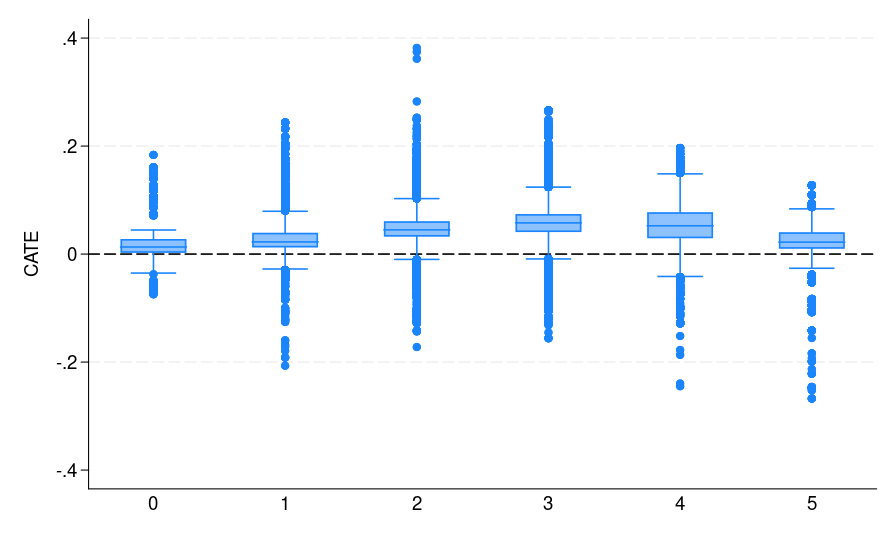
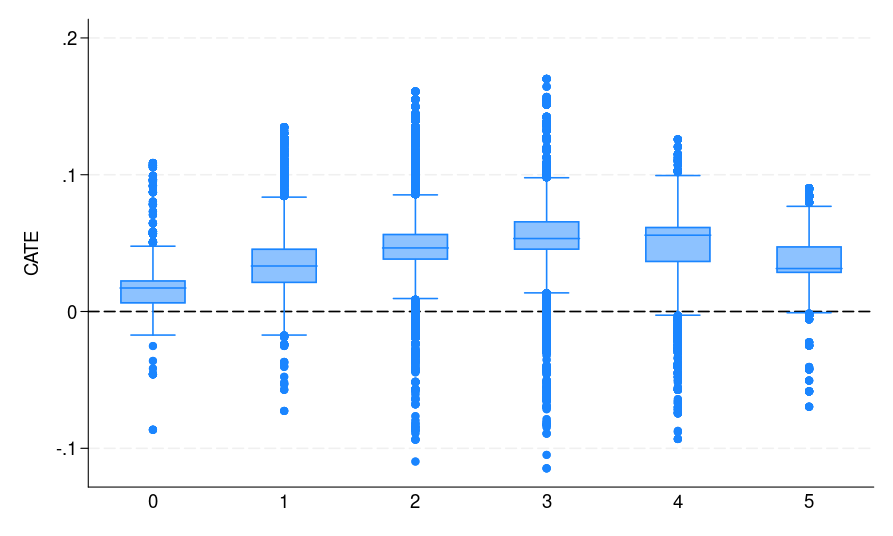
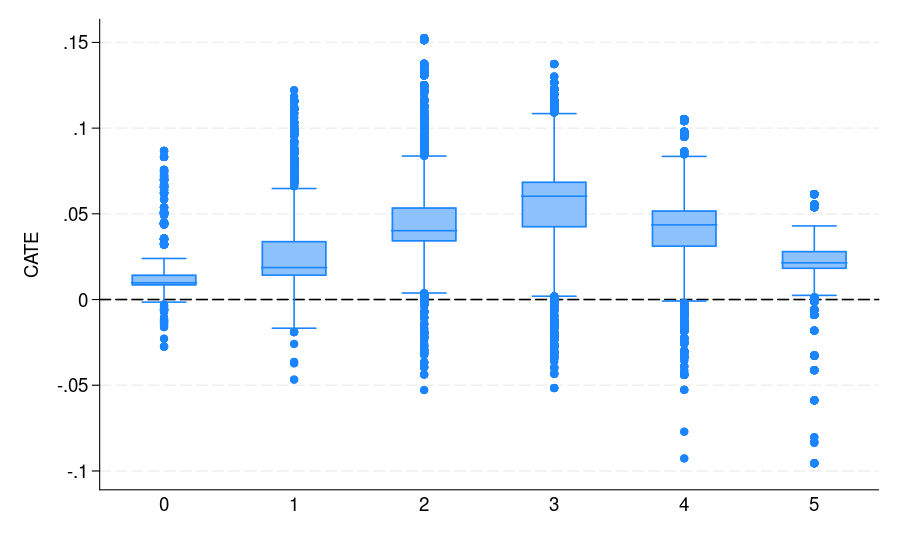
Be aware that catehat_S incorporates the CATE estimate from our S-learner. Determine 1(a) summarizes the outcomes, the place the potential voters are grouped by their voting historical past. It exhibits the distribution of CATE estimates for every of the subgroups. These outcomes may help marketing campaign organizers higher goal mailers sooner or later. As an illustration, if sources are restricted, specializing in potential voters who voted 3 times in the course of the previous 5 elections could also be handiest. This group not solely displays the best estimated ATE but additionally represents the biggest phase of potential voters, making it an excellent goal for maximizing affect.
(a) S-learner
(b) T-learner
(c) X-learner
Determine 1: The CATE estimate distribution for every bin, the place potential voters are grouped by the variety of elections they participated in
Explainable machine studying for CATE
Machine studying fashions are sometimes handled as black bins that don’t clarify their predictions in a approach that practitioners can perceive. Explainable machine studying refers to strategies that depend on exterior fashions to make the selections and predictions of these fashions presentable and comprehensible to a human.
The dialogue on this part applies to all sorts of studying strategies mentioned on this weblog. For illustration, we present solely the S-learner. Having CATE estimates from the earlier sections, we are able to construct a surrogate mannequin, for instance, GBM, for CATE utilizing the predictors and use the out there explainable technique within the h2oml suite of instructions to elucidate CATE predictions. For out there, explainable instructions, see Interpretation and clarification in [H2OML] Intro.
To display, we are going to deal with exploring SHAP values and making a partial dependence plot. We begin by importing the present dataset in Stata as an H2O body. Then, to ensure that the issue variables have an accurate H2O sort enum, we use the _h2oframe issue command with the substitute choice. Then, we run gradient boosting regression for the estimated CATEs in catehat_S. As talked about above, we advise tuning this mannequin as effectively.
We graph the SHAP values and create a partial dependence plot (PDP) for explainability.
. h2omlgraph shapvalues, obs(5)

. h2omlgraph pdp age
(output omitted)
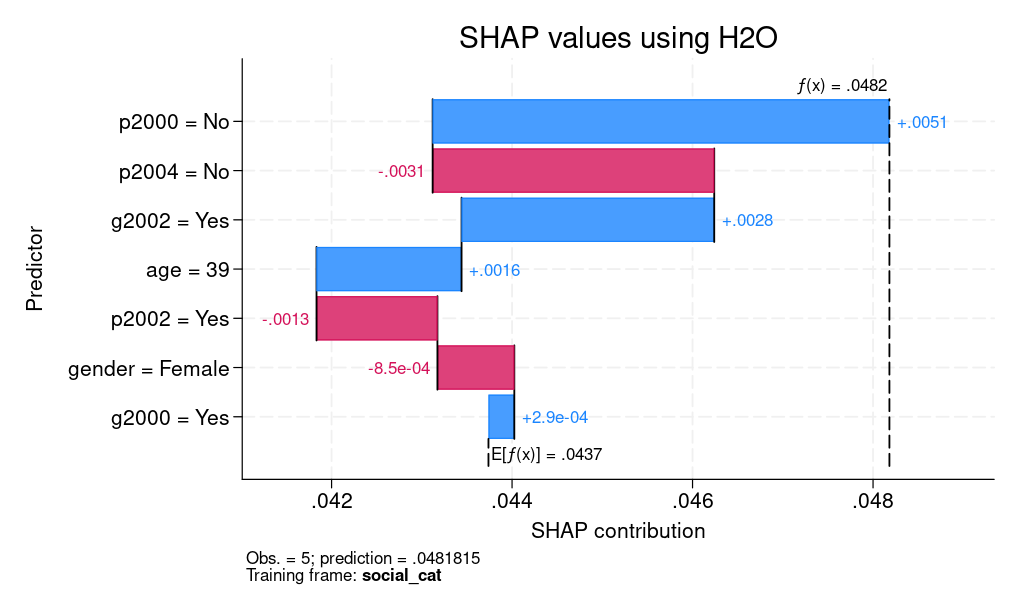
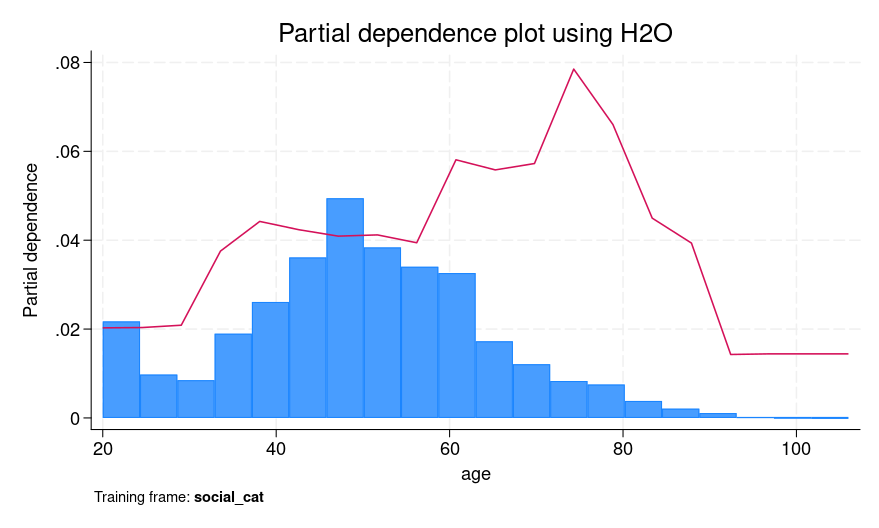
Determine 2 presents each SHAP values for a person prediction and a PDP for age. For SHAP values, we clarify the fifth commentary, which corresponds to a feminine who’s 39 years outdated. We are able to see that the age of 39 and voting within the 2002 basic elections however not voting within the 2000 main elections contribute positively to explaining the distinction between the person’s CATE prediction (0.0482) and the typical prediction of 0.0437. Nonetheless, not voting within the 2004 main elections had a detrimental contribution.
From the PDP, the purple line exhibits a rise in predicted CATE between ages 30 and 40, adopted by a small lower after which a rise from round age 60 to 80. One doable interpretation of the plateau and modest dip between 40 and 60 is that people in that age group could exhibit extra secure voting patterns which can be more durable to affect utilizing social stress mailers.
We may equally discover SHAP values for different people and PDP plots for different predictors.
Subsequent we display the way to implement the T-learner. We start by splitting the dataset into two H2O frames: one for management observations (social0) and one other for handled observations (social1). These frames might be used to suit separate fashions for predicting outcomes within the handled and management teams, as described in appendix A.2.
. // T-learner step 1: Break up information by remedy group
. body change social

. _h2oframe put if remedy == 0, into(social0) substitute // management group
(output omitted)

. _h2oframe put if remedy == 1, into(social1) substitute // handled group
(output omitted)
Subsequent we use the h2oml gbbinclass command to coach a gradient boosting binary classification mannequin on the management group information, with voted as the result. The predictor names are specified utilizing the predictors macro, outlined earlier. We retailer this mannequin utilizing h2omlest retailer so we are able to later reload it for predictions within the subsequent part.
. // T-learner step 2: Practice a GBM mannequin for the management response perform
. _h2oframe change social0

. h2oml gbbinclass voted $predictors, h2orseed(19) // GBM mannequin: predict voting for T=group (management)
(output omitted)

. h2omlest retailer M0                                // Retailer mannequin as MO

. h2omlpredict yhat0_0 yhat0_1, body(social) pr   // Predict yhat0_1 = Pr(Y=1|X,T=0) based mostly on mannequin MO for full pattern

Progress (%): 0 100
After coaching the management mannequin, we change to the handled group body and practice one other GBM mannequin, once more utilizing voted as the result. This mannequin is saved individually and represents our estimate of the remedy response perform.
. // T-learner step 3: Practice a GBM mannequin for the remedy response perform
. _h2oframe change social1

. h2oml gbbinclass voted $predictors, h2orseed(19) // GBM mannequin: predict voting for T=1 group (handled)
(output omitted)

. h2omlest retailer M1                                // Retailer mannequin as M1

. h2omlpredict yhat1_0 yhat1_1, body(social) pr   // Predict yhat1_1 = Pr(Y=1|X,T=1) based mostly on mannequin M1 for full pattern

Progress (%): 0 100
As soon as each fashions are educated, we use them to generate counterfactual predictions yhat0_1 and yhat1_1 for all people within the full dataset. These predictions correspond to (hat{mu}_0(mathbf{x})) and (hat{mu}_1(mathbf{x})) in eqref{eq:catetlearner} in appendix A.2. We then compute their distinction in Stata and retailer it as catehat_T, which corresponds to the T-learner estimate of CATE (hat{tau}_T(mathbf{x})). Final, we plot the distribution of the CATE estimates by voting historical past [figure 1(b)] to evaluate how remedy results fluctuate throughout subgroups. It may be seen that each S- and T-learners (additionally the X-learner) present related CATE estimates.
The X-learner begins through the use of the beforehand educated end result fashions, M0 and M1 from the T-learner, to generate counterfactual predictions. Particularly, we use the management group mannequin to foretell what handled people would have finished underneath management [(hat{mu}_0(X_i^1))] and the handled group mannequin to foretell what management people would have finished underneath remedy [(hat{mu}_1(X_i^0))].
Subsequent we compute imputed remedy results by subtracting these counterfactual predictions from noticed outcomes. For handled people, that is (tilde{D}_i^1 = Y^1_i – hat{mu}_0(X^1_i)), and for management people, it’s (tilde{D}_i^0 = hat{mu}_1(X^0_i) – Y^0_i). These imputed results function pseudooutcomes within the second stage of the X-learner. We then match regression fashions utilizing h2oml gbregress to foretell these pseudooutcomes (tilde{D}_i^1) and (tilde{D}_i^0) utilizing the unique covariates. These correspond to (hat{tau}_1(mathbf{x})) and (hat{tau}_0(mathbf{x})) in eqref{eq:catexlearner} in appendix A.3, that are the estimated CATE capabilities derived from the handled and management teams, respectively.
Lastly, we mix these two CATE estimates saved in cate1 and cate0 utilizing a weighted common. In keeping with Künzel et al. (2019), we use a hard and fast weight (g(x)=0.5) for simplicity, though in apply this may be set to the estimated propensity rating (hat{e}(mathbf{x})).
. // X-learner step 5: Mix CATE estimates from each teams
. _h2oframe get cate0 cate1 totalvote utilizing social, clear

. native gx = 0.5                                                // Mix with weight (0.5 right here, might be e(x))

. generate double catehat_X = `gx' * cate0 + (1 - `gx') * cate1 // Closing CATE estimate

. graph field catehat_X, over(totalvote) yline(0) ytitle("CATE")
The distribution of the CATE estimates by voting historical past is displayed in determine 1(c).
Dialogue
As might be seen from determine 1, all S-, T-, and X-learners present related CATE estimates. This result’s anticipated given the very massive pattern dimension and small variety of predictors. Thus, it’s informative to debate when to undertake which learner. Following Künzel et al. (2019), we advise utilizing the S-learner when the researcher suspects that the remedy impact is easy or zero. If the remedy impact is strongly heterogeneous and the response end result distribution varies between remedy and management teams, then the T-learner may carry out effectively. Utilizing numerous simulation settings, Künzel et al. (2019) present that the X-learner successfully adapts to those completely different settings and performs effectively even when the remedy and management teams are imbalanced.
Appendix
A metalearner is a high-level algorithm that decomposes the CATE estimation downside into a number of regression duties solvable by machine studying fashions (base learners like random forest, GBM, and so on.).
Let ( Y^0 ) and ( Y^1 ) denote the noticed outcomes for the management and remedy teams, respectively. As an illustration, ( Y^1_i ) is the result of the ( i )th unit within the remedy group. Covariates are denoted by ( mathbf{X}^0 ) and ( mathbf{X}^1 ), the place ( mathbf{X}^0 ) corresponds to the covariates of management items and ( mathbf{X}^1 ) to these of handled items; ( mathbf{X}^1_i ) refers back to the covariate vector for the ( i )th handled unit. The remedy project indicator is denoted by ( T in {0, 1} ), with ( T = 1 ) indicating remedy and ( T = 0 ) indicating management.
Regression fashions are represented utilizing the notation ( M_k(Y sim mathbf{X}) ), which denotes a generic studying algorithm, presumably distinct throughout fashions, that estimates the conditional expectation ( mathbb{E}(Y mid mathbf{X} = mathbf{x}) ) for given inputs. These fashions might be any machine studying estimator, together with versatile black-box learners. The primary estimand of curiosity is the CATE eqref{eq:cate}. That is the amount all metalearners are designed to estimate.
A.1 S-learner
From eqref{eq:cate}, essentially the most easy factor to do is to simply implement a machine studying mannequin for the conditional expectation (E(Y|mathbf{X}, T)). The S-learner, the place the “S” stands for single, matches a single mannequin, utilizing each ( mathbf{X} ) and ( T ) as covariates: [ mu(mathbf{x}, t) = mathbb{E}(Y mid mathbf{X} = mathbf{x}, T = t) quadtext{ which is estimated using }quad M{Y sim (mathbf{X}, T)} ] The CATE estimator is given by [ hat{tau}_S(mathbf{x}) = hat{mu}(mathbf{x},1) – hat{mu}(mathbf{x}, 0) tag{2}label{eq:cateslearner} ]
In apply, the remedy (T) is usually one-dimensional, whereas (mathbf{X}) might be high-dimensional. Trying on the CATE estimator in eqref{eq:cateslearner}, discover that the one enter to (hat{mu}) that modifications between the 2 phrases is (T). Consequently, if the machine studying mannequin used for estimation largely ignores (T) and primarily focuses on (mathbf{X}), the ensuing CATE may incorrectly be zero. The T-learner, mentioned subsequent, makes an attempt to handle this subject.
A.2 T-learner
The query we are attempting to reply is, How can we ensure that the mannequin (hat{mu}) doesn’t ignore (T)? Properly, we are able to obtain this by coaching two completely different fashions for the remedy and management response capabilities (mu_1(mathbf{x})) and (mu_0(mathbf{x})), respectively. The T-learner, the place the “T” stands for 2, matches two separate fashions for the remedy and management teams: start{align} mu_1(mathbf{x}) &= mathbb{E}{Y(1) mid mathbf{X} = mathbf{x}, T = 1}, quad textual content{estimated by way of }quad M_1(Y^1 sim mathbf{X}^1) mu_0(mathbf{x}) &= mathbb{E}{Y(0) mid mathbf{X} = mathbf{x}, T = 0}, quad textual content{estimated by way of }quad M_2(Y^0 sim mathbf{X}^0) finish{align} Then the CATE estimator is given by [ hat{tau}_T(mathbf{x}) = hat{mu}_1(mathbf{x}) – hat{mu}_0(mathbf{x}) tag{3}label{eq:catetlearner} ]
To make sure (T) isn’t neglected, we practice two separate statistical fashions. First, we divide our information: ((Y^1,mathbf{X}^1)) consists of observations the place (T= 1), and ((Y^0,mathbf{X}^0)) of observations the place (T= 0). Then, we practice (M_1(Y^1 sim mathbf{X}^1)) to foretell (Y) for the (T=1) group and (M_2(Y^0 sim mathbf{X}^0)) to foretell (Y) for the group (T= 0).
Whereas the T-learner helps overcome the constraints of the S-learner, it introduces a brand new downside: it doesn’t make the most of all out there information when estimating (M_1) and (M_2). The X-learner, which we introduce subsequent, addresses this by making certain the complete dataset is used effectively for CATE estimation.
A.3 X-learner
We first current the steps, then demystify their motivation. The X-learner proceeds in 4 steps:
Match the result fashions: [ hat{mu}_0(x) text{ using } M_1(Y^0 sim mathbf{X}^0) ; text{and }hat{mu}_1(x) text{ using } M_2(Y^1 sim mathbf{X}^1) ]
Match the fashions to estimate: start{align} tau_1(mathbf{x}) &= mathbb{E}(tilde{D}^1 mid mathbf{X} = mathbf{x}), quad textual content{estimated by way of } quad M_3(tilde{D}^1 sim mathbf{X}^1) tau_0(mathbf{x}) &= mathbb{E}(tilde{D}^0 mid mathbf{X} = mathbf{x}), quad textual content{estimated by way of } quad M_4(tilde{D}^0 sim mathbf{X}^0) finish{align}
Mix estimates (hat{tau}_0(mathbf{x}) ) and (hat{tau}_1(mathbf{x}) ) to acquire the specified CATE estimator: [ hat{tau}_X(mathbf{x}) = g(mathbf{x}) hat{tau}_0(mathbf{x}) + {1 – g(mathbf{x})} hat{tau}_1(mathbf{x}) tag{4}label{eq:catexlearner} ] the place ( g(mathbf{x}) in [0,1] ) is a weight perform whose aim is to reduce the variance of (tau(mathbf{x})). An estimator of the propensity rating ( e(mathbf{x}) = mathbb{P}(T=1 mid mathbf{X}=mathbf{x}) ) is one doable alternative for (g(mathbf{x})).
As might be seen, step one of the X-learner is strictly the identical because the T-learner. Separate regression fashions are match to the remedy and management group information. The following two steps type the ingenuity of the strategy, as a result of that is the place all information from each fashions are utilized and the place the “X” (cross-estimation) in X-learner derives its that means. In step 2, (tilde{D}_i^1) and (tilde{D}_i^0) are the ITE estimates for the remedy and management teams, respectively. (tilde{D}_i^1) makes use of the remedy group outcomes and the imputed counterfactual obtained from (hat{mu}_0) in step 1. Analogously, (tilde{D}_i^0) is computed utilizing the management group outcomes and the imputed counterfactual estimated from (hat{mu}_1). This latter step ensures that the ITE estimates for every group make the most of information from each the remedy and management teams. Nonetheless, every of the estimates (tilde{D}_i^1) and (tilde{D}_i^0) makes use of solely a single commentary from its corresponding group. To handle this, the X-learner matches two completely different regression fashions in step 3, leading to two estimates: (hat{tau}_1(mathbf{x})), which intends to successfully estimate (E(Y^1|mathbf{X} = mathbf{x})), and (hat{tau}_0(mathbf{x})), which intends to estimate (E(Y^0|mathbf{X} = mathbf{x})). Lastly, step 4 combines these two estimates right into a single CATE estimate. Relying on the dataset, the selection of the load perform (g(mathbf{x})) could fluctuate. If the sizes of the remedy and management teams differ considerably, one may select (g(mathbf{x})=0) or (g(mathbf{x})=1) to prioritize one group’s estimate. In our evaluation, we use (g(x) = 0.5) to equally weight the estimates from each teams.
References
Athey, S., J. Tibshirani, and S. Wager. 2019. Generalized random forests. Annals of Statistics 47: 1148–1178. https://doi.org/10.1214/18-AOS1709.
Gerber, A., D. P. Inexperienced, and C. W. Larimer. 2008. Social stress and voter turnout: Proof from a large-scale discipline experiment. American Political Science Evaluate 102: 33–48. https://doi.org/10.1017/S000305540808009X.
Jacob, D. 2021. CATE meets ML: Conditional common remedy impact and machine studying. Dialogue Papers 2021-005, Humboldt-Universität of Berlin, Worldwide Analysis Coaching Group 1792. Excessive-Dimensional Nonstationary Time Collection.
Künzel, S. R., J. S. Sekhon, P. J. Bickel, and B. Yu. 2019. Metalearners for estimating heterogeneous remedy results utilizing machine studying. Proceedings of the Nationwide Academy of Sciences 116: 4156–4165. https://doi.org/10.1073/pnas.1804597116.
Robins, J., L. Li, E. Tchetgen, and A. van der Vaart. 2008. Larger order affect capabilities and minimax estimation of nonlinear functionals. Institute of Mathematical Statistics Collections 2: 335–421. https://doi.org/10.1214/193940307000000527.
Robins, J. M., S. D. Mark, and W. Ok. Newey. 1992. Estimating publicity results by the expectation of publicity conditional on confounders. Biometrics 48: 479–495.
Robins, J. M., and A. Rotnitzky. 1995. Semiparametric effectivity in multivariate regression fashions with lacking information. Journal of the American Statistical Affiliation 90 122–129. https://doi.org/10.2307/2291135.
van der Laan, M. J. 2006. Statistical inference for variable significance. Worldwide Journal of Biostatistics Artwork. 2. https://doi.org/10.2202/1557-4679.1008.
Vegetabile, B. G. 2021. On the excellence between “conditional common remedy results” (CATE) and “particular person remedy results” (ITE) underneath ignorability assumptions. arXiv:2108.04939 [stat.ME]. https://doi.org/10.48550/arXiv.2108.04939.
Multimodal vision-language fashions (VLMs) proceed to realize ever-improving scores on chart understanding benchmarks. But, we discover that this progress doesn’t totally seize the breadth of visible reasoning capabilities important for decoding charts. We introduce EncQA, a novel benchmark knowledgeable by the visualization literature, designed to offer systematic protection of visible encodings and analytic duties which can be essential for chart understanding. EncQA supplies 2,076 artificial question-answer pairs, enabling balanced protection of six visible encoding channels (place, size, space, coloration quantitative, coloration nominal, and form) and eight duties (discover extrema, retrieve worth, discover anomaly, filter values, compute derived worth actual, compute derived worth relative, correlate values, and correlate values relative). Our analysis of 9 state-of-the-art VLMs reveals that efficiency varies considerably throughout encodings inside the identical process, in addition to throughout duties. Opposite to expectations, we observe that efficiency doesn’t enhance with mannequin dimension for a lot of task-encoding pairs. Our outcomes recommend that advancing chart understanding requires focused methods addressing particular visible reasoning gaps, slightly than solely scaling up mannequin or dataset dimension.
ORLANDO, Fla. — The seller group has but to totally clear up the pricing drawback for agentic AI. That is in line with Salesforce CEO and Time journal proprietor Marc Benioff, who spoke with Yvonne Genovese, govt vp of enterprise and know-how insights at Gartner, throughout a keynote Tuesday at Gartner’s IT Symposium/Xpo in Orlando, Fla.
Whereas Salesforce has opted to current personalized choices to clients for agentic AI pricing, Benioff mentioned the corporate continues to be figuring out the most effective method for pricing — together with each different vendor.
The concession was the one pointed critique that Benioff — contemporary off his firm’s blockbuster Dreamforce convention and days after retracting his assertion about deploying Nationwide Guard troops to San Francisco — provided relating to the corporate’s push to make agentic AI an integral and dynamic function of the Salesforce platform.
“About 9 months in the past, I made the choice that I wasn’t simply going to have an FAQ and I wasn’t simply going to have a bot, however I used to be going to unleash an ‘agentic layer’ or brokers, and hyperlink them into the entire service platform,” Benioff mentioned.
The newest iteration is Agentforce 360, a three-year growth effort that the corporate unveiled at its Dreamforce occasion this 12 months. The end result, Benioff mentioned, is a platform that within the area of per week returned 50,000 incoming gross sales calls, releasing up time for Salesforce’s 20,000 salespeople.
“An agentic enterprise is unquestionably an organization the place people and brokers are working collectively and are optimized,” Benioff mentioned.
Headcounts, Methods to Pay for Agentic AI
Nevertheless, the usage of agentic AI at Salesforce comes with a worth of its personal — Genovese identified that Salesforce lately laid off 4,000 customer support brokers as the corporate depends extra on Agentforce to reply buyer calls.
“We have now extra staff than we have ever had proper now,” Benioff responded, in a nod to the corporate’s present workforce of 70,000 — nevertheless it’s balanced “otherwise.”
“I’ve a smaller share in service … I tilted extra to distribution, as a result of there have been issues that I did that swiftly created extra alternative for me,” he mentioned.
Along with affecting headcount, there’s one other situation with agentic AI — pricing and ROI, Genovese defined. CIOs cannot justify the price of AI on productiveness enhancements alone and are tasked with demonstrating the ROI of AI investments to their CEOs, she mentioned.
“One of many issues that [CIOs] are combating is that they do not know easy methods to pay for this factor that you simply’re speaking about. This isn’t off the shelf. You are not going to go and take your AI, level it at your information and say, ‘Go forth and prosper,'” Genovese mentioned.
Pricing agentic AI in a way that is palatable to clients is certainly tough, Benioff acknowledged. Clients differ on how they wish to pay for agentic AI, together with primarily based on final result, per consumer, per motion, or by consumption, which has created challenges in pricing the know-how, he mentioned.
“So we launched a brand new agentic enterprise license settlement, which is only a versatile mannequin that offers us the power to open it up, that the shopper can select their pricing,” Benioff mentioned. He added that the corporate isn’t at a spot the place it will probably dictate pricing however as a substitute must “let clients have final flexibility on pricing.”
AI ROI Requires ‘Excessive Partnership’ Between Distributors, CIOs
Nonetheless, CIOs want extra than simply versatile pricing choices, Genovese mentioned, urgent Benioff on how they’ll reveal the ROI for AI.
“That is going to take excessive partnership,” Benioff mentioned. “And for those who assume anyone has the entire reply or any vendor will get on this stage and says, ‘Oh, I do know precisely what to do right here on this planet of this new agentic enterprise.’ No, they’ve made a mistake.”
Distributors must change the best way they work with clients, working intently with them to find out how “extremely personalized pricing” can help their AI methods, he mentioned.
Benioff additionally challenged Gartner to step up in fixing the agentic AI pricing drawback, encouraging the analysis agency to information CIOs on getting the appropriate worth.
“Clearly, Gartner goes to assist the shopper with the seller choice, the pricing, the settlement,” Benioff mentioned. “This is a chance the place Gartner can step in and elevate all of us.”
Synthetic intelligence took over because the star at Google I/O 2025, showcasing a number of the finest tech options from the corporate. Google continues to goal for management in AI by exhibiting off greater than 100 AI-enabled updates throughout its merchandise at one time.
From improved language know-how to video creation instruments and from real-time fraud detection to AI helpers, these bulletins spotlight a recent and thrilling time for Google’s services. This yr’s occasion wasn’t nearly incremental upgrades. It was about redefining what AI can do in our each day lives, work, and artistic endeavors.
Let’s overview the highest 15 AI bulletins from Google I/O 2025.
Google unveiled two main updates to its Gemini household. The two.5 Professional model introduces a brand new “Deep Assume” mode, providing stronger reasoning capabilities for extra complicated duties. Gemini 2.5 Flash, however, is optimized for velocity, making it wonderful for fast, high-volume queries. Each help native audio responses and improved privateness instruments.
2. Veo 3: Breakthrough in AI Video Creation
Veo 3 stole the highlight with its capability to generate sensible video content material, full with synchronized dialogue and ambient sounds. Google even recreated the well-known “Will Smith consuming spaghetti” clip to exhibit simply how far AI video has come.
3. Move: The AI Assistant for Filmmakers
Move is a brand new instrument designed for creators. It lets customers flip scripts or pictures into brief movies utilizing the mixed energy of Veo and Imagen. Whether or not you’re a hobbyist or a professional, Move makes AI-powered filmmaking accessible.
4. Imagen 4: Extra Real looking Picture Technology
Picture Supply: Google
Google upgraded its picture technology instrument with Imagen 4, delivering sharper visuals, higher lighting, and extra correct particulars. It’s now able to producing close to photo-quality outcomes from easy textual content prompts.
The mannequin excels at dealing with complicated scenes and textures, making it ideally suited for each artists and entrepreneurs. Imagen 4 additionally brings higher understanding of person intent, lowering mismatches in visible output.
5. Venture Astra: The Subsequent-Gen AI Helper
Astra isn’t simply one other assistant. It’s constructed to reply in real-time via your cellphone’s digicam. From figuring out objects to answering follow-up questions primarily based on visible enter, Astra goals to be your most interactive AI companion but.
It combines speech, imaginative and prescient, and context to reply naturally in stay situations. Google envisions Astra as a hands-free co-pilot for on a regular basis problem-solving.
6. AlphaEvolve: Instructing AI to Uncover
Video Supply: Google
AlphaEvolve represents a brand new course in AI analysis. As an alternative of simply making use of identified strategies, this technique can uncover and refine its personal algorithms, shifting a step nearer to AI that learns learn how to study.
This might revolutionize fields like supplies science or finance, the place discovery is essential. The know-how builds on DeepMind’s earlier breakthroughs, corresponding to AlphaFold.
7. Gemini in Chrome: Smarter Searching
Chrome is getting a mind increase. Gemini is now a part of your browser expertise, providing context-aware solutions, summarizing pages, and serving to you discover what you want with much less effort.
Now you can ask questions instantly within the browser and get AI-curated solutions with out switching tabs. It additionally helps summarize lengthy articles or evaluate product evaluations immediately.
8. AI Mode in Search: A Conversational Overhaul
Video Supply: Google
Google Search now has an “AI Mode” that lets customers ask questions in a extra pure, conversational manner. It’s powered by Gemini and focuses on giving extra direct, summarized solutions reasonably than an inventory of hyperlinks.
You may dive deeper into follow-up questions with out rephrasing or beginning over. This mode can also be designed to work throughout gadgets, from desktop to cellular.
9. Sensible Houses with Gemini
Video Supply: Google
New instruments within the House API deliver Gemini’s smarts to linked gadgets. Assume voice-controlled routines, real-time digicam insights, and clever residence automation that responds to your habits.
It may possibly even analyze movement patterns or counsel energy-saving settings primarily based on utilization. Gemini allows extra seamless interplay between completely different gadgets in your house.
Google Docs, Gmail, and Meet are getting extra useful. Actual-time translation in Meet, smarter writing solutions in Docs, and predictive replies in Gmail make on a regular basis work smoother and quicker.
Workspace now additionally adapts its options primarily based in your workflow, saving time on repetitive duties. It’s a productiveness improve that feels private, not robotic.
AI is making on-line purchasing extra intuitive. New options embrace digital try-ons and tailor-made product solutions, designed to assist buyers make selections with confidence.
The tech additionally analyzes evaluations and worth traits to help with smarter shopping for decisions. That is a part of Google’s effort to compete extra instantly with platforms like Amazon.
12. Android Studio Meets Gemini
Builders can now depend on Gemini in Android Studio to generate app code from mockups. It helps velocity up the design-to-code course of and reduces repetitive work for engineers.
The assistant may detect bugs or counsel enhancements as you construct, making it a hands-on coding companion. It’s a big increase for each solo builders and bigger groups.
13. Rip-off Detection with AI in Android
Video Supply: Google
To guard customers, Android is rolling out real-time rip-off detection. The system listens for suspicious name cues and notifies customers earlier than they fall for a rip-off, one other instance of AI working behind the scenes for safety.
It really works completely on-device for privateness and doesn’t retailer name content material. Google says it can evolve primarily based on new rip-off techniques and person suggestions.
14. Smarter Studying with AI on YouTube
Google makes use of AI to enhance instructional movies by mechanically producing quizzes and apply questions. This goals to make studying extra energetic and fascinating for college kids of all ages.
The function is designed to help a wide range of matters, from math to historical past. It additionally recommends customized research content material primarily based on how customers work together with the fabric.
Customers would possibly see options like real-time well being teaching, contextual reminders, or AI-powered emergency alerts. It’s about making the smartwatch not simply good, however really useful.
Conclusion
Google I/O 2025 confirmed simply how far the corporate is pushing the bounds of what’s attainable with know-how. As a result of AI now offers us with good instruments, inventive software program and real-time help, it’s quickly changing into a part of how we stay each day.
These new options make it simpler for us to study, develop applications, store on-line and guarantee we’re protected by becoming into what we already do every day. Google is laying the inspiration for higher and extra helpful digital companies by including AI to Search, Android and Workspace.
There’s little doubt that these developments will go away the lab and have a long-lasting impression on our use of know-how at residence, at work and in all places else.. As they roll out, we’ll seemingly see new habits type, and even greater modifications take form in how we use and belief our instruments.