The typical gross sales rep spends solely 40% of their time really promoting. The remainder is eaten up by obligatory, however lower-value work: buyer relationship administration (CRM) updates, prospect analysis, electronic mail drafting, and countless context-switching between instruments. Earlier than you recognize it, the day has handed and also you’ve spent solely a small fraction of your time on the issues that shut offers and ship worth for patrons.
Amazon Fast is an AI assistant for work that turns questions into solutions, solutions into actions, and actions into outcomes. Fast helps reps spend extra time promoting and fewer time on administrative duties, whether or not you’re working within the browser, the desktop app, or immediately inside Microsoft 365, Outlook, and different instruments you already use on daily basis. The outcome? Your gross sales crew can cowl extra territory, shut offers sooner, and deepen buyer loyalty at any scale.
On this put up, we stroll by way of a number of ways in which Fast delivers on this promise. We cowl the complete gross sales cycle, from figuring out your highest-priority prospect, contacting them, working the deal to shut, and retaining the CRM updated because the account matures, whereas defending your scarcest useful resource: your time.
Lead scoring and prospect prioritization: give attention to the highest-value alternatives
You’re watching a listing of 200 leads in your CRM. Some stuffed out a kind 6 months in the past. Others downloaded a whitepaper final week. Just a few replied to chilly electronic mail messages. Which of them deserve your consideration in the present day?
This problem is the norm. Most gross sales groups lack visibility into which leads are literally prepared to purchase, resulting in missed alternatives and longer gross sales cycles. Or, scarce sources are used prioritizing smaller alternatives on the expense of the most important ones.
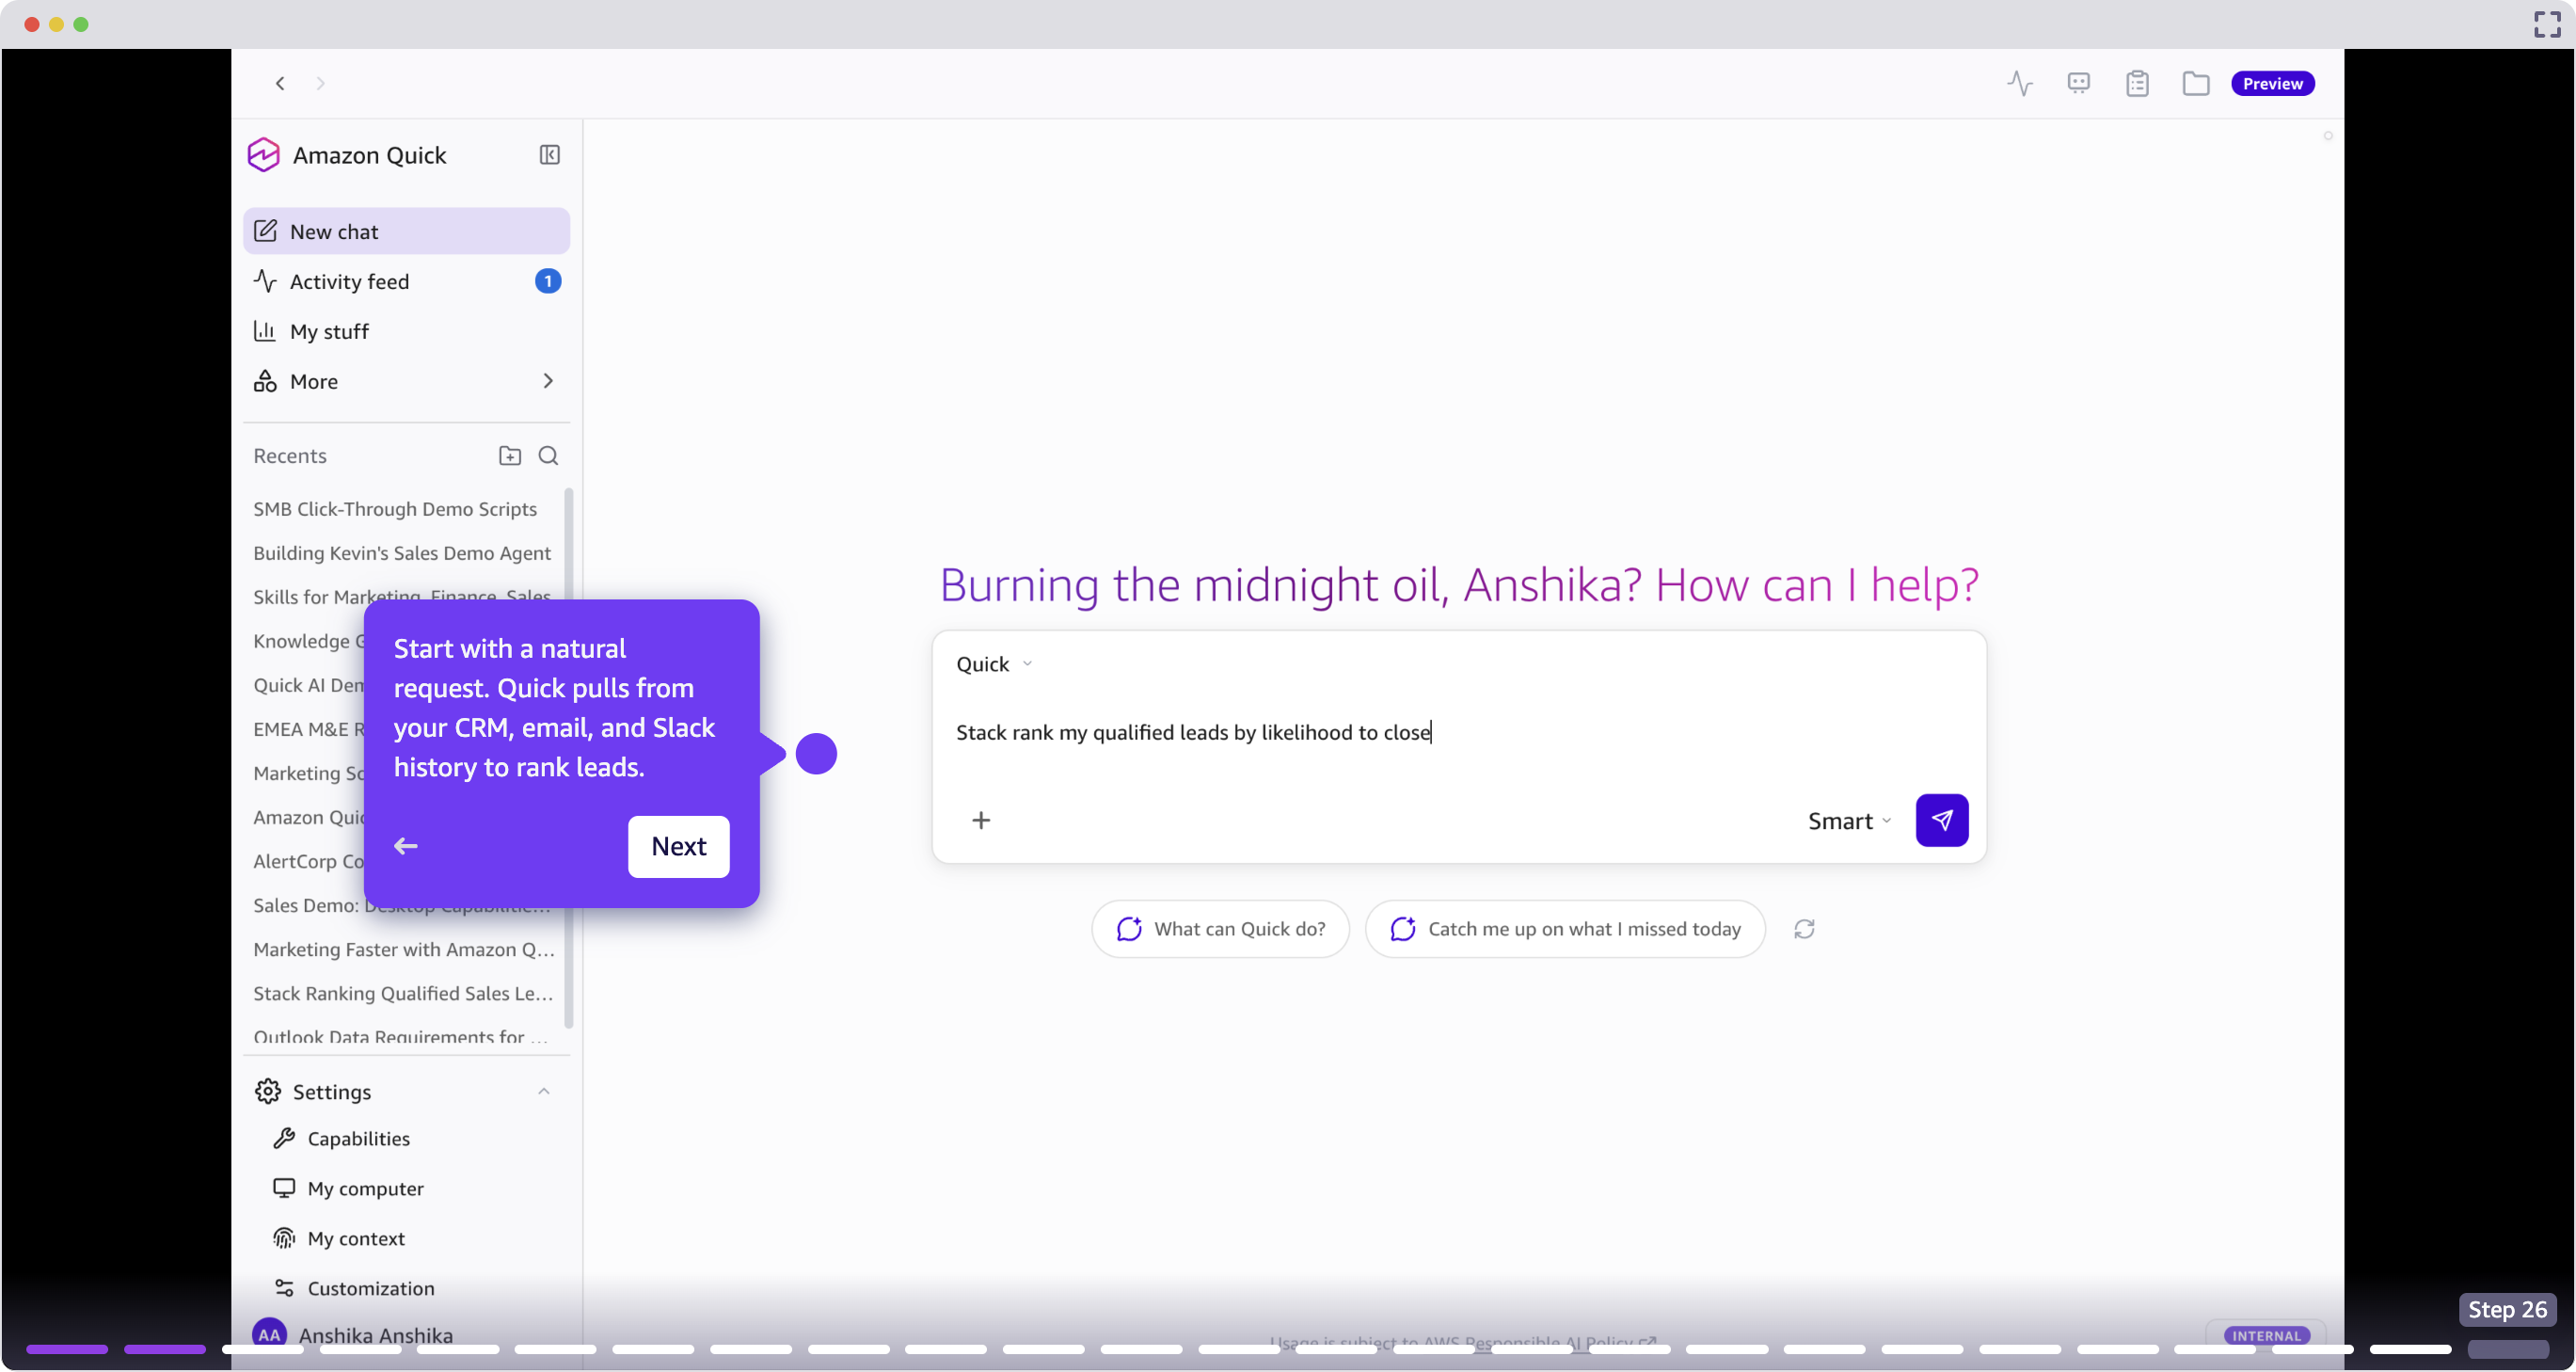
Amazon Fast helps you determine and prioritize high-intent prospects mechanically by connecting to your CRM, electronic mail, internet analytics, and help programs to research engagement indicators and dynamically rank leads by shopping for intent. With customized chat brokers that pull context from inside paperwork, alternative particulars, and account historical past, Fast helps you give attention to the prospects most probably to transform.
Earlier than we will begin prioritizing prospects for outreach, you need to combine Fast together with your present CRM system. Step-by-step directions can be found for Salesforce, HubSpot, ServiceNow, and different programs within the Fast documentation.
Begin by making a dashboard utilizing Amazon Fast Sight, the enterprise intelligence service inside Amazon Fast that’s used to construct interactive visualizations out of your linked knowledge sources. Then, use chat to immediate Fast to evaluate the dashboard and supply a listing of probably the most pressing offers to pursue.
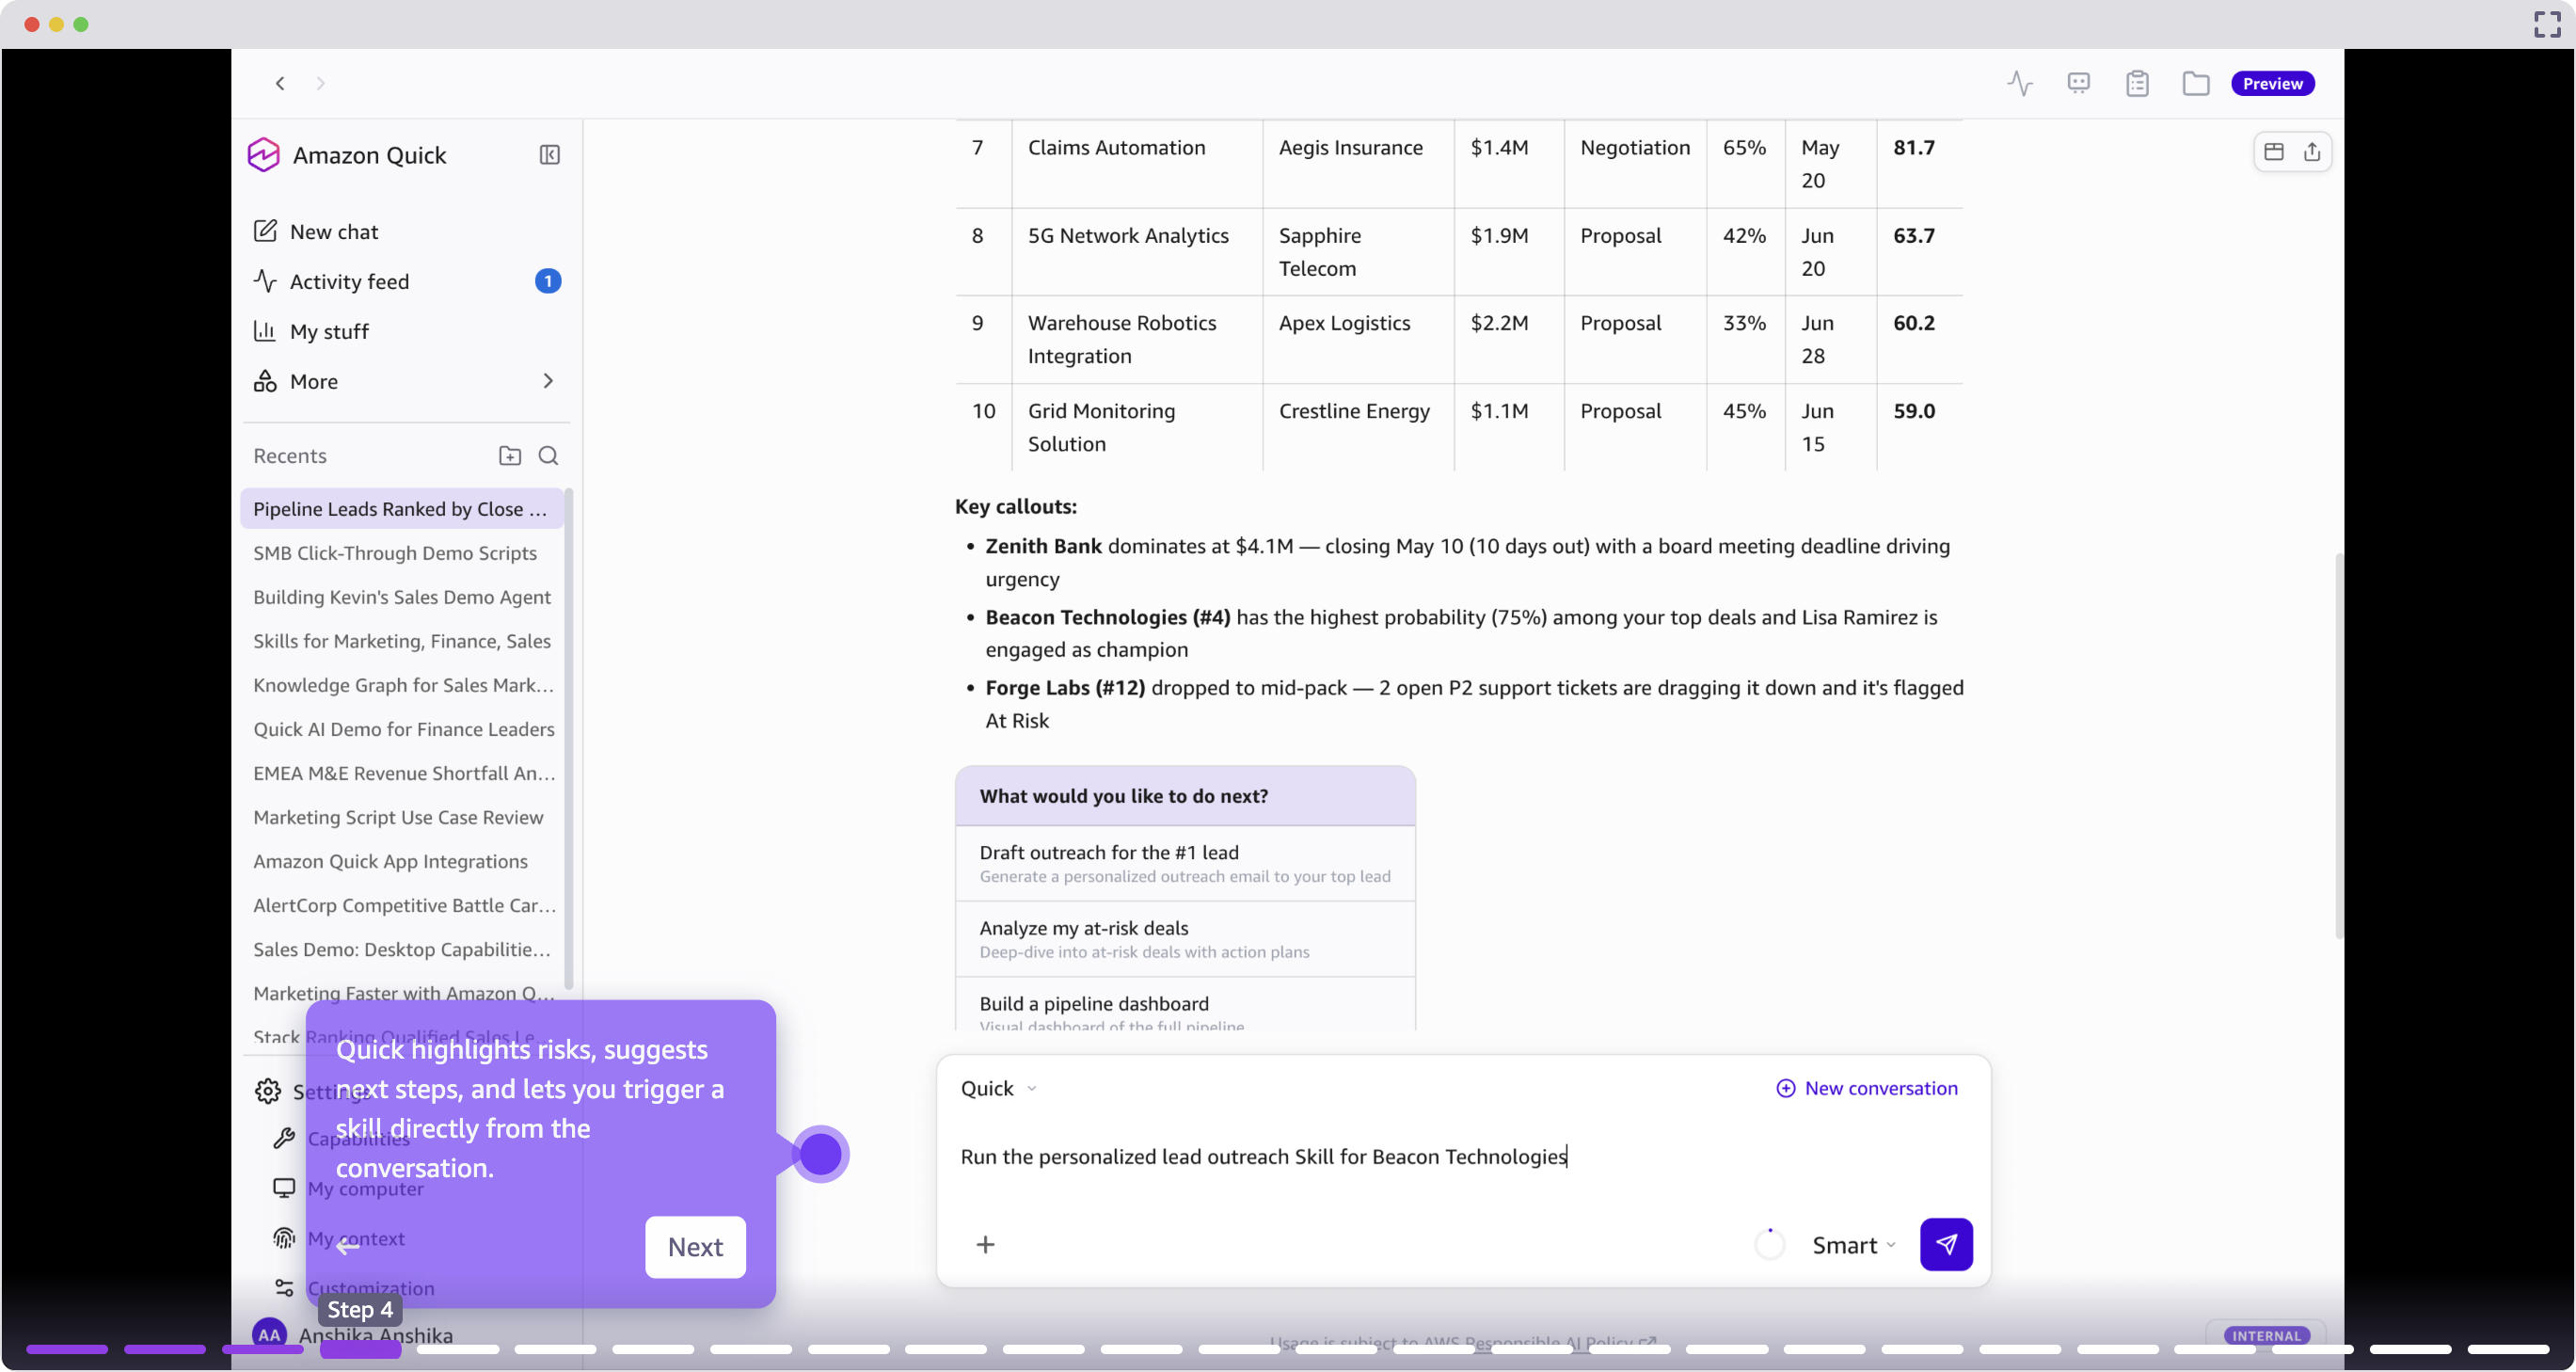
The consumer gives a pure language immediate, for instance “rank my pipeline”, and Fast aggregates knowledge throughout linked programs to provide a prioritized view. Offers with stalled development, overdue follow-ups, or aggressive strain floor on the high.
Danger detection and subsequent steps
For every deal, Fast identifies particular threat indicators comparable to stalled electronic mail threads, missed follow-ups, and competitor mentions, and recommends concrete subsequent actions. Sellers can set off a follow-up ability immediately from the dialog with out switching context.
Personalised outreach and electronic mail engagement: craft messages that resonate in seconds
Now that you just’ve recognized your highest-priority prospect, it’s time to succeed in out. Historically, crafting a message that’s sufficiently customized required you to manually search throughout your CRM, inside paperwork, and exterior indicators like the corporate’s web site, current press releases, and your prospect’s LinkedIn web page. The choice is to ship a generic electronic mail message that may nearly definitely be ignored.
Fast removes this tradeoff, serving to you craft extremely tailor-made outreach that references particular context comparable to current firm information, ache factors from previous interactions, and related use instances, with out hours of guide analysis.
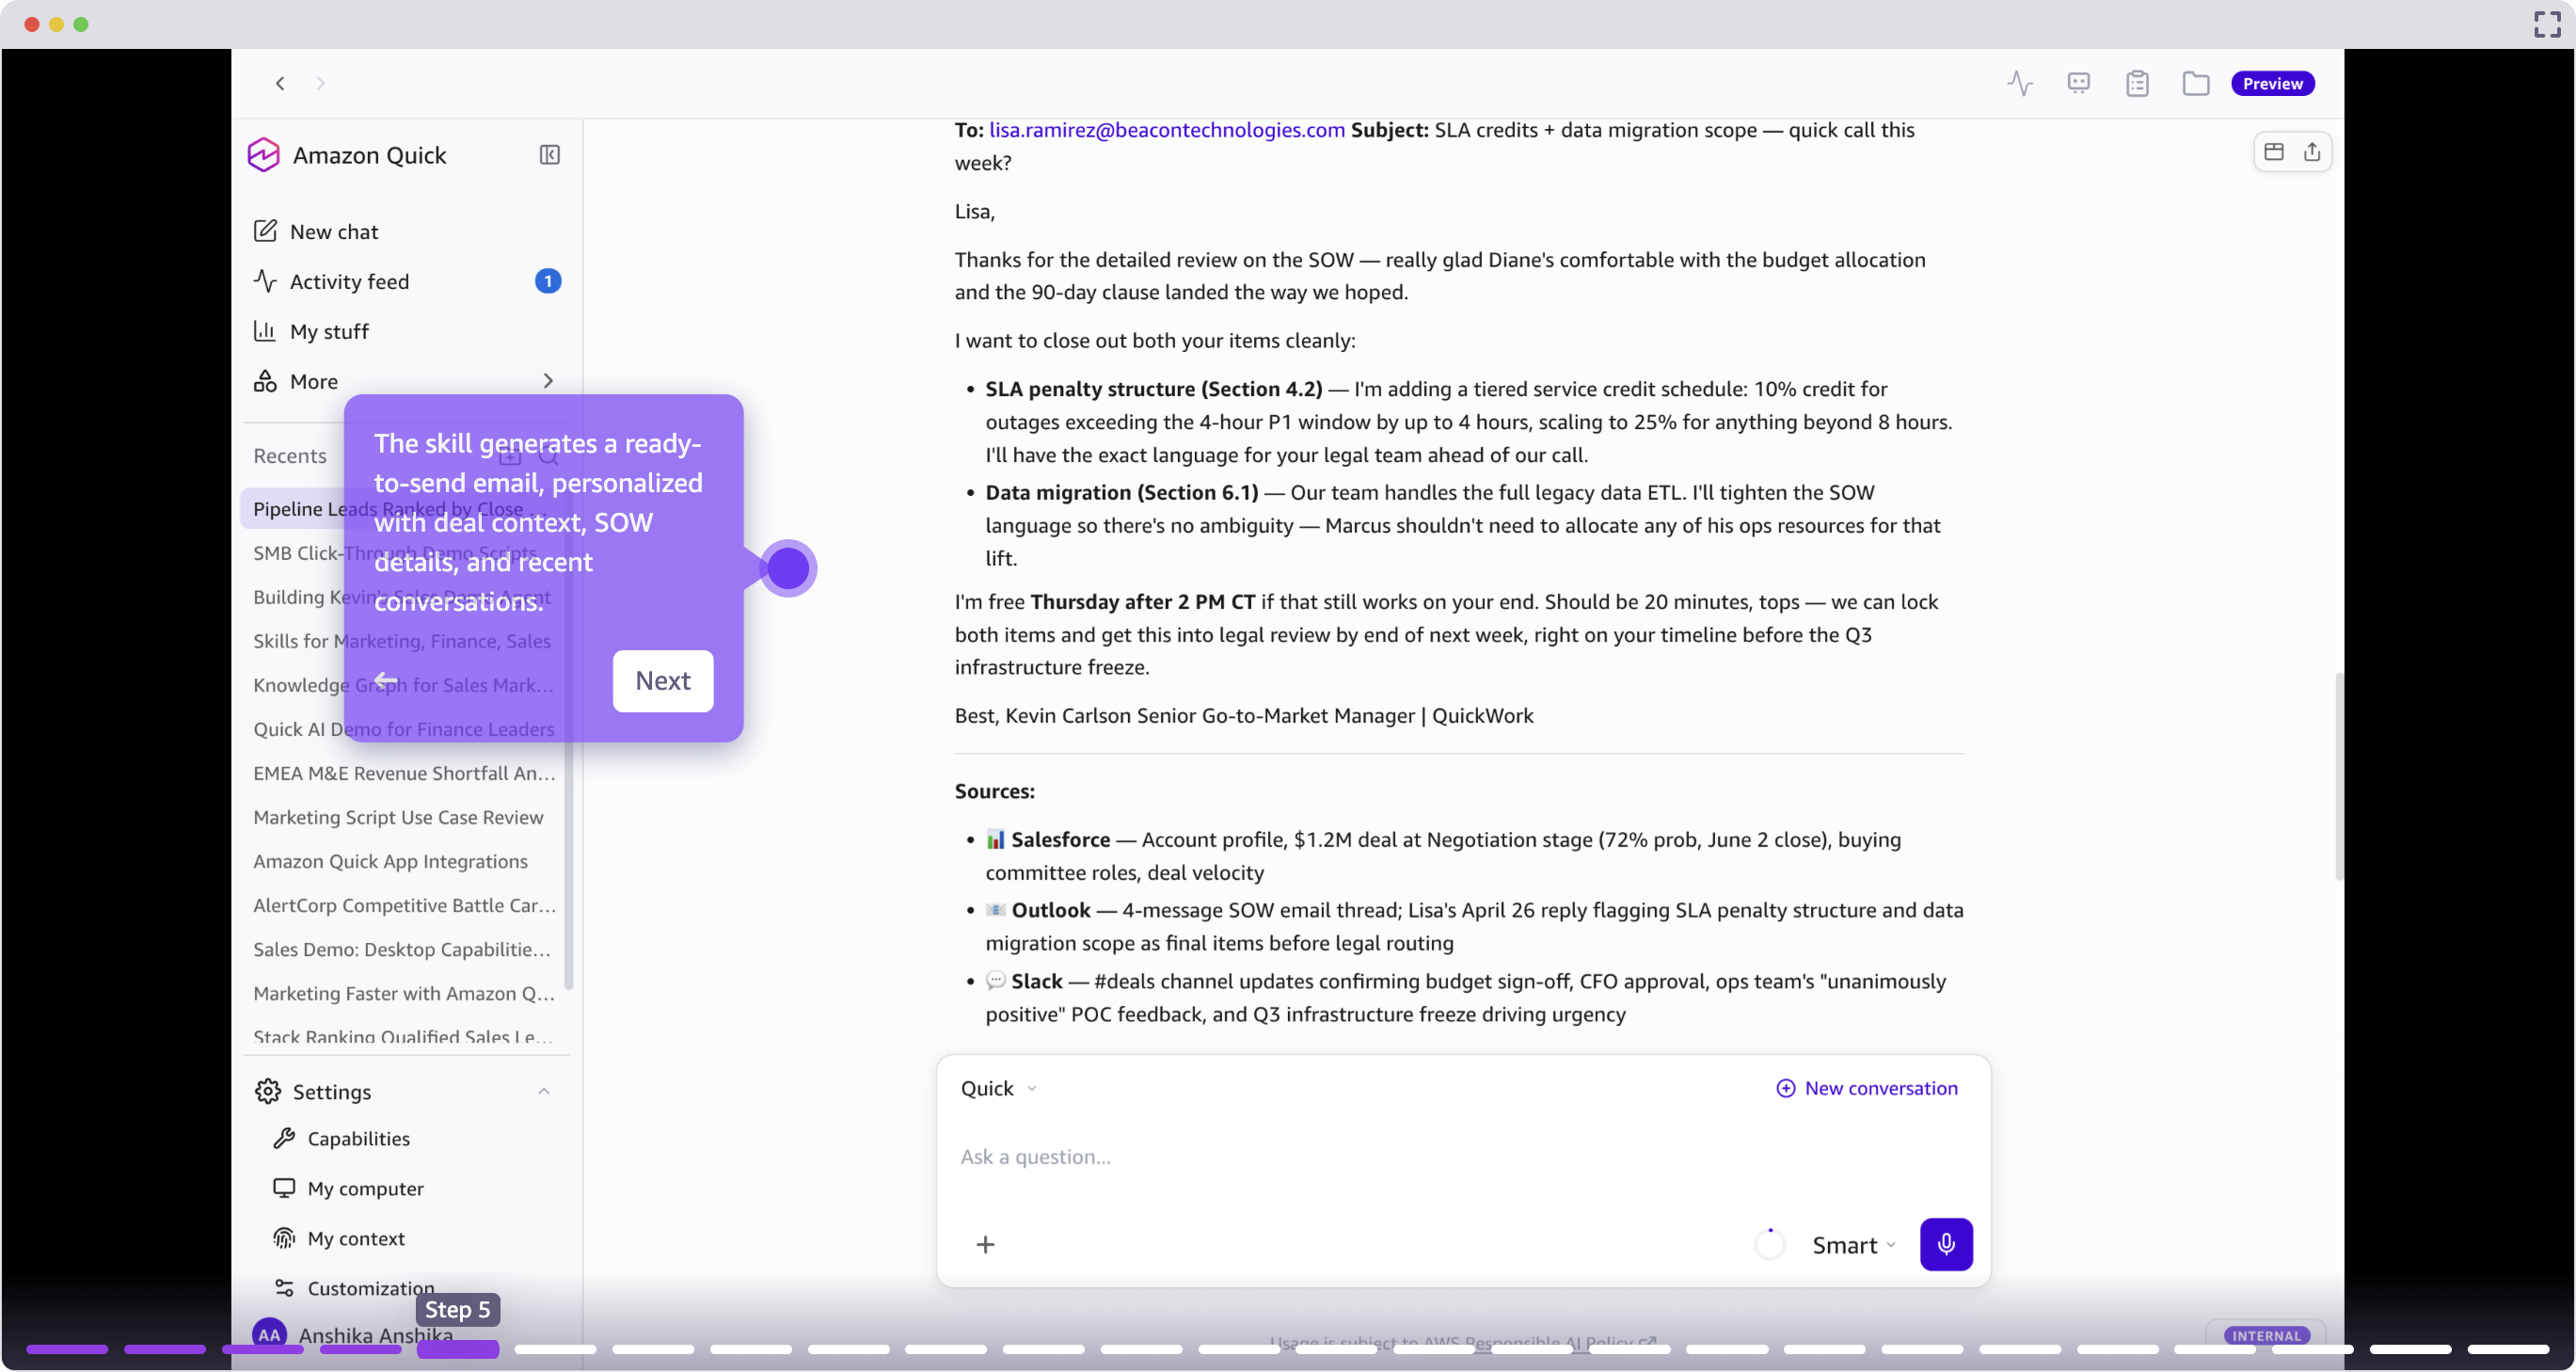
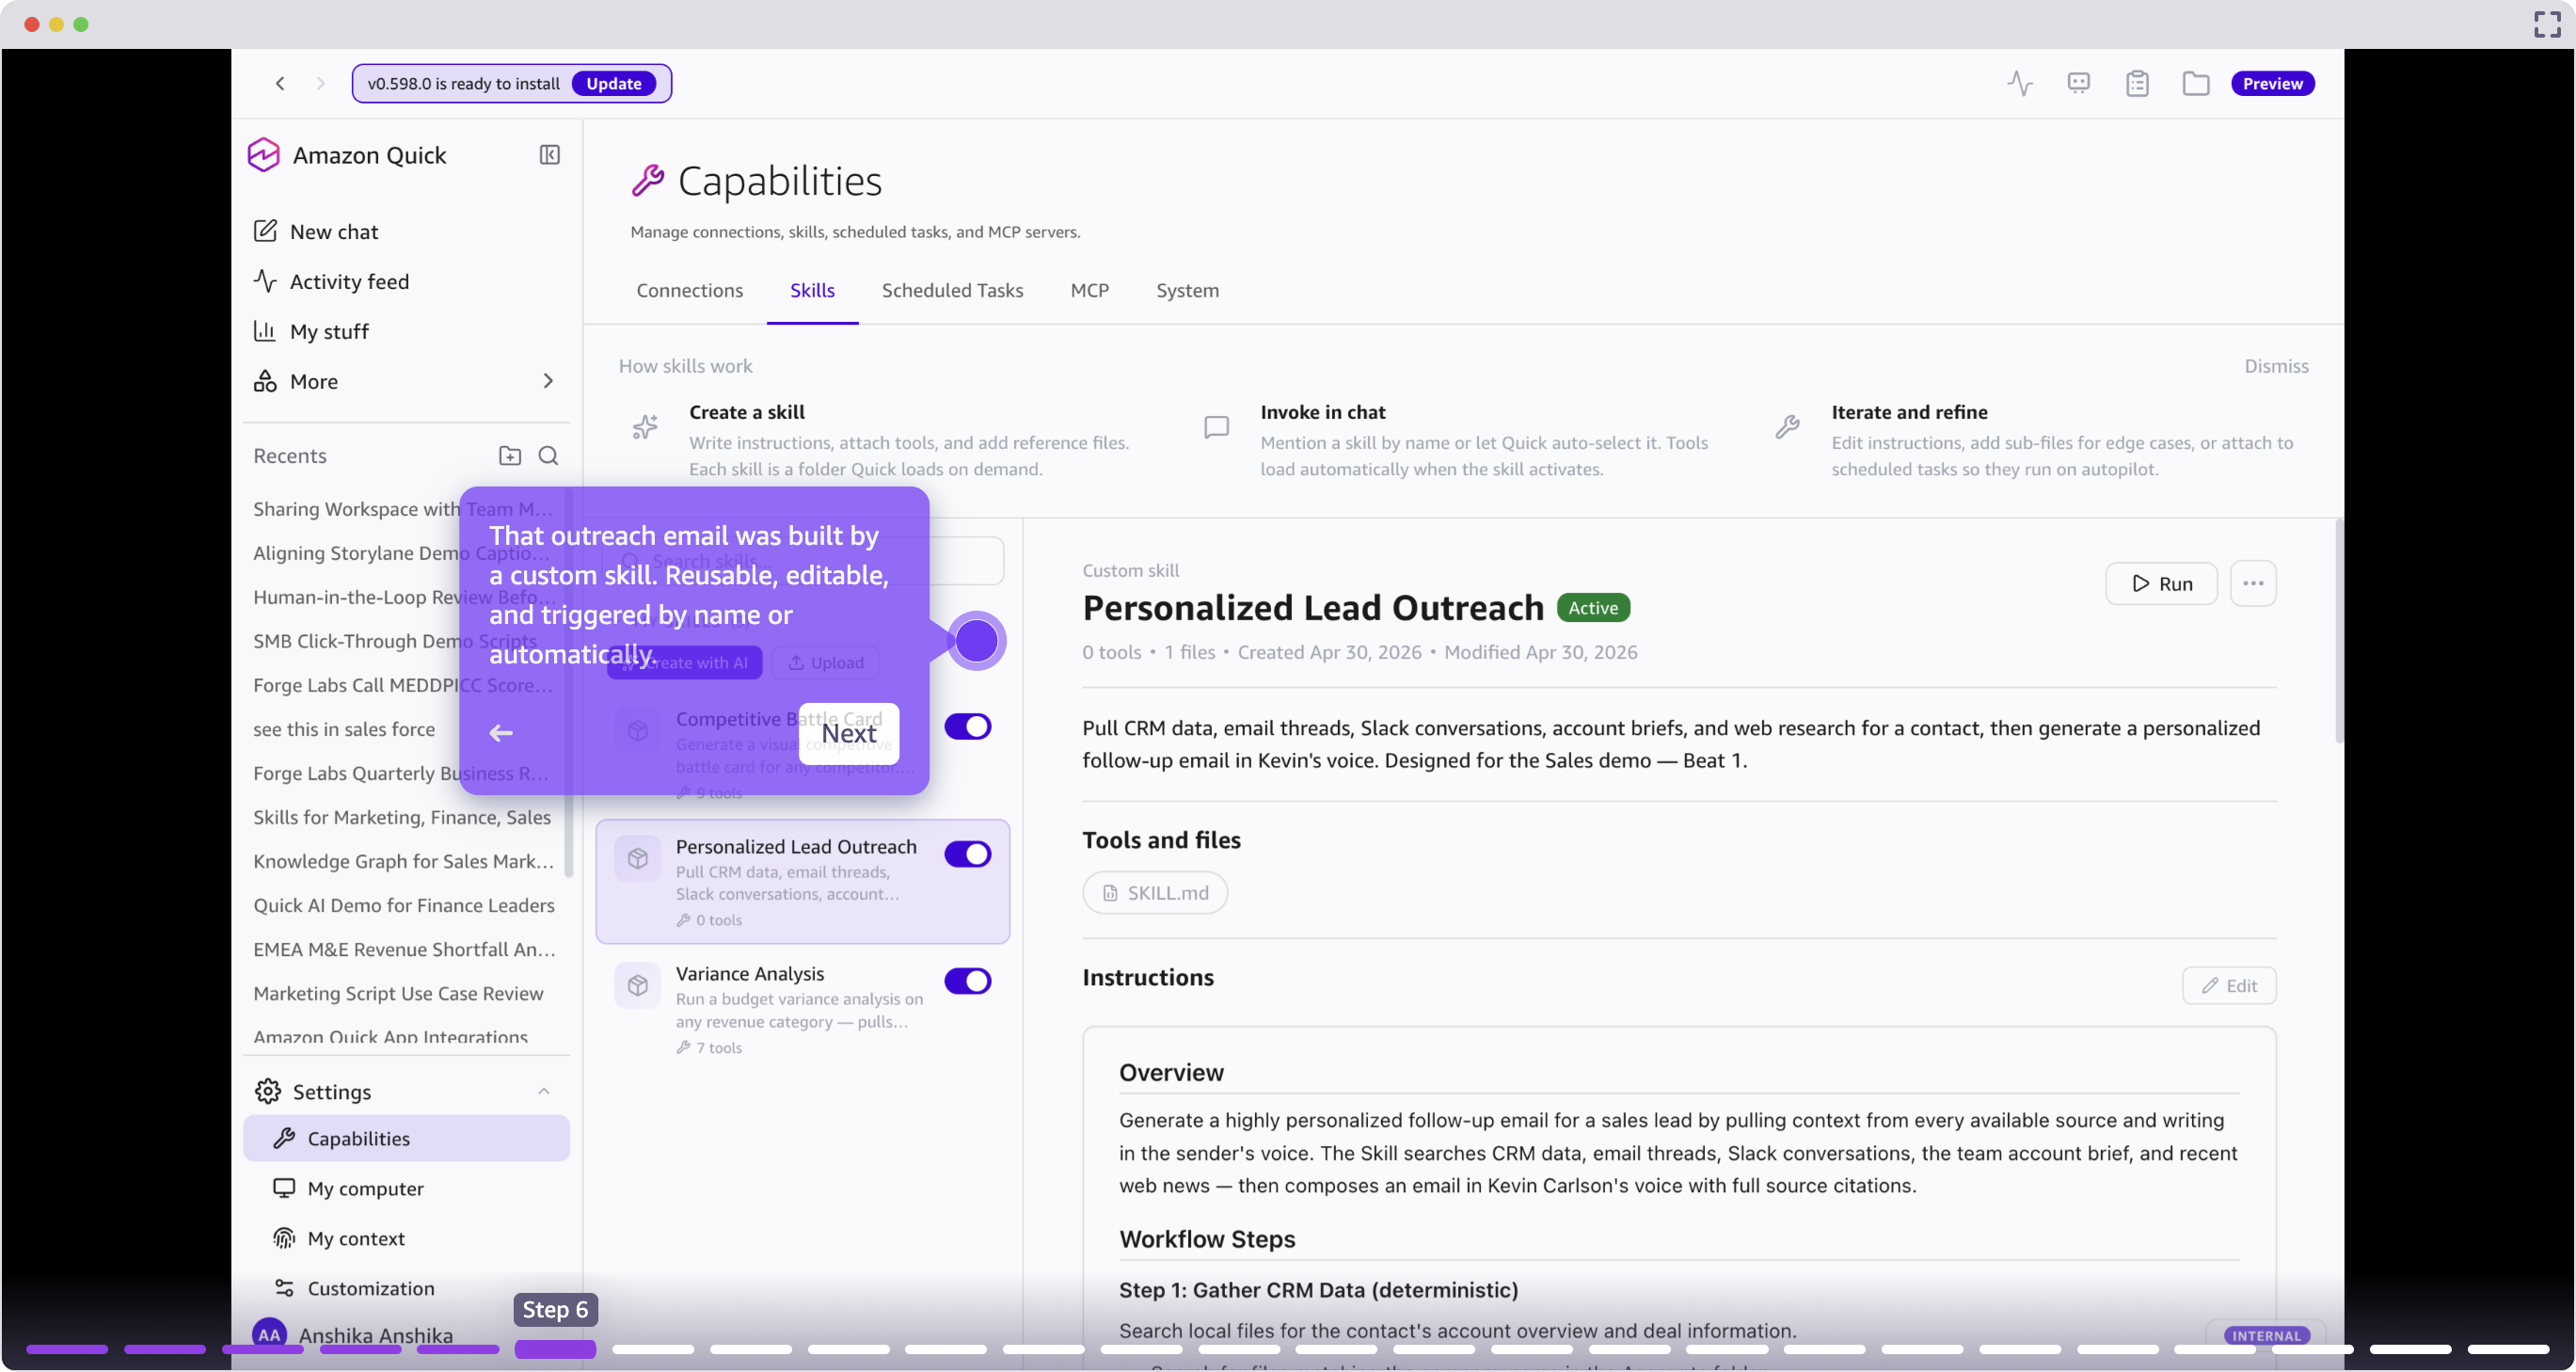
As a result of this can be a recurring problem, you possibly can create a ability utilizing Amazon Fast: a reusable, automated workflow that runs a collection of steps in your behalf. On this case, we inform Fast to “analysis a prospect by pulling knowledge from a number of sources (CRM, electronic mail threads, Slack conversations, account briefs, and internet analysis), then generate a personalised outreach message.” You utilize this ability for the present prospect, however you possibly can repurpose it throughout all of your accounts going ahead.
This step requires you to combine Outlook with Amazon Fast.
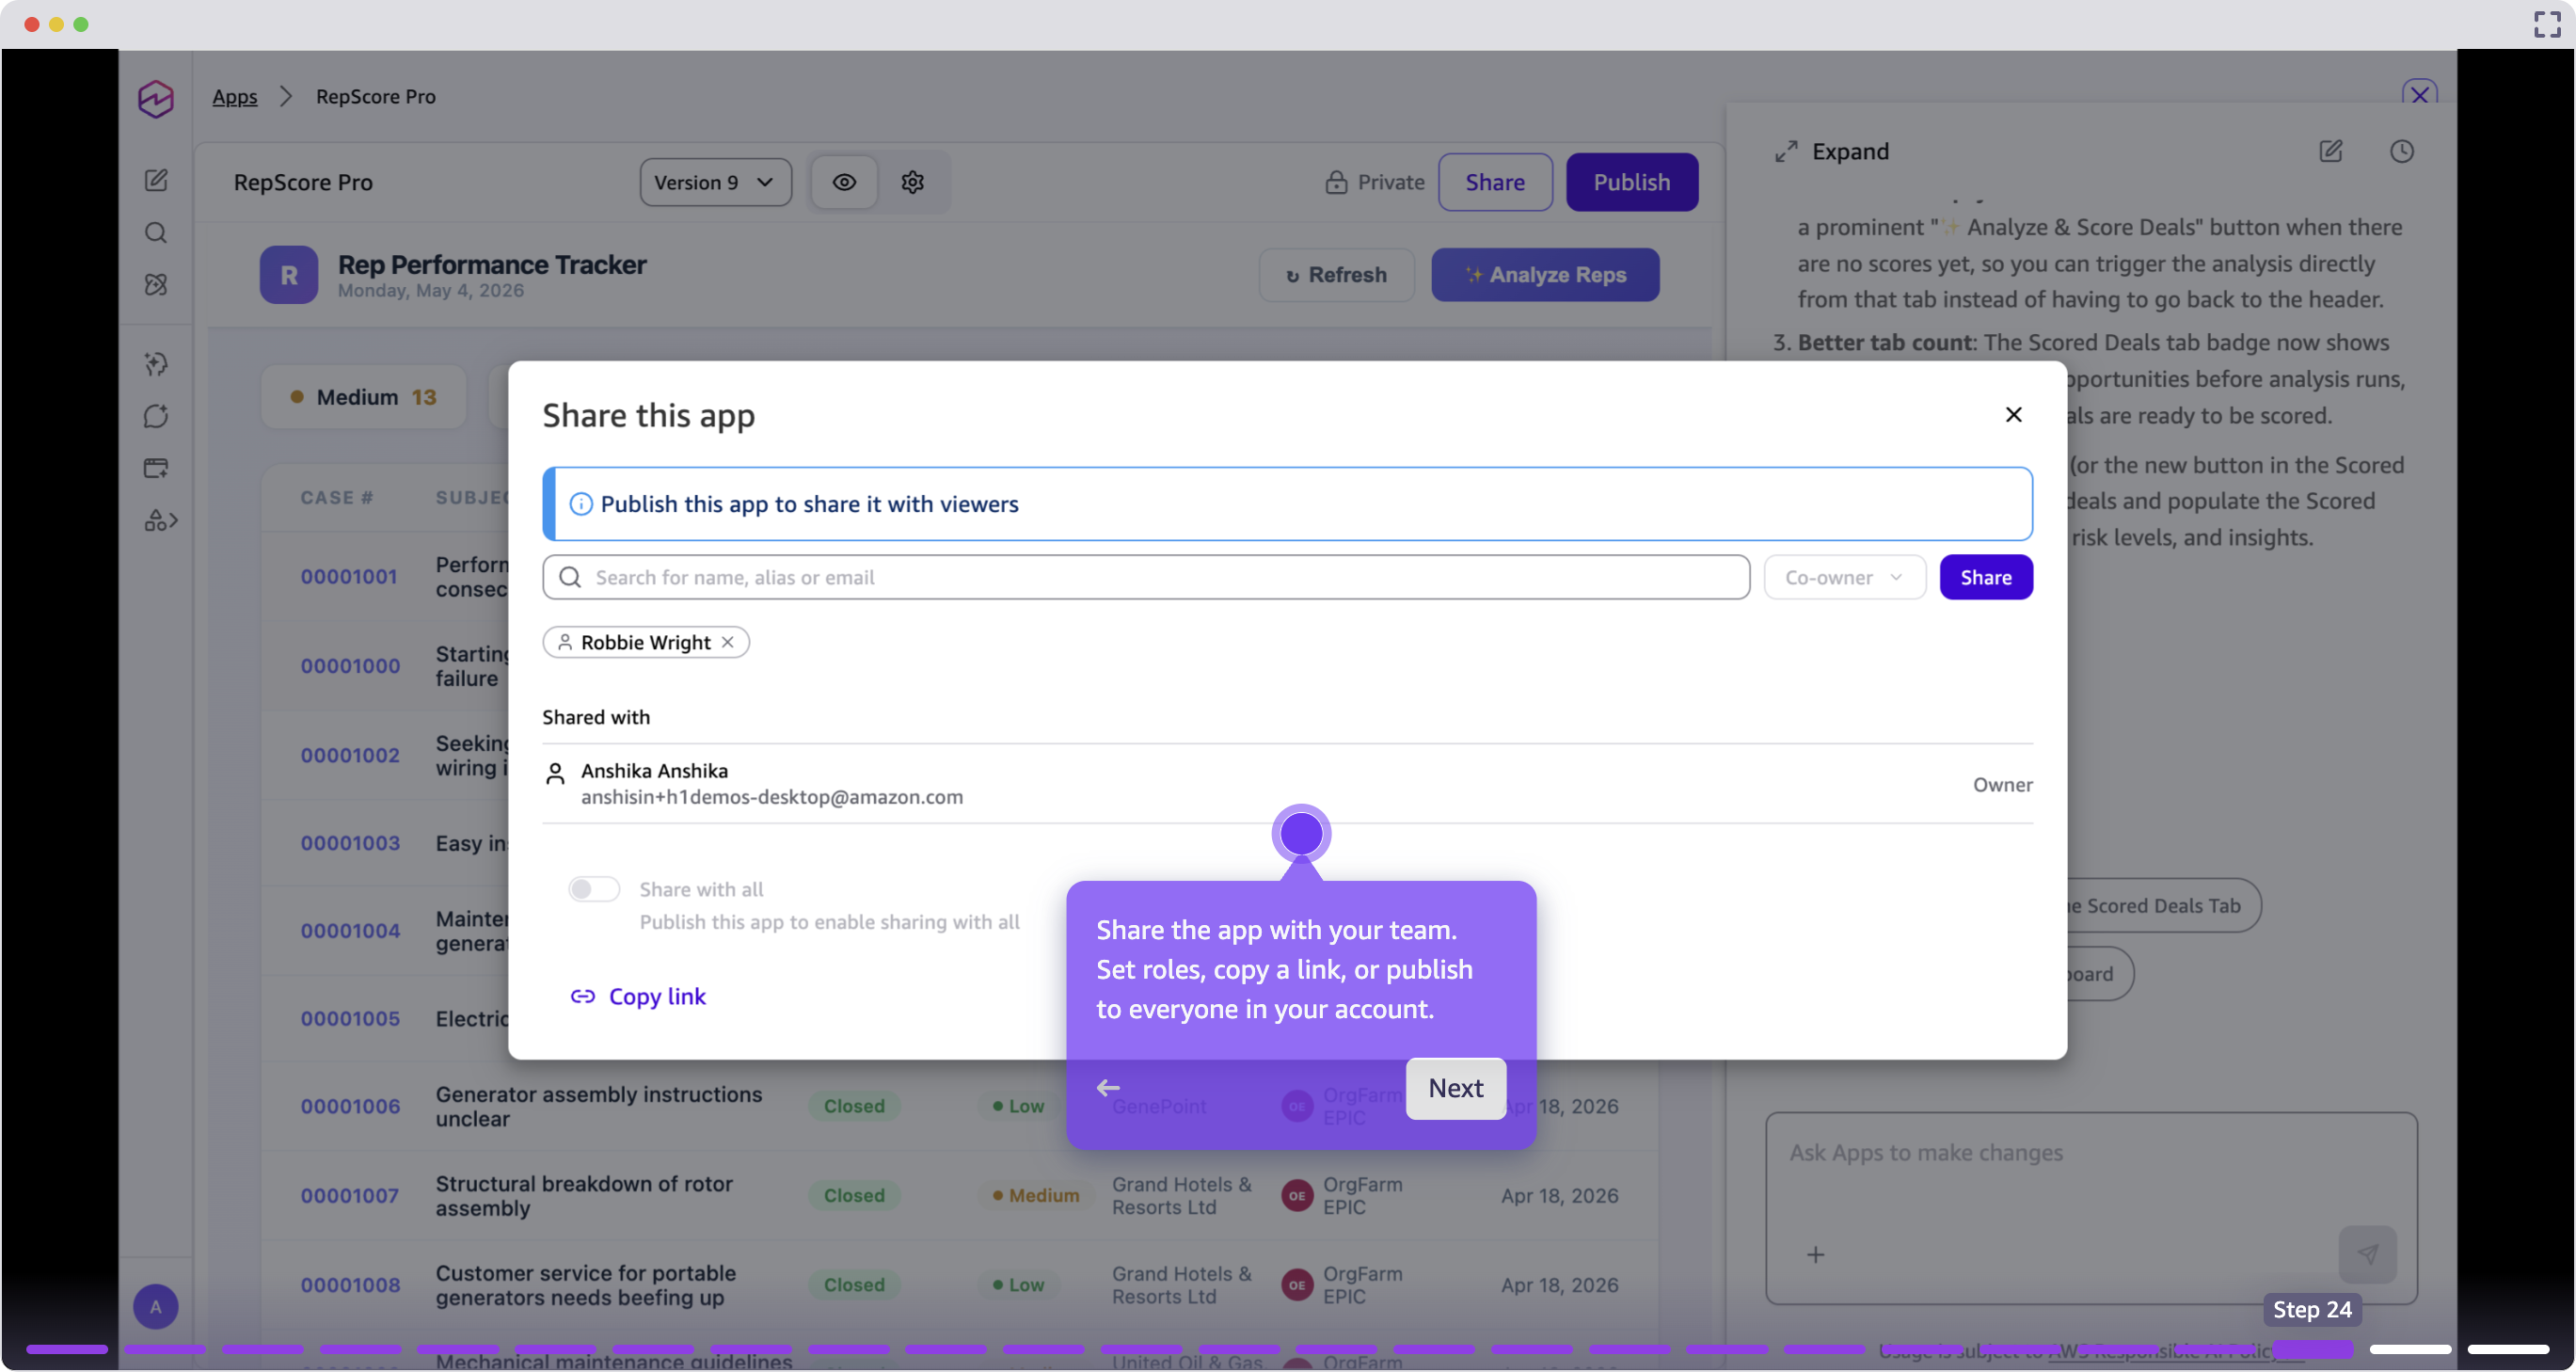
This outreach is powered by a customized ability: a reusable workflow that any crew member can set off by identify or configure to run mechanically when situations are met. After reviewing the e-mail and offering any suggestions, you possibly can ship it immediately from Fast.
With the extensions for Microsoft 365, you can even work immediately inside Outlook or Groups. Fast surfaces as a facet panel inside your electronic mail consumer, so you possibly can generate customized outreach, pull account context, and refine messaging with out ever switching tabs.
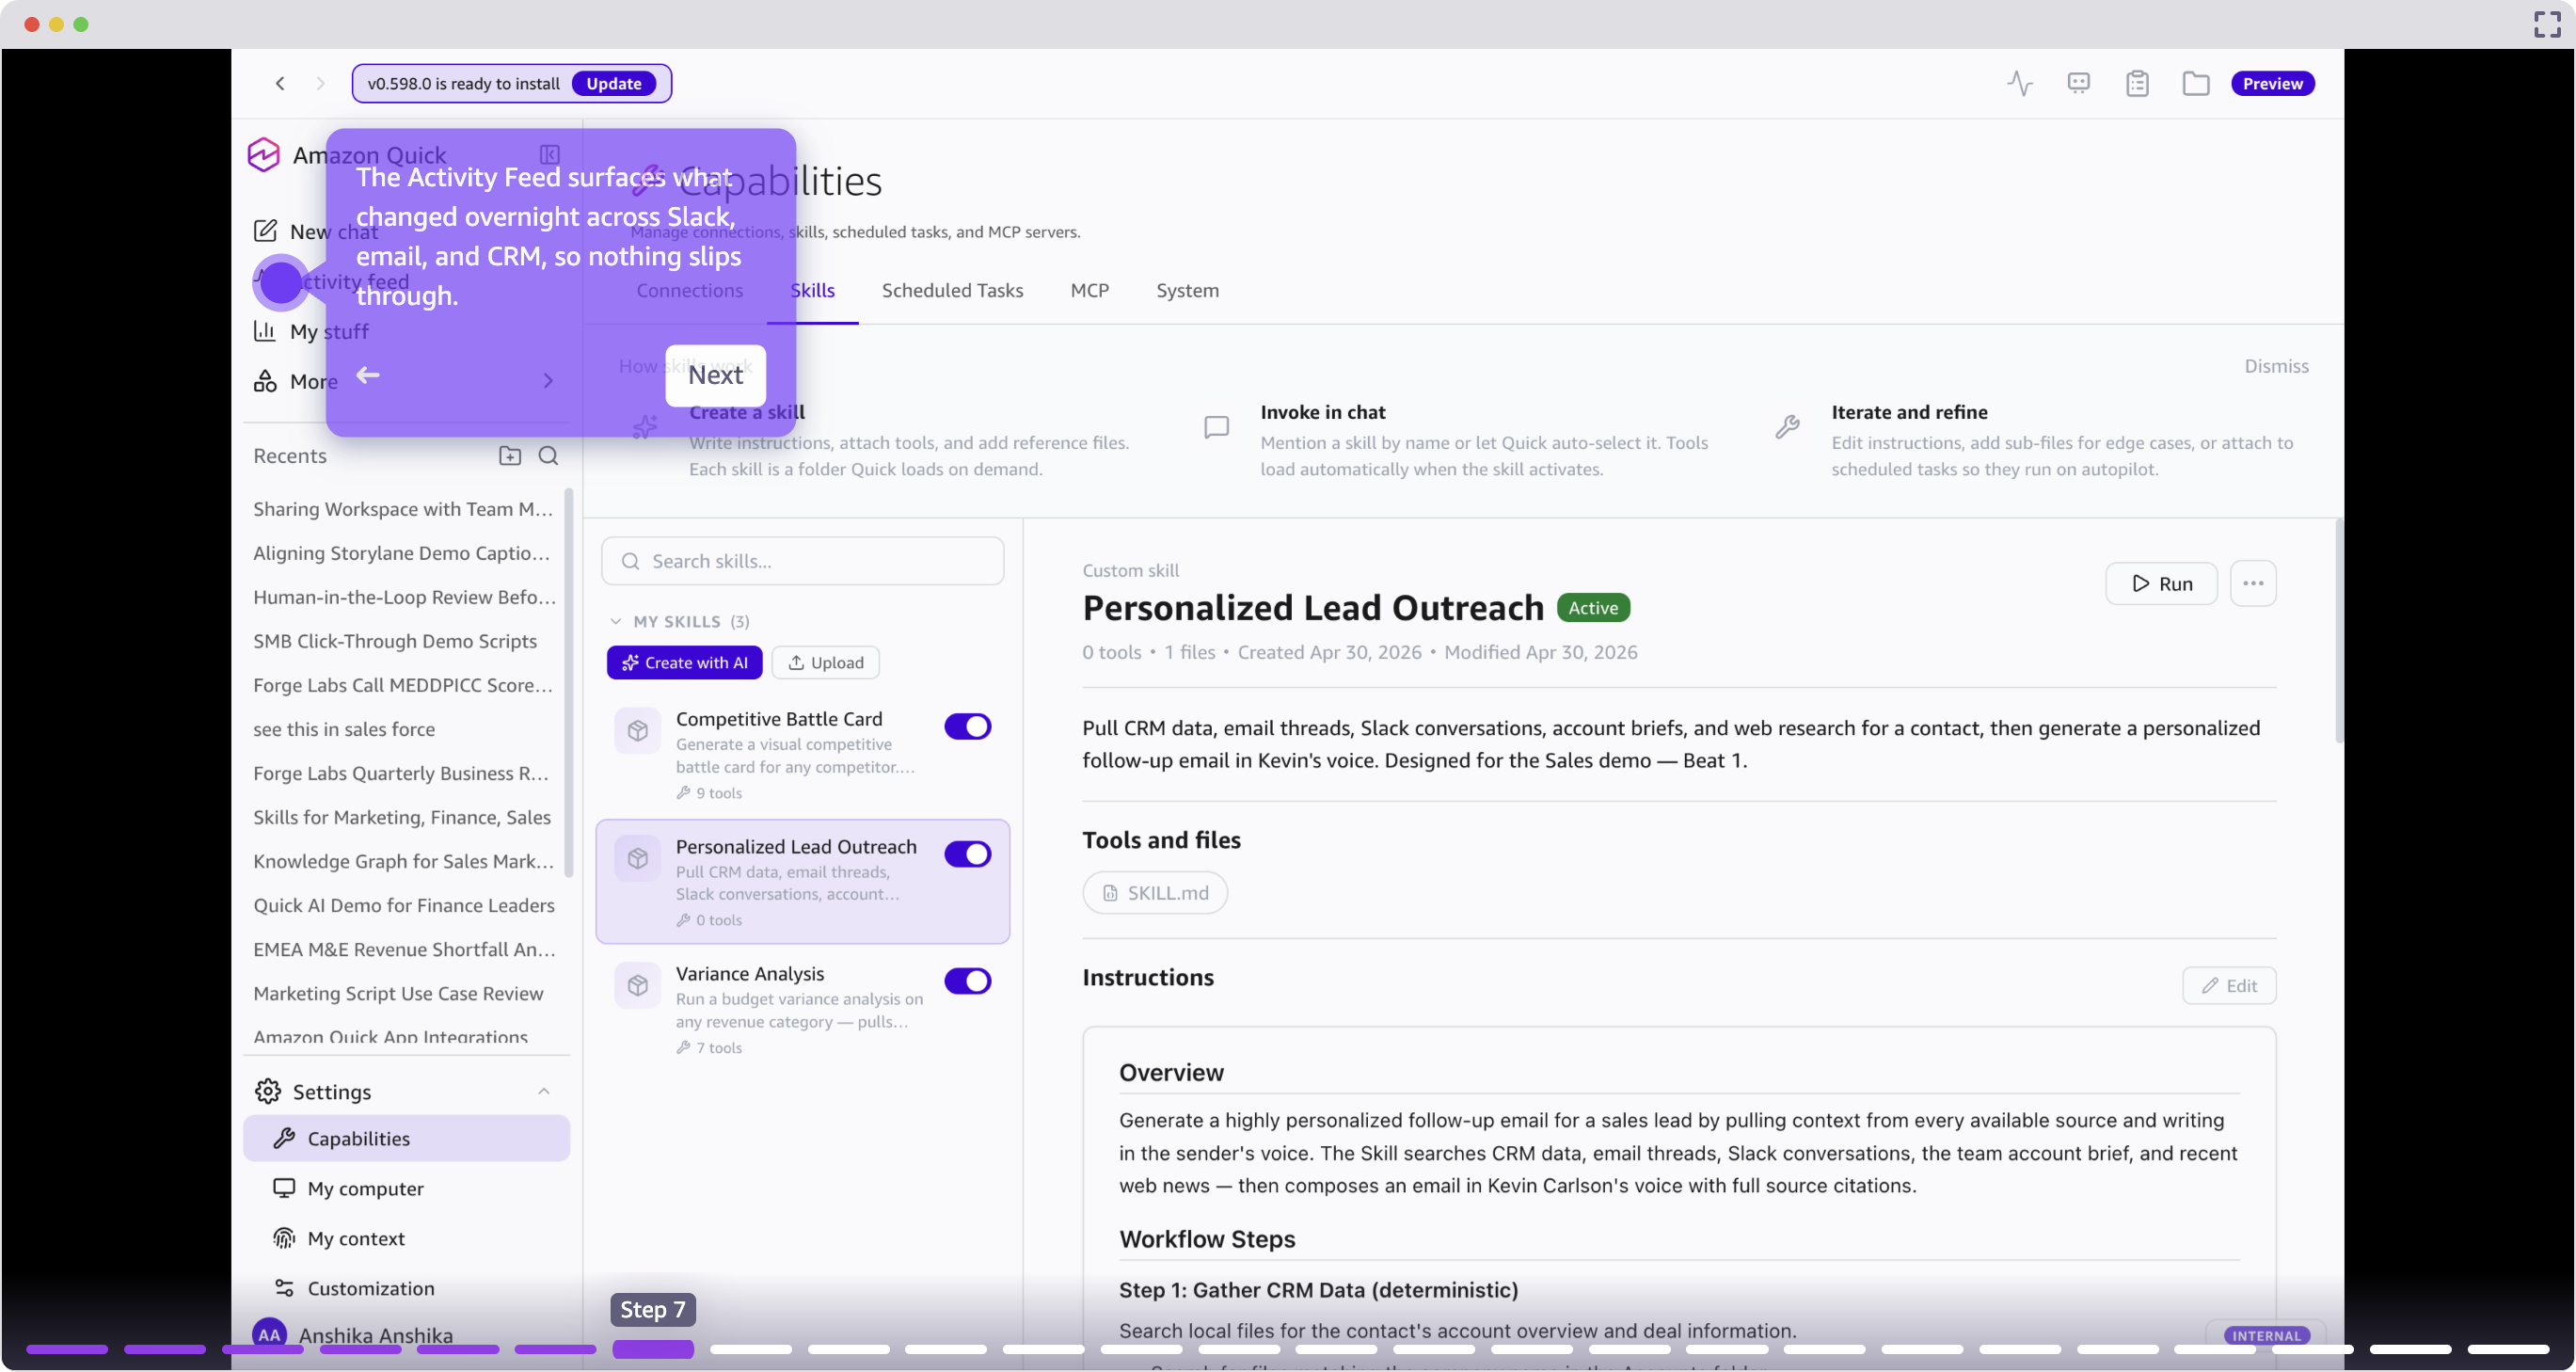
Exercise monitoring: begin on daily basis with readability
The Exercise Feed surfaces modifications that occurred in a single day throughout Slack, electronic mail, and CRM, prioritized by relevance to the vendor’s energetic offers. This replaces guide morning triage throughout a number of instruments with a single consolidated view.
Account intelligence: put together to shut with confidence
The client agrees to satisfy the next week to debate your proposed answer. Success! However now comes the prep work. Historically, you’d spend a number of hours getting ready, toggling between Salesforce for deal historical past, ServiceNow for help tickets, your electronic mail consumer for previous conversations, and a search engine for business context. By the point you’ve pieced collectively a full image, you’ve burned an hour.
You possibly can ask Fast to create a one-page assembly prep doc with the account snapshot, attendee bios, questions, and dangers. Hyperlink Fast Chat to a Fast Area, a centralized information repository the place you possibly can arrange paperwork, knowledge sources, and recordsdata that Fast can reference when answering questions or ending duties.
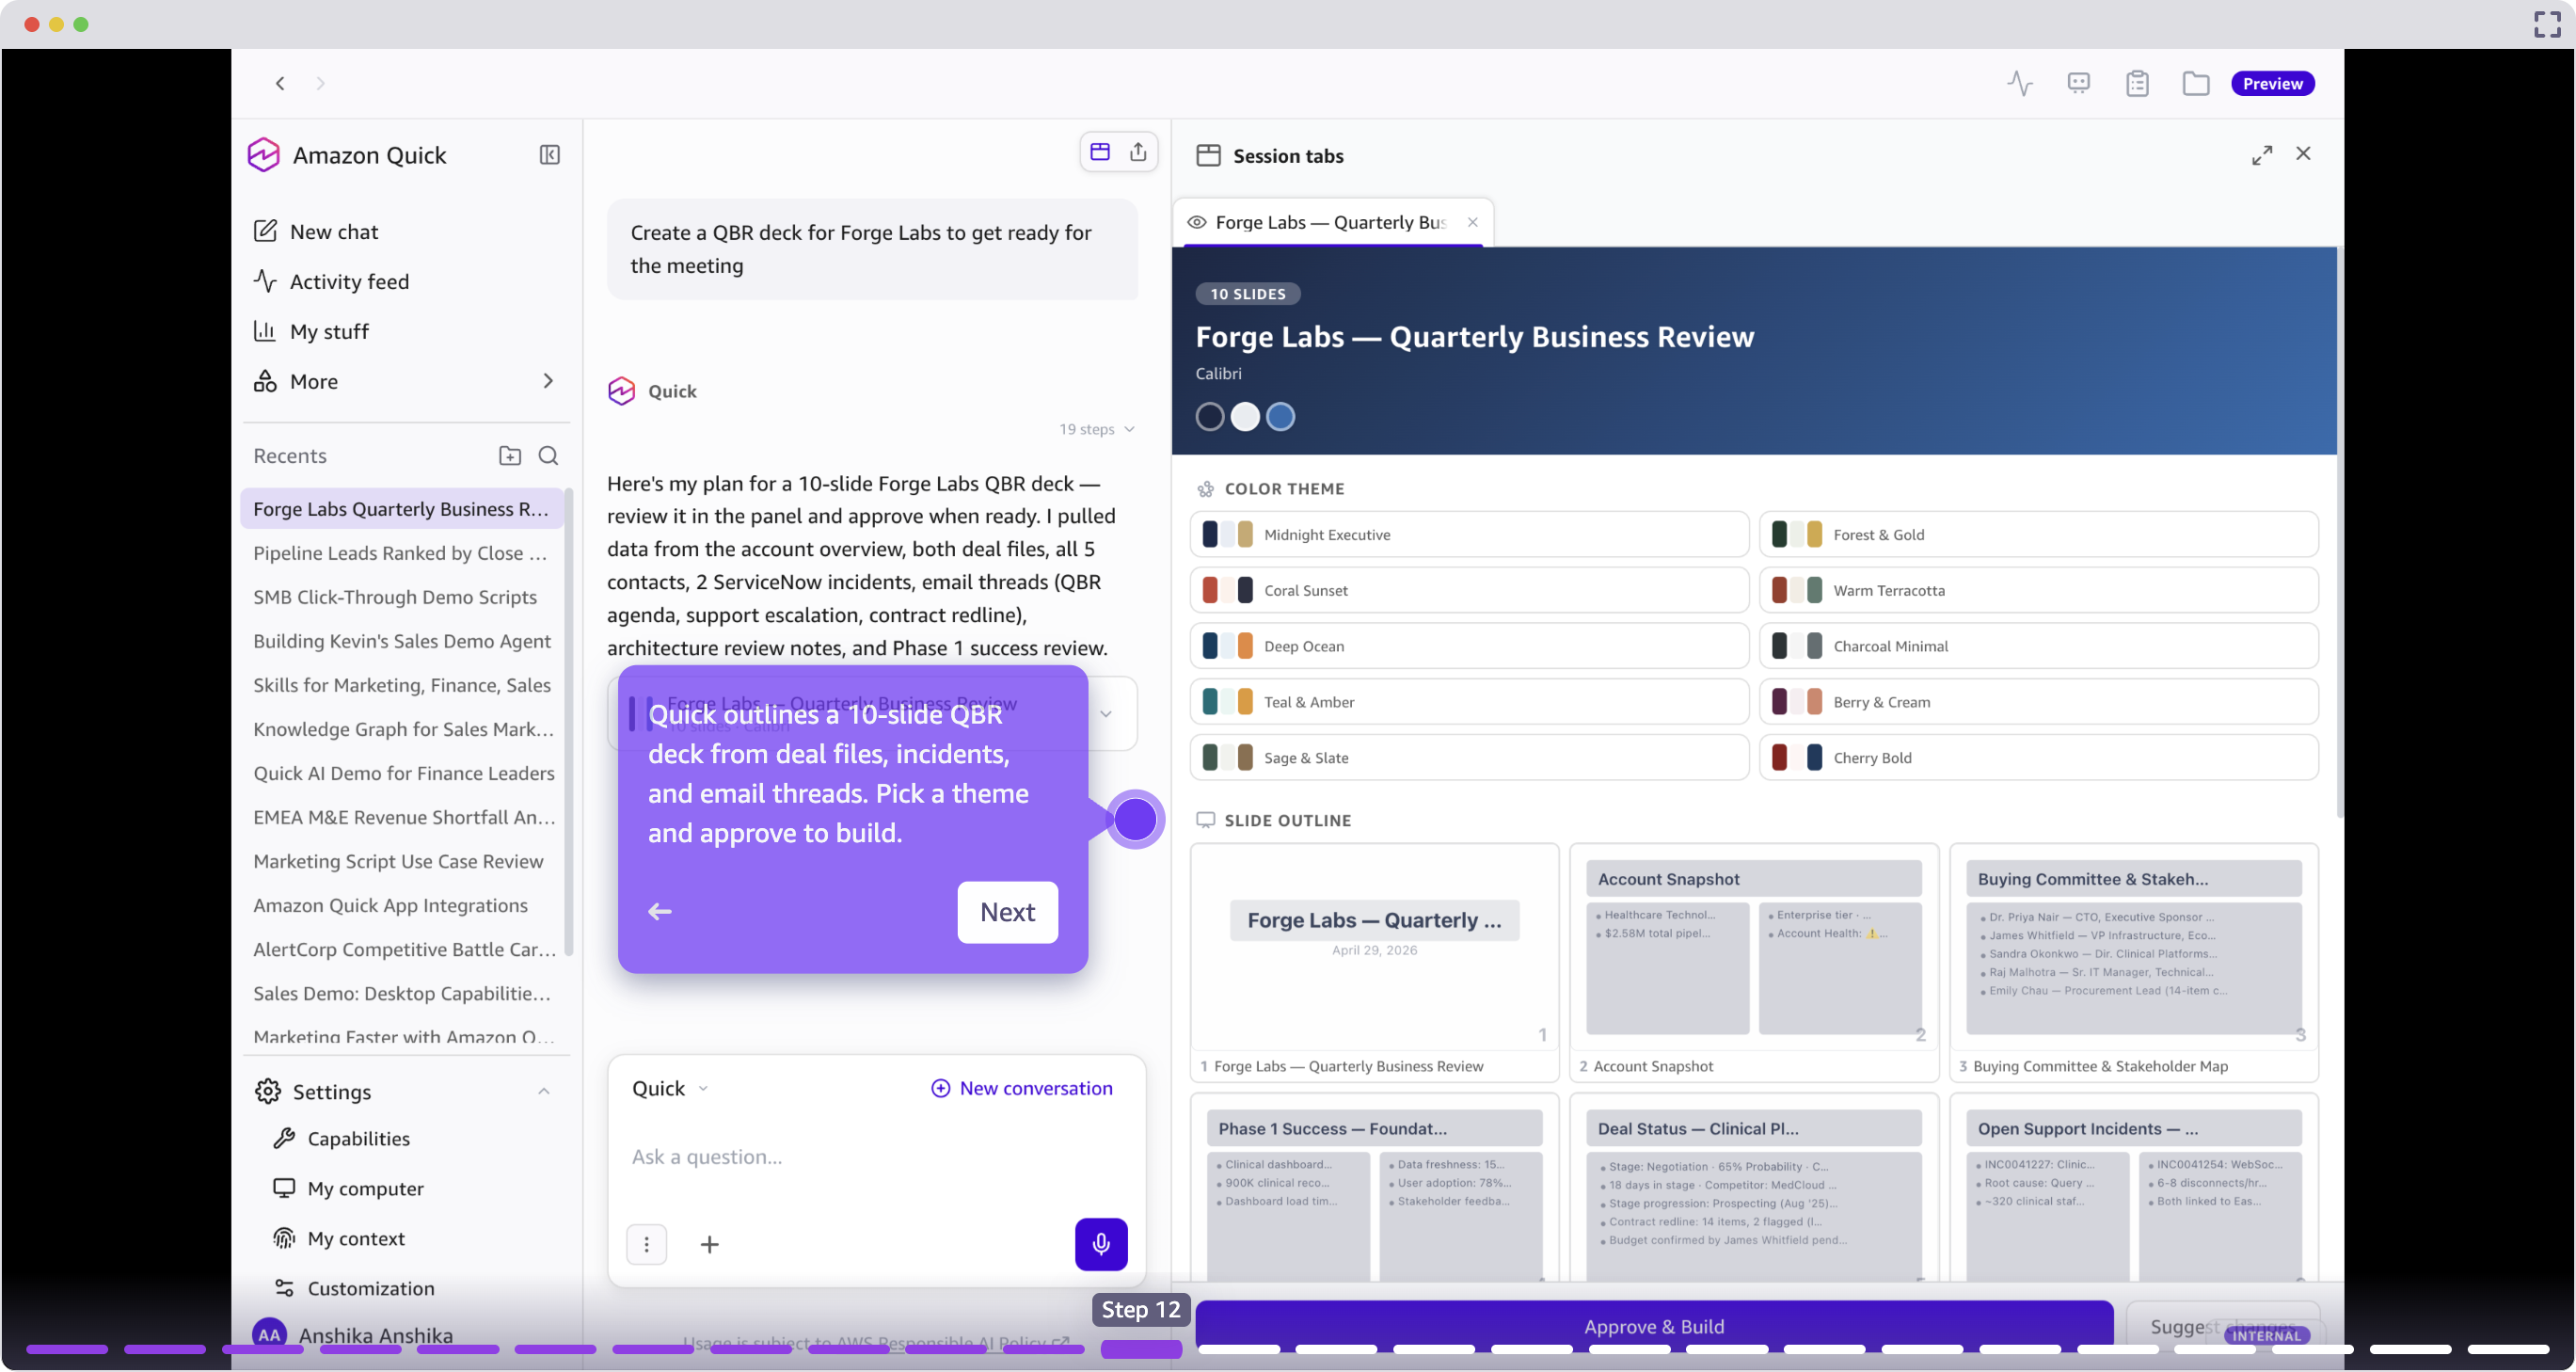
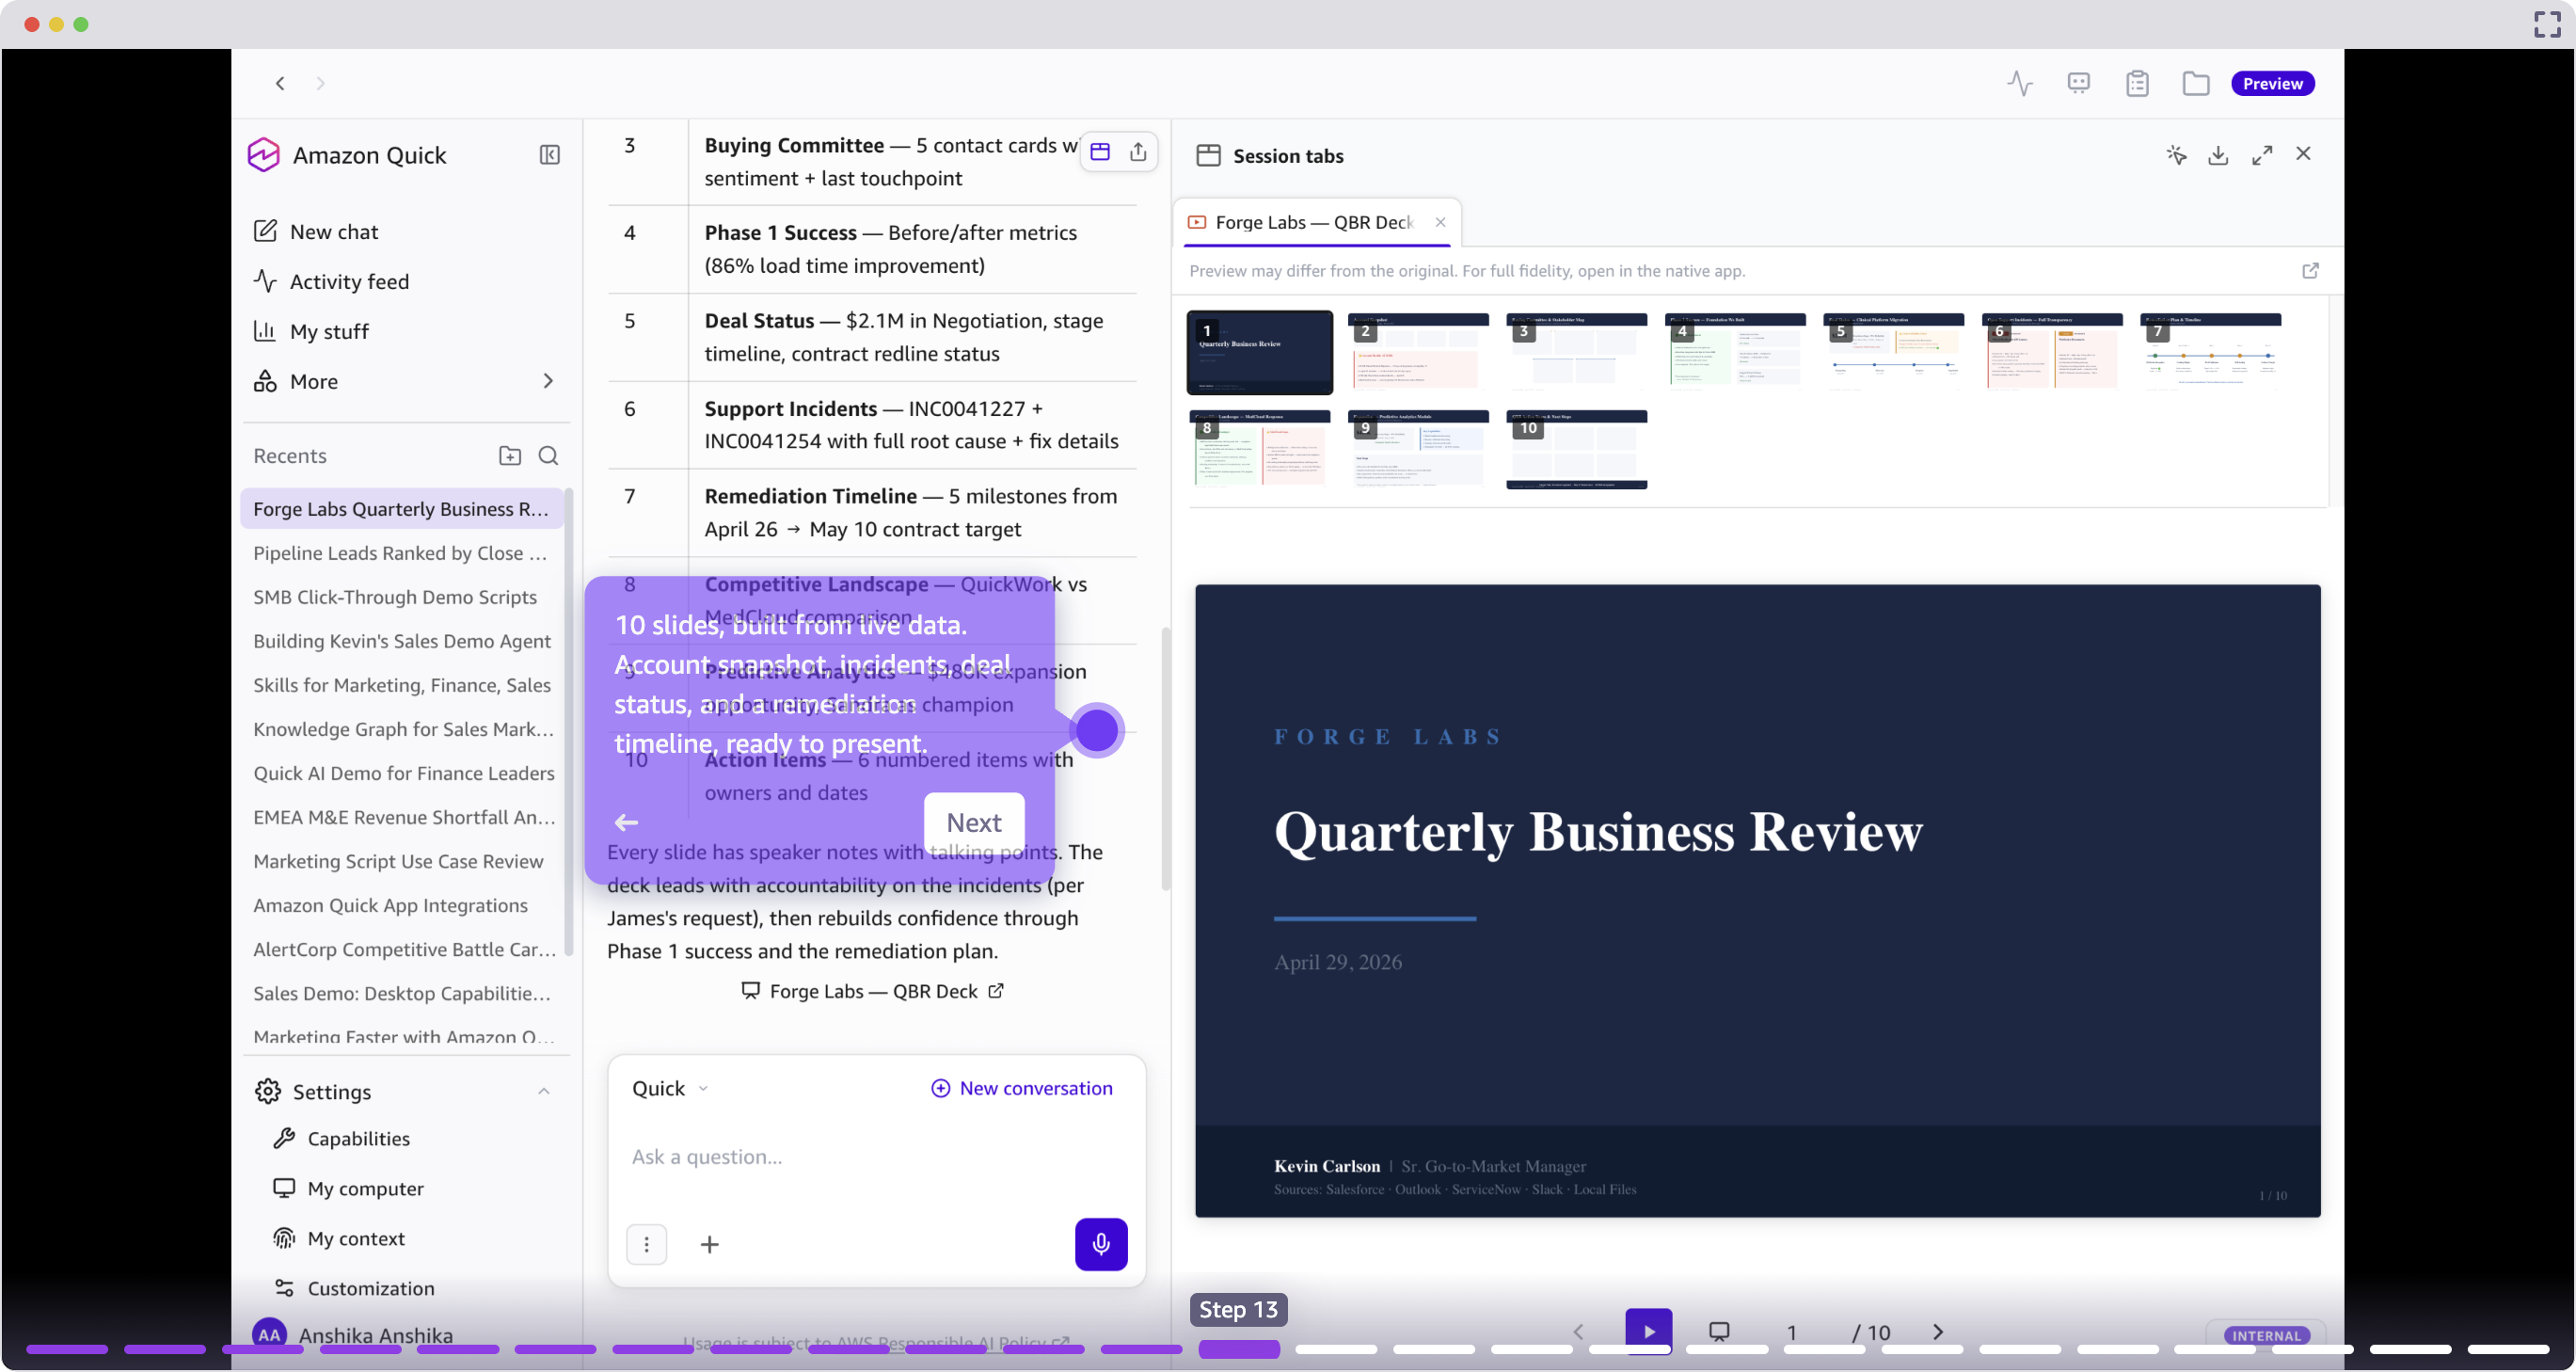
When getting ready for a Quarterly Enterprise Assessment (QBR), Fast can go additional by outlining and constructing a full presentation deck from deal recordsdata, help incidents, and electronic mail threads. The vendor critiques the proposed define, selects a theme, and approves the construct.
The ensuing deck contains an account snapshot, incident timeline, deal standing, and remediation plan, constructed from present knowledge relatively than manually assembled from a number of sources. A couple of minutes of prep as an alternative of hours.
Name transcript scoring: consider each dialog in opposition to your methodology
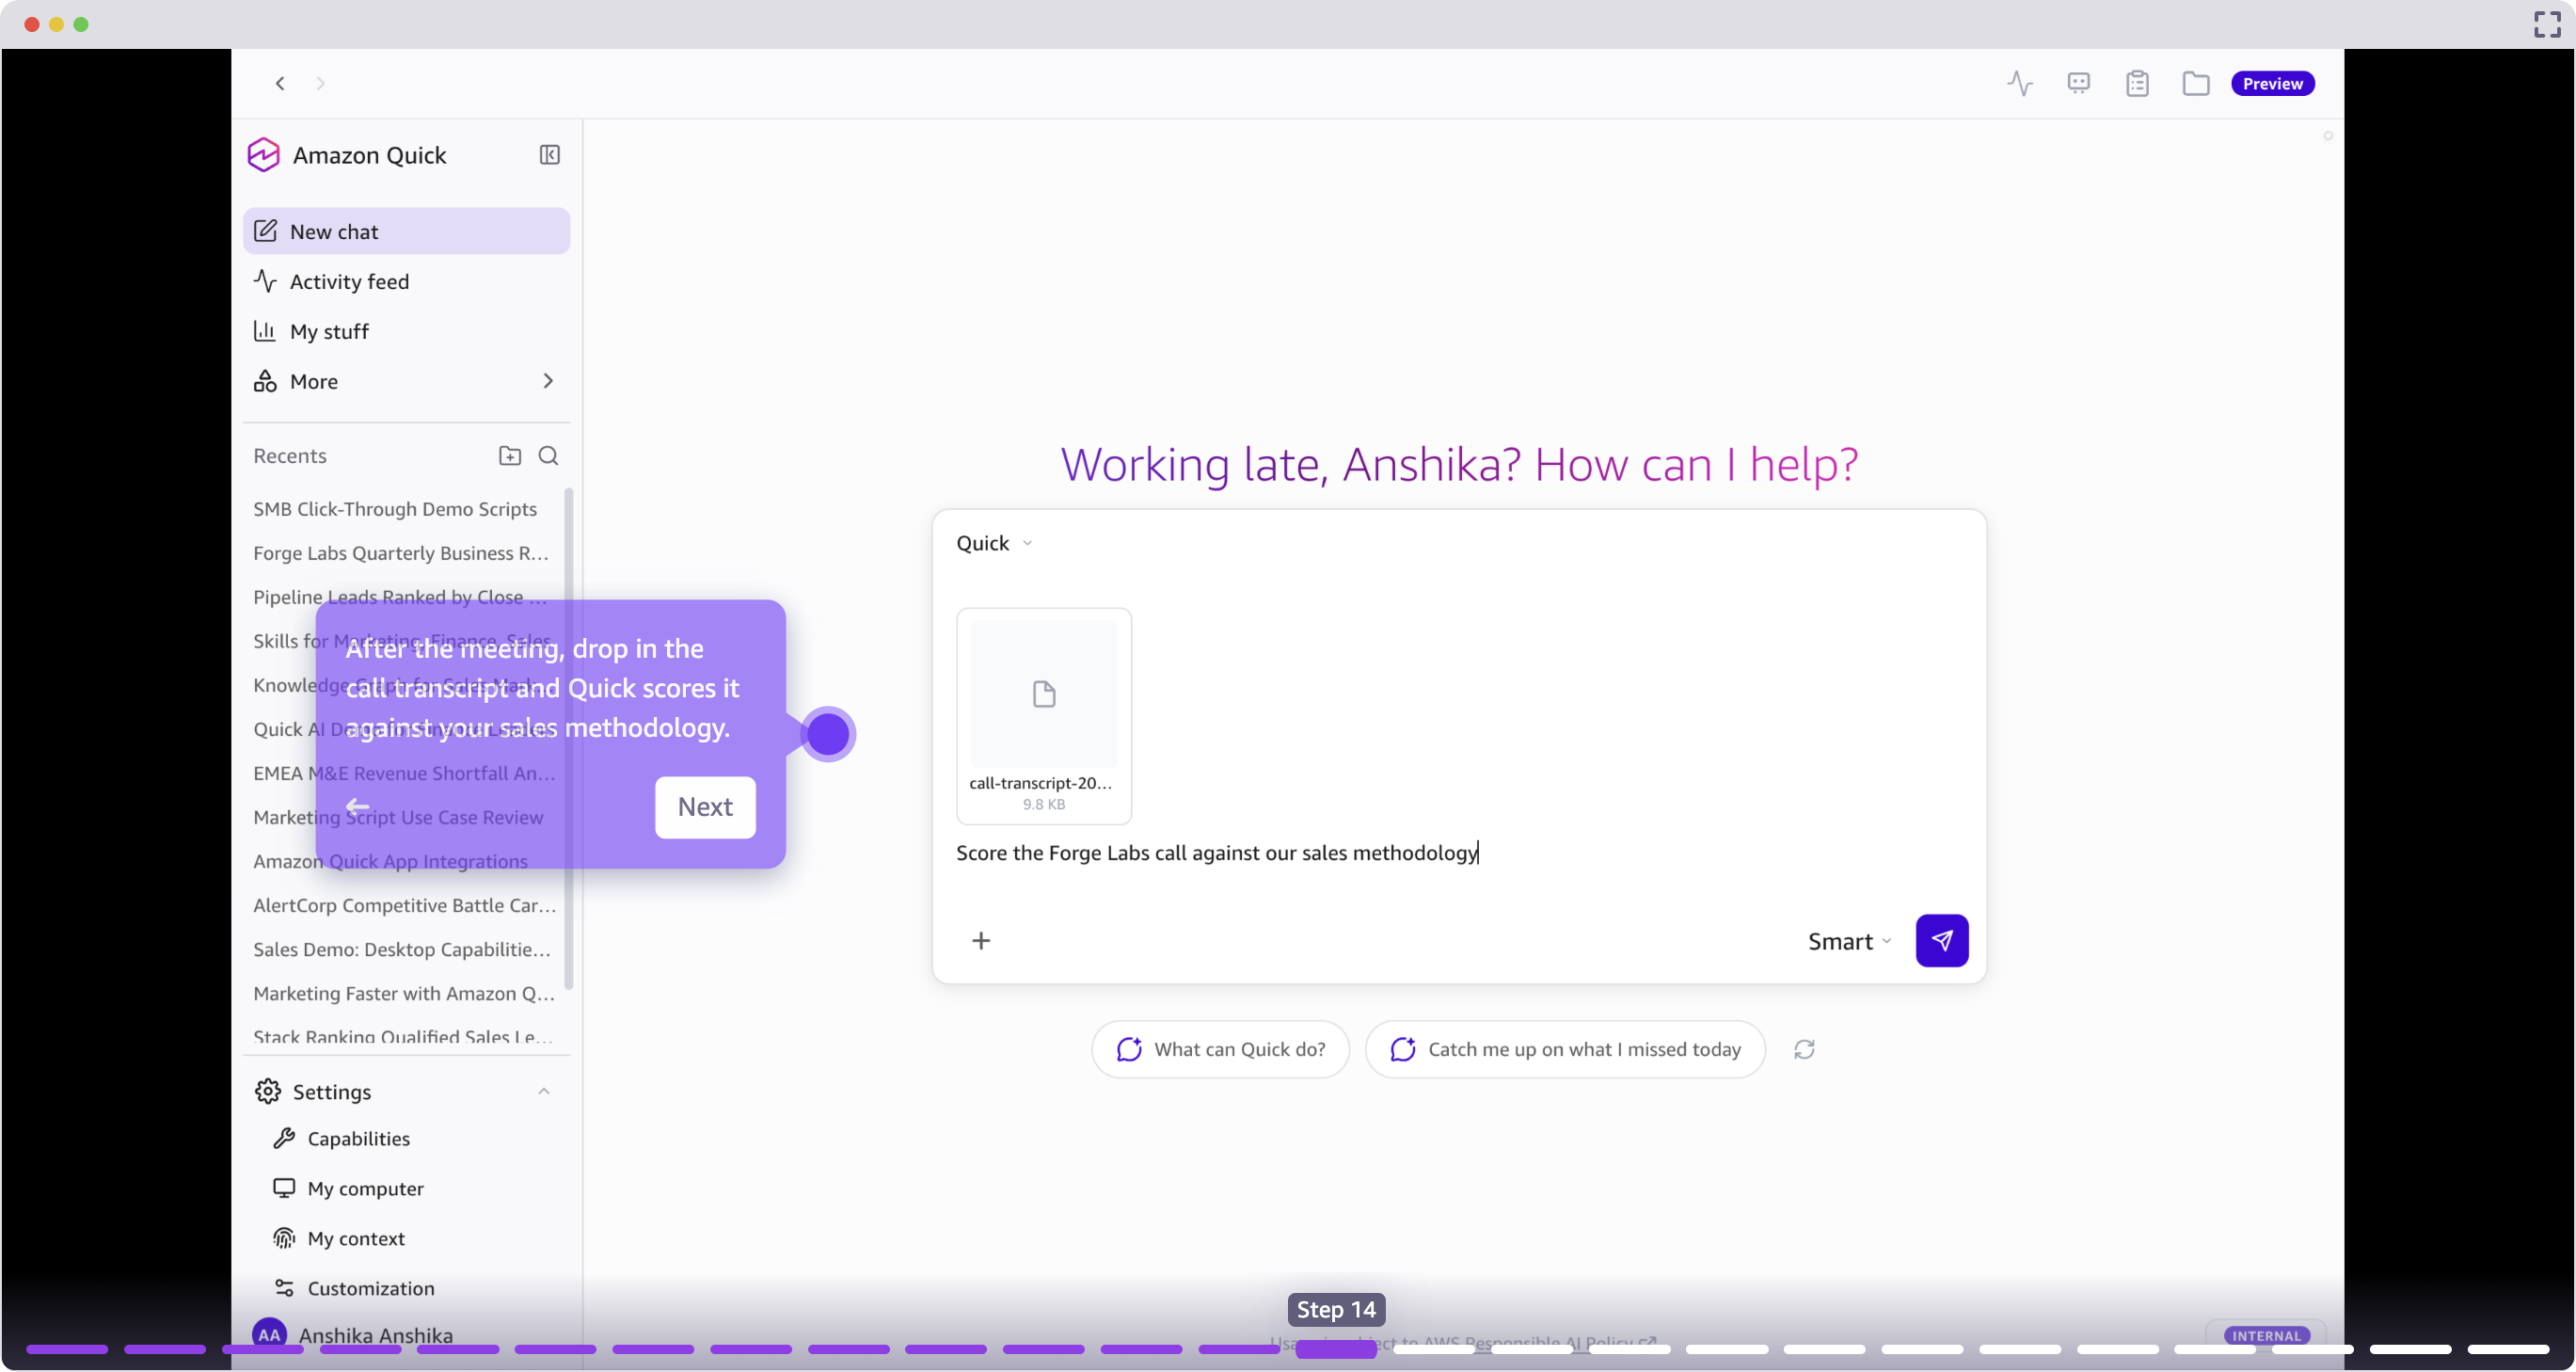
After a gathering, sellers can drop a name transcript into Fast for automated scoring in opposition to their gross sales methodology, comparable to MEDDPICC, BANT, or a customized framework. Fast identifies what was coated, what gaps stay, and gives a structured evaluation of deal well being primarily based on the dialog.
CRM automation and exercise logging: hold the system of file correct
Historically, each interplay requires 15–20 minutes of CRM updates which are typically troublesome to prioritize whereas juggling different time-sensitive buyer interactions. As time passes between a gathering and updating Salesforce, context will get misplaced and particulars slip by way of the cracks.
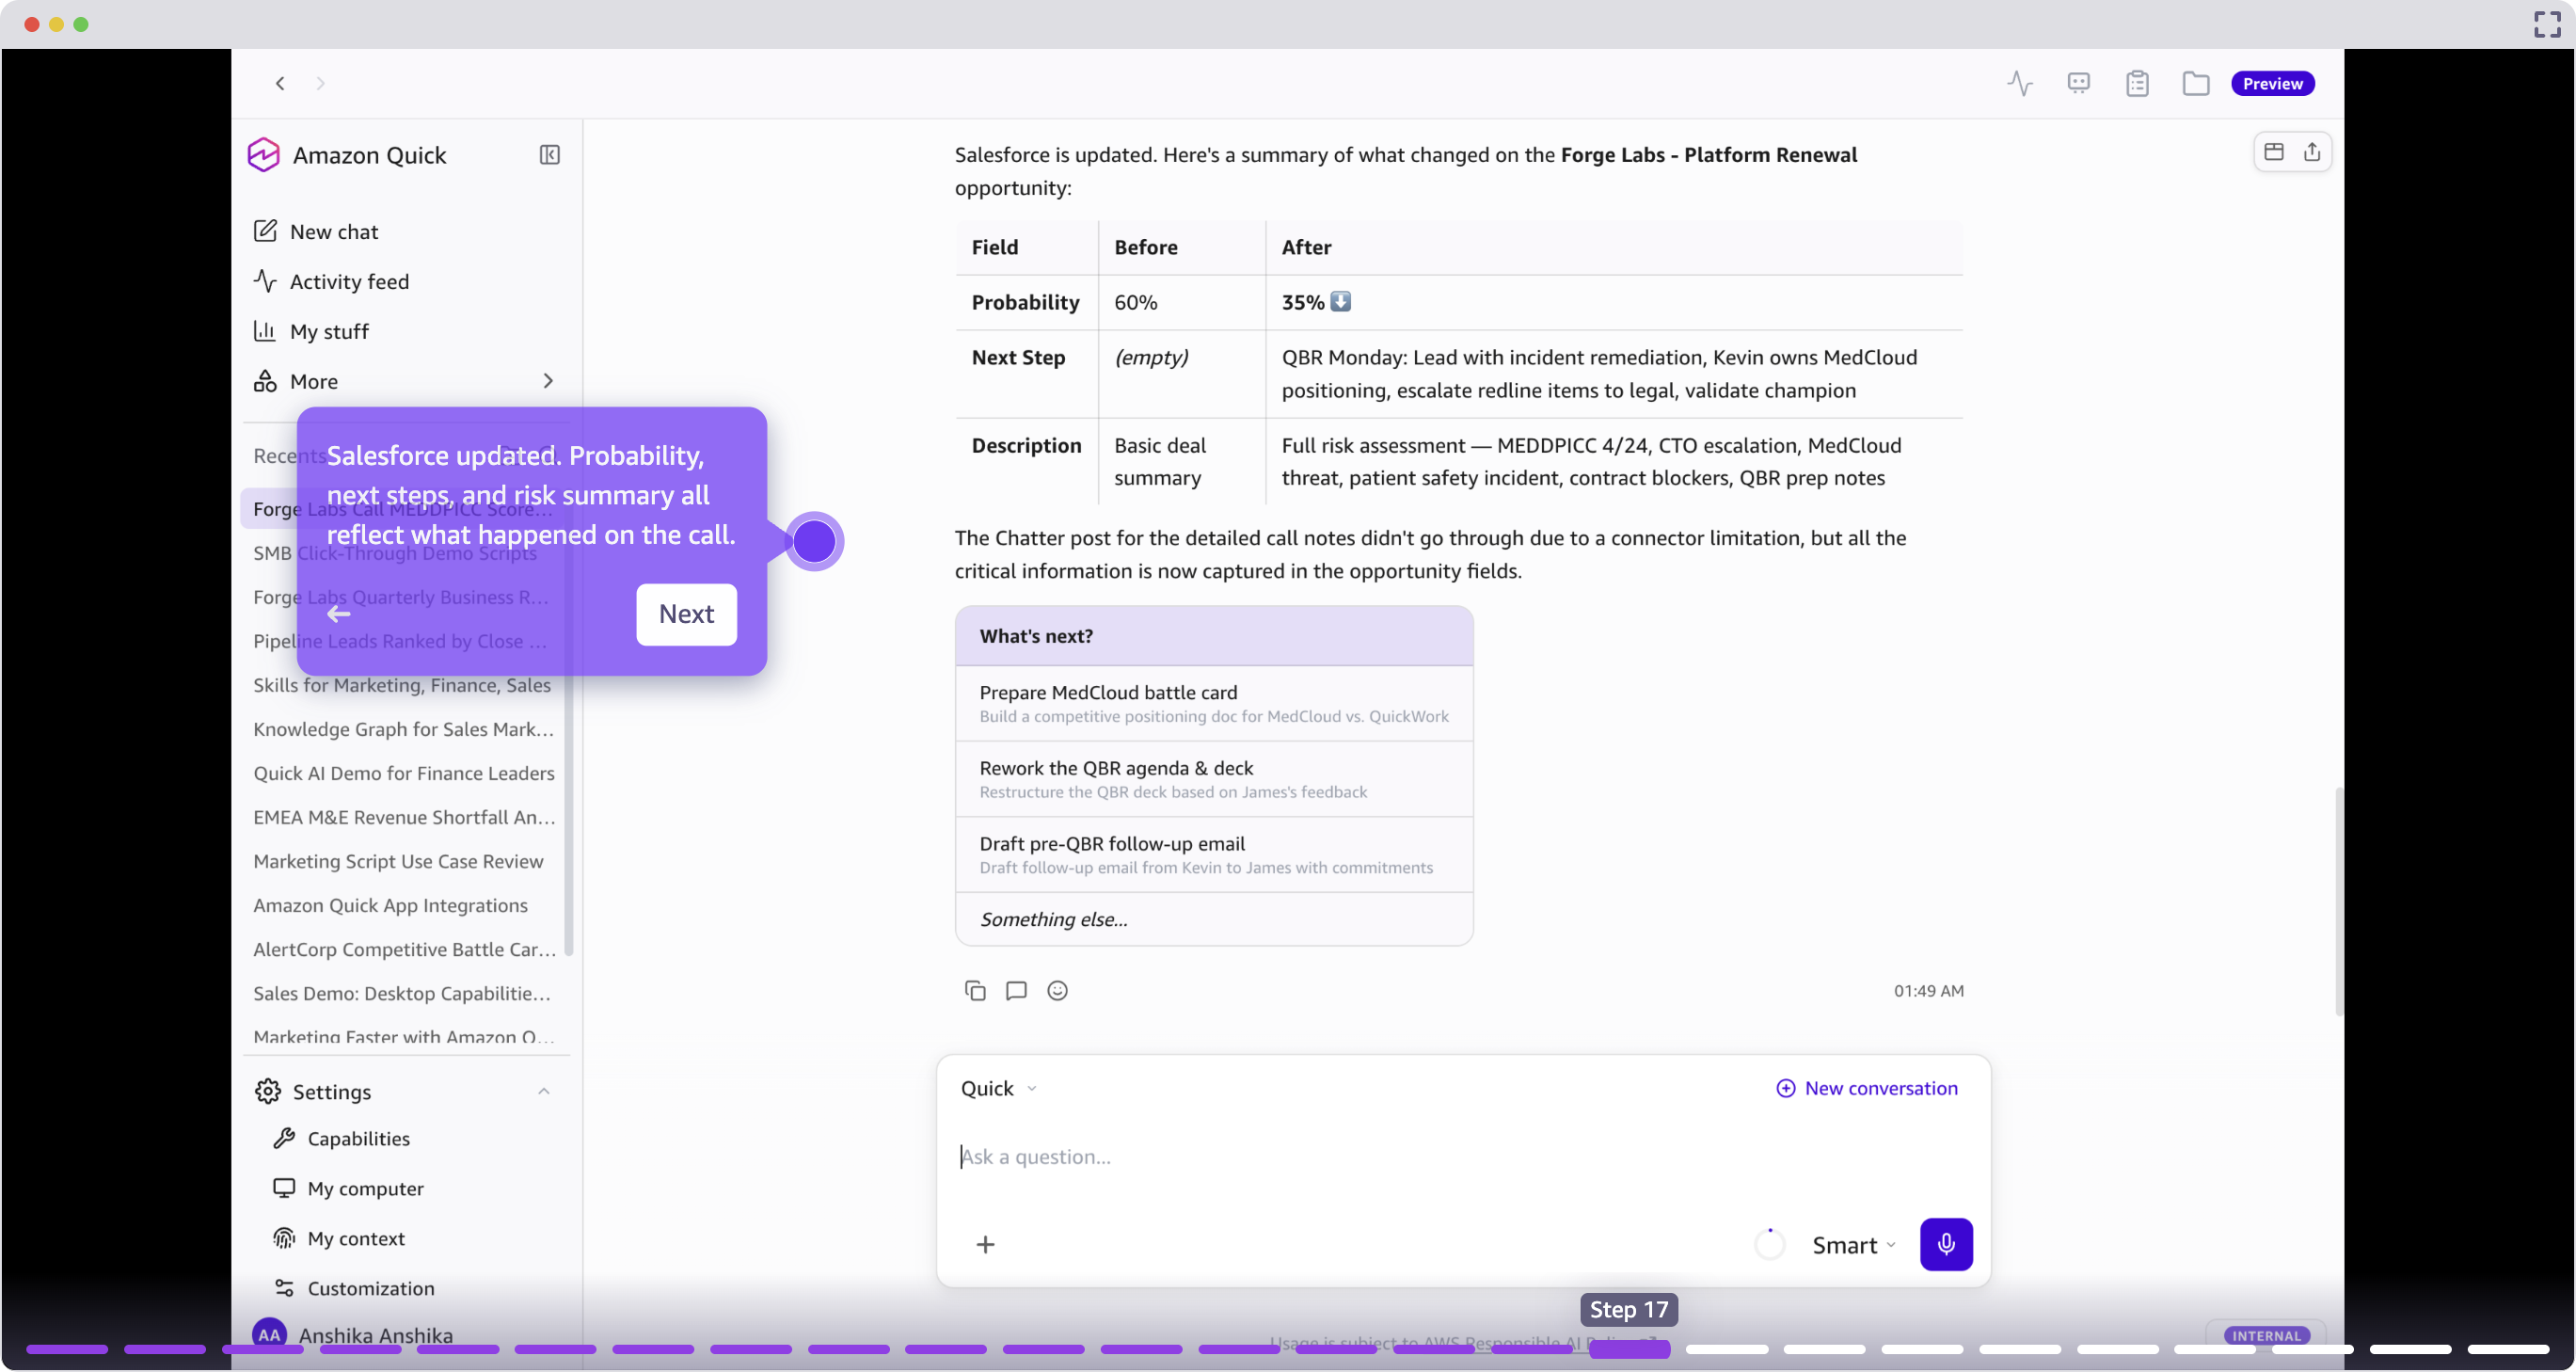
Following name evaluation, Fast pushes structured updates to Salesforce, together with deal likelihood, subsequent steps, threat flags, and a dialog abstract. This retains the system of file correct with out requiring guide knowledge entry.
Customized purposes from pure language: construct instruments with out code
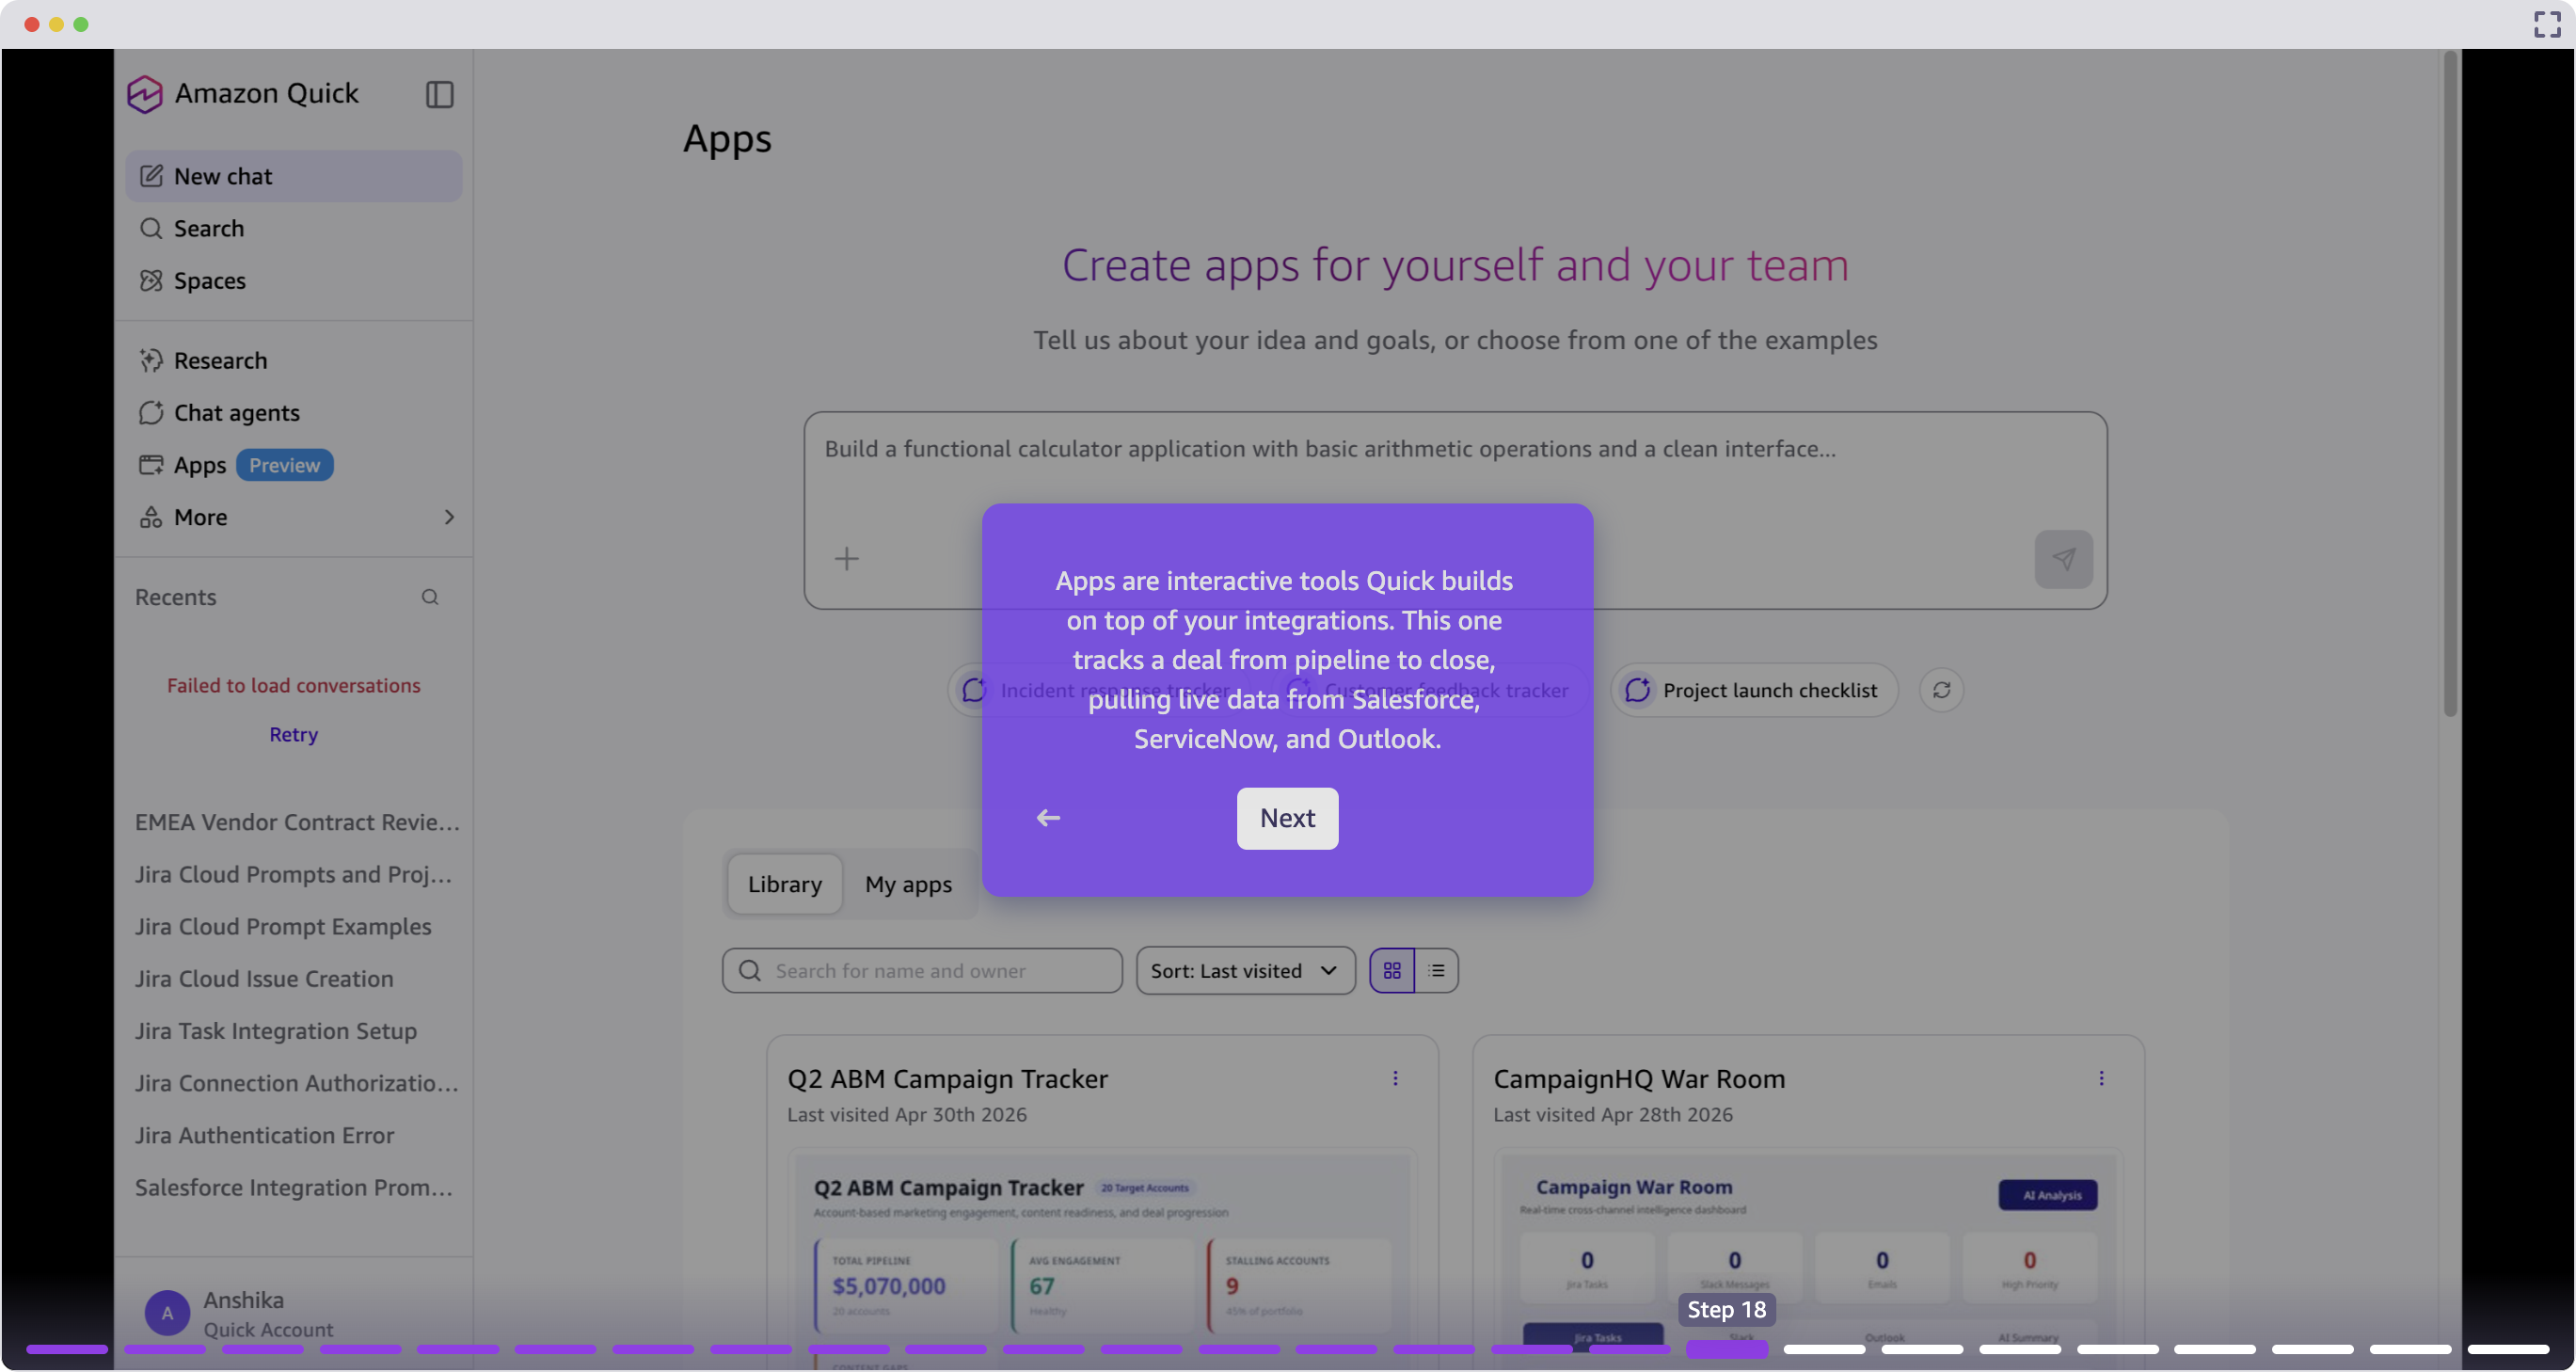
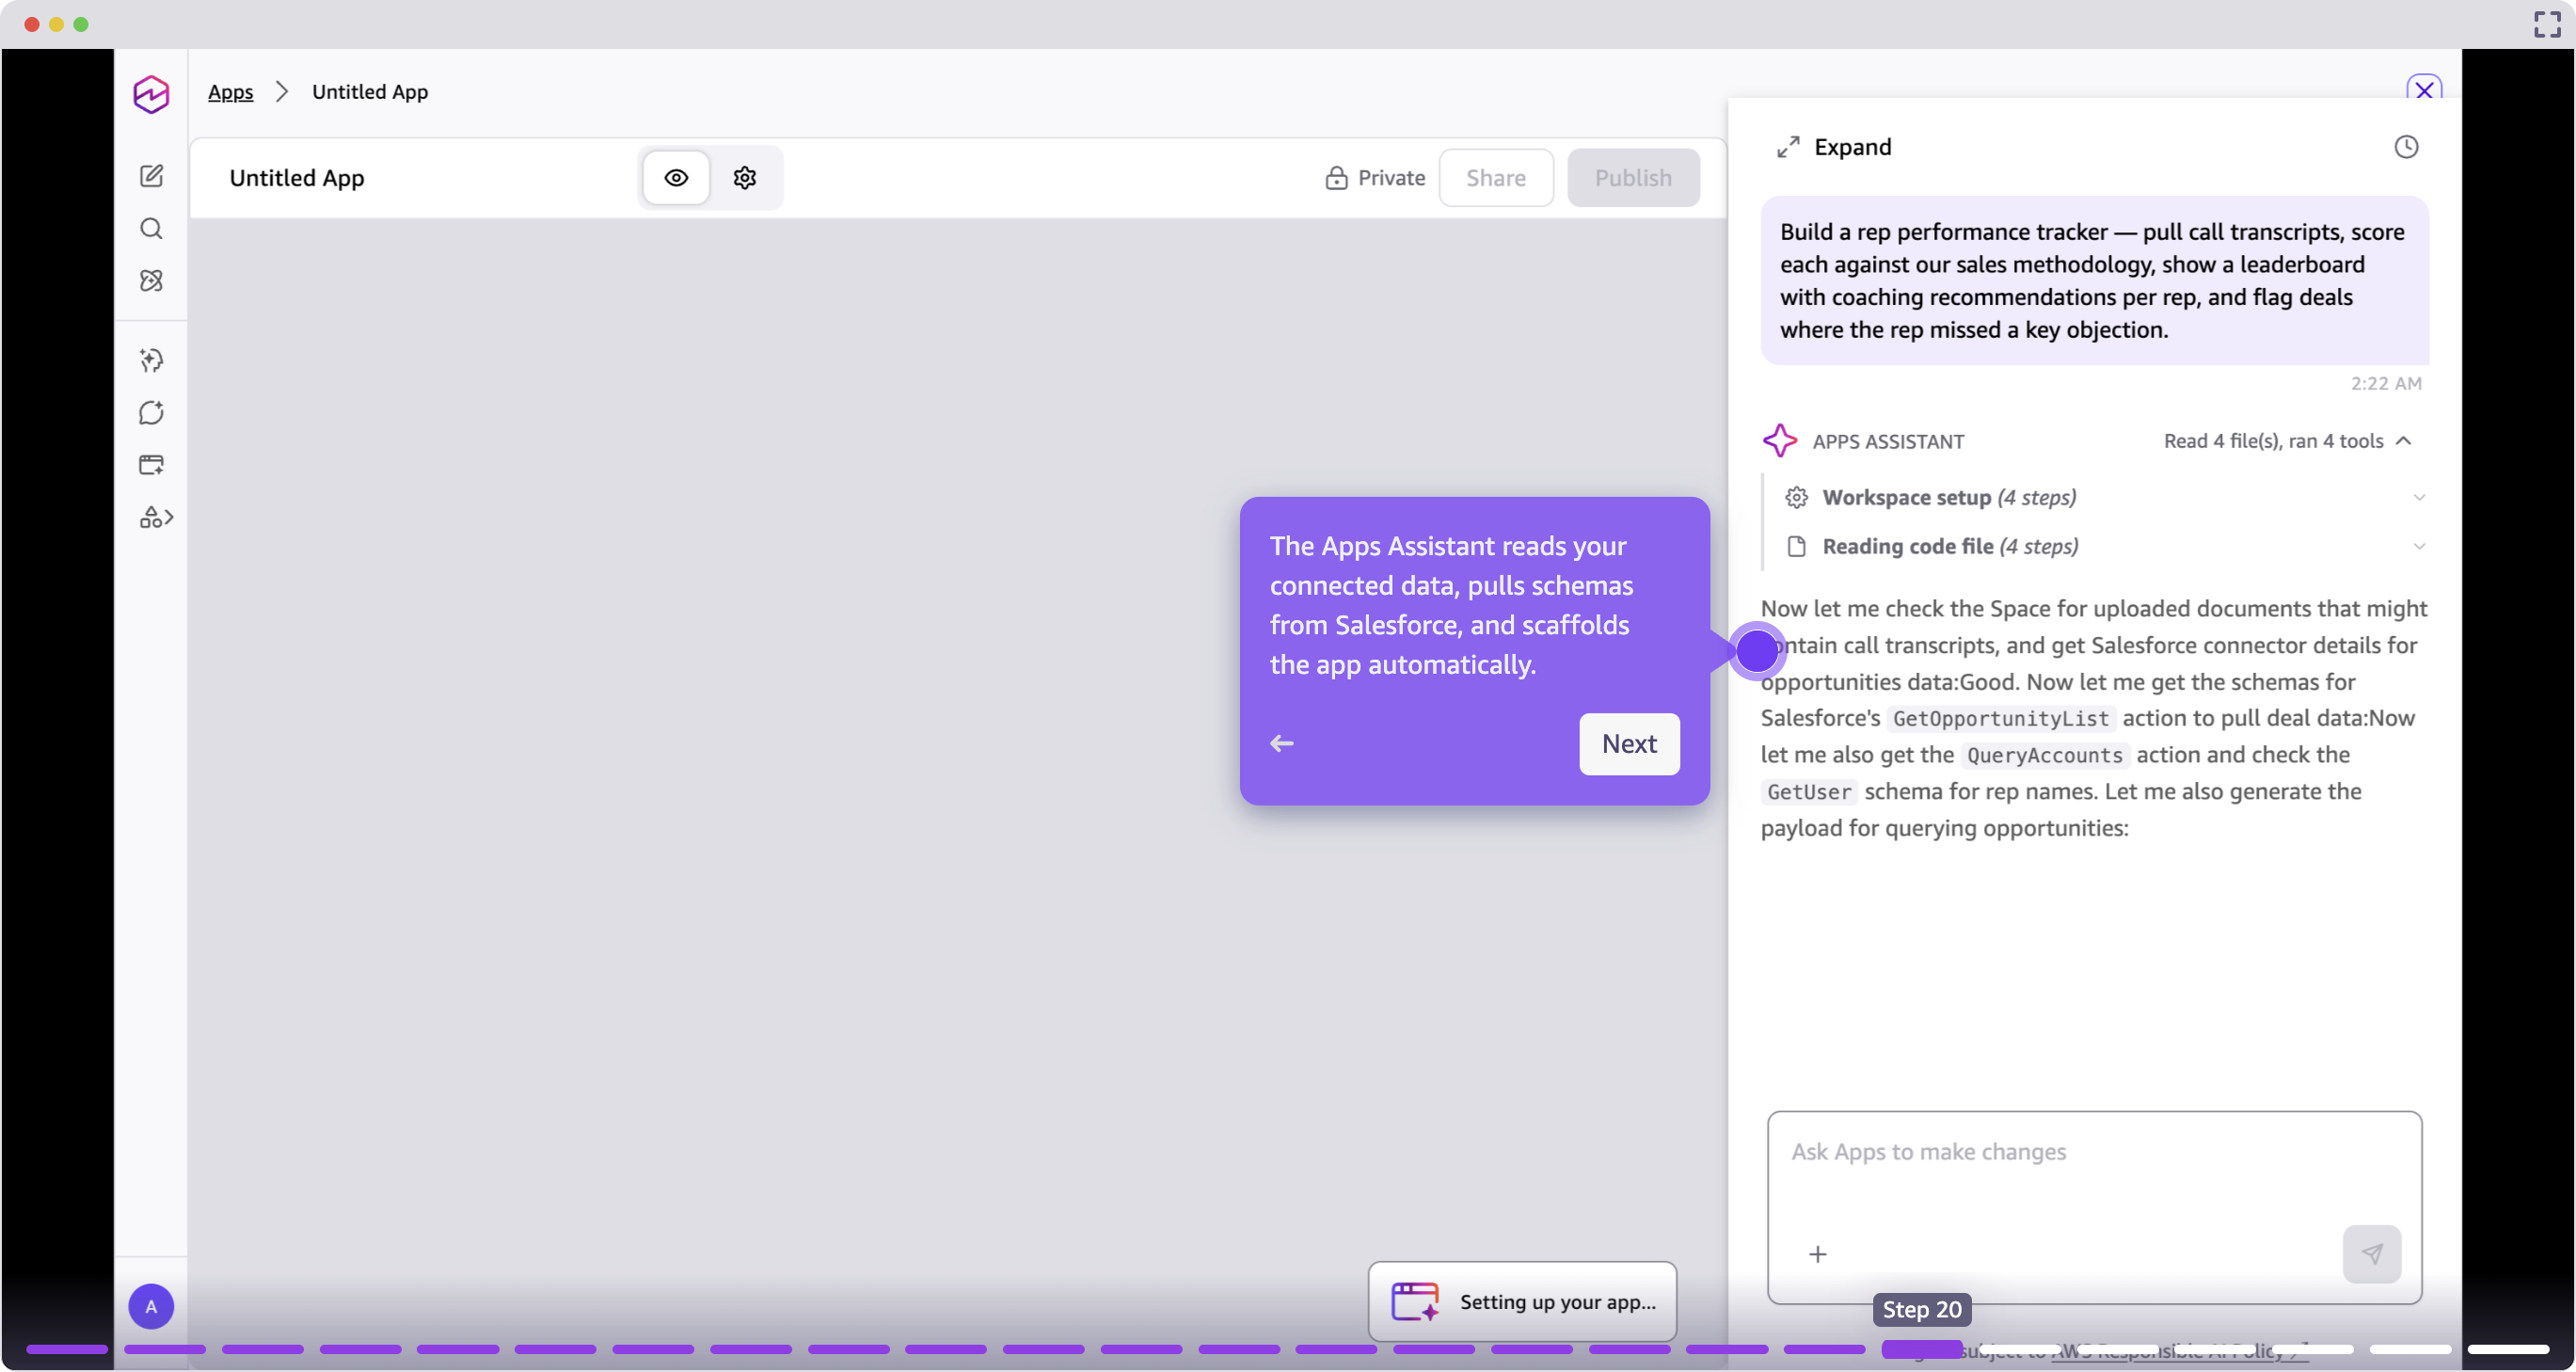
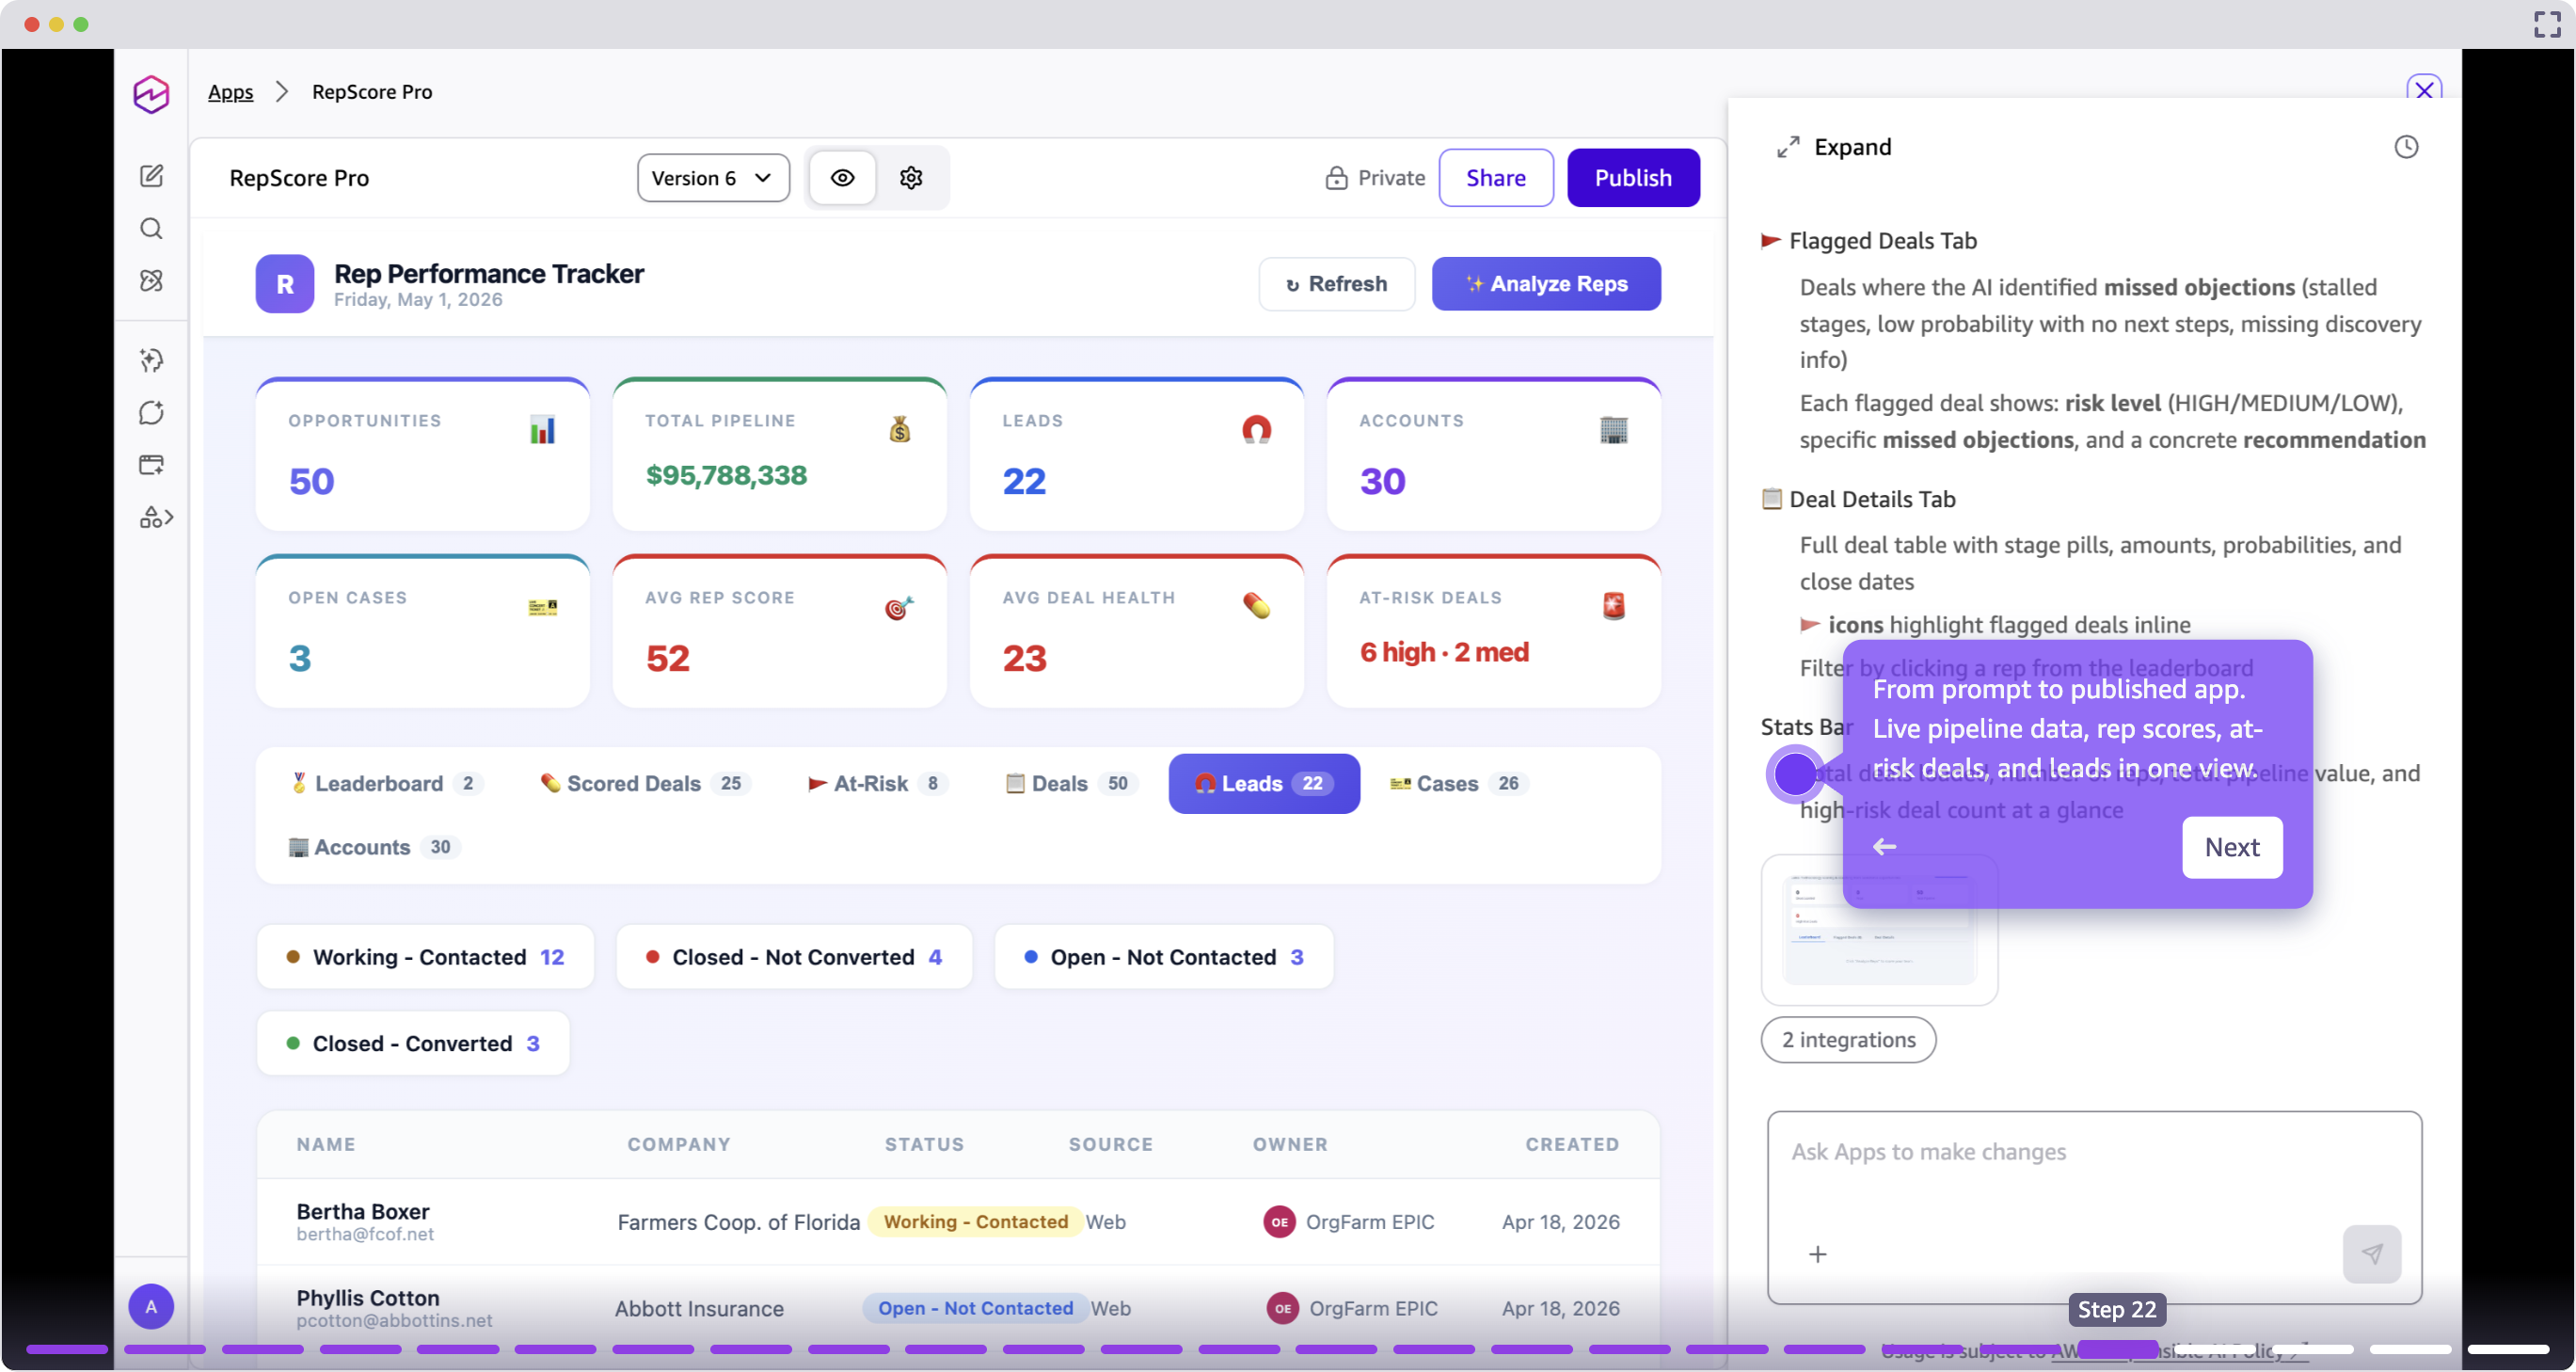
Fast lets sellers and gross sales operations groups construct interactive purposes from a pure language immediate, mechanically studying linked knowledge schemas and scaffolding a reside software with out writing code.
The ensuing software is reside, shareable, and iterable. You possibly can add options, change layouts, or join new knowledge sources with follow-up prompts.
Data Graph: map relationships throughout your e book of enterprise
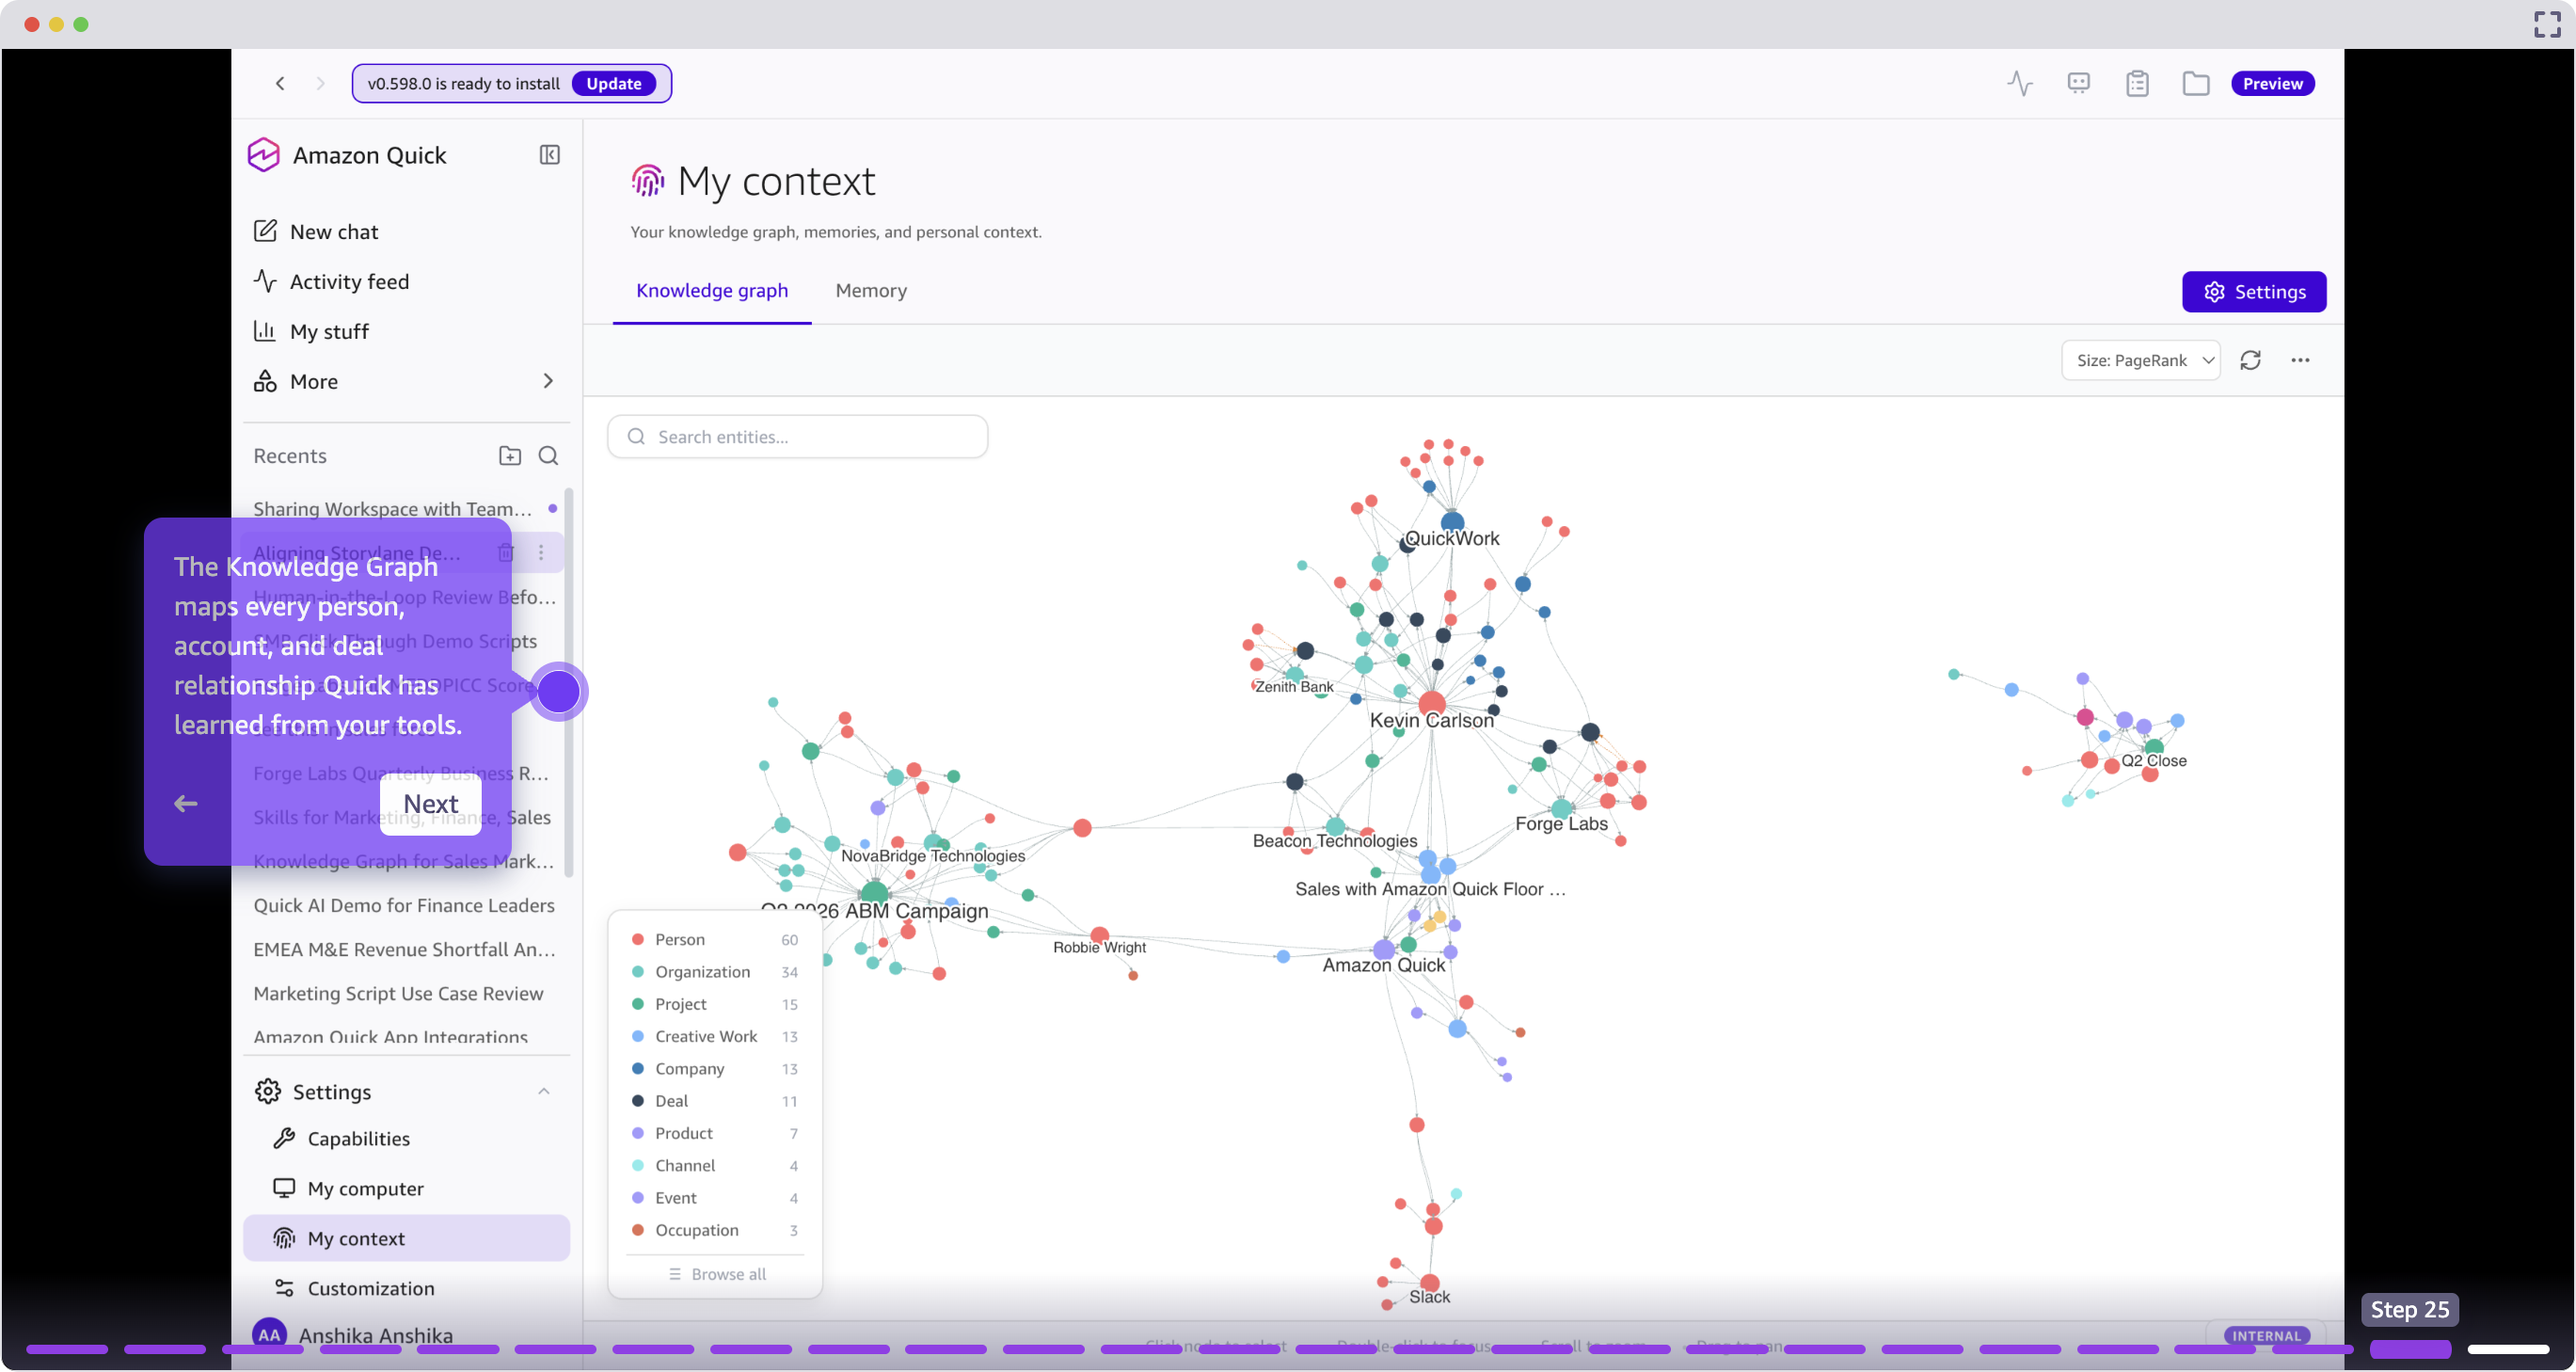
The Data Graph maps relationships between folks, accounts, offers, and interactions that Fast has realized from linked instruments. Sellers can question relationship historical past, determine heat introduction paths, and perceive account constructions with out guide analysis.
Getting began
This put up demonstrated a full gross sales workflow in Amazon Fast, from morning pipeline evaluation by way of customized outreach, assembly preparation, name scoring, CRM updates, customized software creation, and relationship mapping. Every functionality connects to the subsequent, making a steady workflow that retains sellers in circulation relatively than switching between instruments.
The next desk summarizes the capabilities coated on this put up.
Functionality
Operate
Pipeline scoring
Rank offers utilizing reside CRM indicators.
Danger detection
Floor stalled offers and aggressive threats.
Personalised outreach
Generate context-aware electronic mail messages from deal historical past.
Customized abilities
Codify and share reusable workflows.
Exercise Feed
Monitor in a single day modifications throughout programs.
Assembly prep and QBR decks
Construct displays from reside account knowledge.
Name scoring
Consider transcripts in opposition to methodology.
CRM updates
Push structured updates to Salesforce.
Customized purposes
Construct interactive instruments from prompts.
Data Graph
Map relationship intelligence.
What may your day appear like? Begin with one workflow, comparable to lead scoring, assembly prep, or CRM automation, and expertise the distinction. Discover the Amazon Fast for Gross sales web page to study extra, or watch Fast in motion within the Gross sales demo and full walkthrough.
This week’s updates all give attention to one thing we hear from IT professionals and platform engineers on a regular basis:
How can we make our environments safer, extra manageable, and simpler to modernize with out including extra complexity?
Whether or not you are working PostgreSQL workloads in Azure, securing Kubernetes storage, or planning your subsequent wave of SQL Server migrations, this week’s bulletins deliver sensible enhancements that may assist cut back operational overhead whereas strengthening your total platform technique.
We’ll take a look at three newly accessible capabilities:
Replace #1 – Usually Accessible: Microsoft Defender safety assessments for Azure Database for PostgreSQL Versatile Server
Replace #2 – Usually Accessible: Encryption in Transit for Azure Information NFS Shares in Azure Kubernetes Service (AKS)
Replace #3 – Usually Accessible: Increasing Azure Arc SQL Migration with SQL Server on Azure Digital Machines
As at all times, I am approaching these updates from an infrastructure and operations perspective. I will cowl why every functionality issues, what to be careful for earlier than manufacturing deployment, and a few sensible steps you may take to start out evaluating them in your personal surroundings.
Let’s dig in.
This launch brings automated safety posture evaluation immediately into managed PostgreSQL environments. For ITPros, this issues as a result of database safety is commonly handled individually from infrastructure safety tooling, creating blind spots and silos.
What modified is that Defender now runs native vulnerability scanning and compliance checks in opposition to PostgreSQL configurations, patches, and the methods a database could possibly be uncovered to safety dangers or assault alternatives. As a substitute of counting on exterior scanners or handbook audits, you get platform-native assessments built-in together with your present Defender workflows.
The operational impression is critical: now you can implement safety baselines on the database layer with the identical consistency you apply to VMs and community sources, lowering the hole between infrastructure and information safety accountability.
Operationally, this improves your safety baseline enforcement and reduces the necessity for separate database safety evaluation instruments. It additionally strengthens how effectively you may show and show that safety controls are in place and dealing for compliance critiques the place regulators count on constant, documented safety controls.
Earlier than manufacturing rollout, validate that Defender price fashions suit your funds, that evaluation frequency aligns together with your change home windows, and that remediation steering maps to your patch and upkeep processes.
Stipulations embrace enabling Microsoft Defender for Cloud, registering the PostgreSQL Versatile Server supplier, and making certain community connectivity so assessments can attain the database endpoint.
Allow Microsoft Defender for Cloud if not already lively, and guarantee PostgreSQL Versatile Server subscription protection.
Register the goal PostgreSQL Versatile Server situations and ensure Defender has community visibility to the database endpoints.
Run a baseline evaluation and evaluate preliminary findings to grasp present safety posture and customary remediation patterns.
Prioritise findings by severity and enterprise impression, then schedule patches and configuration modifications in upkeep home windows.
Monitor ongoing assessments and monitor remediation progress by way of Defender dashboards, validating that fixes cut back publicity scores.
This instance validates that Defender is actively assessing your PostgreSQL property. The sequence checks Defender standing, confirms PostgreSQL registration, and retrieves present evaluation scores.
Run these queries in a pilot subscription first to grasp information construction and anticipated output earlier than scaling to manufacturing databases.
az account set --subscription  az safety sql-vulnerability-assessment baseline present --resource-group  --server-name  --database-name

az safety pricing present --subscription  --query "[?name=='VirtualMachines' || name=='SqlServers' || name=='StorageAccounts'].[name,pricingTier]" -o desk

az supplier present --namespace Microsoft.DBforPostgreSQL --query "registrationState" -o tsv
Anticipated behaviour: Defender standing exhibits lively, PostgreSQL situations are registered with the supplier, and pricing tier displays your protection stage. If assessments don’t run, examine community guidelines, managed id permissions, and Defender plan activation. If baseline information is lacking, set off a handbook scan and anticipate completion.
This launch closes a major hole in information safety for Kubernetes workloads consuming NFS shares from Azure Information. Beforehand, NFS site visitors between AKS nodes and Azure Information was unencrypted, creating compliance and safety dangers for delicate workloads.
What modified is which you can now implement encryption for NFS communication on the Azure Information layer, not simply on the utility layer. That is necessary as a result of conventional NFS lacks built-in encryption, and counting on community isolation alone is more and more inadequate.
For ITPros managing regulated workloads (healthcare, finance, PII-sensitive information), this removes a management hole. Encryption in transit now turns into a platform-native function as an alternative of a workaround, lowering structure complexity and enhancing auditability.
The operational worth is stronger compliance posture and diminished assault floor for information in movement between containers and storage. It additionally simplifies the safety story when auditors ask about information safety controls.
Earlier than enabling in manufacturing, validate that NFS-over-TLS introduces acceptable latency overhead in your workload patterns, check failover and reconnection behaviour below encryption, and ensure that monitoring and logging nonetheless work appropriately.
Stipulations embrace working AKS with Azure CNI or Kubenet networking, having Azure Information with NFS 4.1 enabled, and making certain the NFS consumer libraries on container photographs assist TLS.
Create an Azure Information NFS share with encryption in transit enabled and ensure TLS model alignment together with your safety requirements.
Deploy a check AKS workload that mounts the NFS share and validate that pods mount efficiently with encrypted site visitors.
Run efficiency baselines (throughput, latency, CPU overhead) earlier than and after enabling encryption to doc operational expectations.
Monitor pod logs and Azure Information metrics throughout the check to verify no silent failures or sudden throttling happens.
Roll out to manufacturing workloads in phases, with clear rollback standards tied to utility latency and error charges.
This instance validates that your AKS cluster can efficiently mount NFS shares with encryption enabled. The sequence checks cluster networking, confirms NFS connectivity, and checks mount success.
Run these instructions in a non-production cluster first to validate surroundings readiness earlier than touching manufacturing storage.
az aks present --resource-group  --name  --query "networkProfile.{networkPlugin:networkPlugin,networkPolicy:networkPolicy,podCidr:podCidr}" -o jsonc

az storage account present --resource-group  --name  --query "{identify:identify,sort:sort,accessTier:accessTier}" -o jsonc

kubectl get pvc -A --all-namespaces -o huge kubectl describe pv  | grep -i nfs
Anticipated behaviour: cluster networking is correctly configured, storage account sort helps NFS, and PVC/PV sources present NFS mount factors. If mounts fail, examine community safety group guidelines, storage account firewall allowances, and subnet delegation. If latency will increase, monitor useful resource utilisation and alter workload placement if wanted.
This functionality brings SQL Server migration into the Azure Arc operational footprint, making a unified migration and stock expertise. For ITPros, this issues as a result of SQL Server modernisation is commonly fragmented throughout a number of instruments and groups.
What modified is which you can now uncover, assess, and execute SQL migrations by way of Arc-native workflows, utilizing the identical permissions and governance mannequin you have already got for infrastructure and hybrid sources.
The operational acquire is consistency: discovery information feeds migration planning, assessments floor blockers early, and rollout will be managed by way of the identical change and approvals processes you employ for different infrastructure migrations.
Operationally, this reduces tooling sprawl and improves coordination between infrastructure and database groups. Arc turns into your single management airplane for monitoring migration progress, managing runbooks, and accumulating audit proof.
Earlier than manufacturing use, validate that your SQL Server stock is full, that migration blockers are understood and addressed, and that your upkeep home windows can accommodate anticipated cutover timings.
Stipulations embrace Azure Arc agent deployment on supply VMs, Azure Database Migration Service readiness, and community connectivity to focus on Azure SQL sources.
Deploy Azure Arc brokers to SQL Server VMs and ensure all situations report wholesome standing with full stock information.
Run Arc-integrated SQL Server assessments to establish compatibility points, dependencies, and really helpful migration targets.
Pilot migration for a non-critical workload to determine runbook patterns, measure cutover time, and validate post-migration validation procedures.
Scale migration in waves utilizing documented runbooks, with gates for monitoring information well being and utility efficiency after every cutover.
This instance validates Arc agent well being and SQL Server discovery completeness. The sequence ensures your Arc infrastructure is prepared for migration workflows.
Run these instructions as a part of your pre-migration guidelines to catch configuration gaps earlier than committing to migration timelines.
az account present --output desk az connectedmachine record --resource-group  --query "[].{identify:identify,standing:standing,osName:osName}" -o desk

az useful resource record --resource-type Microsoft.AzureArcData/sqlServerInstances --query "[].{identify:identify,resourceGroup:resourceGroup,location:location}" -o desk

az connectedmachine machine extension record --resource-group  --machine-name  --query "[].{identify:identify,provisioningState:provisioningState}" -o desk
Anticipated behaviour: Arc brokers report wholesome standing, SQL Server situations are totally found with correct stock, and required extensions are provisioned efficiently. If discovery is incomplete, examine Arc agent connectivity, extension deployment, and SQL service working standing on supply VMs. If migration pre-checks fail, confirm SQL Server model compatibility and evaluate Defender logs for blocking points.
For any new functionality this week, in the event that they map to your operational roadmap, run a managed pilot, measure the impression, after which scale with confidence. That’s how you progress the needle on modernisation whereas managing threat.
🐍 Cease Utilizing If-Else Chains: Use the Registry Sample in Python As a substitute Kanwal Mehreen · Python · July 15, 2026 Lengthy conditional chains hinder extensibility in Python by violating the Open/Closed Precept, making code brittle when new choices are launched. The Registry Sample solves this by changing hardcoded dispatch logic with a central lookup desk the place parts register themselves dynamically. Implementing this sample permits system habits to be pushed by configuration, leading to extra maintainable and simply extensible pipelines.
➡️ 12 Methods to Cut back LLM Latency and Inference Prices in Manufacturing Kanwal Mehreen · Language Fashions · July 14, 2026 Decreasing LLM latency and inference prices in manufacturing requires optimizing workflow design by minimizing token utilization, using mannequin routing for particular duties, implementing multi-layered caching methods, and managing context budgets quite than relying solely on bigger contexts or aggressive batching.
➡️ 5 Actual-World SQL Initiatives to Construct Your Knowledge Portfolio Abid Ali Awan · SQL · July 13, 2026 Constructing a robust knowledge portfolio requires executing real-world SQL tasks throughout domains like buyer churn, knowledge warehousing, gross sales evaluation, banking segmentation, and healthcare to display the flexibility to wash knowledge, mannequin programs, and derive actionable enterprise insights.
➡️ Git Worktrees for AI Growth Shittu Olumide · Programming · July 17, 2026 Git worktrees present a necessary infrastructure layer that allows a number of AI brokers to function concurrently on a single repository by creating remoted workspaces, eliminating the chance of file collisions and context loss throughout parallel improvement.
➡️ Structured Language Mannequin Era with Outlines Iván Palomares Carrascosa · Language Fashions · July 13, 2026 The Outlines library introduces deterministic certainty into LLM output era by masking syntactically unlawful tokens, enabling practitioners to reliably get hold of strictly structured outputs like JSON by implementing particular constraints throughout inference.
➡️ 7 Python Frameworks for Orchestrating Native AI Brokers Shittu Olumide · Synthetic Intelligence · July 15, 2026 Seven Python frameworks present the mandatory orchestration layers for constructing, coordinating, and working safe, cost-effective AI brokers straight on native infrastructure.
➡️ 10 YouTube Channels Preserving You Forward in AI Vinod Chugani · Synthetic Intelligence · July 16, 2026 A curated number of ten YouTube channels gives complete, high-quality academic content material spanning machine studying concept, deep studying implementation, paper evaluation, LLM utility improvement, and business development monitoring for accelerating skilled AI information.
➡️ Getting Began with Conductor for Gemini CLI Shittu Olumide · Programming · July 14, 2026 Conductor introduces Context-Pushed Growth to resolve context points in AI coding by persisting mission specs and architectural context in repository recordsdata, enabling brokers to generate correct code based mostly on established mission constraints throughout classes.
➡️ 5 FREE Assets on Agentic AI Nahla Davies · Synthetic Intelligence · July 17, 2026 A curated set of free assets gives a structured path for practitioners to maneuver past constructing agent demos by integrating hands-on framework expertise, theoretical foundations in multi-agent programs, orchestration patterns, and important analysis methods.
➡️ Working with Pi Coding Brokers Shittu Olumide · Programming · July 16, 2026 Pi Coding Brokers advocates for a minimalist architectural method by explicitly documenting the options it omits, arguing that lowering built-in complexity and injected context results in extra environment friendly and cost-effective agentic workflows.
Apple has elevated costs for Apple Music and Apple One subscription plans, with particular person Apple Music rising to $11.99 month-to-month and household plans reaching $19.99.
Macworld notes these hikes observe earlier worth changes in October 2022, with Apple citing rising licensing prices as justification for the will increase.
Apple One bundles additionally noticed worth jumps, with Household plans now costing $27.95 and Premier plans reaching $39.95 month-to-month.
Only a few weeks after elevating costs on Macs, iPads, and different units, Apple has hiked costs on one more of its merchandise: Apple Music. In a quiet change to its web site, Apple has adjusted the pricing for all Apple Music plans in addition to Apple One.
Apple first elevated Apple Music costs in October 2022, when it went from $9.99 to $10.99 monthly. This replace raises the worth by one other buck, to $11.99 a month. Right here’s how the brand new pricing seems to be throughout all tiers:
Particular person: $11.99 (was $10.99)
Household: $19.99 (was $16.99)
Pupil: $6.99 (was $5.99)
Apple One Particular person: $19.95 (no change)
Apple One Household: $27.95 (was $25.95)
Apple One Premier: $39.95 (was $37.95)
Apple Music nonetheless prices lower than Spotify, which raised the worth of its Premium subscription by $1 to $12.99 monthly earlier this yr. Final August, Apple raised the worth of its Apple TV streaming service to $12.99 a month, a $3 enhance. On the time, Apple didn’t modify Apple One pricing.
In a press release to the press, Apple blamed the worth hikes on “rising licensing prices.” Apple’s Companies division, which additionally contains in-app purchases and subscriptions by the App Retailer, has been a constant supply of development. Final quarter, the corporate posted income of practically $31 billion
In accordance with famed, tap-dancing centenarian Dick Van Dyke, the key is optimism – and by no means waking up in a foul temper.
Nicely, a brand new scoping overview has dangerous information for anybody hoping for a shortcut.
It is all of these issues.
A crew led by pharmacologist Shaima Ibrahim of the American College in Cairo in Egypt reviewed 124 research on centenarians and supercentenarians spanning 55 years of analysis, and located no single magic formulation for dwelling previous 100.
As a substitute, the overview, revealed in Uncover Public Well being, suggests longevity emerges from numerous influences, from genes and DNA restore, food plan and exercise stage, to social help, and plain outdated luck.
Individuals who attain their a hundredth birthday haven’t got a secret technique a lot as a lifetime accumulating small benefits.
However there’s one other catch. Finding out centenarians means finding out solely the individuals who reached 100 – not the various extra who did not. That makes it troublesome to know whether or not a selected trait or habits really helped folks reside longer, or just occurred to be frequent amongst those that survived.
A human lifetime is a wealthy and sophisticated tapestry woven of many threads.
A single examine typically has a decent give attention to a single thread; a overview zooms out and sees how that examine suits within the larger image.
Ibrahim and her colleagues searched 1000’s of papers earlier than narrowing them all the way down to 124 research of centenarians, semi-supercentenarians (aged 105–109), and supercentenarians (aged 110+) that investigated components linked to distinctive longevity.
They then grouped the findings into broad classes.
Some targeted on biology – genetics, epigenetics, DNA restore, telomeres, irritation, metabolism, mitochondrial operate, and cognitive resilience. Others examined life-style, together with food plan, bodily exercise, smoking, alcohol use, character, and social connections.
The organic research advised that exceptionally long-lived folks typically age otherwise at a mobile stage.
The researchers repeatedly discovered proof of extra environment friendly DNA restore, more healthy mitochondria, higher management of irritation, and metabolic variations which will assist defend in opposition to age-related illness.
Genetics additionally performs a task, though the overview emphasizes that no single ‘longevity gene‘ exists.
“Distinctive longevity is polygenic, involving a number of genetic variants every with modest results that collectively exert substantial affect on lifespan,” the researchers write of their paper.
Way of life components performed simply as robust a task.
Throughout totally different populations, centenarians had been extra prone to eat largely plant-based diets, keep bodily lively via on a regular basis actions comparable to strolling and gardening, keep away from smoking, and preserve robust social and household ties.
Character traits comparable to resilience and decrease neuroticism had been additionally a constant theme.
Probably the most hanging findings needed to do with illness.
Centenarians do not keep away from illness fully, however many appear to delay it till a lot later than common – a phenomenon the researchers refer to as “compression of morbidity”.
Not everybody follows that sample, nonetheless. Some distinctive agers develop age-related illness a lot sooner than common, however then handle to reside with it for many years.
The researchers classify centenarians into three teams based mostly on their relationship with illness: escapers, who keep away from main age-related illness altogether; delayers, who develop it a lot later than common; and survivors, who develop illness earlier however reside with it for a few years.
This all paints a promising, if sophisticated, image of longevity – however with some caveats.
Solely a tiny fraction of the inhabitants lives to 100 – and centenarian research hardly ever embody the various different people who shared lots of the identical genes, diets, personalities, or habits however died many years earlier.
The overview cannot set up whether or not any of those components really trigger distinctive longevity, but it surely does, maybe, provide one thing extra scientifically priceless. It highlights the largest gaps in longevity analysis, significantly the necessity for long-term research that may distinguish trigger from coincidence.
“Longevity is pushed by a posh interaction of things during which genetic contribution strengthens dramatically at superior ages, but environmental and behavioral components stay decisive for most people,” the researchers write.
For these seeking to reside an extended and comfortable life, the recommendation stays a lot because it at all times has. Get your steps in, plant a tree, and eat a carrot.
This text was fact-checked by Michael Irving and edited by Rebecca Dyer. Whereas we delight ourselves on our course of, we’re solely human. When you spot a mistake, please tell us.
You might be working Claude Code on a characteristic department. The agent has been working for twenty minutes, it has learn your codebase, constructed up context, and began making actual progress on the authentication rewrite. Then a Slack message seems: manufacturing is down, somebody wants a hotfix on most important, and so they want it now.
Within the previous workflow, you stash your modifications, swap branches, lose all the things your AI agent constructed up, repair the bug, push, swap again, and spend ten minutes getting the agent re-oriented to what it was doing. In case you have been working two brokers concurrently on the identical listing, the state of affairs is worse — each brokers touching package deal.json, each producing edits to the identical information, and the second writes silently, overwriting the primary. No warning. No error. Simply corrupted work you uncover an hour later when exams fail in a method that is not sensible.
Git worktrees eradicate this whole class of issues. They don’t seem to be a brand new invention — the characteristic has been in Git since model 2.5, launched in 2015 — however the AI coding wave of 2025–2026 made them important infrastructure. One .git listing, a number of working directories, every by itself department, every invisible to the others. Every AI agent will get its personal remoted workspace. The hotfix will get its personal workspace. Nothing collides.
By the tip, you’ll know what worktrees are, how one can set them up, how one can run parallel AI brokers inside them with out chaos, and how one can preserve them over the lifetime of a mission.
# What Git Worktrees Really Are
A regular Git repository has one working listing — the folder the place your information stay and the place you edit code. To work on a unique department, you turn to it, which modifications all of the information in that listing to match the department. When you’ve got uncommitted work, you stash it first. In case your AI agent is mid-task, you interrupt it.
Git worktrees break this constraint. A worktree is a separate listing checked out from the identical repository. You possibly can have as many as you want, every by itself department, all coexisting concurrently in your filesystem.
my-project/                    ← most important worktree  (department: most important)
my-project-feat-auth/          ← linked worktree (department: feat/auth)
my-project-feat-api/           ← linked worktree (department: feat/api)
my-project-hotfix-login/       ← linked worktree (department: hotfix/login)
All 4 directories share the identical .git folder. They share historical past, objects, and commits. However every has its personal checked-out information, its personal index, and its personal working state. An agent modifying information in my-project-feat-auth/ can not see or contact something in my-project-feat-api/. They’re bodily separate directories that occur to share a git backend.
Why does this beat a number of clones? The naive various to worktrees is cloning the repository twice and dealing in numerous clone directories. This works, nevertheless it has actual prices: you duplicate your complete repository on disk, git historical past just isn’t shared between clones, commits in a single clone usually are not instantly seen in one other, and there’s no coordination between them on the git layer. With worktrees, you clone as soon as. Each extra worktree provides solely the price of the checked-out information, not one other copy of the total historical past.
The seven instructions that cowl all the things it’s good to handle worktrees:
Command
What It Does
git worktree add -b
Create a brand new worktree on a brand new department
git worktree add
Try an present department into a brand new worktree
git worktree record
Present all energetic worktrees with their branches and commit hashes
git worktree lock
Forestall a worktree from being pruned (helpful whereas an agent is working)
git worktree unlock
Launch the lock
git worktree take away
Delete a worktree cleanly (department is preserved)
git worktree prune
Clear up metadata for worktrees that have been manually deleted
That’s the full floor space. The whole lot else on this article is a workflow constructed on high of those seven instructions.
# Setting Up
Stipulations: Git 2.5 or greater. Run git --version to examine. Any fashionable system (macOS, Linux, Home windows with WSL or Git Bash) ships with a model above 2.5.
// Step 1: Beginning From a Clear Repository
Worktrees work finest when your most important department is clear. Commit or stash any in-progress work earlier than creating your first worktree.
# Confirm you've gotten a clear working tree
git standing

# If there may be uncommitted work, commit it
git add . && git commit -m "checkpoint: work in progress"
// Step 2: Creating Your First Worktree
# Create a brand new worktree at ../myapp-feat-auth on a brand new department feat/auth
# Exchange "myapp" together with your mission identify and "feat/auth" together with your department identify
git worktree add -b feat/auth ../myapp-feat-auth most important

# Confirm it was created
git worktree record
Each directories exist. Each comprise the identical information from the most important department. From this level, any modifications you make in myapp-feat-auth/ keep on feat/auth and are utterly remoted from most important.
// Step 3: Setting Up the Atmosphere within the New Worktree
That is the step most tutorials skip. A worktree is a brand new working listing. It doesn’t routinely have your .env file, your put in node_modules, or your Python digital surroundings. It’s essential set these up explicitly.
cd ../myapp-feat-auth

# Copy surroundings information which can be gitignored
# .env, .env.native, and comparable information usually are not tracked in git --
# they won't seem within the new worktree routinely
cp ../myapp/.env .env
cp ../myapp/.env.native .env.native 2>/dev/null || true

# Node.js mission: set up dependencies
# Every worktree is an impartial working listing --
# node_modules from the mother or father doesn't carry over
npm set up

# Python mission: create and activate a digital surroundings
# python -m venv .venv && supply .venv/bin/activate && pip set up -r necessities.txt
// Step 4: Verifying the Worktree Is Remoted
# From inside the brand new worktree
git department
# Ought to present: * feat/auth

# Make a check change
echo "// check" >> test-isolation.js
git standing
# Solely reveals the change on this worktree

# Change to the principle listing and confirm it's unaffected
cd ../myapp
git standing
# Clear -- the test-isolation.js change is invisible right here
ls test-isolation.js 2>/dev/null || echo "Not right here -- isolation confirmed"
That’s all it’s good to get began. The worktree is stay. Any agent you open in that listing operates solely on feat/auth.
# A Actual-World Case Examine
The clearest documented instance of git worktrees used for AI-driven parallel improvement comes from the Microsoft World Hackathon 2025.
Tamir Dresher, an engineering lead, confronted an issue that everybody constructing with AI brokers finally hits: too many options, too little time, and no solution to work on multiple factor directly with out fixed context-switching. Creating a number of clones of the repository was cumbersome. Switching branches destroyed the AI agent’s context. One thing needed to change.
The answer was to make use of git worktrees to create what Dresher described as a digital AI improvement crew. Every characteristic received its personal worktree. Every worktree received its personal VS Code window. Every window ran its personal AI agent. Dresher’s position shifted from developer to tech lead: scoping duties, reviewing output, guiding brokers that received caught, and merging completed work.
The setup seemed like this:
myapp/                       ← most important window: coordination and evaluations
myapp-feat-authentication/   ← Agent 1: implementing OAuth2 circulate
myapp-feat-api-endpoints/    ← Agent 2: constructing REST endpoints
myapp-bugfix-login-crash/    ← Agent 3: fixing manufacturing bug
Every VS Code window was utterly impartial. Language servers, linters, and check runners run per window. The brokers by no means touched one another’s information. When Agent 1 completed, Dresher reviewed the diff, authorized it, and opened a pull request (PR) from that department — the identical workflow as reviewing a PR from a human engineer.
Three concrete benefits Dresher documented from the hackathon:
No context loss. Every AI agent maintained full context of its particular job. Switching between options meant switching VS Code home windows, not branches, not stashes, not agent restarts. The agent’s understanding of what it was constructing stayed intact.
Totally different instruments for various jobs. As a result of every window was impartial, Dresher ran Roo in a single window for fast characteristic improvement and GitHub Copilot with Visible Studio in one other for debugging advanced points. Mixing instruments throughout duties was trivial.
Clear department administration. If a characteristic wanted to be deserted, closing the window and deleting the worktree took ten seconds. The opposite brokers have been unaffected.
The sample that emerged from this hackathon is now a documented finest apply throughout the AI coding group.
# Operating Parallel AI Brokers With Worktrees
The mechanics of the total parallel workflow have 4 levels: arrange the worktrees, give every agent its context, run the brokers, and checkpoint repeatedly.
// Stage 1: Scripting the Worktree Creation
Don’t create worktrees manually every time. A script ensures each worktree will get the identical setup — surroundings information, dependency set up, and a clear start line.
Stipulations: Git 2.5+, Bash (macOS/Linux/WSL)
run: Save as create-worktree.sh in your mission root, run chmod +x create-worktree.sh, then ./create-worktree.sh feat/auth-redesign most important.
#!/usr/bin/env bash
# create-worktree.sh
# Creates an remoted worktree for one AI agent job
# Utilization: ./create-worktree.sh  [base-branch]
# Instance: ./create-worktree.sh feat/auth-redesign most important

set -euo pipefail

BRANCH="${1:?Utilization: $0  [base-branch]}"
BASE="${2:-main}"
REPO_ROOT="$(git rev-parse --show-toplevel)"
REPO_NAME="$(basename "$REPO_ROOT")"

# Exchange slashes in department identify with dashes for listing naming
# feat/auth-redesign turns into feat-auth-redesign within the path
WORKTREE_PATH="${REPO_ROOT}/../${REPO_NAME}-${BRANCH////-}"

echo "Creating worktree for department: $BRANCH"
echo "Base department: $BASE"
echo "Worktree path: $WORKTREE_PATH"

# Fetch newest so the brand new department begins from the present distant state
git fetch origin 2>/dev/null || echo "(no distant -- skipping fetch)"

# Create the worktree on a brand new department from the bottom department
# Falls again to testing an present department if -b fails
git worktree add -b "$BRANCH" "$WORKTREE_PATH" "$BASE" 2>/dev/null ||
  git worktree add "$WORKTREE_PATH" "$BRANCH"

# Copy non-tracked surroundings information into the worktree
# These are gitignored, so they don't carry over routinely
for f in .env .env.native .env.improvement .env.check; do
  if [ -f "$REPO_ROOT/$f" ]; then
    cp "$REPO_ROOT/$f" "$WORKTREE_PATH/$f"
    echo "Copied $f"
  fi
completed

# Node.js: set up dependencies within the new working listing
if [ -f "$WORKTREE_PATH/package.json" ]; then
  echo "Putting in Node dependencies..."
  (cd "$WORKTREE_PATH" && npm set up --silent 2>/dev/null ||
   echo "(npm set up skipped -- run it manually within the worktree)")
fi

# Python: remind the developer to arrange their surroundings
if [ -f "$WORKTREE_PATH/requirements.txt" ] || [ -f "$WORKTREE_PATH/pyproject.toml" ]; then
  echo "Python mission detected."
  echo "Run within the new worktree:"
  echo "  python -m venv .venv && supply .venv/bin/activate && pip set up -r necessities.txt"
fi

echo ""
echo "Worktree prepared. Open it in your IDE and begin your agent:"
echo "  cd $WORKTREE_PATH"
What this does: The script creates the worktree, copies gitignored surroundings information throughout (the commonest setup failure), and runs dependency set up within the new listing. The ${BRANCH////-} substitution safely converts department names like feat/auth into filesystem-friendly listing names like feat-auth. The fallback on line 23 handles the case the place the department already exists remotely.
// Stage 2: Setting Up the AGENTS.md Context File
The only most essential factor you are able to do to enhance agent output is give every agent a transparent, written context file. Peer-reviewed analysis at ICSE 2026 confirmed that incorporating architectural documentation into agent context produces measurable beneficial properties in purposeful correctness, architectural conformance, and code modularity. The AGENTS.md file is the way you ship that context reliably, at scale, throughout each session.
Create this file in your mission root and commit it. Each agent reads it on session begin. Totally different instruments learn completely different filenames — AGENTS.md (OpenAI Codex), CLAUDE.md (Claude Code), AGENTS.md (generic) — however the content material issues greater than the identify.
# AGENTS.md
# Challenge context for AI coding brokers
# Commit this to your repository root.
# Each agent that opens this mission reads it first.

## Challenge Overview
Node.js/TypeScript REST API with a React frontend.
Stack: Node 20, Categorical 5, Prisma ORM, PostgreSQL, React 18, Vite.

## Construct and Take a look at Instructions
npm run dev          # begin dev server on port 3000
npm run construct        # manufacturing construct to dist/
npm run check         # run all exams (Vitest)
npm run check:watch   # watch mode
npm run lint         # ESLint and Prettier examine
npm run db:migrate   # run pending Prisma migrations
npm run db:seed      # seed improvement information

## Structure
- API routes:        src/routes/        one file per useful resource
- Enterprise logic:    src/providers/      by no means in route handlers
- Database entry:   src/repositories/  by no means name Prisma straight from providers
- Shared sorts:      src/sorts/index.ts

## Conventions
- All exported capabilities require JSDoc feedback
- No console.log in dedicated code -- use src/utils/logger.ts
- Error dealing with: throw typed errors from providers, catch in route handlers
- Department naming: feat/, repair/, refactor/

## Prohibited Zones -- Do NOT modify until explicitly informed to
- src/auth/              (safety crew possession, separate overview course of)
- prisma/migrations/     (solely modify through npm run db:migrate)
- .env information             (by no means commit, by no means learn outdoors config/)

## Present Worktree Process
Process:                 [FILL IN before starting the agent]
Department:               [FILL IN]
Acceptance standards:  [FILL IN]
The underside part is what makes this file work per-worktree. Each time you create a brand new worktree, open AGENTS.md and fill in these three traces earlier than beginning the agent. This scopes the agent’s work exactly and prevents it from wandering into areas it mustn’t contact.
For Claude Code particularly, the native -w flag handles worktree creation and session begin in a single command:
# Create a worktree and begin a Claude Code session inside it
claude --worktree feat/auth-redesign

# Quick kind
claude -w feat/auth-redesign

# With tmux panes for split-screen visibility
claude -w feat/auth-redesign --tmux
claude --worktree creates .claude/worktrees/feat-auth-redesign/ on a department known as worktree-feat-auth-redesign, then begins the session inside it. The .worktreeinclude file (gitignore syntax) controls which gitignored information are routinely copied into new worktrees:
# .worktreeinclude -- place in your repo root
# Information to repeat into each new worktree on creation
.env
.env.native
.env.improvement
// Stage 3: Operating A number of Brokers at As soon as
While you want three or 4 brokers working concurrently, scripting your complete setup saves time and ensures consistency.
run: Save as parallel-setup.sh, run chmod +x parallel-setup.sh, then ./parallel-setup.sh feat/auth feat/api feat/dashboard.
#!/usr/bin/env bash
# parallel-setup.sh
# Creates N worktrees for N parallel AI brokers in a single command
# Utilization: ./parallel-setup.sh ...
# Instance: ./parallel-setup.sh feat/auth feat/api feat/dashboard

set -euo pipefail

if [ $# -eq 0 ]; then
  echo "Utilization: $0 ... "
  echo "Instance: $0 feat/auth feat/api feat/dashboard"
  exit 1
fi

REPO_ROOT="$(git rev-parse --show-toplevel)"
REPO_NAME="$(basename "$REPO_ROOT")"
MAIN_BRANCH="most important"

echo "Establishing ${#@} parallel worktrees..."
git fetch origin 2>/dev/null || echo "(no distant -- skipping fetch)"

for BRANCH in "$@"; do
  SAFE="${BRANCH////-}"
  WT_PATH="${REPO_ROOT}/../${REPO_NAME}-${SAFE}"

  if [ -d "$WT_PATH" ]; then
    echo "Already exists: $WT_PATH (skipping)"
    proceed
  fi

  # Create worktree on a brand new department from most important
  git worktree add -b "$BRANCH" "$WT_PATH" "$MAIN_BRANCH" 2>/dev/null ||
    git worktree add "$WT_PATH" "$BRANCH"

  # Copy surroundings information
  for f in .env .env.native; do
    [ -f "$REPO_ROOT/$f" ] && cp "$REPO_ROOT/$f" "$WT_PATH/$f"
  completed

  echo "Created: $WT_PATH  (department: $BRANCH)"
completed

echo ""
echo "All worktrees:"
git worktree record
echo ""
echo "Open every path in a separate terminal or IDE window and begin your agent."
echo "Bear in mind to fill within the Process part of AGENTS.md in every worktree."
What this does: One command produces all of the worktrees with surroundings information copied. Operating ./parallel-setup.sh feat/auth feat/api feat/dashboard provides you three remoted working directories in underneath 5 seconds. Open every in its personal terminal tab, fill in AGENTS.md, and begin the brokers.
# Holding Worktrees From Drifting
The largest long-term failure mode just isn’t conflicts at creation time — it’s drift. A worktree that runs for 3 days with out syncing to most important accumulates divergence that makes merging a mission in itself.
Practitioners utilizing Claude Code with worktrees in manufacturing are clear on this: after finishing a checkpoint, pull and merge updates from the principle department — this prevents the worktree from drifting too far, which might end in huge, hard-to-resolve conflicts. The advice is to sync on the finish of each vital agent session, not simply earlier than the PR.
The fitting technique is rebase, not merge. Rebasing writes your department’s commits on high of the newest most important, which retains the historical past linear and makes the PR diff clear.
run: Save as sync-worktree.sh, run chmod +x sync-worktree.sh, then run ./sync-worktree.sh from inside any worktree listing.
#!/usr/bin/env bash
# sync-worktree.sh
# Rebases the present worktree department onto the newest most important
# Run at checkpoints to forestall department drift
# Utilization (from contained in the worktree): ./sync-worktree.sh [main-branch-name]
# Instance: ./sync-worktree.sh most important

set -euo pipefail

MAIN_BRANCH="${1:-main}"
CURRENT_BRANCH="$(git rev-parse --abbrev-ref HEAD)"

if [ "$CURRENT_BRANCH" = "$MAIN_BRANCH" ]; then
  echo "Already on $MAIN_BRANCH -- nothing to sync."
  exit 0
fi

echo "Syncing '$CURRENT_BRANCH' onto '$MAIN_BRANCH'..."

# Reject if there may be uncommitted work -- rebase requires a clear state
if ! git diff --quiet || ! git diff --cached --quiet; then
  echo "ERROR: Uncommitted modifications detected."
  echo "Commit your progress first:"
  echo "  git add . && git commit -m 'checkpoint: agent progress'"
  exit 1
fi

# Fetch the newest distant state
git fetch origin

# Rebase this department onto the newest most important
# --autostash handles minor working tree variations routinely
git rebase "origin/$MAIN_BRANCH" --autostash

echo ""
echo "Carried out. '$CURRENT_BRANCH' is updated with origin/$MAIN_BRANCH."
echo ""
echo "When able to push:"
echo "  git push --force-with-lease"
echo ""
echo "Notice: --force-with-lease is safer than --force."
echo "It refuses to push if another person pushed to this department since your final fetch."
What this does: The uncommitted-changes examine earlier than the rebase is a crucial security measure. A rebase on a grimy tree produces a complicated state. --autostash handles minor variations. --force-with-lease on push is safer than --force as a result of it refuses to overwrite distant work you haven’t seen but.
The complete merge lifecycle from agent completion to merged PR:
# Contained in the worktree, after the agent finishes its job

# 1. Commit the agent's work
git add .
git commit -m "feat: implement OAuth2 + PKCE auth circulate"

# 2. Sync with most important earlier than opening a PR
./sync-worktree.sh

# 3. Run exams to confirm nothing broke within the sync
npm run check

# 4. Push the department
git push --force-with-lease origin feat/auth-redesign

# 5. Open a PR through GitHub CLI or the online interface
gh pr create
  --title "feat: OAuth2 + PKCE authentication"
  --body "Implements OAuth2 per docs/auth-spec.md. All exams move."

# 6. After the PR merges, clear up
cd ../myapp
./cleanup-worktree.sh feat/auth-redesign
# The Full Command Reference
Each git worktree command with actual examples. Hold this part open whereas constructing your first workflow.
// Creating Worktrees
# Create a worktree on a brand new department from most important
git worktree add -b feat/funds ../myapp-payments most important

# Try an present department into a brand new worktree
git worktree add ../myapp-feat-auth feat/auth

# Indifferent HEAD -- helpful for reproducing a bug at a selected commit
git worktree add --detach ../myapp-debug abc1234

# Monitor a distant department straight
git worktree add ../myapp-hotfix origin/hotfix/login-crash
// Inspecting and Managing
# Present all worktrees with path, commit hash, and department identify
git worktree record

# Machine-readable output to be used in scripts
git worktree record --porcelain

# Lock a worktree so prune doesn't take away it
# Use whereas an agent is working to guard in opposition to unintentional cleanup
git worktree lock ../myapp-feat-auth --reason "agent-running"

# Launch the lock
git worktree unlock ../myapp-feat-auth

# Transfer a worktree listing (shut any open editors first)
git worktree transfer ../myapp-feat-auth ../worktrees/auth-redesign
// Cleanup
# Take away a worktree cleanly -- the department is preserved in git
git worktree take away ../myapp-feat-auth

# Pressure take away even with uncommitted modifications
# Solely use this if you find yourself sure the work may be discarded
git worktree take away --force ../myapp-feat-auth

# Clear up metadata for worktrees manually deleted with rm -rf
git worktree prune

# Preview what could be pruned with out really pruning
git worktree prune --dry-run

# Repair worktree references after shifting the .git listing
git worktree restore
# Frequent Errors and Fixes
Error Message
Trigger
Repair
deadly: 'feat/auth' is already checked out
Department in use by one other worktree
Use a unique department, or take away the prevailing worktree first
deadly: already exists
Goal listing exists
Delete it or select a unique path
error: '...' is a most important worktree
Tried to take away the principle checkout
Solely linked worktrees may be eliminated
error: worktree has modified information
Uncommitted modifications current
Commit the work, or use --force to discard
Worktree seems in git worktree record after rm -rf
Metadata not cleaned up
Run git worktree prune
# Conclusion
Git worktrees usually are not superior Git arcana. They’re a core infrastructure primitive that grew to become important the second AI coding brokers began working in parallel on the identical codebases.
The workflow on this article just isn’t theoretical. It’s what Tamir Dresher’s crew ran on the Microsoft World Hackathon. It’s what practitioners with Claude Code, Cursor, and Codex are documenting throughout GitHub and Medium proper now. It’s the sample the agentic coding group has converged on for one purpose: it’s the easiest factor that reliably solves the issue it was constructed to resolve.
The setup price is low. The 4 scripts on this article cowl the total lifecycle — create, sync, and clear up — in about 120 traces of bash. The conceptual mannequin is straightforward: one job, one department, one worktree, one agent. The payoff is that you may run a number of brokers in parallel with out spending your afternoon untangling conflicts that neither agent created deliberately.
In case you are already utilizing AI coding instruments and never utilizing worktrees, set them up in your subsequent mission. The create-worktree.sh script is a ten-second begin. In case you are constructing a crew workflow round AI brokers, AGENTS.md and the parallel setup script transfer you from ad-hoc periods to a repeatable course of that scales.
The mannequin writes the code. Your job is to create the circumstances the place it could try this cleanly, in parallel, with out getting in its personal method.
Shittu Olumide is a software program engineer and technical author keen about leveraging cutting-edge applied sciences to craft compelling narratives, with a eager eye for element and a knack for simplifying advanced ideas. You too can discover Shittu on Twitter.
Regardless of what some entrepreneurs will declare, there isn’t a take a look at for perimenopause. That doesn’t imply girls ought to need to put up with signs, however therapy recommendations typically lack scientific proof. And never all of the signs girls expertise in midlife may be blamed on hormones.
This article is from The Spark, our weekly local weather tech publication. Enroll to obtain it in your inbox each Wednesday.
The must-reads
I’ve combed the web to search out you at this time’s most enjoyable/necessary/scary/fascinating tales about expertise.
1China’s AI hole with the US might have simply narrowed A Chinese language startup has launched the world’s largest open AI mannequin. (Reuters $) + It competes with some Anthropic and OpenAI fashions. (Gizmodo) + The mannequin’s launch despatched AI and semiconductor shares sliding. (Bloomberg $) + Chinese language Nvidia options are additionally gaining traction. (SCMP) + Xi Jinping pitched China as an AI companion to the growing world. (CNBC) + The nation is betting large on open-source. (MIT Know-how Assessment)
2 Trump Media is promoting prompt entry to “market-moving’ social posts It’s developed a brand new technique to monetize the president’s posts. (Quartz) + And Trump may revenue straight from promoting entry to his statements. (BBC) + Kalshi says it caught Trump’s teleprompter operator insider buying and selling. (Verge)
3 Astronomers have discovered an environment on a close-by Earth-like planet It’s the primary probably liveable world identified to host an environment. (NYT $) + Making it a prime contender within the seek for aliens. (404 Media) + However you must know tips on how to spot one. (MIT Know-how Assessment)
4 A mind implant has restored feeling in a paralysed hand The recipient can now feed himself and drink from a cup. (Guardian) + Motion continued when the stimulation was turned off. (New Scientist $) + China has accredited a world-first mind chip. (MIT Know-how Assessment)
5 The EU has advised Google to share search knowledge and open up AI on Android It will likely be compelled to share knowledge with competing search suppliers. (Ars Technica) + And open Android telephones to rivals’ AI bots. (WP $)
6 Interval trackers are hiding privateness issues New analysis uncovers how they’re sharing customers’ well being knowledge. (BBC)
7 The Tesla driver in a deadly Texas crash overrode FSD, investigators say He bypassed the tech by urgent the gasoline pedal to 100%. (Verge)
8 A brand new stealth drone spins so quick that it disappears Although its creators admit it will possibly nonetheless be simply heard. (New Scientist $)
9 An area-station examine suggests why astronauts’ our bodies waste away Microgravity disrupts mitochondria, lowering protein manufacturing. (Nature)
10 “Adversarial clothes” that confuses facial recognition is all the fashion Privateness might be the following large pattern. (Guardian)
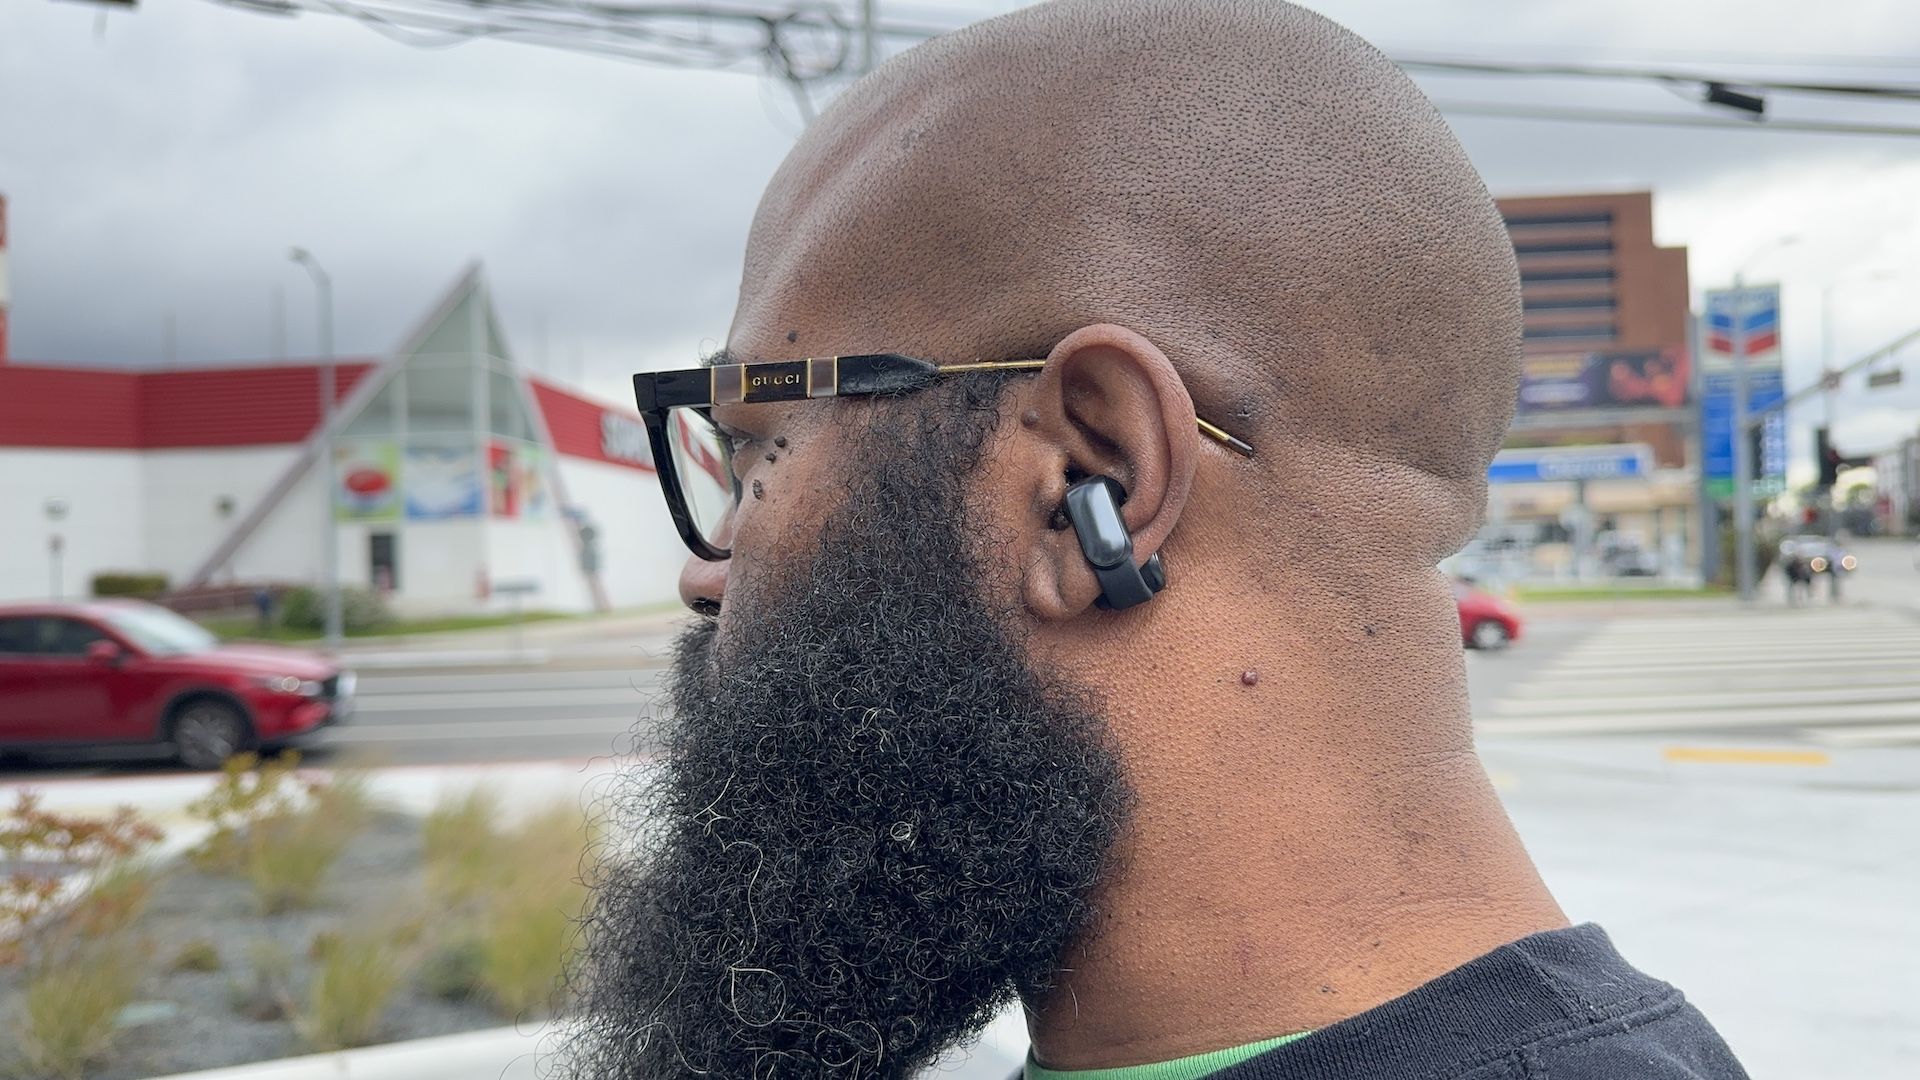
We love the Bose Extremely Open earbuds for plenty of causes, however particularly for his or her highly effective immersive sound setting, their minimal, smooth design, quick charging speeds, and a comparatively lengthy battery life.
Whereas they do not include multipoint connection or wi-fi charging, the Bose Extremely Open are nonetheless head and shoulders above different rivals in general high quality and design. At $199, they’re nonetheless just a little extra expensive than others, however $100 off feels prefer it might be all of the justification you want in the event you’re already out there.
✅Advisable if: you need the greatest open-ear earbuds in the marketplace and your finances is round $199; you need a pair of open-ear earbuds that will not compromise on immersive, high-quality audio; you want having easy-to-use button controls for playback, quantity, answering calls, and extra in your earbuds; you want one thing with a minimal, comfy match that may be worn and used for lengthy intervals of time.
❌Skip this deal if: you are not in search of open-ear earbuds and would moderately spend this amount of cash on higher-quality, totally in-ear units; you want one thing that gives greater than 4 hours of battery when spatial, immersive, or different modes are engaged; you favor a pair of earbuds with the next mud and water resistance score than IPX4.
The Bose Extremely Open earbuds are a certifiably nice pair of open-ear buds, that includes a mind-blowing immersive mode and a stable stereo audio mode, a charging case, and a minimal, comfy design. Bose says they will get customers as much as 4 hours of playtime in immersive mode or as much as 7 in stereo mode, whereas the case can provide as much as 48 hours of with intermittent fees.
Generally used sweeteners can straight intrude with the expansion of micro organism that assist help a wholesome intestine, in response to laboratory analysis from the College of Cambridge.
The strongest impact appeared when researchers mixed isosteviol, a sweetener utilized by the meals and beverage trade, with the antidepressant duloxetine. Collectively, the 2 compounds sharply decreased the expansion of two necessary bacterial species related to digestive well being, blood sugar regulation, and immune operate.
The scientists warning that the experiments have been carried out in a laboratory slightly than in individuals. Extra analysis will due to this fact be wanted to find out whether or not the bacterial adjustments result in significant well being results beneath real-world situations.
Sweeteners Could Not Be Biologically Inactive
Sweeteners are present in numerous on a regular basis merchandise, together with gentle drinks, sweet, desserts, breakfast cereals, snacks, and a few drugs. They’re generally promoted as options that present sweetness with much less sugar or fewer energy.
Nevertheless, rising proof has linked sweetener consumption with situations together with kind 2 diabetes, weight problems, and most cancers. These associations don’t show that sweeteners straight trigger these illnesses, and researchers are nonetheless working to know the organic processes that may clarify the connections.
One potential issue is the intestine microbiome, the big group of micro organism and different microorganisms dwelling within the digestive system. These microbes assist break down meals, produce helpful compounds, practice the immune system, and affect metabolism. Adjustments within the quantity or steadiness of those organisms might have an effect on well being all through the physique.
Regardless of the widespread use of sweeteners, comparatively little analysis has examined whether or not they straight have an effect on particular person intestine micro organism.
Professor Kiran Patil from the Medical Analysis Council (MRC) Toxicology Unit on the College of Cambridge mentioned: “Most of what we all know concerning the potential influence of sweeteners on our well being comes from animal analysis or from inhabitants research. Whereas these research have indicated involvement of the microbiome in mediating the impact of sweeteners, it is troublesome to know the way sweeteners act within the physique — is it via direct interactions with our intestine micro organism?”
“Answering that is additional sophisticated by the truth that we not often ever take sweeteners by themselves — we take them with drinks, in snacks, and even in treatment to masks bitterness,” added Dr. Sonja Blasche, a lead writer of the research, additionally the MRC Toxicology Unit.
Testing 39 Sweeteners In opposition to Intestine Micro organism
For the research, printed in Molecular Methods Biology, Dr. Blasche and her colleagues investigated how synthetic and low-calorie sweeteners affect intestine micro organism. In addition they examined whether or not these results change when sweeteners are blended with substances generally encountered in meals, drinks, and medicines.
The workforce grew 25 bacterial species individually within the laboratory. The choice included micro organism thought-about helpful, impartial, or probably dangerous.
Every species was then uncovered to 39 commercially used sweeteners, together with each pure and synthetic varieties. The researchers monitored how shortly every bacterial tradition multiplied and whether or not its development slowed or stopped.
About three-quarters of the sweeteners affected the expansion of at the very least one bacterial species. A number of decreased or utterly halted the expansion of micro organism related to a wholesome digestive system.
These findings counsel that some sweeteners are usually not merely inactive substances that cross via the digestive tract with out interacting with the organisms dwelling there.
Extra Than 100 Sudden Interactions
Individuals not often eat a sweetener in isolation. It might seem alongside caffeine in a beverage, flavoring in a dessert, or an lively ingredient in a medicine.
To recreate a few of that complexity, the researchers paired the sweeteners with substances together with caffeine, vanillin (vanilla extract), advantame (a synthetic sweetener), and eight generally used medicine.
The workforce recognized greater than 100 instances by which a sweetener’s impact modified when one other compound was current. The mixed results grew to become stronger in 34 instances and weaker in 68 instances.
Because of this the influence of a selected sweetener might rely partly on what else is consumed on the identical time.
Antidepressant Mixture Stood Out
Essentially the most dramatic outcome concerned isosteviol and duloxetine, an antidepressant prescribed to deal with melancholy, nervousness, and sure varieties of continual ache.
When used collectively, the compounds strongly suppressed Roseburia intestinalis and Parabacteroides merdae. Each species are thought-about necessary members of the intestine microbiome and have been linked to digestive well being and metabolic regulation.
Duloxetine is extensively used. Greater than 4.2 million sufferers within the US acquired prescriptions for the drug in 2023.
Learning micro organism one species at a time can reveal direct results, however the human intestine is a crowded ecosystem by which microbes consistently work together. To raised replicate these situations, the scientists constructed a simplified microbial group containing all 25 bacterial species.
They allowed the group to develop after which uncovered it to totally different mixtures of sweeteners and medicines. The workforce tracked which species grew to become extra plentiful, which declined, and whether or not the group retained its total selection.
Intestine Microbial Variety Declined
The mix of isosteviol and duloxetine decreased microbial variety inside the artificial group. Better variety is usually thought-about a function of a resilient and wholesome intestine microbiome, though the perfect microbial composition can differ between people.
The mix additionally modified the group’s inner steadiness by permitting some bacterial species to flourish whereas others declined.
Extra experiments steered that these adjustments elevated toxicity towards sure host cells. In addition they disrupted the exercise of different cells concerned in irritation and immune responses.
These outcomes increase the likelihood that interactions between sweeteners, drugs, and microbes may affect greater than digestion alone. Nevertheless, the simplified laboratory system can not absolutely reproduce the complexity of the human physique.
Dr. Blasche mentioned: “Sweeteners are sometimes marketed as metabolically impartial, however our research challenges this concept. We discovered that they’ll straight have an effect on intestine micro organism, significantly when blended with different compounds comparable to treatment and meals components. These frequent mixtures may have unintended results on our intestine microbiome.”
Human Research Are Nonetheless Wanted
The researchers emphasize that the findings shouldn’t be interpreted as proof that sweeteners or the examined mixtures trigger hurt in individuals.
The experiments concerned micro organism and cell fashions beneath managed laboratory situations. Within the human digestive system, sweeteners could also be absorbed, chemically altered, diluted, or damaged down earlier than reaching explicit microbes. Weight loss program, genetics, treatment use, and the prevailing composition of an individual’s microbiome may additionally change the end result.
Future research might want to decide whether or not comparable interactions happen in people, what doses can be required, and whether or not any microbial adjustments produce measurable results on well being.
Professor Patil, the research’s senior writer, added: “Our research means that synthetic sweeteners do not simply cross via the physique passively — they’ll work together with intestine microbes, and these results will be amplified or altered by different substances like drugs. These findings can assist information new research in direction of understanding how sweeteners would possibly affect well being in surprising methods.”
The analysis was funded by the European Union’s Horizon 2020 program and the UK Medical Analysis Council.
, I’ll give my first impressions of the latest OpenAI mannequin, GPT-5.6. The mannequin was launched a couple of days in the past, and I’ve gotten the possibility to check it extensively for the reason that launch and evaluate it towards different fashions similar to GPT-5.5, Opus 4.8, and Fable 5.
I’ll give my judgment on the mannequin, share my experiences with it, and clarify find out how to work as successfully as potential with it. I imagine it’s a mannequin with some professionals and a few cons in comparison with the choice Anthropic fashions similar to Opus 4.8 and Fable 5. However general, it’s an excellent mannequin, and I undoubtedly advocate making an attempt it out.
This infographic highlights the primary contents of this text. I’ll focus on my first impressions of GPT 5.6, protecting the totally different elements of the mannequin, and in addition the strategies that I apply every day to get essentially the most out of the mannequin. Picture by ChatGPT.
Why use GPT-5.6?
To begin with, I’d prefer to cowl why you need to care about this text, and on this case, it’s why you need to care about GPT-5.6 and find out how to use it successfully. To begin with, the explanation you need to care about GPT-5.6 is that the earlier era of the identical mannequin, GPT-5.5, was a terrific mannequin and a mannequin I personally used extensively.
I imagine GPT-5.5 was principally on par with Opus 4.8 in a variety of duties, and in some duties, similar to code evaluate, it was far superior in my view.
Thus, you need to in fact care concerning the subsequent era of the identical mannequin, GPT-5.6, because it ought to, on paper, be higher. Moreover, GPT-5.6 has some quirks which you need to undoubtedly find out about. For instance, the mannequin is available in three totally different sizes:
The place Sol refers back to the Solar, Terra refers back to the Earth, and Luna refers back to the Moon, representing the sizes of the fashions. Sol is one of the best one and the frontier mannequin. Additionally they, with every mannequin, launched totally different reasoning ranges, which may make the mannequin suppose for longer or shorter earlier than offering solutions. The straightforward trade-off is that when you make the mannequin cause for longer, it is going to give higher-quality responses, however it is going to take longer to offer responses.
I’ll share my strategies and ideas on find out how to use the fashions as successfully as potential.
My ideas on GPT-5.6
First, let me cowl my general ideas on GPT-5.6. General, I’d say it’s an enchancment over GPT-5.5 in principally each side. It’s only a bit higher than GPT-5.5 for all the pieces.
I in fact use the mannequin for code evaluations, by which it nonetheless discovers a variety of points. I imagine it’s barely higher at catching points within the code, each with regard to precision and recall, i.e., catching all of the bugs that exist, which is recall, and really being right when reporting a bug, which is precision.
I’ve additionally tried the mannequin for precise implementations, and I imagine GPT-5.6 is ready to work for longer to finish duties and is principally extra thorough in the best way it does its work. I nonetheless imagine GPT-5.5 was fairly good at getting duties executed, however I feel GPT-5.6 is barely higher.
Nonetheless, it’s value noting that I don’t suppose it is a very sturdy enchancment; I imagine it’s an incremental enchancment over the earlier GPT mannequin.
One draw back I wish to be aware is that when you use GPT-5.6 with further excessive and even extremely considering, it principally drains your utilization limits instantly.
Now it’s value noting that OpenAI really eliminated the five-hour utilization restrict, a minimum of for a short lived period of time, which undoubtedly helps lots right here. So that you solely have the weekly restrict; nevertheless, I imagine that when you use the mannequin with further excessive or ultra-thinking, it principally drains your utilization instantly, and when you’re on a subscription, it’s very onerous to make use of the mannequin for an prolonged time frame, and undoubtedly very onerous to make use of a number of fashions in parallel.
Moreover, I feel that when you use the mannequin with one among these excessive reasoning modes, it’s additionally very, very gradual. Slower than I’d anticipate it to be, undoubtedly when engaged on less complicated duties. So, I’ve really ended up utilizing further excessive considering for planning and medium reasoning for precise implementations, which I’ll cowl extra within the subsequent part. However I feel it’s value noting that I needed to tune down the reasoning ranges to keep away from hitting charge limits instantly.
That is, in fact, necessary as a result of while you take a look at the benchmarks, what’s reported is normally one of many tremendous reasoning ranges, and when you’re not ready to make use of that as a result of it drains your utilization instantly, then that in fact makes the mannequin successfully worse for you when making an attempt it in comparison with the benchmarks.
I’d additionally prefer to have a brief part protecting my ideas on the totally different sizes that you could select. I principally use Sol, the biggest mannequin, as I imagine it’s one of the best mannequin. Nonetheless, I’ve learn some benchmarks saying that in some conditions you’re higher off utilizing Terra with the next reasoning degree than Sol with the decrease reasoning ranges. I examined this a bit myself and wasn’t actually capable of discover any stark variations, so I ended up staying with Sol with the reasoning efforts that I discussed earlier.
How you can successfully apply GPT-5.6 to resolve issues
Use circumstances for GPT-5.6
Now I’ll get into find out how to successfully use GPT-5.6 to resolve issues. The primary factor you need to begin doing instantly, particularly when you’re utilizing Claude Code, is to have GPT carry out your code evaluations.
For my part, you principally don’t want human code evaluations anymore. In fact, you may want it if there’s a essential piece of infrastructure otherwise you actually desire a human to have a look at it, however for essentially the most half, I imagine that Codex is sweet sufficient as a code reviewer to keep away from bugs being pushed to manufacturing.
Now you may also, in fact, use GPT-5.6 for precise implementations. Nonetheless, in my view, I’ve higher success utilizing the next setup for implementations. The 1st step is that I exploit Claude Fable to plan the implementation, and step two is that I change and begin executing the implementation with Claude Opus 4.8 as a substitute. For my part, this provides me higher outcomes than simply utilizing GPT-5.6, even when I exploit the next reasoning degree for planning after which a decrease reasoning degree for implementations.
And one other level you may use GPT-5.6 for is laptop use or browser use. For my part, GPT is excellent at laptop use and browser use, and it’s fairly quick when interacting with the browser, particularly if I exploit a medium reasoning degree. I feel GPT-5.6 navigates my browser extremely properly, which is, in fact, necessary when verifying code end-to-end, for instance, or performing actions within the browser for you. So I imagine it is a superb use case.
Strategies to make use of GPT-5.6 successfully
Now, I’ll transfer over to some particular strategies that I implement and apply when using GPT-5.6. The primary subject I need to cowl is the reasoning ranges. As I discussed earlier, when you go together with the additional excessive or ultra-reasoning ranges, I imagine the mannequin is each too gradual and spends utilization limits manner too quick, which doesn’t actually work when you’re on the subscription, even when you’re on the $200 subscription.
Thus, the method that I began utilizing is that I’ve further excessive considering once I’m planning with GPT-5.6. So, at all times once I’m beginning a job, I begin with plan mode, which has further excessive reasoning. When the plan is completed, I change to a medium reasoning degree to really implement the code, contemplating code implementation is commonly simpler than code planning. It’s because code planning requires you to look into your entire repository and take into account how one thing ought to be applied, whereas the precise implementation is simply implementing the plan that was already made for you.
One other crucial method when utilizing GPT-5.6 is giving it entry to all the pieces. One factor that I observed that was fairly inconvenient was that I’ve labored principally with Claude Code earlier than and had given Claude entry to all the pieces I’m utilizing via MCP, similar to Gmail, Google Calendar, Slack, Playwright MCP, and so forth. After which once I began utilizing GPT-5.6, it carried out worse as a result of I didn’t bear in mind to present it entry to all of those instruments. So my different predominant tip right here is to really present GPT-5.6 entry to all of the instruments that it wants.
OpenAI has principally all the identical connectors that Claude Code has, and there’s no cause you shouldn’t give entry to Codex when you already give entry to Claude Code.
And lastly, the final tip I need to cowl is to keep in mind that OpenAI typically provides out resets, which is without doubt one of the massive variations between Claude Code and Codex. So, with Claude Code, they often do resets of utilization limits for everybody, which is, in fact, nice when you’ve spent a few of your limits; nevertheless, Codex additionally does that, however they normally really present you a banked reset, which is principally a reset that you could set off at any time limit and can reset your utilization limits.
This may be nice in case you have excessive anticipated utilization for a shorter time, or when you simply spent all of your tokens and must spend extra tokens. Nonetheless, it’s value noting that resetting the utilization limits not solely, in fact, units your utilization to 0%, nevertheless it additionally resets the date of when the following utilization reset happens. So your subsequent five-hour restrict can be 5 hours later, and your subsequent week restrict can be one week later. So in addition they reset, which reduces the advantage of the banked resets, although they’re nonetheless very priceless, in fact.
Traditionally, OpenAI has offered banked resets from time to time, so in case you have a subscription, you’ll get them over time.
Conclusion
On this article, I coated my opinion on the newest OpenAI mannequin, GPT-5.6, and my ideas on it. I mentioned why you need to use the mannequin, highlighting that the earlier era of the OpenAI mannequin, GPT-5.5, was already superb, and that that is an enchancment over the mannequin. I additionally shared some particular strategies on find out how to use the mannequin successfully, which is essential as a result of GPT-5.6 comes with some totally different utilization settings. For instance, it is available in three totally different sizes of fashions, they usually even have totally different reasoning ranges you may select between. I imagine you have to be utilizing GPT-5.6 for code evaluations, undoubtedly. And the distinction between GPT-5.6 and Opus 4.8 shouldn’t be that massive in relation to code implementations, laptop use, and so forth. So my present coding setup will nonetheless stay: Claude Fable for planning, Opus 4.8 for execution, and GPT-5.6 for reviewing my code. In fact, you need to at all times keep on prime of the newest fashions, strive them out your self, see in the event that they work higher on your use circumstances, and thus determine if it’s related to you.