Home Blog Page 17

10 YouTube Channels Preserving You Forward in AI

[ad_1]


Introduction

 
The unreal intelligence (AI) ecosystem is transferring at a breakneck tempo. In the event you attempt to learn each new analysis paper on ArXiv or check each open-source repository that hits GitHub, you may burn out earlier than the week is over. For information professionals, staying up to date is not about studying every part; it is about curating the precise data streams. In 2026, YouTube has solidified its place because the premier platform for AI training, providing every part from line-by-line code walkthroughs to high-level business evaluation.

On this article, we stroll by means of the highest 10 YouTube channels for information scientists and AI engineers, organized into 4 key classes: The Analysis and Paper Breakers, The Sensible AI Builders, The Core Idea Educators, and The Business Analysts.

We have additionally highlighted a particular playlist or video kind for every channel so you possibly can soar straight into the very best content material. Whether or not you are trying to construct multi-agent methods, perceive the maths behind transformers, or work out which new mannequin is value your time, these channels belong in your subscription feed.
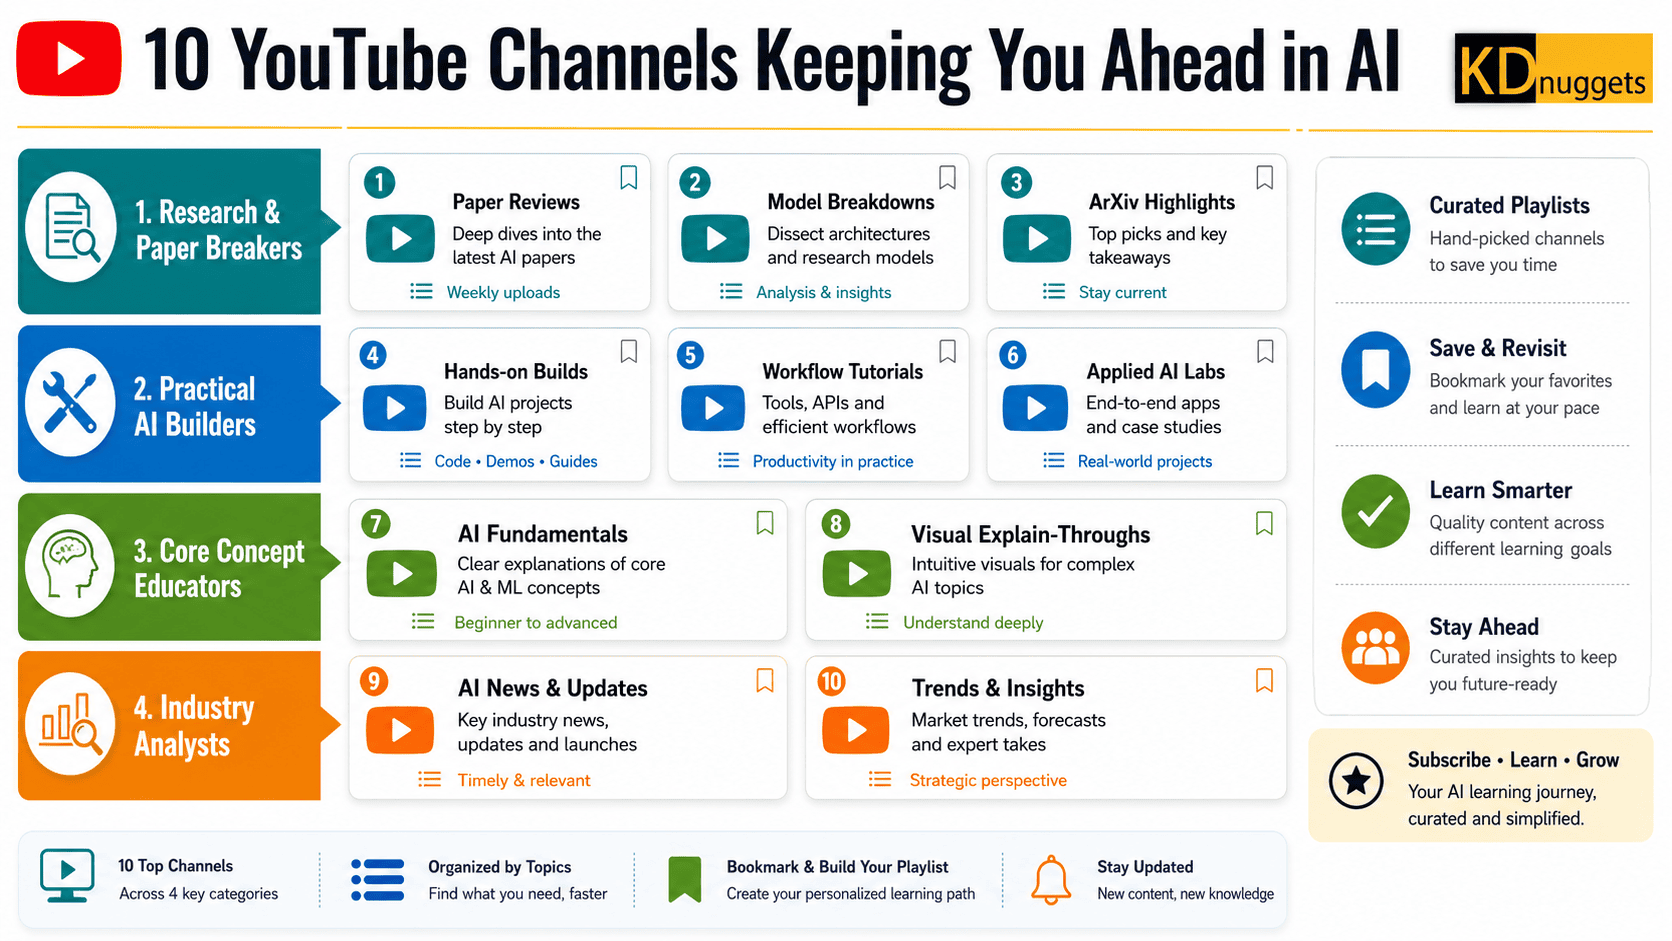
 

YouTube Channels Keeping Ahead AI
Click on to enlarge


The Analysis and Paper Breakers


// 1. Demystifying New Fashions with Two Minute Papers

Studying tutorial machine studying papers is usually a dense and exhausting course of. Hosted by Károly Zsolnai-Fehér, Two Minute Papers is known for taking essentially the most complicated AI analysis and distilling it into extremely visible, accessible, and enthusiastic short-form movies.

Here is why this channel is a must-watch:

  • Breaks down complicated analysis visually, displaying the precise outputs of latest generative fashions, robotics simulations, and rendering engines.
  • Distills 30-page tutorial papers into 5-to-10-minute summaries that spotlight the core breakthroughs and sensible implications.
  • Offers a relentless pulse on the place the bleeding fringe of AI analysis is heading earlier than it turns into commercialized.

Studying Useful resource: Browse his latest movies protecting the most recent generative video fashions and fluid physics simulations to see what the following era of AI will seem like.


// 2. Deep Diving into Machine Studying Papers with Yannic Kilcher

If Two Minute Papers supplies the visible abstract, Yannic Kilcher supplies the rigorous, line-by-line technical deep dive. Yannic reads essentially the most complicated machine studying papers so you do not have to, breaking down the maths, the structure, and the methodology on a digital whiteboard.

Key options of Yannic’s content material:

  • Affords thorough walkthroughs of mathematical formulation and neural community architectures that different channels gloss over.
  • Offers trustworthy, unfiltered critiques of hyped papers, usually declaring flawed methodologies or exaggerated claims.
  • Covers the open-source group extensively, conserving you up to date on the debates and philosophical shifts shaping the AI house.

Studying Useful resource: His “Machine Studying Papers Defined” playlist is a goldmine for engineers who need to perceive the mechanics behind new basis fashions.


The Sensible AI Builders


// 3. Constructing AI Purposes with AI Jason

Understanding how a big language mannequin (LLM) works is fully completely different from integrating one right into a enterprise workflow. AI Jason focuses strictly on the applying layer, educating builders find out how to construct sensible, production-ready instruments utilizing trendy agentic frameworks.

What makes Jason’s channel invaluable:

  • Delivers step-by-step tutorials on retrieval-augmented era (RAG) and sophisticated multi-agent architectures.
  • Balances low-code automation instruments with Python-based options, catering to a variety of technical proficiencies.
  • Focuses on actual enterprise use circumstances, transferring properly past fundamental chatbots to completely autonomous workflow methods.

Studying Useful resource: Search his channel for “LangChain Multi-Agent tutorials” to learn to orchestrate a number of LLMs to finish complicated, multi-step duties.


// 4. Engineering Trendy LLM Apps with AssemblyAI

Whereas it is technically a company channel, AssemblyAI produces a few of the most unbiased, high-quality academic content material for AI builders on YouTube. They persistently prioritize real instruction over product promotion.

Here is what AssemblyAI gives the developer group:

  • Excessive-production-value crash programs on vector databases, RAG methods, and API integrations.
  • Clear, visible explanations of complicated audio fashions, speech-to-text methods, and pure language processing (NLP) architectures.
  • Code-along tasks that provide you with production-ready templates you possibly can convey immediately into your personal repositories.

Studying Useful resource: Their “Massive Language Fashions Defined” sequence is among the cleanest, most sensible introductions to constructing with trendy APIs.


// 5. Coding the Future with Sentdex

Harrison Kinsley’s Sentdex channel has been a staple of the Python programming group for years. Because the business has developed, so has his content material, with a major focus now on utilized machine studying and deep studying constructed from the bottom up.

Why Sentdex stays important:

  • Offers from-scratch coding tutorials that power viewers to know the underlying mechanics of neural networks with out hiding behind high-level libraries.
  • Explores all kinds of functions, from coaching customized reinforcement studying fashions to constructing self-driving automotive simulations in video games.
  • Adopts new APIs and frameworks instantly upon launch, supplying you with an early have a look at find out how to work with the most recent instruments.

Studying Useful resource: The “Neural Networks from Scratch in Python” playlist is important for anybody who needs to genuinely perceive deep studying mechanics moderately than simply use them.


The Core Idea Educators


// 6. Studying from First Rules with Andrej Karpathy

As a founding member of OpenAI and former Director of AI at Tesla, Andrej Karpathy is among the most revered engineers within the subject. His YouTube channel features as a graduate-level course in deep studying, taught by somebody who has constructed frontier fashions himself.

Options that make Karpathy’s channel stand aside:

  • Well-known for his “Let’s construct from scratch” long-form coding periods, the place he constructs complicated methods like GPT tokenizers and backpropagation engines stay on display screen.
  • Delivers exceptionally clear explanations of core ideas together with backpropagation, transformers, and the coaching loop behind giant language fashions.
  • Bridges the hole between tutorial concept and optimized manufacturing code in a approach that few educators can.

Studying Useful resource: Put aside a weekend for his “Neural Networks: Zero to Hero” sequence. It is probably the greatest free AI programs obtainable wherever as we speak.


// 7. Constructing Statistical Instinct with StatQuest

If the arithmetic behind information science and machine studying really feel intimidating, StatQuest with Josh Starmer is the precise place to start out. Josh has a uncommon expertise for turning complicated statistical ideas and machine studying algorithms into easy, intuitive explanations.

What you get from StatQuest:

  • Removes intimidating notation and replaces it with step-by-step visible reasoning, protecting every part from fundamental chance and principal part evaluation (PCA) to complicated transformer architectures.
  • Covers the total spectrum of information science in a logical, scaffolded order that rewards long-term subscribers.
  • Produces “BAM!” moments — the channel’s signature educating system — that make sure the core logic of an algorithm really sticks.

Studying Useful resource: His “Machine Studying” playlist is the perfect companion when getting ready for information science technical interviews.


// 8. Structured Machine Studying Training with DeepLearning.AI

Based by AI educator Andrew Ng, the DeepLearning.AI channel extends his legendary Coursera curriculum to YouTube. It gives a structured, university-tier strategy to constructing experience in information science and machine studying.

Why this channel is a staple:

  • Covers the core ideas of classical machine studying, deep studying, and trendy MLOps frameworks in a logical, progression-based order.
  • Options “AI Heroes” interview segments, the place Andrew Ng speaks immediately with high researchers concerning the state and way forward for the sphere.
  • Repeatedly updates its content material to mirror the shift from conventional machine studying towards generative AI paradigms.

Studying Useful resource: The “AI for Everybody” introductory video sequence is a wonderful place to begin for constructing a grounded, hype-free understanding of the know-how.


The Business Analysts


// 9. Chopping By the Hype with AI Defined

For conserving tempo with fast mannequin releases, benchmarks, and business information, AI Defined gives essentially the most sober, analytical breakdowns on the platform. In an ecosystem stuffed with overclaiming, this channel is a constant supply of essential considering.

Key options of AI Defined:

  • Checks new fashions in opposition to troublesome logic and reasoning duties moderately than merely repeating an organization’s press launch.
  • Analyzes benchmarks, functionality overhangs, and the security and financial concerns of deploying frontier fashions at scale.
  • Consolidates every week’s value of fragmented AI information into dense, extremely informative summaries that respect your time.

Studying Useful resource: Tune into the weekly information roundups for a no-nonsense evaluation of a very powerful basis mannequin releases and analysis findings.


// 10. Discovering New Instruments with Matt Wolfe

Generative AI is producing 1000’s of latest instruments and software program platforms each week. Matt Wolfe focuses on the sensible, on a regular basis instruments coming into the market, making his channel precious for anybody trying to automate and speed up their workflows.

Why Matt Wolfe is value your time:

  • Offers hands-on, screen-share critiques of latest AI software program, browser extensions, and artistic platforms with trustworthy assessments.
  • Cuts by means of the noise to focus on the instruments companies are literally adopting for productiveness, video era, and workflow automation.
  • Maintains an energetic pulse on the AI startup ecosystem, surfacing helpful merchandise properly earlier than they seem on mainstream tech media.

Studying Useful resource: His common “AI Information and Instruments” weekly wrap-ups are one of the environment friendly methods to find software program that may velocity up your day-to-day work.


Wrapping Up

 
The ten channels above cowl each degree of the stack — from foundational math and from-scratch coding to paper evaluation, LLM utility improvement, and business pattern monitoring. Choose one from every class, spend a month with it, and see which of them you really sit up for opening. These are those to maintain.


Vinod Chugani is an AI and information science educator who bridges the hole between rising AI applied sciences and sensible utility for working professionals. His focus areas embrace agentic AI, machine studying functions, and automation workflows. By his work as a technical mentor and teacher, Vinod has supported information professionals by means of ability improvement and profession transitions. He brings analytical experience from quantitative finance to his hands-on educating strategy. His content material emphasizes actionable methods and frameworks that professionals can apply instantly.

[ad_2]
Hackers abuse ViPNet software program to focus on Russian govt companies

0

[ad_1]

A sophisticated menace actor is abusing the replace mechanism for the ViPNet personal networking product suite to focus on Russian organizations, together with authorities companies.

Dubbed HelloNet, the marketing campaign has been energetic since a minimum of Could, deploying a malicious payload that acts as a proxy and loader for extra malware.

In response to Kaspersky researchers, HelloNet has impacted organizations within the authorities, vitality, transport, schooling, and logistics sectors.

image

ViPNet replace abuse

ViPNet is a household of Russian information-security merchandise developed by InfoTeCS, offering VPN, endpoint, and community entry safety, firewall, certificates administration, centralized administration, and safe messaging and file switch.

The device is usually utilized in Russia, the place it’s licensed by the authorities to be used in authorities and different regulated environments.

Resulting from its market attain in Russia, particularly amongst high-value organizations, it has been focused typically by hackers. In April, 2025, Kaspersky reported that menace actors impersonated a ViPNet replace in assaults.

Within the newest marketing campaign, attackers positioned a malicious file (wtsapi32.dll, dubbed HelloInjector) contained in the native ViPNet Replace System listing to be sideloaded at system startup by way of the legit itcsrvup64.exe.

This DLL is the first-stage loader that injects into the svchost.exe course of, granting next-stage payloads elevated privileges on Home windows and persistence throughout reboots.

Kaspersky doesn’t describe precisely how the attackers gained preliminary entry to carry out this file change, nor do they declare that ViPNet’s replace infrastructure itself was compromised.

Malware toolset

HelloInjector runs its embedded payload, which Kaspersky named HelloProxy, in reminiscence and contacts the command-and-control (C2) server to obtain further modules.

Considered one of these modules is HelloExecutor, a backdoor that may execute instructions and conduct community reconnaissance on the host.

A second one is HelloCleaner, a device that removes ViPNet log knowledge to cover the malicious exercise.

One other implant referred to as HelloBackdoor is Rust-based and helps importing and downloading information, in addition to command execution.

Kaspersky has tentatively attributed the marketing campaign to an unidentified Chinese language-speaking superior persistent menace (APT) group.

Nevertheless, the researchers confused that the proof is weak, relying totally on an unused string referencing the Chinese language web site sina.com and a malware obtain mirror hosted by the College of Science and Know-how of China.

Because of this, they assign the attribution low confidence and don’t rule out the opportunity of a false flag operation.

The cybersecurity agency recommends thorough monitoring of techniques working ViPNet software program, notably visitors passing via ports 5003, 5060 (HelloProxy), and 443 (HelloBackdoor).


article image

Safety groups log 54% of profitable assaults and alert on simply 14%. The remainder transfer via your atmosphere unseen.

The Picus whitepaper reveals how breach and assault simulation assessments your SIEM and EDR guidelines so threats cease slipping by detection.

Get the whitepaper

[ad_2]

Can Ozempic forestall or deal with most cancers? It is approach too quickly to say, an skilled cautions

0

[ad_1]

Within the weeks across the 2026 annual assembly of the American Society of Medical Oncology, my telephone stored buzzing with alerts about GLP-1 medication and most cancers. The headlines had been in all places — from NPR and The Washington Publish to Substack and heated exchanges on social media — all circling the identical declare: Ozempic may decrease the chance of most cancers.

Behind these headlines is a actual wave of research, involving thousands and thousands of sufferers. I am a doctor and medical epidemiologist, and my group and I design and interpret these similar sorts of research that take a look at what broadly used medication truly do.

[ad_2]

Backpropagation Defined for Rookies (Half 1): Constructing the Instinct

[ad_1]

to know backpropagation?

In case you’re making an attempt to know how fashionable AI techniques like massive language fashions (LLMs) are skilled, backpropagation is without doubt one of the most vital ideas to know.

However in case you ask me how I felt once I encountered it, I used to be utterly misplaced by trying on the math equations. It felt like a psychological block for me.

I spotted and needed to begin from scratch and construct my understanding one step at a time.

That journey started with my earlier article, the place we constructed a neural community from scratch utilizing a easy dataset and understood the way it makes predictions.

The weblog obtained an excellent response. Thanks for that!

Now, let’s proceed with the identical strategy. We’ll break down backpropagation step-by-step, retaining it as easy and intuitive as earlier than.

Earlier than we start, I simply need to say one factor. We’ll take this one step at a time.

Matters like backpropagation can really feel overwhelming at first, however as soon as we construct a powerful basis, every little thing else turns into a lot simpler to know.

So, let’s get began.


Welcome again!

Let’s proceed our studying journey via deep studying.

We have already got a primary understanding of neural networks, which we explored utilizing a easy dataset within the earlier weblog.

Now, let’s first recall what we realized within the earlier weblog on neural networks.

Fast Recap

We thought of this easy dataset.

Picture by Creator

After plotting the information, it appeared like this:

Picture by Creator

We noticed {that a} single line was not sufficient to suit it. So, we determined to unravel it utilizing neural networks.

Subsequent, we obtained to know concerning the equation of a single neuron, and after that, we realized concerning the totally different layers in a neural community.

For simplicity, we thought of one hidden layer with two hidden neurons.

Subsequent, we noticed how the 2 hidden neurons produced two totally different linear transformations, after which we needed to mix them within the output layer.

Nonetheless, we came upon that combining two strains produced one other line, not the curve that would match the information.

That is the place we realized the importance of activation capabilities, as they introduce non-linearity into the mannequin.

So, we handed the outputs from the hidden neurons via the activation perform (ReLU) after which mixed them within the output layer.

In different phrases, we took the linear mixture of the outputs from the activation perform within the output layer, and eventually, we obtained the curve.

Picture by Creator

Within the earlier weblog we constructed the neural community structure and noticed the way it makes predictions via ahead propagation.

Picture by Creator

Earlier than we find out how backpropagation works, let’s first have a look at the values produced at every layer throughout the ahead cross which we mentioned in earlier weblog.

We’ll use these values all through the weblog to know how the community learns by updating its parameters.

Picture by Creator

Why Does the Community Have to Be taught?

After we have a look at the ultimate curve produced by our neural community, we are able to see that it isn’t an excellent match.

For instance, when the hours studied (x) is 1, the precise examination rating is 55, however our neural community predicts it as 28, which is a large distinction.

Now, we have to make our neural community carry out higher, which implies it ought to predict values which are a lot nearer to the precise examination scores.

To do this, the neural community must study. By studying, we imply determining which parameters ought to be elevated and which ought to be decreased to scale back the loss.


Studying from a Acquainted Instance

Now, how can we do that?

At this level, we don’t understand how to do this.

Let’s do one factor. Let’s proceed with what we already know.

However what can we already know?

We have already got an thought about easy linear regression, how the loss is calculated, and the way the bowl curve seems.

Possibly we are able to study one thing from it.

In easy linear regression, we have to discover the optimum values for β0 (intercept) and β1 (slope).

After all, we have already got formulation, however we additionally derived them ourselves.

What we did was plot a graph with three axes. One axis represented (β0), the second represented (β1), and the third represented the loss.

We plotted the loss values for various (β0) and (β1) values and noticed a bowl-shaped curve.

We then understood that the minimal loss happens on the backside of the curve, the place the slope of the loss floor turns into zero.

Picture by Creator

To search out that time, we used partial differentiation and ultimately solved the ensuing equations to acquire the formulation.

In easy linear regression, we are able to use totally different loss capabilities such because the Sum of Squared Errors (SSE), Imply Squared Error (MSE), or different appropriate loss capabilities relying on the issue.

Right here, we’ll take into account the Imply Squared Error (MSE) as our loss perform.

For easy linear regression, the loss perform is

[
L(beta_0,beta_1)=frac{1}{n}sum_{i=1}^{n}left(y_i-hat{y}_iright)^2
]

the place

[
hat{y}_i=beta_0+beta_1x_i.
]

Discover that the loss relies upon solely on two parameters, [beta_0] and [beta_1]

Now we have to search out the values of [beta_0] and [beta_1] that decrease this loss.

Now, let’s have a look at our neural community.

Since our present downside is a non-linear regression downside, we are able to proceed utilizing the identical Imply Squared Error (MSE).

The loss perform can now be written as

[
L(w_1,w_2,w_3,w_4,b_1,b_2,b_3)
=
frac{1}{n}
sum_{i=1}^{n}
left(y_i-hat{y}_iright)^2.
]

Nonetheless, in contrast to easy linear regression, our prediction is now not given by

[
hat{y}=beta_0+beta_1x.
]

As an alternative, it’s produced by your complete neural community.

For our neural community,

[
hat{y}_i
=
w_3,mathrm{ReLU}(w_1x_i+b_1)
+
w_4,mathrm{ReLU}(w_2x_i+b_2)
+
b_3.
]

Consequently, the loss now not depends upon simply two parameters. It now depends upon all seven parameters of the neural community, that are [w_1,w_2,w_3,w_4,b_1,b_2,b_3]

Similar to in easy linear regression, our aim remains to be the identical: discover the values of those parameters that decrease the loss.

To attain that, we have to perceive how the loss modifications after we change every parameter individually whereas retaining the remaining parameters fastened.

In different phrases, we have to compute partial derivatives equivalent to

[
frac{partial L}{partial w_1},
quad
frac{partial L}{partial w_2},
quad
frac{partial L}{partial w_3},
quad
ldots,
quad
frac{partial L}{partial b_3}.
]

These partial derivatives inform us how delicate the loss is to every parameter and assist us decide whether or not that parameter ought to be elevated or decreased to scale back the loss.


Setting the Purpose

In easy linear regression, after we plot the loss values for various mixtures of the slope and intercept, we get a bowl-shaped curve in three-dimensional house.

For our neural community, nevertheless, we can not visualize the loss floor in the identical method as a result of it now exists in eight-dimensional house.

Regardless that we are able to’t visualize it, our goal stays the identical which is to search out the parameter values that decrease the loss.


Time to Perceive Chain Rule

Now, based mostly on what we already know from easy linear regression, we discovered a strategy to proceed additional, which is to compute the partial derivatives of the loss with respect to every parameter.

The parameters are

[w_1,w_2,w_3,w_4,b_1,b_2,b_3]

However earlier than we proceed, there may be one vital idea that we have to perceive, and that’s the chain rule as a result of it’s the basis of every little thing we’re going to do subsequent.

The chain rule is used at any time when one amount depends upon one other amount, which in flip depends upon one other amount.

Let’s perceive this with a easy instance.

Suppose

[
y=x^2
]

and

[
z=y^3
]

Now, we need to discover

[
frac{dz}{dx}
]

First, let’s discover this spinoff utilizing classical differentiation.

Discover that [z] is written by way of [y] not [x] Since we would like the spinoff with respect to [x] we are able to first eradicate the intermediate variable by substituting [y=x^2] into the equation for [z]

Substituting,

[
z=(x^2)^3=x^6
]

Now the expression relies upon solely on [x] so we are able to differentiate it straight.

Utilizing the facility rule,

[
frac{dz}{dx}
=
frac{d}{dx}(x^6)
=
6x^5
]

This technique might be straightforward for easy issues like this one as a result of we are able to simply substitute one expression into one other.

Nonetheless, think about a a lot larger expression with a number of intermediate variables.

Rewriting your complete equation earlier than differentiating would change into troublesome and there’s a greater probability for errors.

As an alternative of mixing every little thing right into a single expression first, now we have a way more systematic strategy referred to as the chain rule.

As an alternative of eliminating the intermediate variables, with the chain rule we are able to work via them one step at a time.

Let’s see how we are able to implement chain rule.

We already know that, [frac{dz}{dx}] tells us how a lot [z] modifications after we make a really small change in [x]

Right here [z] doesn’t rely straight on [x]

As an alternative, the connection seems like this:

[
x rightarrow y rightarrow z.
]

Which means that at any time when [x] modifications, it first modifications [y] and that change in [y] then modifications [z]

Now as a substitute of making an attempt to distinguish every little thing without delay, the chain rule tells us to interrupt the issue into smaller items.

[
frac{dz}{dx}=frac{dz}{dy}timesfrac{dy}{dx}
]

Now let’s calculate every half individually.

Since

[
z=y^3,
]

we get

[
frac{dz}{dy}=3y^2.
]

Equally, since

[
y=x^2,
]

we get

[
frac{dy}{dx}=2x.
]

Multiplying these collectively,

[
frac{dz}{dx}=3y^2times2x.
]

Lastly, we all know that

[
y=x^2,
]

so we substitute it again into the equation.

[
frac{dz}{dx}=3(x^2)^2times2x=6x^5.
]

The vital factor we are able to observe right here is that we by no means differentiated your complete expression at a time.

As an alternative, we broke it into smaller derivatives, solved them one after the other, after which multiplied them collectively.

We’ll use precisely the identical thought in our neural community.

The one distinction is that the chain is now a bit longer.


Fixing step-by-step utilizing Classical Differentiation Methodology

Now that we perceive the chain rule, let’s proceed to calculate the partial derivatives with respect to every parameter.

Till now, we used particular values for the weights and biases to know how the ahead cross works. Nonetheless, our goal is to study these values from the information.

So, as a substitute of utilizing fastened values, let’s signify them utilizing parameters first.

The output of our neural community is given by

[
hat{y}=w_3a_1+w_4a_2+b_3
]

the place

[
a_1=mathrm{ReLU}(z_1)
]
[
z_1=w_1x+b_1
]

and

[
a_2=mathrm{ReLU}(z_2)
]
[
z_2=w_2x+b_2
]

Utilizing this output, we are able to calculate the Imply Squared Error (MSE), which is the loss perform of our neural community.

The final MSE equation is

[
L(w_1,w_2,w_3,w_4,b_1,b_2,b_3)=frac{1}{n}sum_{i=1}^{n}(y_i-hat{y}_i)^2
]

Now, let’s substitute the prediction equation into the loss perform.

[
L(w_1,w_2,w_3,w_4,b_1,b_2,b_3)=frac{1}{n}sum_{i=1}^{n}left(y_i-left(w_3a_{1i}+w_4a_{2i}+b_3right)right)^2
]

Since

[
a_{1i}=mathrm{ReLU}(w_1x_i+b_1)
]

and

[
a_{2i}=mathrm{ReLU}(w_2x_i+b_2)
]

the entire loss perform turns into

[
L(w_1,w_2,w_3,w_4,b_1,b_2,b_3)=frac{1}{n}sum_{i=1}^{n}left(y_i-left(w_3mathrm{ReLU}(w_1x_i+b_1)+w_4mathrm{ReLU}(w_2x_i+b_2)+b_3right)right)^2
]

Now, let’s begin discovering the partial spinoff with respect to any one of many parameters, let’s start with

[w_1]

So, now we have to calculate

[
frac{partial}{partial w_1}left[frac{1}{n}sum_{i=1}^{n}left(y_i-left(w_3,mathrm{ReLU}(w_1x_i+b_1)+w_4,mathrm{ReLU}(w_2x_i+b_2)+b_3right)right)^2right]
]

This equation appears troublesome to unravel. How can we discover the partial spinoff with respect to

[w_1]

from such a big equation?

Let’s proceed utilizing the identical concepts from differentiation that we already know.

As an alternative of differentiating every little thing without delay, we’ll simplify the issue step-by-step.

We need to compute

[
frac{partial L}{partial w_1}
]

Substitute the loss perform into the spinoff.

[
frac{partial L}{partial w_1}
=
frac{partial}{partial w_1}
left(
frac{1}{n}
sum_{i=1}^{n}
(y_i-hat{y}_i)^2
right)
]

Discover that we don’t substitute the complete expression for

[hat{y}_i]

but. We’ll try this solely when it turns into needed.

As [frac{1}{n}] is a continuing, we all know that it may be moved exterior the spinoff.

[
frac{partial L}{partial w_1}
=
frac{1}{n}
frac{partial}{partial w_1}
left(
sum_{i=1}^{n}
(y_i-hat{y}_i)^2
right)
]

The summation can be linear, so the spinoff can cross via it.

What can we imply by that?

It means in summation we add many phrases collectively and we are able to differentiate every time period individually after which add the derivatives.

[
frac{partial L}{partial w_1}
=
frac{1}{n}
sum_{i=1}^{n}
frac{partial}{partial w_1}
left(
(y_i-hat{y}_i)^2
right)
]

Now Differentiate the Sq.

Let

[
A=y_i-hat{y}_i
]

Then

[
frac{partial L}{partial w_1}
=
frac{1}{n}
sum_{i=1}^{n}
frac{partial}{partial w_1}(A^2)
]

Utilizing the facility rule,

[
frac{partial}{partial w_1}(A^2)
=
2A
frac{partial A}{partial w_1}
]

Substitute this into the earlier equation.

[
frac{partial L}{partial w_1}
=
frac{2}{n}
sum_{i=1}^{n}
A
frac{partial A}{partial w_1}
]

Exchange [A] with [y_i-hat{y}_i].

[
frac{partial L}{partial w_1}
=
frac{2}{n}
sum_{i=1}^{n}
(y_i-hat{y}_i)
frac{partial}{partial w_1}
(y_i-hat{y}_i)
]

Differentiate the Expression Inside

We all know that the true goal (precise commentary) [y_i] is a continuing,

[
frac{partial y_i}{partial w_1}=0
]

Due to this fact,

[
frac{partial}{partial w_1}
(y_i-hat{y}_i)
=
-frac{partialhat{y}_i}{partial w_1}
]

Substitute this again.

[
frac{partial L}{partial w_1}
=
-frac{2}{n}
sum_{i=1}^{n}
(y_i-hat{y}_i)
frac{partialhat{y}_i}{partial w_1}
]

Now Differentiating the Prediction [frac{partialhat{y}_i}{partial w_1}
]

We all know that from the output layer in our neural community

[
hat{y}_i
=
w_3a_{1i}
+
w_4a_{2i}
+
b_3
]

Substitute the equations of hidden neuron activation capabilities.

[
hat{y}_i
=
w_3mathrm{ReLU}(w_1x_i+b_1)
+
w_4mathrm{ReLU}(w_2x_i+b_2)
+
b_3
]

Differentiate with respect to [w_1]

[
frac{partialhat{y}_i}{partial w_1}
=
frac{partial}{partial w_1}
left(
w_3mathrm{ReLU}(w_1x_i+b_1)
+
w_4mathrm{ReLU}(w_2x_i+b_2)
+
b_3
right)
]

Differentiating every time period individually.

As [w_3] is fixed,

[
frac{partial}{partial w_1}
left(
w_3mathrm{ReLU}(w_1x_i+b_1)
right)
=
w_3
frac{partial}{partial w_1}
mathrm{ReLU}(w_1x_i+b_1)
]

The second time period incorporates solely [w_2] so

[
frac{partial}{partial w_1}
left(
w_4mathrm{ReLU}(w_2x_i+b_2)
right)
=0
]

Additionally,

[
frac{partial b_3}{partial w_1}=0
]

Therefore,

[
frac{partialhat{y}_i}{partial w_1}
=
w_3
frac{partial}{partial w_1}
mathrm{ReLU}(w_1x_i+b_1)
]

Differentiate the ReLU Expression

Let

[
u=w_1x_i+b_1
]

Then

[
mathrm{ReLU}(w_1x_i+b_1)
=
mathrm{ReLU}(u)
]

Now Differentiating

[
u=w_1x_i+b_1
]

with respect to [w_1]

[
frac{du}{dw_1}=x_i
]

Now differentiate the activation.

[
frac{d,mathrm{ReLU}(u)}{du}
=
mathrm{ReLU}'(u)
]

Right here we use the chain rule,

[
frac{partial}{partial w_1}
mathrm{ReLU}(w_1x_i+b_1)
=
mathrm{ReLU}'(u)
frac{du}{dw_1}
]

Substituting [frac{du}{dw_1}=x_i]

[
frac{partial}{partial w_1}
mathrm{ReLU}(w_1x_i+b_1)
=
mathrm{ReLU}'(u)x_i
]

Changing [u]

[
frac{partial}{partial w_1}
mathrm{ReLU}(w_1x_i+b_1)
=
mathrm{ReLU}'(w_1x_i+b_1)x_i
]

This ReLU derivation would possibly get complicated, let’s decelerate and see what we really did right here.

We all know that the ReLU activation doesn’t depend upon w1w_1 straight.

It depends upon the worth of w1xi+b1w_1x_i+b_1​.

On the similar time, the expression w1xi+b1w_1x_i+b_1​ depends upon w1w_1​.

So when w1w_1 modifications, it first modifications w1xi+b1w_1x_i+b_1, which in flip modifications the output of the ReLU.

That is precisely the form of scenario the place we use the chain rule.

So to search out how the ReLU modifications with respect to w1w_1​, we first discover how w1xi+b1w_1x_i+b_1 modifications with respect to w1w_1, after which how the ReLU modifications with respect to w1xi+b1w_1x_i+b_1​.

Lastly, we mix these two outcomes utilizing the chain rule.


Now Substitute Again

Earlier, we discovered

[
frac{partial L}{partial w_1}
=
-frac{2}{n}
sum_{i=1}^{n}
(y_i-hat{y}_i)
frac{partialhat{y}_i}{partial w_1}
]

We additionally calculated

[
frac{partialhat{y}_i}{partial w_1}
=
w_3
mathrm{ReLU}'(w_1x_i+b_1)
x_i
]

Substitute this into the earlier equation.

[
frac{partial L}{partial w_1}
=
-frac{2}{n}
sum_{i=1}^{n}
(y_i-hat{y}_i)
w_3
mathrm{ReLU}'(w_1x_i+b_1)
x_i
]

Last consequence

Now we have derived

[
frac{partial L}{partial w_1}
=
-frac{2}{n}
sum_{i=1}^{n}
(y_i-hat{y}_i)
w_3
mathrm{ReLU}'(w_1x_i+b_1)
x_i
]

This tells us precisely how the loss modifications when the load

[w_1]

modifications.

At first, this equation might look obscure, however it’s really fairly easy.

Because it tells us how the whole loss modifications after we make a really small change to the load w1​, this worth is named the gradient, and it’s precisely what gradient descent makes use of to replace the load.

To calculate this gradient, the equation considers each coaching instance within the dataset.

For every coaching instance:

[(y_i-hat{y}_i)] tells us how far the prediction is from the precise worth.

[w_3] tells us how a lot the primary hidden neuron contributes to the ultimate prediction.

[mathrm{ReLU}'(w_1x_i+b_1)] tells us whether or not the change in [w_1] can cross via the ReLU activation.

[x_i] tells us how a lot a small change in [w_1] impacts the neuron’s enter.

Every coaching instance contributes its personal gradient based mostly on these portions.

We add all of those particular person contributions collectively, and since we’re utilizing the Imply Squared Error (MSE) loss perform, dividing by nn provides the common gradient throughout your complete dataset.

This common gradient tells us how w1w_1 ought to be adjusted to scale back the general loss, quite than simply the error for a single coaching instance.

Conclusion

In case you keep in mind our dialogue on Easy Linear Regression, we calculated the partial derivatives with respect to solely two parameters.

On this weblog, now we have efficiently derived

[frac{partial L}{partial w_1}]

Though the derivation was lengthy, We used the identical concepts from calculus that we already knew in each step.

We merely utilized differentiation step-by-step and used the chain rule wherever it was required.

Now, our neural community nonetheless has six extra parameters, and every of them has its personal partial spinoff.

So, what do you suppose?

Do we have to repeat this whole course of for each weight and bias?

Happily, no.

As neural networks change into bigger, manually deriving each gradient would rapidly change into laborious and inefficient.

There needs to be a greater method.

The excellent news is that we don’t want any new arithmetic.

We merely want a greater strategy to manage these calculations.

The whole lot remains to be constructed on the identical chain rule we’ve been utilizing all through this text.

Within the subsequent half, we’ll see how the chain rule might be utilized effectively throughout your complete neural community, main us to probably the most vital algorithms in deep studying: backpropagation.


I hope you realized one thing from this text. In case you’re nonetheless confused about neural networks or wish to revisit the fundamentals, you’ll be able to all the time learn my earlier article right here.

In case you discovered this beneficial, be at liberty to share it with individuals who may have it.

In case you’ve got any doubts or ideas, you’ll be able to touch upon LinkedIn.

“It doesn’t matter how slowly you go so long as you don’t cease.”
— Confucius

Thanks for studying, and I’ll see you in Half 2!

[ad_2]

Ship apps quicker with GitHub, Vercel, and Firestore

0

[ad_1]

The chilly begin actuality

Whereas the trade has made huge strides in minimizing initialization instances—significantly with light-weight edge networks—conventional Node.js-based serverless capabilities nonetheless expertise chilly begins. If a operate has not been invoked not too long ago, or if visitors spikes require a brand new occasion to spin up concurrently, the primary request will take a noticeable latency hit because the container provisions and the code hundreds.

API as an alternative of RAM

In a standard server surroundings, you may retailer transient information in international RAM, permitting subsequent requests to entry shared context immediately. Within the serverless mannequin, each request may hit a recent container. Due to this fact, all shared context should be externalized. Though Firestore serves brilliantly because the state supervisor, counting on a database for high-frequency, sub-millisecond, ephemeral caching introduces community latency and per-operation prices. That mentioned, utilizing a shared RAM state on a server is non-trivial additionally, until you might be utilizing a single app server and VM (as a result of high-availability or fail-over necessities will reduce the RAM win on a standard server).

Tuning for velocity and management

Each architectural determination is a trade-off. There are not any cost-free selections. By adopting the GitHub, Vercel, and Firestore stack, you might be explicitly maximizing function velocity over fine-grained management.

[ad_2]

Might Your AI Techniques Already Be Excessive-Danger Underneath the EU AI Act?

[ad_1]


The European Fee’s newest draft pointers present much-needed readability on how organizations ought to classify high-risk AI methods below Article 6 of the EU AI Act. Nevertheless, in addition they increase an essential query for enterprises: might your current AI methods already be thought-about high-risk with out you realizing it?

The reply could rely on greater than what the expertise does.

Underneath the EU AI Act, an AI system’s meant objective performs a central function in figuring out its danger classification. This implies how a system is documented, marketed, deployed, and used could be simply as essential as its technical capabilities.

Article 6 outlines two routes by which an AI system could also be categorised as high-risk. These embody AI used inside sure regulated merchandise and AI deployed in delicate use instances that would considerably have an effect on folks’s well being, security, or elementary rights.

For enterprise groups, this creates a number of speedy questions:

Which AI methods throughout the group fall inside the scope of Article 6?
Does present documentation precisely replicate how every system is getting used?
Might the Article 6(3) exemption apply, and what proof could be required?
What ought to authorized, governance, and expertise groups be doing now?

Airia’s on-demand webinar, EU AI Act: What It Really Requires and Enterprises Must Do Now, breaks down the brand new steerage and turns it right into a sensible choice framework.

The session covers the 2 pathways to high-risk classification, the constraints of the Article 6(3) self-assessment mechanism, and the steps enterprises can take to evaluate their AI methods extra confidently.

Entry the on-demand webinar to know what the most recent steerage means to your AI governance program and what your group ought to do subsequent.

EU AI Act Webinar – Airia


[ad_2]

System freezes plagued my Mac for months. A easy repair lastly solved it

0

[ad_1]

[ad_2]

‘Aliens’ at 40: James Cameron’s sequel is a sci-fi icon, however do you know he stop the film twice?

0

[ad_1]

The place does James Cameron’s “Aliens” rank among the many different Alien films? That depends upon who you ask. Some would possibly say it is one of the best, whereas others put it simply behind the unique (spoiler alert: it is one of the best). Regardless, there is no denying that this 1986 movie shifted gears, shifting the franchise from horror to horror-tinged sci-fi motion and paving an alternate path for the long run.

As Cameron acknowledged in an interview with Lofficier, the plan at all times was “to do a movie that was not as scary… it is scary, but it surely’s not as scary, however extra intense, and I like to make use of the phrase, exhilarating. As a result of I feel you get exhilarated by the depth of the form of motion that is on this movie.”

By way of story development, the sequel’s shake-up makes full sense. Sigourney Weaver’s Ellen Ripley survived the Xenomorph in “Alien”, however now she should conquer her fears and face the grim creature as soon as once more. This time, she has allies and firepower on her aspect, although most of these Colonial Marines grow to be about as helpful as French kissing a beehive.

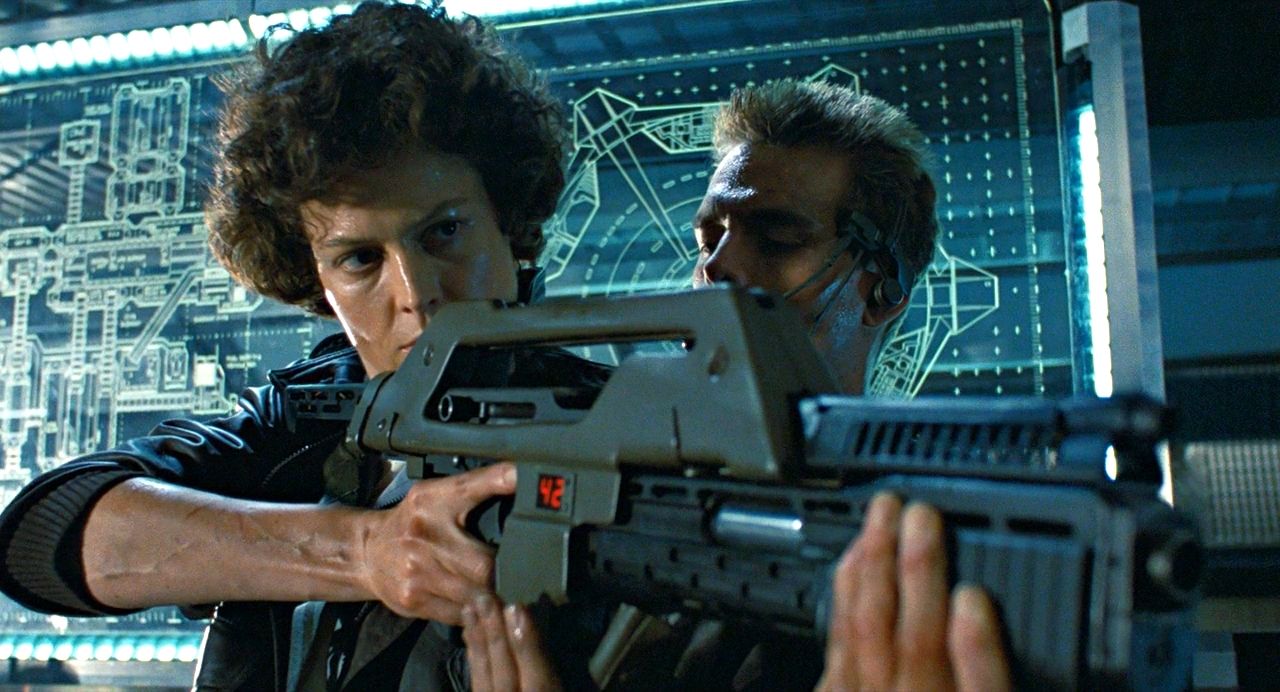
Screenshot from the sci-fi movie Aliens (1986)

(Picture credit score: twentieth Century Fox)

“Aliens” exploded right into a monster hit, each financially and critically, suggesting that Cameron has a Midas contact in relation to sequels. Well-known film critic Roger Ebert referred to as it “an excellent instance of filmmaking craft”, and it is powerful to argue that time. But what’s wonderful to ponder is how “Aliens” almost fell aside a number of instances earlier than it truly occurred.

[ad_2]

Is quantum readiness value your effort?

0

[ad_1]

How do CIOs strike a stability between preparation for quantum tomorrow whereas incurring prices within the right here and now?

A lot of the consideration on quantum computing focuses on the hazard of unhealthy actors getting their fingers on the know-how and breaching conventional cybersecurity defenses. There are additionally expectations for quantum to assist drug discovery and different complicated calculations — if and when the know-how turns into sensible. However is it value investing time, power and cash now, when such sensible use stays down the street?

On this episode of the InformationWeek Podcast, Pal Narayanan, chief digital and data officer at Kenco, and Rishi Kaushal, CIO of Entrust, focus on the place quantum computing resides on their radar and how they’re making ready for its full arrival.

They reply questions on whether or not their preparations included procuring new {hardware} and talent units inside their organizations. Do different members of their C-suites have questions on potential vulnerabilities within the wake of quantum? Is there a number of disbelief concerning the potential influence in contrast with the price of preparation?

Associated:Avoiding community logjams within the age of AI

Are there extra advantages to making ready for quantum threats? Has the prep effort put firms on higher footing to reply to present threats?

The Questionable Concepts tabletop train returns as effectively, because the panelists cope with challenges that embody gremlins, goblins and the traditional GNO/ME working system.


[ad_2]

There’s plenty of hype round perimenopause. Don’t purchase it.

[ad_1]

At this time, details about perimenopause is extra prevalent and accessible than ever. If you happen to’re a lady in your 40s and also you’re not feeling 100%, chances are high there’ll be somebody on-line able to let you know you’re in perimenopause. And that you just may wish to begin spending your cash on blood checks, apps, and dietary supplements or demanding hormone substitute remedy. However as common readers may need guessed by this level, it’s not that straightforward.

Perimenopause tends to begin across the age of 46 or 47. It’s throughout this time that many ladies begin to expertise some signs like scorching flashes, irregular or unusually heavy intervals, or anxiousness, for instance. And it may be heavy going. “Typically signs are at their worst within the perimenopause,” says Mary Ann Lumsden, former president of the Worldwide Menopause Society.

That’s as a result of hormones can fluctuate wildly. Ranges of estrogen, progesterone, luteinizing hormone, and follicle-stimulating hormone can roller-coaster earlier than leveling off after menopause. And that’s why, regardless of what some entrepreneurs will declare, there isn’t a take a look at for perimenopause.

“You possibly can’t interpret hormone [measures] as a result of they modify a lot,” says Lumsden. “And that’s fairly regular.”

That doesn’t imply ladies ought to need to put up with signs. However precisely how these signs are handled is one other subject that has been clouded by misinformation.

Final week, I advised a pal about some unusually dangerous pelvic ache I’d skilled. Her rapid recommendation was to seek out out if I used to be perimenopausal and, if I used to be, to request hormone substitute remedy (HRT) as quickly as doable. If my physician wouldn’t prescribe it, she continued, I ought to merely discover one other physician who would.

[ad_2]